
Fine Tune Quantized Llms On Industrial Data With Bitsandbytes And Trl
Fine-Tune Quantized LLMs on Industrial Data with bitsandbytes and TRL ...

A simple repo for fine-tuning LLMs with both GPTQ and bitsandbytes ...
How to fine tune LLMs with Axolotl | by Edgar Bermudez | about ai | Medium
How to Efficiently Fine-tune Quantized LLMs for Finance with FIN-LLAMA ...
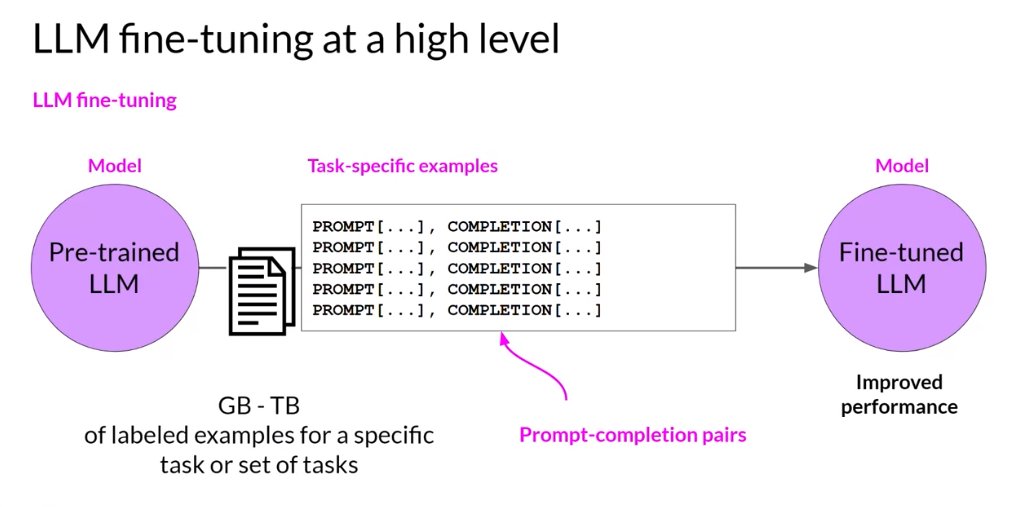
Introduction to LLMs and the generative AI : Part 3— Fine Tuning LLM ...
Quantization of LLMs and Fine-Tuning with QLoRA

Tuto Startup - Fine-tune LLMs with synthetic data for context-based Q&

GPTQLoRA: Efficient Finetuning of Quantized LLMs with GPTQ : r/LocalLLaMA

Introduction to LLMs and the generative AI : Part 3— Fine Tuning LLM ...
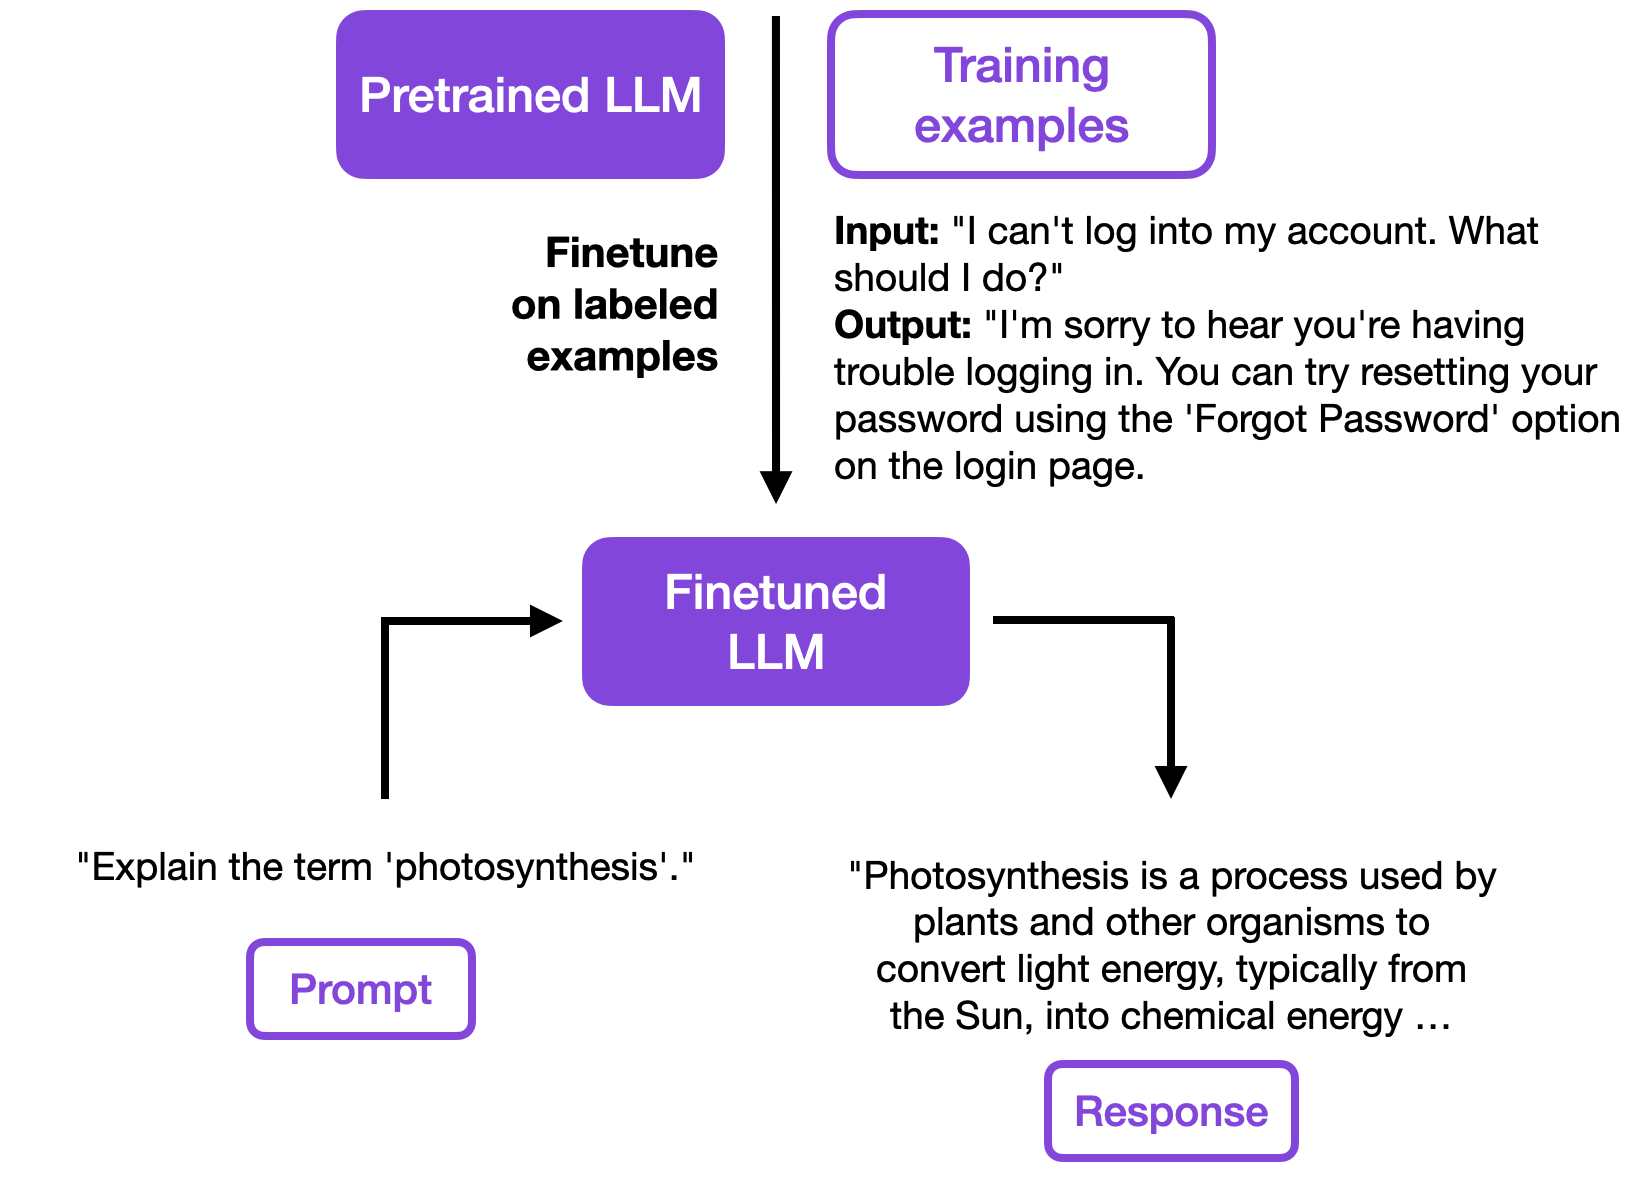
Finetuning Falcon LLMs More Efficiently With LoRA and Adapters
Advertisement Space (300x250)
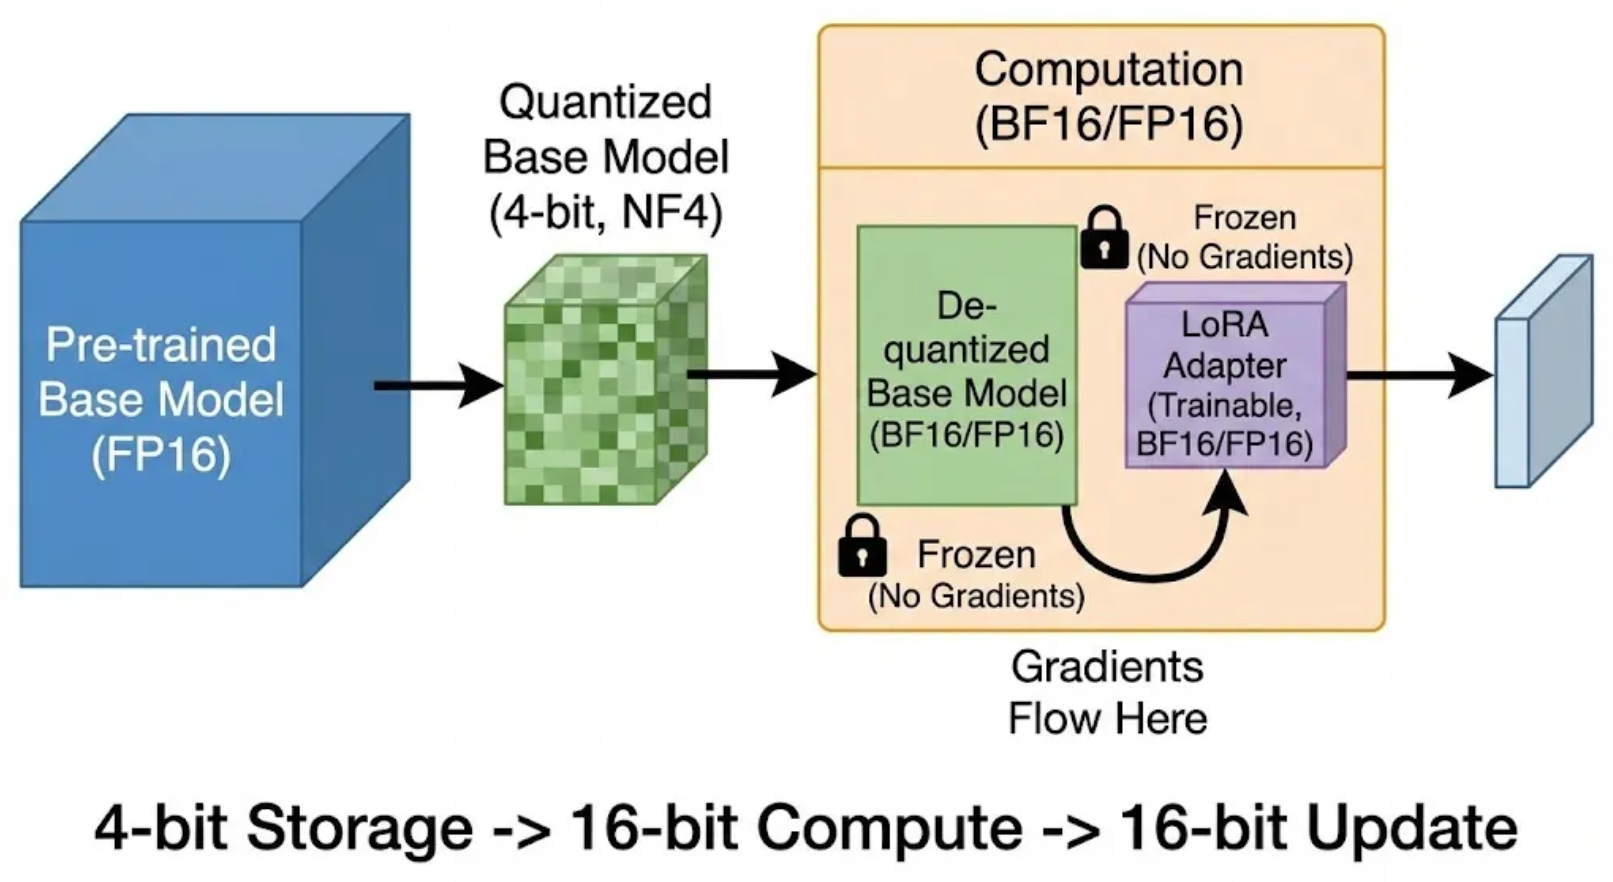
[논문 리뷰] QLoRA: Efficient Finetuning of Quantized LLMs

Efficient Fine-Tuning of Quantized Models via Adaptive Rank and ...

Finetuning LLMs Efficiently with Adapters
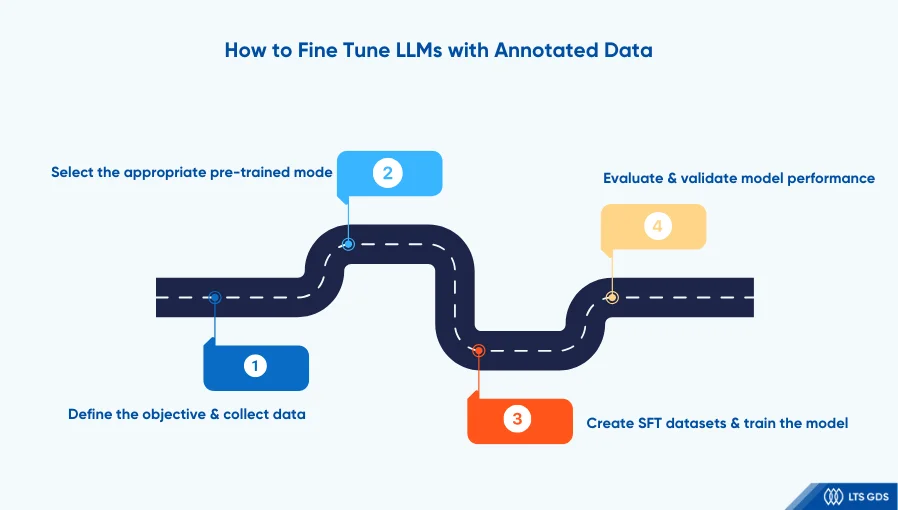
A Guide to Data Labeling for Fine-tuning LLMs

論文紹介:QLoRA: Efficient Finetuning of Quantized LLMs | PDF

ReFT: Enhancing LLMs with reinforcement fine-tuning | SuperAnnotate

How to Improve Machine Utilization for Multiple Fine-Tuned LLMs with ...
How to Fine-Tune LLMs in 2024 with Hugging Face
How to Use LLM with Private Data Best Practices for Data Security
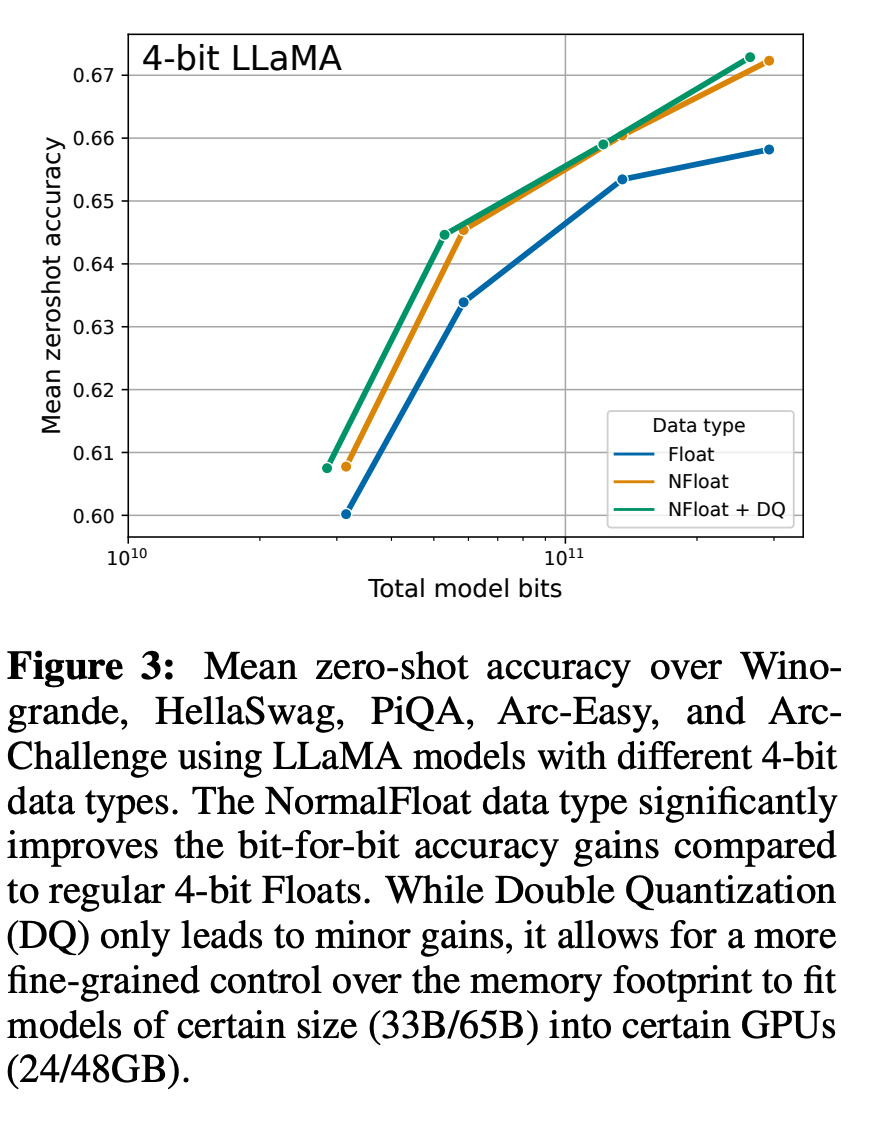
[논문분석] QLoRA: Efficient Finetuning of Quantized LLMs
Advertisement Space (336x280)

The visualization of two approaches to fine-tune LLMs based on ...
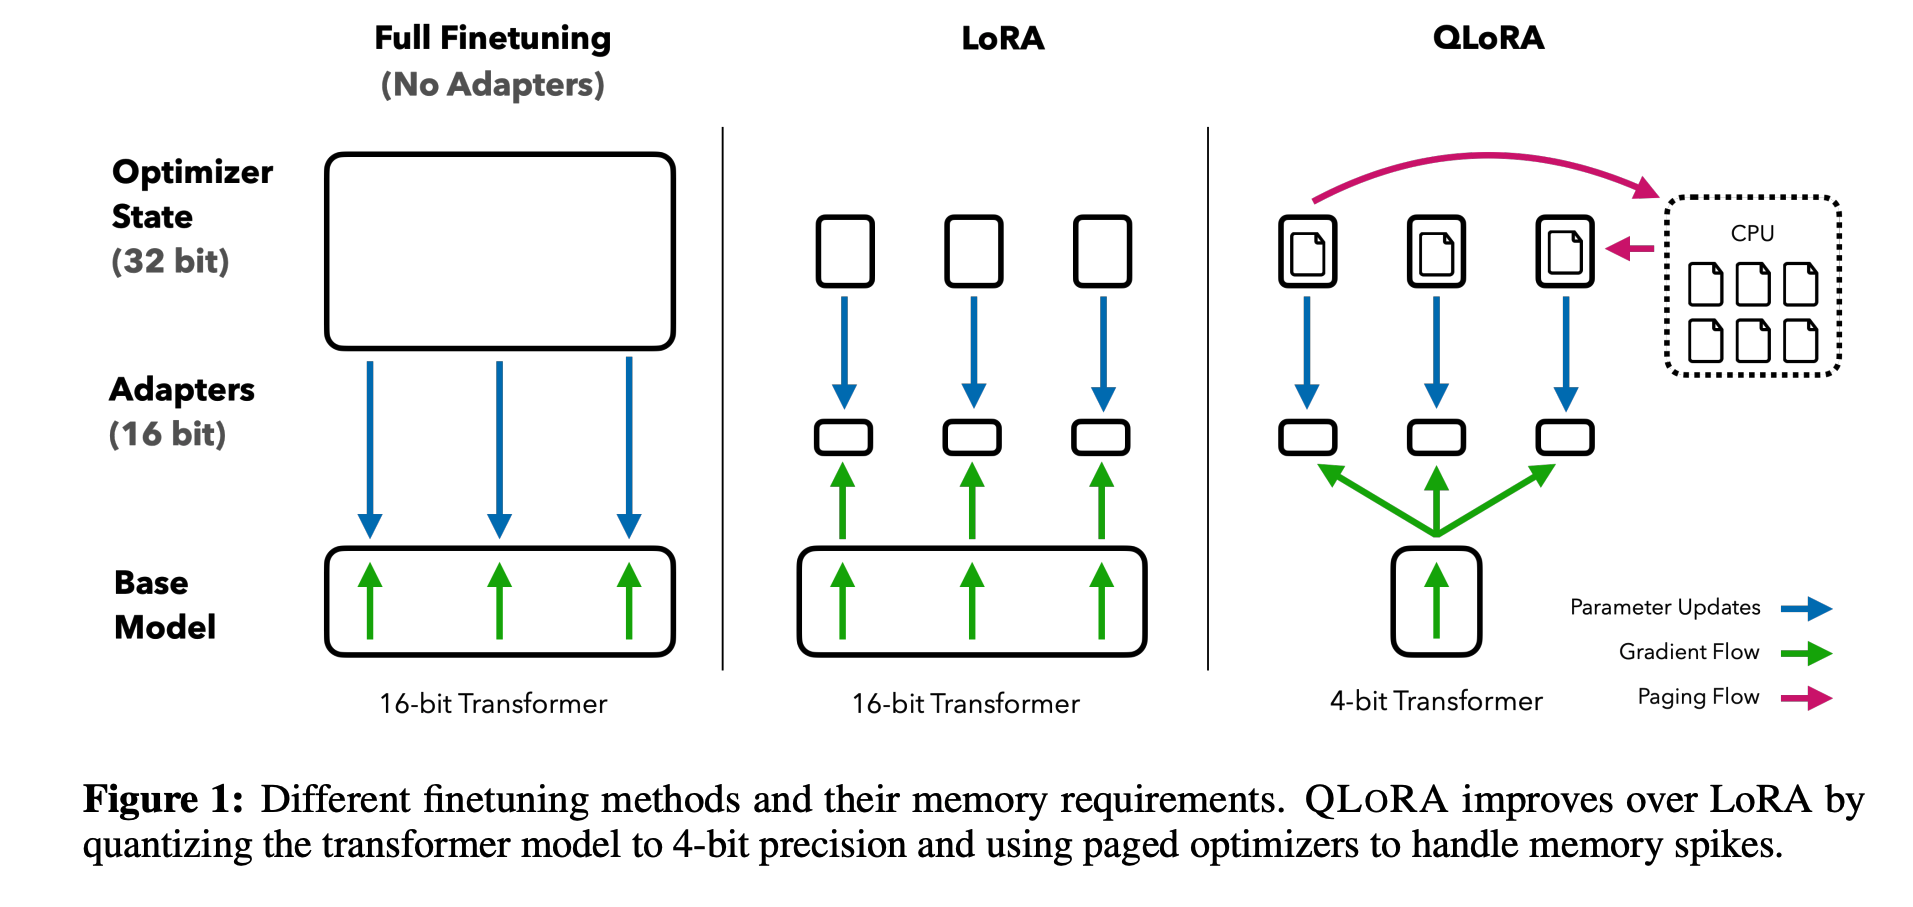
[논문분석] QLoRA: Efficient Finetuning of Quantized LLMs

Finetune LLMs on your own consumer hardware using tools from PyTorch ...

(PDF) QLoRA: Efficient Finetuning of Quantized LLMs

QLoRA: Efficient Finetuning of Quantized LLMs (Ko/En Subtitles) - YouTube

Finetune LLMs on your own consumer hardware using tools from PyTorch ...
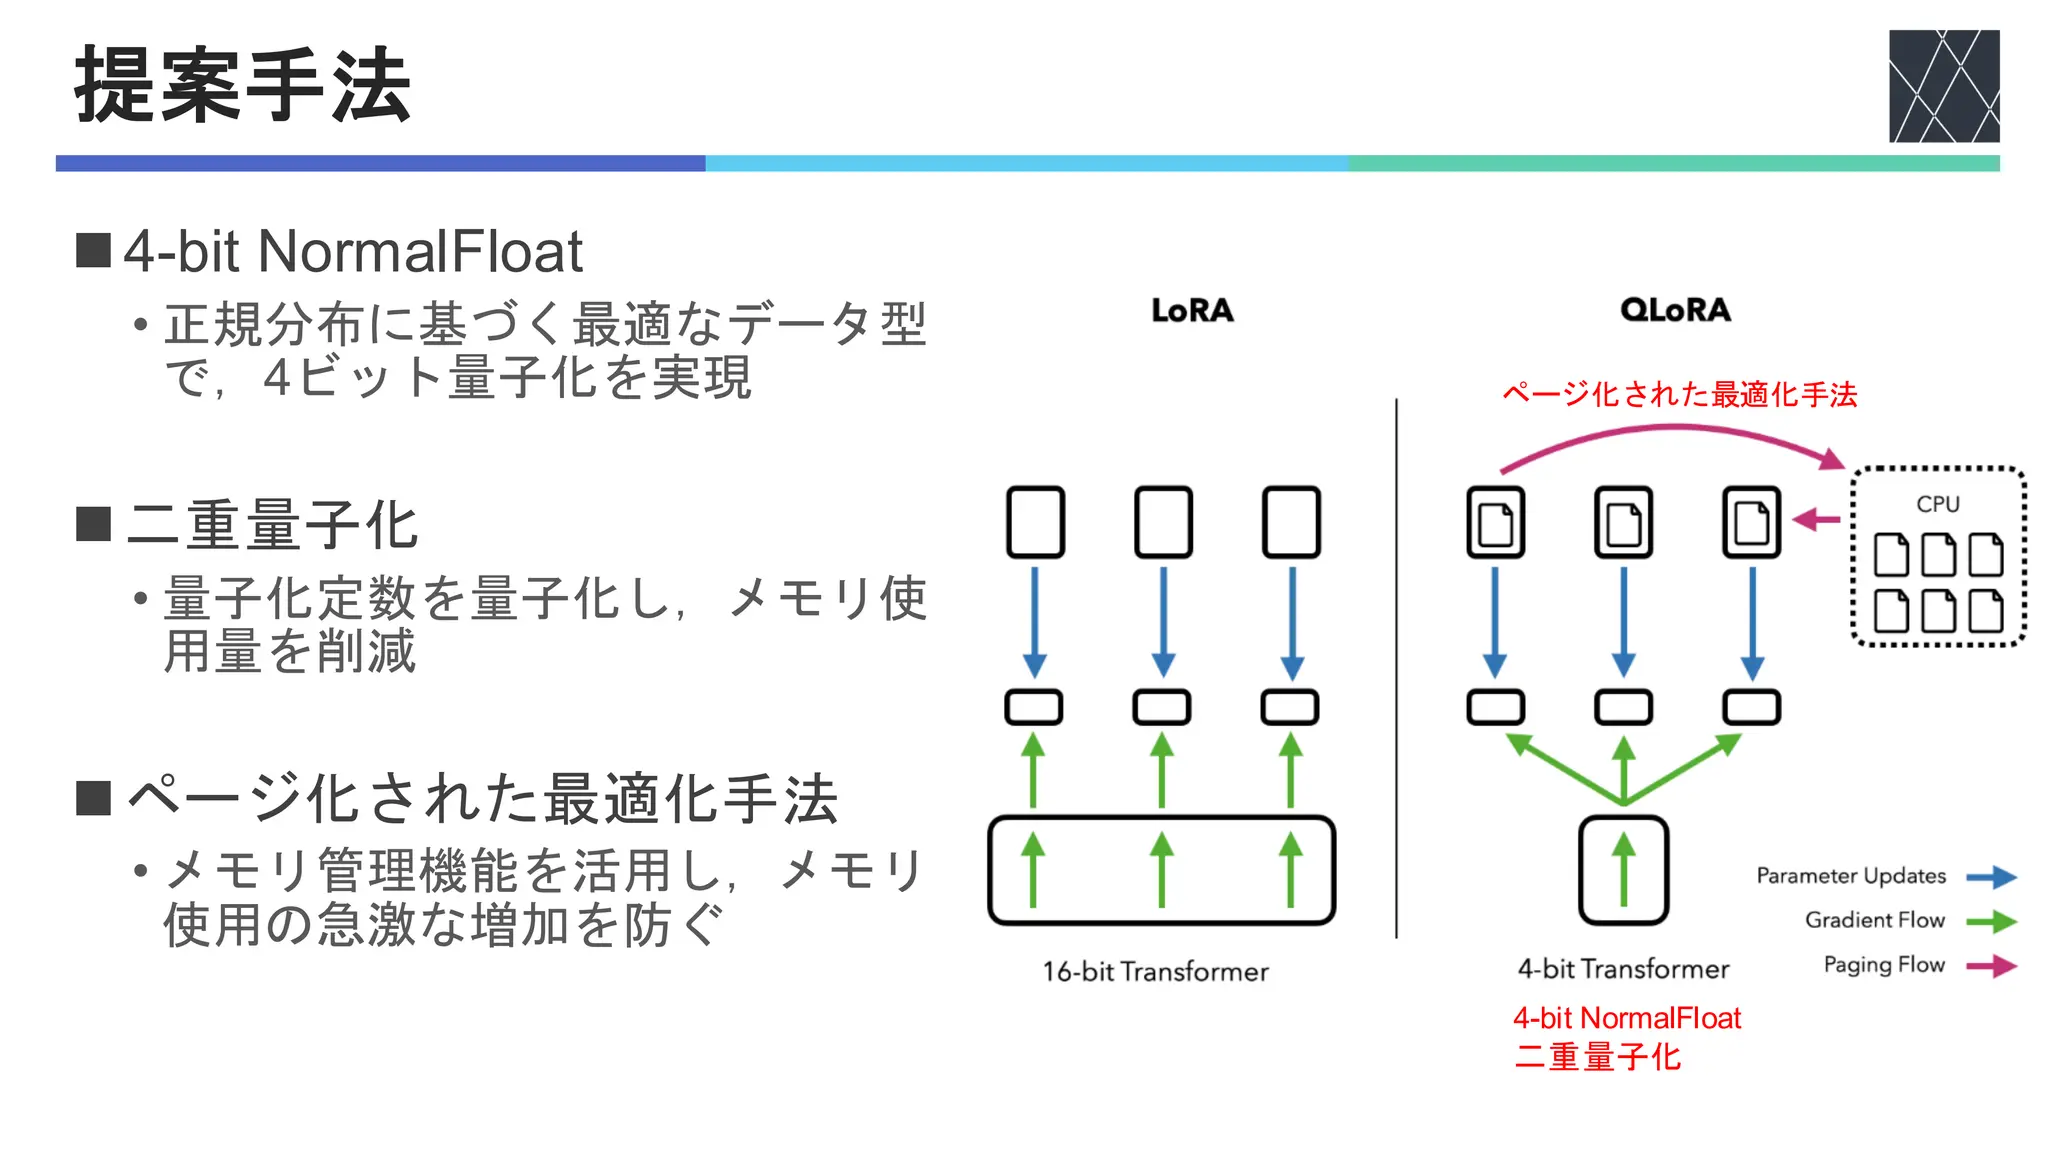
論文紹介:QLoRA: Efficient Finetuning of Quantized LLMs | PDF
Finetune LLMs on your own consumer hardware using tools from PyTorch ...
Fine-Tuning LLM Series (Part 1): Optimize LLMs with LoRA & Quantization
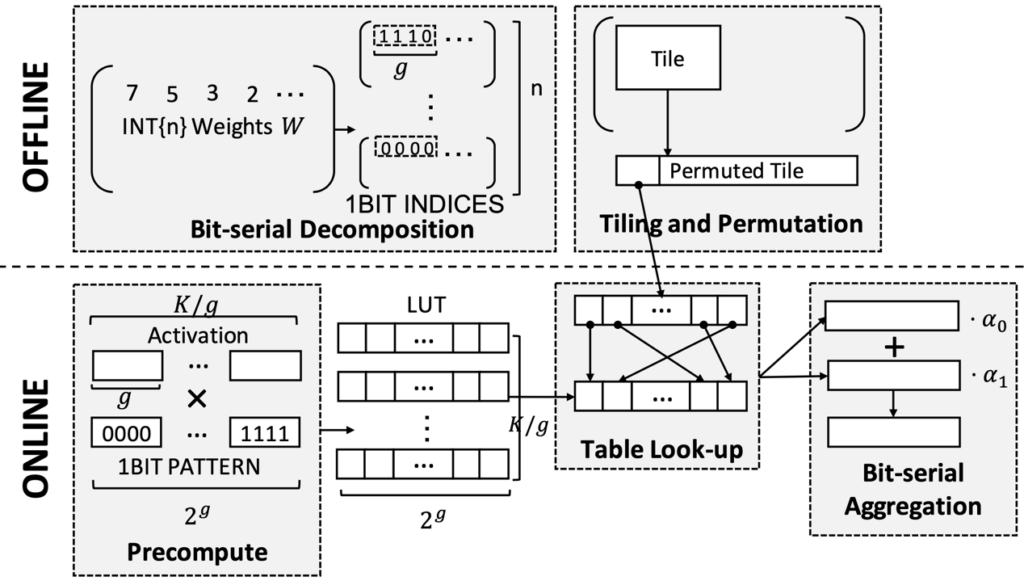
Advances to low-bit quantization enable LLMs on edge devices ...
Advertisement Space (336x280)
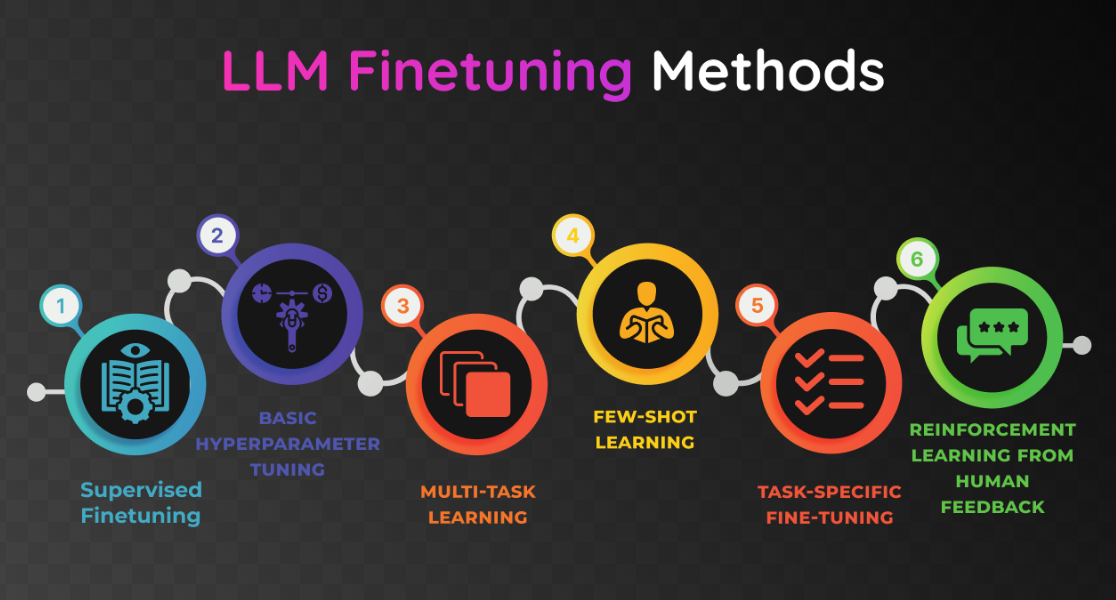
Fine-tuning LLMs to Write Data Science Code | by Benedict Neo | bitgrit ...
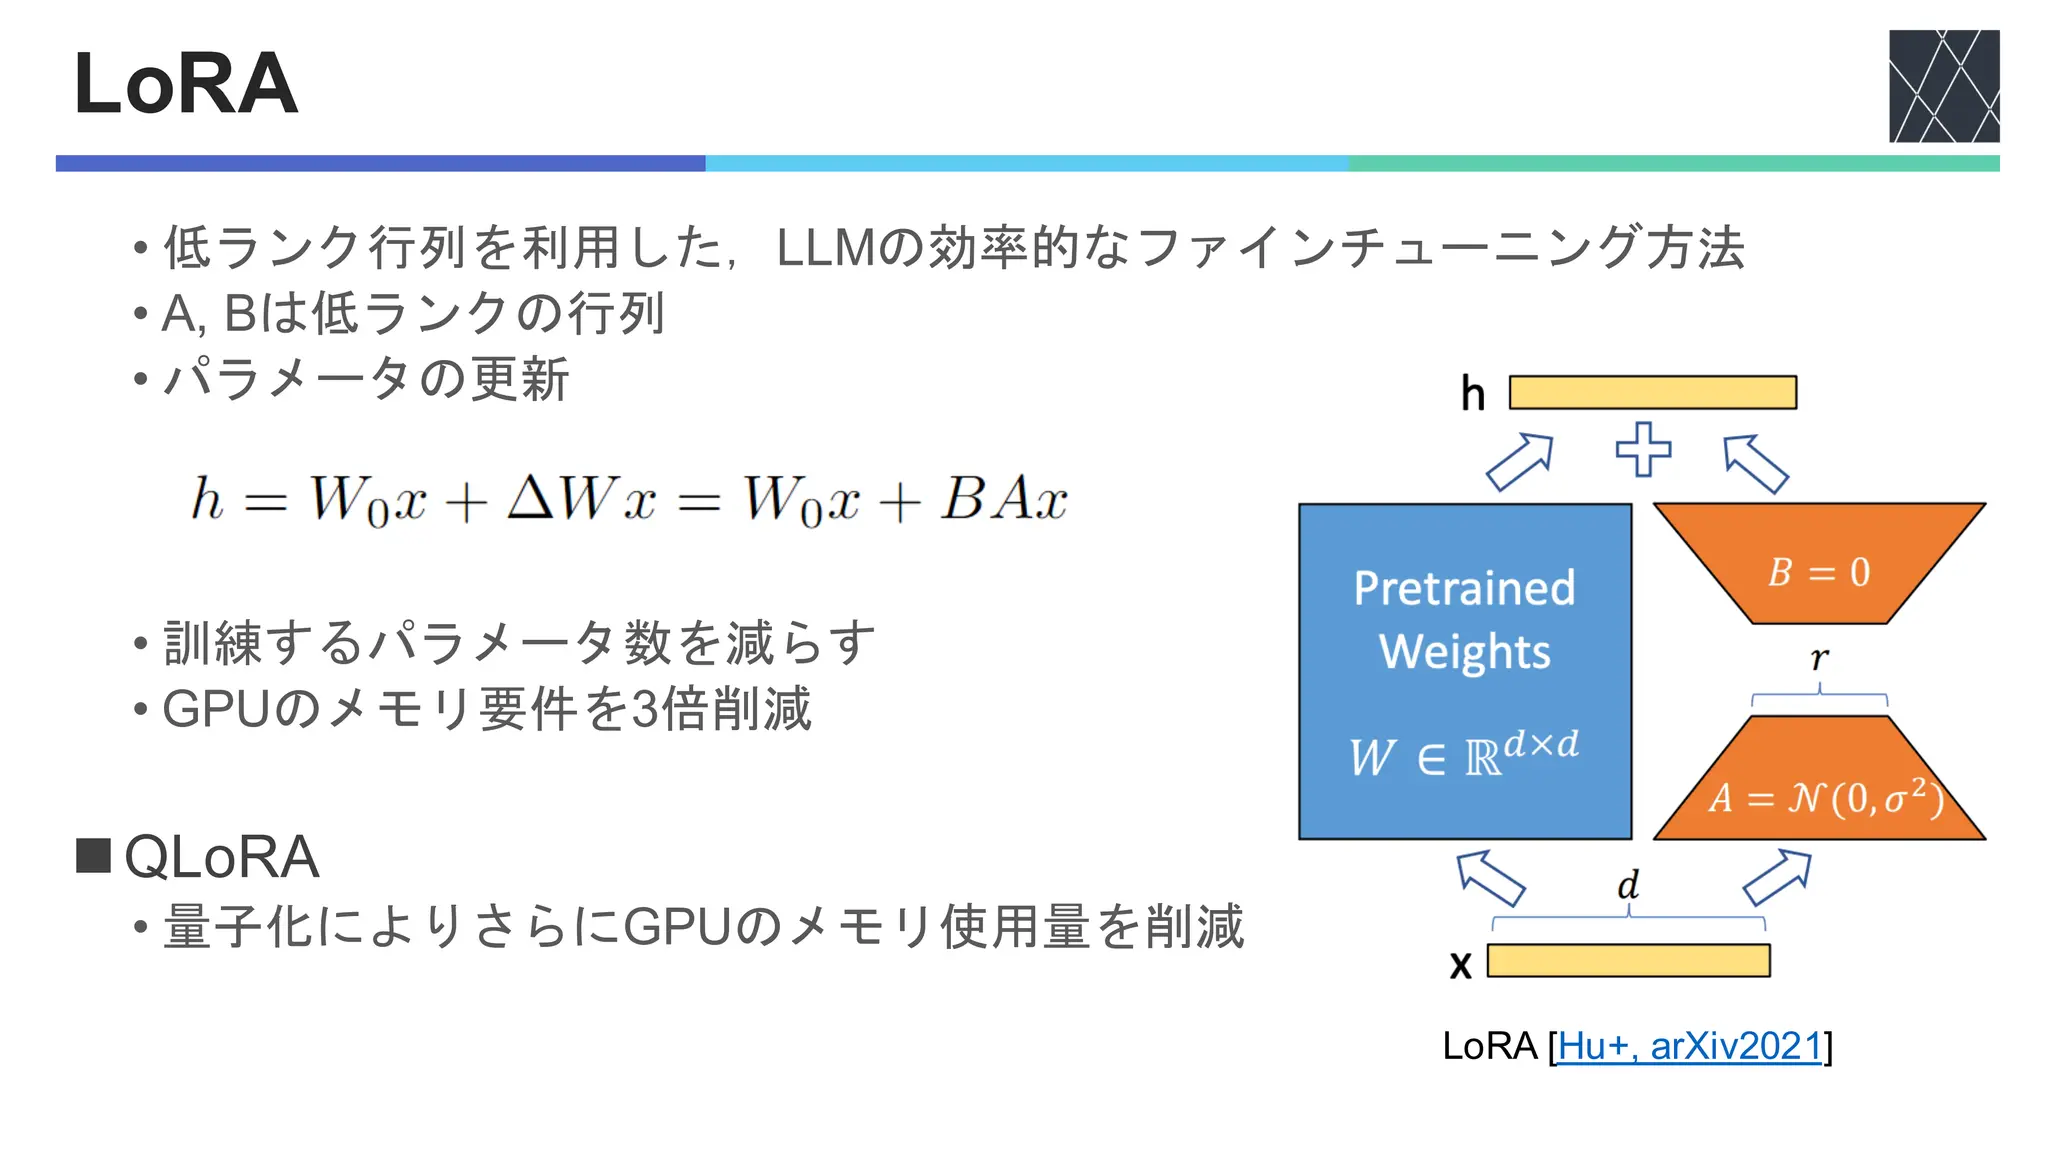
論文紹介:QLoRA: Efficient Finetuning of Quantized LLMs | PDF

QLoRA: Fine-Tuning LLMs Efficiently with 4-bit Precision

(PDF) QLoRA: Efficient Finetuning of Quantized LLMs
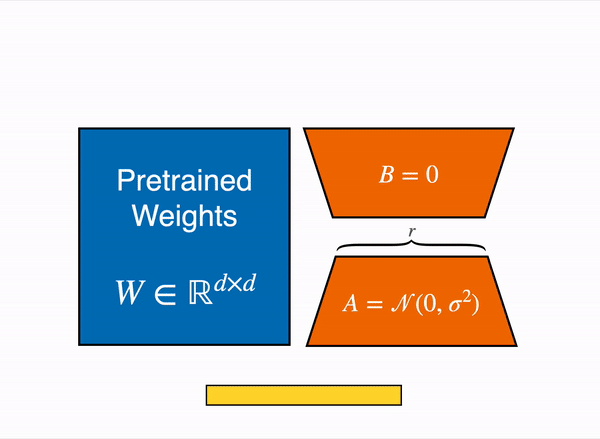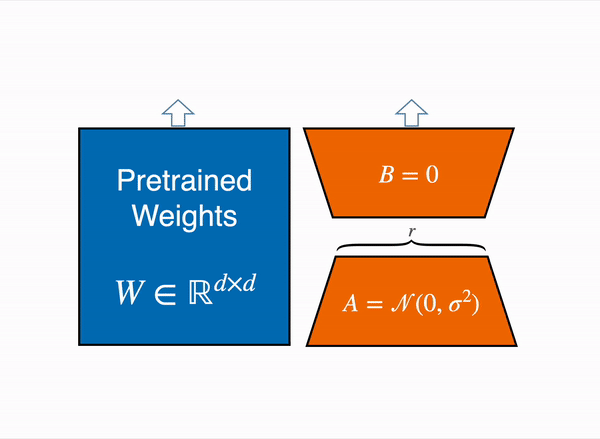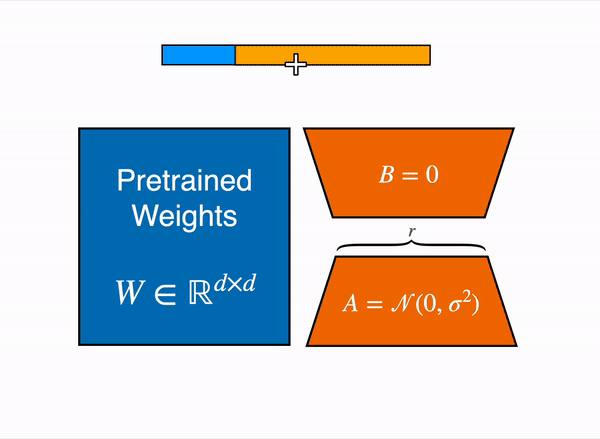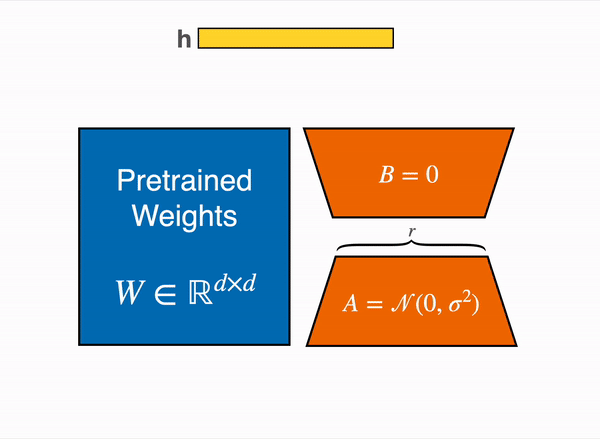
Making LLMs even more accessible with bitsandbytes, 4-bit quantization ...
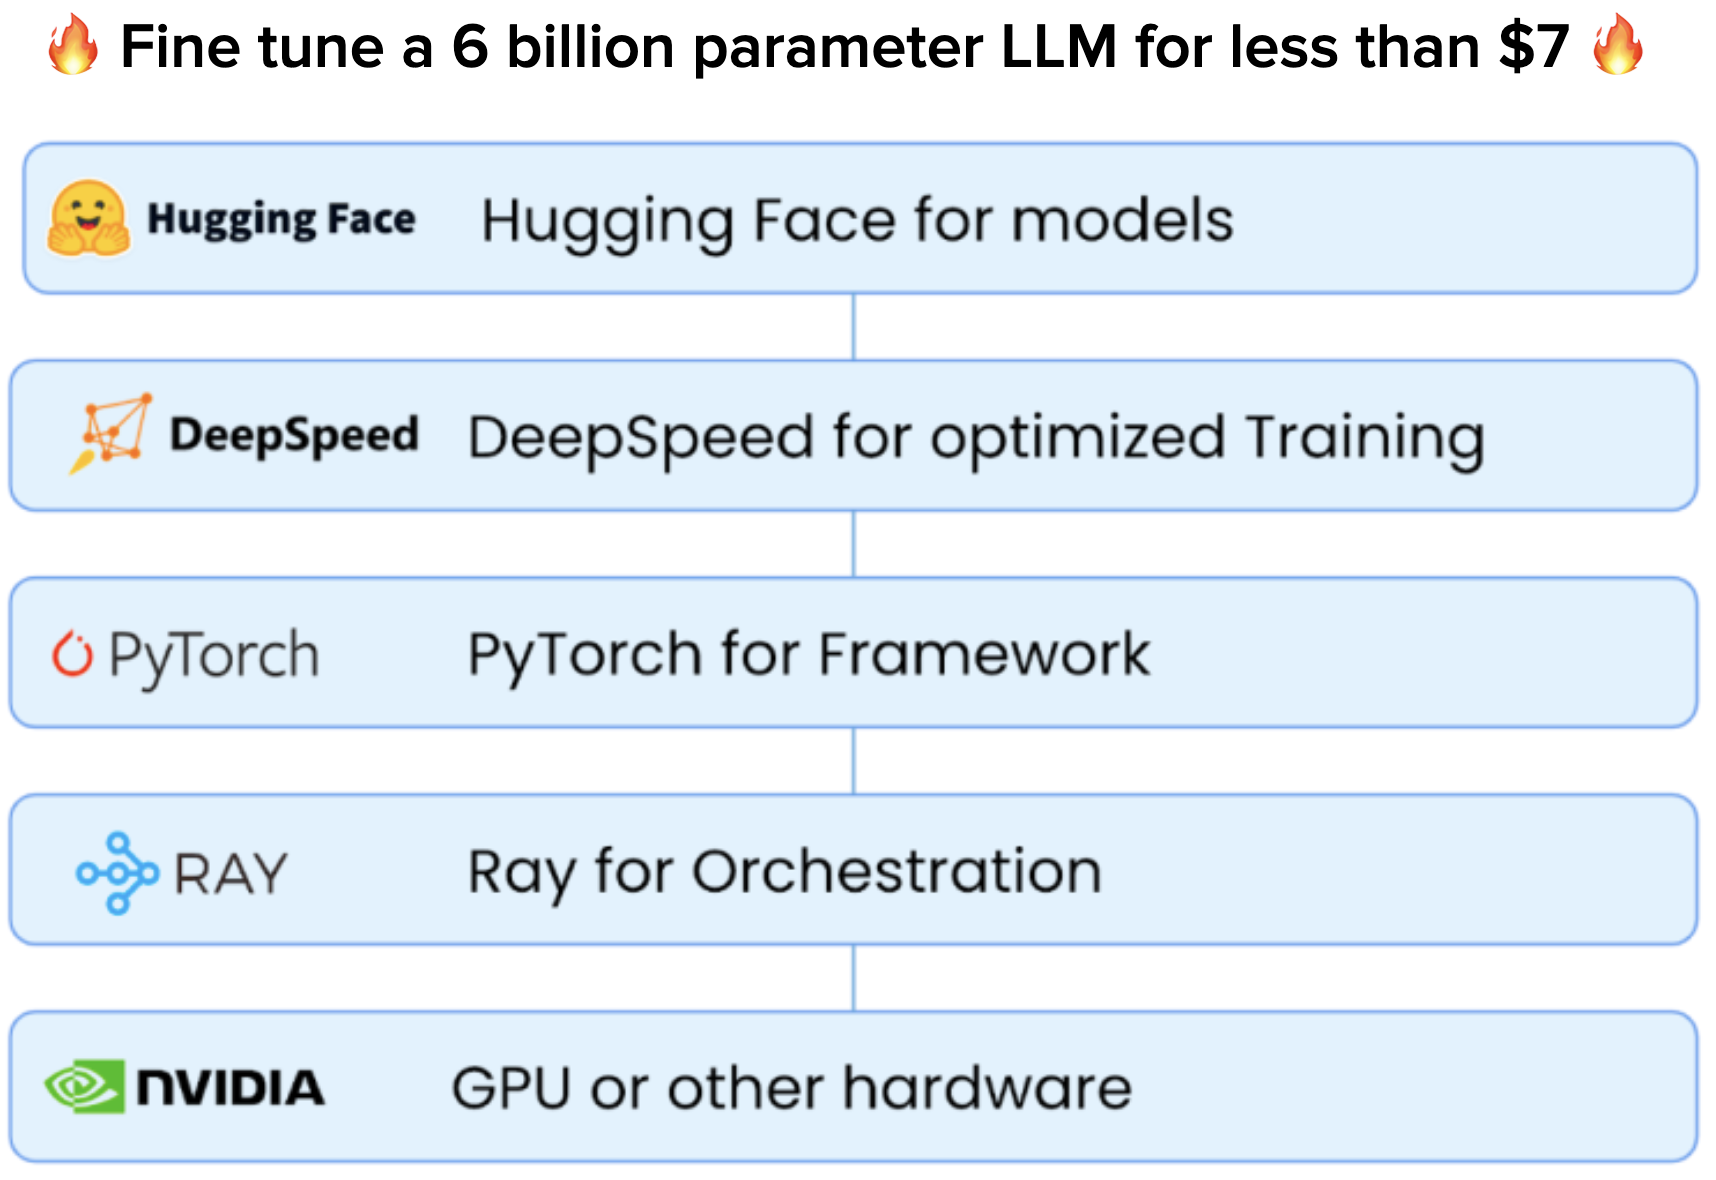
Llmtune: 4-Bit Finetuning Of Llms On A Consumer Gpu – UCIS