
Fix Reward Model Stage Of Llama Training Issue 3975 Hpcaitech
fix reward model stage of llama training · Issue #3975 · hpcaitech ...
[FEATURE]: Load the reward model in Stage 3 training script of ChatGPT ...
[BUG]: The training code of reward model may be wrong · Issue #3490 ...
Out of Memory Issue When Training Llama 2 7B Model with Sequence Length ...
how to speed up llama 2 70b model loading · Issue #5016 · hpcaitech ...
Is there a first pretraining stage model for Llama 7b? · Issue #364 ...
How to train the llama 7B model on two Nvidia 3090 GPUs · hpcaitech ...
3 three steps for training any model? · Issue #1 · hpcaitech ...
[BUG]: FAILED to run RLHF Training Stage1 of ColossalChat for LLaMA 13b ...
Failed to use pipeline parallel on LLAMA model · Issue #3881 ...
Advertisement Space (300x250)
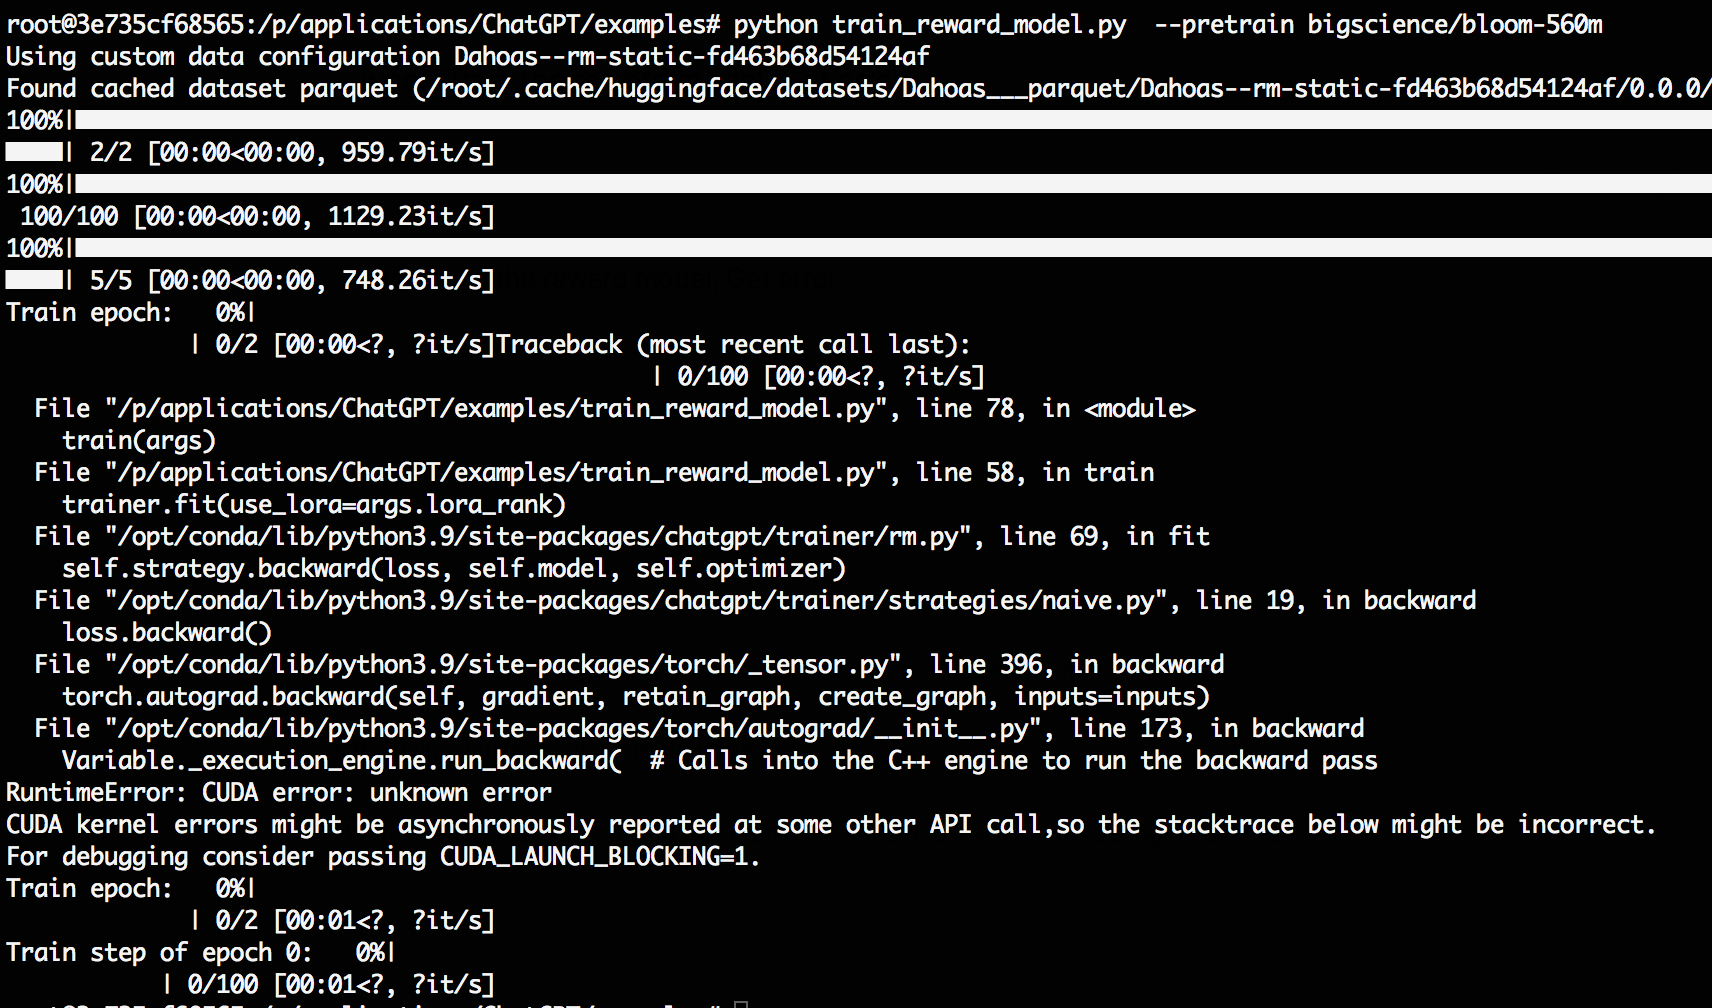
when Train the reward model, Get error · Issue #2818 · hpcaitech ...
[BUG]: Training is slower than DeepSpeed in llama 7B? · Issue #4342 ...
[BUG]: [coati]: llama sft training not fit with other LMs · Issue #3314 ...
FINE-TUNING LLAMA 2: DOMAIN ADAPTATION OF A PRE-TRAINED MODEL | PDF
OOM error during PPO training with Llama 3.2 3B · Issue #742 · OpenRLHF ...
[BUG]: LoRA still does not support the training of reward models ...

Results of pre-training stage 1 · Issue #210 · ymcui/Chinese-LLaMA ...
FINE-TUNING LLAMA 2: DOMAIN ADAPTATION OF A PRE-TRAINED MODEL | PDF
FINE-TUNING LLAMA 2: DOMAIN ADAPTATION OF A PRE-TRAINED MODEL | PDF
[RFC] heterogenous training to extreme model scale · Issue #562 ...
Advertisement Space (336x280)
[FEATURE]: Better optmizer for llm training · Issue #4964 · hpcaitech ...
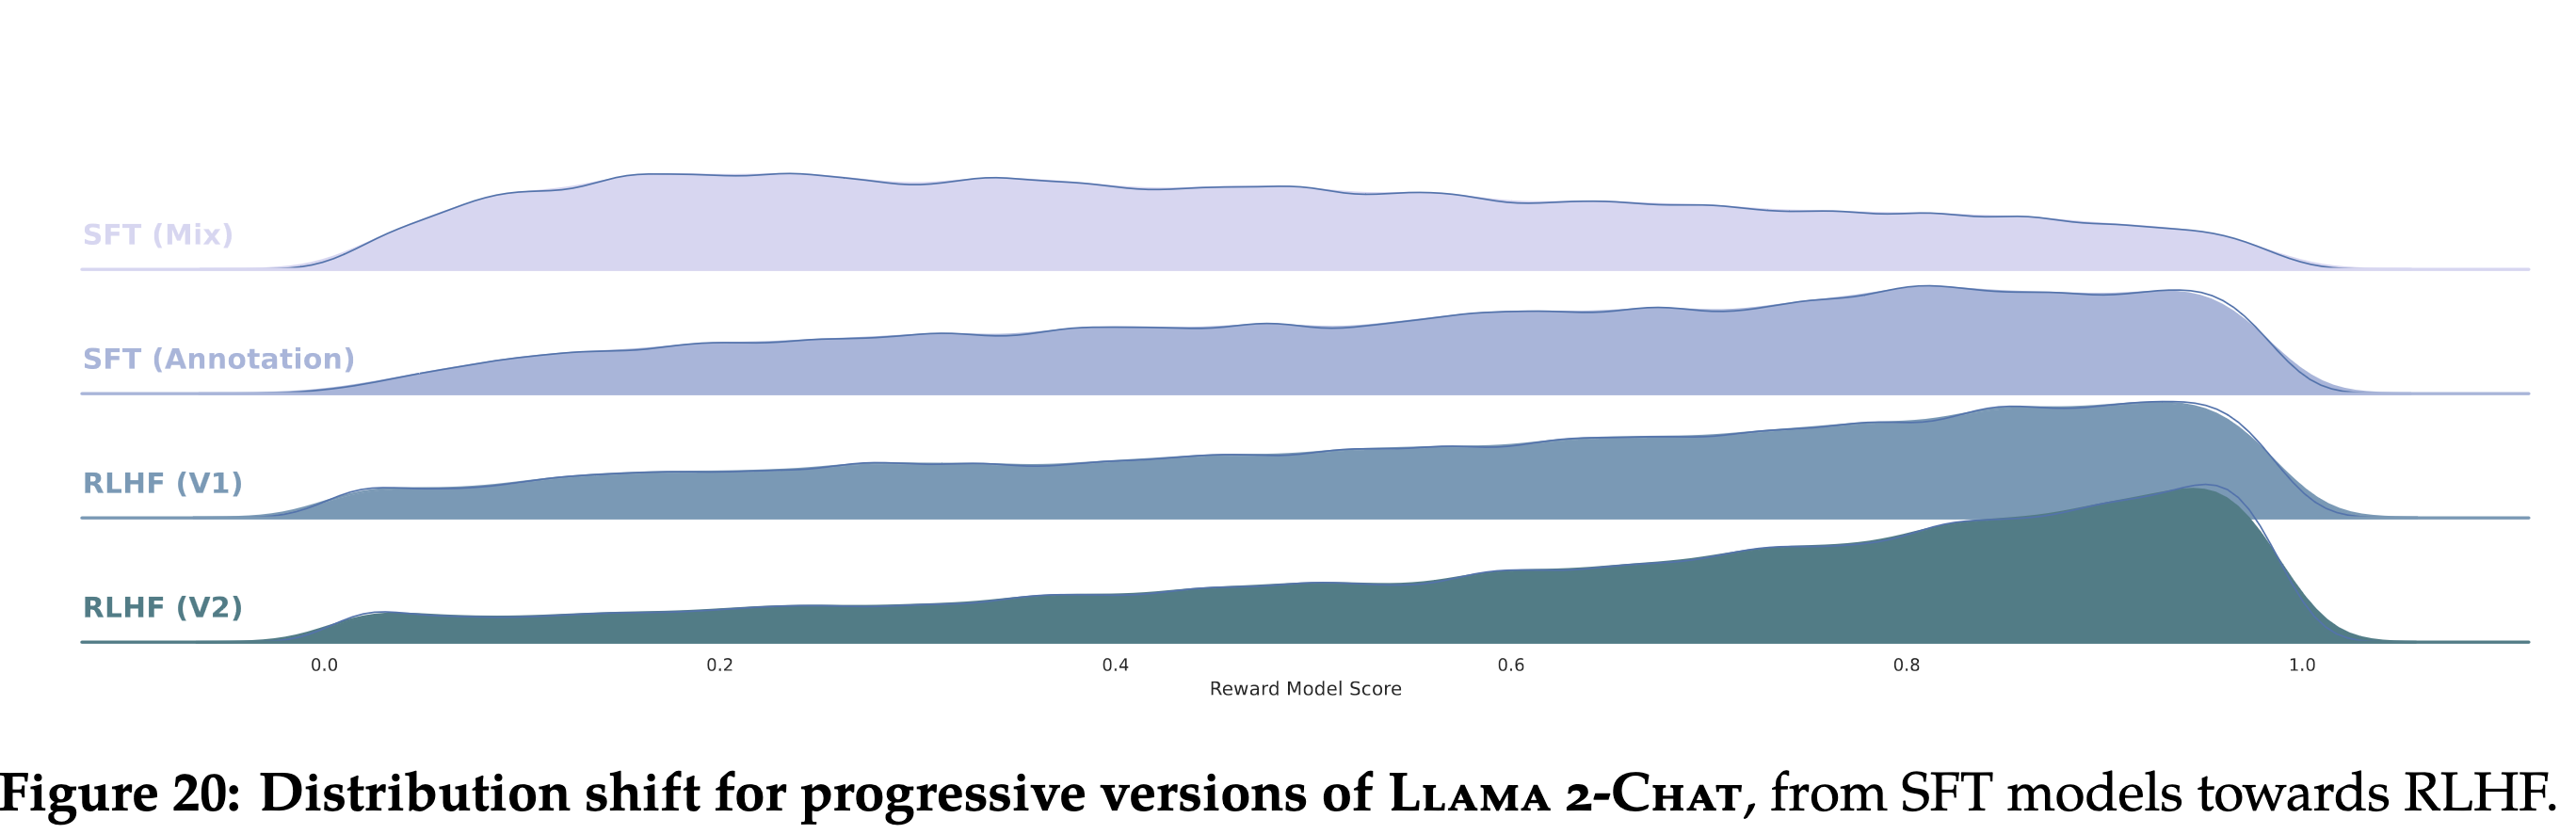
LLAMA 2 Paper and Model Deep Dive — The GenAI Guidebook
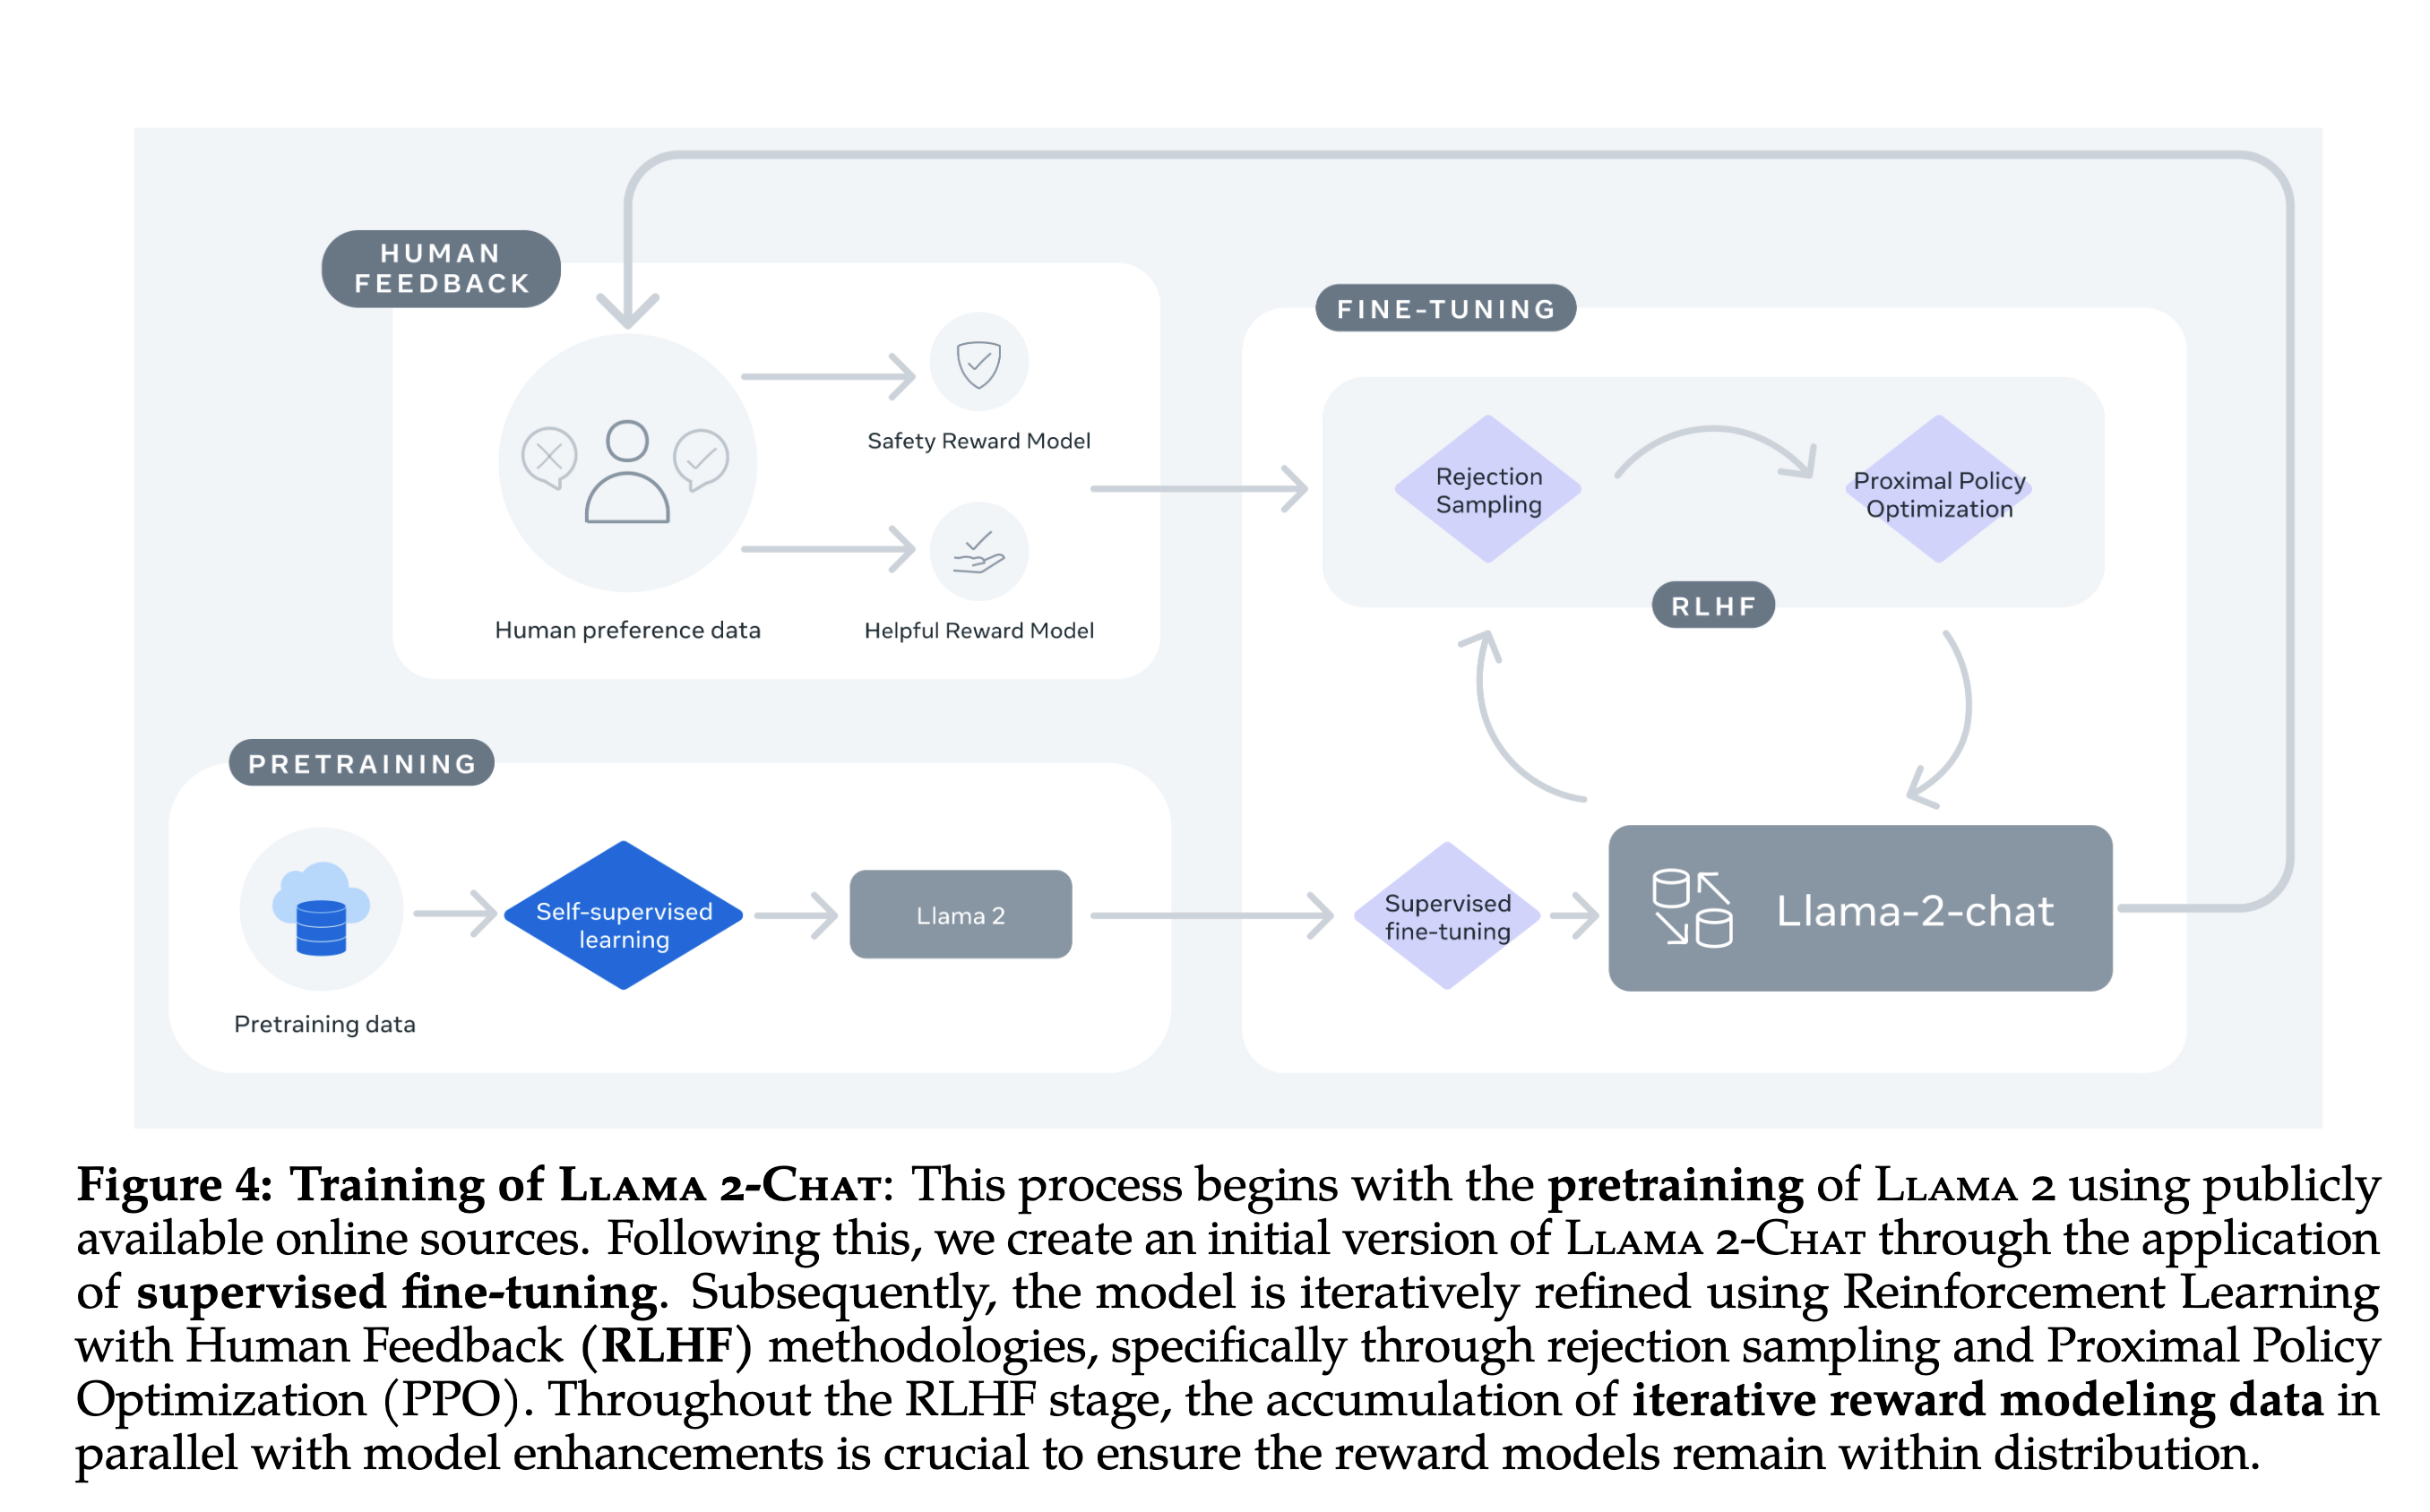
LLAMA 2 Paper and Model Deep Dive — The GenAI Guidebook
![- 70 billion parameter LLaMA3 model training accelerated by 18%[[code ...](https://raw.githubusercontent.com/hpcaitech/public_assets/main/examples/images/LLaMA3-70B-H100.png)
- 70 billion parameter LLaMA3 model training accelerated by 18%[[code ...
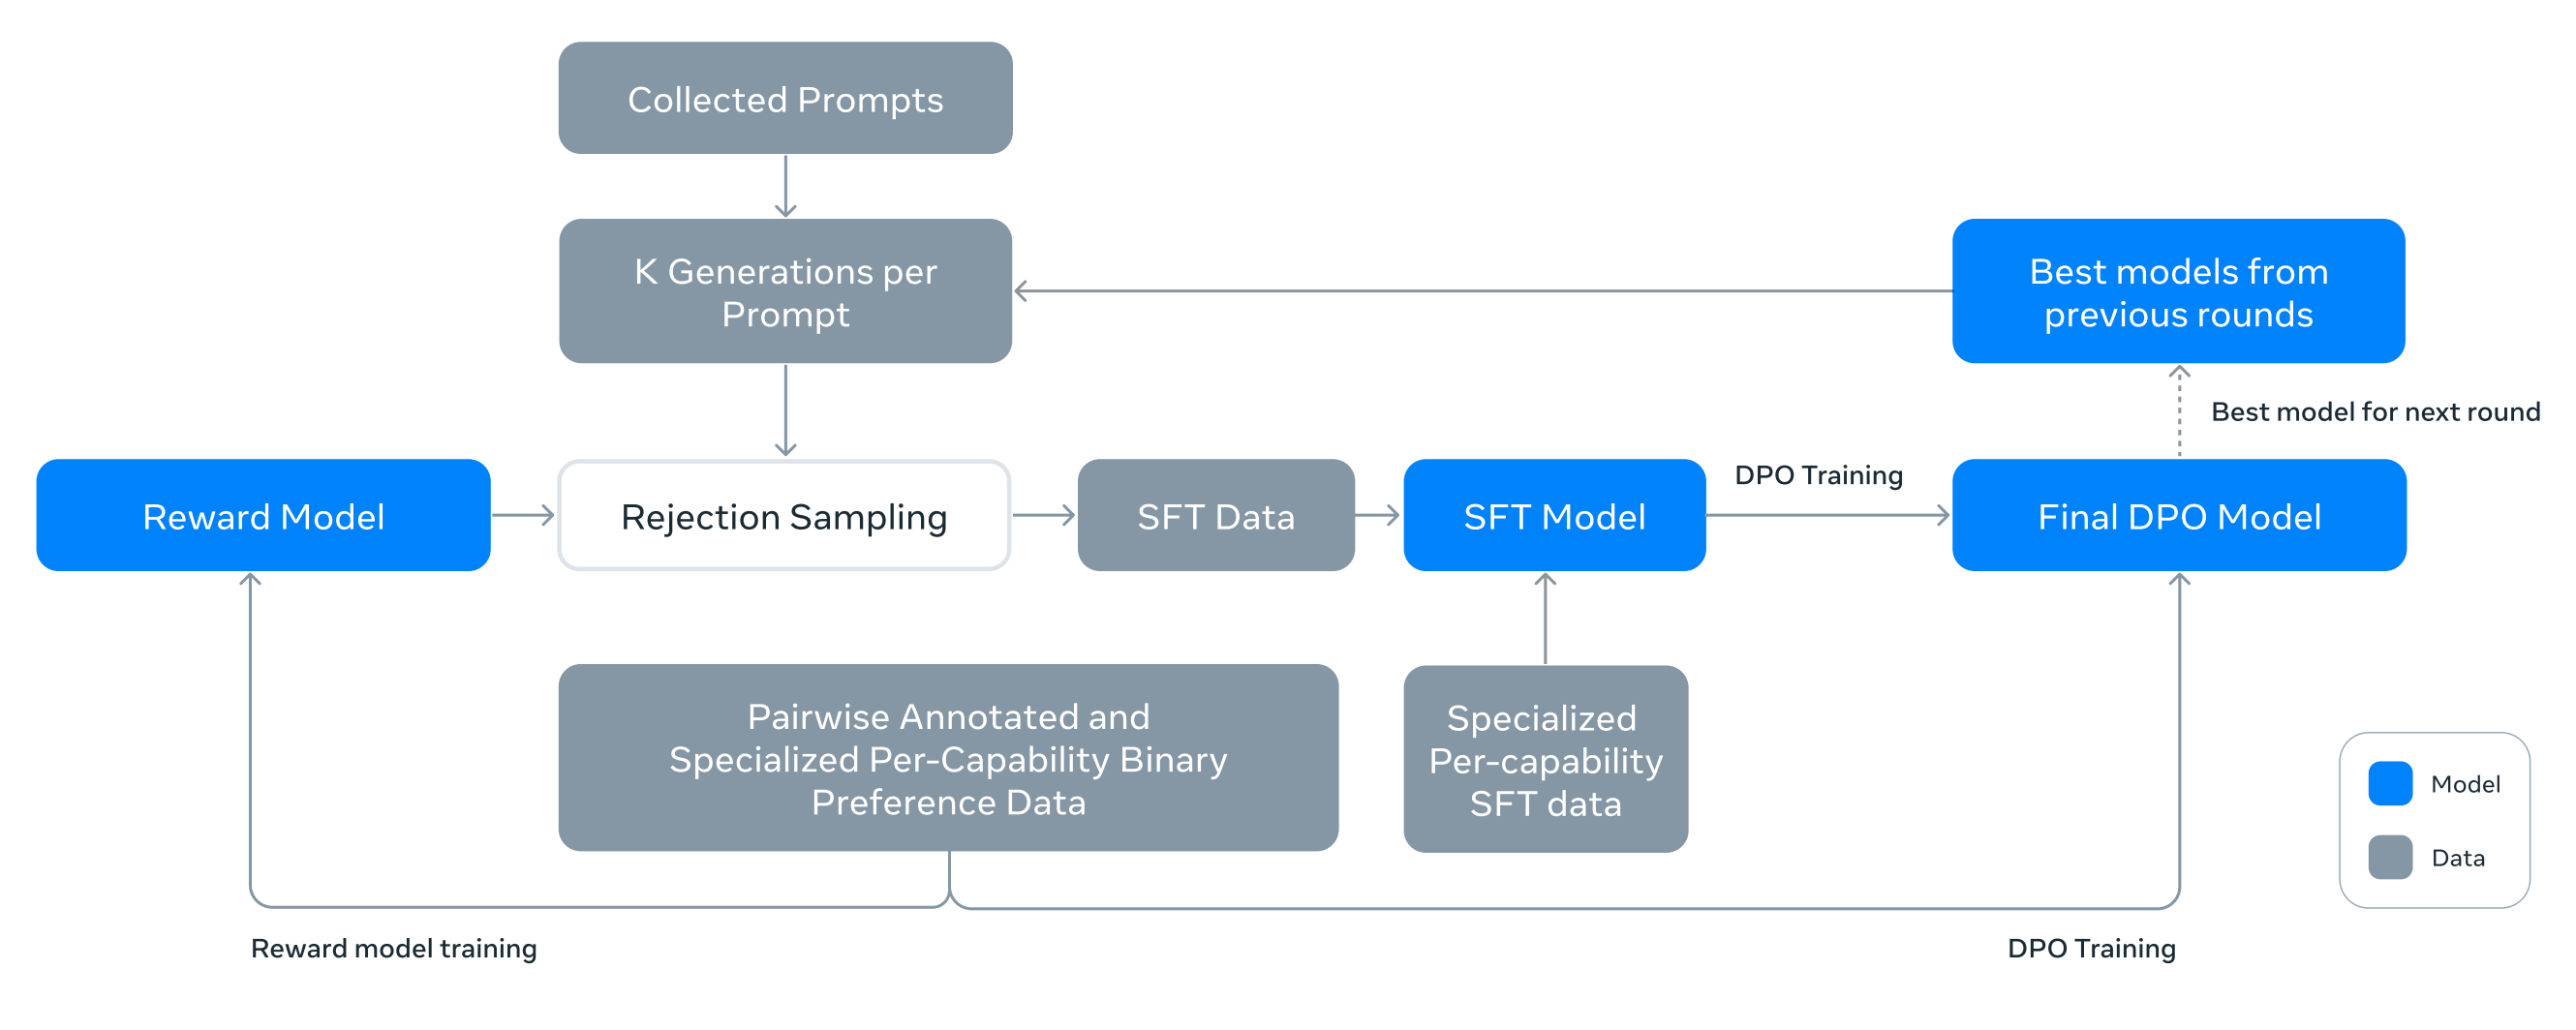
Llama 4: The Challenges of Creating a Frontier-Level LLM
reward model推理速度非常慢 · Issue #7140 · hiyouga/LLaMA-Factory · GitHub
[BUG]: RLHF Training Stage1 of ColossalChat works well on a single GPU ...
[BUG]: The LLama model trained in Lora mode is unable to perform normal ...

Training llama2-7b-chat, is my model overfitting? i think my model is ...
[BUG]: a error occuring when I train the reward model with multi-cards ...
Advertisement Space (336x280)
[Question]: Why is the save training model so big using the peft ...
Download link broken for Llama 3.1-405b-Instruct FP8 · Issue #21 · meta ...
Llama-2-7b-hf model loading · Issue #2005 · lm-sys/FastChat · GitHub

Can not train llama-7b due to OOM on 40GA100 · Issue #3331 · hpcaitech ...
save and load model&optimizer checkpoints for continue training · Issue ...
Incompatibility issues with llama-7b model · Issue #3 · FasterDecoding ...