
Fp16 Output Mismatch Issue 2082 Nvidiatensorrt Github
fp16 output mismatch · Issue #2082 · NVIDIA/TensorRT · GitHub
Output has nan in FP16 mode · Issue #1787 · NVIDIA/TensorRT · GitHub
[QST] INT8 GEMM with FP16 output · Issue #767 · NVIDIA/cutlass · GitHub
fp16 precision failed · Issue #2855 · NVIDIA/TensorRT · GitHub
FP16 weights out of range error · Issue #420 · NVIDIA/TensorRT · GitHub
Cannot use fp16 model · Issue #2087 · NVIDIA/TensorRT · GitHub
Subnormal FP16 value detected · Issue #2186 · NVIDIA/TensorRT · GitHub
How to use FP16 precision in C++ · Issue #1754 · NVIDIA/TensorRT · GitHub
Tensorrt model gives wrong output · Issue #3616 · NVIDIA/TensorRT · GitHub
Int8 mode is slower than fp16 · Issue #993 · NVIDIA/TensorRT · GitHub
Advertisement Space (300x250)
question about fp16 · Issue #241 · NVIDIA/pix2pixHD · GitHub
bert model fp16 returns nan · Issue #2118 · NVIDIA/TensorRT · GitHub
FP16 error in multi gpu · Issue #2312 · open-mmlab/mmdetection · GitHub
Error in processing fp16 data · Issue #21872 · opencv/opencv · GitHub

I got wrong output when fp16_mode is True · Issue #395 · NVIDIA-AI-IOT ...
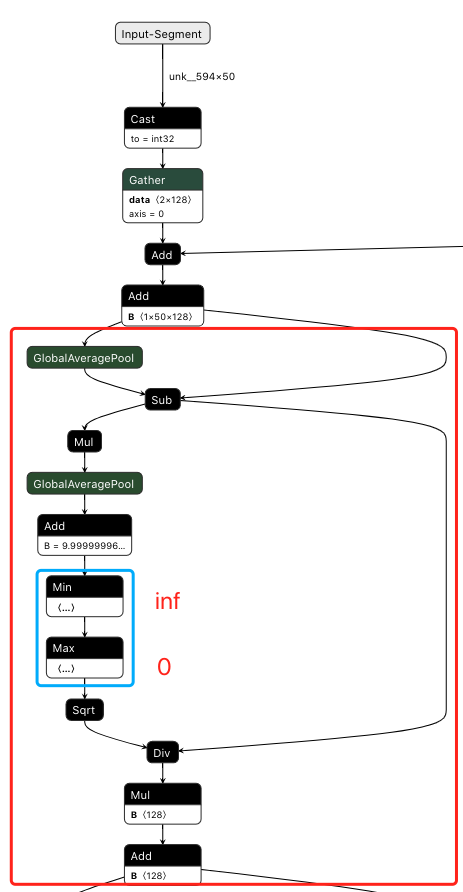
Roberta fp16 got wrong inference results · Issue #2466 · NVIDIA ...
CPP FP16 inference result does not matched to python api? · Issue #473 ...
Instance normalization with FP16 has large errors · Issue #776 · NVIDIA ...
fp16 mismatch----layernorm overflow · Issue #2564 · NVIDIA/TensorRT ...
Marginal Improvement Between INT8 and FP16 · Issue #2843 · NVIDIA ...
Advertisement Space (336x280)
No speedup between fp16 and int8 precisions · Issue #2197 · NVIDIA ...
Inference yolov5 fp16 engine in c++ get nan output but inference fp32 ...
Can't avoid fp16 conversion of an onnx node · Issue #2899 · NVIDIA ...
Roberta fp16 got wrong inference results · Issue #2466 · NVIDIA ...
tesla P40 does not support FP16? · Issue #56 · NVIDIA/TensorRT · GitHub
why builder.fp16_mode is useless · Issue #1252 · NVIDIA/TensorRT · GitHub
The fp16 inference of pytorch swintransformer op got `nan` output ...
NaN values with FP16 TensorRT Inference · Issue #116 · mit-han-lab ...
EfficientNMS plugin doesn't support fp16 · Issue #1758 · NVIDIA ...
FP16 quantization does not seem to work well · Issue #520 · NVIDIA-AI ...
Advertisement Space (336x280)
How to convert the output tensor from FP16 to FP32 w/ ov 2.0 C++ API ...
fp16 mode takes much more time than fp32 · Issue #572 · NVIDIA/TensorRT ...
FasterTransformer failed to run FP16 mode on Tesla P100 · Issue #601 ...
[Bug] Tensorrt output incorrect with batch inference · Issue #2808 ...
Does it Work on FP16 with latest nvidia amp? · Issue #36 ...

Quantization FP16 model using pytorch_quantization and TensorRT · Issue ...