
Fp8 Example Llm Compressor Docs

FP8 Example - LLM Compressor Docs

module - LLM Compressor Docs

utils - LLM Compressor Docs
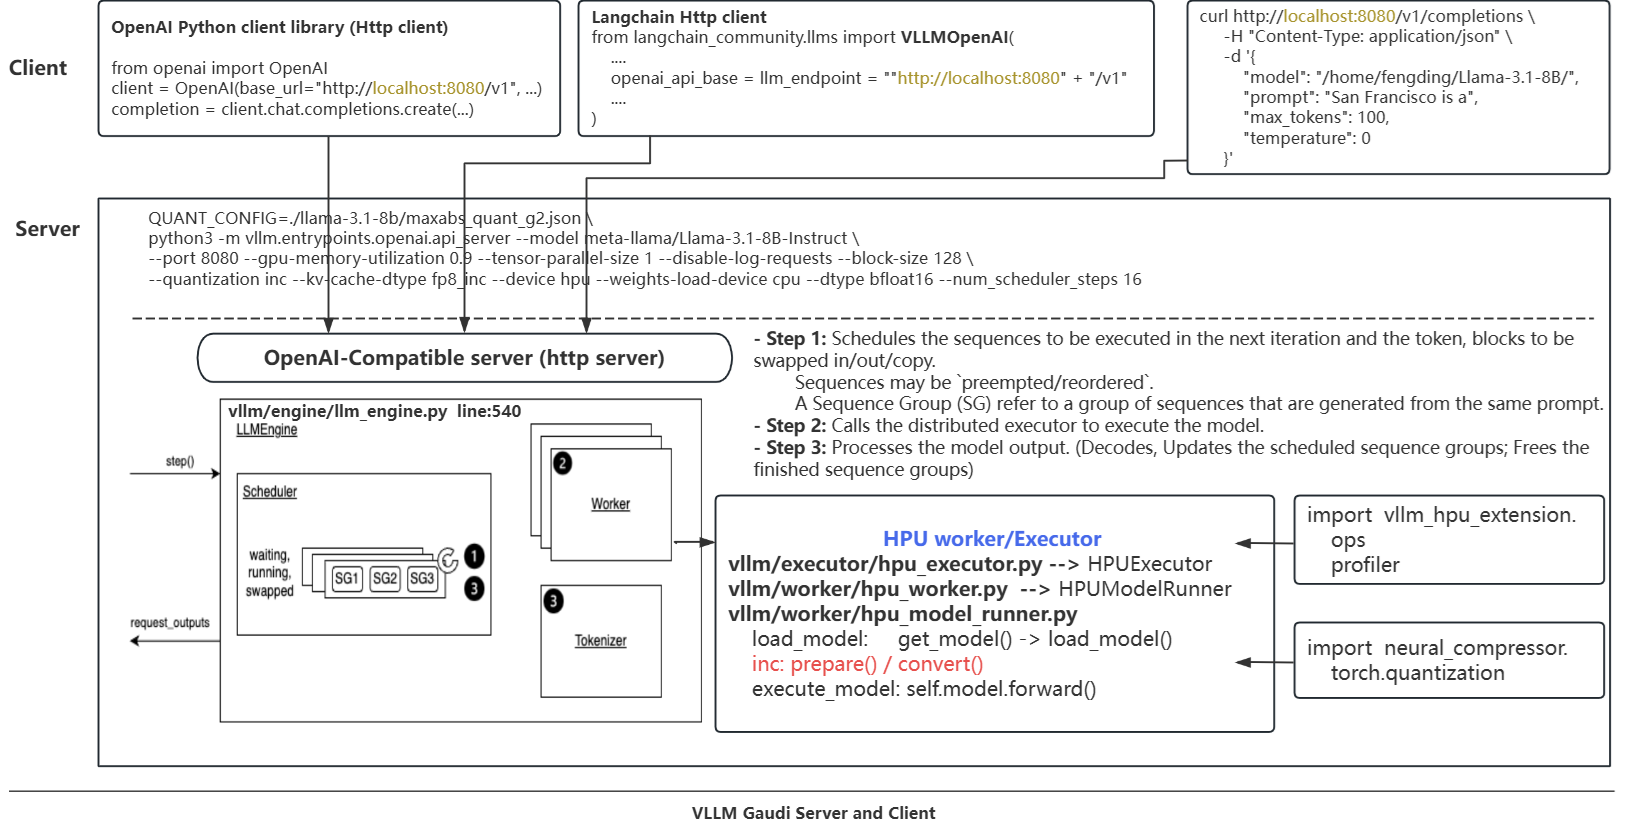
FP8 Quantization — Intel® Neural Compressor 3.2 documentation
FP8 Quantization — Intel® Neural Compressor 3.2 documentation
FP8 Quantization — Intel® Neural Compressor 3.8 documentation

Towards Fully FP8 GEMM LLM Training at Scale | AI Research Paper Details

[2502.01070] An Investigation of FP8 Across Accelerators for LLM Inference

How FP8 boosts LLM training by 18% on Amazon SageMaker P5 instances ...

How FP8 boosts LLM training by 18% on Amazon SageMaker P5 instances ...
Advertisement Space (300x250)

[논문 리뷰] Towards Fully FP8 GEMM LLM Training at Scale

LLM Compressor: Optimize LLMs for low-latency deployments | Red Hat ...
vLLM brings FP8 inference to the open source community | Red Hat Developer
FP8-RL: A Practical and Stable Low-Precision Stack for LLM ...
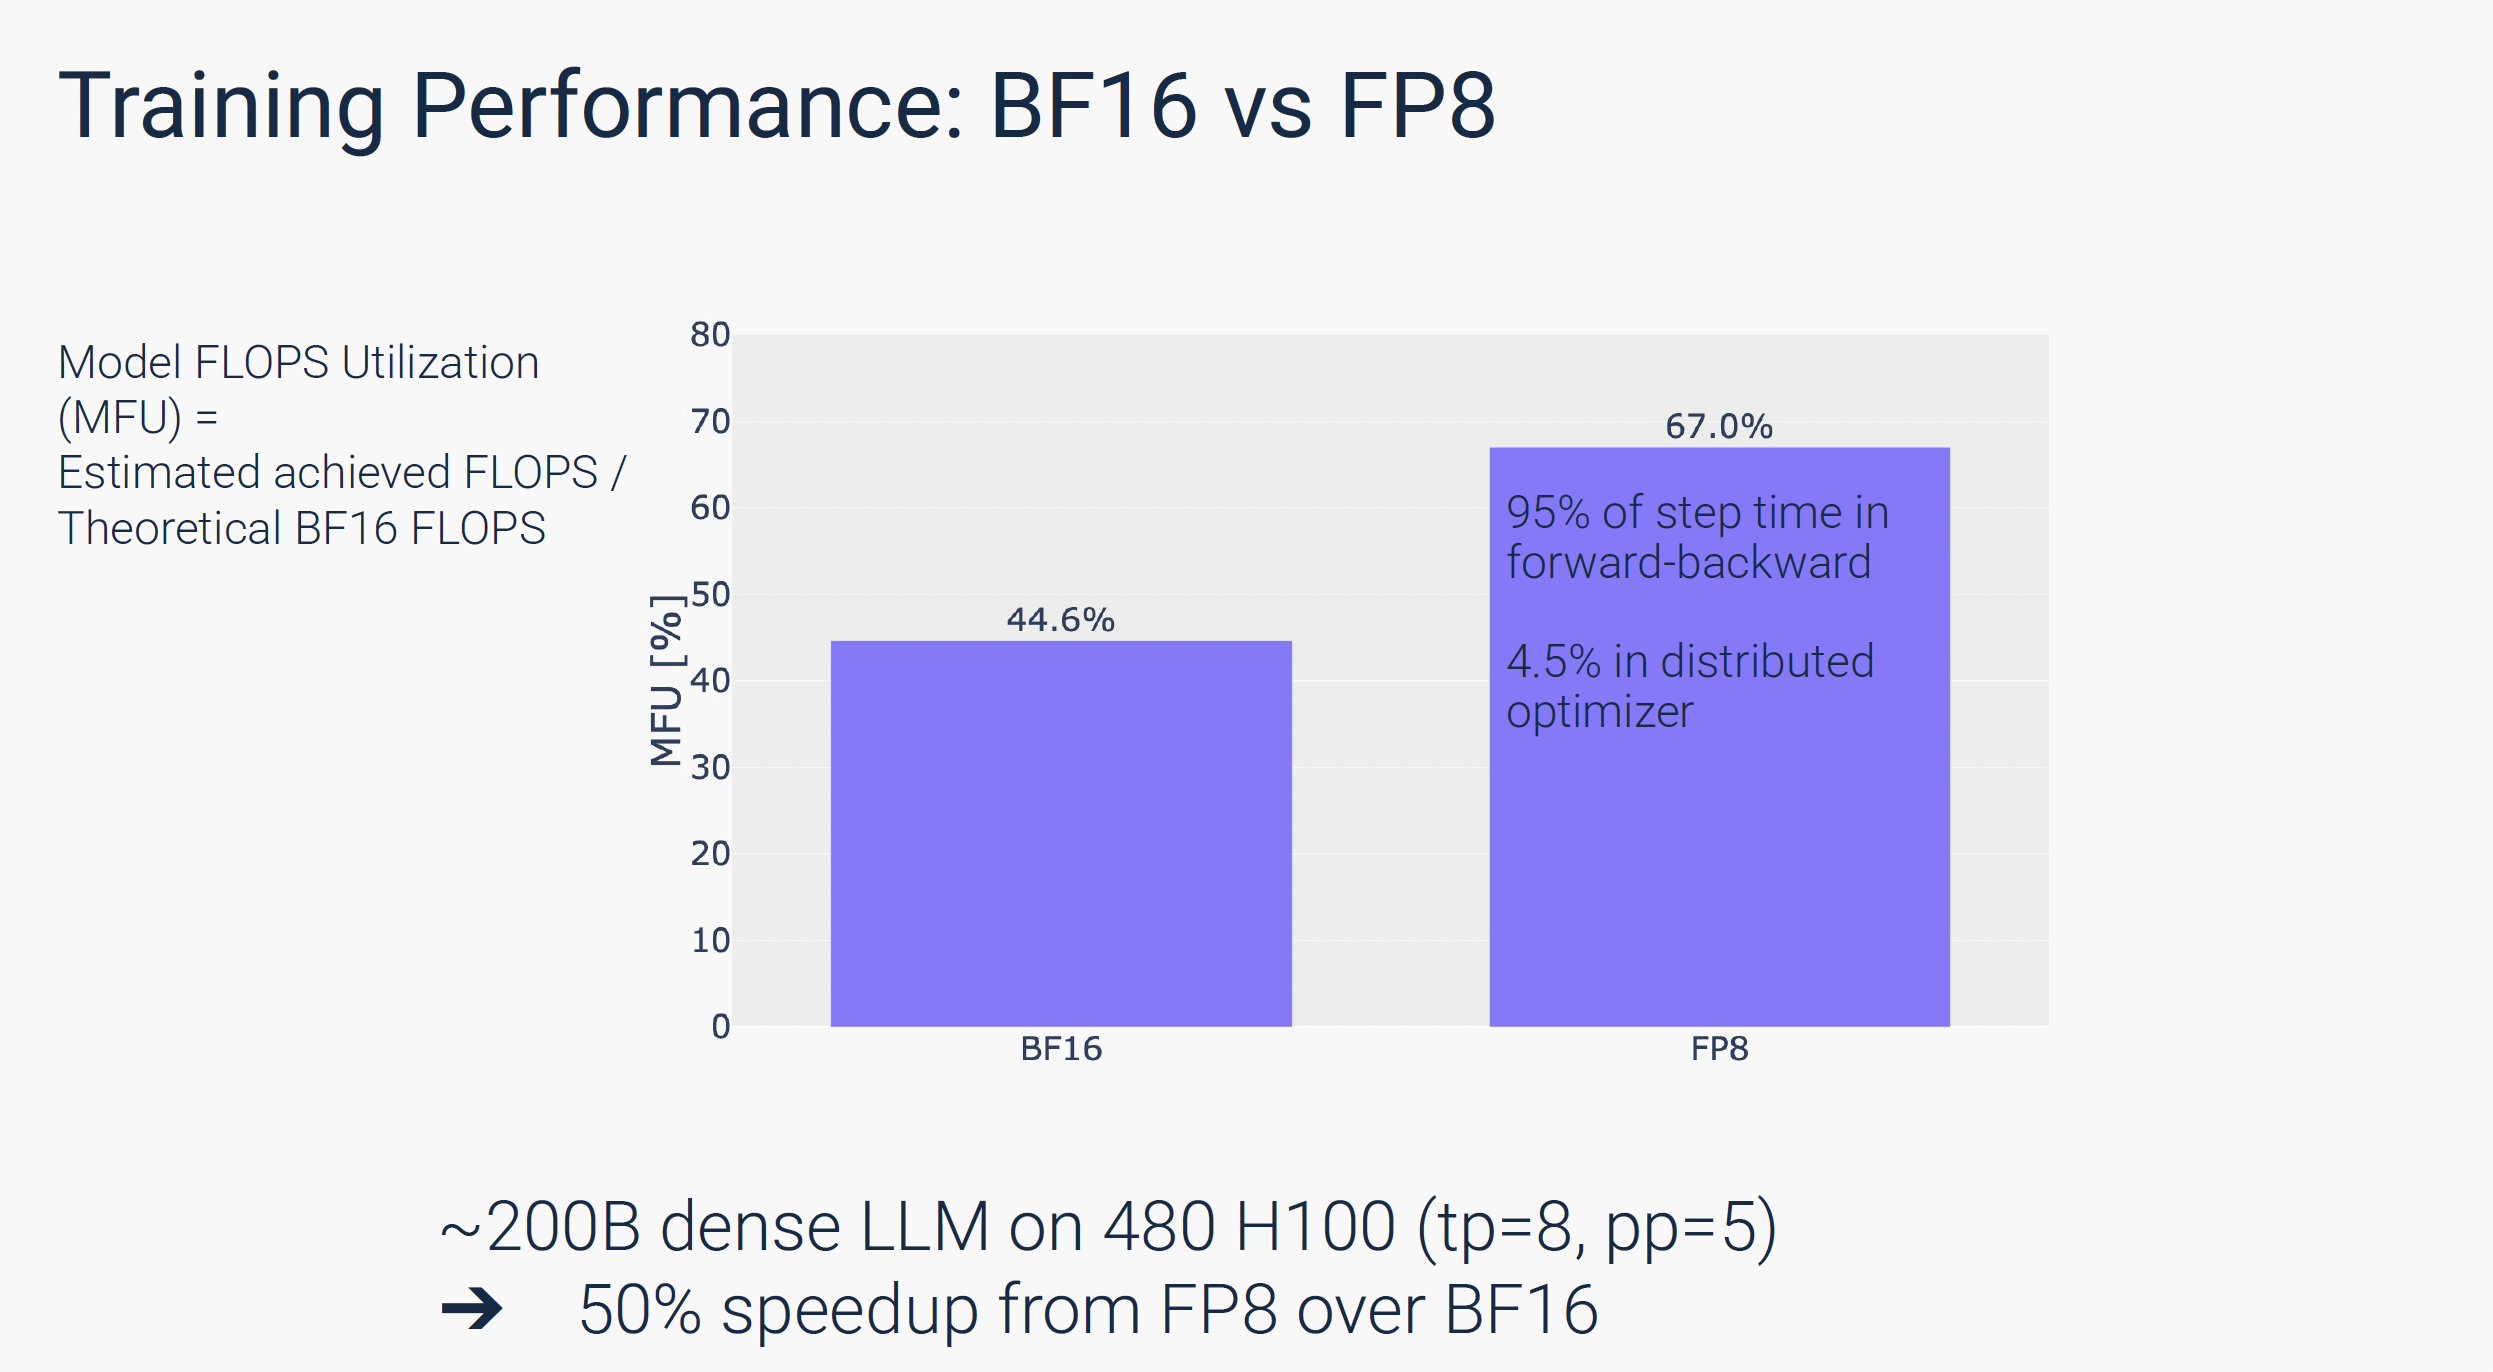
How we built DeepL’s next-generation LLMs with FP8 for training and ...
FP8 Quantization | intel/neural-compressor | DeepWiki

如何使用 FP8 加速大模型训练 - NVIDIA 技术博客

How we built DeepL’s next-generation LLMs with FP8 for training and ...
Let's talk about FP8 W8A8 · Issue #1525 · vllm-project/llm-compressor ...
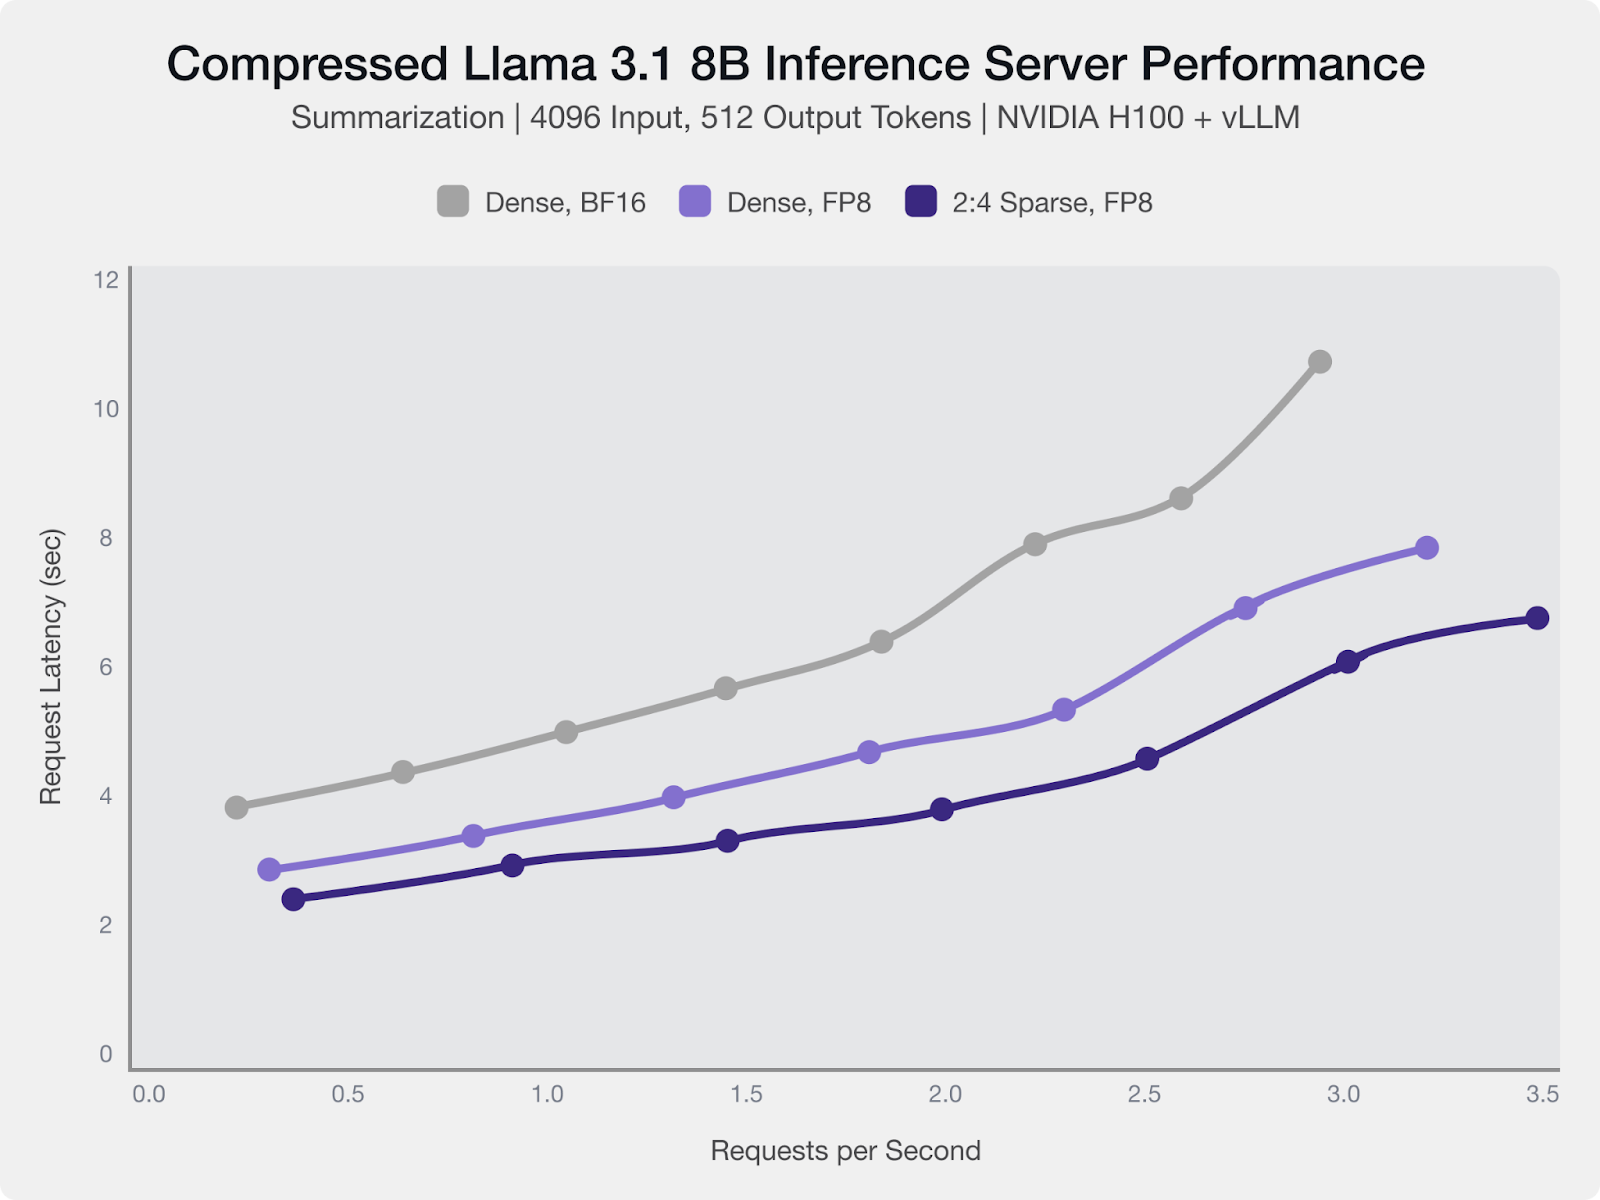
Axolotl meets LLM Compressor: Fast, sparse, open | Red Hat Developer
Advertisement Space (336x280)

如何使用 FP8 加速大模型训练 - NVIDIA 技术博客
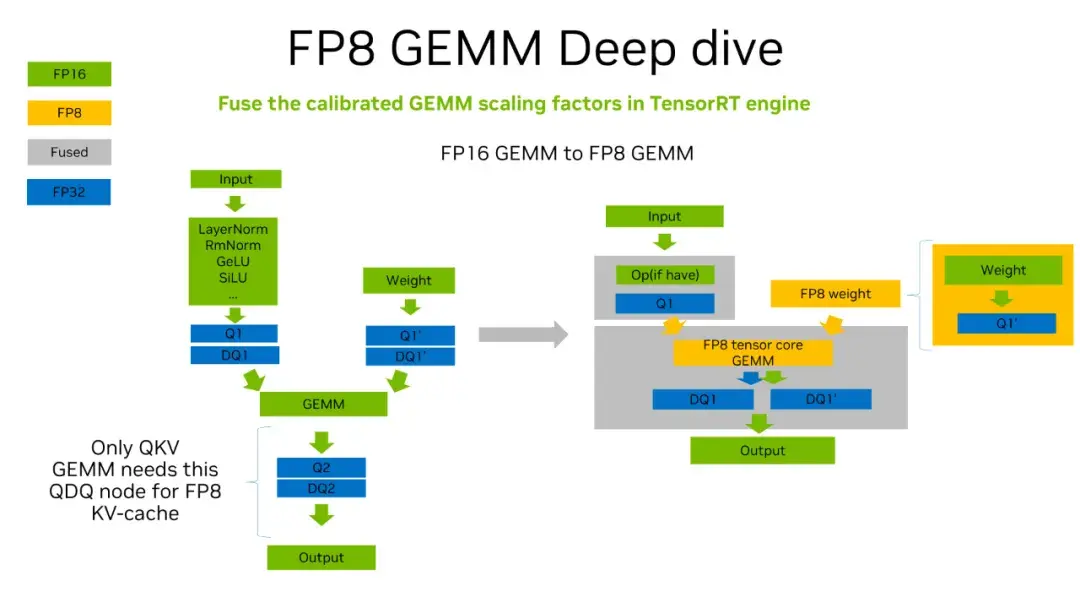
TensorRT-LLM 低精度推理优化:从速度和精度角度的 FP8 vs INT8 的全面解析 - 知乎
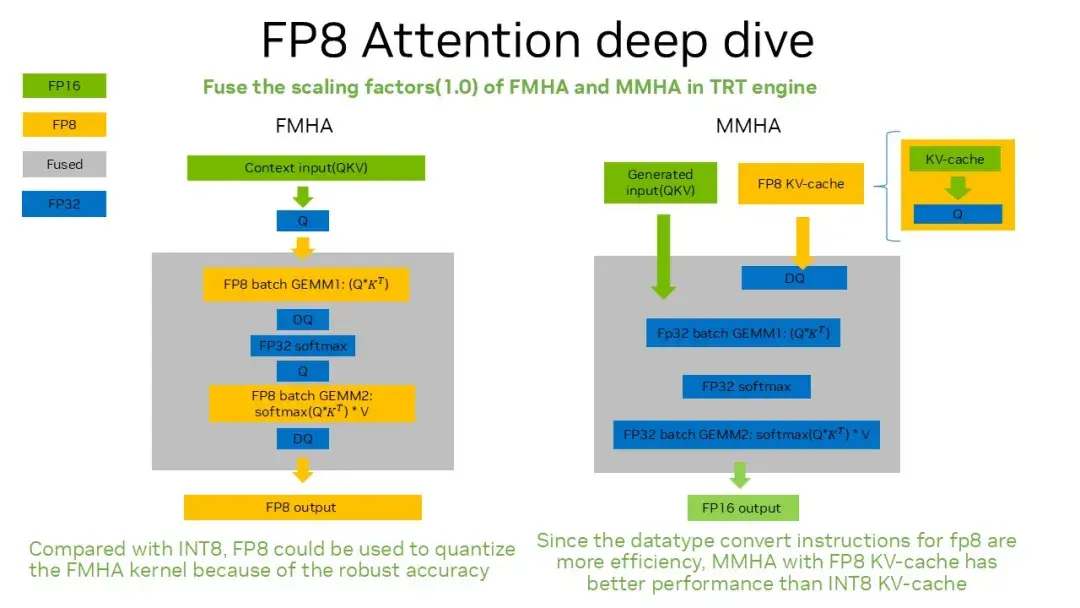
TensorRT-LLM 低精度推理优化:从速度和精度角度的 FP8 vs INT8 的全面解析 - 知乎
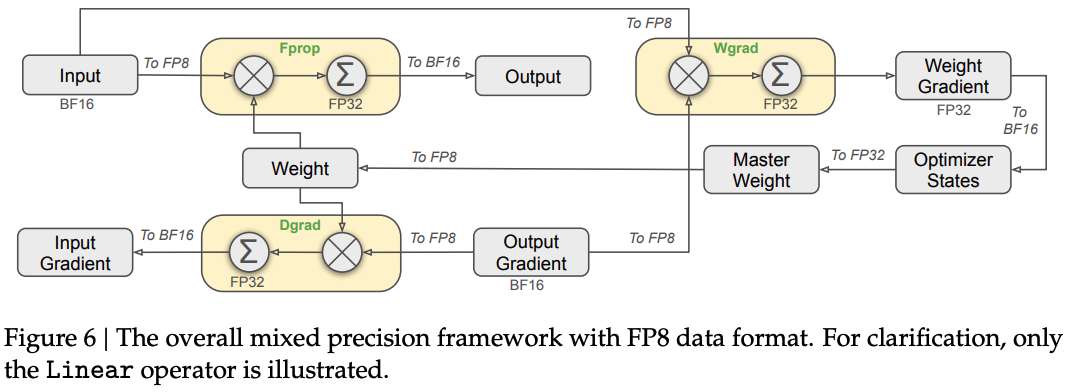
Building and Aligning a Dialogue LLM with User Data and RL | Building ...
GitHub - intel/neural-compressor: SOTA low-bit LLM quantization (INT8 ...

TensorRT-LLM 低精度推理优化:从速度和精度角度的 FP8 vs INT8 的全面解析 - NVIDIA 技术博客
llm-compressor/examples/compressed_inference/fp8_compressed_inference ...
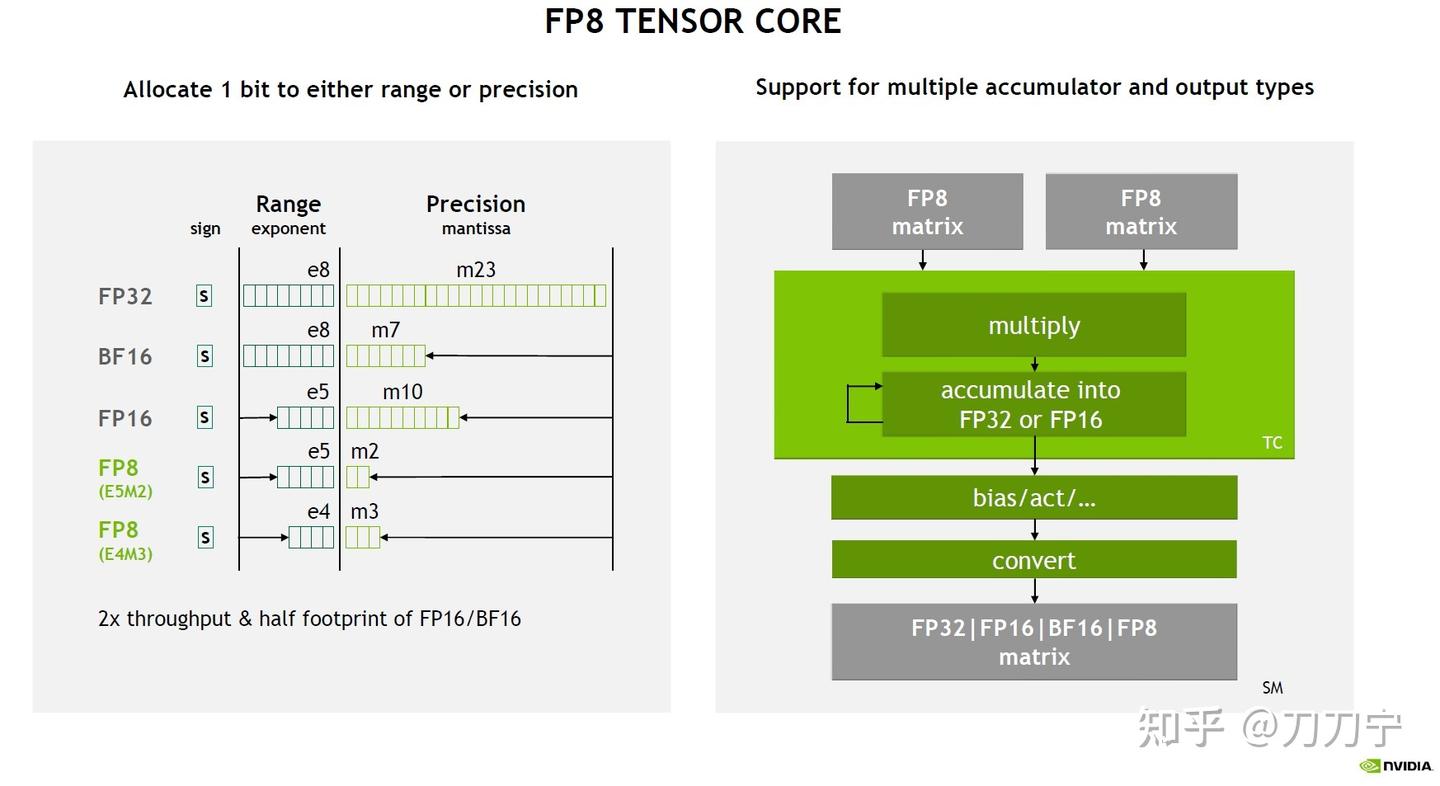
量化那些事之FP8与LLM-FP4 - 知乎
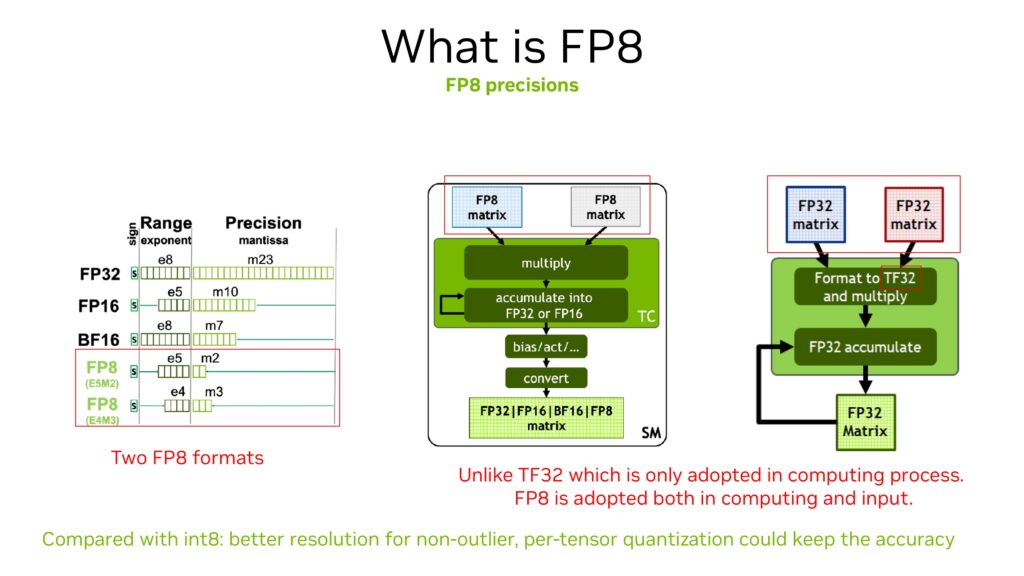
TensorRT-LLM 低精度推理优化:从速度和精度角度的FP8 vs Int8 的全面解析_fp8 int8-CSDN博客
github- llm-compressor :Features,Alternatives | Toolerific
Advertisement Space (336x280)
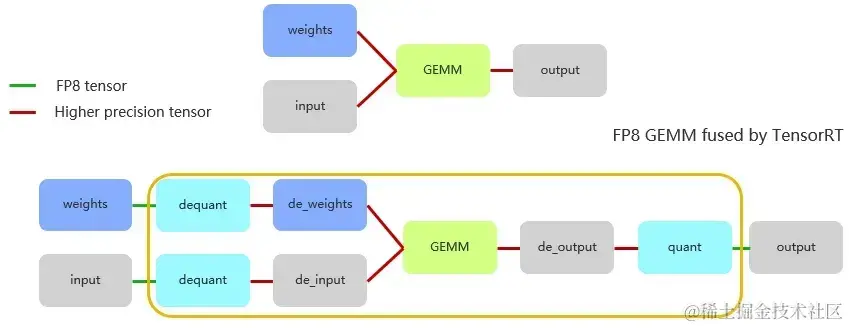
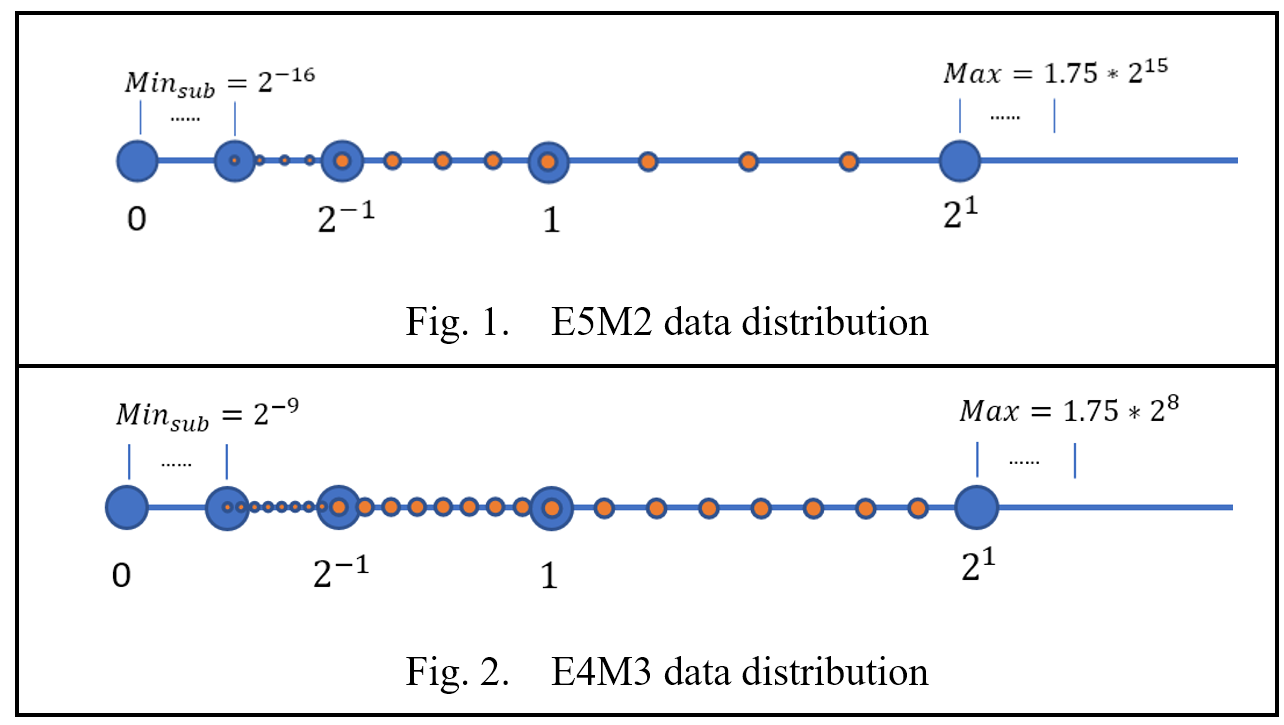
大模型量化技术原理:FP8_e4m3-CSDN博客
Examples & Tutorials | vllm-project/llm-compressor | DeepWiki
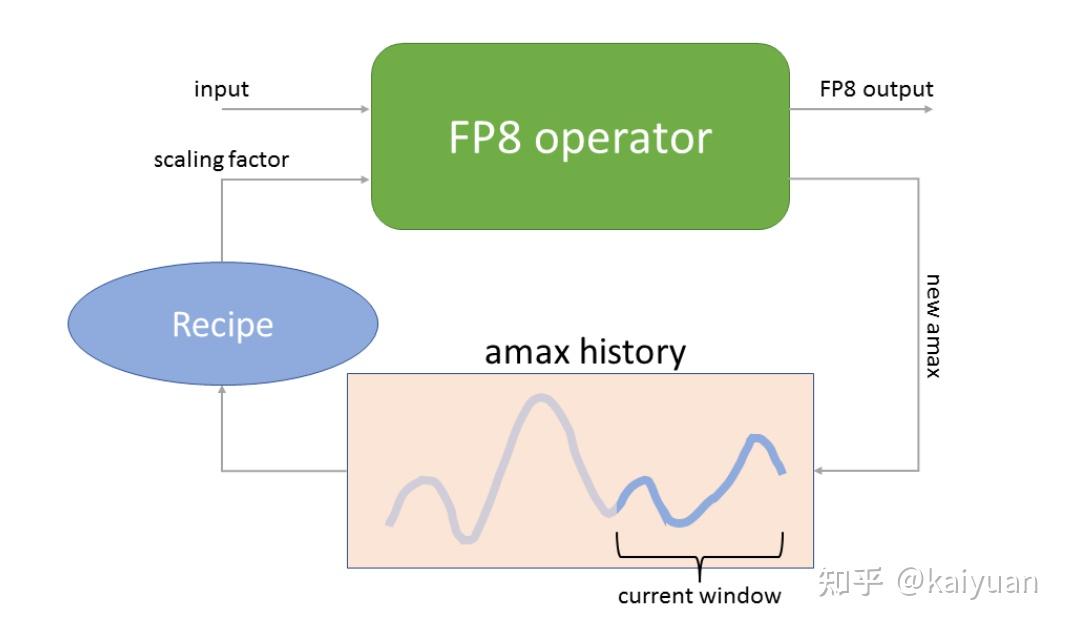
[LLM]FP8计算在模型训练中的应用 - 知乎
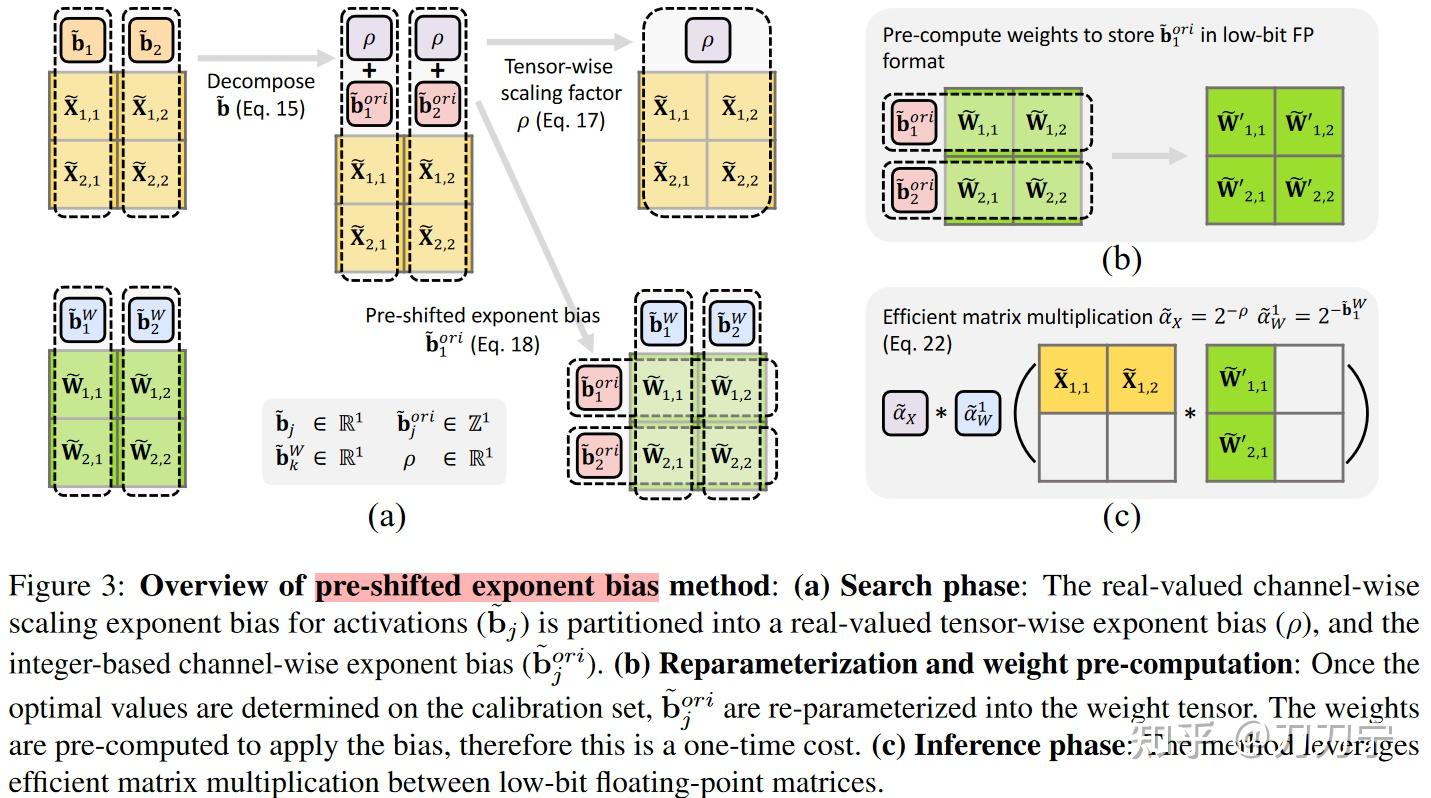
量化那些事之FP8与LLM-FP4 - 知乎
w8a8_fp8 quantization · Issue #958 · vllm-project/llm-compressor · GitHub
Model Compression with LLM-Compressor and Deployment on Vast.ai (Part 1)