
Fused Attention Kernel Issue 3280 Nvidiatensorrt Github
fused attention kernel · Issue #3280 · NVIDIA/TensorRT · GitHub
Print values inside fused attention kernel · Issue #612 · triton-lang ...
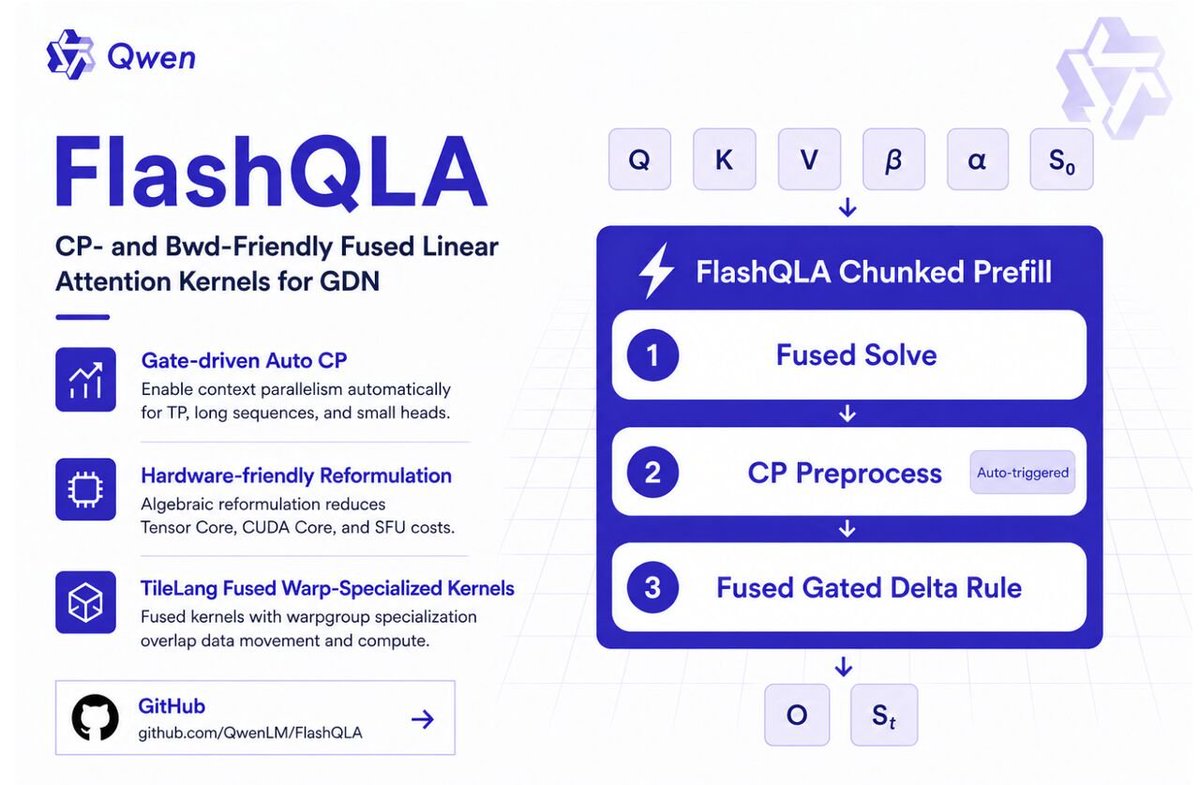
Qwen Team released FlashQLA: a fused linear attention kernel library ...
NO KERNEL? NO FUSED OPTIMIZATION? · Issue #3 · NVIDIA/TensorRT · GitHub
[Myelin] Myelin fused Attn but not run at MHA Kernel · Issue #3620 ...
[Myelin] Myelin fused Attn but not run at MHA Kernel · Issue #3620 ...
[Myelin] Myelin fused Attn but not run at MHA Kernel · Issue #3620 ...
[Myelin] Myelin fused Attn but not run at MHA Kernel · Issue #3620 ...
attention fp8 compute type · Issue #1921 · NVIDIA/TensorRT-LLM · GitHub
Error in fused softmax kernel result · Issue #132 · NVIDIA/Megatron-LM ...
Advertisement Space (300x250)

Error in fused softmax kernel result · Issue #132 · NVIDIA/Megatron-LM ...

(PDF) BLADE: Energy‐efficient attention accelerator with fused kernel ...
[feature request] implement RMSNorm fused cuda kernel · Issue #1271 ...
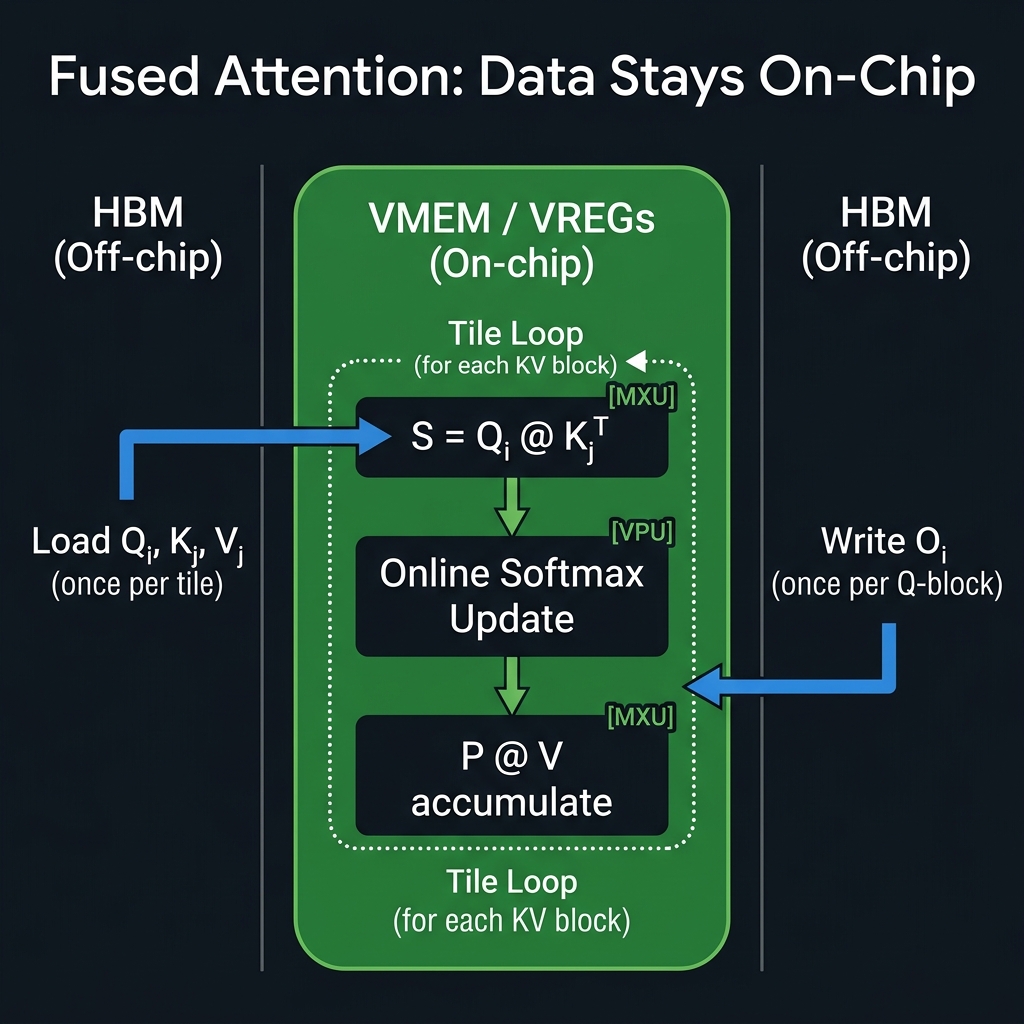
Implementing a Fast Attention Fusion Kernel | Hello, world! I’m Keshan ...
GitHub - kst179/fused-attention: Fast and low-memory attention layer ...
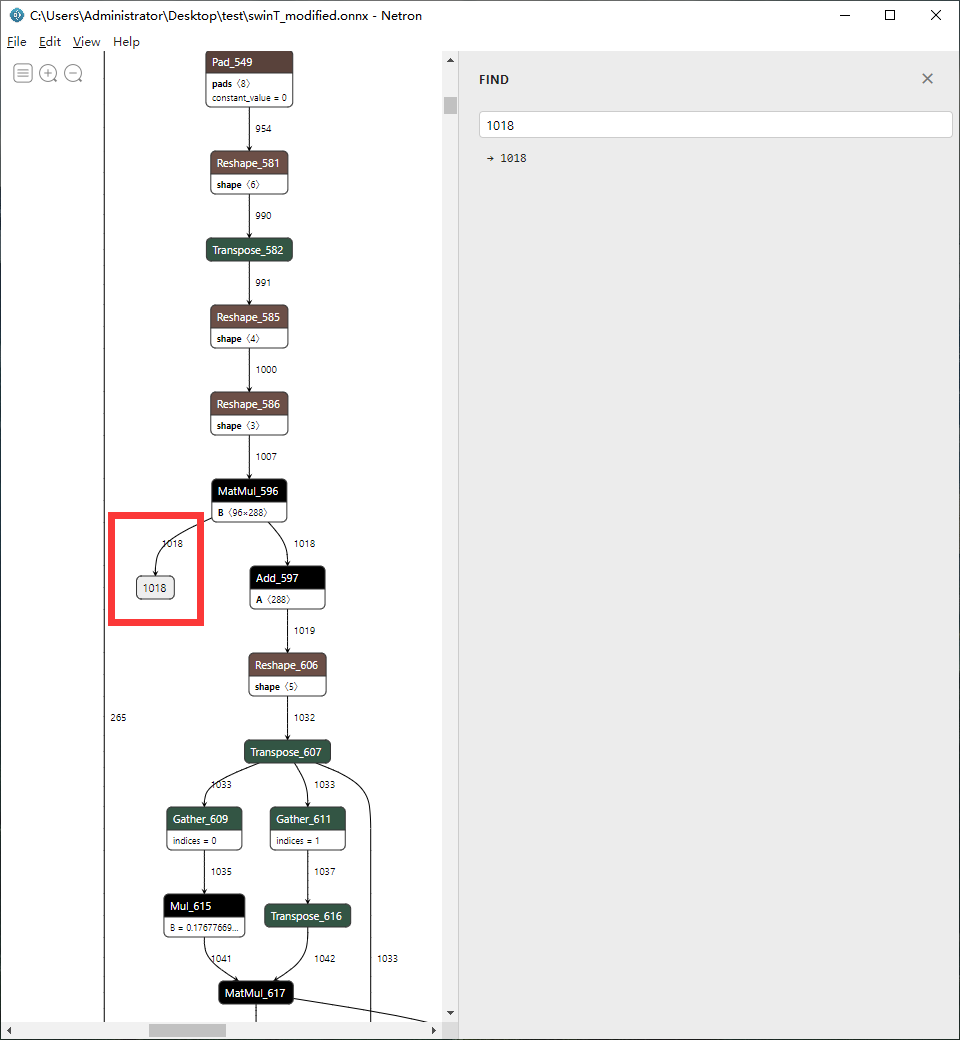
Question about Layer Fuse · Issue #1996 · NVIDIA/TensorRT · GitHub
Custom Attention implementation not well optimised by TensorRT · Issue ...
Implementation bug in Disentangled Attention Plugin · Issue #3370 ...
How to set TensorRT-LLM to use Flash Attention 3 · Issue #2238 · NVIDIA ...
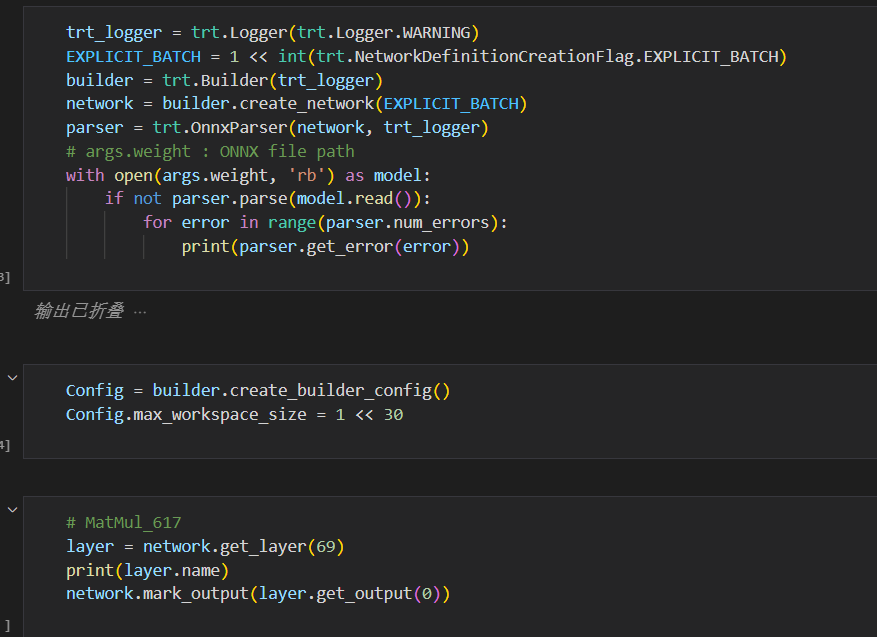
Question about Layer Fuse · Issue #1996 · NVIDIA/TensorRT · GitHub
Advertisement Space (336x280)
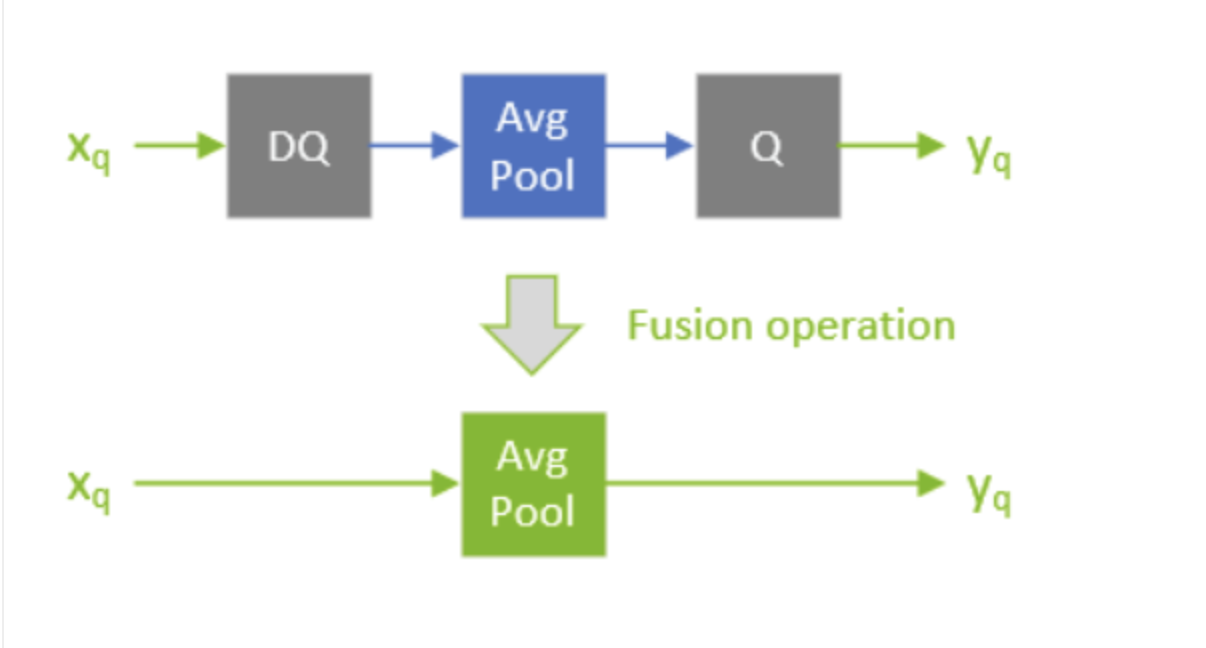
Does fused DeQuant node still convert to FP32? · Issue #2476 · NVIDIA ...
Do tensorrt 9.2 support flash attention v2 · Issue #3647 · NVIDIA ...
Memory issue when using fused_dense kernel with deepspeed · Issue #222 ...
NATTEN FNA kernel launch failed!Fused neighborhood attention is not ...
Meta's xFormers has Attention kernel written in CUTLASS · NVIDIA ...
Build failures · Issue #32 · NVIDIA/TensorRT-LLM · GitHub
Fused Attention Backend | NVIDIA/TransformerEngine | DeepWiki

Question about Layer Fuse · Issue #1996 · NVIDIA/TensorRT · GitHub
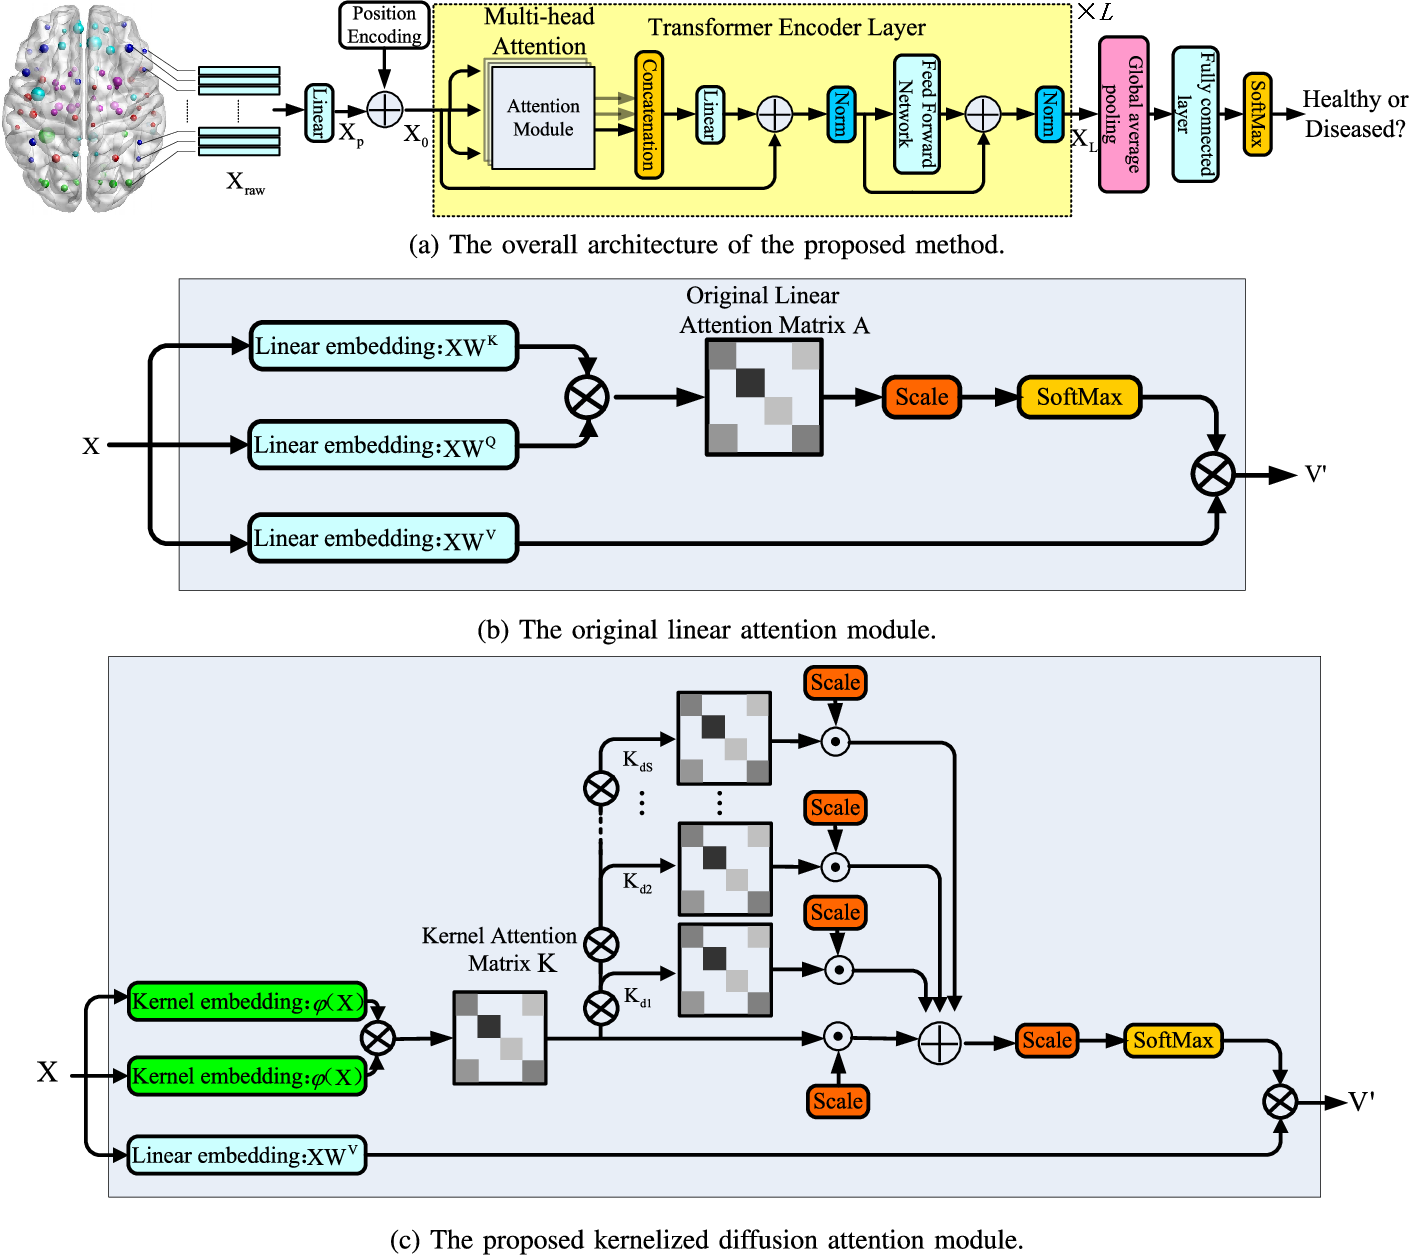
Figure 1 from Diffusion Kernel Attention Network for Brain Disorder ...
Does Fused Multi-head Attention support self-defined attention-mask ...
Advertisement Space (336x280)
Fused Attention Operations | NVIDIA/TransformerEngine | DeepWiki
Attention Kernel Implementation | flashinfer-ai/flashinfer | DeepWiki
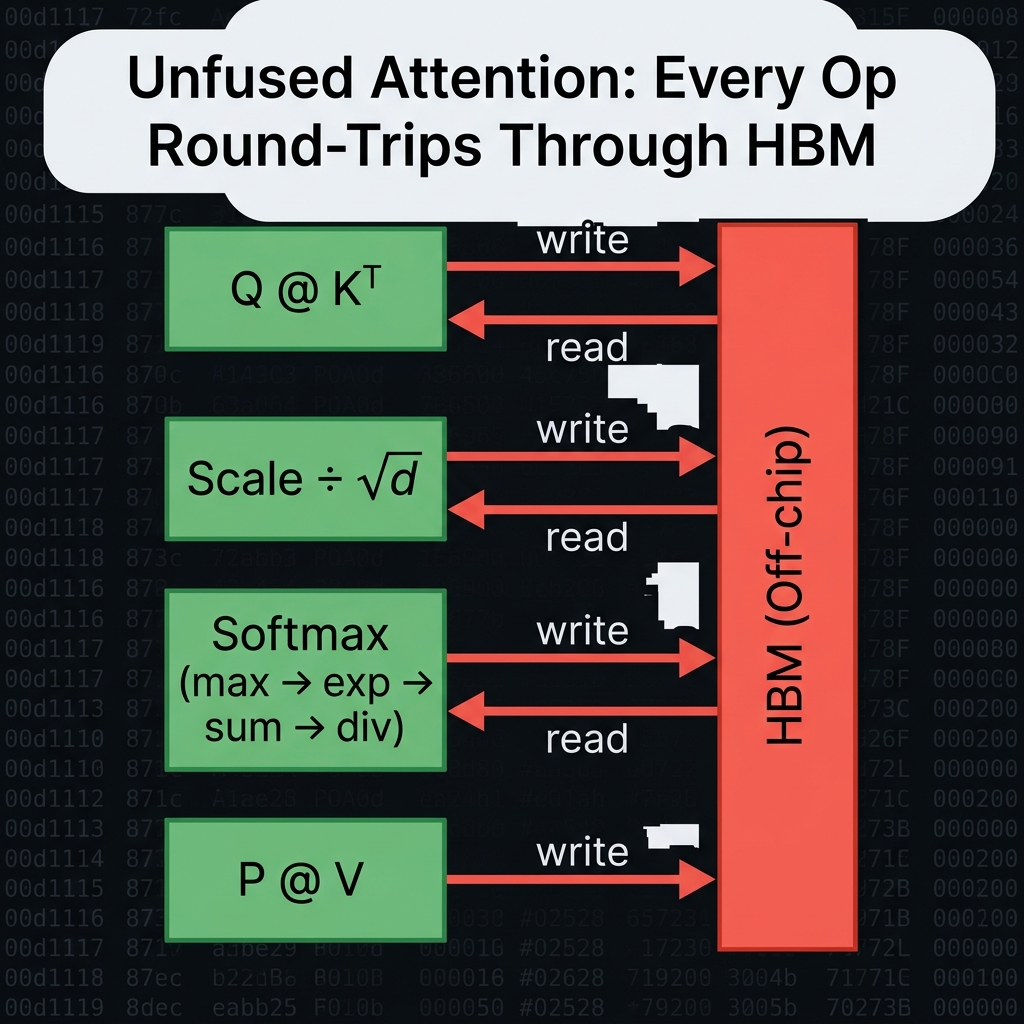
Implementing a Fast Attention Fusion Kernel | Hello, world! I’m Keshan ...
no kernel image is available for execution on the device · Issue #159 ...
fix Flash Attention kernel not found issue. by lzbgt · Pull Request ...
Multi-layer MLP fusion conditions · Issue #3232 · NVIDIA/TensorRT · GitHub