
Github Cloud1204edgeaifinal Llm Acceleration
GitHub - cloud1204/Edge_Ai_Final: LLM Acceleration
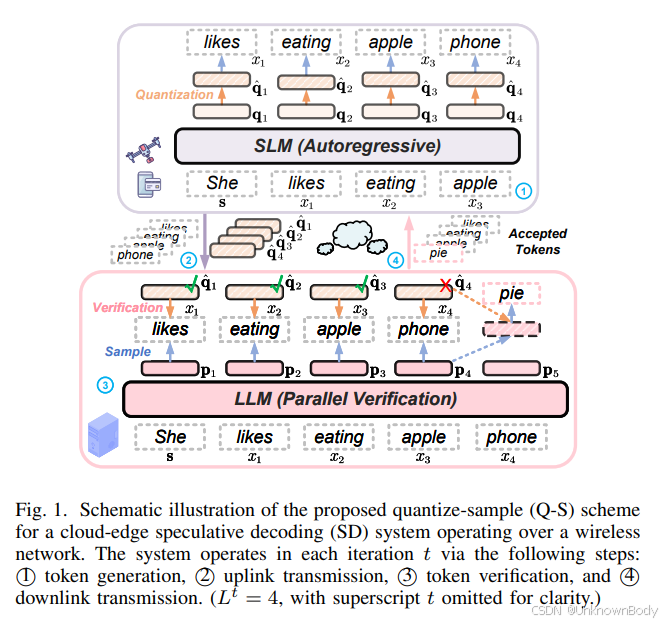
Quantize-Sample-and-Verify: LLM Acceleration via Adaptive Edge-Cloud ...
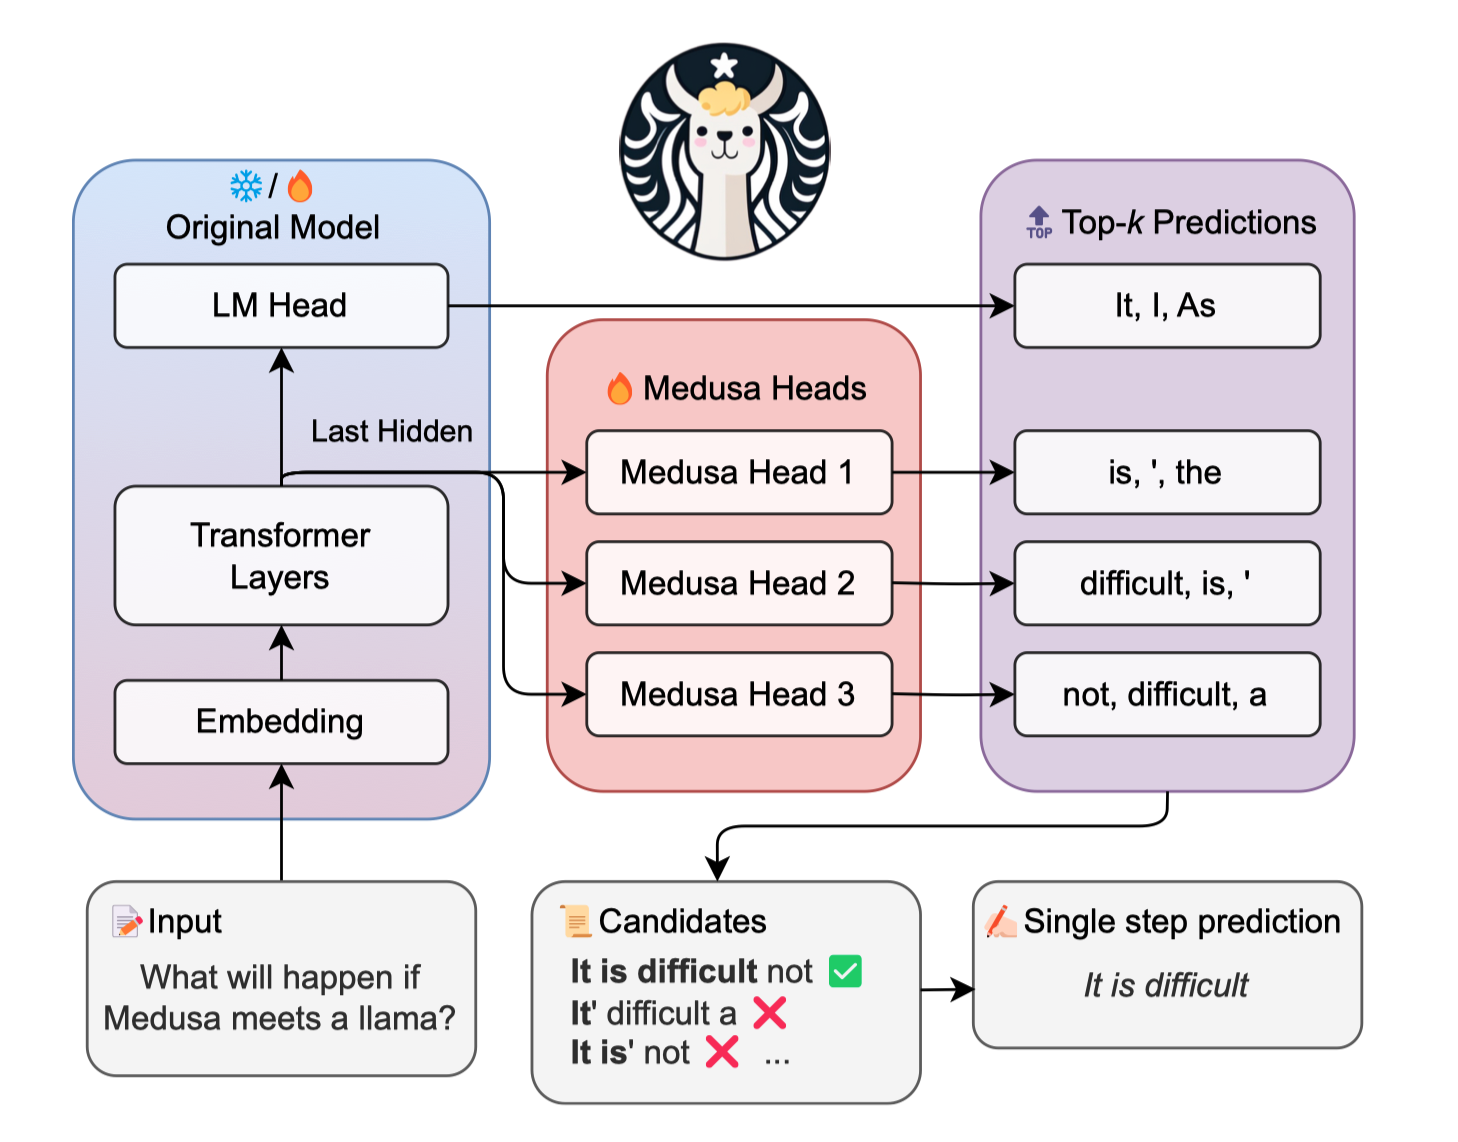
Outline of LLM acceleration | Benson's blog
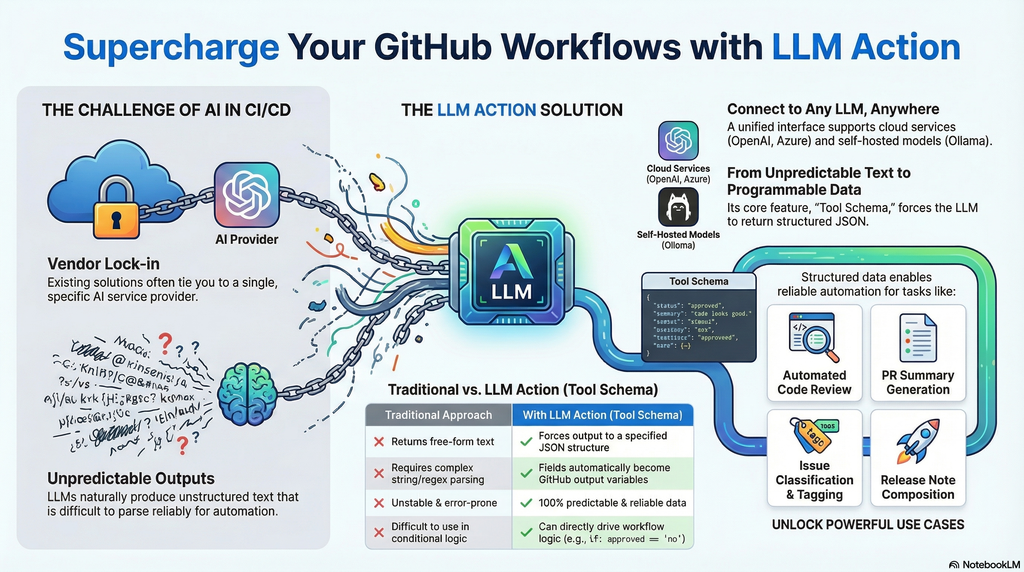
Building AI-Powered GitHub Workflows: A Complete Guide to LLM Action ...

ISCA`25 LIA A Single-GPU LLM Inference Acceleration with Cooperative ...
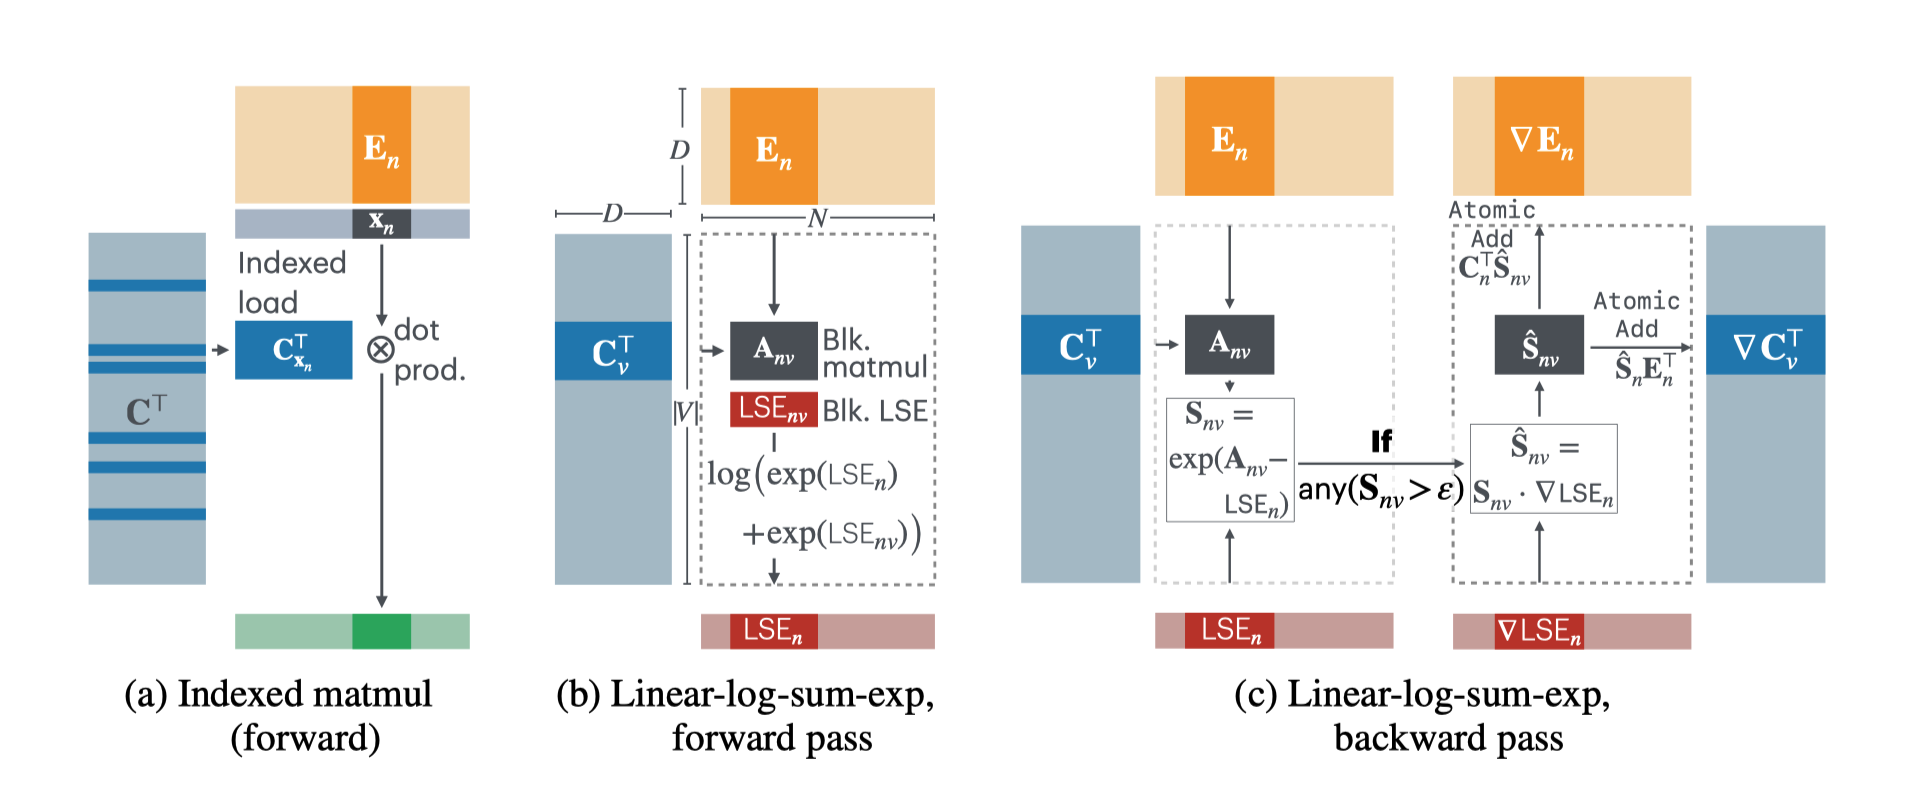
Outline of LLM acceleration | Benson's blog

LLM Acceleration on Versal AI Edge by RaiderChip and iWave
GitHub - shishishu/LLM-Inference-Acceleration: LLM Inference with Deep ...

LLM Inference Acceleration via Efficient Operation Fusion

LLM Inference Acceleration via Efficient Operation Fusion
Advertisement Space (300x250)

LLM Inference Acceleration via Efficient Operation Fusion | AI Research ...
NPU support for LLM acceleration without gpu · nomic-ai gpt4all ...
LLM Inference Acceleration | Inference Engineering
GitHub - ModelCloud/GPTQModel: LLM model quantization (compression ...
GitHub - whutbd/ZhiLight-LLm: A highly optimized inference acceleration ...

GitHub - skyiron/lemonadeLLMserverAI: Local LLM Server with GPU and NPU ...

LLM Inference Acceleration via Efficient Operation Fusion
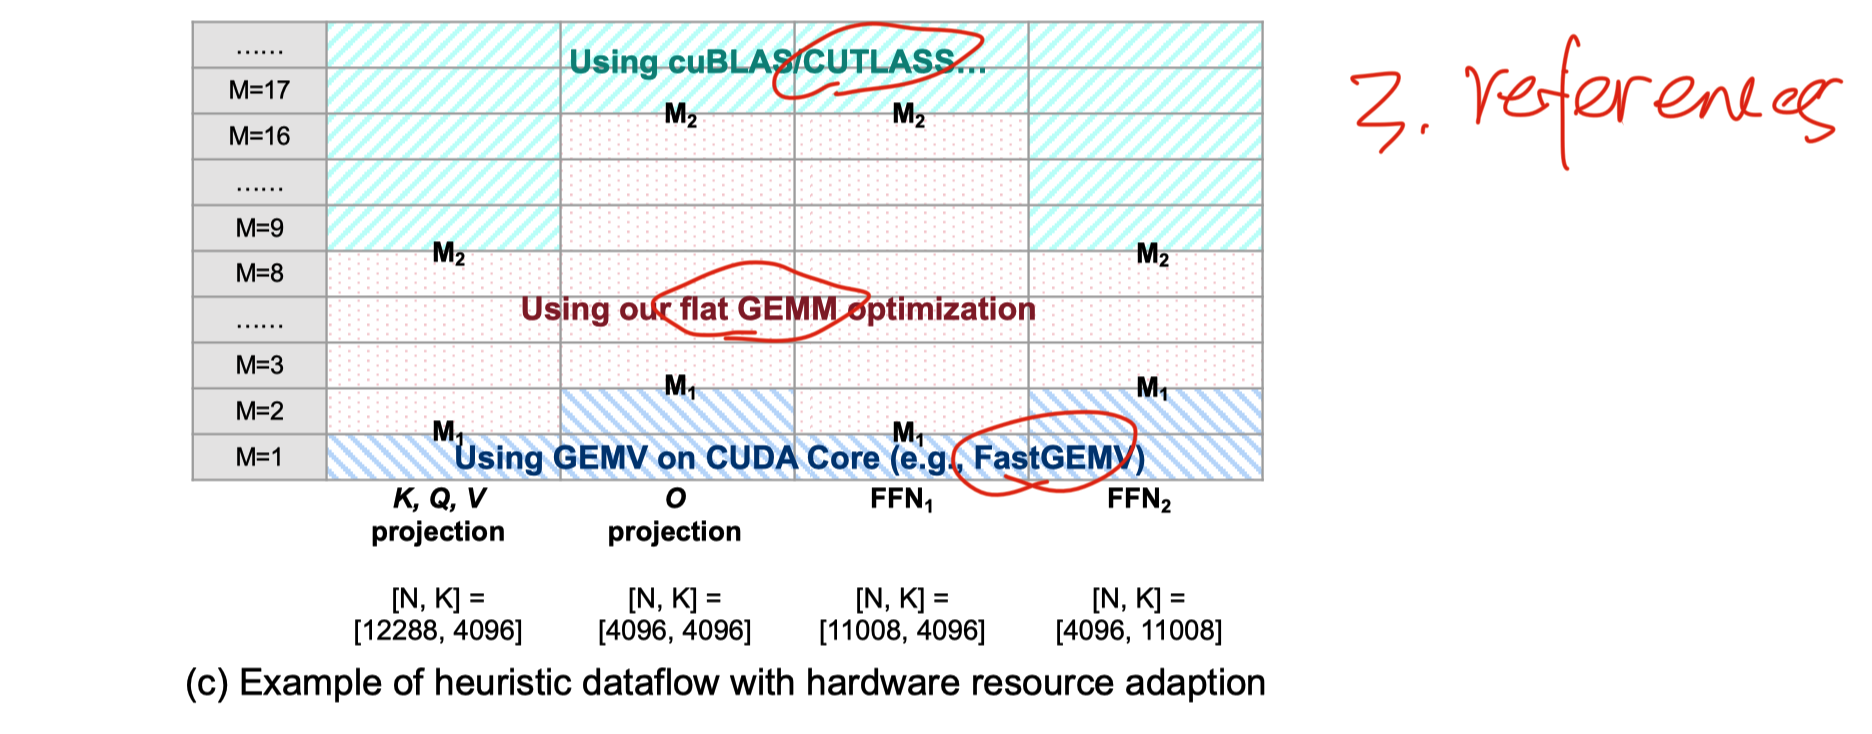
Outline of LLM acceleration | Benson's blog
Acceleration Multiple Heads Decoding for LLM via Dynamic Tree Attention ...
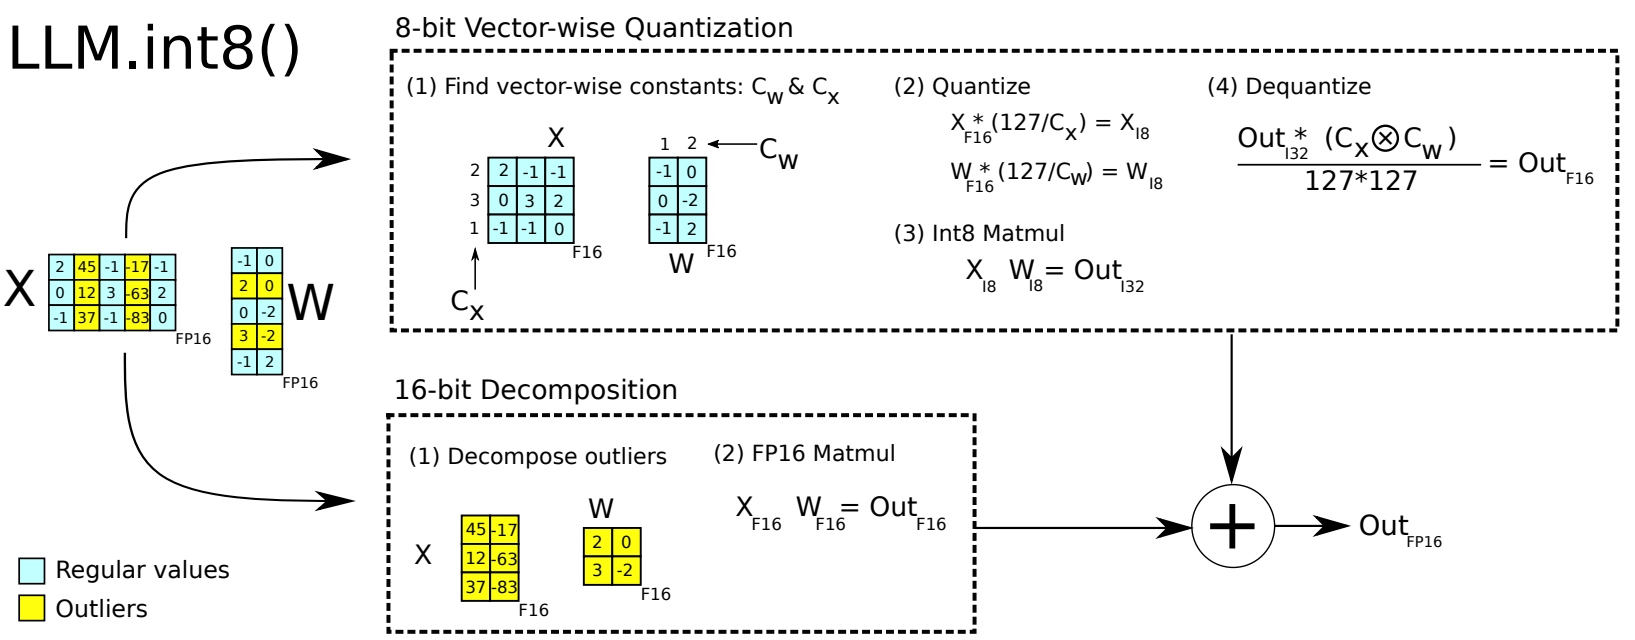
20. Inference Acceleration (WIP) — LLM Foundations
Advertisement Space (336x280)
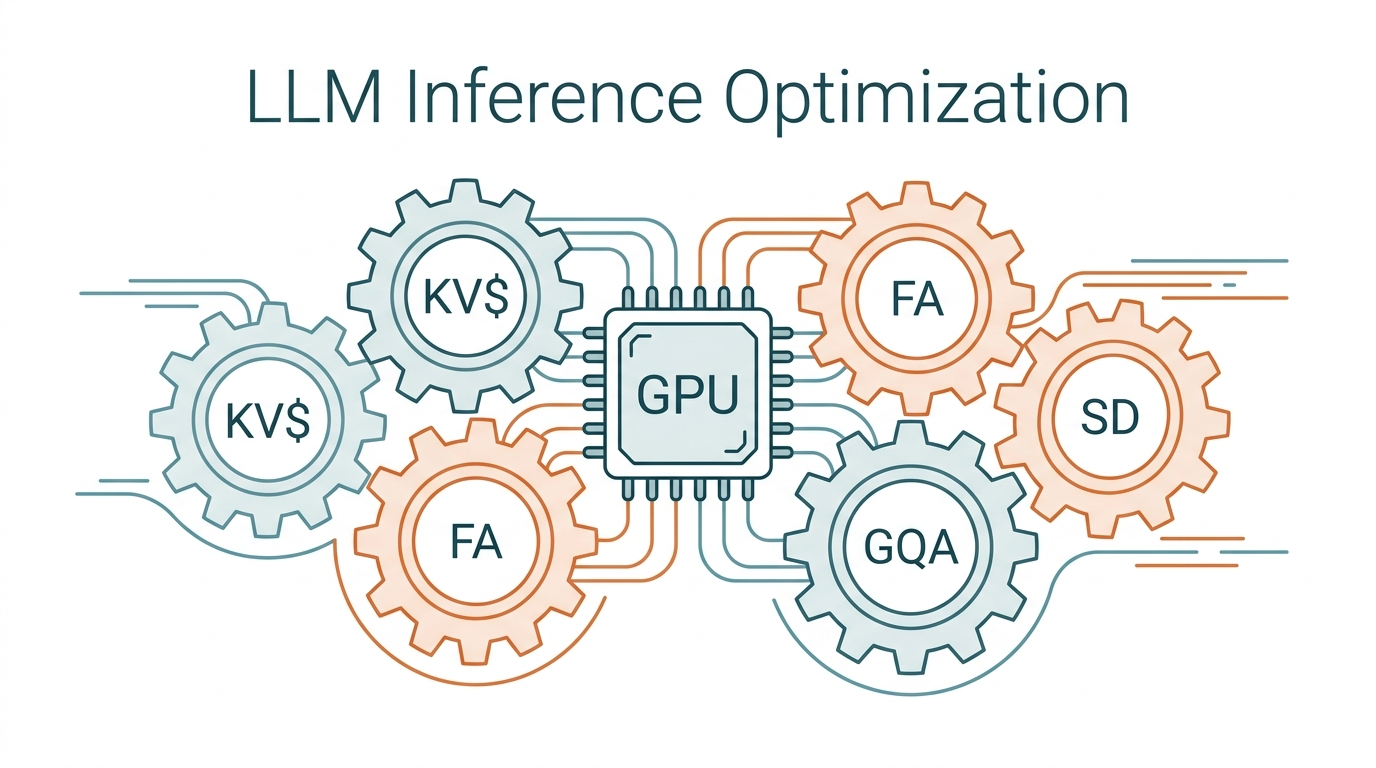
Why Is AI Getting Faster? Six Techniques Behind LLM Inference Acceleration

Your AI, Your Rules: Running a Local LLM with GPU Acceleration on ...

GitHub - bytedance/ABQ-LLM: An acceleration library that supports ...
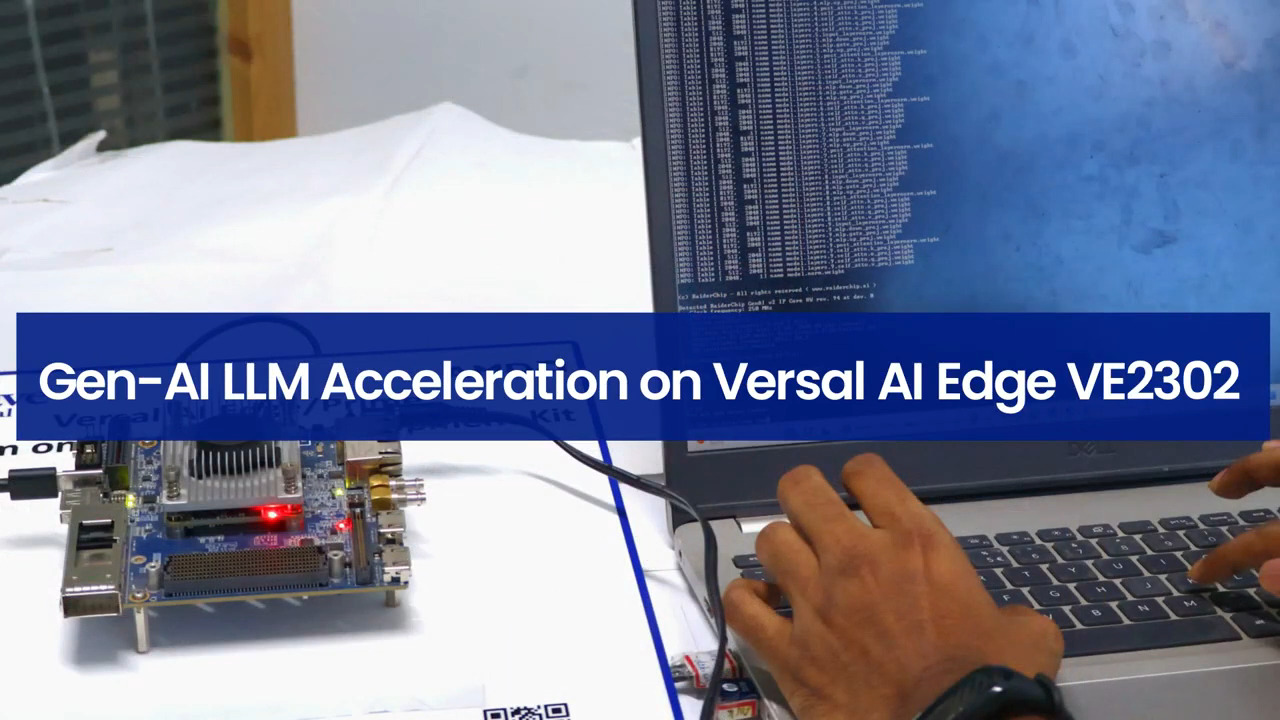
Gen-AI LLM Acceleration on Versal AI Edge VE2302 | DigiKey

Foundational data protection for enterprise LLM acceleration with ...

Foundational data protection for enterprise LLM acceleration with ...
ISCA`25 LIA A Single-GPU LLM Inference Acceleration with Cooperative ...
GPU and VRAM for Local LLM Acceleration
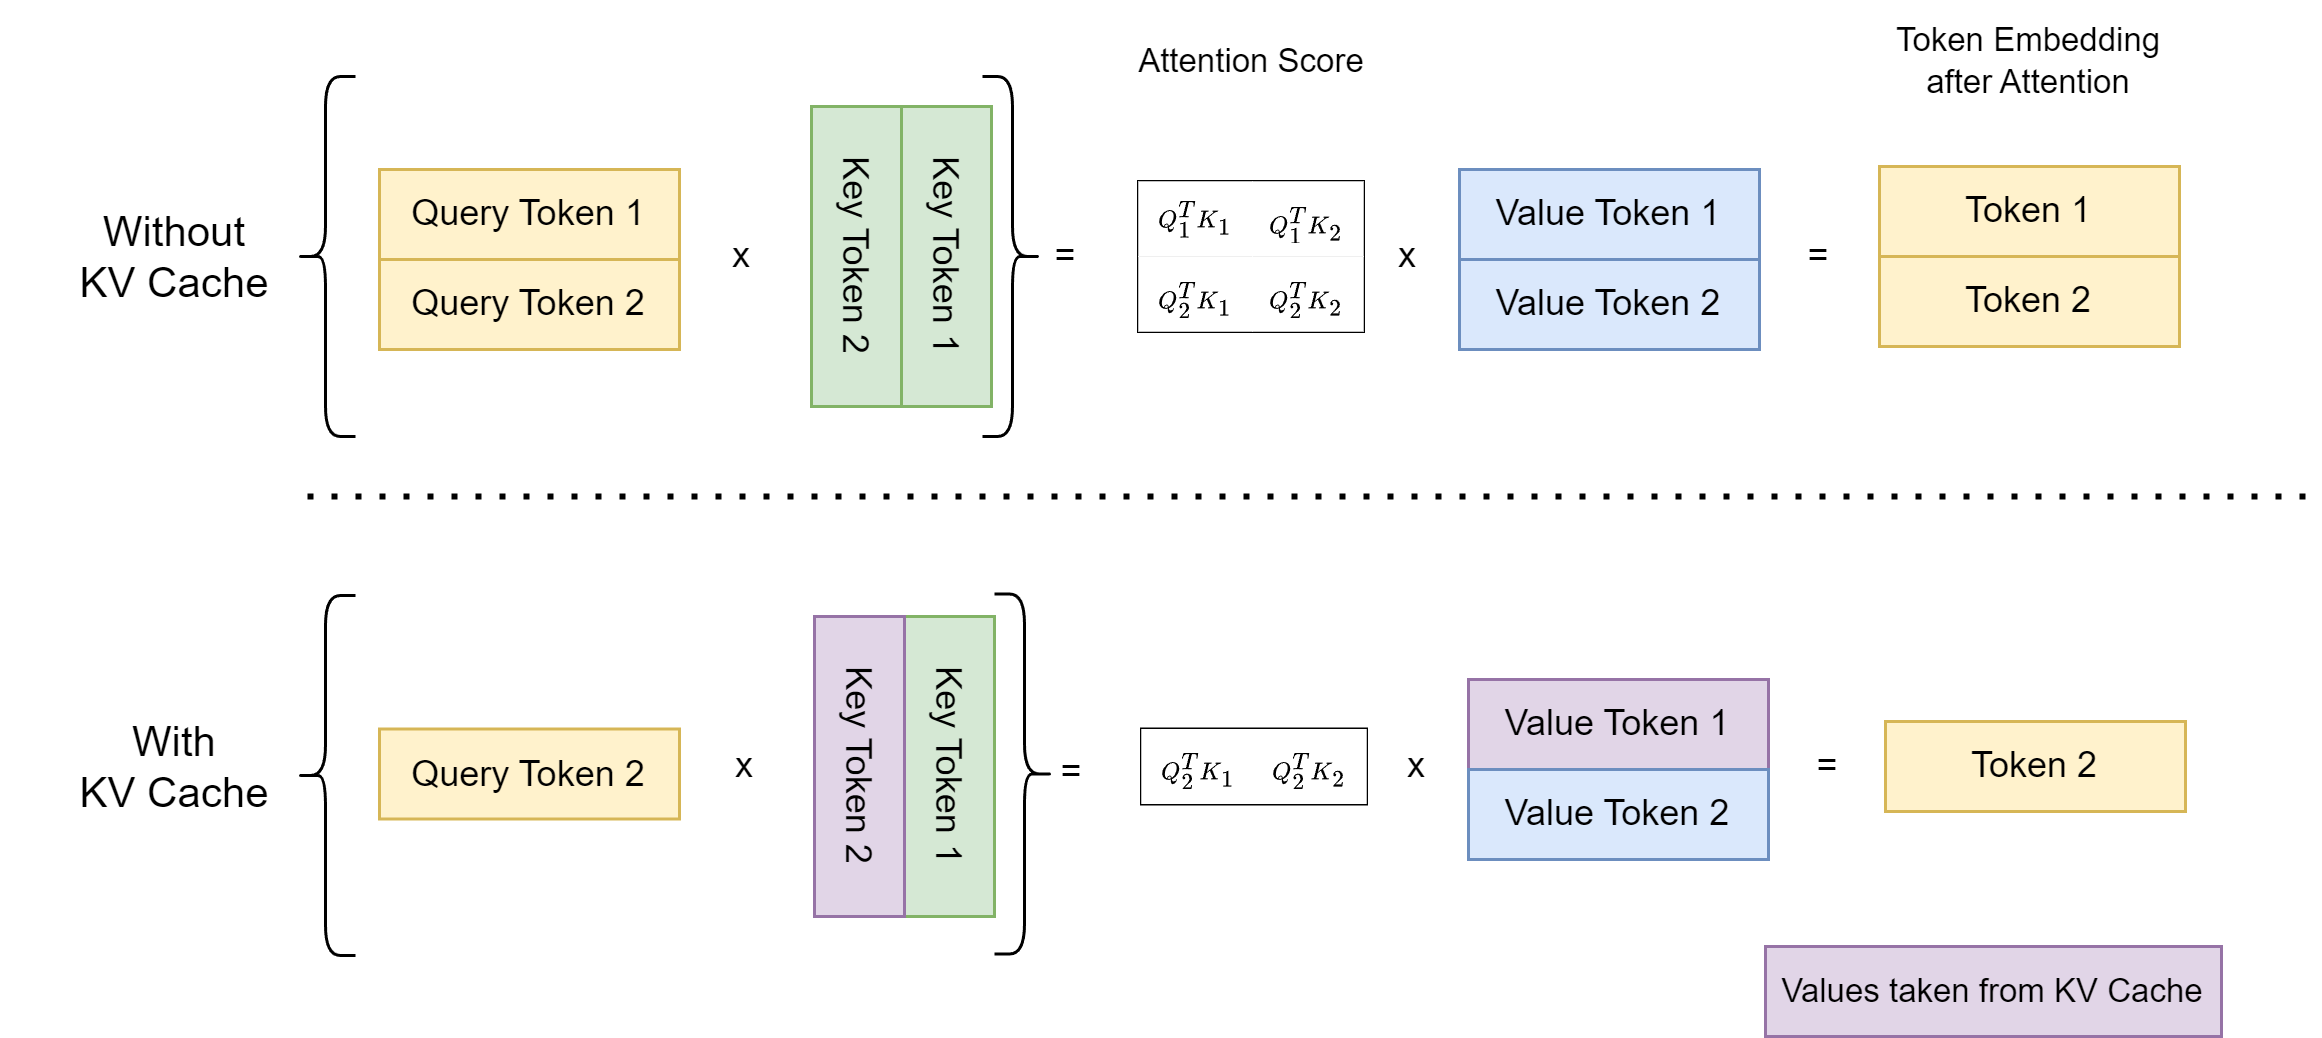
20. Inference Acceleration (WIP) — LLM Foundations
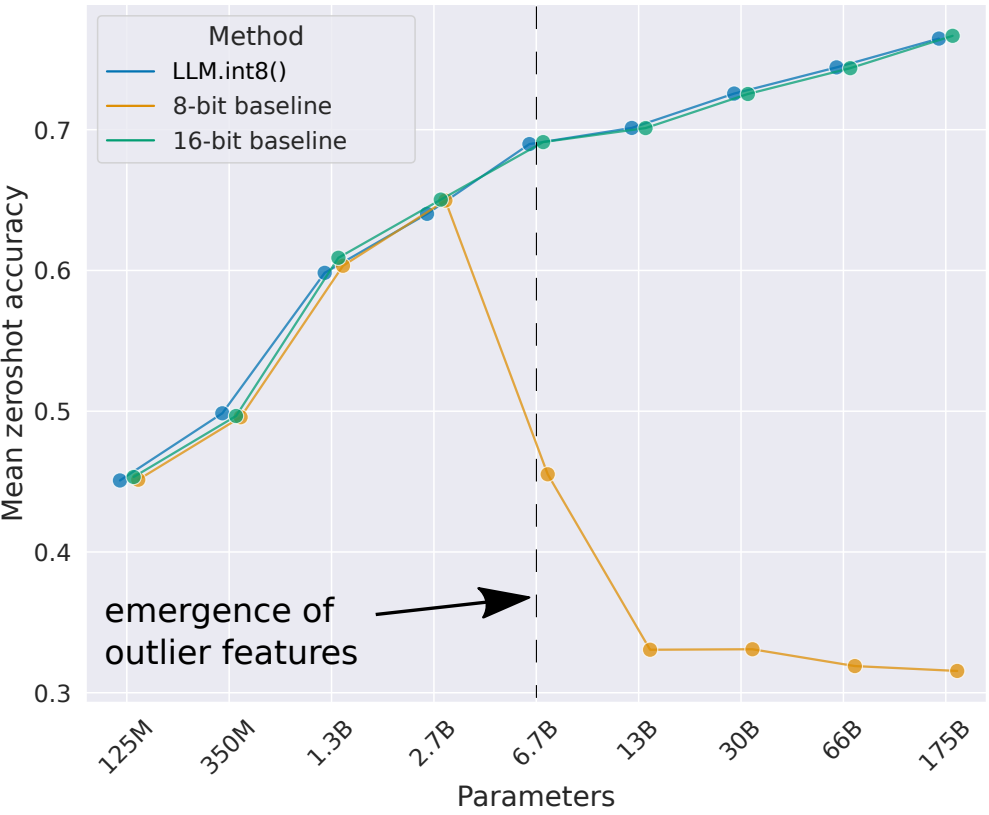
20. Inference Acceleration (WIP) — LLM Foundations
Advertisement Space (336x280)

Edge AI Acceleration Lab · GitHub
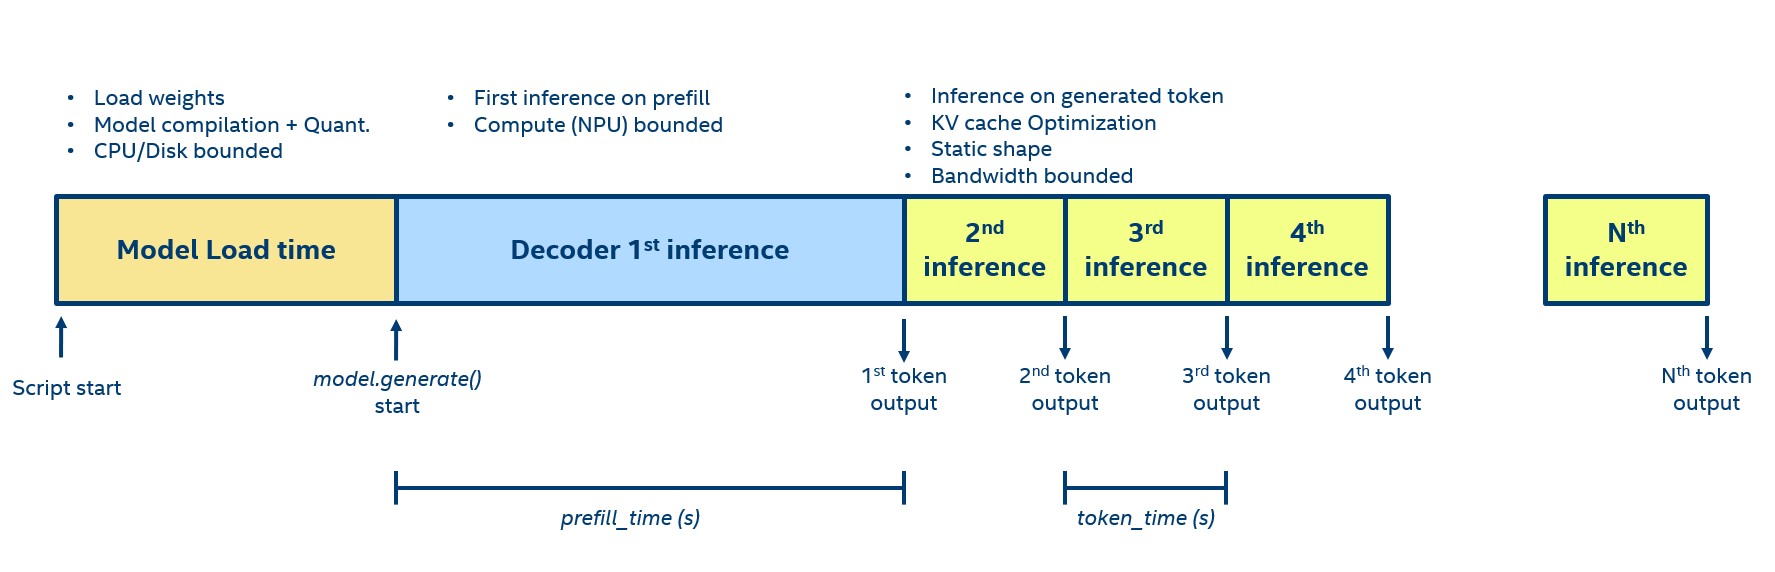
Decoding LLM performance — Intel® NPU Acceleration Library documentation
GitHub - FLY-Open-AI/AI-Acceleration-Suite: AIAS (AI Acceleration Suite ...
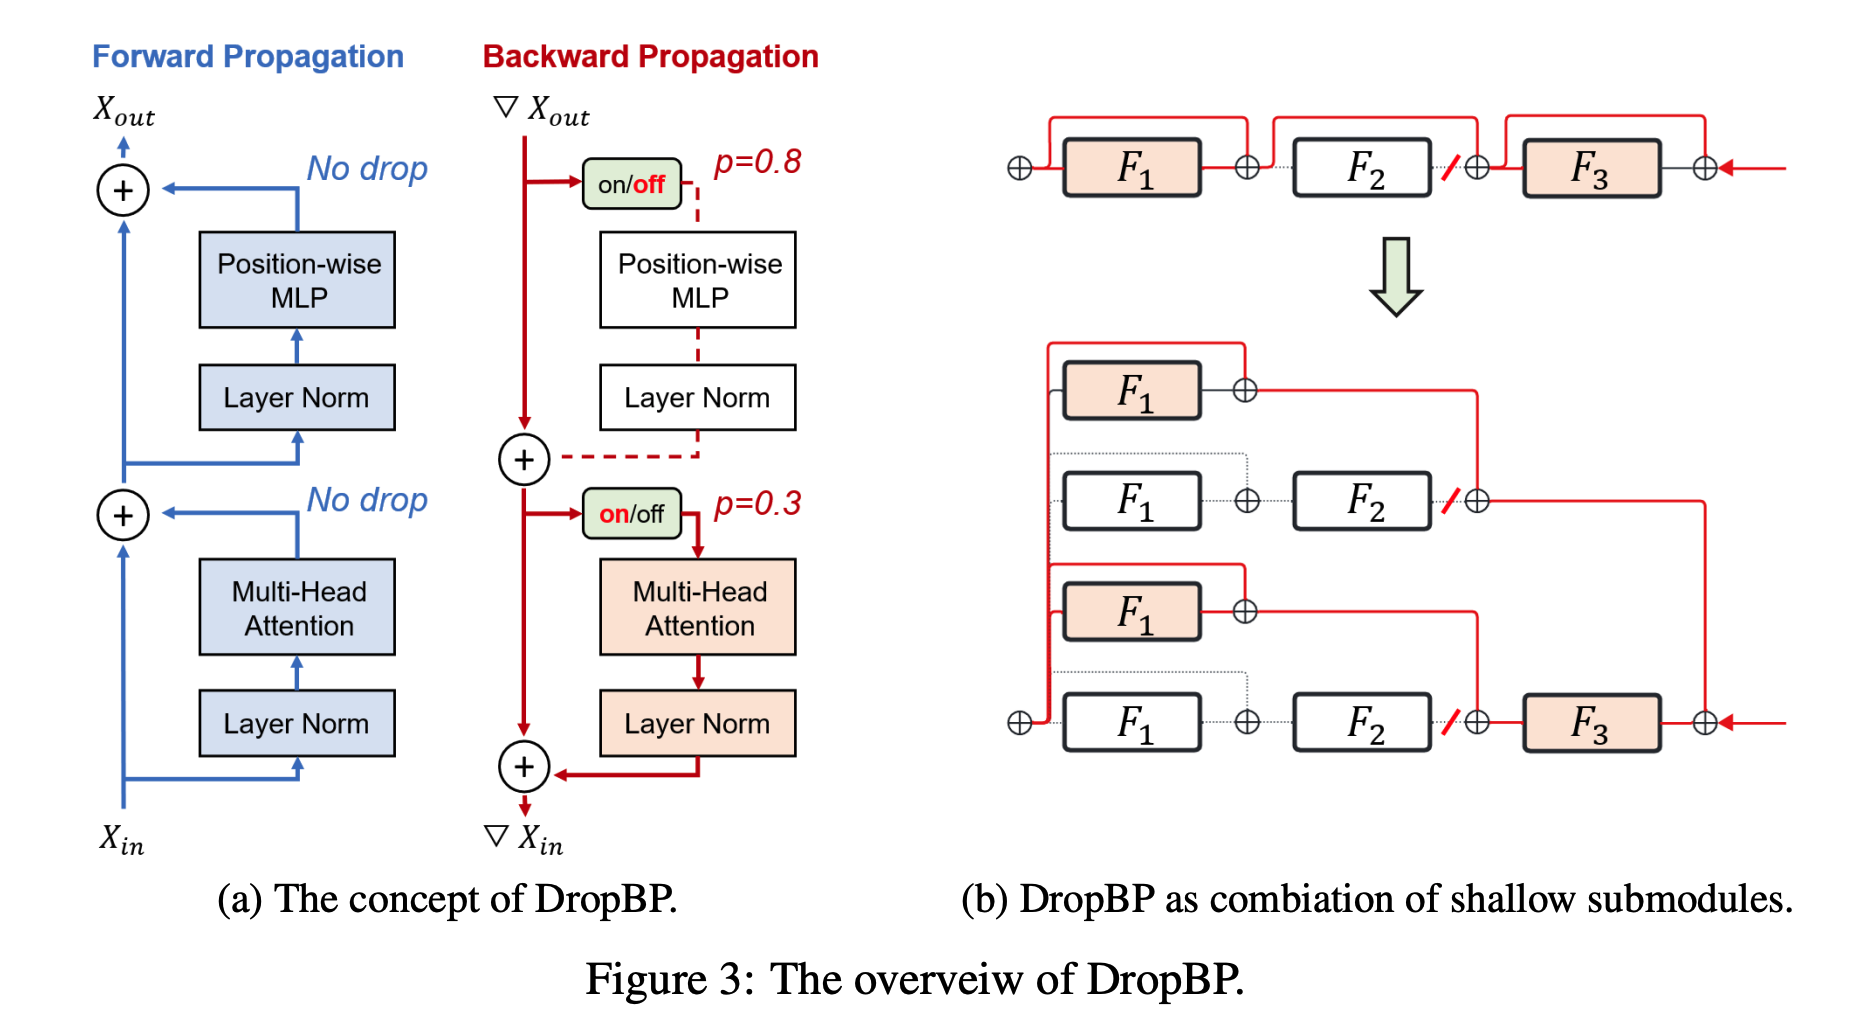
Outline of LLM acceleration | Benson's blog
LLM Acceleration - Synogate
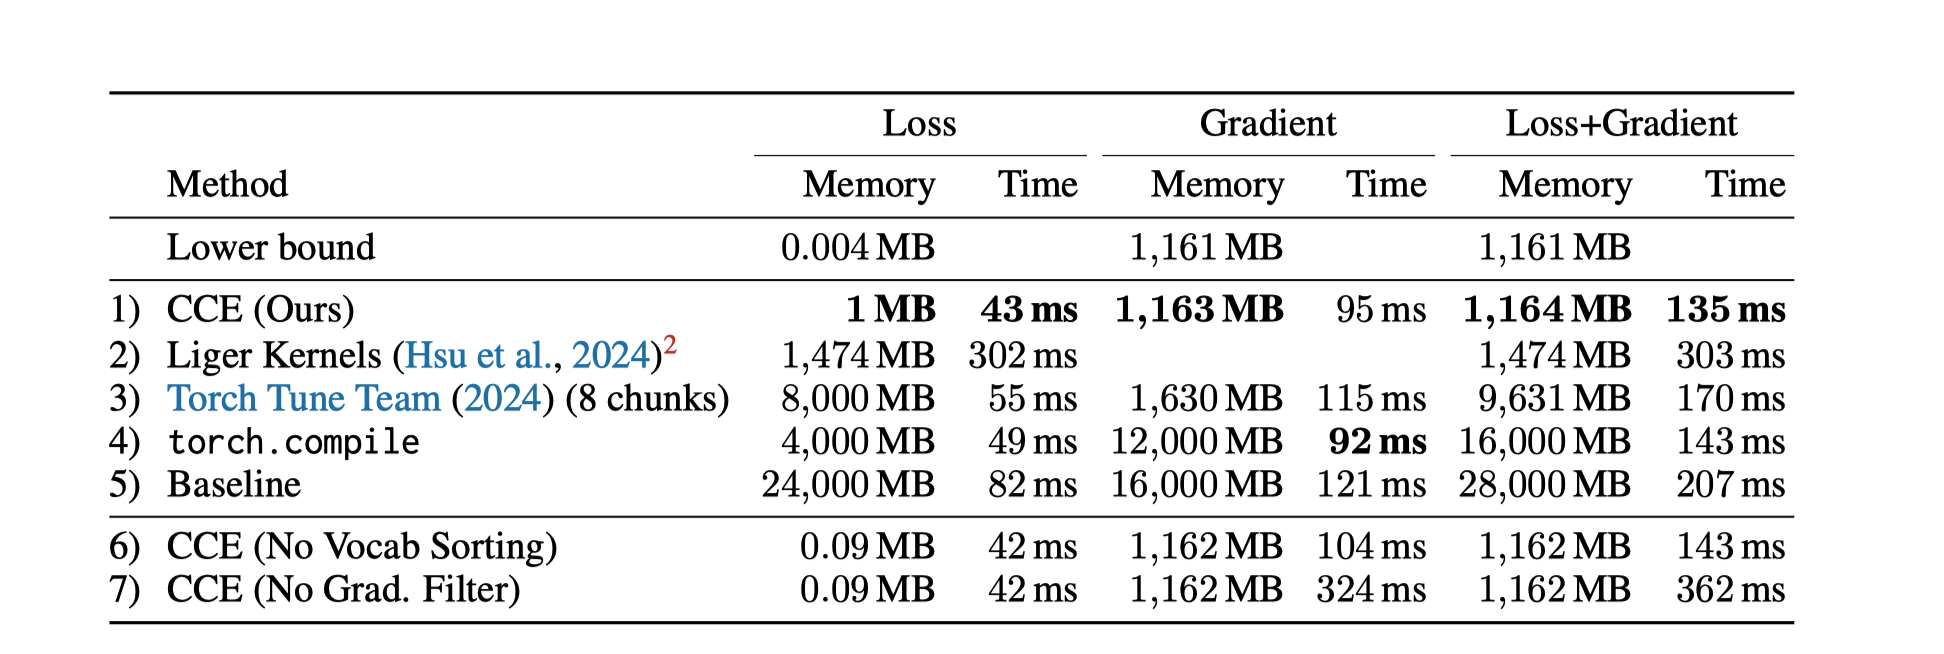
Outline of LLM acceleration | Benson's blog