
Github Gpustackllama Box Lm Inference Server Implementation Based
GitHub - gpustack/llama-box: LM inference server implementation based ...
GitHub - gpustack/llama-box: LM inference server implementation based ...
GitHub - gaztrabisme/llm-server: Local LLM inference server using llama ...

Web Based Inference GUI Server for Easy Model Deployment on the Spark ...

GitHub - huggingface/inference-benchmarker: Inference server ...
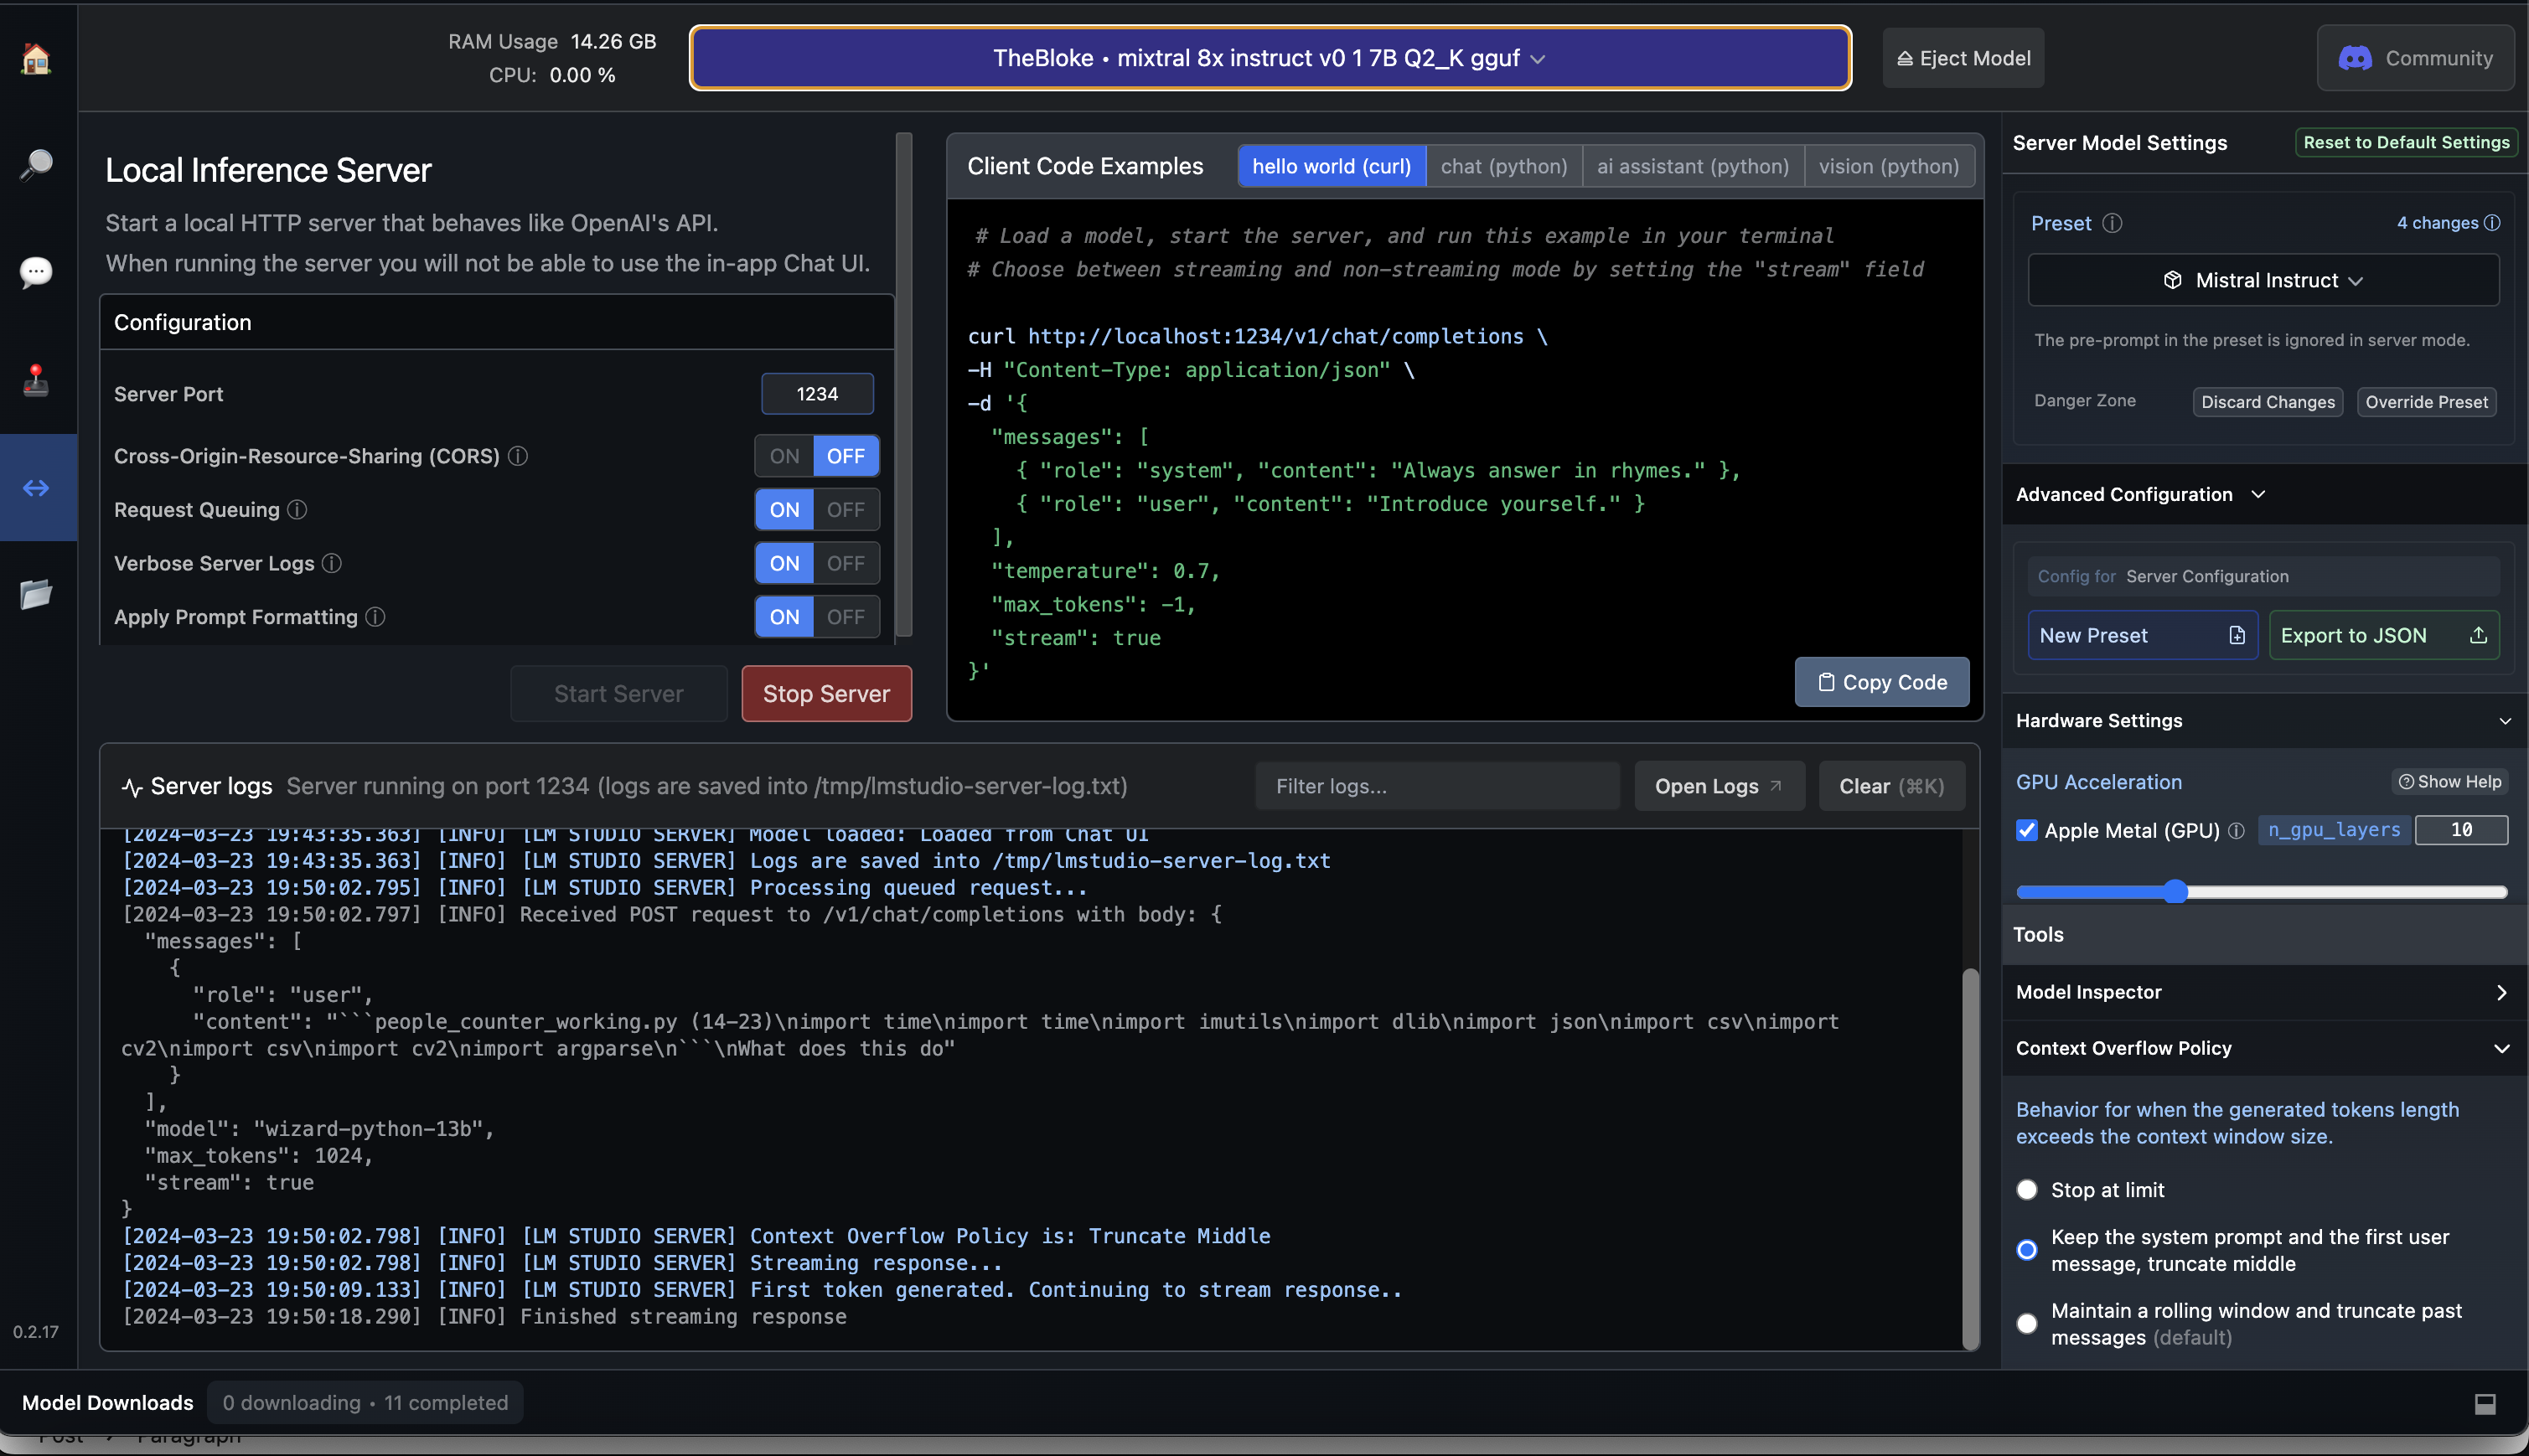
Building a GitHub CoPilot (Equivalent) Using LM Studio, Ollama ...
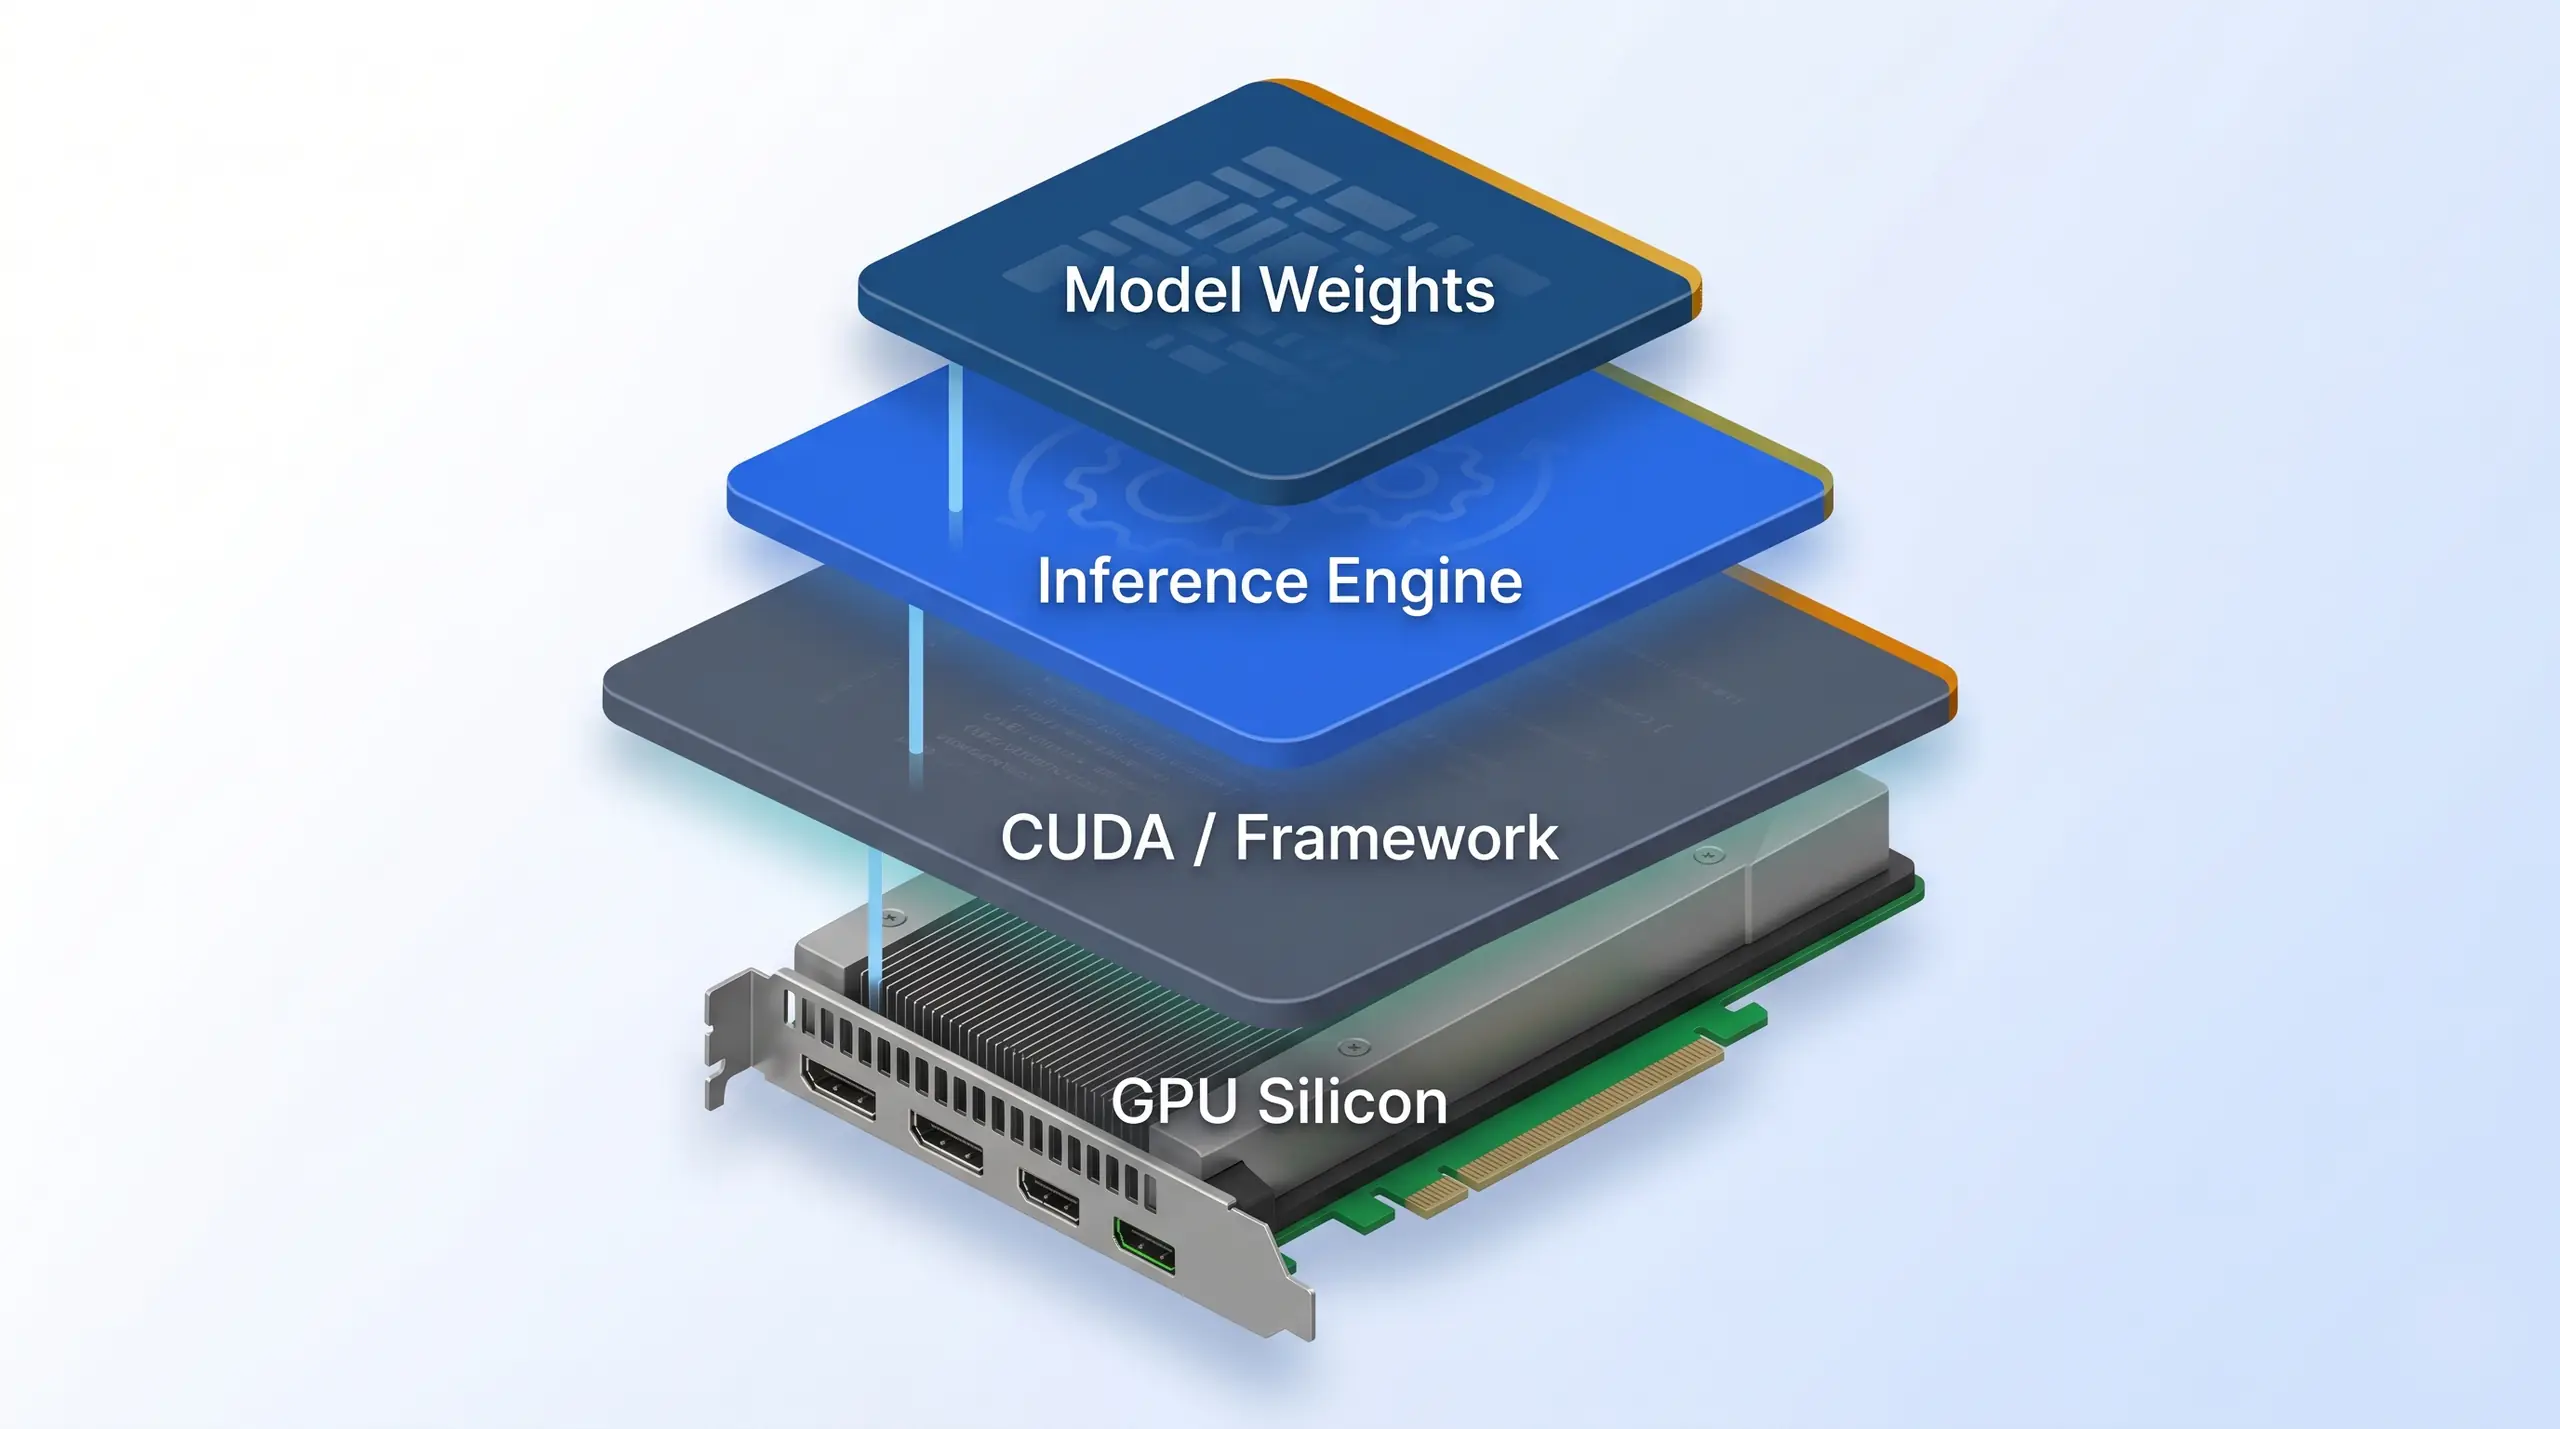
vLLM, Ollama, LM Studio, llama.cpp: Choosing the best LLM inference ...
Building a GitHub CoPilot (Equivalent) Using LM Studio, Ollama ...
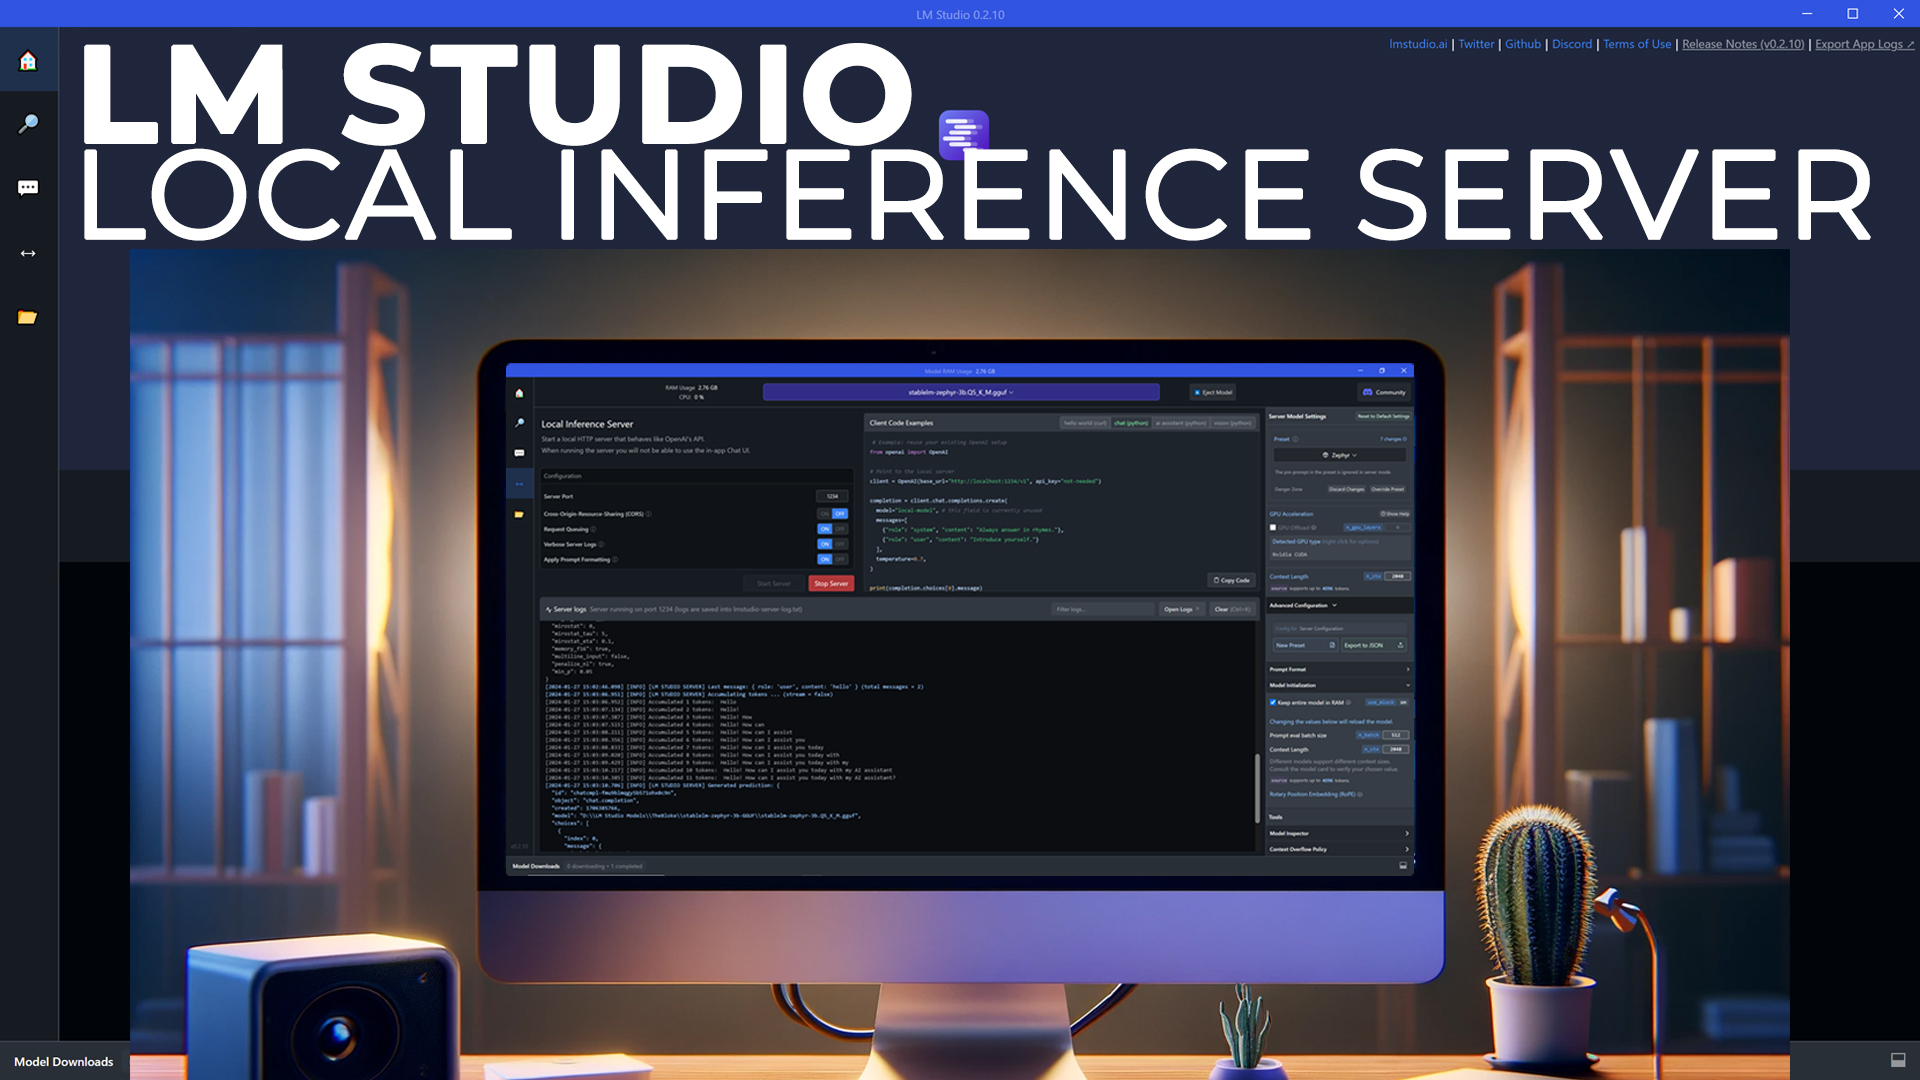
Run a Local Server with LM Studio: Tutorial - VTM Systems Store
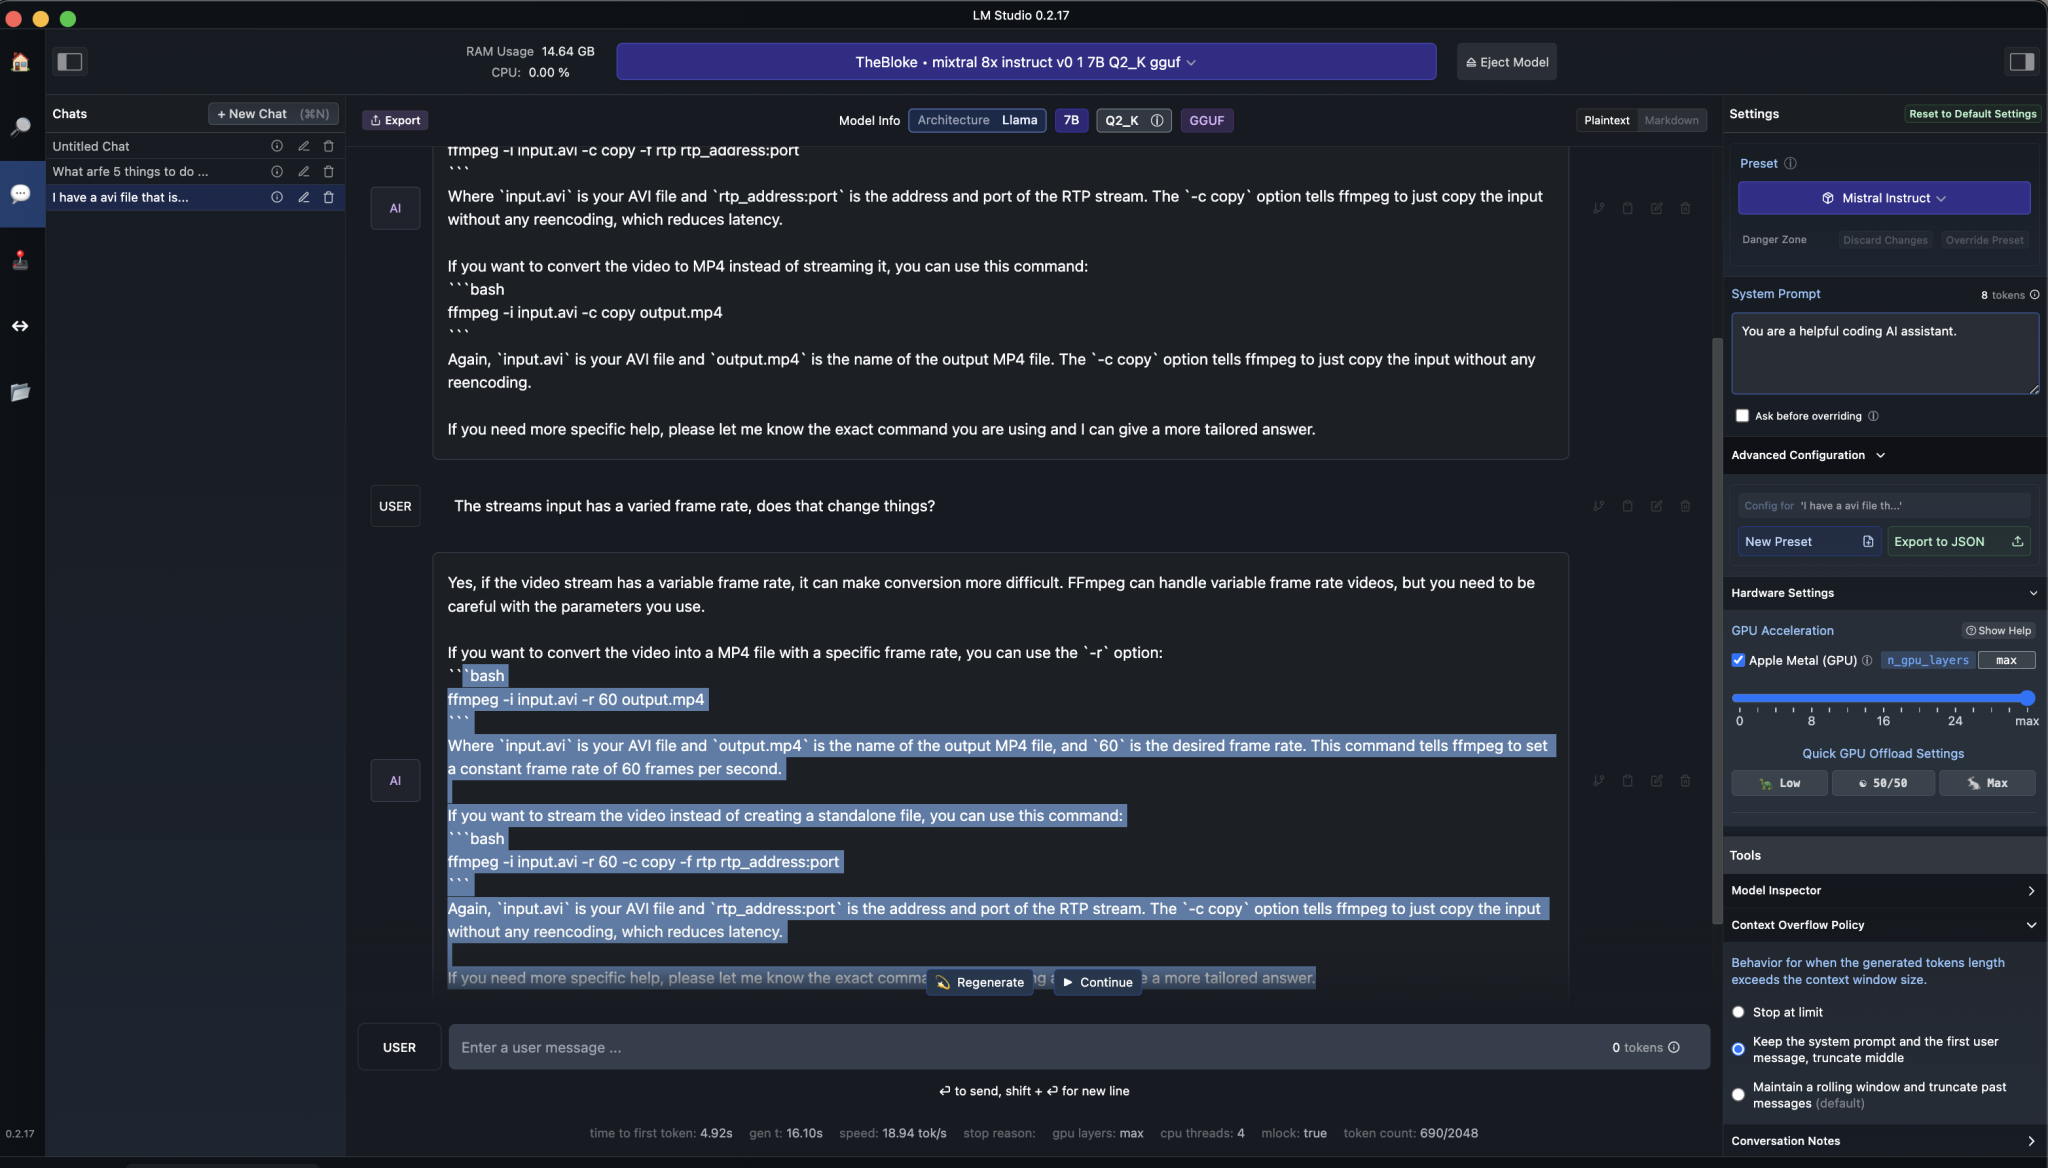
Building a GitHub CoPilot (Equivalent) Using LM Studio, Ollama ...
Advertisement Space (300x250)
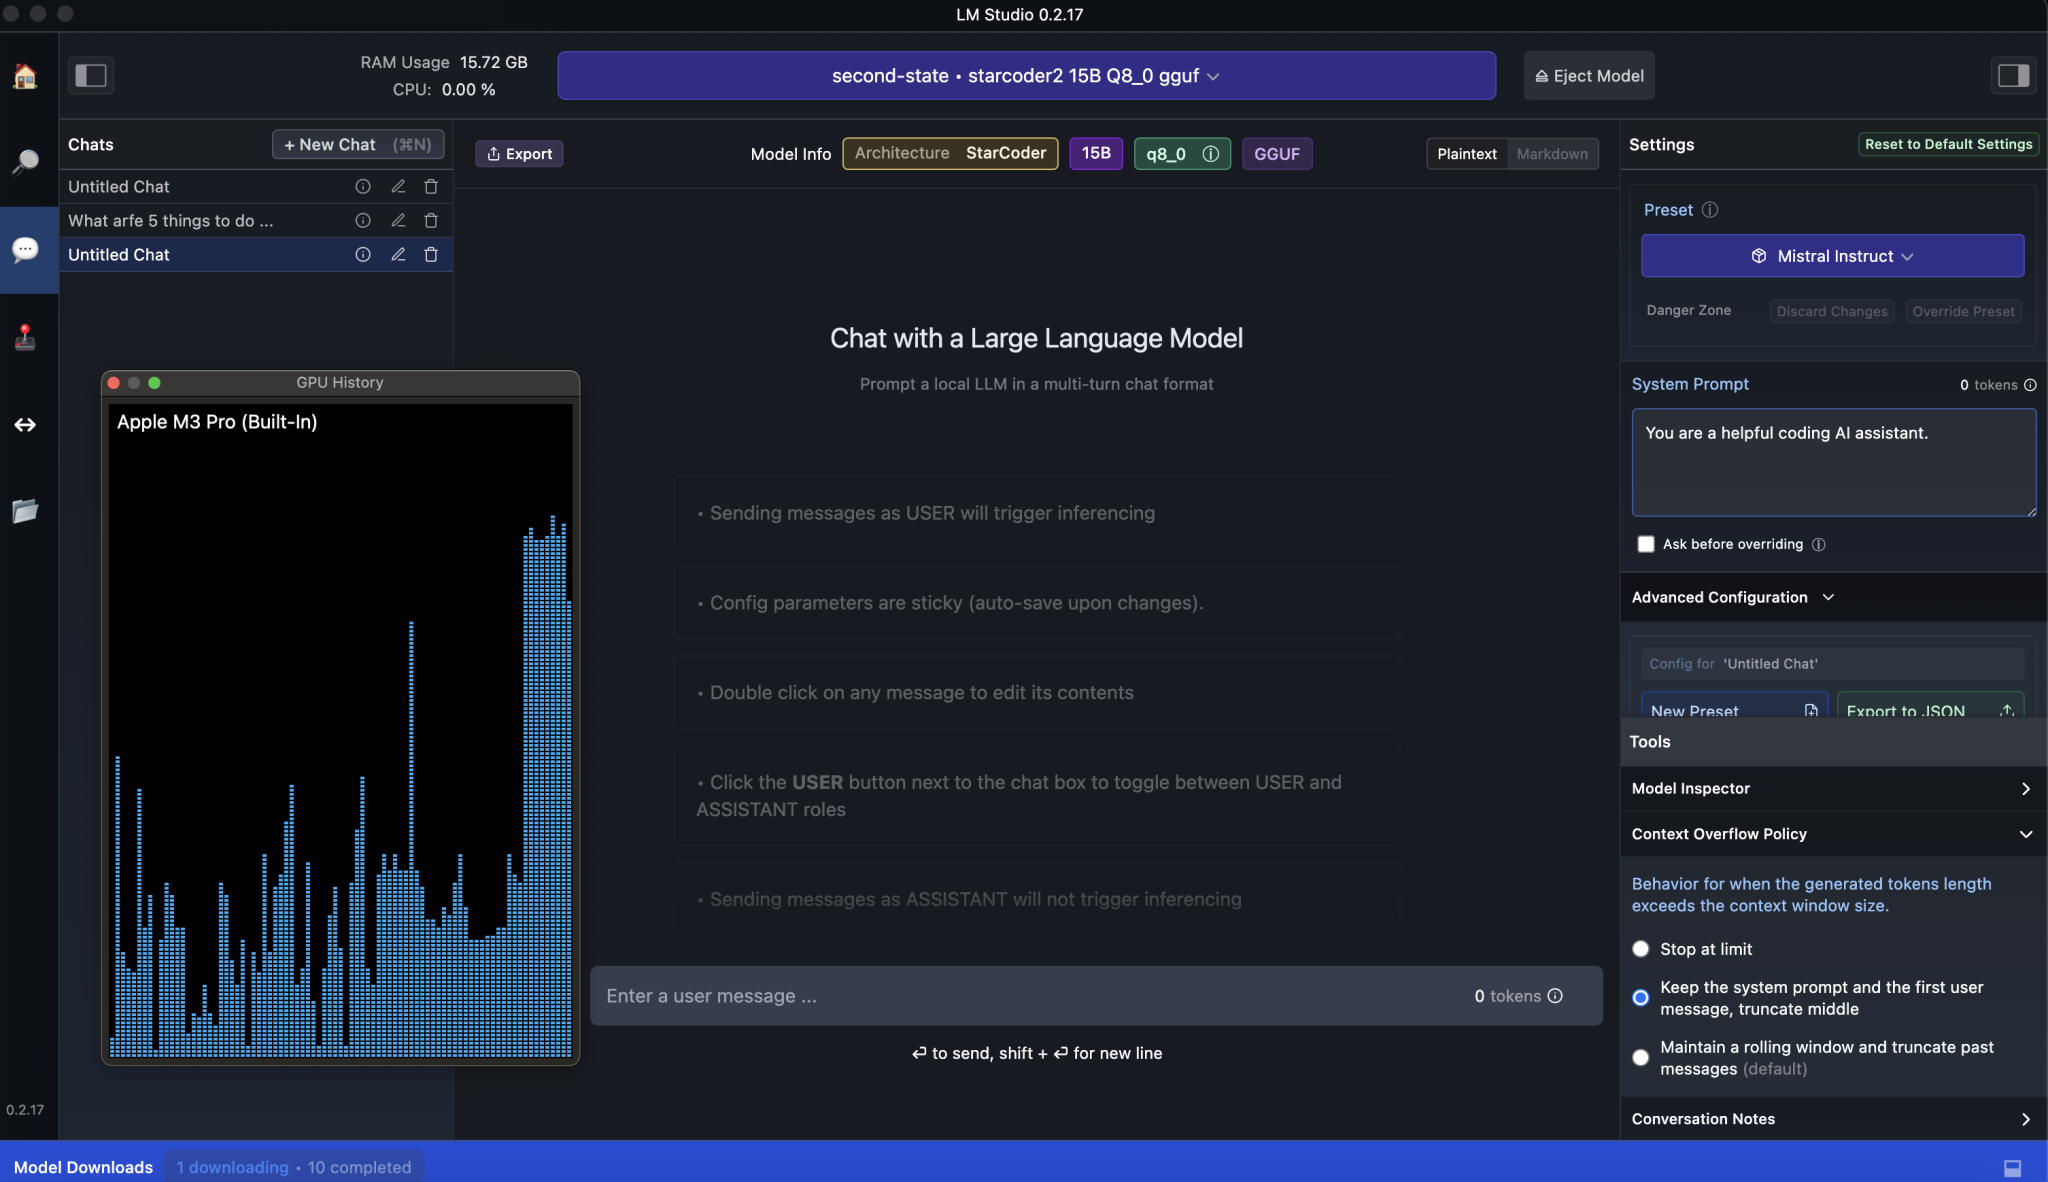
Building a GitHub CoPilot (Equivalent) Using LM Studio, Ollama ...
LLM inference server performances comparison llama.cpp / TGI / vLLM ...
GitHub - aju22/LLaMA2: This repository contains an implementation of ...
GitHub - USTC-ADSL/llama.cpp_bench-MOE: LLM inference in C/C++ · GitHub
GitHub - hemanth/llmux: Unified LLM inference proxy with multi-provider ...
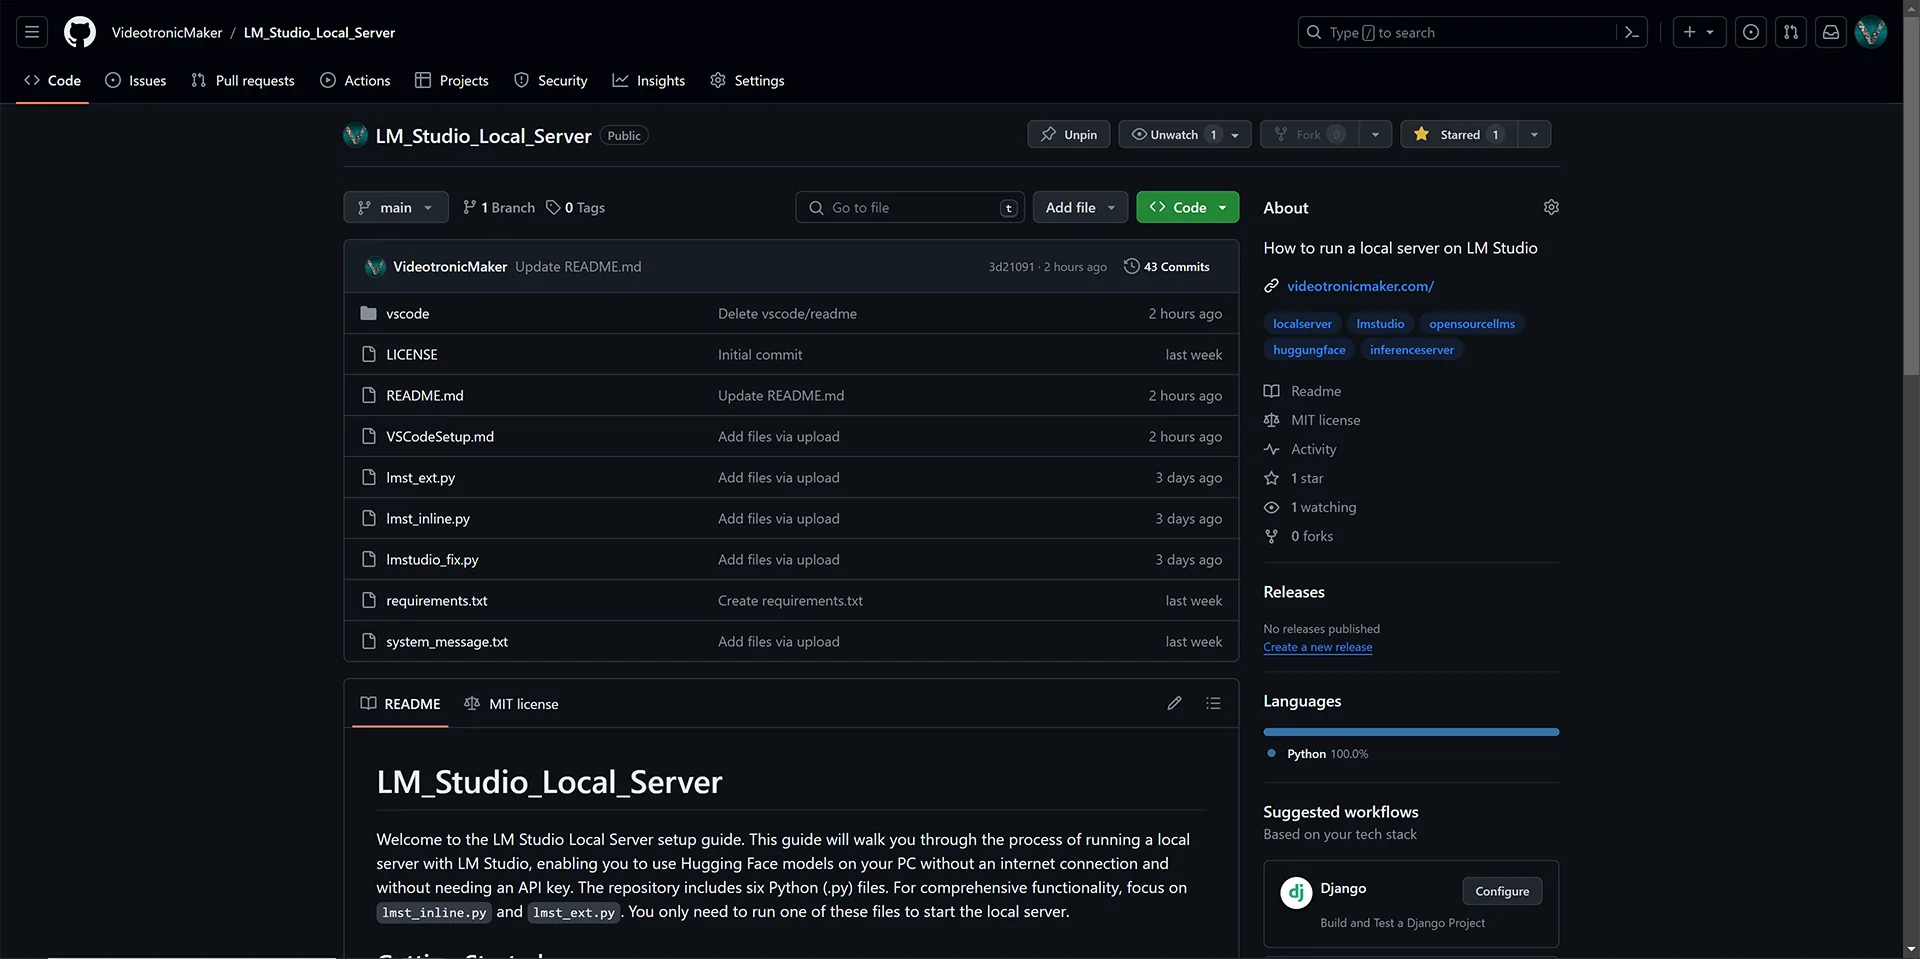
Run a Local Server with LM Studio: Tutorial - VTM Systems Store
Building a Self-Hosted AI Model Inference Server with Ollama, NVIDIA ...
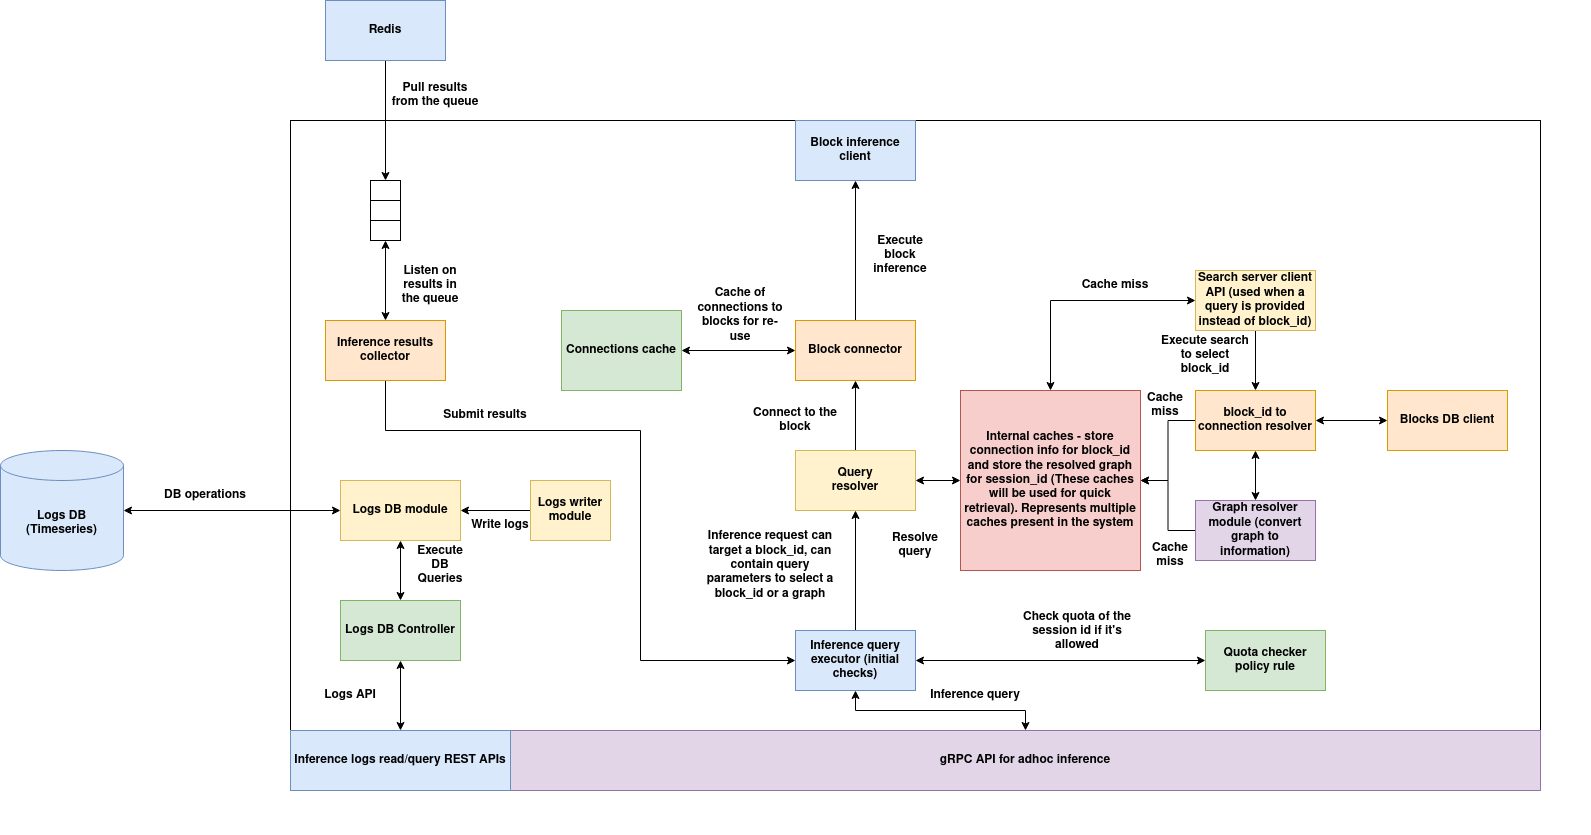
Inference server - AIGr.id
LM Studio TTS Google Inference Server-API
Implementation of NoMAD-Attention: Enhancing LLM Inference Efficiency ...
Advertisement Space (336x280)
GitHub - whutbd/ScaleLLM-llm-infer: A high-performance inference system ...
GitHub - intel/ipex-llm: Accelerate local LLM inference and finetuning ...

LLM Inference Efficiency | NexT
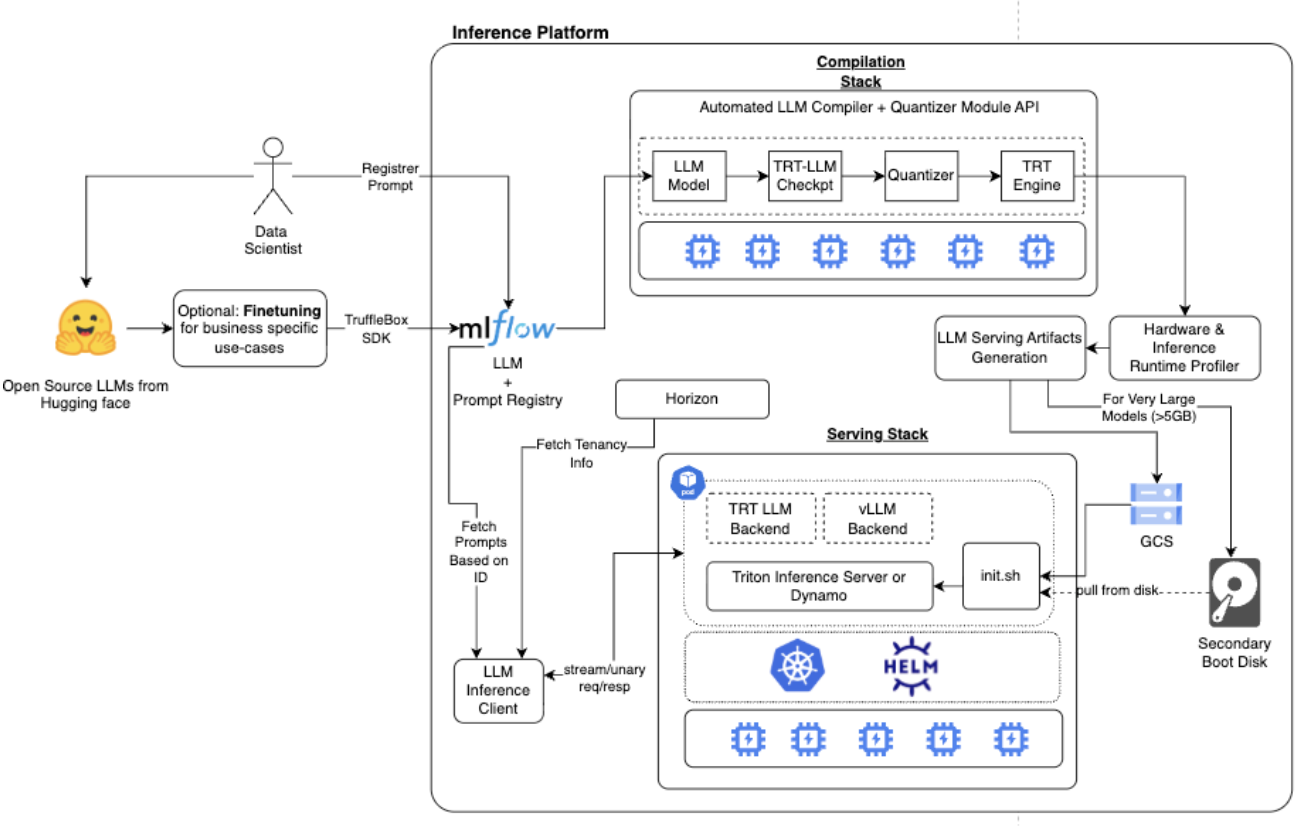
Designing a Production-Grade LLM Inference Platform: From Model Weights ...
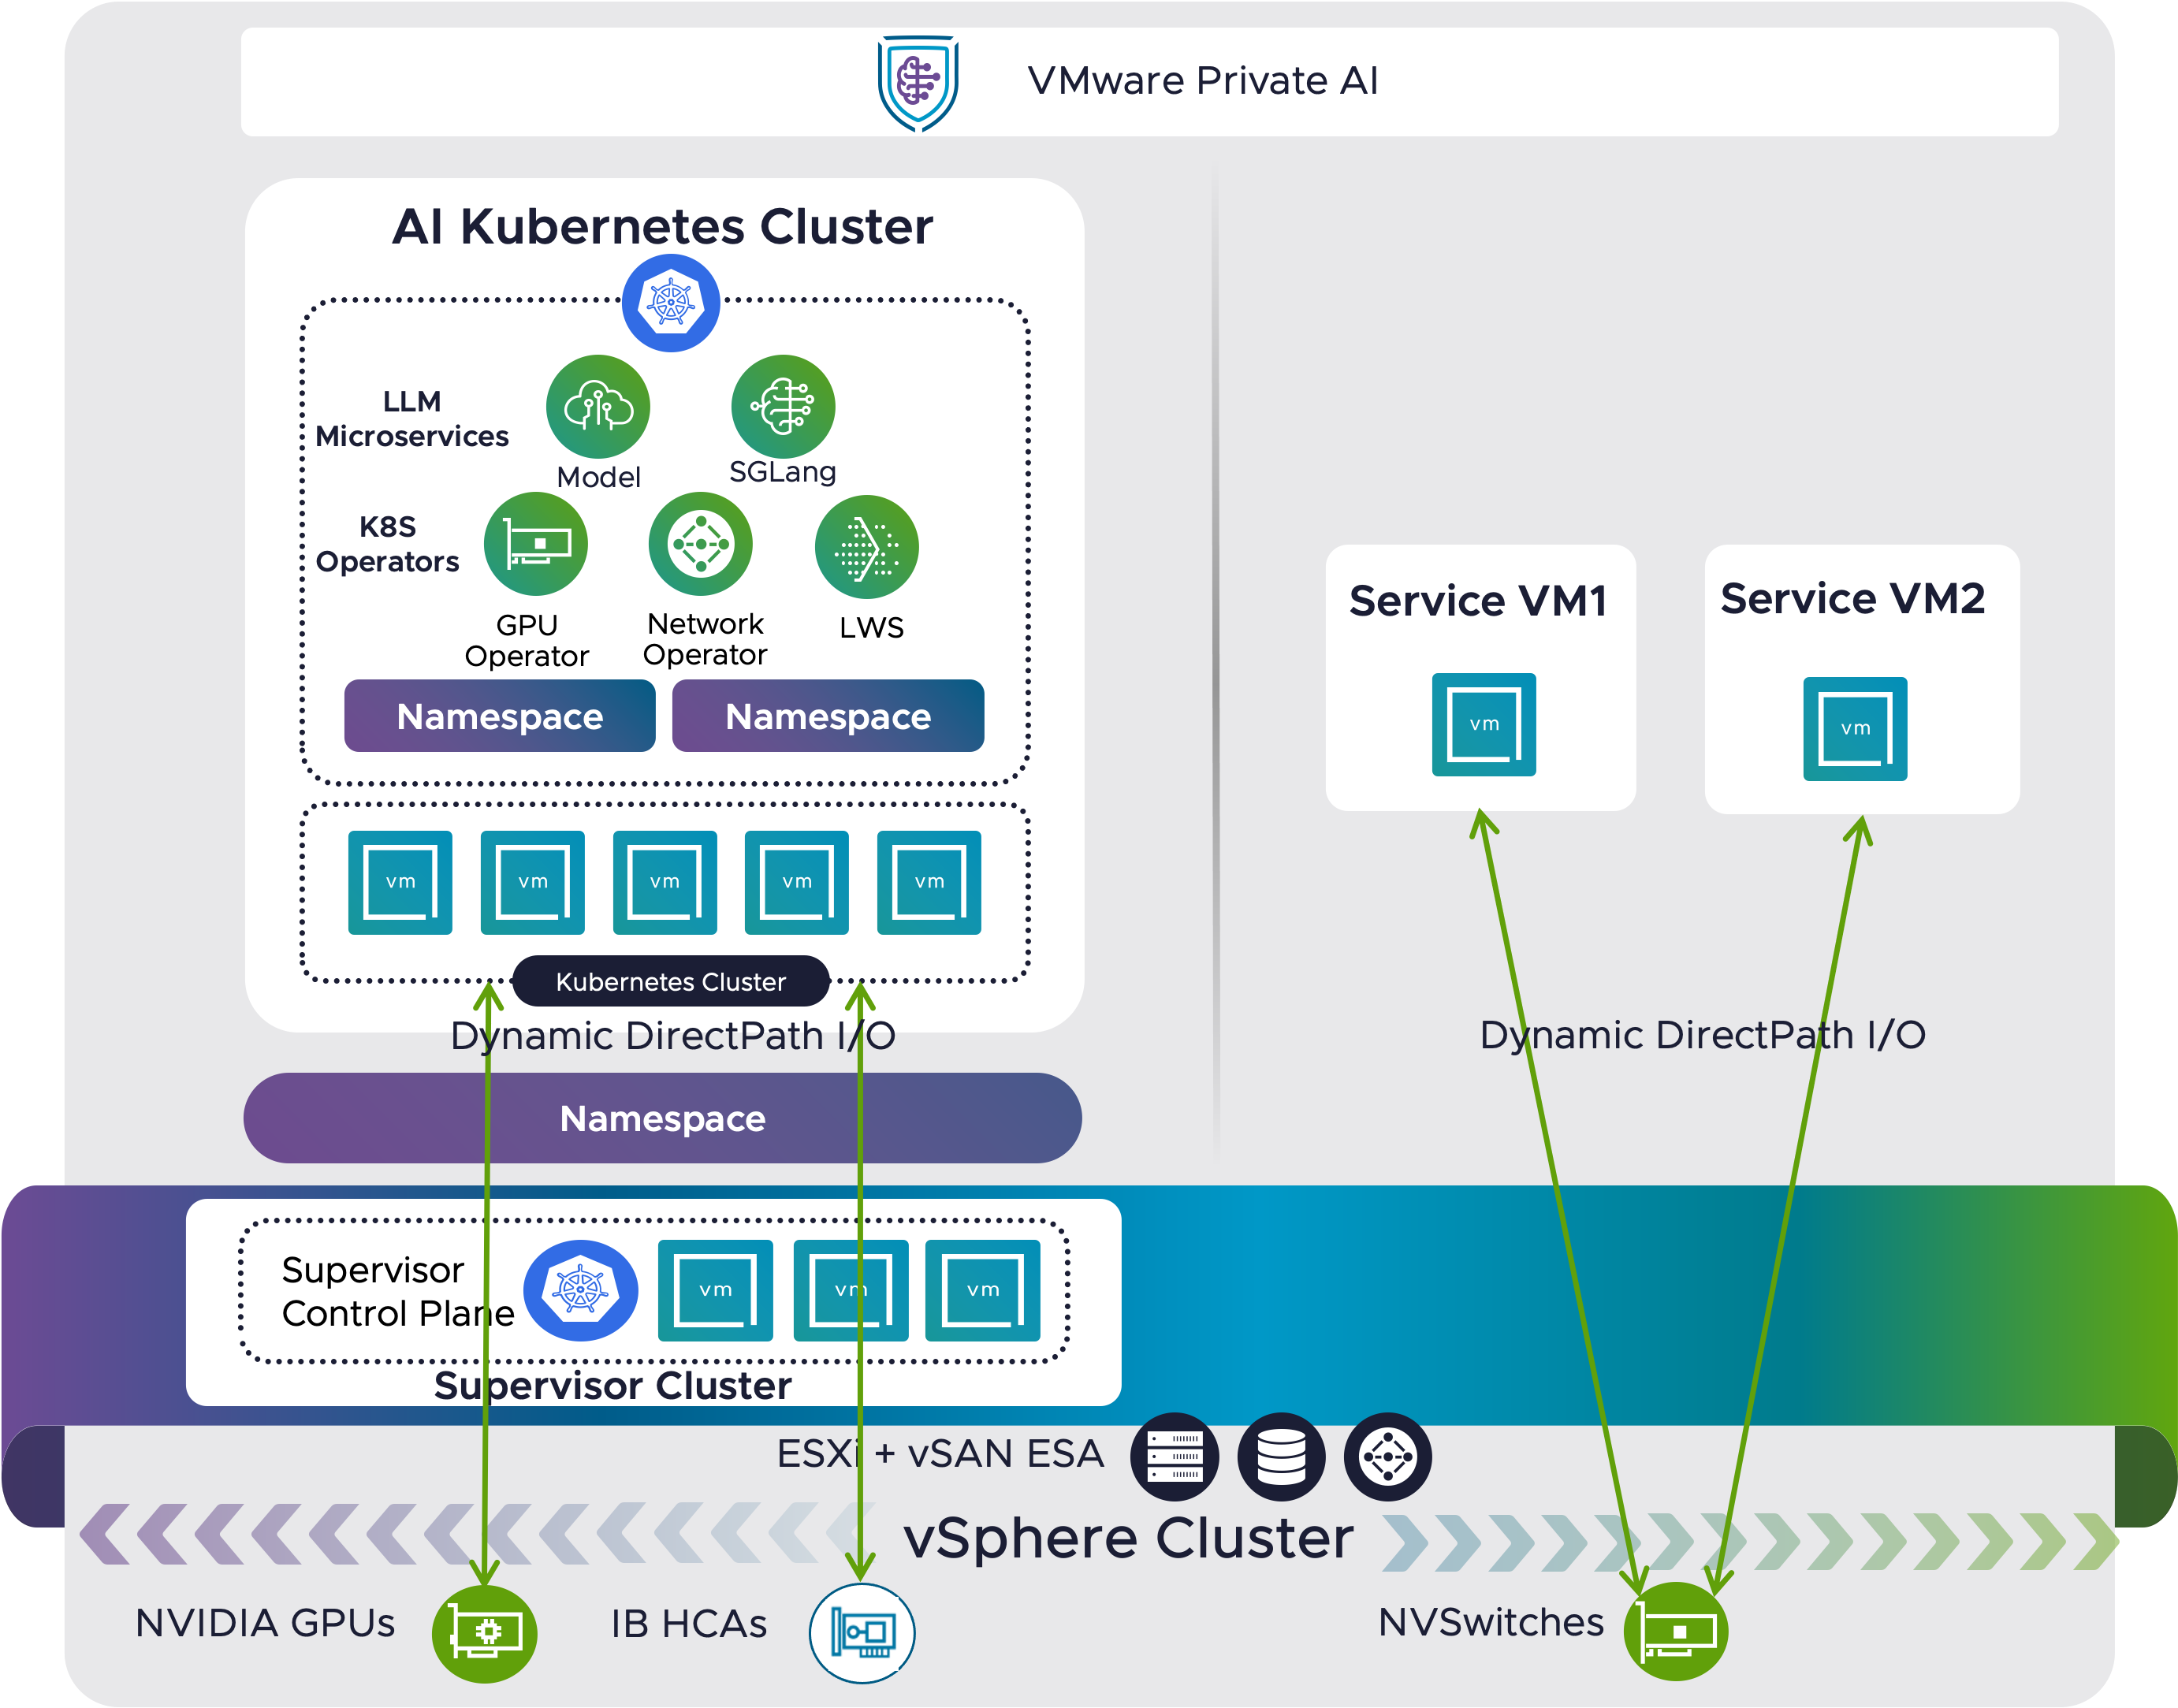
Deploy Distributed LLM Inference with GPUDirect RDMA over InfiniBand in ...

The Future of Serverless Inference for Large Language Models — AI ...
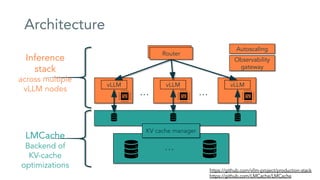
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

GitHub - OpenCSGs/llm-inference: llm-inference is a platform for ...
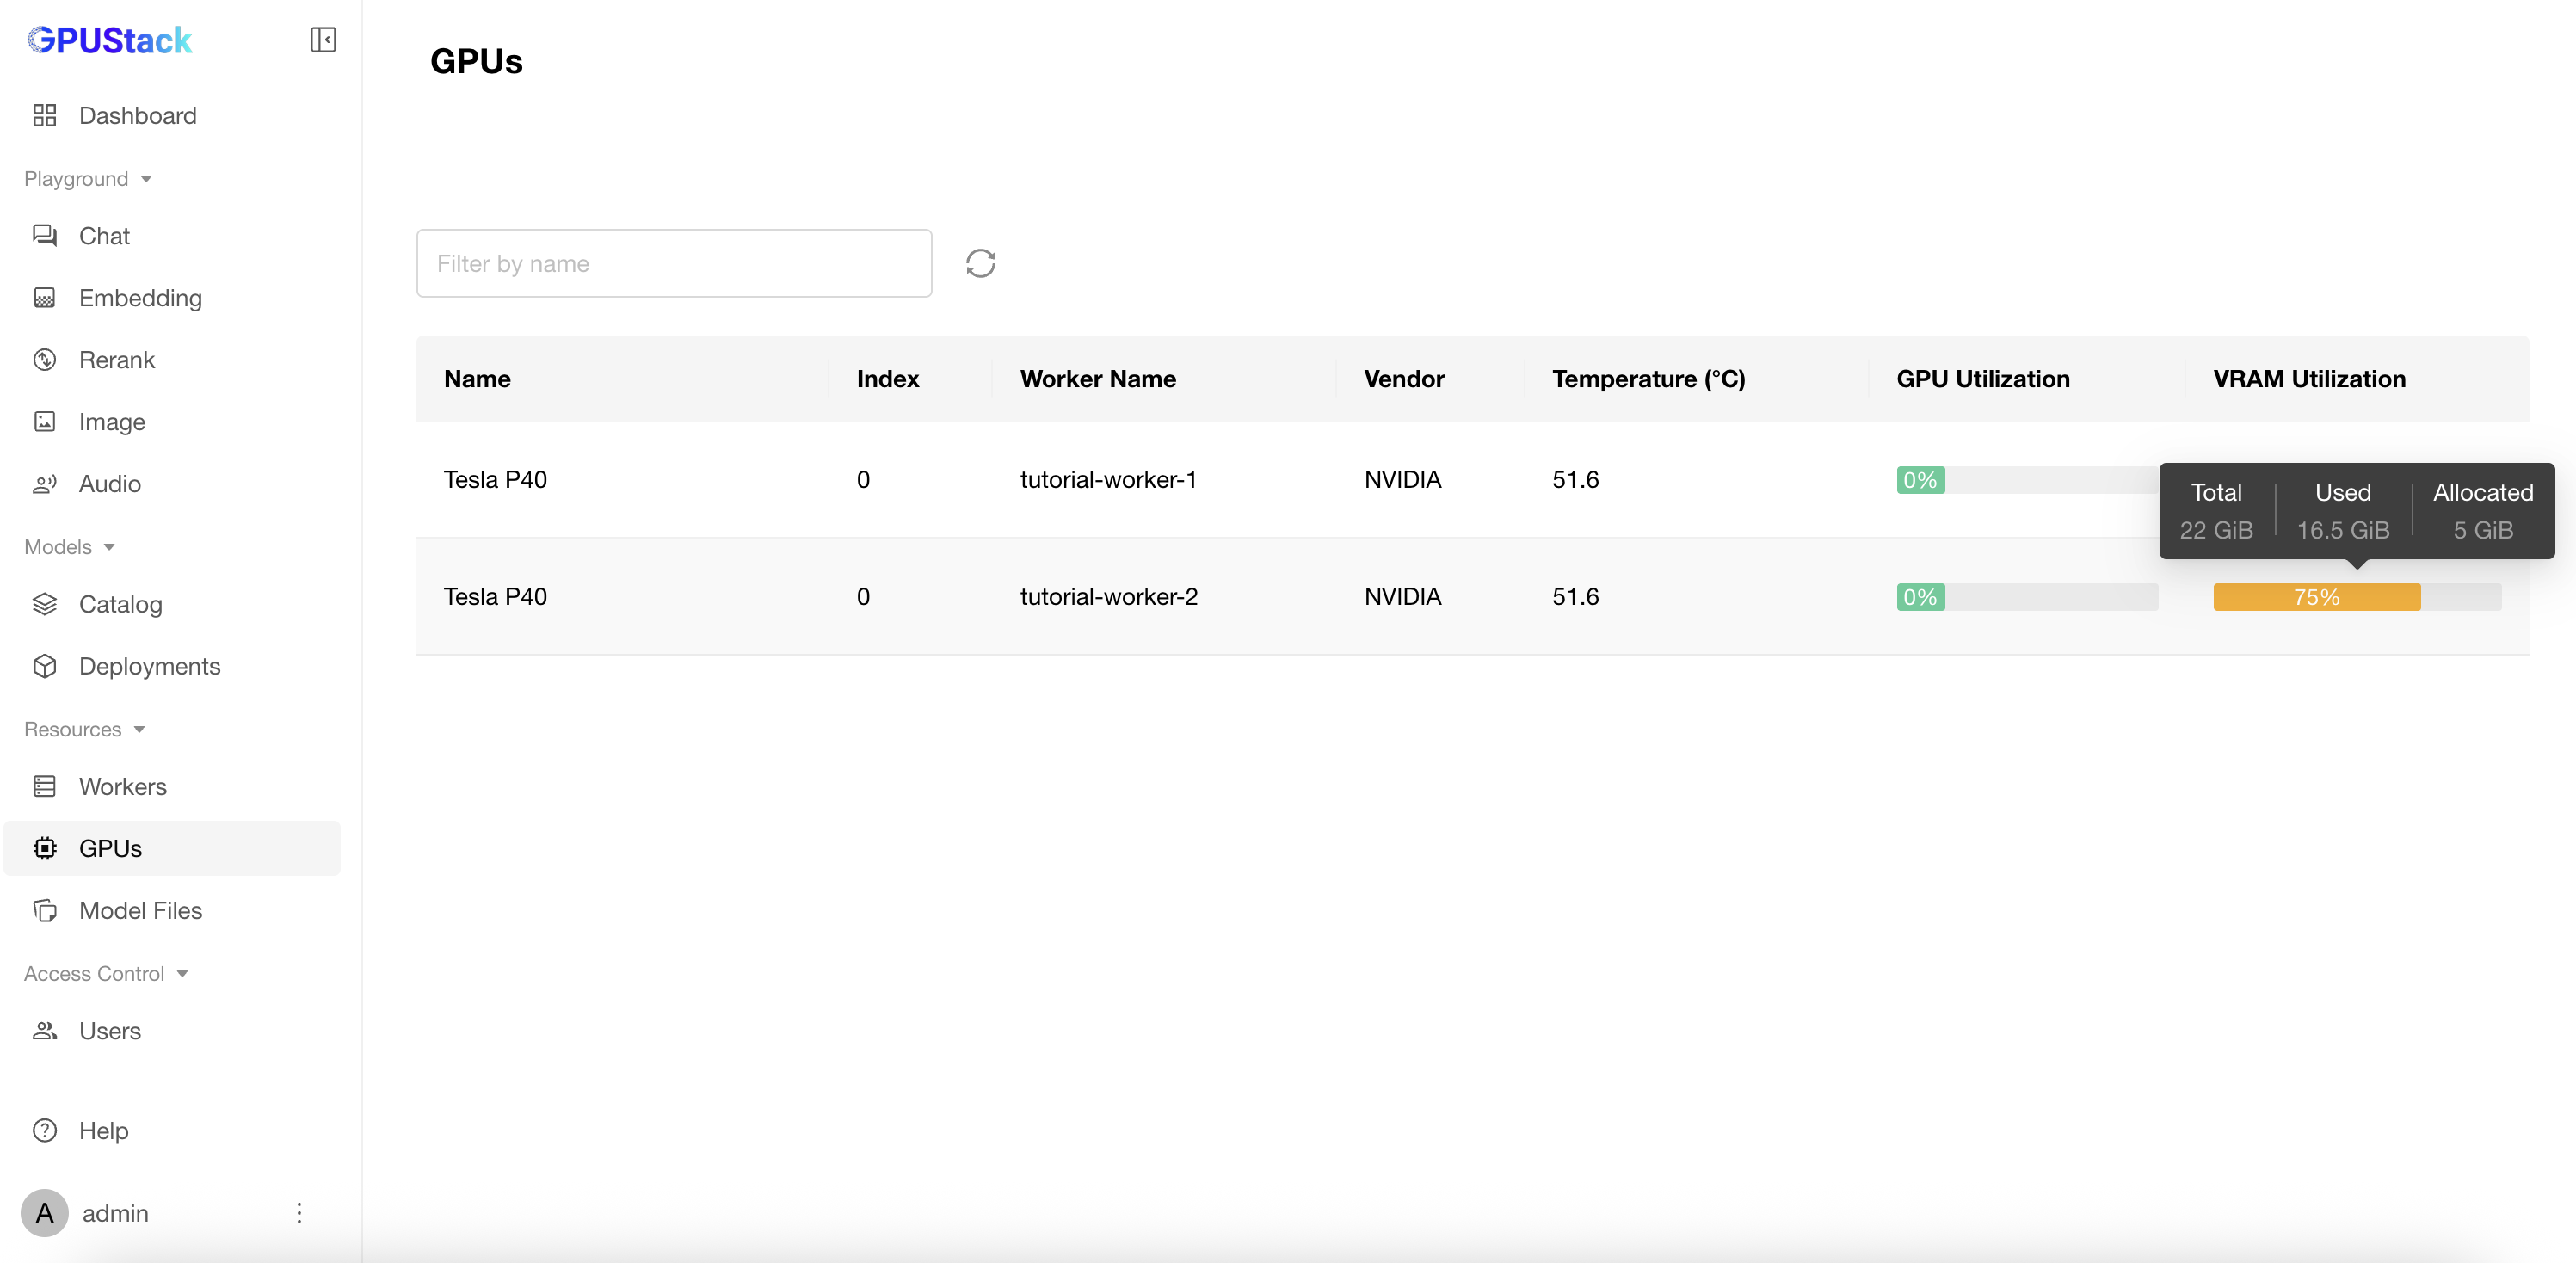
Performing Distributed Inference Across Workers (llama-box) - GPUStack
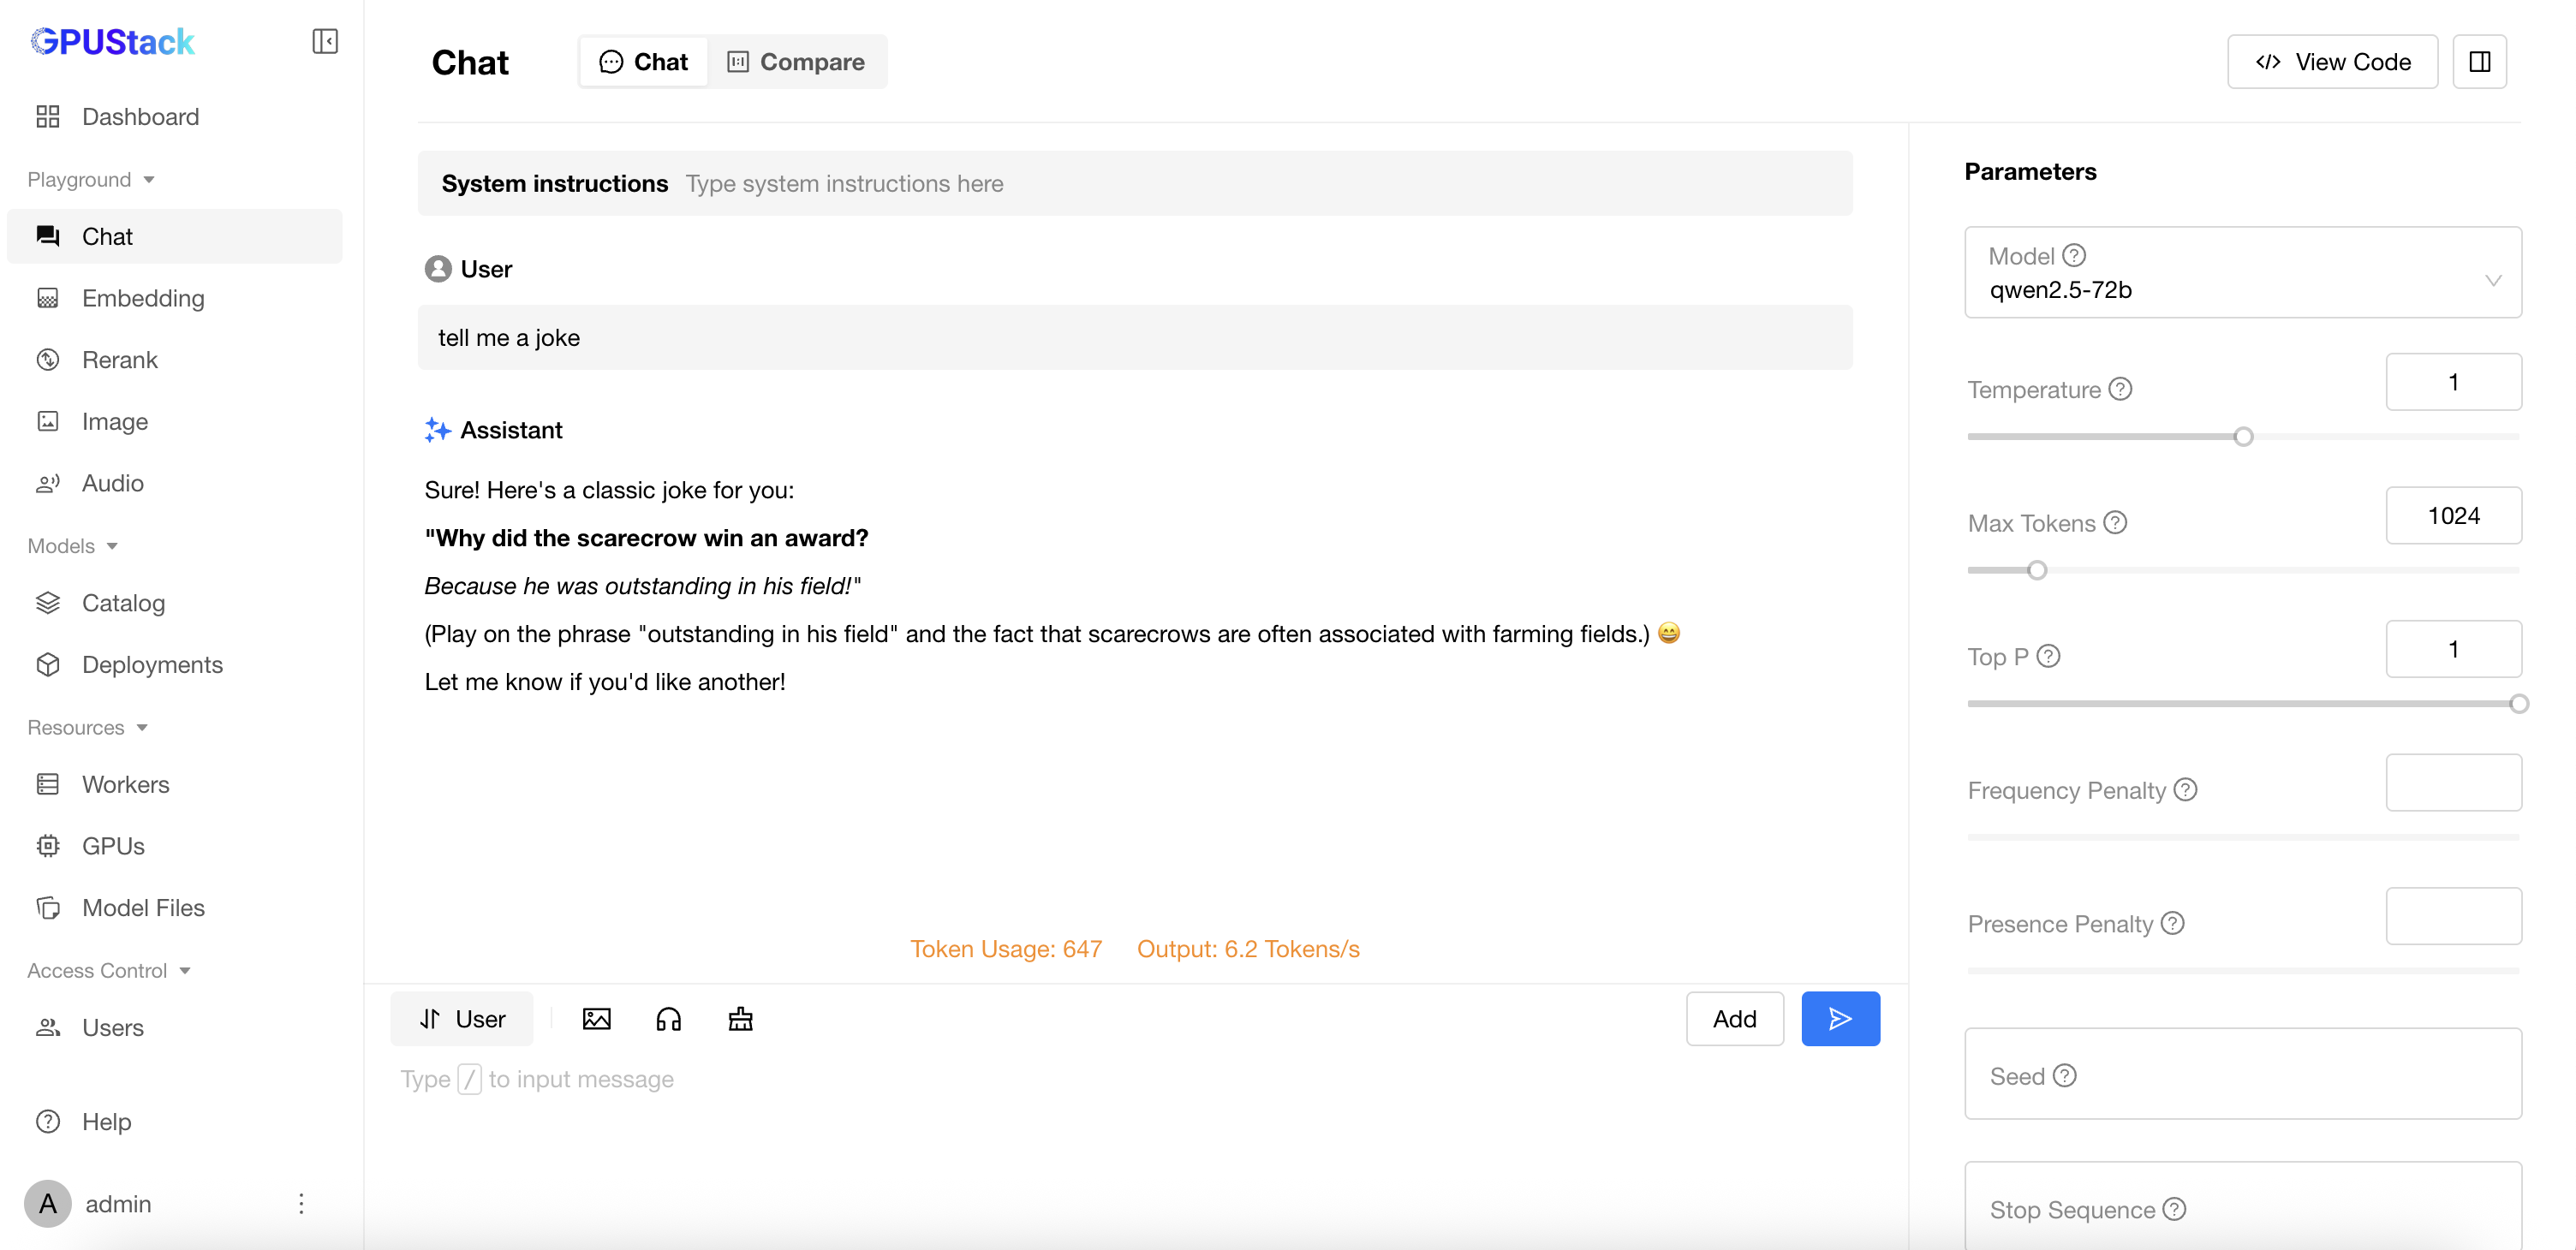
Performing Distributed Inference Across Workers (llama-box) - GPUStack
Advertisement Space (336x280)

How I Built a Production-Grade GitOps LLM Inference Stack on a $200 Homelab
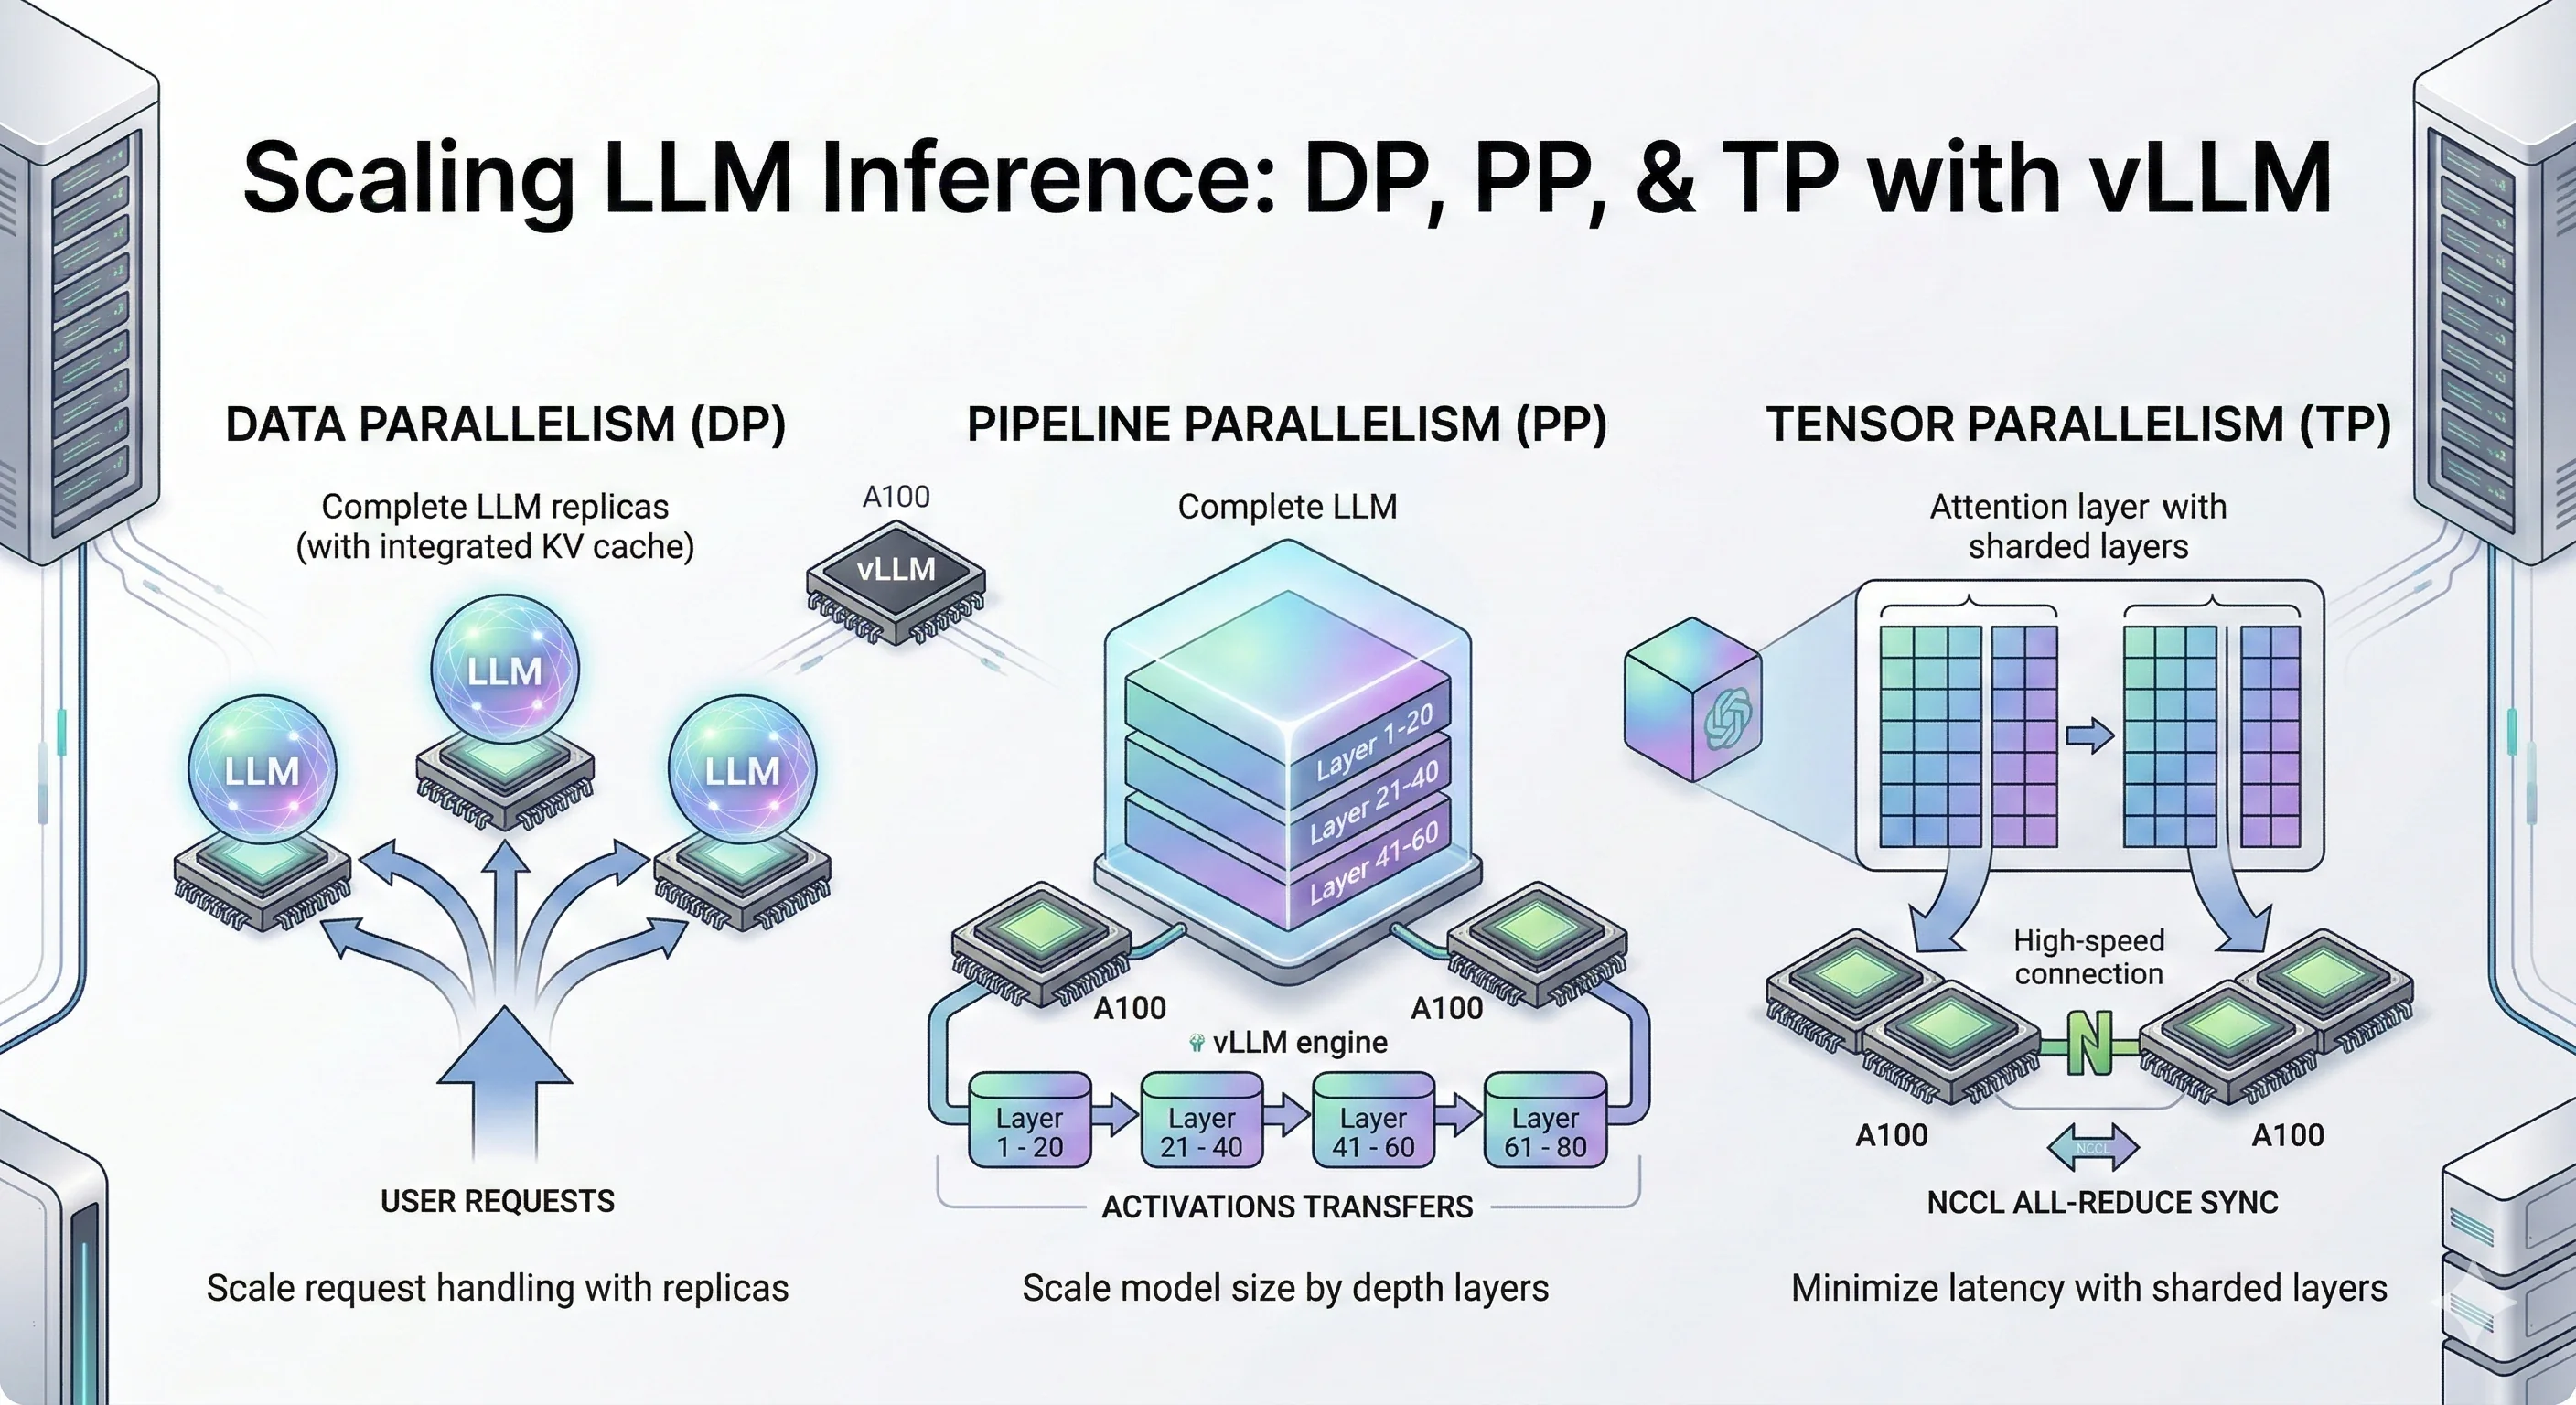
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
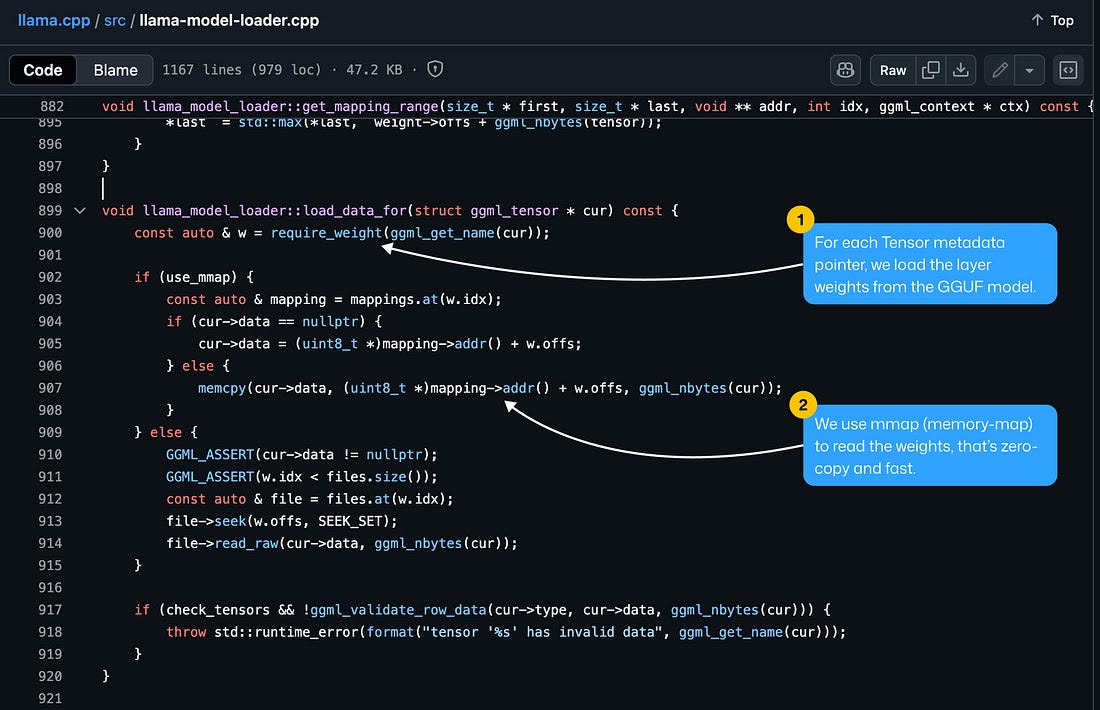
Local LLM Inference : llama.cpp, GGUF, Quantizations and GGML Explained
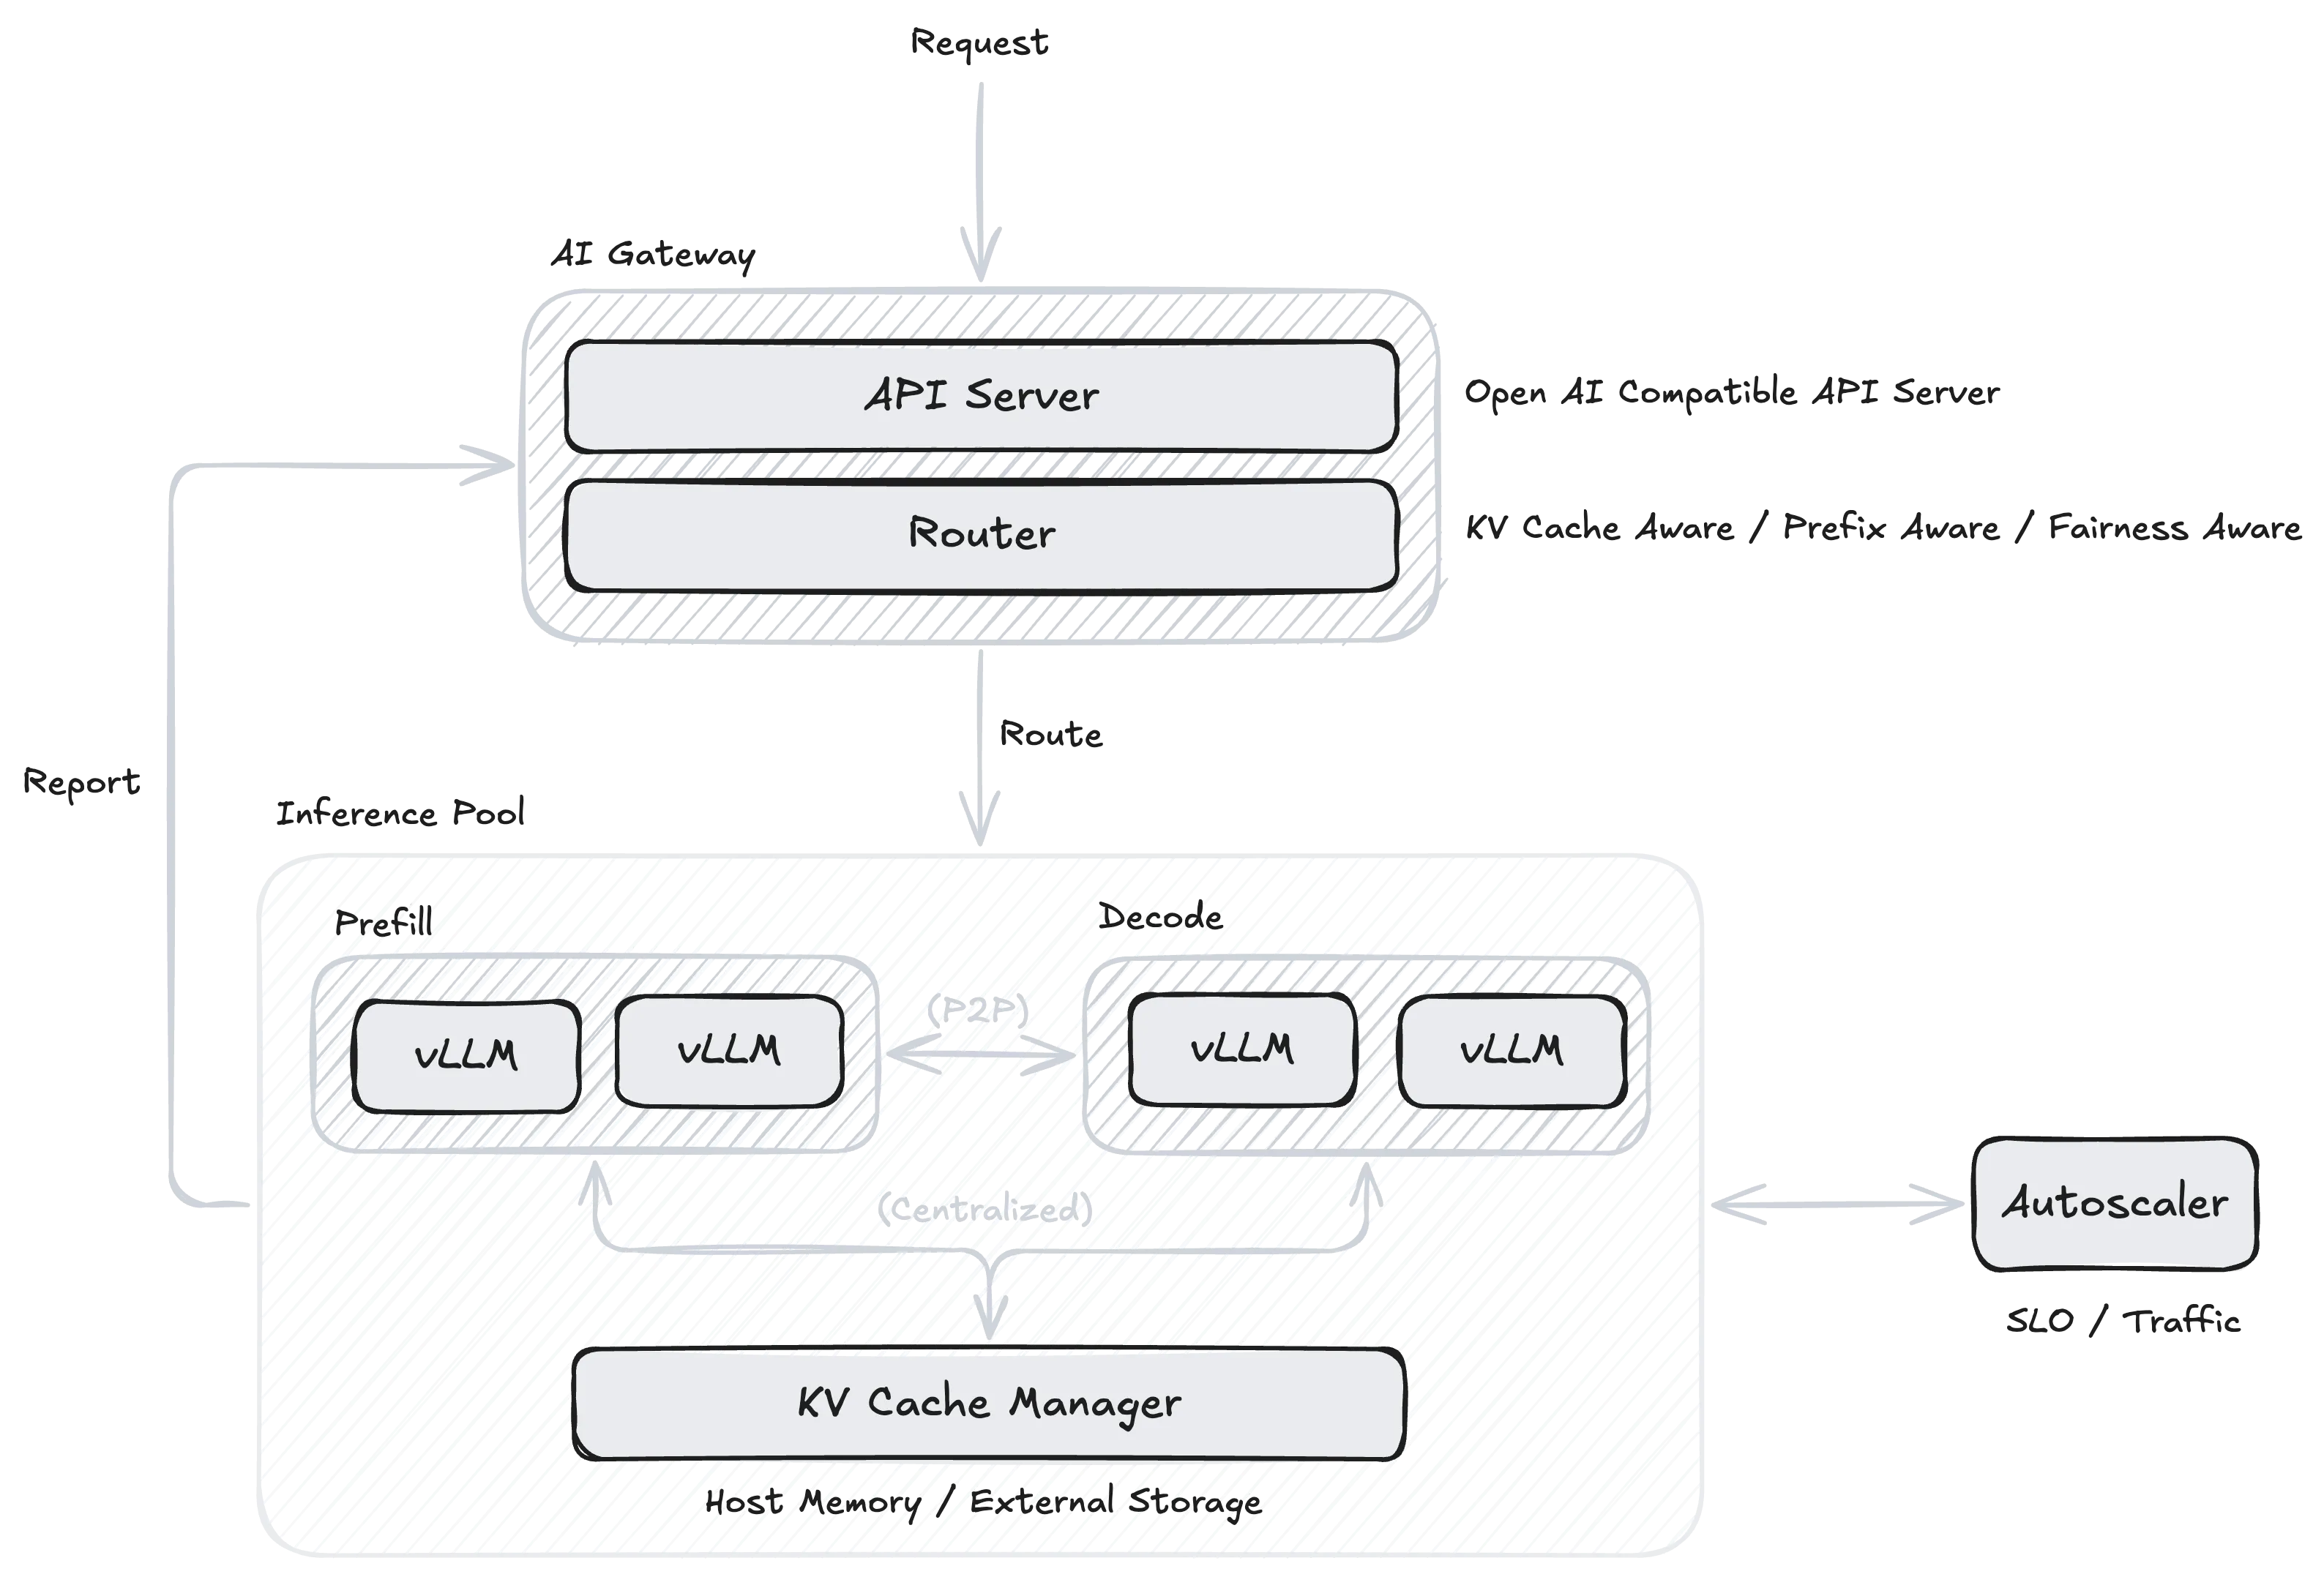
Kubernetes-Based LLM Inference Architectures: An Overview | Yuchen ...
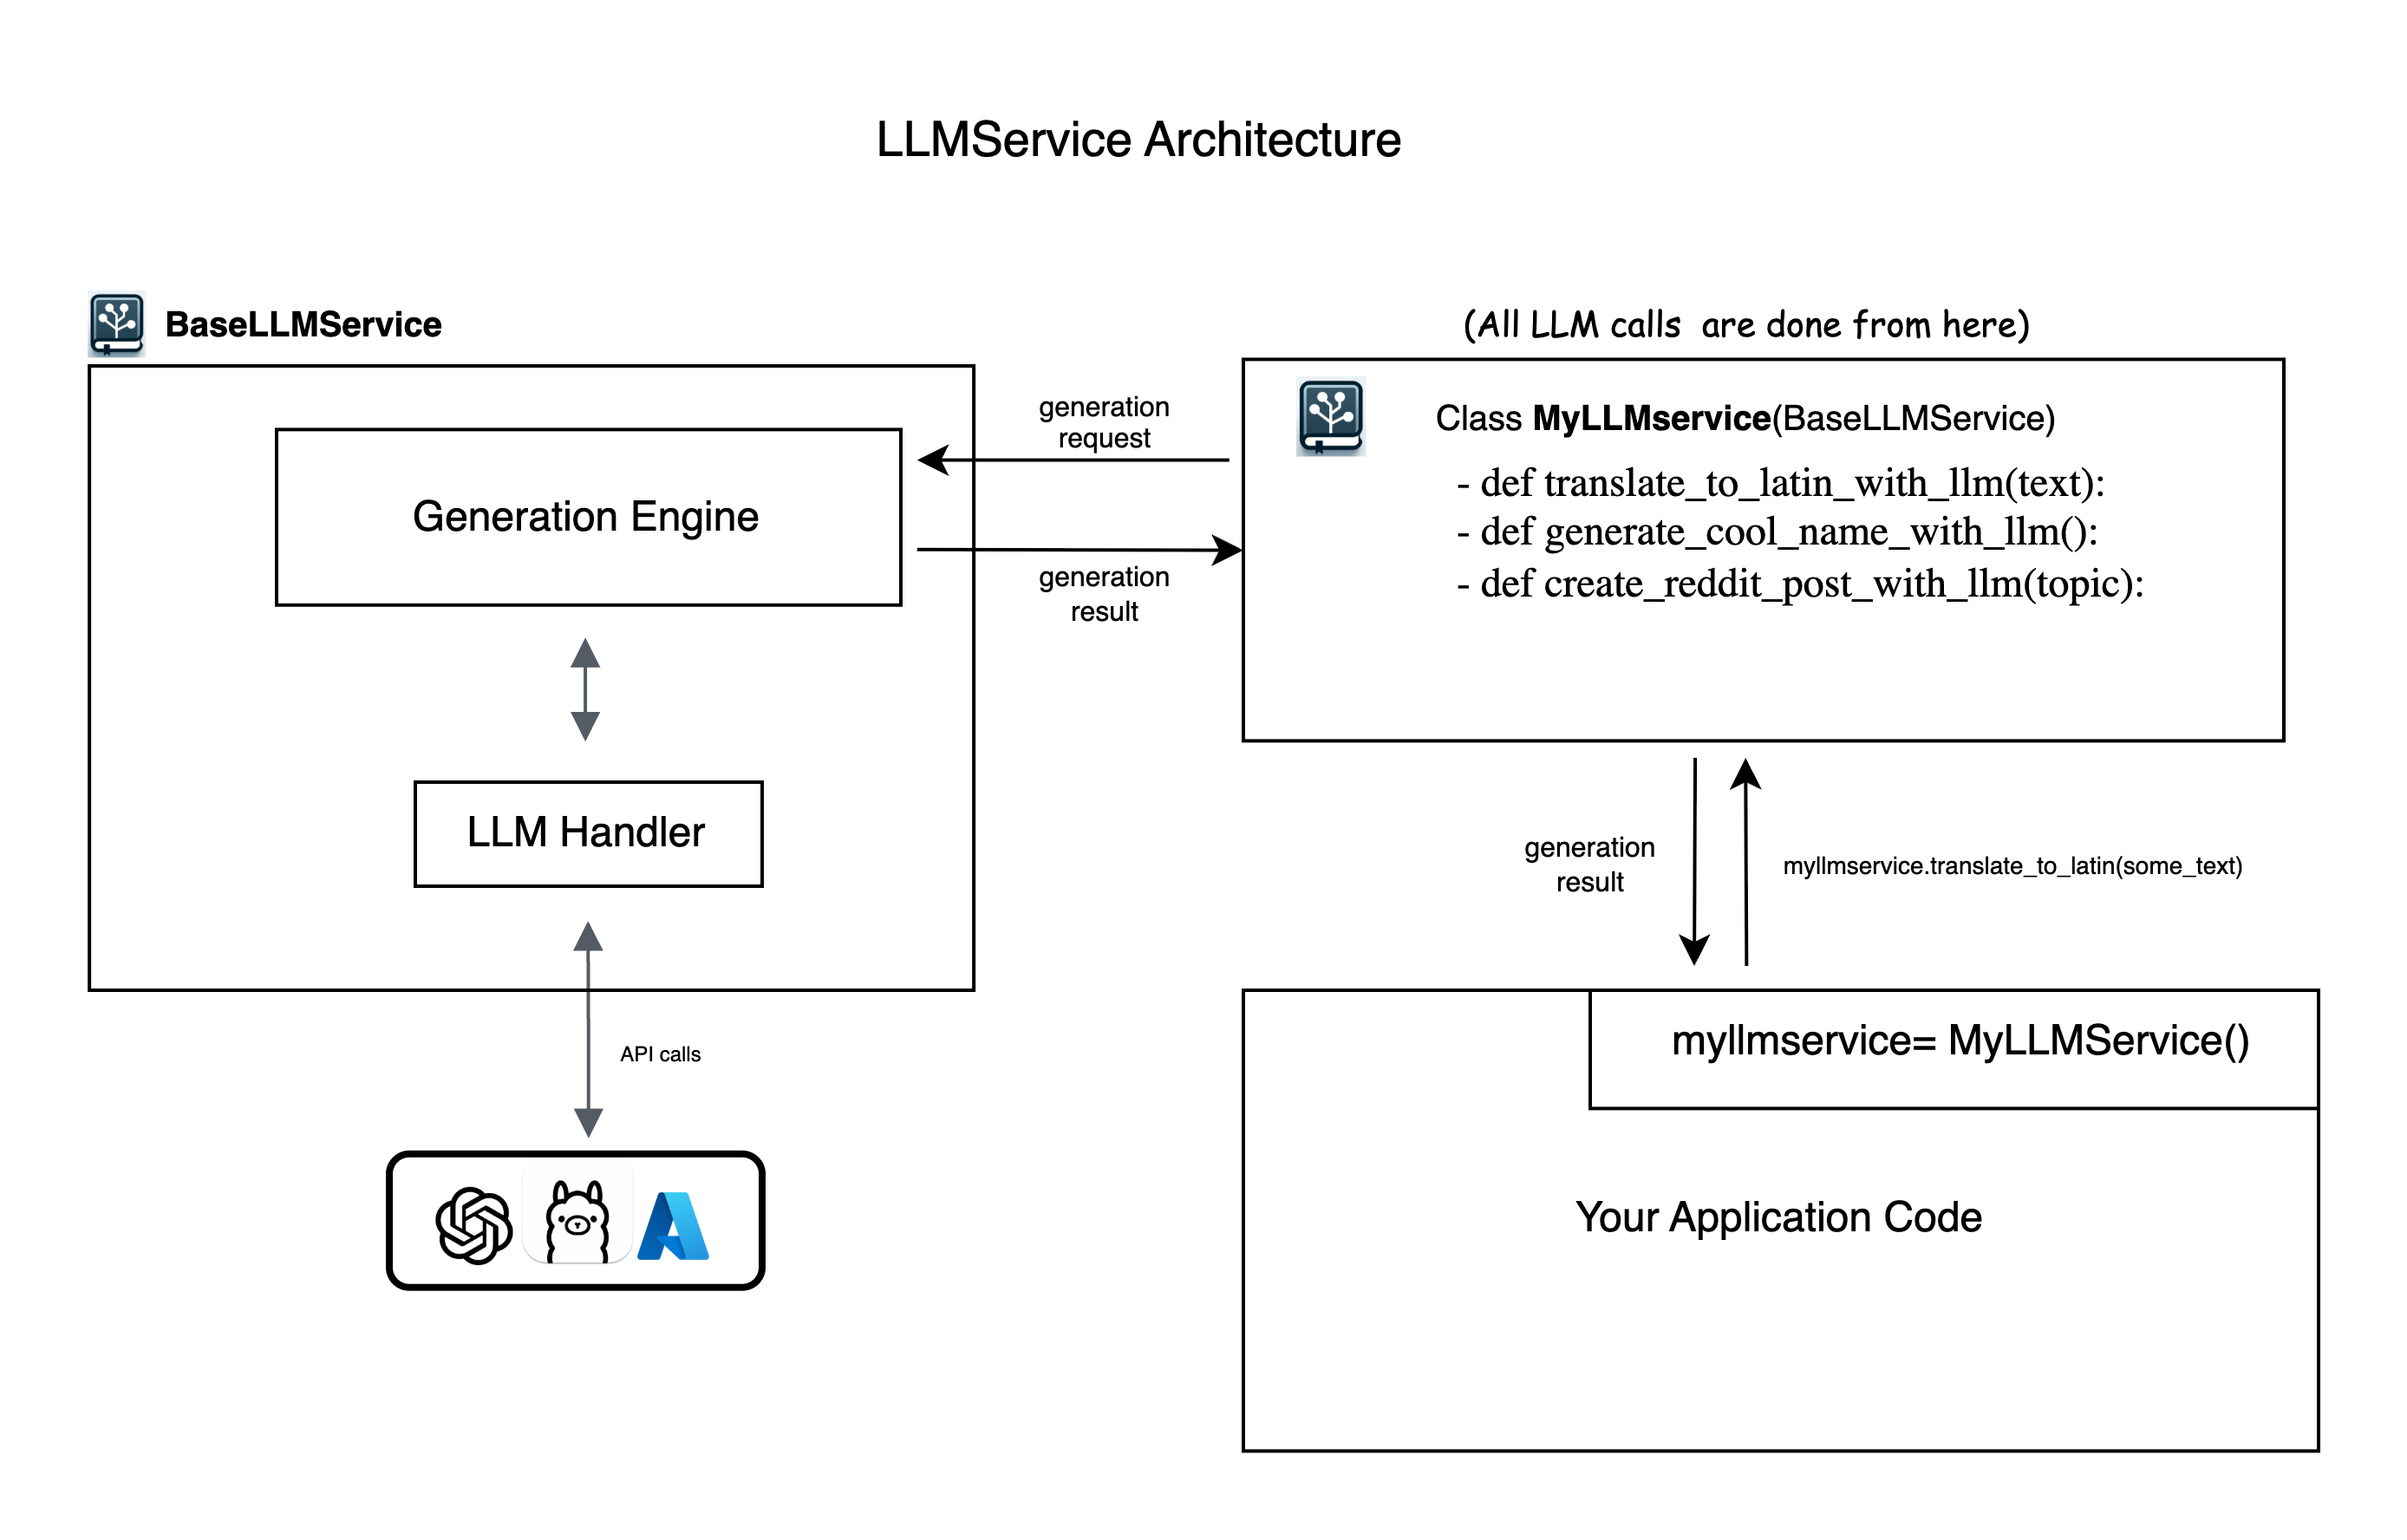
GitHub - karaposu/LLMService · GitHub
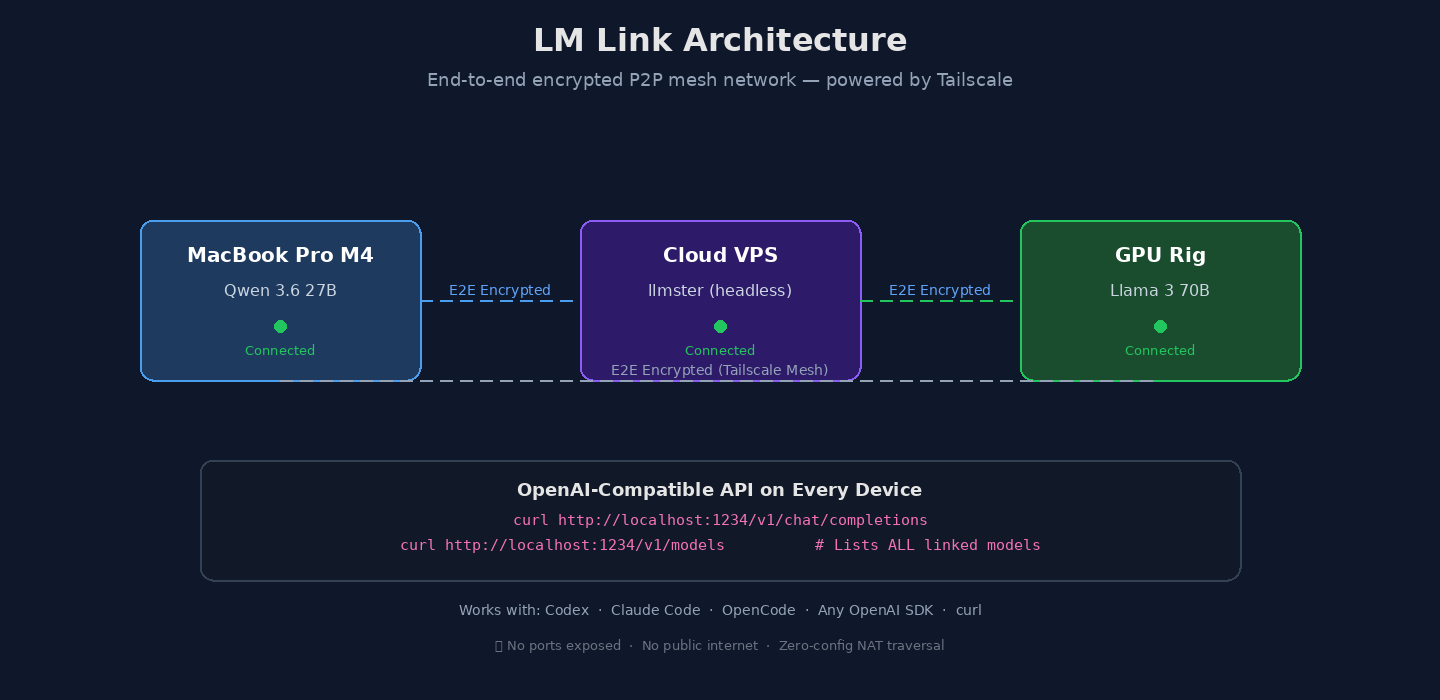
Run Your Mac's AI Models From Any Server — Zero Config, Zero Cost