
Github Ktk488aliyun Gpu Llm Deployment Gpu
GPU Guide for LLM Deployment - RTX 4090 to A100 Benchmarks (2026)
GitHub - BrandonKang/GPU-LLM-test: testing GPU performance for LLM use ...
GitHub - MegaStood/Intell-gpu-llm-guide: tuitorial for intel gpu llm ...
GitHub - gpustack/gpustack: Simple, scalable AI model deployment on GPU ...
GitHub - RichyMeas/core-gpt: consumer GPU LLM experiments end to end ...
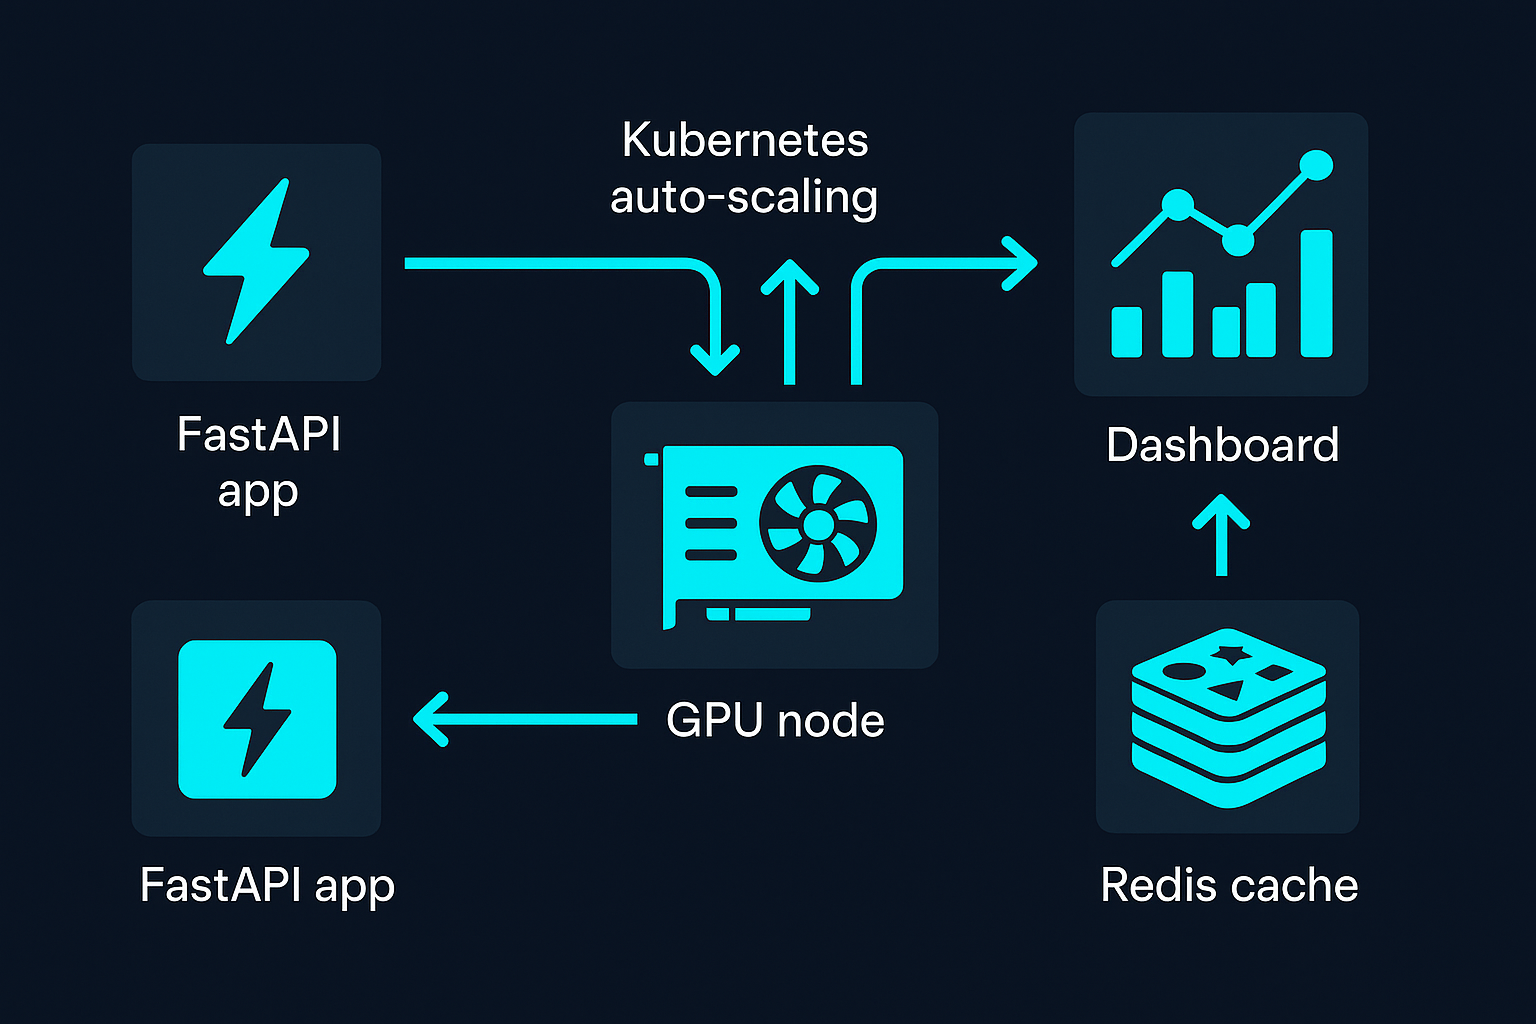
How to Launch a Production Ready LLM API with GPU Auto Scaling in Under ...
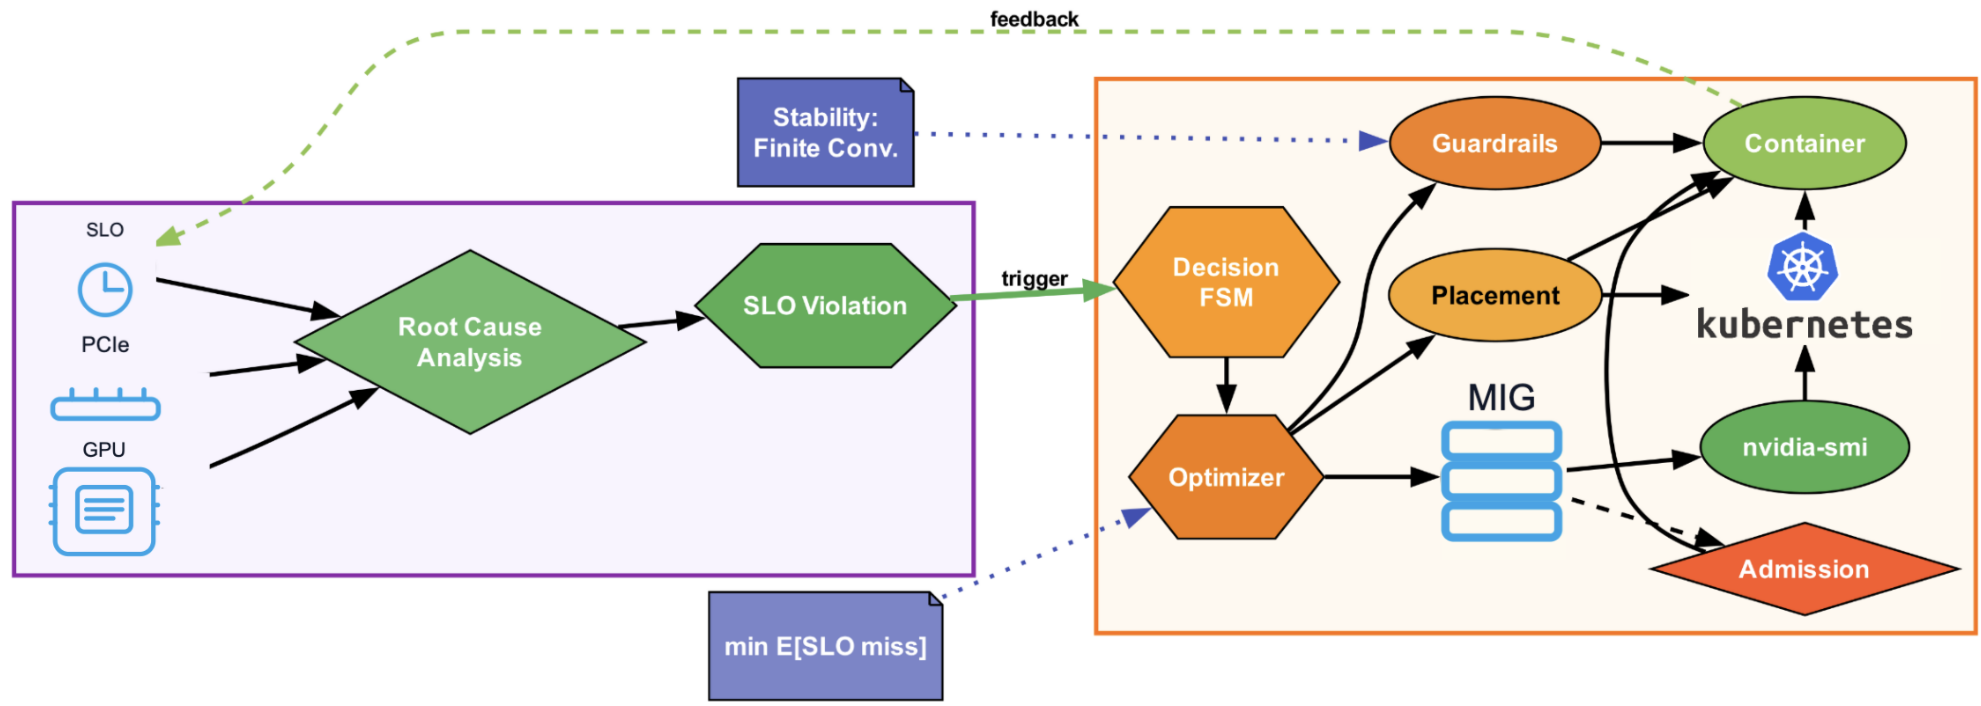
[논문 리뷰] Predictable LLM Serving on GPU Clusters
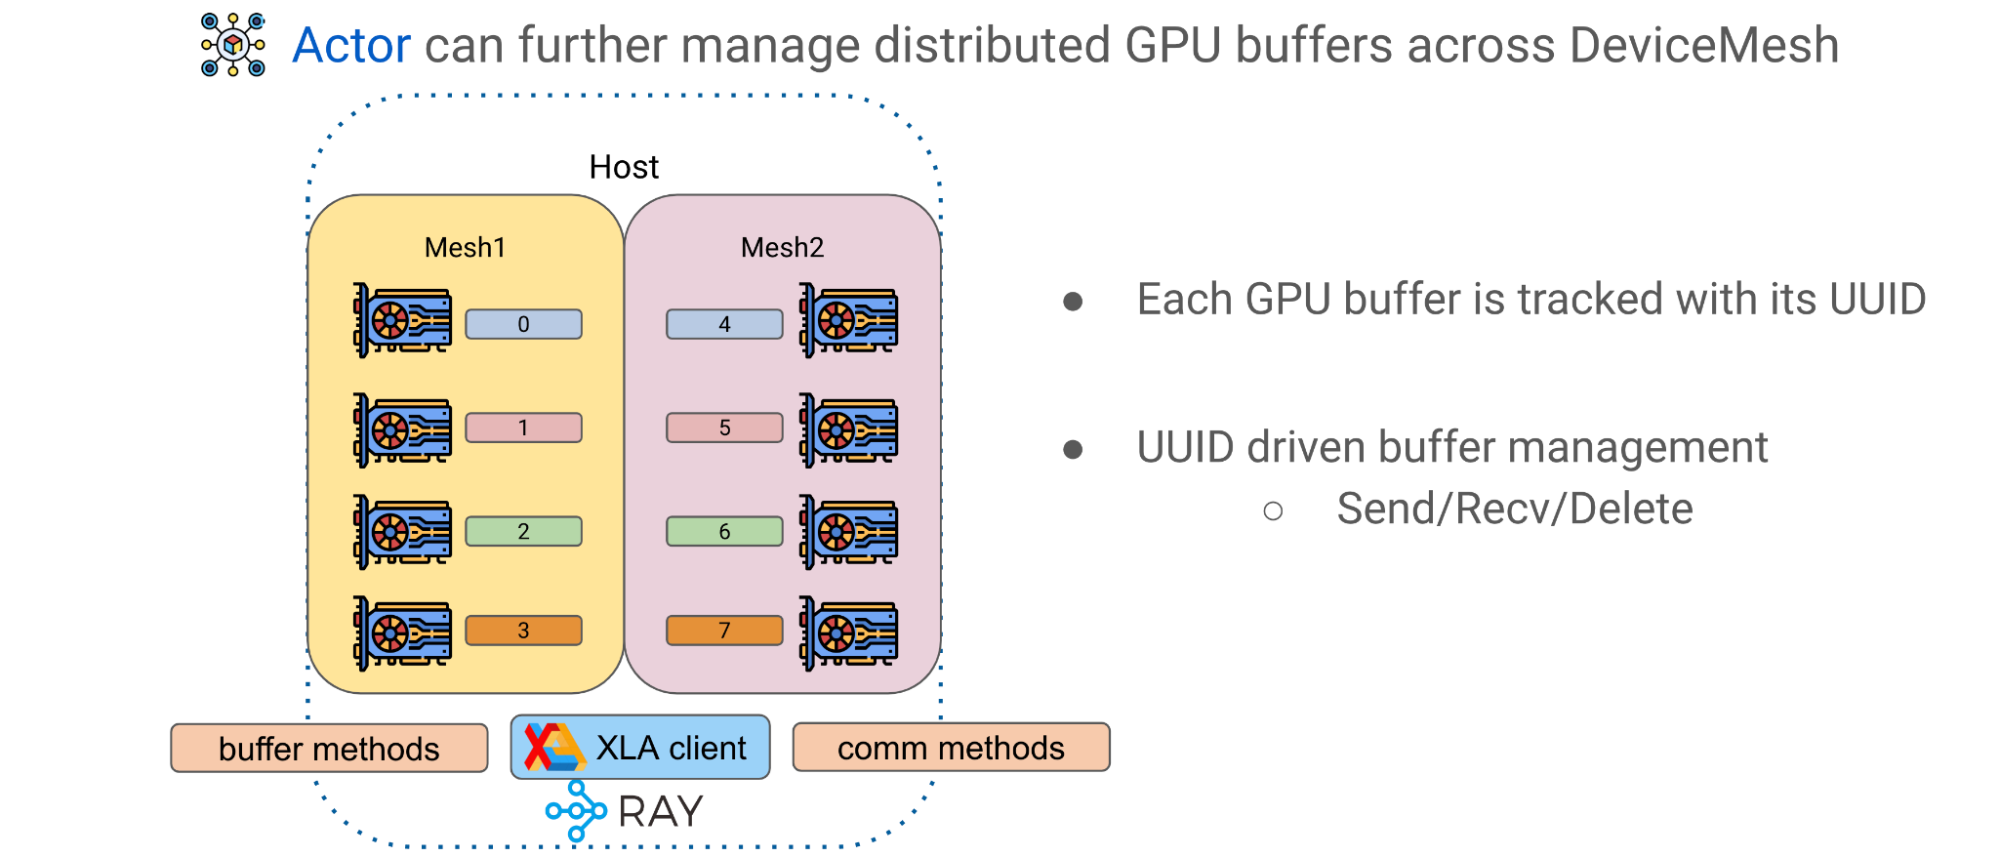
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray
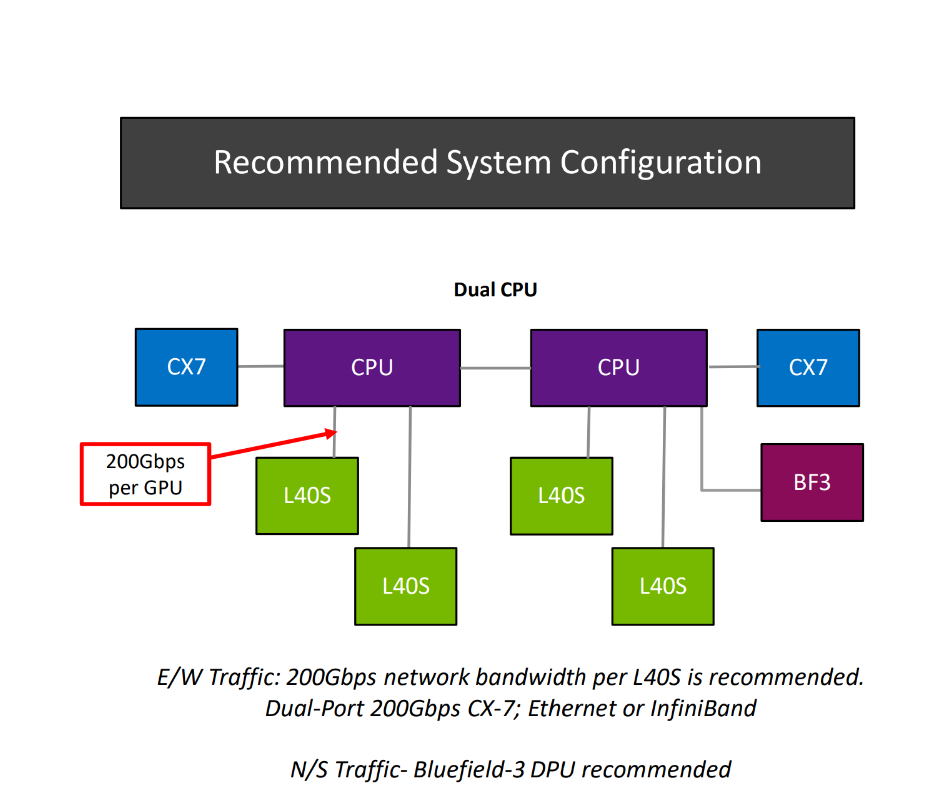
Choosing the Right GPU for LLM Inference and Training

LLM Inference - Consumer GPU performance | Puget Systems
Advertisement Space (300x250)

GPU Kernel Optimization Beyond Full Builds: An LLM Framework with ...

Deploying LLM Inference on Kubernetes with the NVIDIA GPU Operator: A ...
Reserved GPU for LLM APIs — Optimize Cost for High Volume Traffic

LLM Inference - NVIDIA RTX GPU Performance | Puget Systems
Embedded LLM Launches TokenVisor to Monetize AMD AI GPU
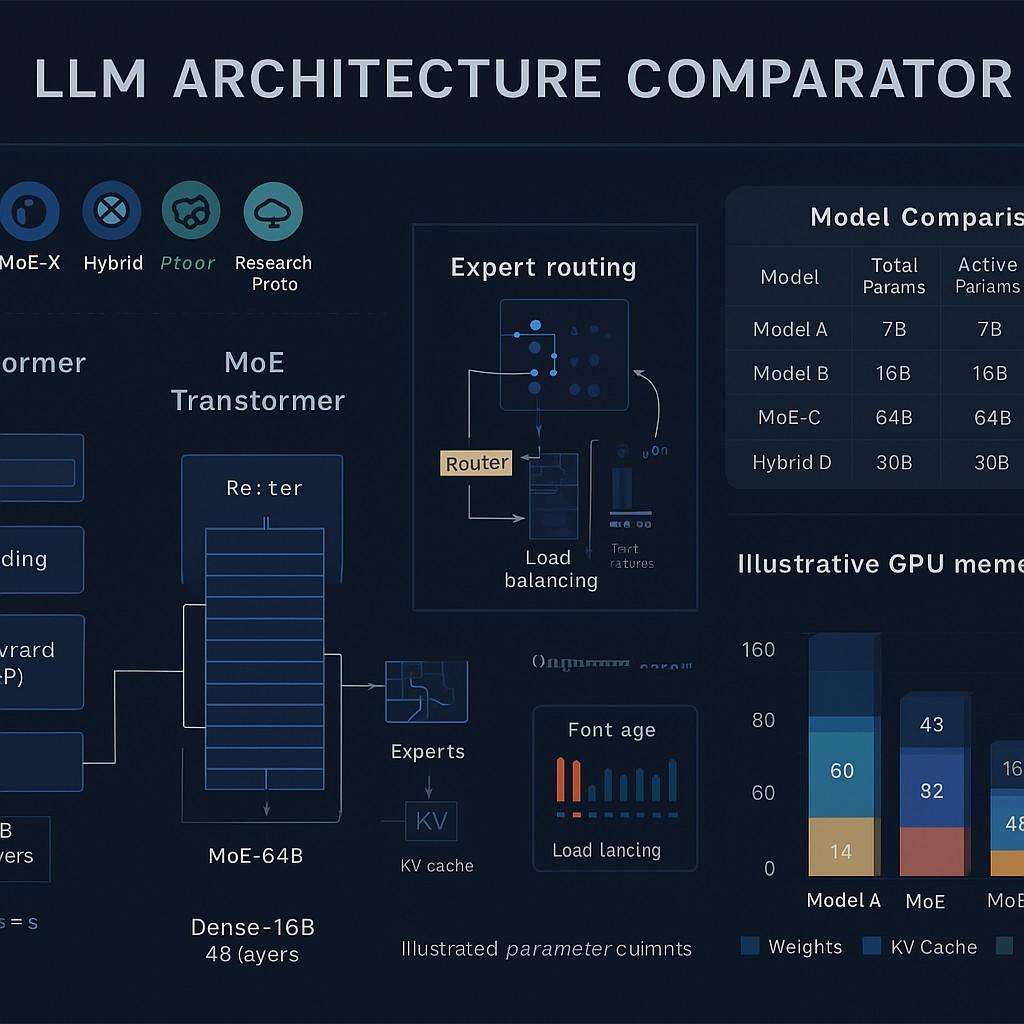
Free LLM VRAM Calculator: GPU Memory Requirements for Large Language ...
Production LLM API with GPU Auto Scaling in Under an Hour
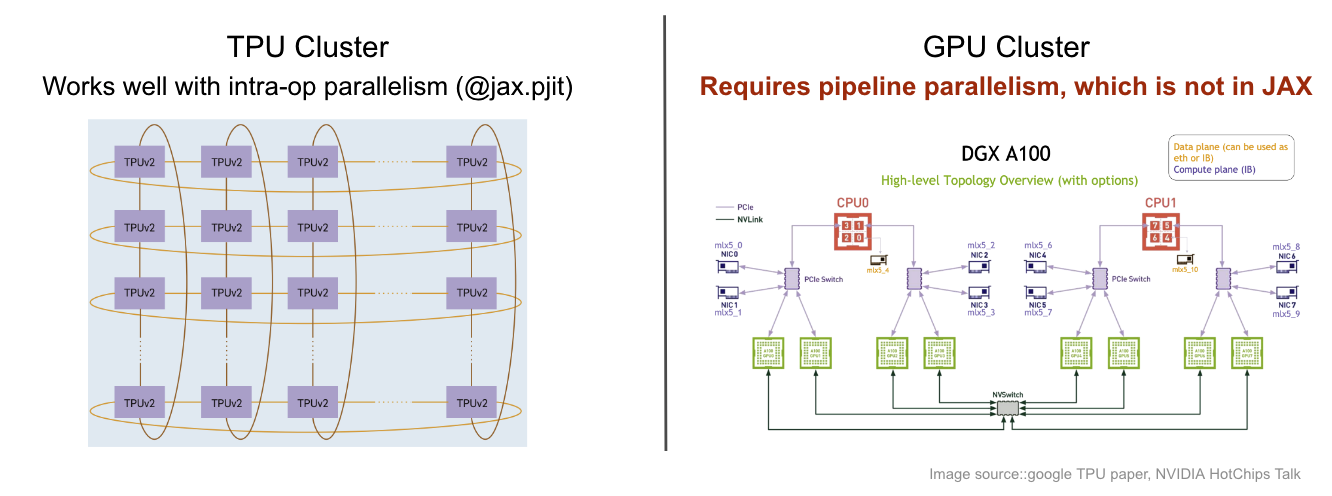
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray

The LLM GPU Buying Guide - August 2023 : r/LocalLLaMA

人工智能 - 面向国产 DCU 加速卡的 LLM Agent 驱动 GPU 内核优化框架适配与验证 - 个人文章 - SegmentFault 思否
Advertisement Space (336x280)
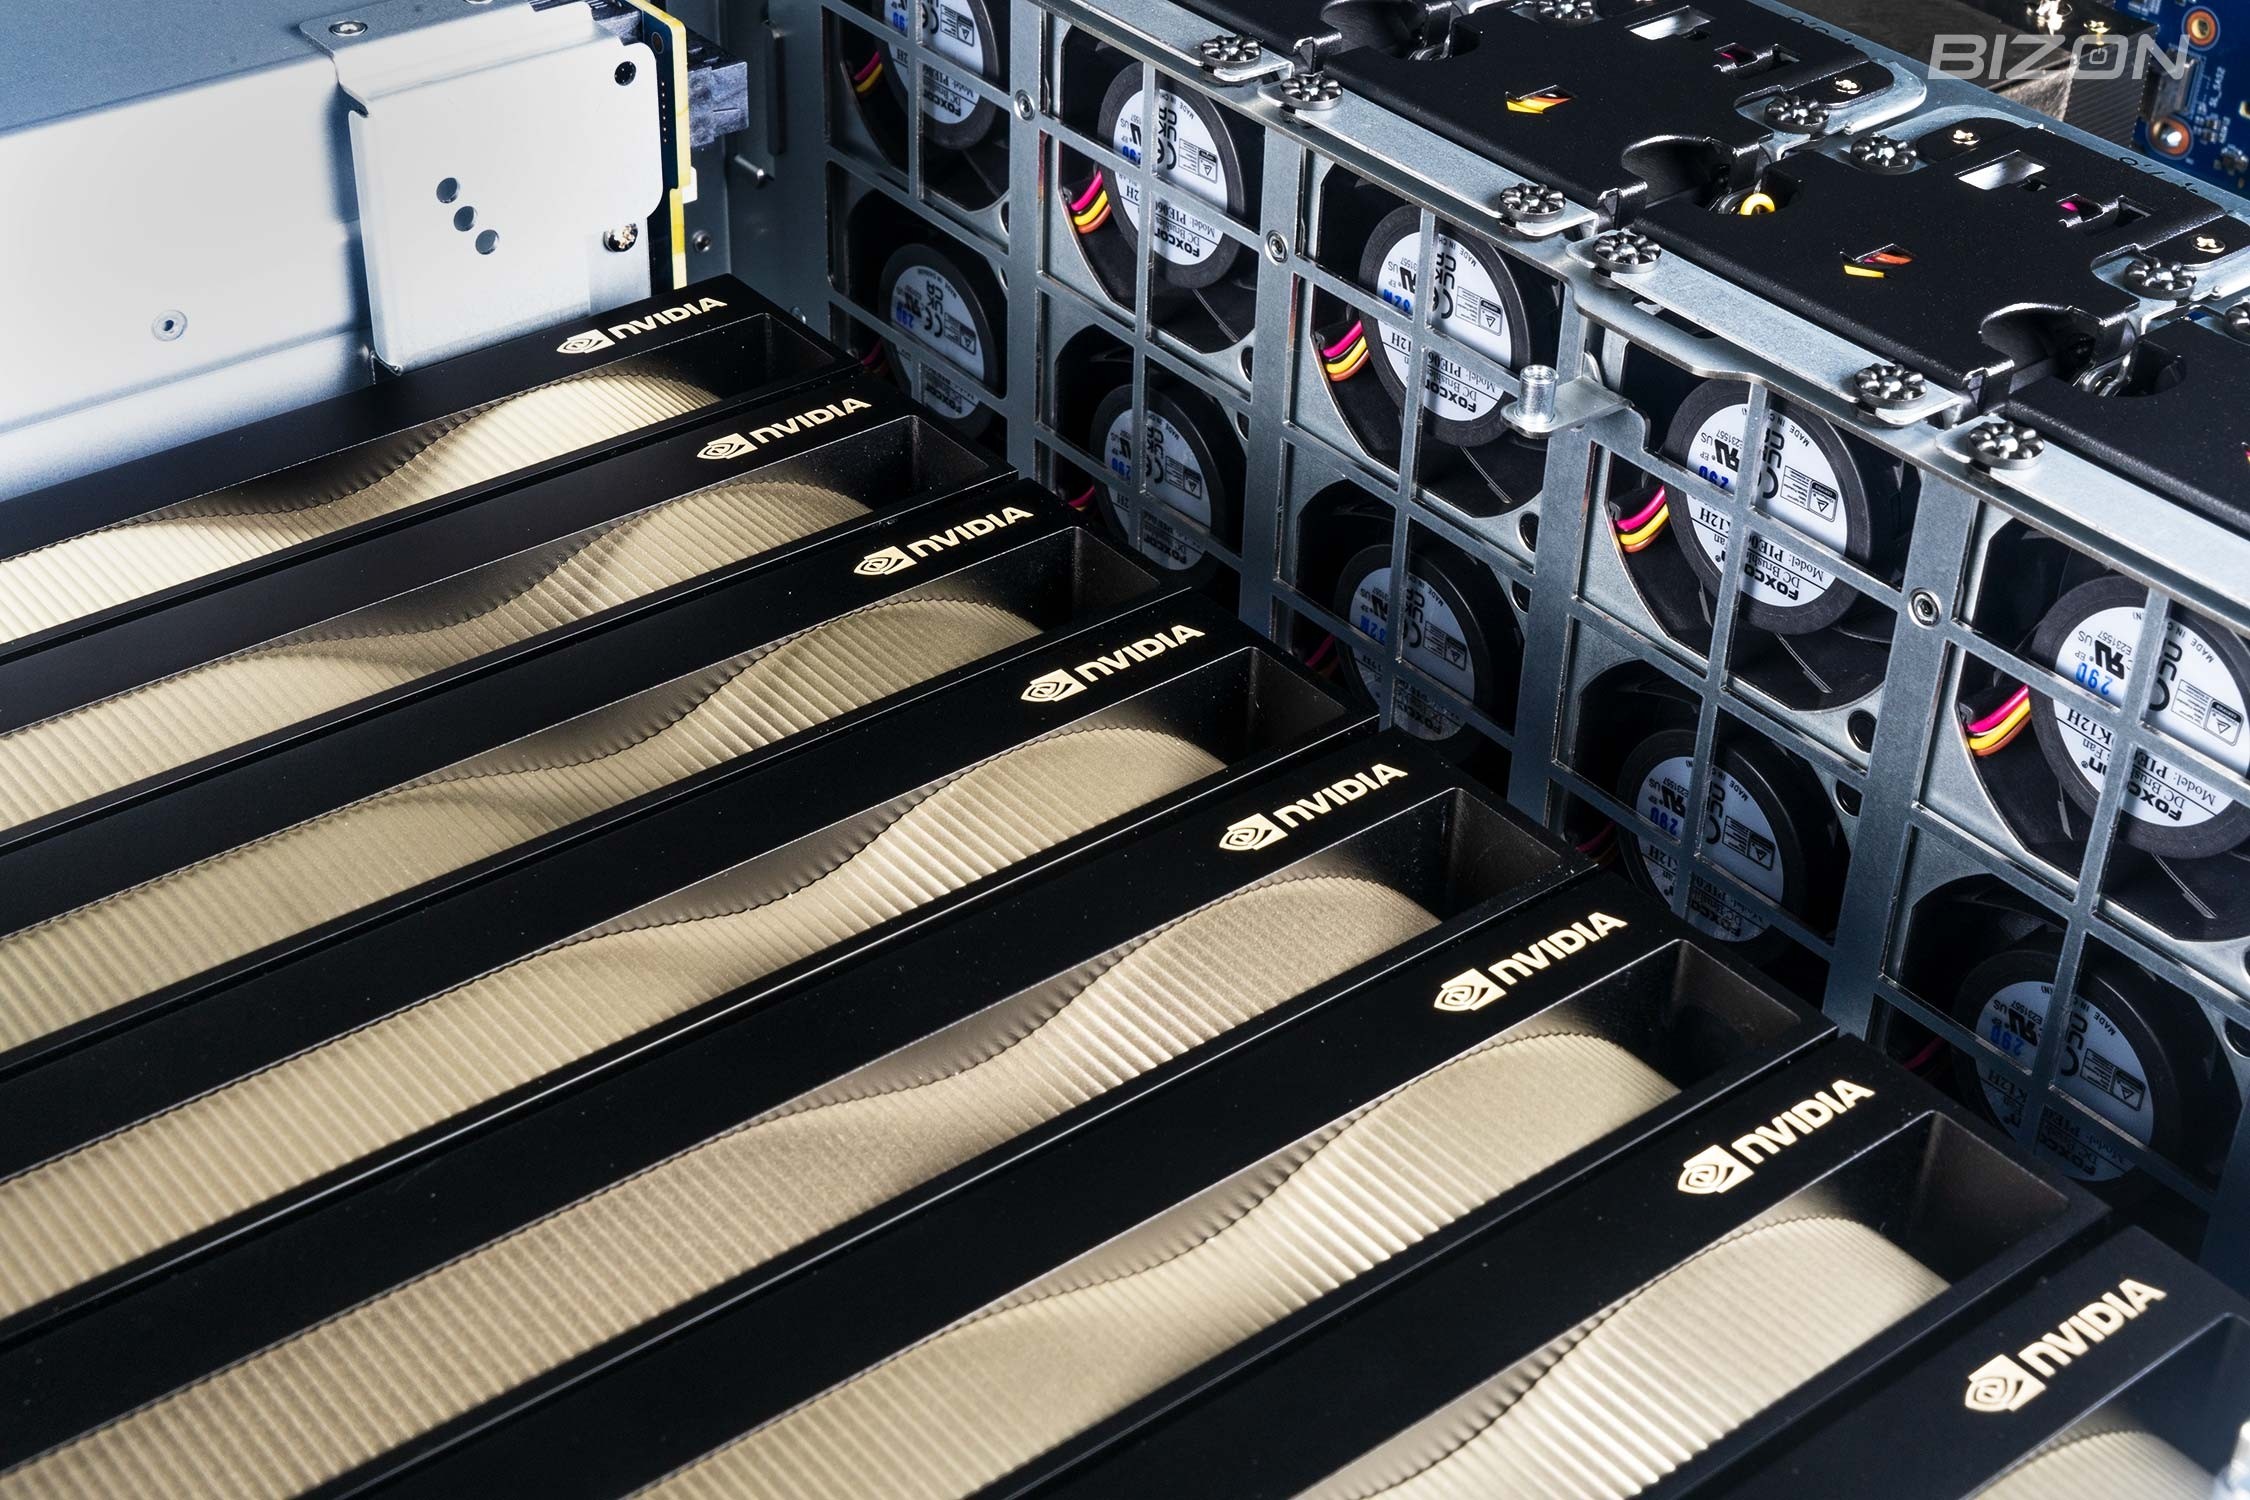
Best GPU for LLM Inference and Training – March 2024 [Updated] | BIZON
Announcing GPU and LLM Model Serving | Databricks Blog
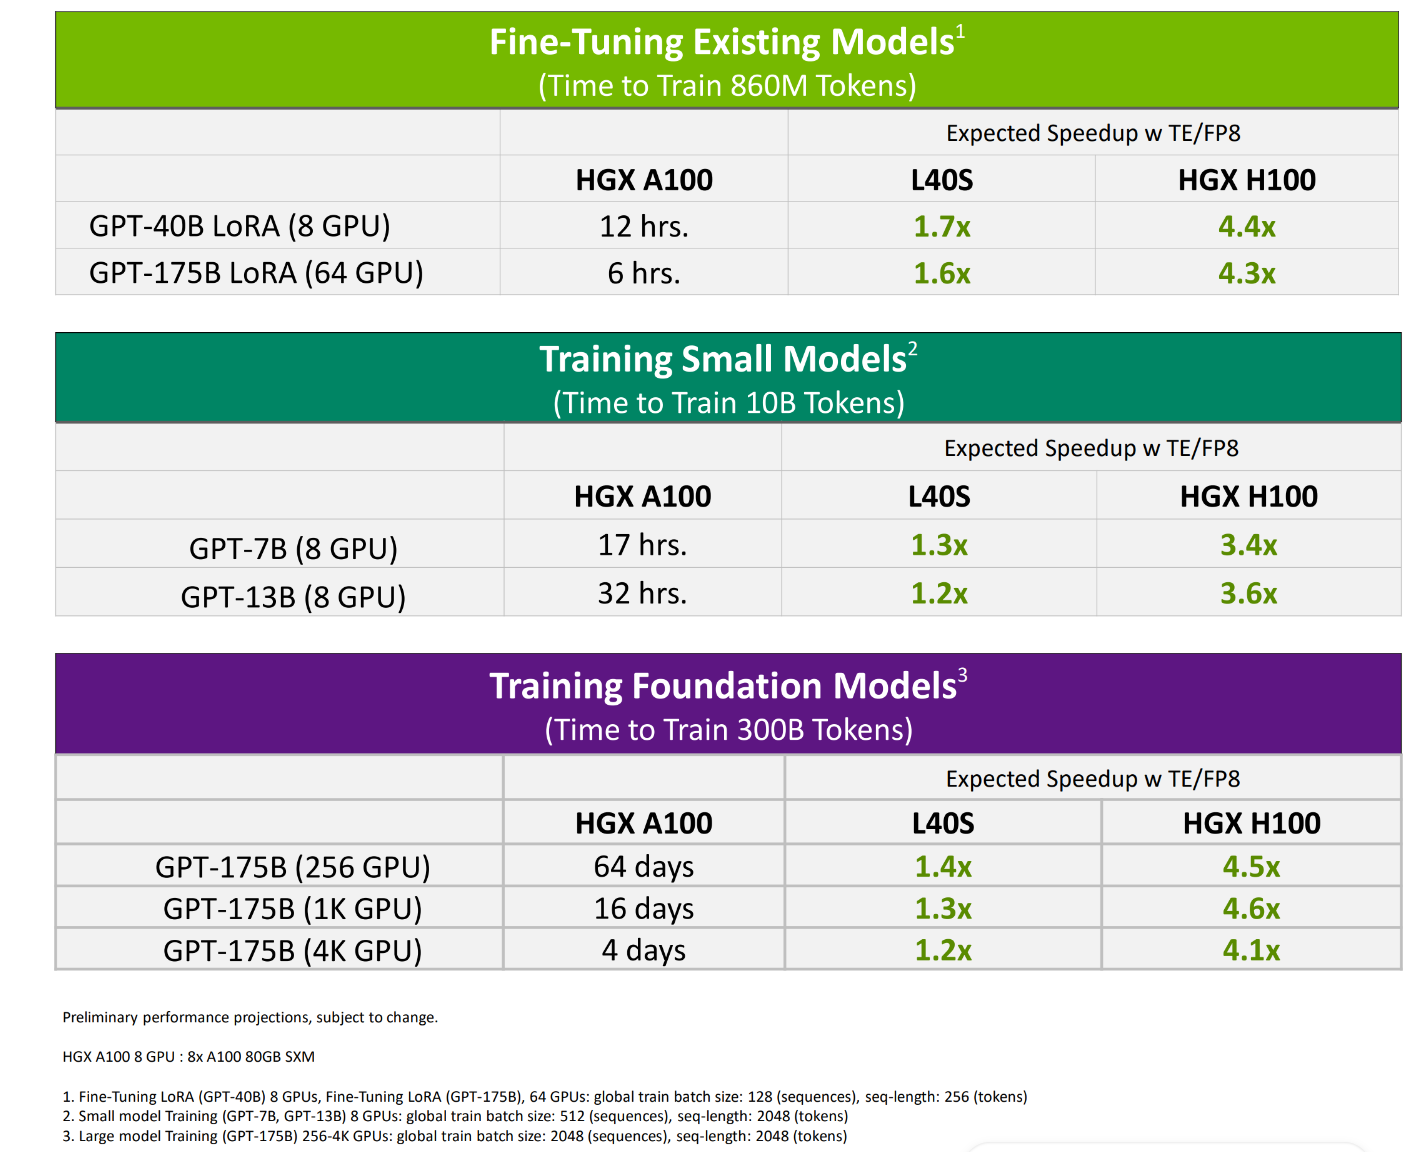
Choosing the Right GPU for LLM Inference and Training

The GPU Deployment Dilemma: Compatibility, Sharding, and AI Compute ...

Best GPU for LLM in 2026: 7 Local & Cloud Picks
GPU Deployment | langflow-ai/openrag | DeepWiki
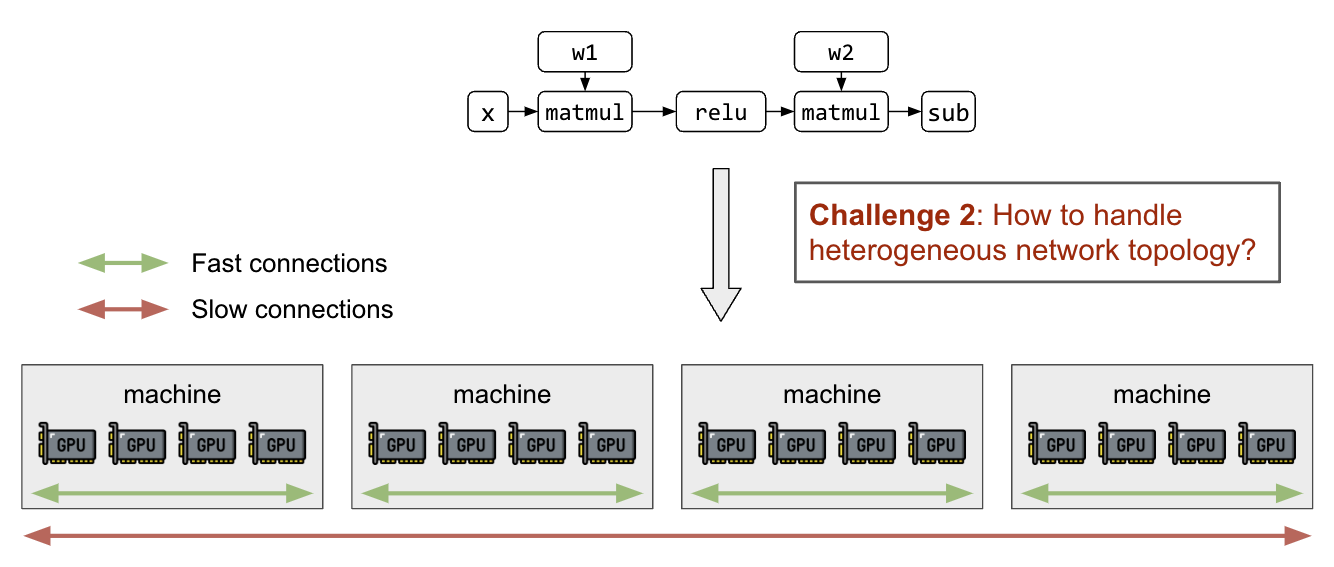
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray
LLM 모델 파인튜닝을 위한 GPU 최적화 | 패스트캠퍼스
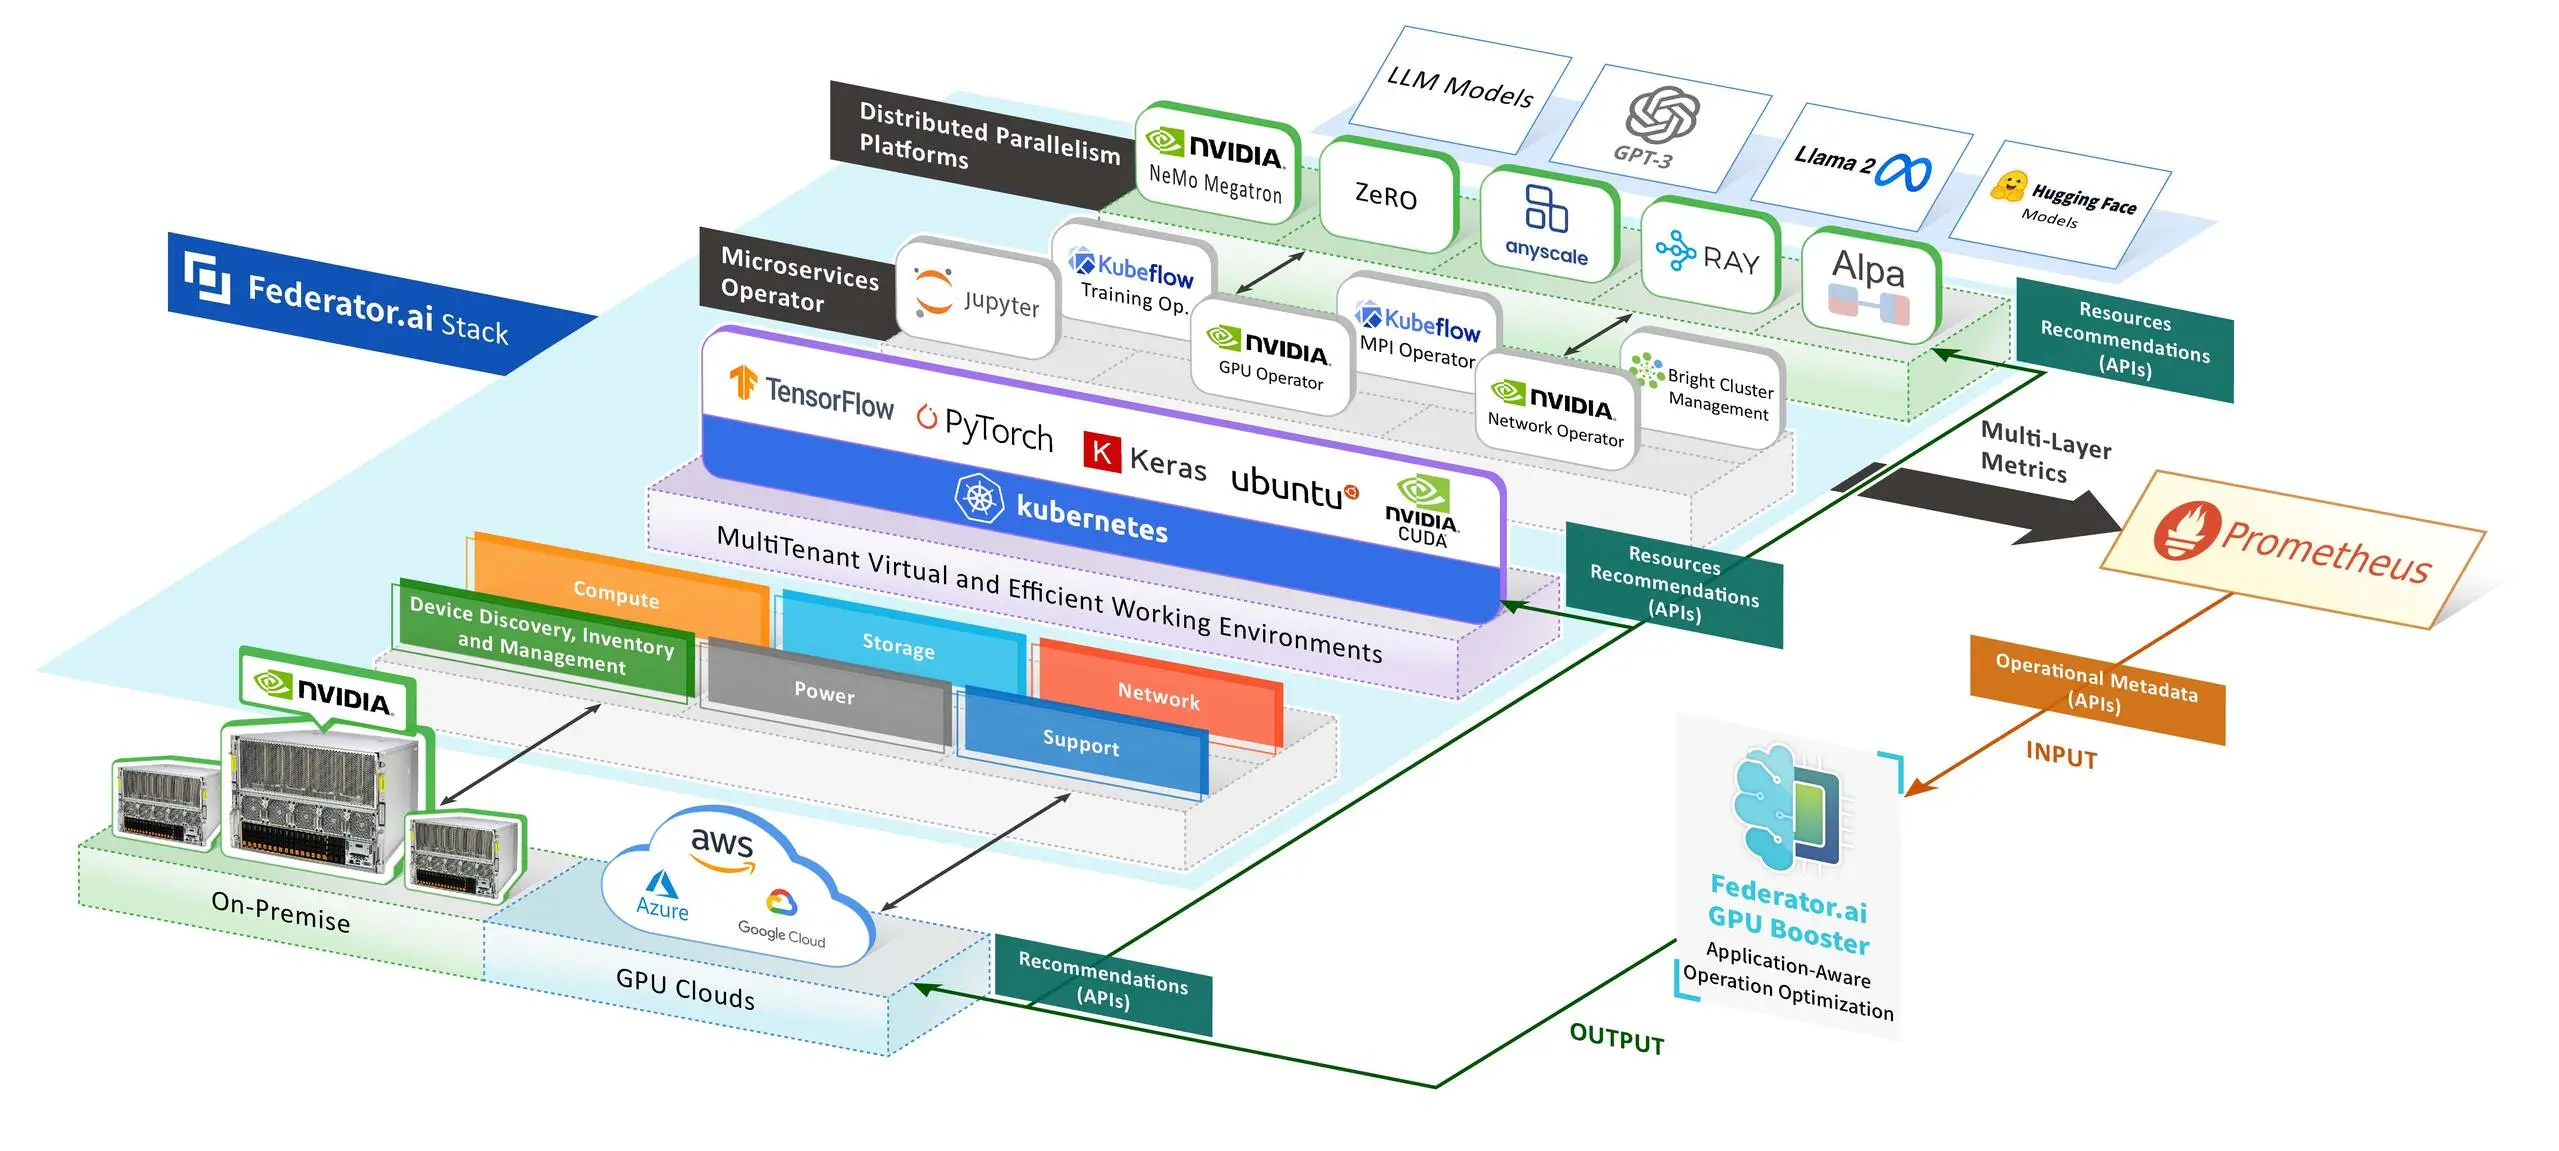
Optimized Dynamic GPU Allocation in LLM Training | ProphetStor
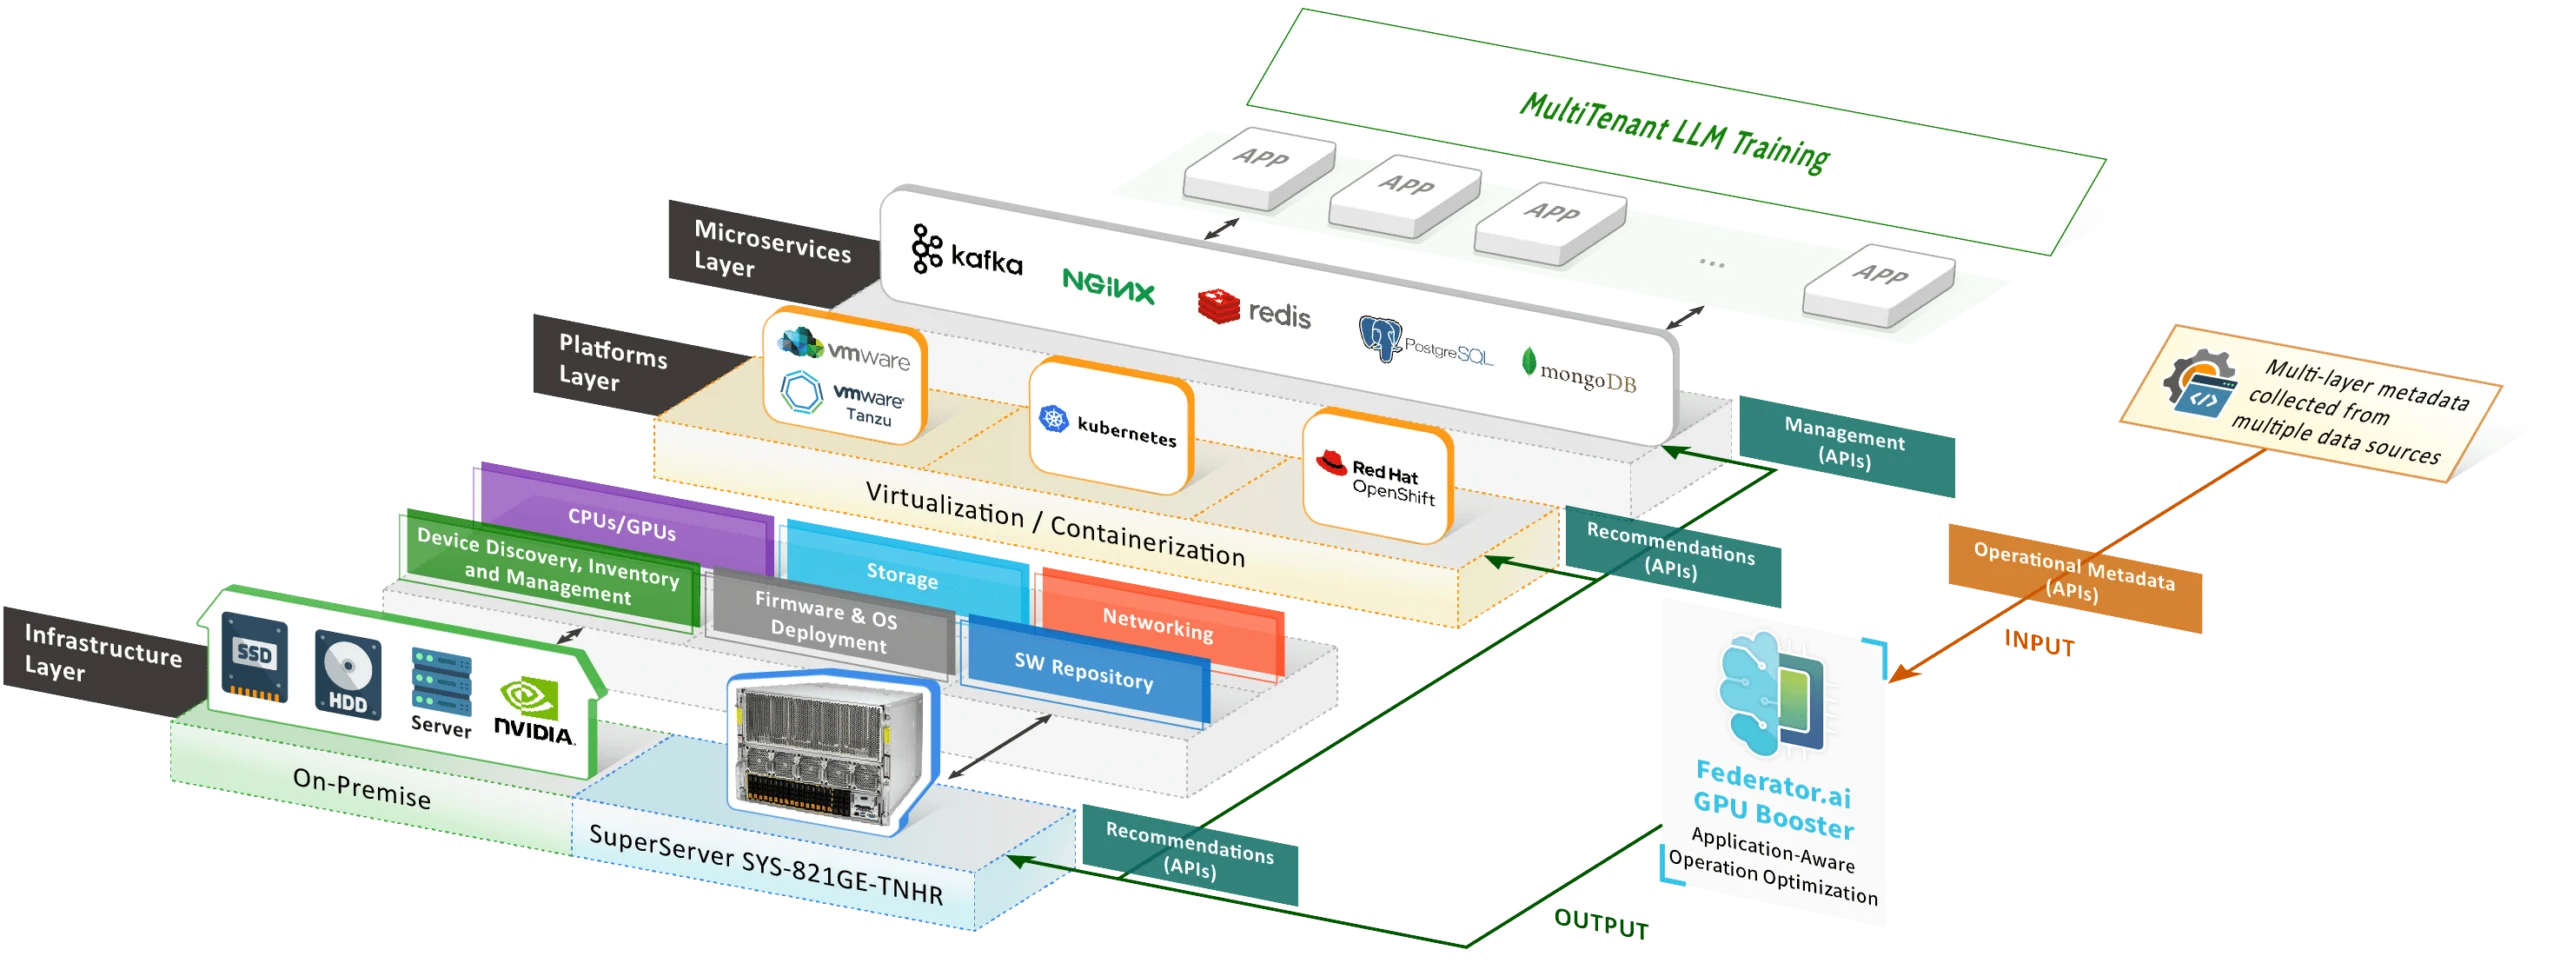
Maximizing GPU Efficiency in MultiTenant LLM Training | ProphetStor
Advertisement Space (336x280)

使用 Alpa 和 Ray 在大型 GPU 集群中高效扩展 LLM 训练 - NVIDIA 技术博客
LLM Observability on GPU Cloud: Deploy Langfuse, Arize Phoenix, and ...

Configuración de entrenamiento, ajuste e inferencia de LLM con GPU ...

Best GPU for LLM in 2026: 7 Local & Cloud Picks
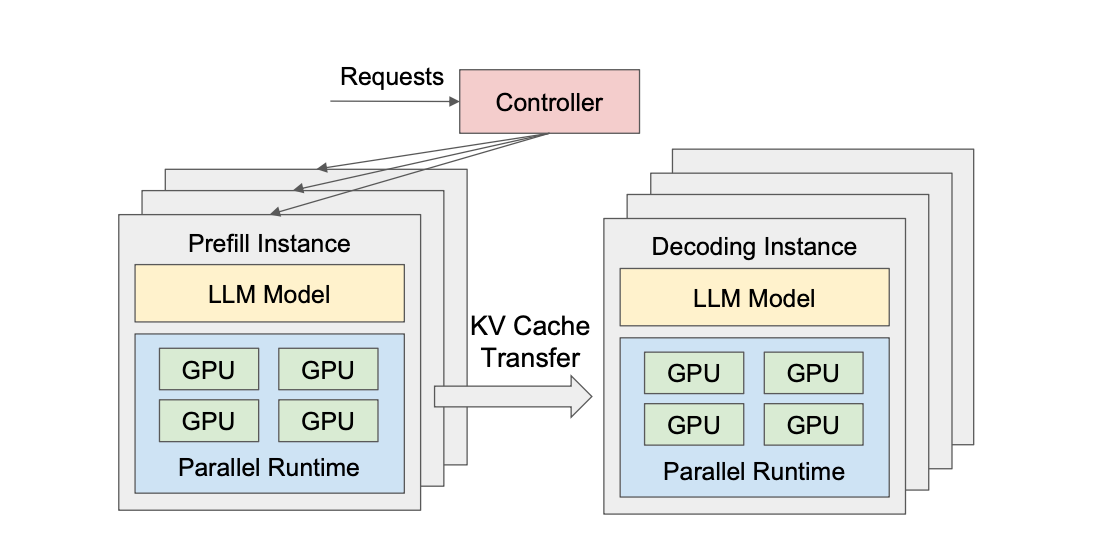
Simple Guide on FLOPs in GPU Utilisation - Floating Bytes
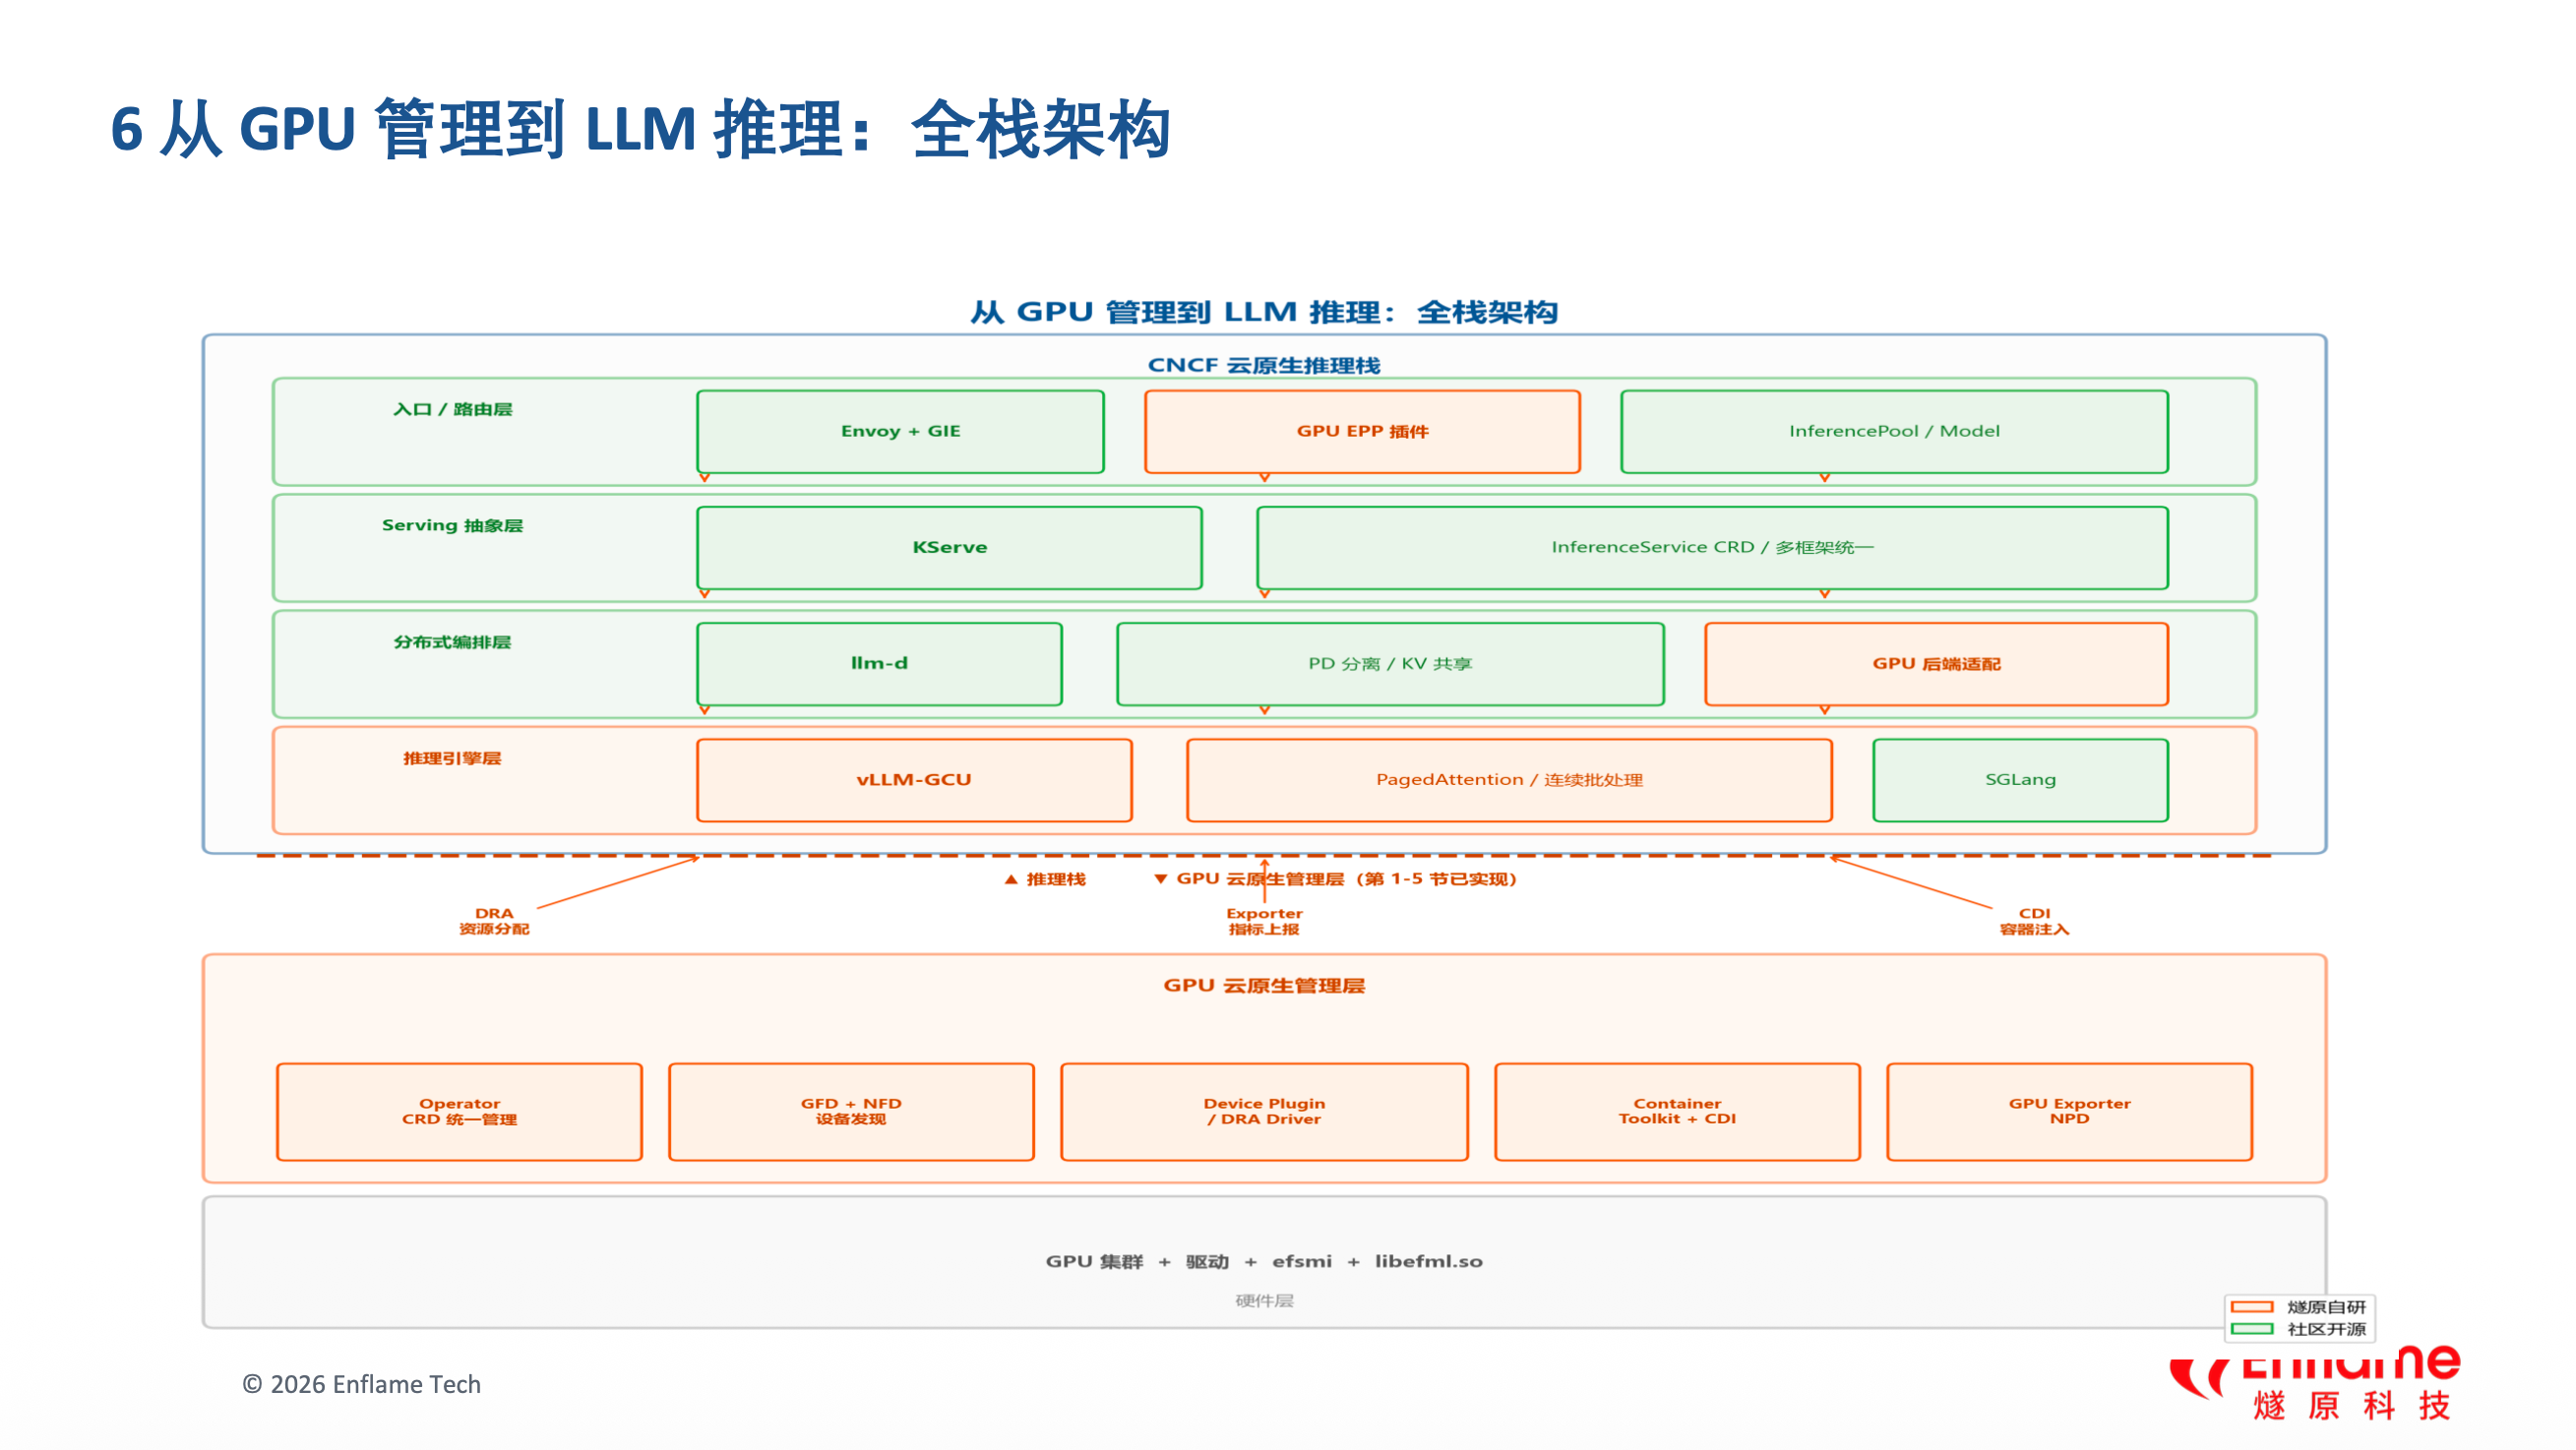
国产 GPU 如何丝滑融入 K8s?燧原科技的全栈云原生实践 | 密瓜智能博客 | 密瓜智能