
Github Kvcache Aicustomflashinfer Flashinfer Kernel Library For
GitHub - kvcache-ai/custom_flashinfer: FlashInfer: Kernel Library for ...

GitHub - flashinfer-ai/flashinfer: FlashInfer: Kernel Library for LLM ...
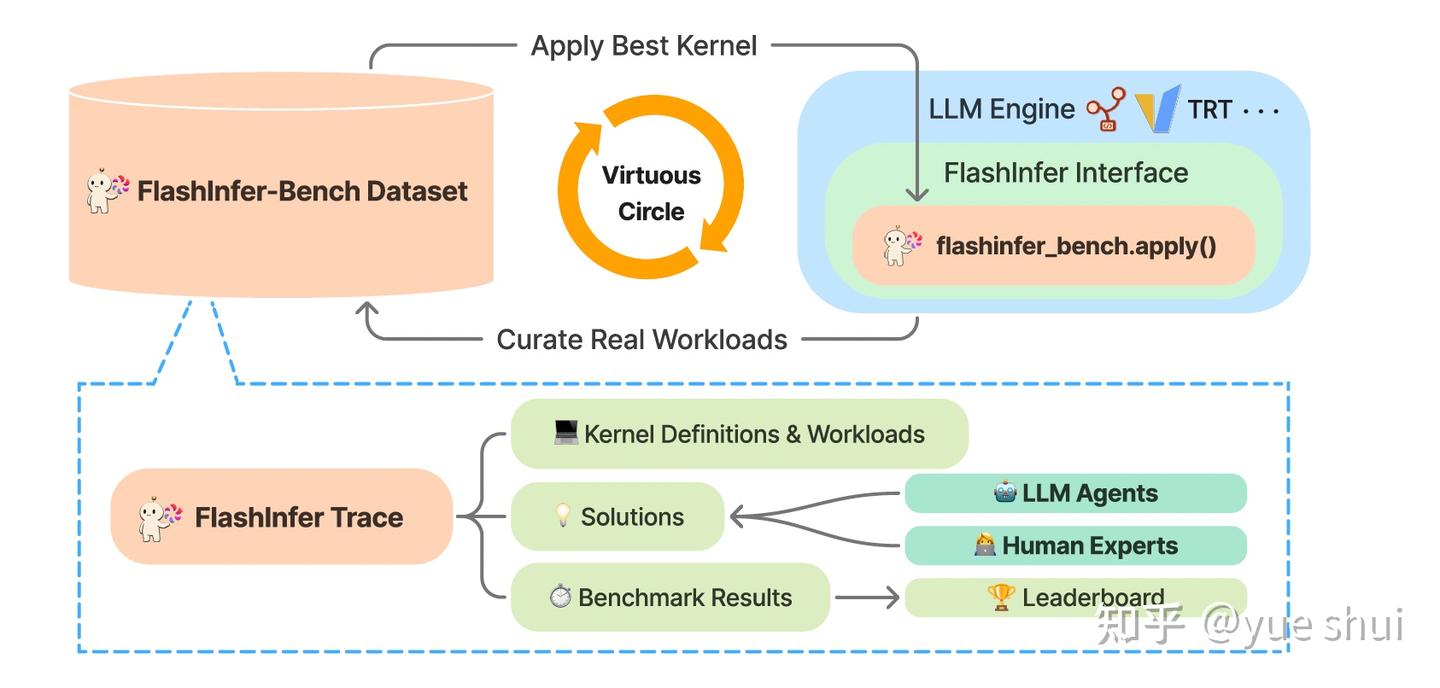
基于代码智能体的 GPU Kernel 生成与优化:MLSys 2026 FlashInfer 比赛总结 - 知乎
FlashInfer 0.2 - Efficient and Customizable Kernels for LLM Inference ...
sgl-kernel: Custom CUDA Kernel Library | kvcache-ai/sglang | DeepWiki
FlashInfer: A Kernel Library Revolutionizing Large Language Model ...
kvcache · GitHub Topics · GitHub
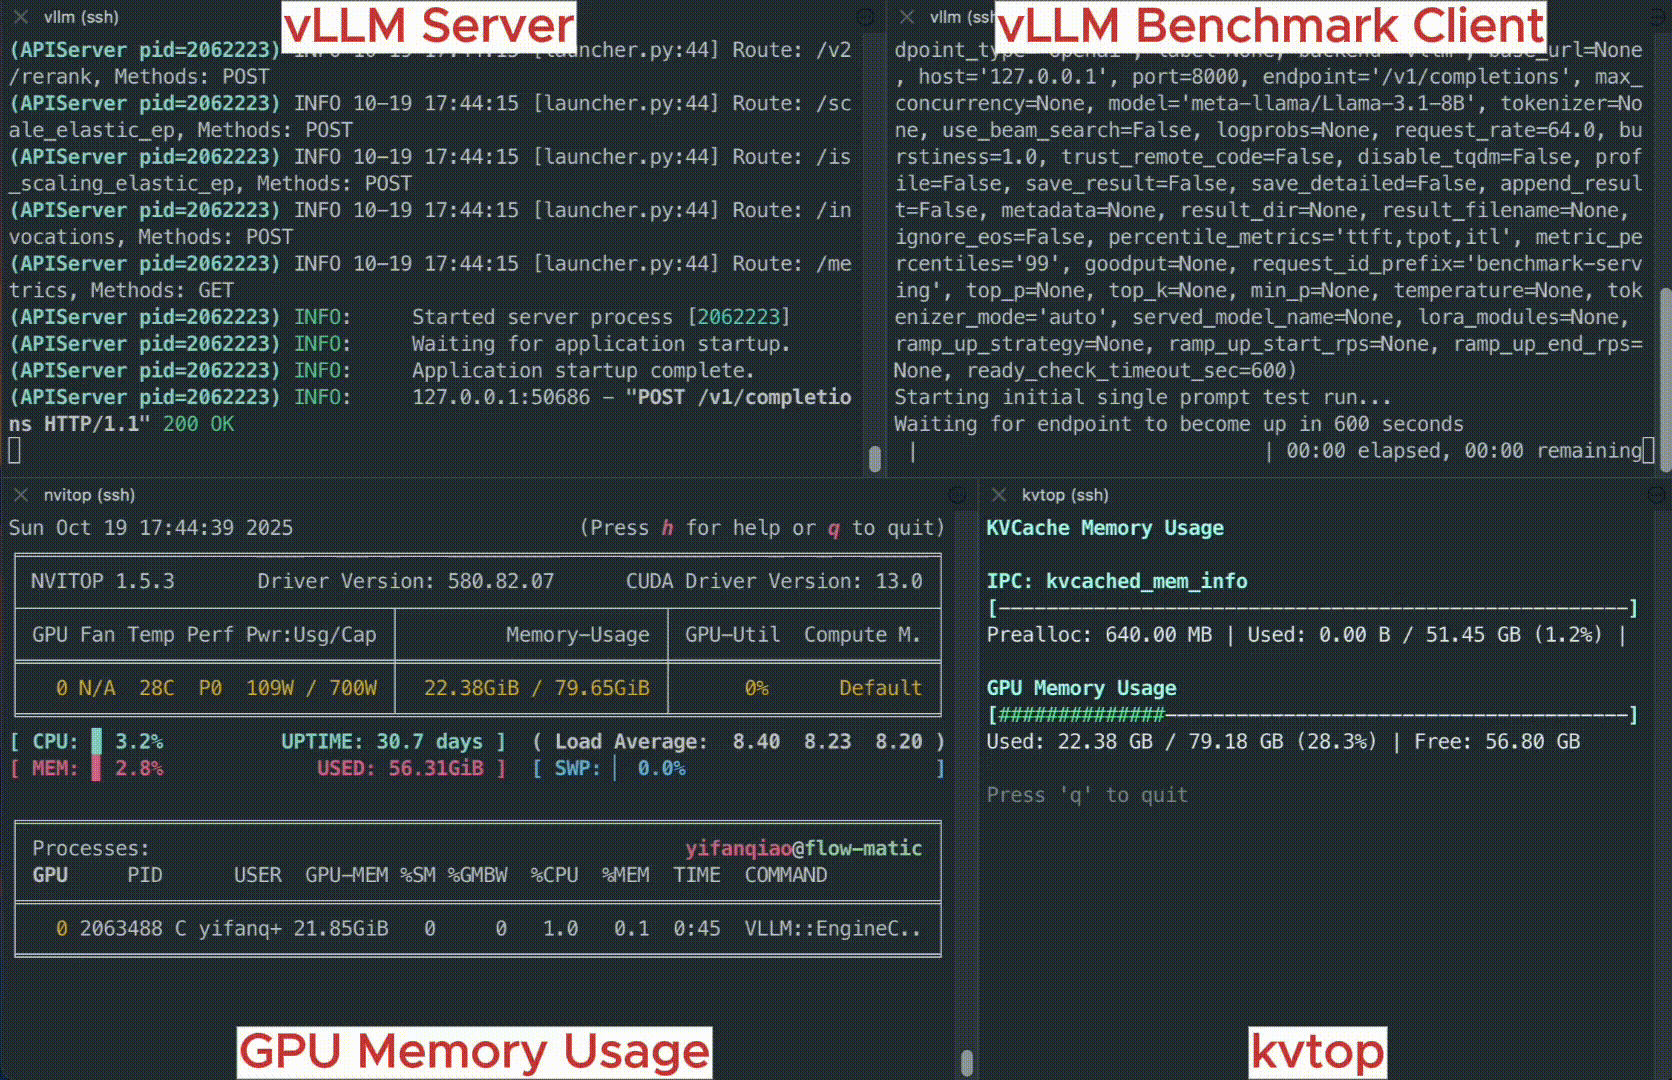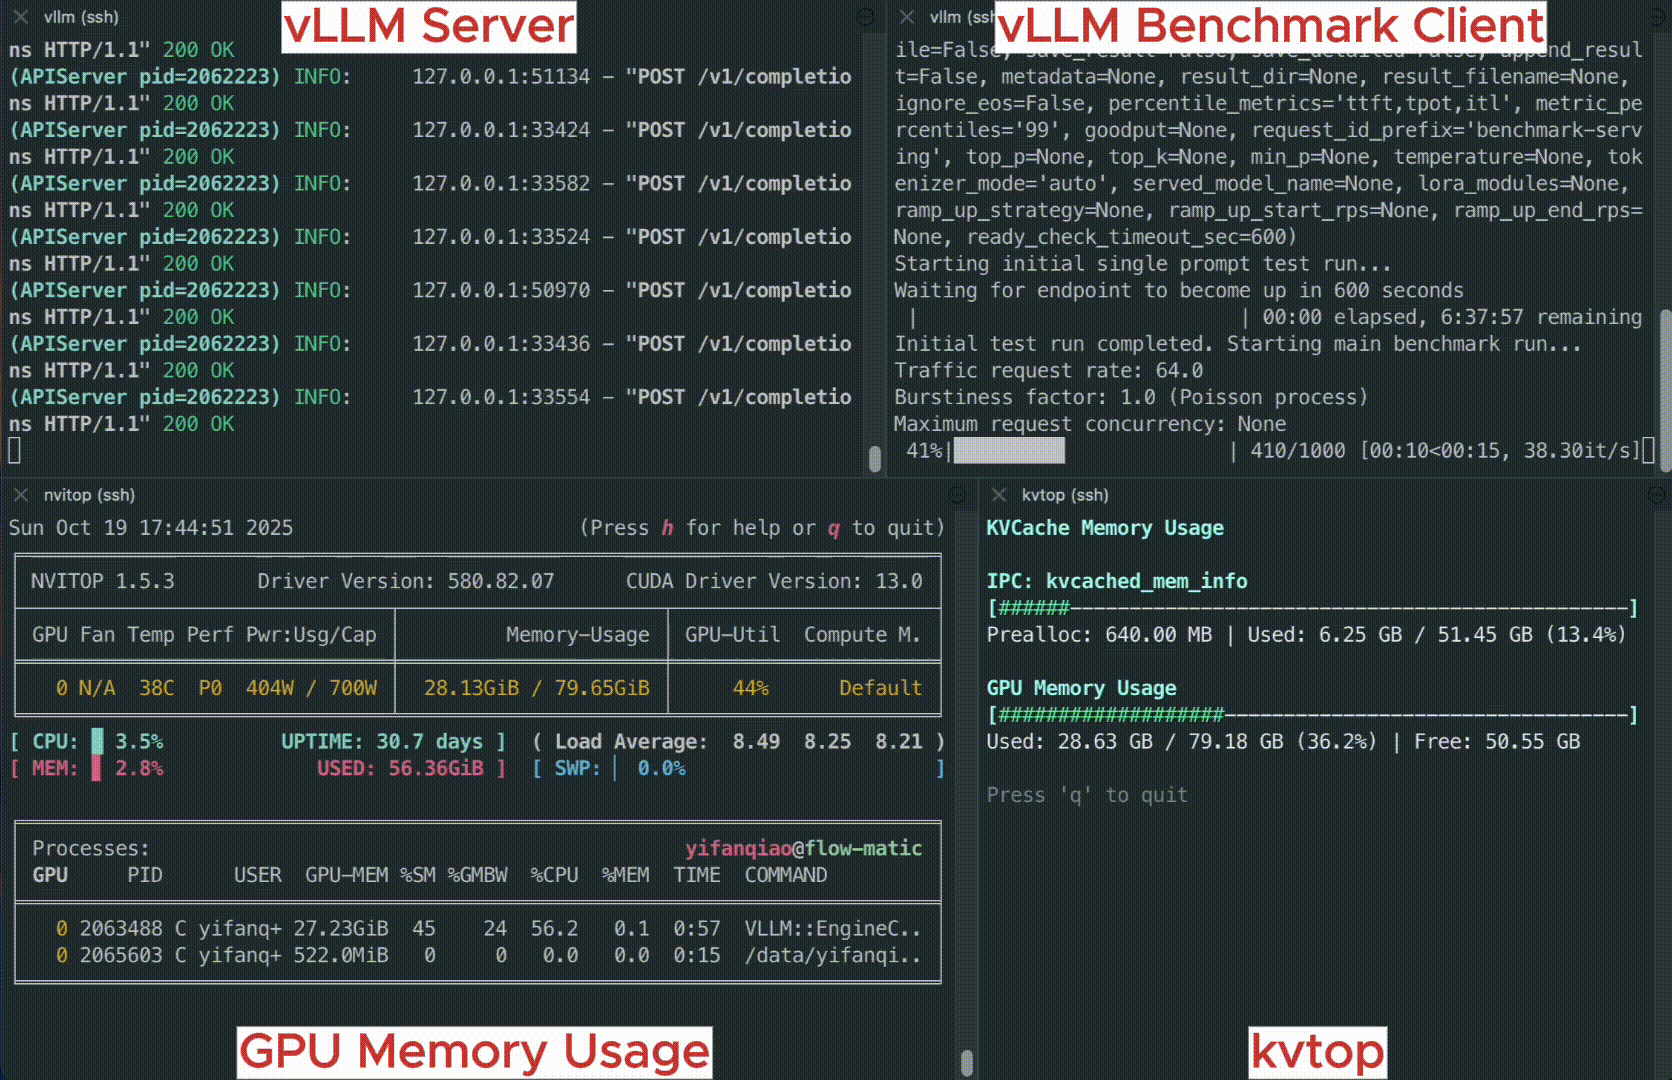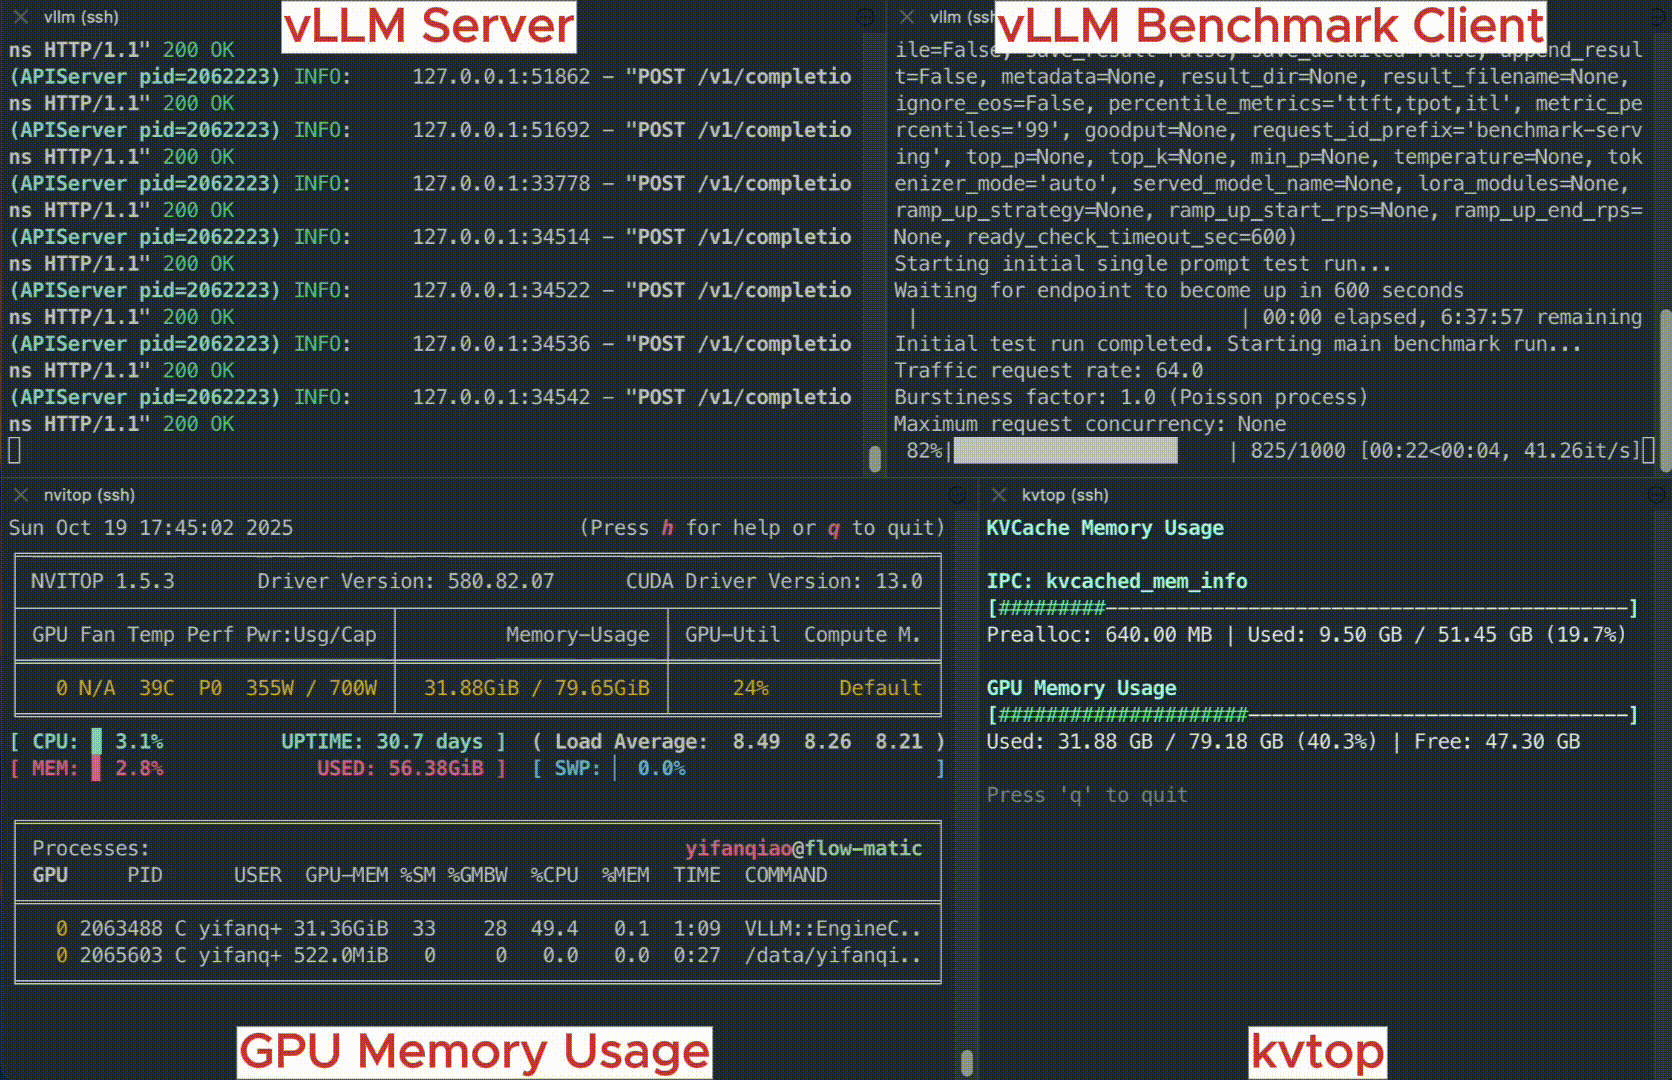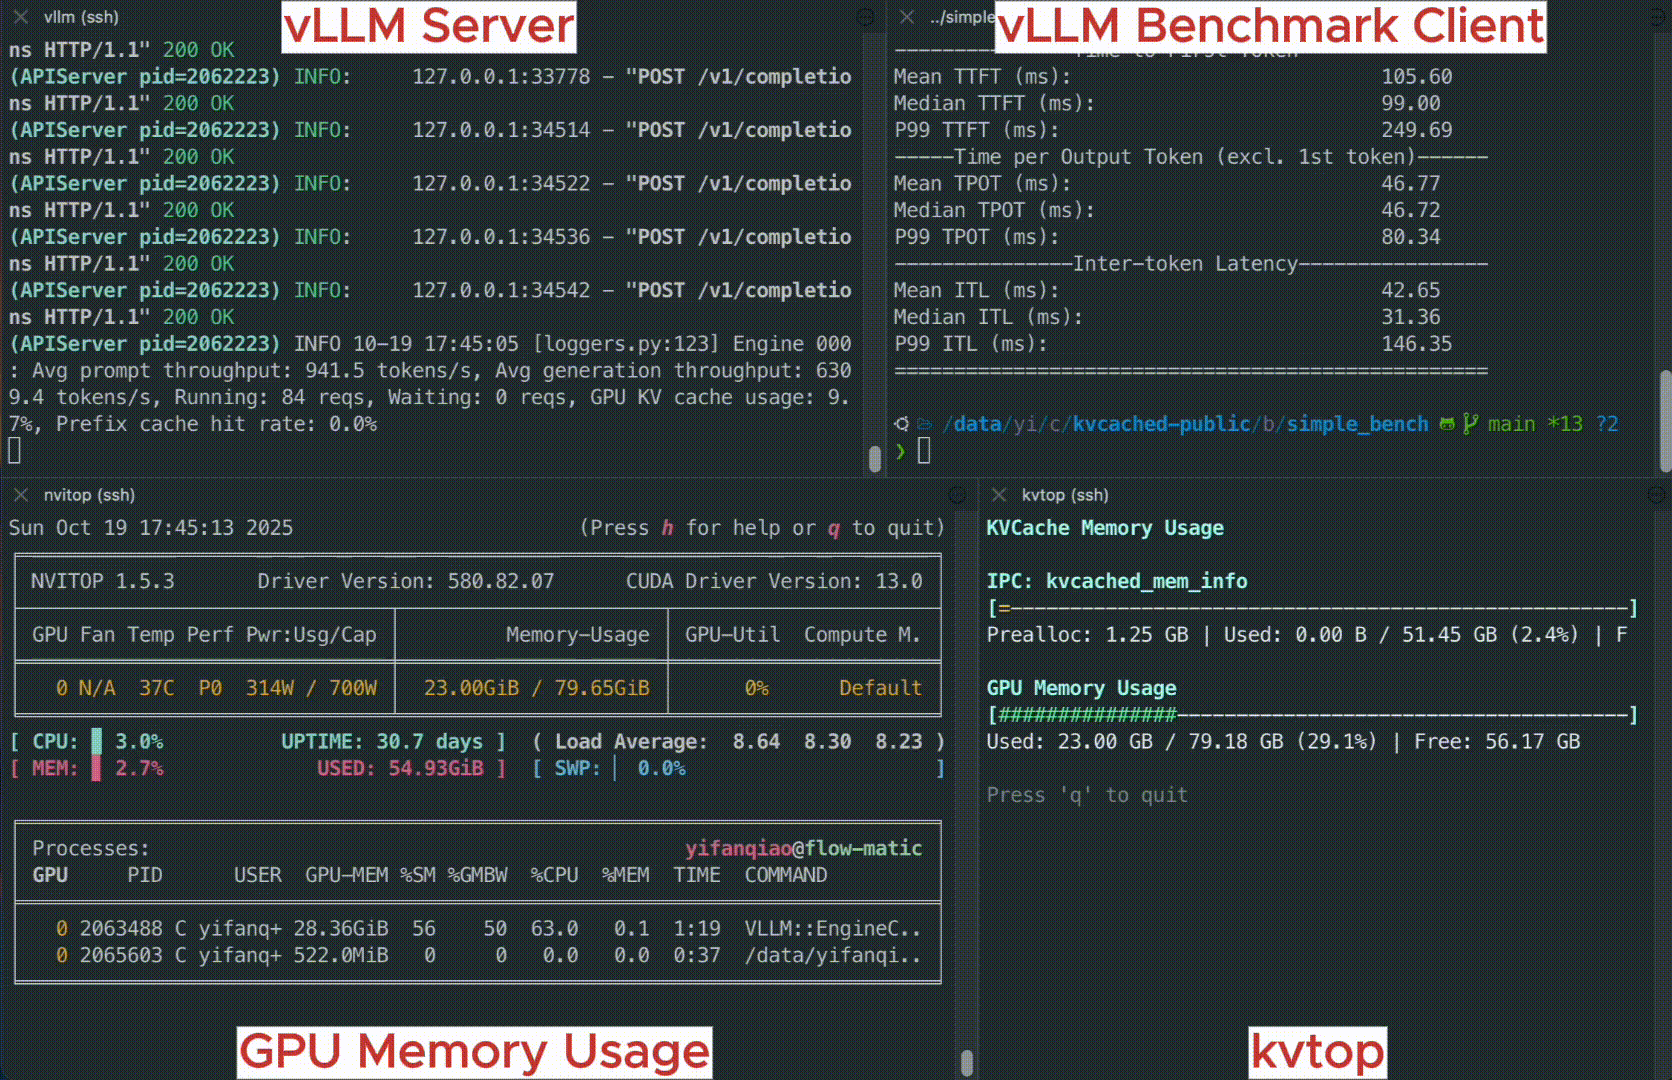
GitHub - ovg-project/kvcached: Virtualized Elastic KV Cache for Dynamic ...

FlashInfer · GitHub
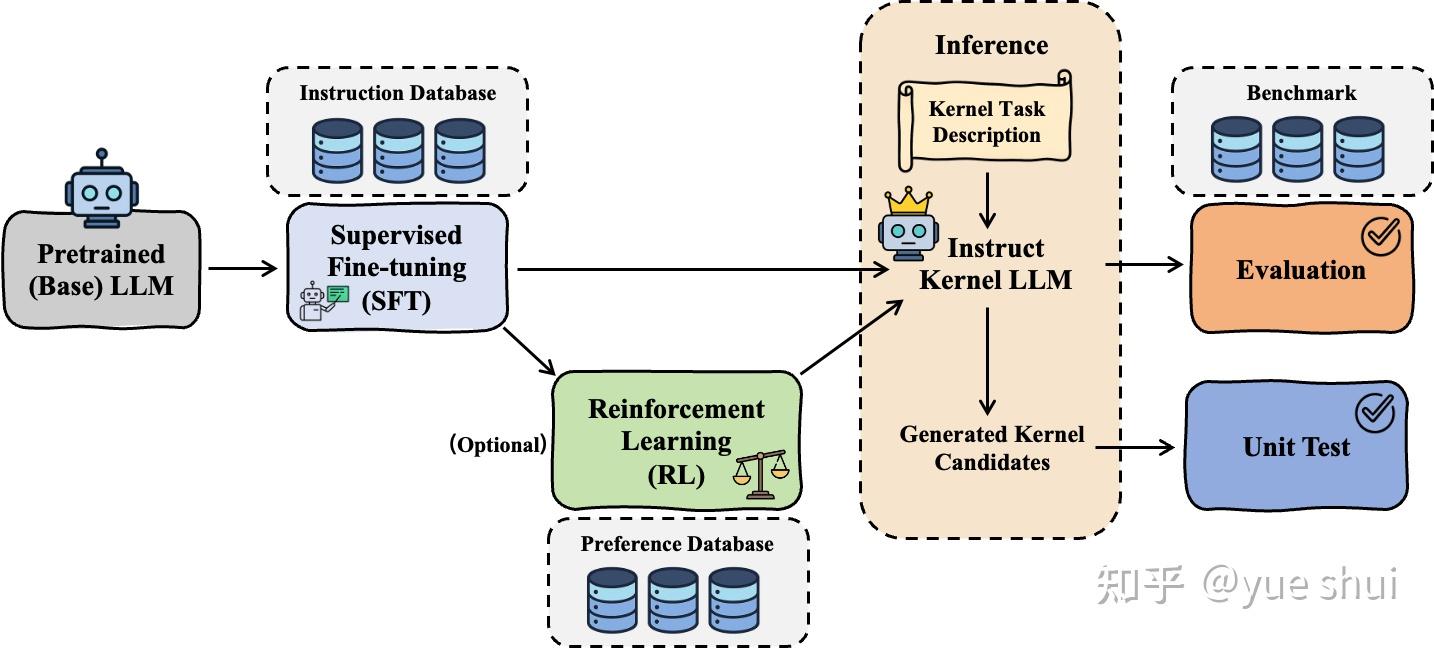
基于代码智能体的 GPU Kernel 生成与优化:MLSys 2026 FlashInfer 比赛总结 - 知乎
Advertisement Space (300x250)

GitHub - alibaba/tair-kvcache: Alibaba Cloud's high-performance KVCache ...
GitHub - Passw/kvcache-ai-ktransformers: A Flexible Framework for ...
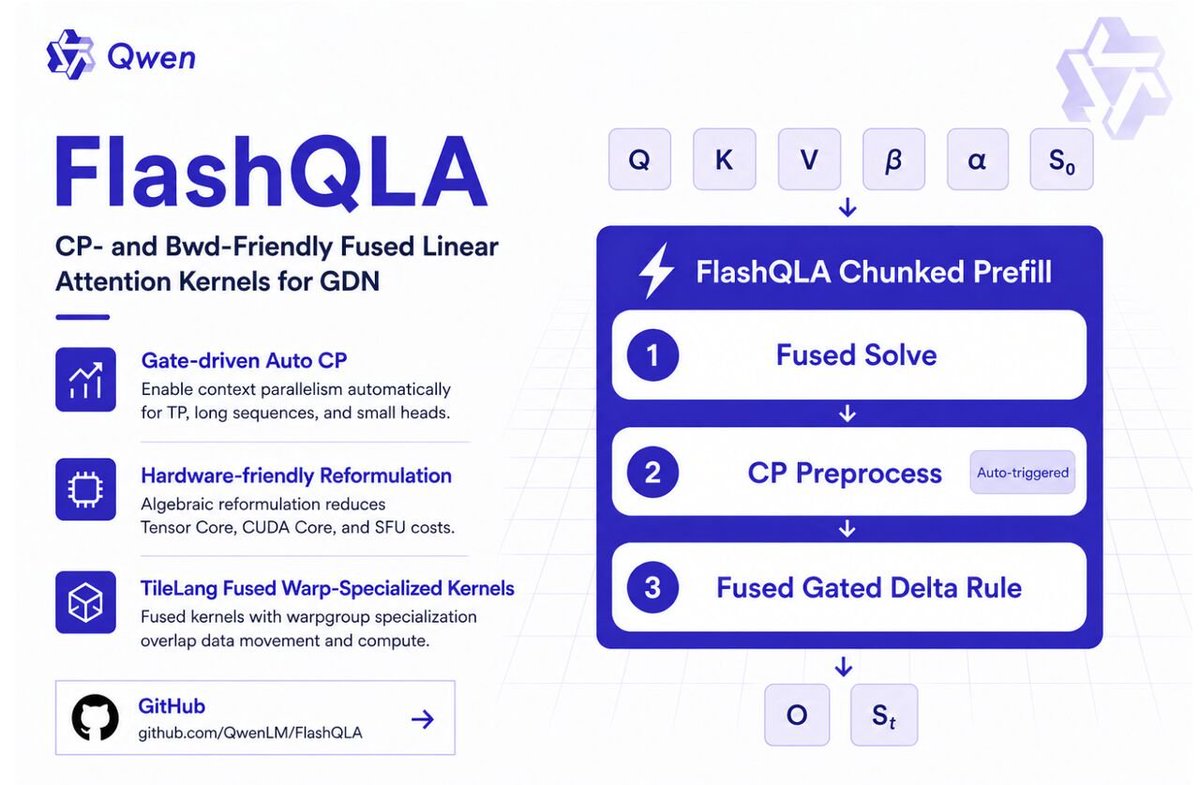
Qwen Team released FlashQLA: a fused linear attention kernel library ...
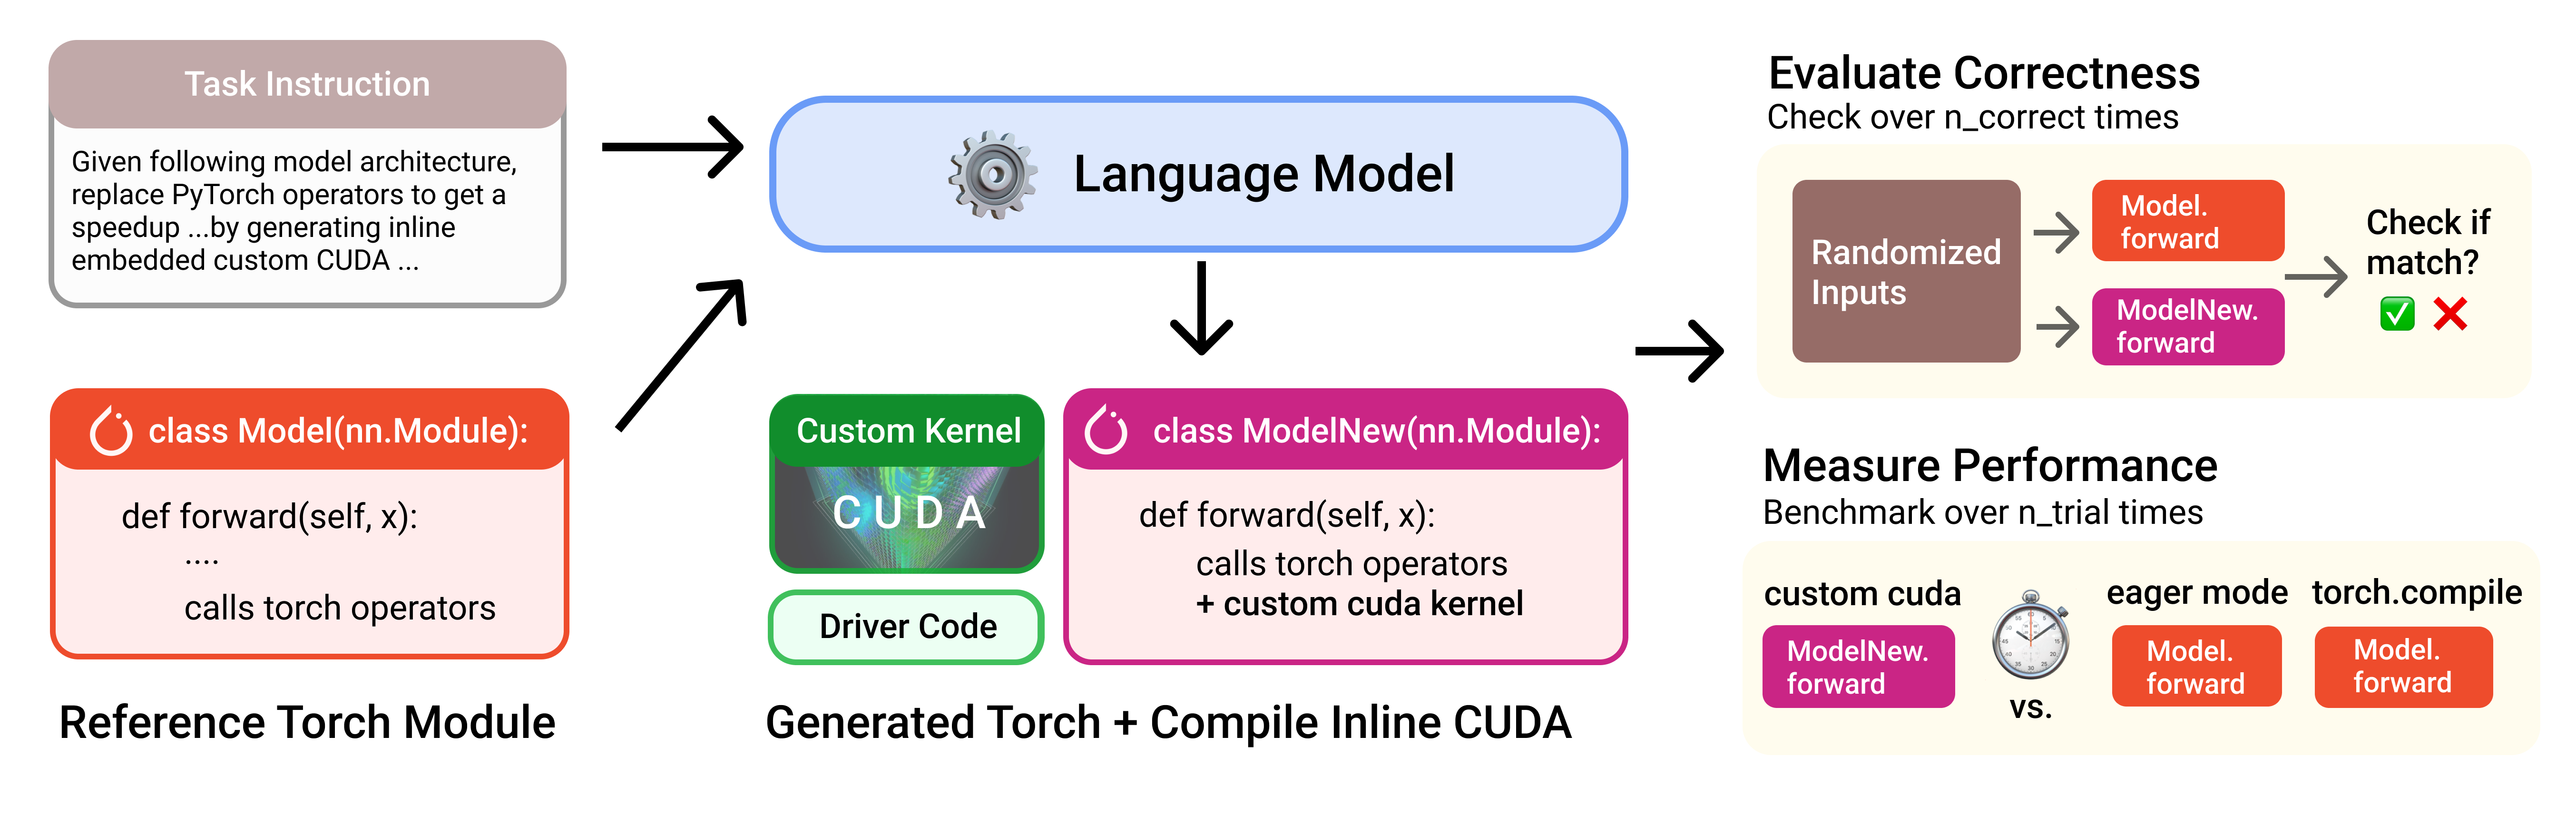
基于代码智能体的 GPU Kernel 生成与优化:MLSys 2026 FlashInfer 比赛总结 | Yue Shui 博客

GitHub - sipeed/kflash_gui: Cross platform GUI wrapper for kflash.py ...
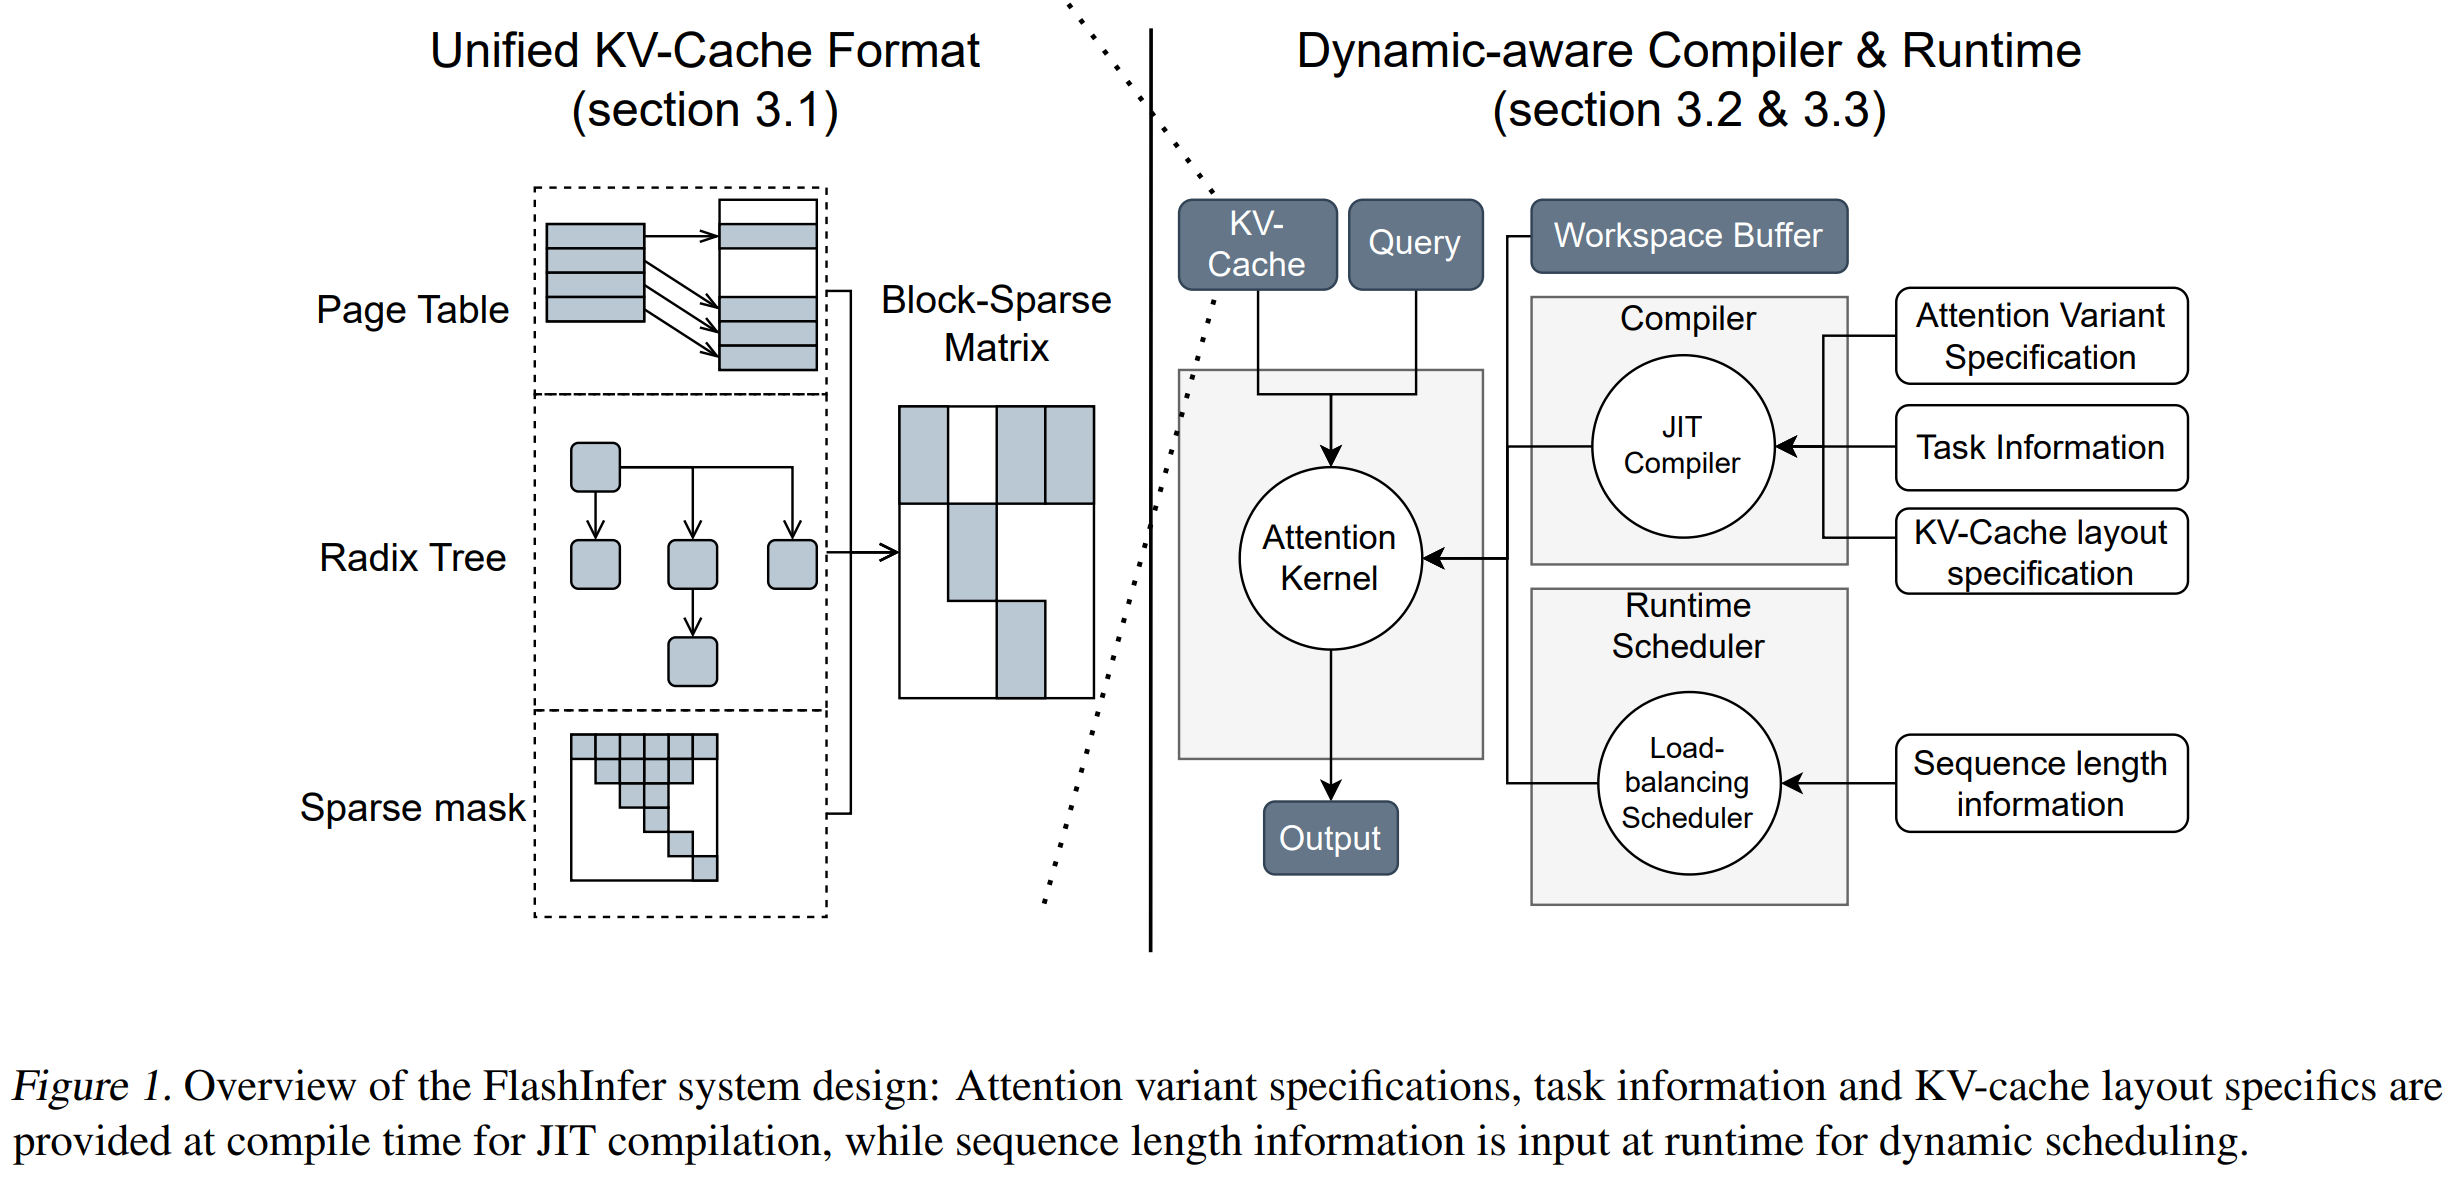
Summary: FLASHINFER: EFFICIENT AND CUSTOMIZABLE ATTENTION ENGINE FOR ...

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...
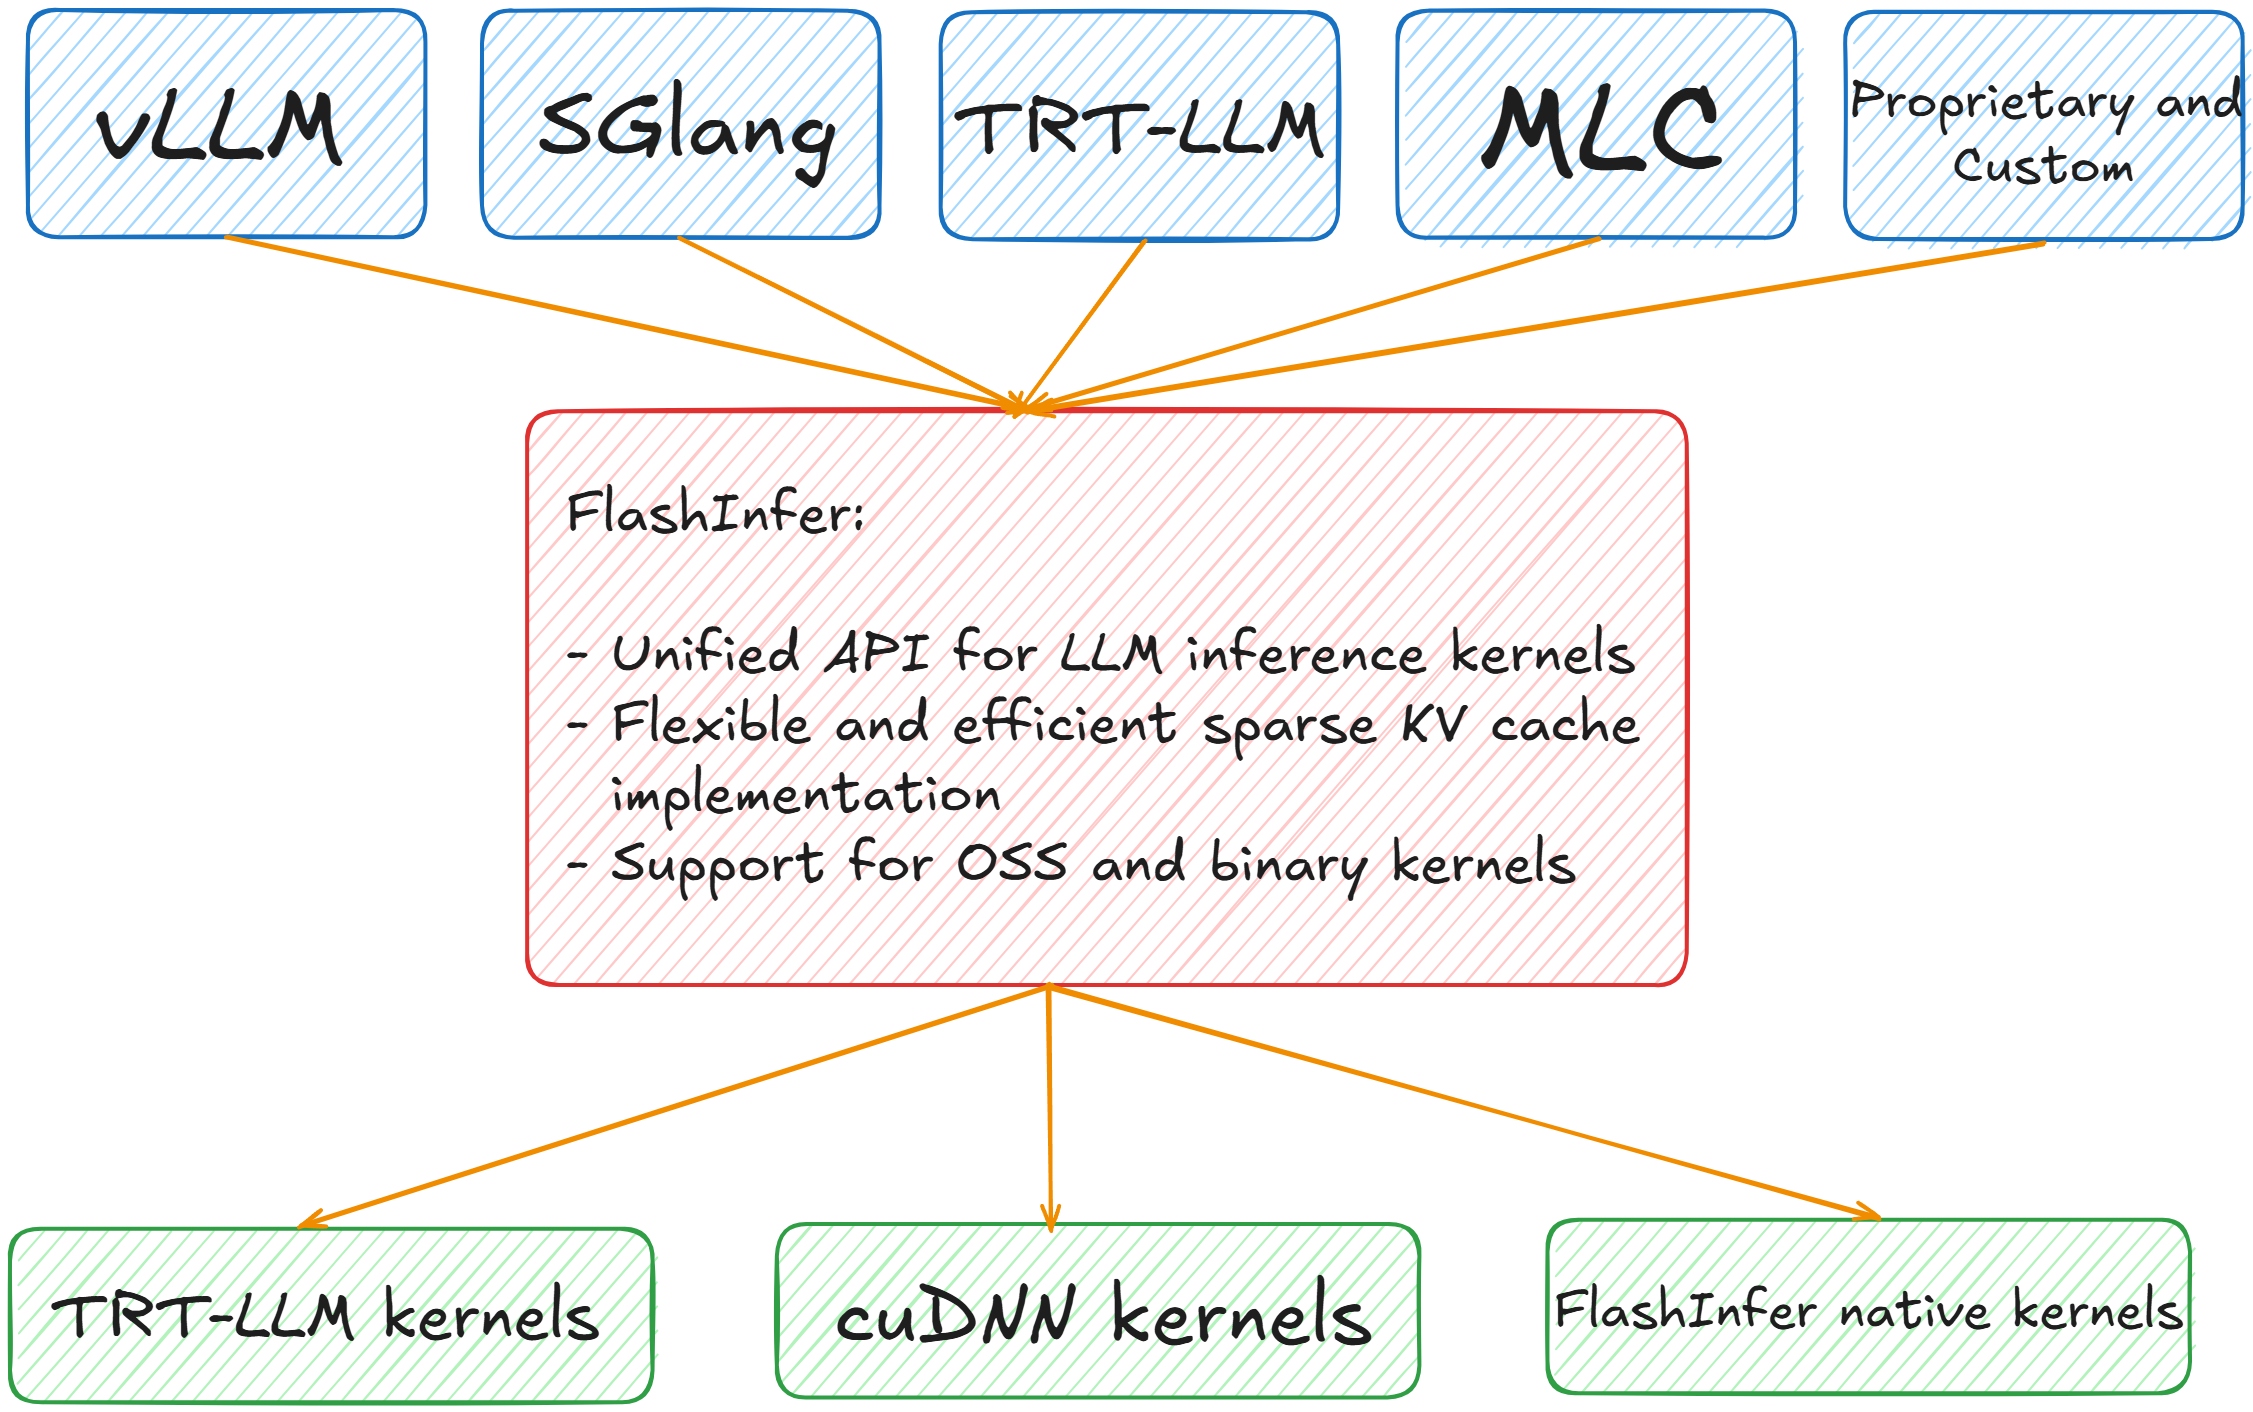
Dissecting FlashInfer - A Systems Perspective on High-Performance LLM ...
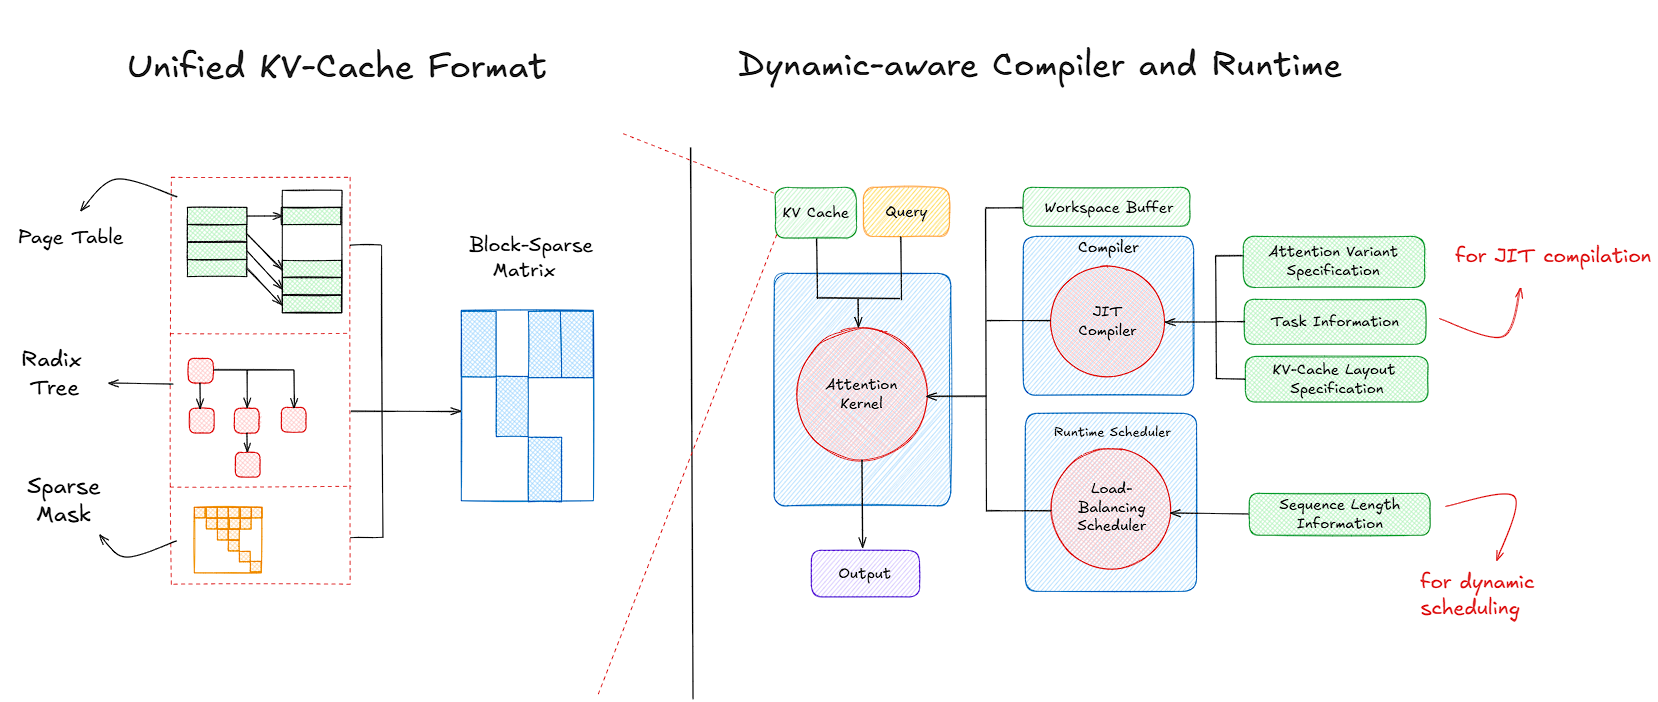
Dissecting FlashInfer - A Systems Perspective on High-Performance LLM ...
github- flashinfer :Features,Alternatives | Toolerific
Advertisement Space (336x280)

AIBrix v0.3.0 Release: KVCache Offloading, Prefix Cache, Fairness ...
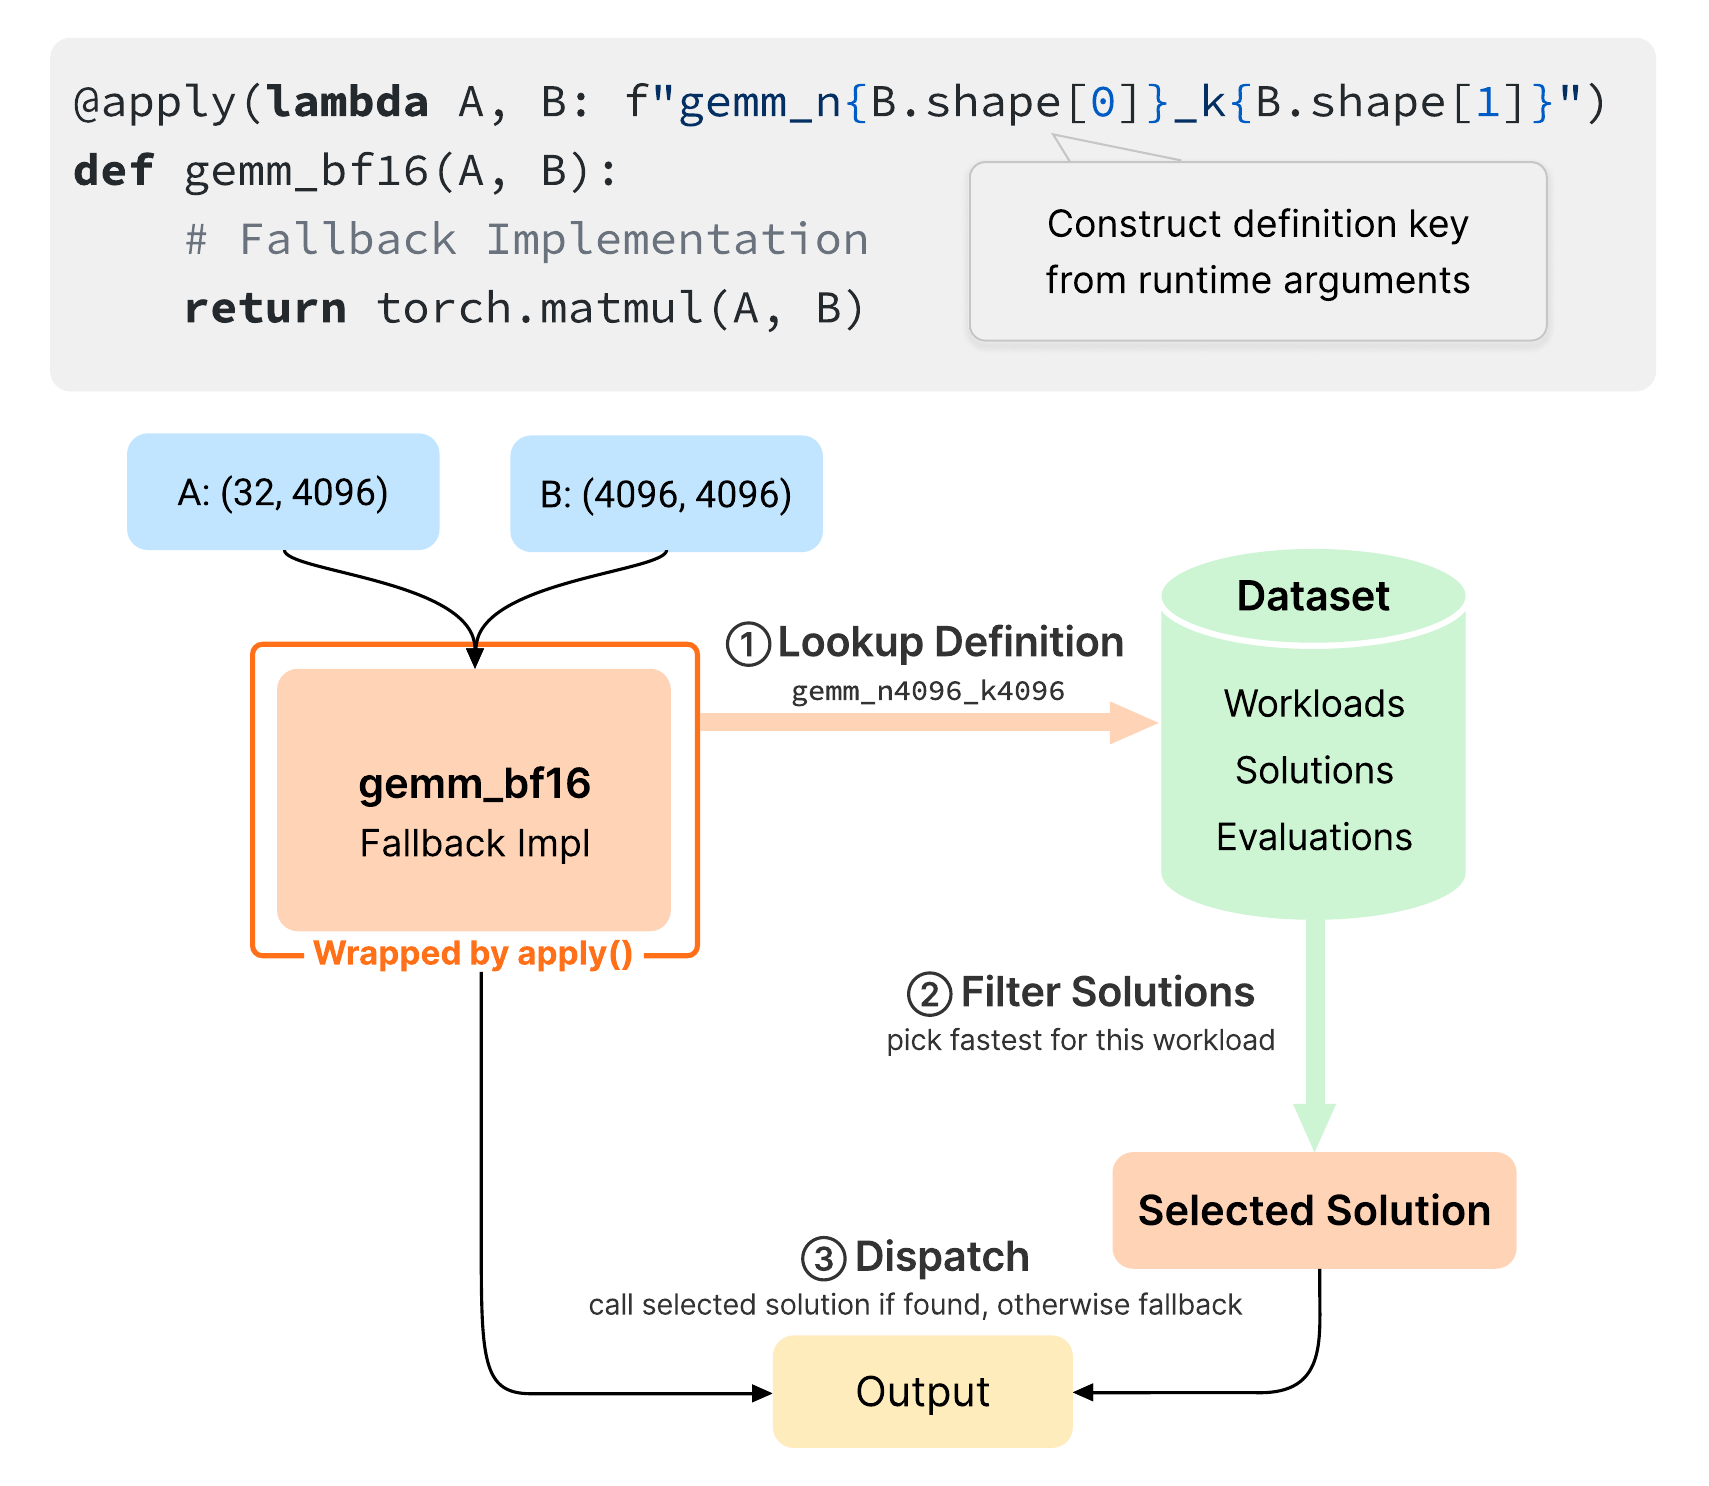
FlashInfer-Bench: Building the Virtuous Cycle for AI-driven
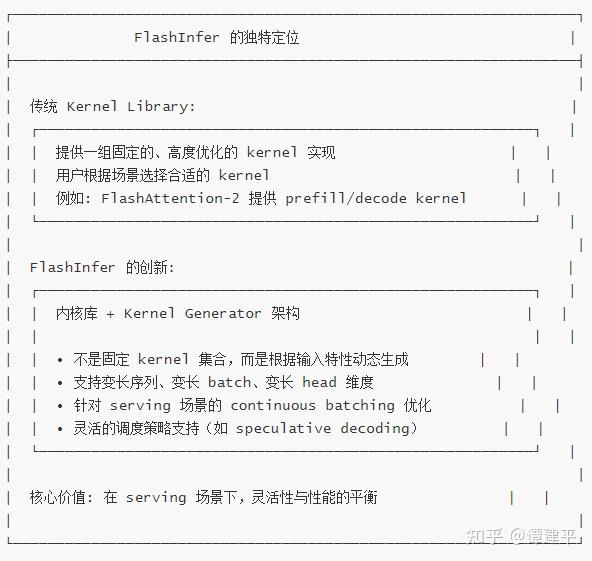
FlashInfer 第1章:项目定位_它为什么不是"又一个 attention kernel" - 知乎
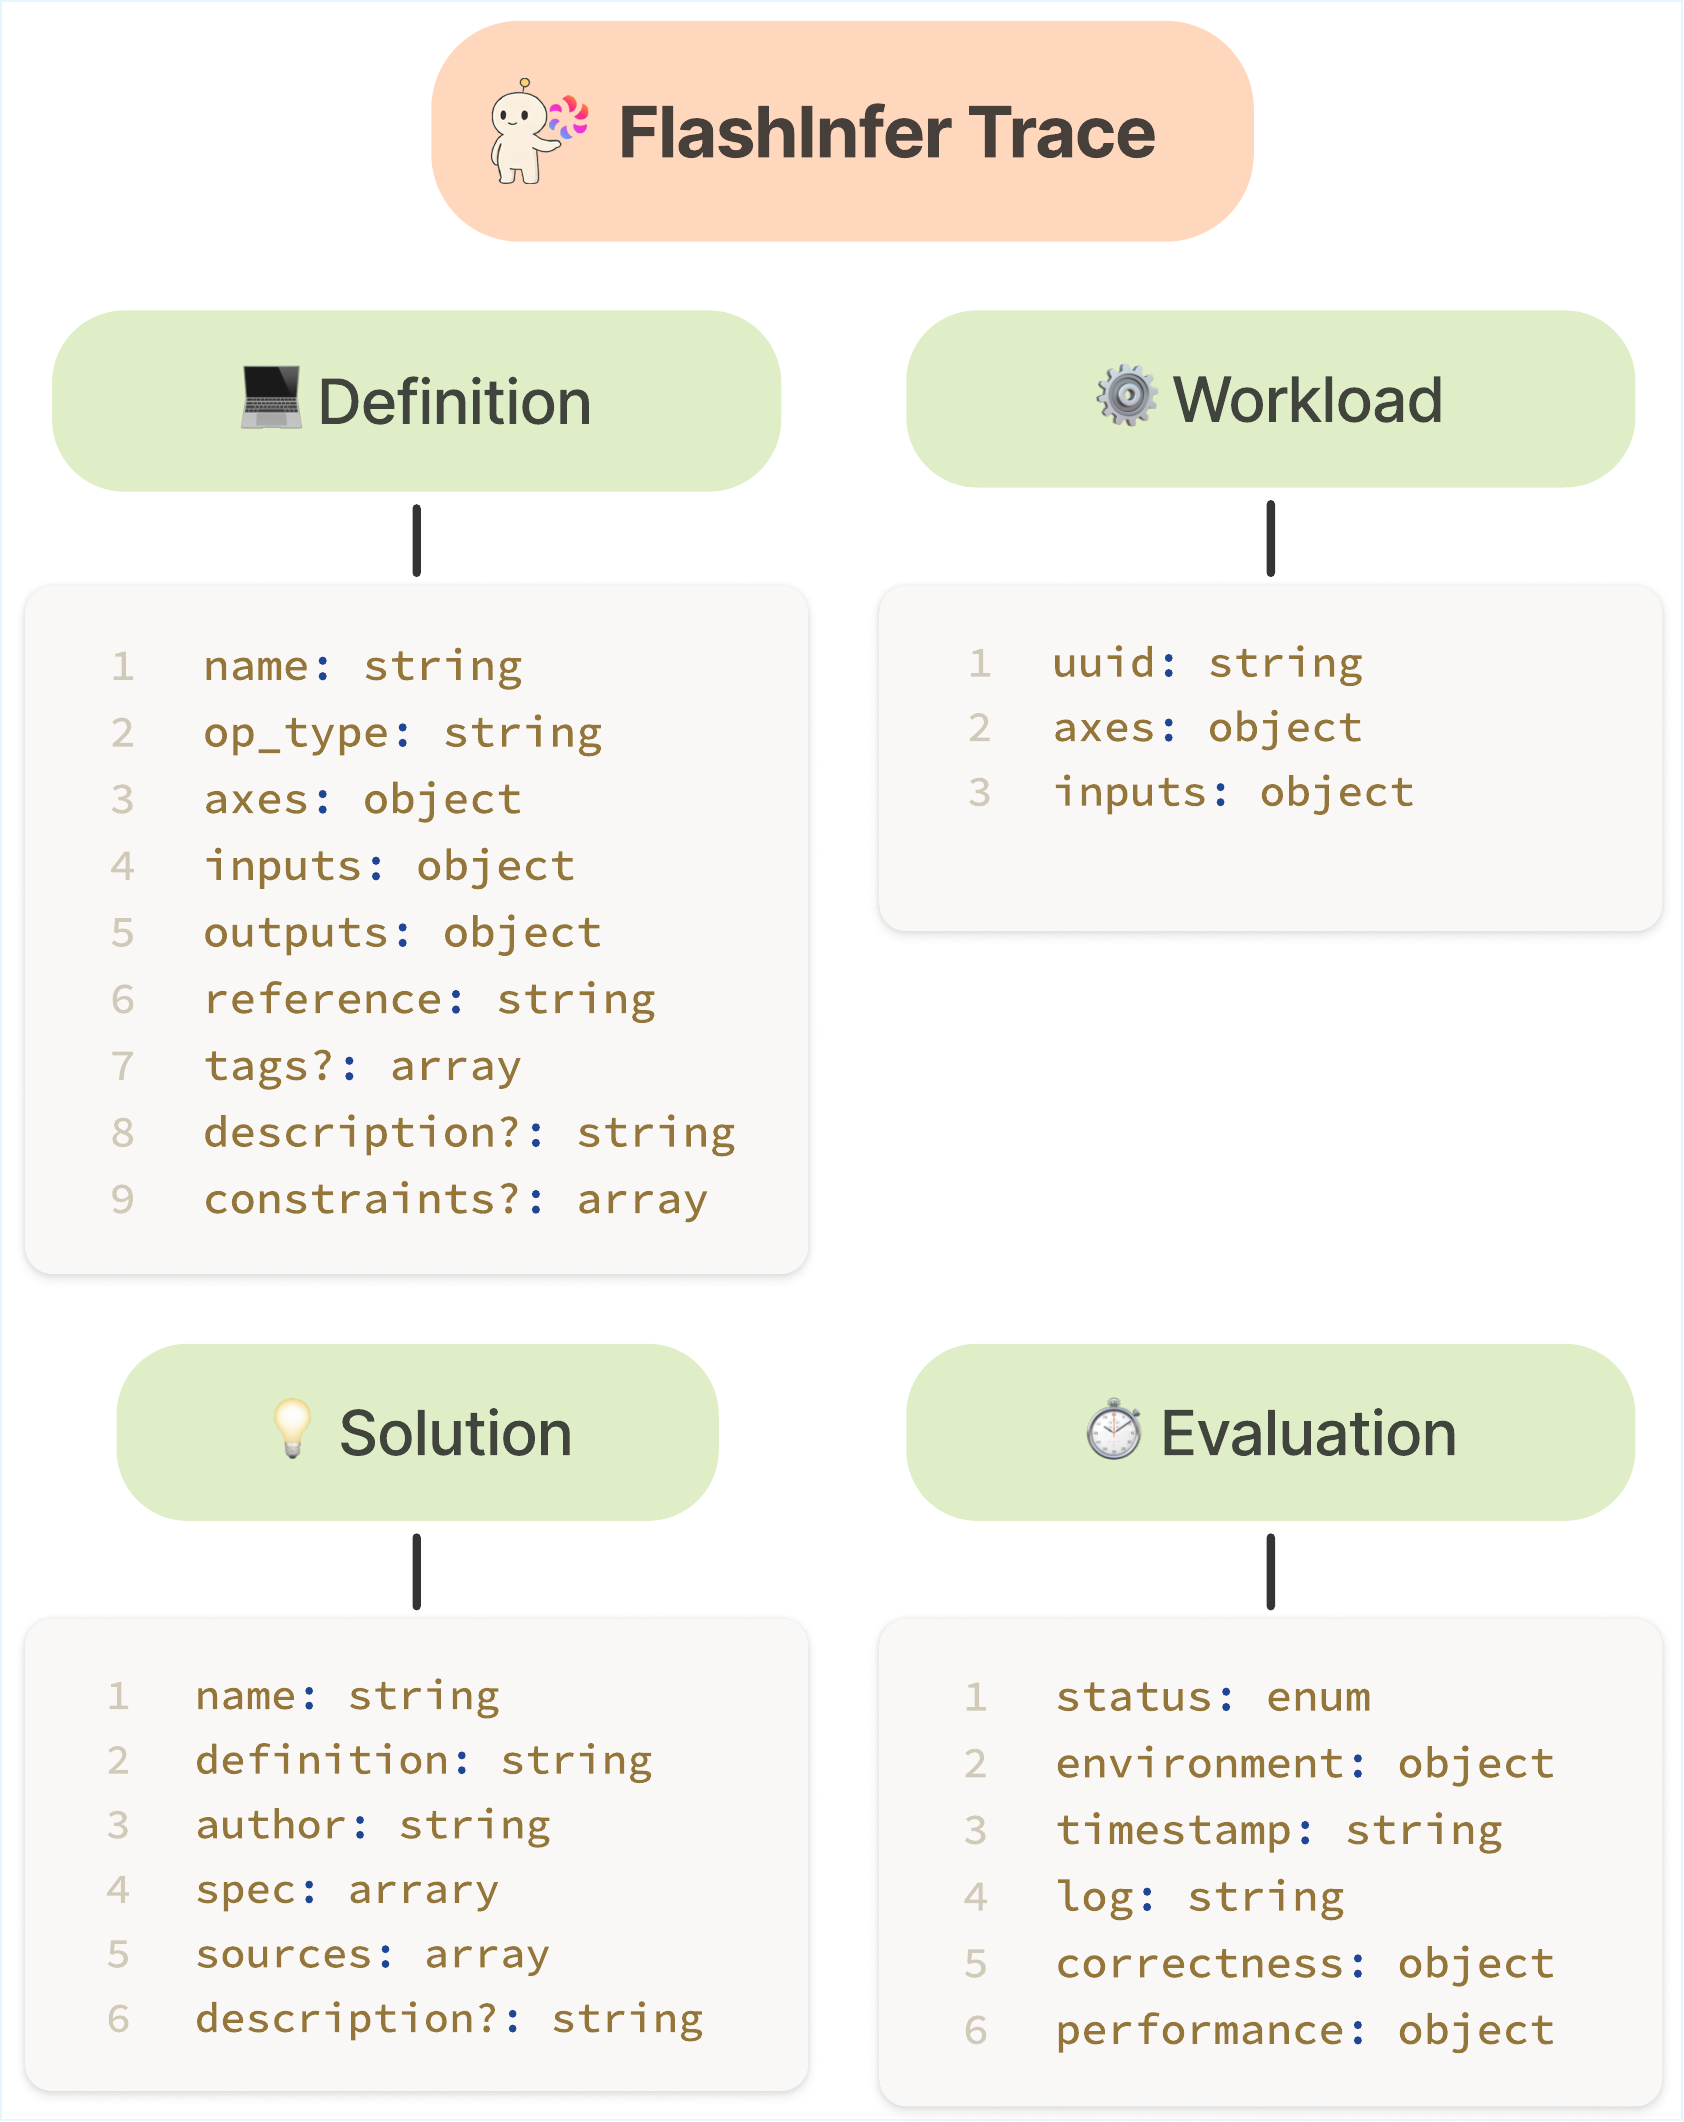
FlashInfer-Bench: Building the Virtuous Cycle for AI-driven
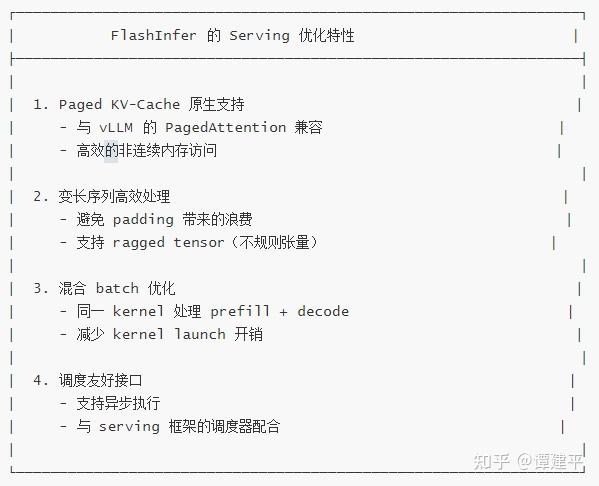
FlashInfer 第1章:项目定位_它为什么不是"又一个 attention kernel" - 知乎
GitHub - crafff/FlashInfer-AI-Kernel-Xuanwu

[KVCache] FlashInfer

Bring Your Own Kernel to FlashInfer-Bench - FlashInfer-Bench
add-cuda-kernel - Add CUDA Kernels to FlashInfer - Skillstore
Custom Kernel Development | flashinfer-ai/flashinfer-bench | DeepWiki
Advertisement Space (336x280)
[Bug] module 'flashinfer' has no attribute 'mla' · Issue #792 · kvcache ...
Attention Kernel Implementation | flashinfer-ai/flashinfer | DeepWiki
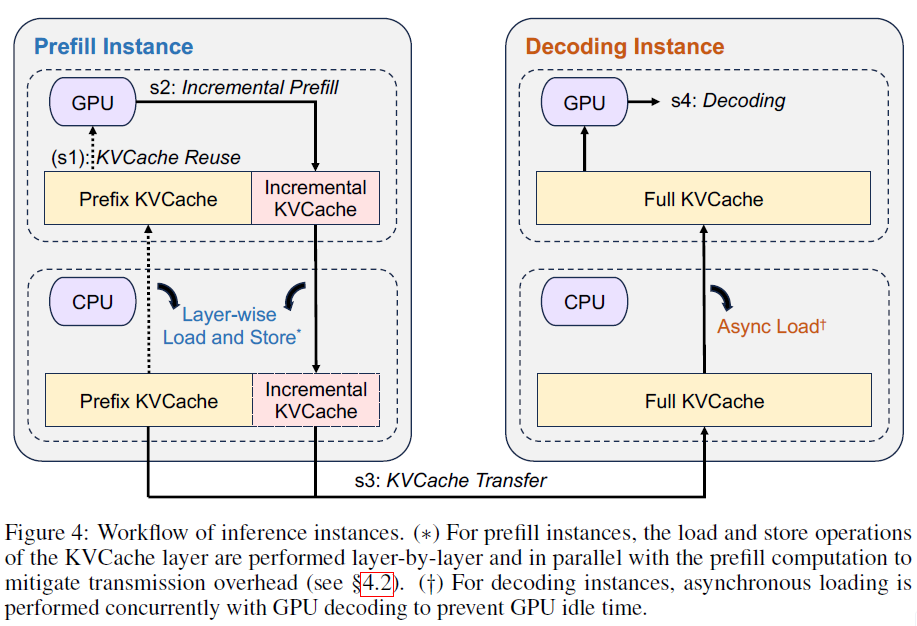
Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving ...
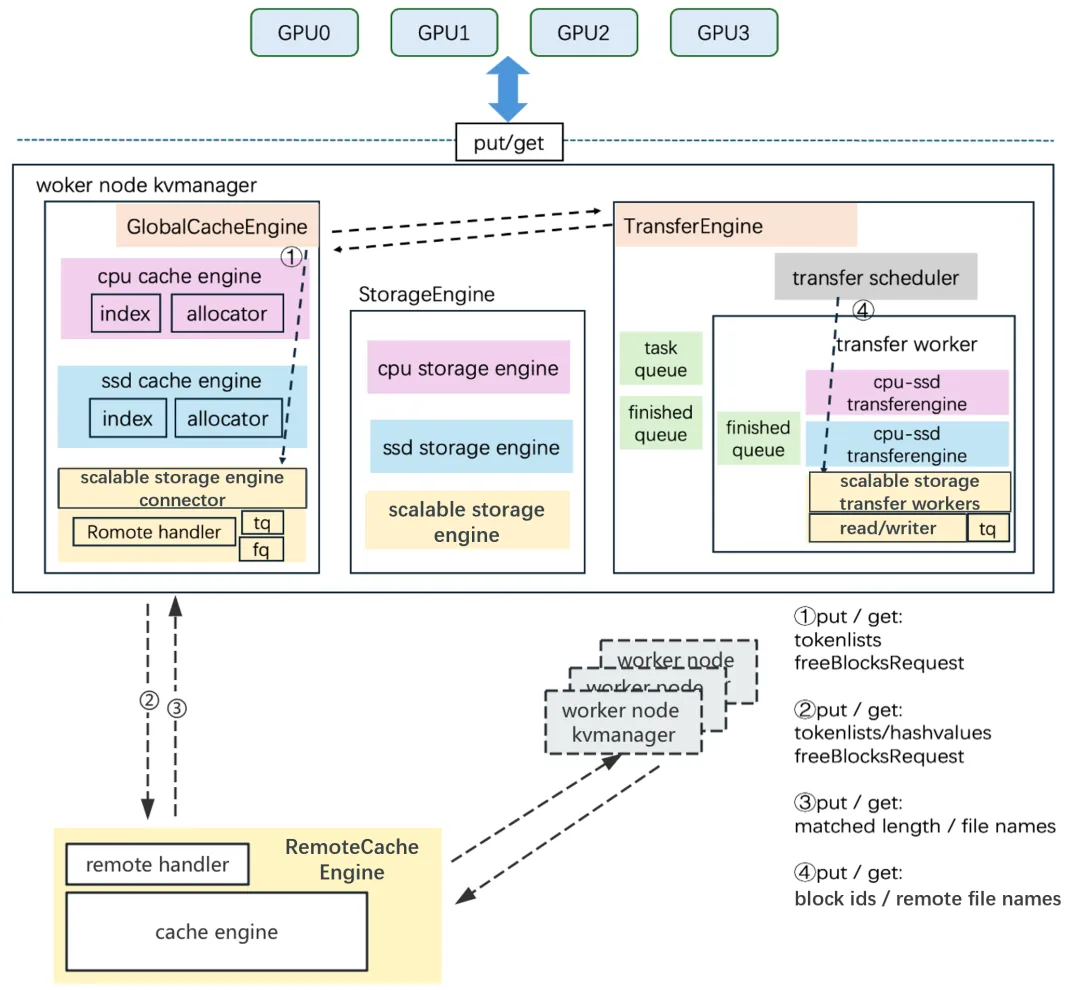
FlexKV首页、文档和下载 - 面向高性能分布式推理的 KVCache Manager - OSCHINA - 中文开源技术交流社区
FlashInfer download | SourceForge.net

Run High-Performance LLM Inference Kernels from NVIDIA Using FlashInfer ...