
Github Lmcachelmbench Modular Serving Engine X Workload Generator

GitHub - LMCache/LMBench: Modular Serving Engine x Workload Generator ...
GitHub - LMCache/LMBench: Modular Serving Engine x Workload Generator ...

Modular: Accelerating AI model serving with the Modular AI Engine
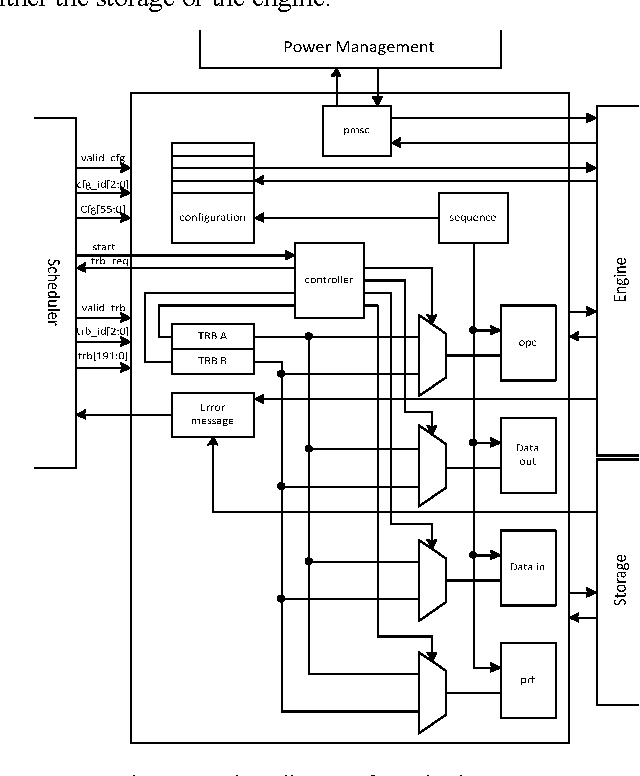
Figure 5 from Design of workload generator for modular hardware ...
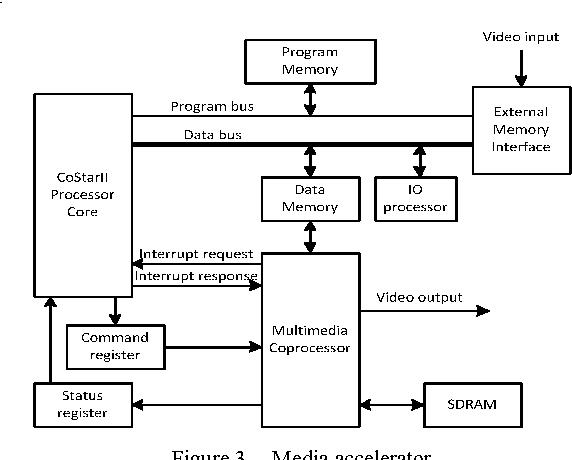
Figure 3 from Design of workload generator for modular hardware ...
Modular: Accelerating AI model serving with the Modular AI Engine

Modular: Accelerating AI model serving with the Modular AI Engine
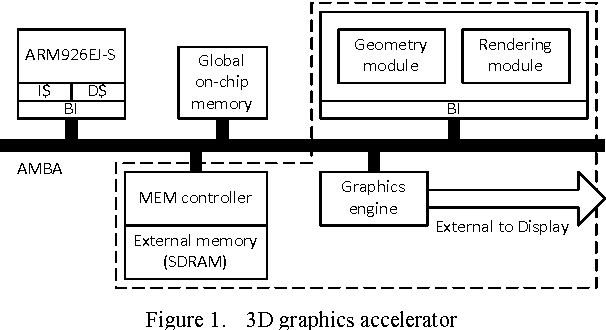
Figure 1 from Design of workload generator for modular hardware ...

Modular: Accelerating AI model serving with the Modular AI Engine

Autellix: An Efficient Serving Engine for LLM Agents as General ...
Advertisement Space (300x250)

BurstGPT: A Real-World Workload Dataset to Optimize LLM Serving Systems ...

Md - The fastest serving engine for LLMs is here (open-source)! LMCache ...

LMCache: Fast LLM Serving Engine with Cache | Sumanth P posted on the ...
GitHub - modular/modular: The Modular Platform (includes MAX & Mojo ...
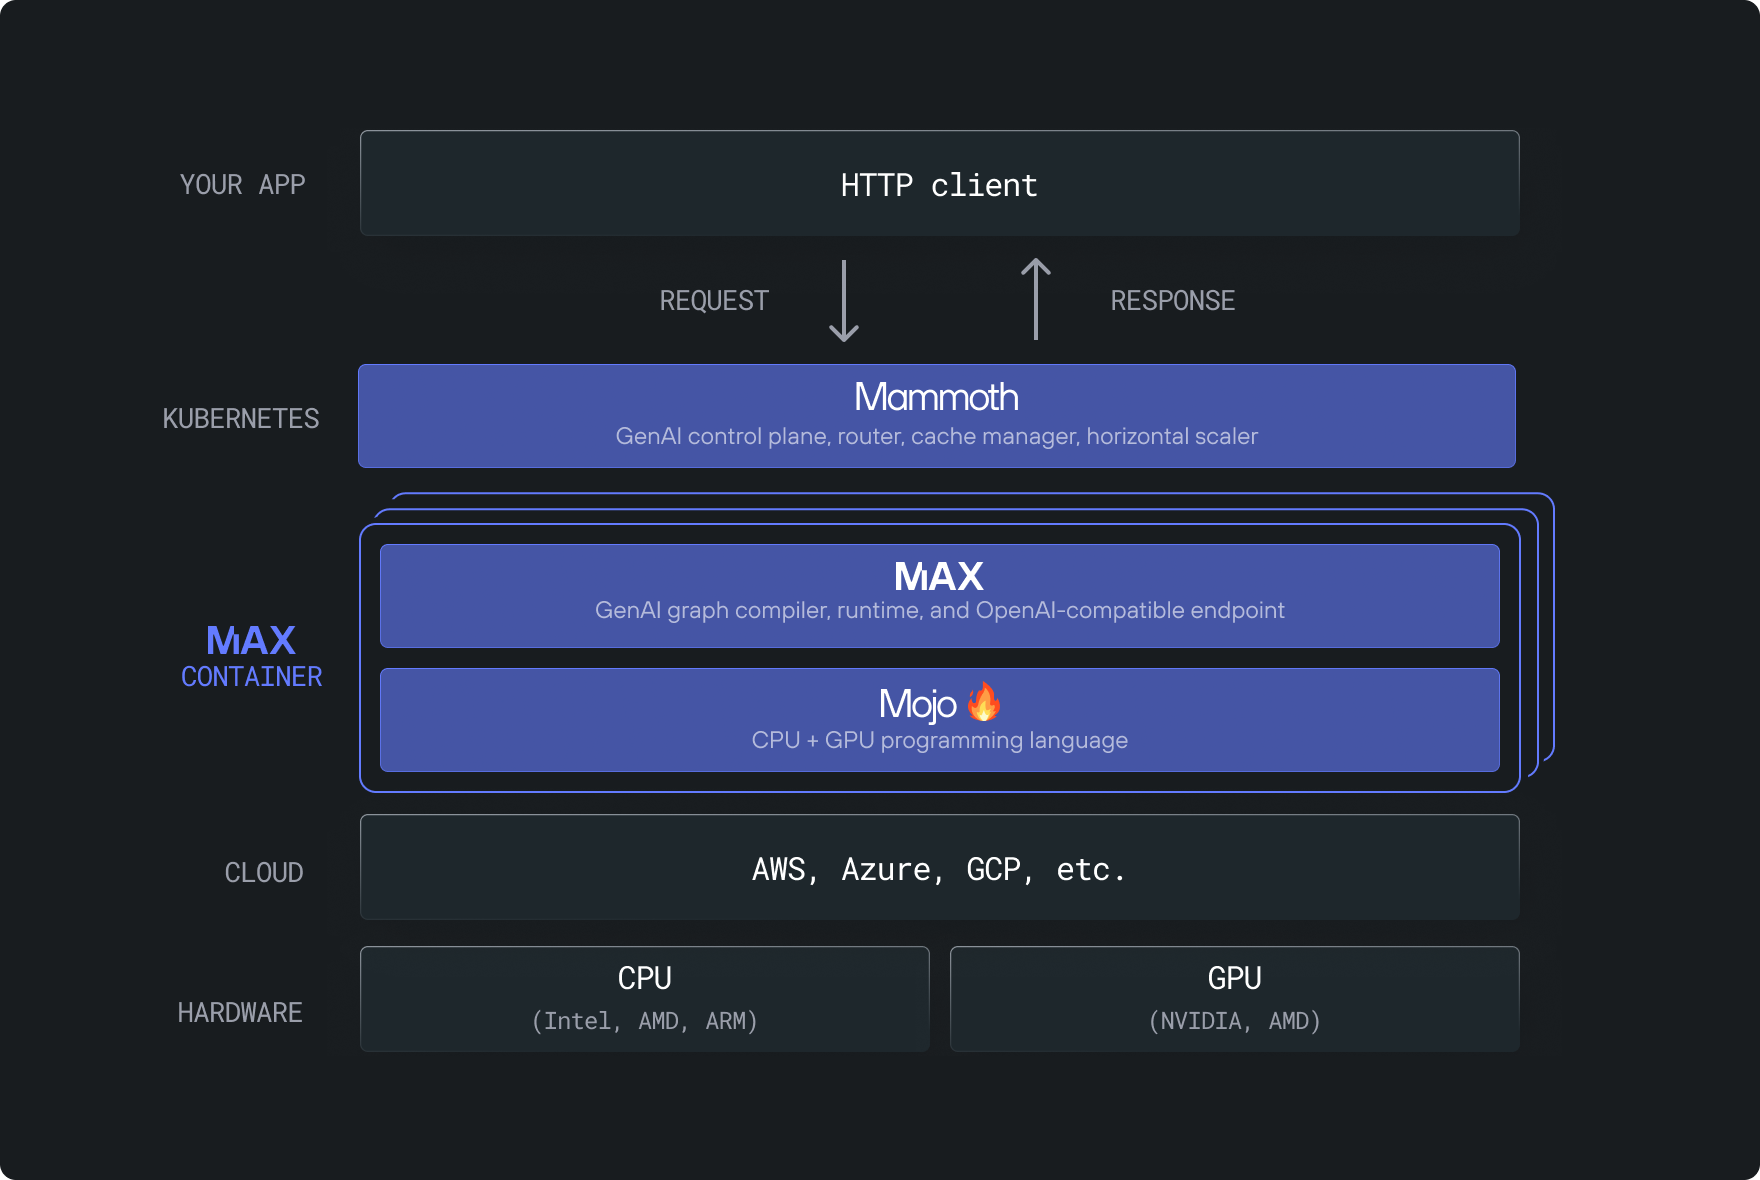
GitHub - modular/modular: The Modular Platform (includes MAX & Mojo ...

GitHub - LouisSch/Backtest-Engine: A modular high-performance C++ ...

Autellix: An Efficient Serving Engine for LLM Agents as General ...

vLLM: Open-Source LLM Inference Engine for Multi-Tenant Serving ...
Serving Engine Configuration | vllm-project/production-stack | DeepWiki
Discussion on "The Imperative: Why LLM Serving Engine Choice Defines ...
Advertisement Space (336x280)

The architecture of the workload generator | Download Scientific Diagram
What is vLLM? | High-Throughput LLM Serving Engine | Inference Systems

Autellix: An Efficient Serving Engine for LLM Agents as General ...

Autellix: An Efficient Serving Engine for LLM Agents as General ...
CVE-2026-34760: vLLM is an inference and serving engine for large ...
GitHub - mzbac/mlx-llm-server: For inferring and serving local LLMs ...

Autellix: An Efficient Serving Engine for LLM Agents as General ...

Autellix: An Efficient Serving Engine for LLM Agents as General ...

Steam Community :: Guide :: How to make a modular engine
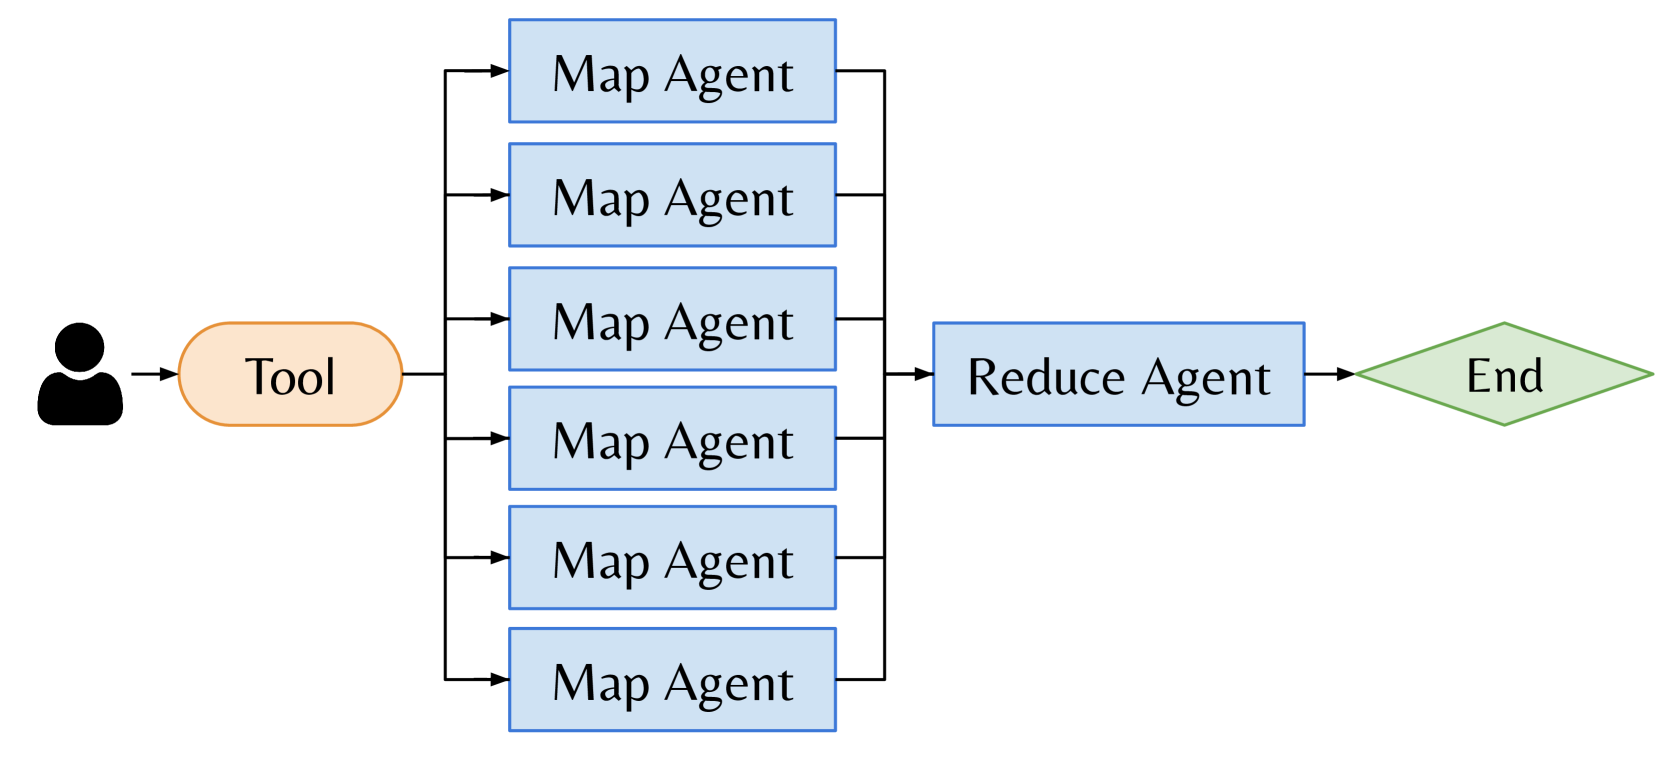
Autellix: An Efficient Serving Engine for LLM Agents as General ...
Advertisement Space (336x280)
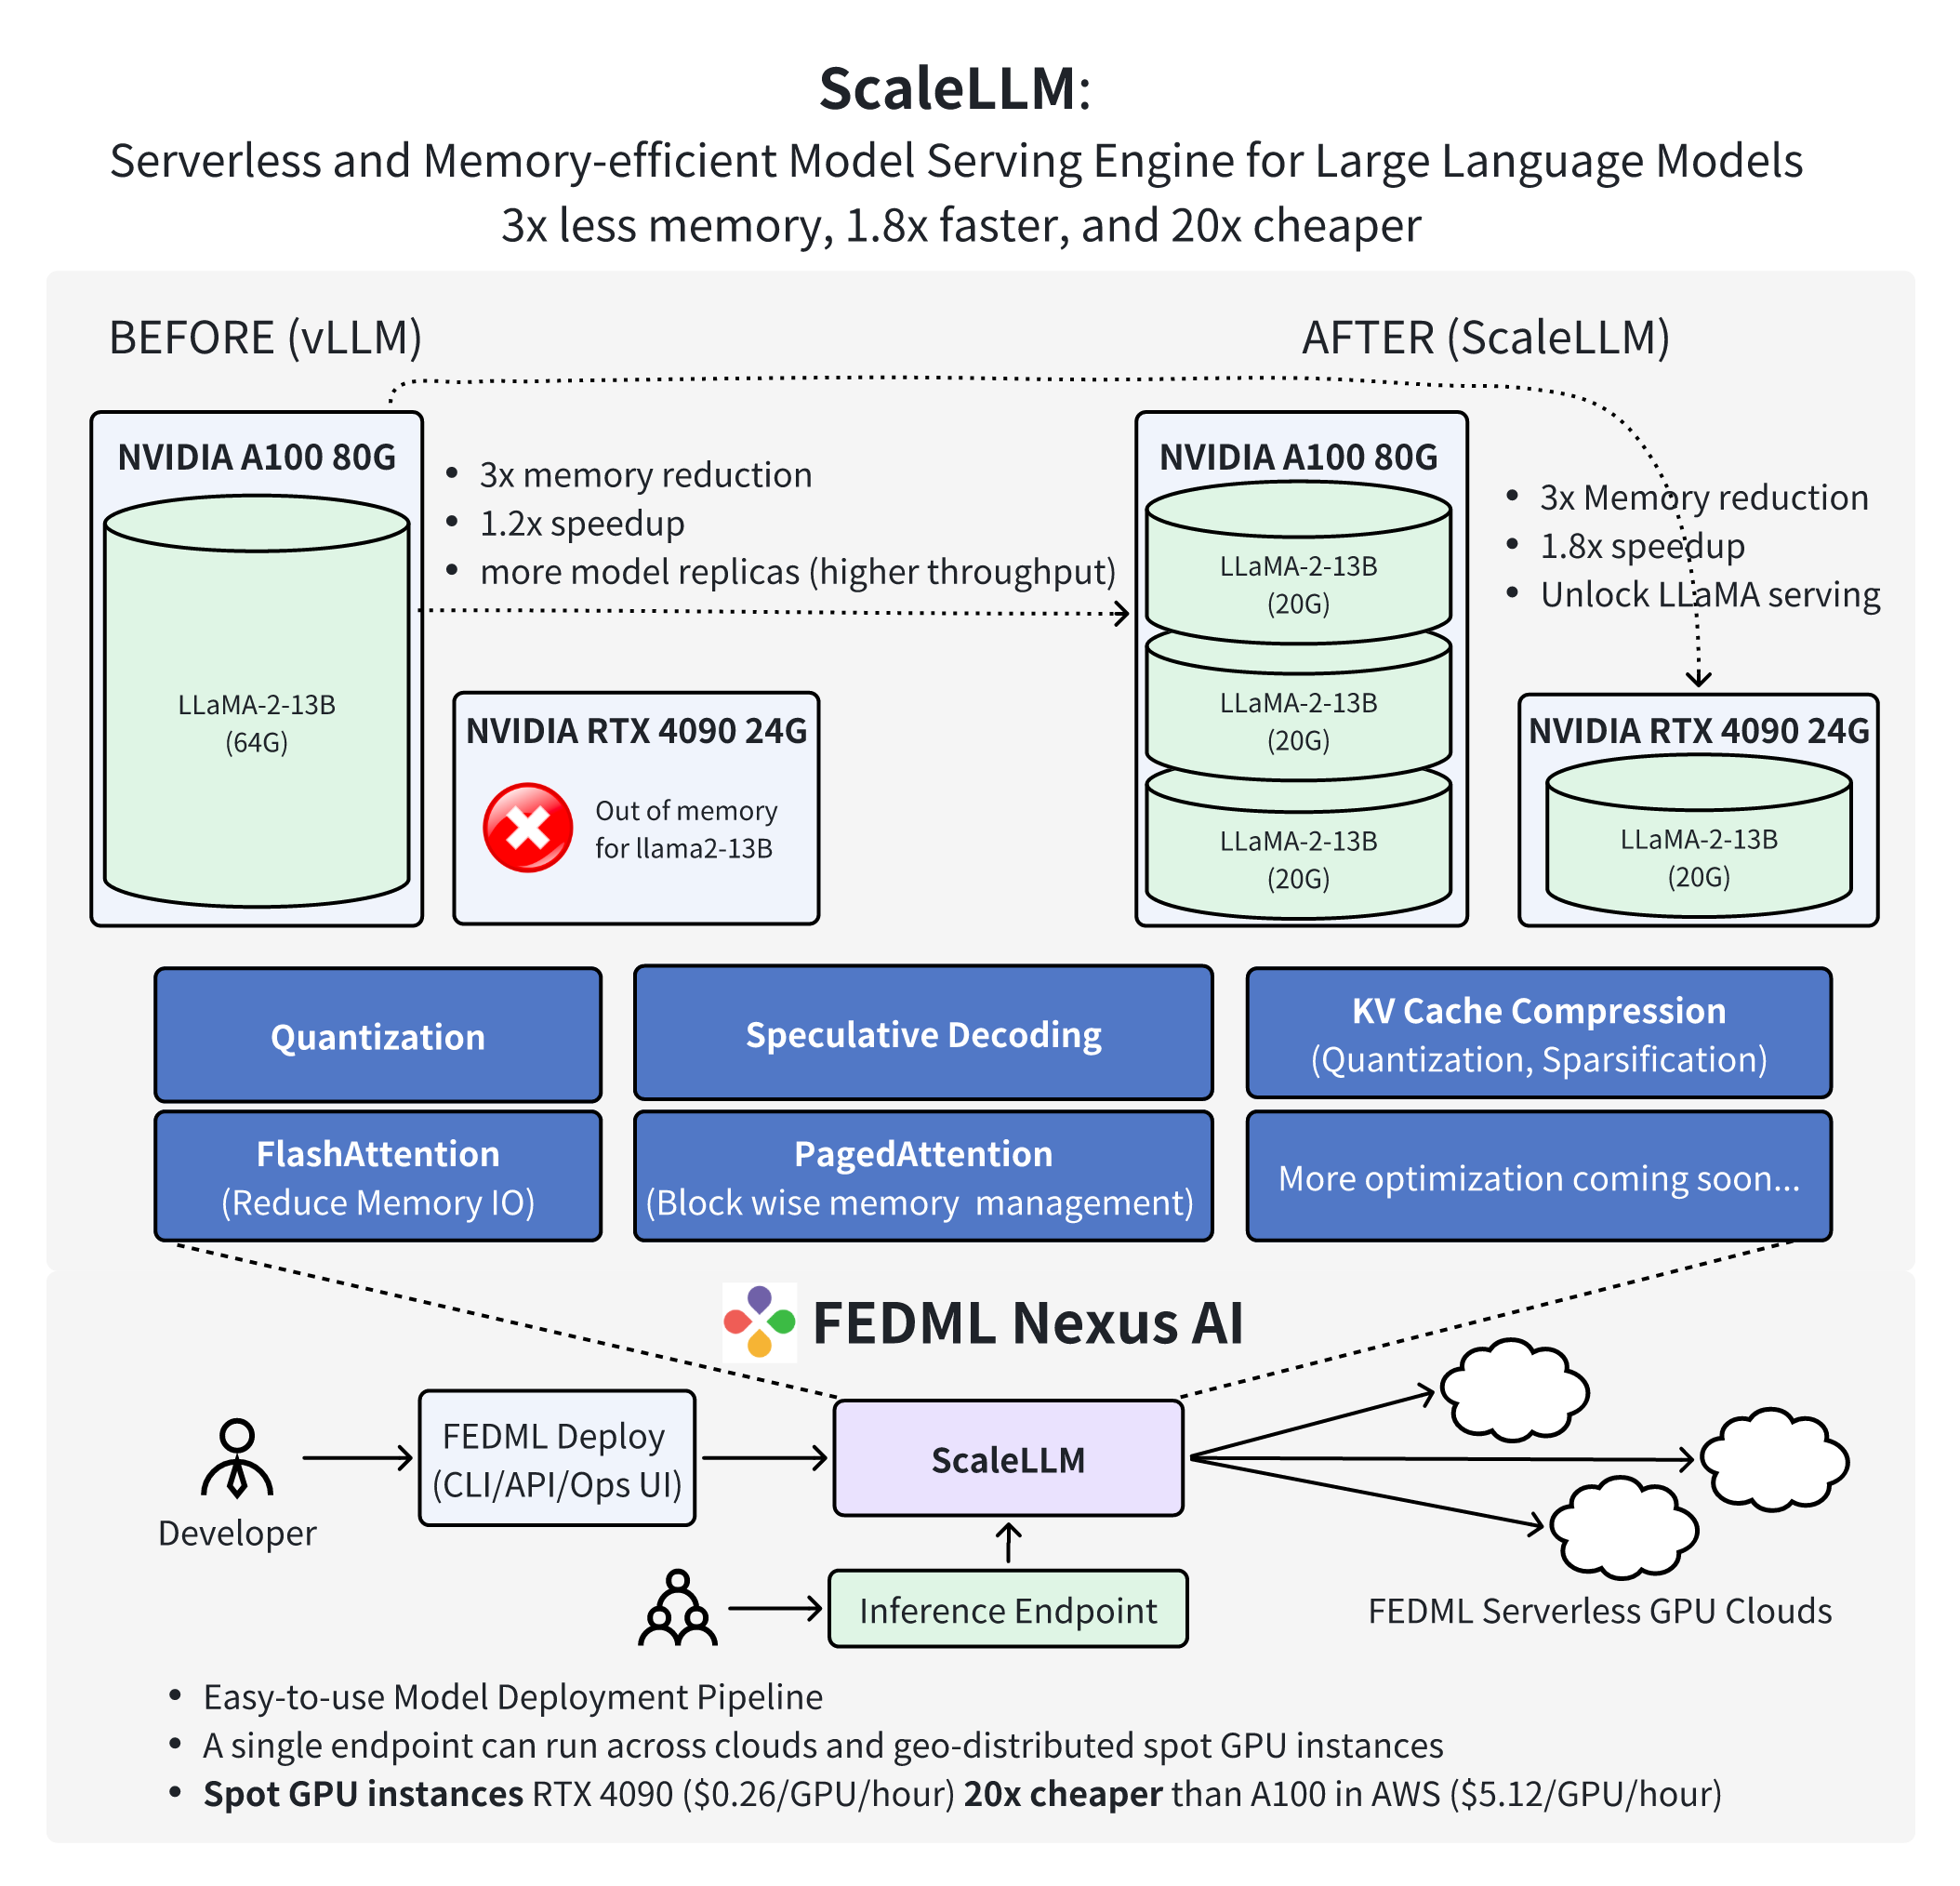
ScaleLLM: Serverless and Memory-efficient Model Serving Engine for ...

See the fastest LLM serving engine, 100% open source!!! | Eduardo Ordax
Integration with Serving Engines | LMCache/LMCache | DeepWiki
GitHub - hokiyoung/kv-cache-workload-bench: A ShareGPT-based multi ...
GitHub - leigao97/vllm-bench: A high-throughput and memory-efficient ...
GitHub - lili321456/LMCBench