
Github Machinelearningsystem22nips Flash Attention Fast And Memory
GitHub - MachineLearningSystem/22NIPS-flash-attention: Fast and memory ...

GitHub - MachineLearningSystem/22NIPS-flash-attention: Fast and memory ...

GitHub - MachineLearningSystem/22NIPS-flash-attention: Fast and memory ...

Flash Attention for AI Workloads: Improving Performance and GPU Memory ...

GitHub - MachineLearningSystem/22NIPS-flash-attention: Fast and memory ...

Flash attention(Fast and Memory-Efficient Exact Attention with IO ...
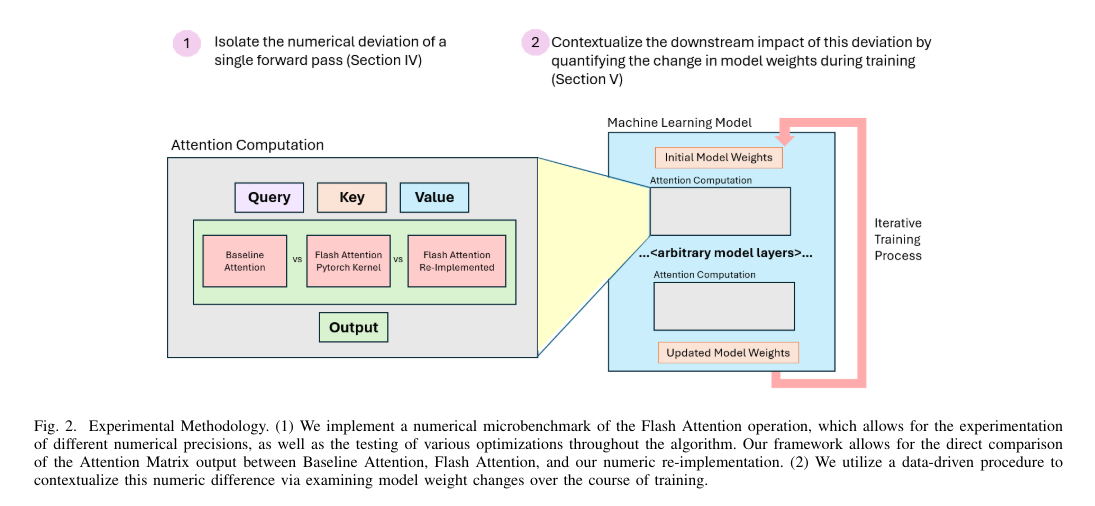
Analyzing the Impact of Flash Attention on Numeric Deviation and ...

Flash attention(Fast and Memory-Efficient Exact Attention with IO ...

GitHub - Yard1/vllm-flash-attention: Fast and memory-efficient exact ...
GitHub - Dao-AILab/flash-attention: Fast and memory-efficient exact ...
Advertisement Space (300x250)

GitHub - Oneflow-Inc/flash-attention-v2: Fast and memory-efficient ...

GitHub - neuralmagic/vllm-flash-attention: Fast and memory-efficient ...

GitHub - mdrumond/flash-attention: Fast and memory-efficient exact ...

GitHub - renll/customized-flash-attention: Fast and memory-efficient ...
GitHub - rishisankar/flashattention2: Flash Attention 2 CUDA ...
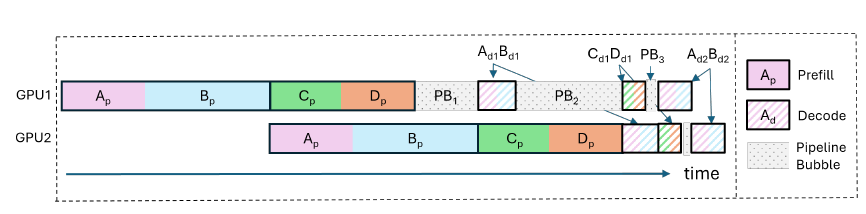
Flash Attention (Fast and Memory-Efficient Exact Attention with IO ...
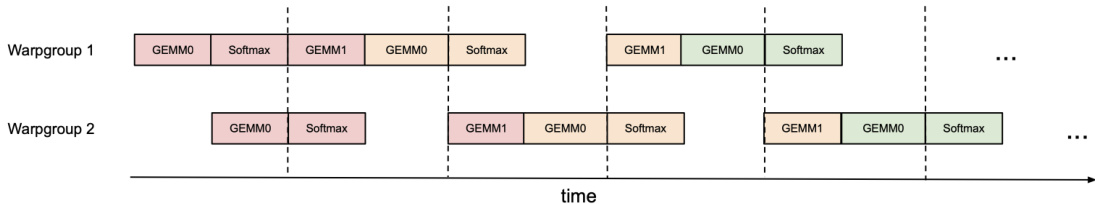
FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low ...
Requires flash attention 2 · Issue #4176 · modular/modular · GitHub

FlashAttention: Fast and Memory-Efficient Exact Attention with IO ...

[R] FlashAttention: Fast and Memory-Efficient Exact Attention with IO ...
Advertisement Space (336x280)

[R] FlashAttention: Fast and Memory-Efficient Exact Attention with IO ...

FlashAttention: Fast and Memory-Efficient Exact Attention with IO ...
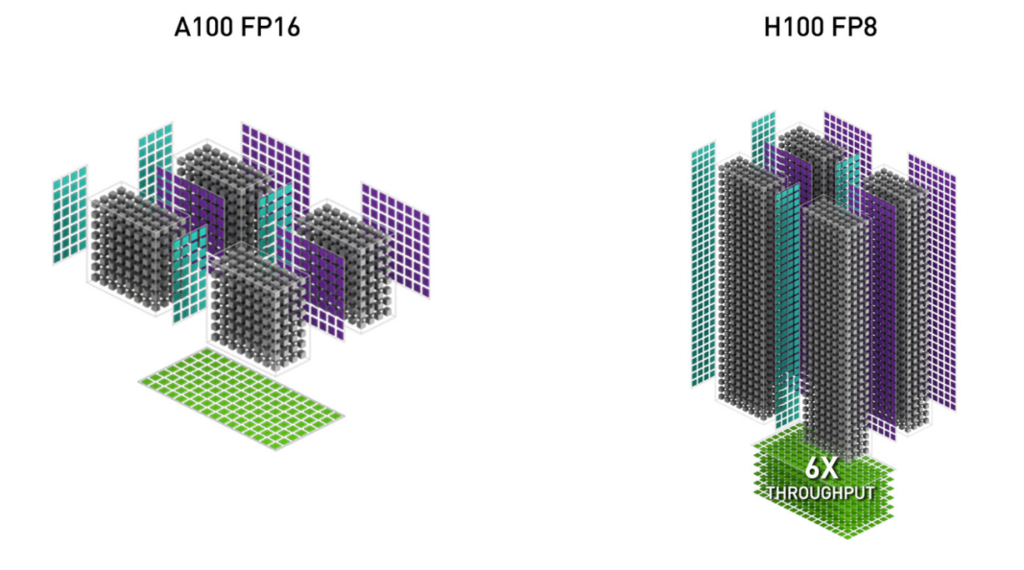
FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low ...

Flash attention(Fast and Memory-Efficient Exact Attention with IO ...
FlashAttention: Fast and Memory-Efficient Attention
Paper page - FlashAttention: Fast and Memory-Efficient Exact Attention ...
FlashAttention: Fast and Memory-Efficient Attention Algorithm (6803 ...
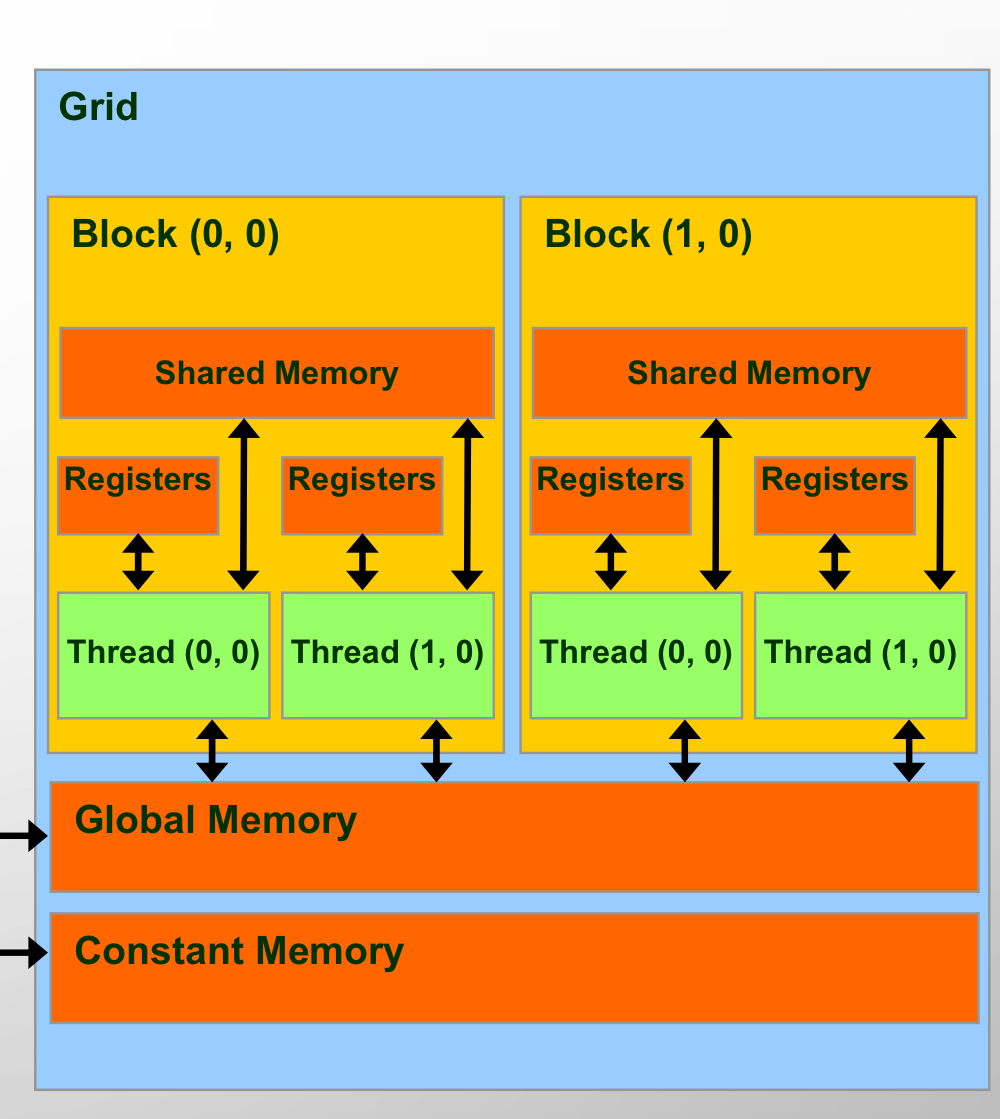
FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
Flash attention 加速效果较差,大约只提升5%的推理速度 · Issue #49 · QwenLM/Qwen · GitHub

flashT5: A fast implementation using Flash Attention : r/LocalLLaMA
Advertisement Space (336x280)

Flashattention: Fast and Memory-Efficient Exact Attention With Io ...

Flash attention(Fast and Memory-Efficient Exact Attention with IO ...
about flash attention v1 and v2 speed · Issue #114209 · pytorch/pytorch ...
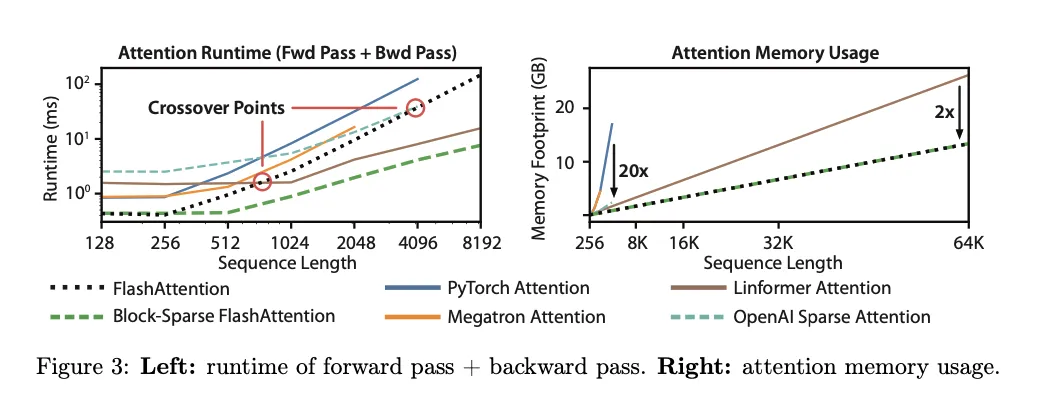
FlashAttention: Fast and Memory-Efficient Exact Attention with IO ...
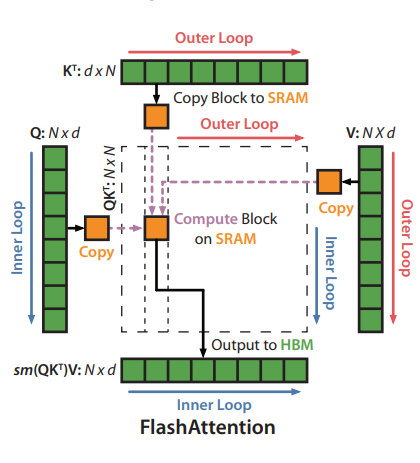
Paper Summary #8 - FlashAttention: Fast and Memory-Efficient Exact ...
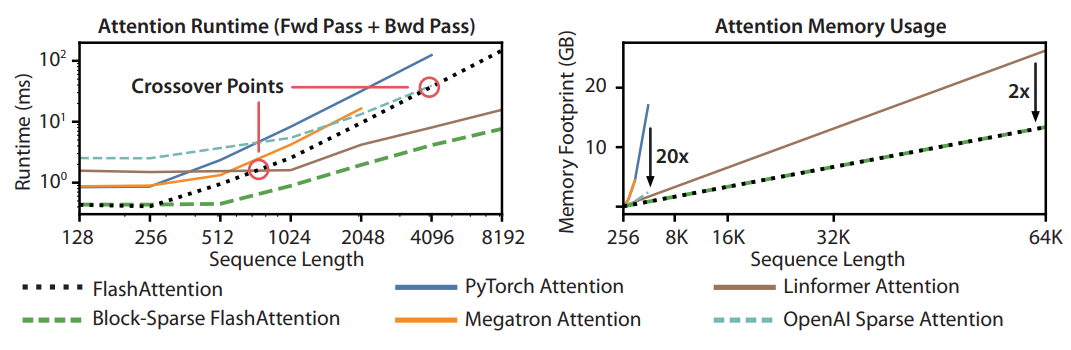
Paper Summary #8 - FlashAttention: Fast and Memory-Efficient Exact ...