
Github Maverick Escape Ordinary Codingevalllm Evaluate Llms
GitHub - maverick-escape-ordinary-coding/Eval_llm: Evaluate LLM's ...

GitHub - maverick-escape-ordinary-coding/Eval_llm: Evaluate LLM's ...
GitHub - gitwitorg/react-eval: Framework to evaluate LLM generated ...
Evaluate LLMs Effectively Using DeepEval: A Practical Guide | DataCamp
GitHub - mattpocock/evalite: Evaluate your LLM-powered apps with ...
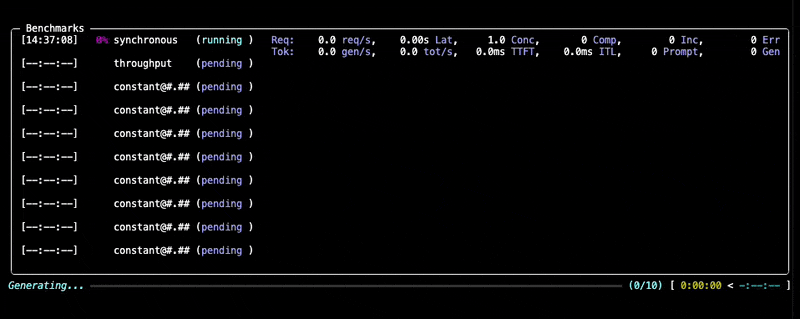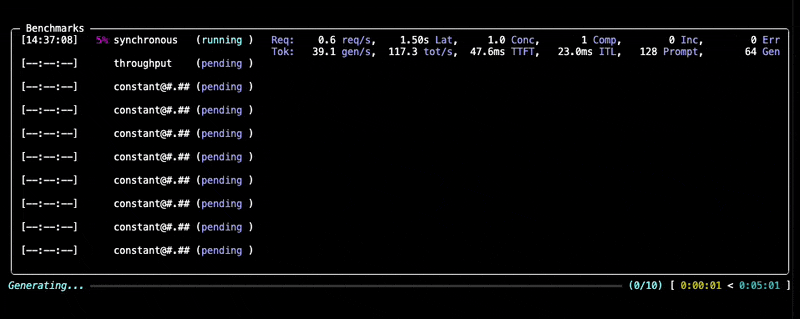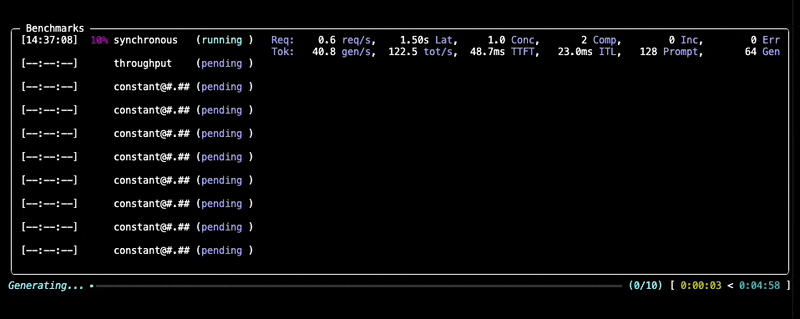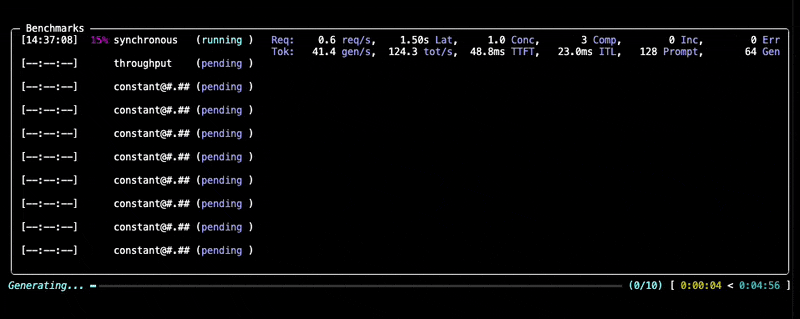
GitHub - vllm-project/guidellm: Evaluate and Enhance Your LLM ...

Evaluate LLMs with Language Model Evaluation Harness - YouTube

GitHub - vllm-project/guidellm: Evaluate and Enhance Your LLM ...

Evaluate LLMs Locally on Datasets - OpenCompass - Average Tool - YouTube
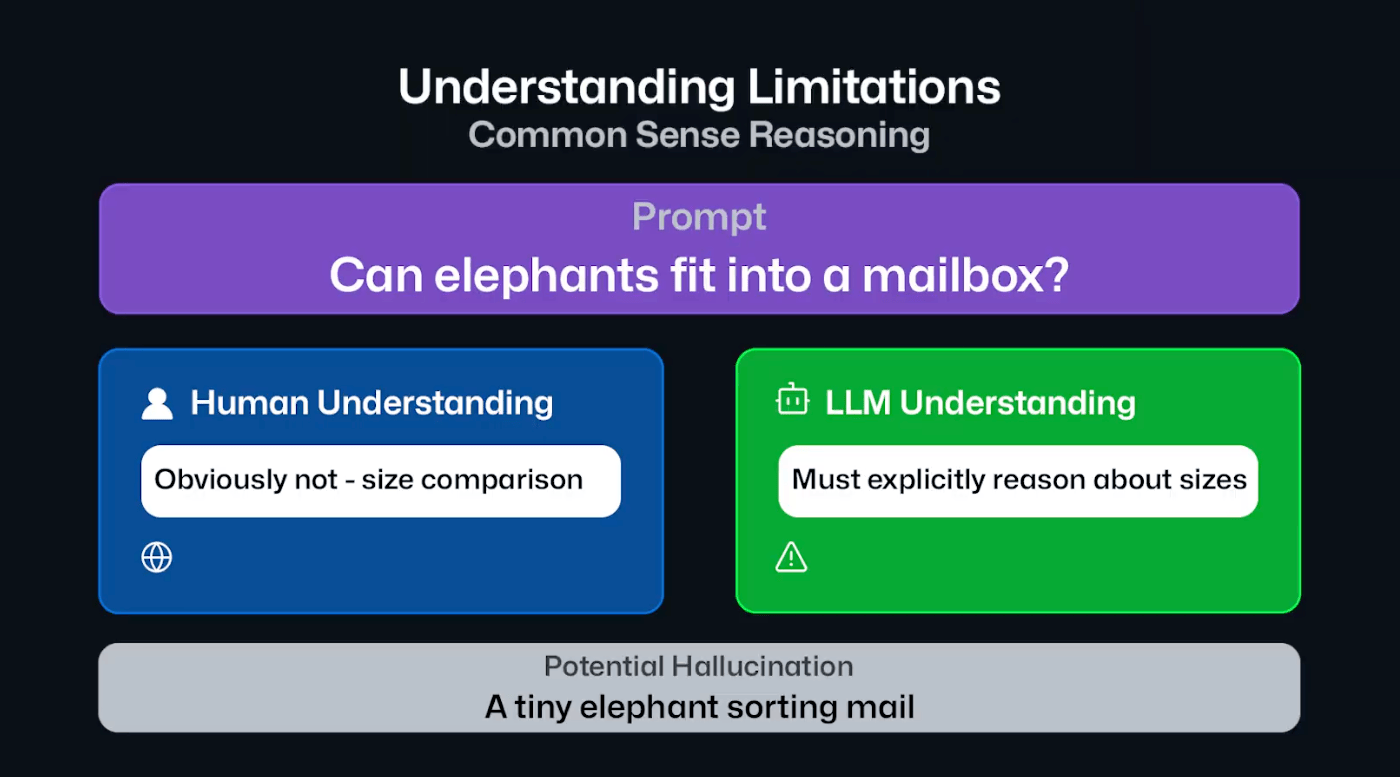
GitHub for Beginners: How to get LLMs to do what you want - The GitHub Blog
Advertisement Space (300x250)

How to evaluate LLMs using code and prompts | Karthik K.K posted on the ...

Four Ways Benchmark Providers Evaluate LLMs - Annielytics.com
How to Evaluate LLMs on Your Own Data (Practical Eval Harness for ...

How Do We Evaluate LLMs Performance Effectively?
GitHub - mlfoundations/evalchemy: Automatic evals for LLMs · GitHub

GitHub - Jellyfish042/uncheatable_eval: Evaluating LLMs with Dynamic ...

Free github pull request review tool based on ai maverick – Artofit
GitHub - vishal-labade/llm_exp_platform_v2: Experimentation framework ...

Does Teaming-Up LLMs Improve Secure Code Generation? A Comprehensive ...

[论文评述] HLS-Eval: A Benchmark and Framework for Evaluating LLMs on High ...
Advertisement Space (336x280)

5 Developer Techniques to Enhance LLMs Performance! - DEV Community
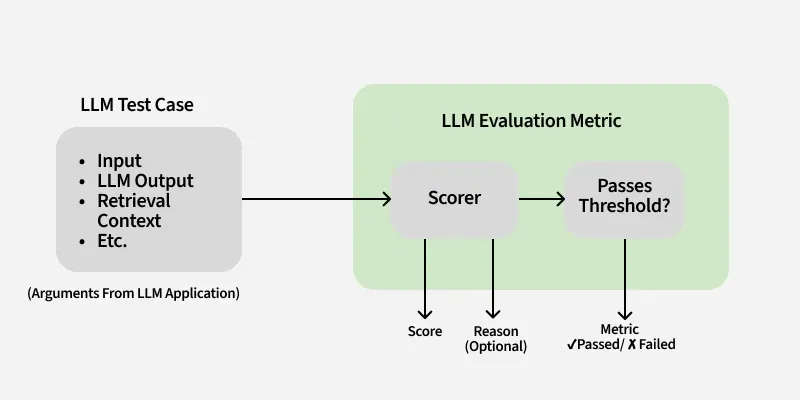
How to Evaluate LLMs? - GeeksforGeeks
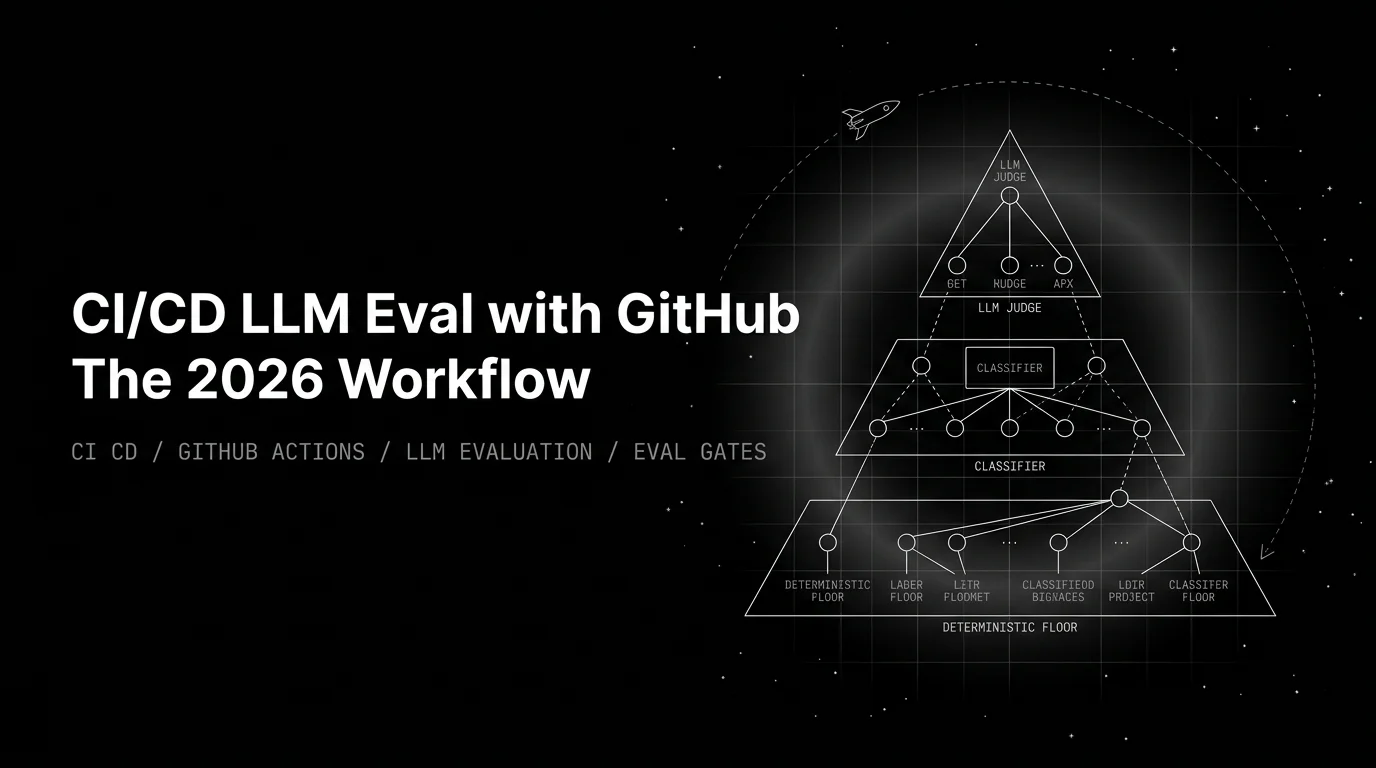
LLM Eval Gates in GitHub Actions (2026)

Evaluating LLM Models in GitHub Copilot. A Practical Scoring and ...
GitHub - evo-eval/evoeval: EvoEval: Evolving Coding Benchmarks via LLM ...

Meeseeks: An Iterative Benchmark Evaluating LLMs Multi-Turn Instruction ...
GitHub - vahinichilukamarri/llm-evaluation-engine: End-to-end AI system ...
GitHub - evalkit/evalkit: The TypeScript LLM Evaluation Library · GitHub
LLM Coding Benchmarks Explained: Evaluate Models for Agents | Blaxel Blog
GitHub - entbappy/LLM-Evaluation-with-MLFlow
Advertisement Space (336x280)
Evaluating LLMs for Production Beyond Benchmarks
GitHub - EvolvingLMMs-Lab/lmms-eval: One-for-All Multimodal Evaluation ...
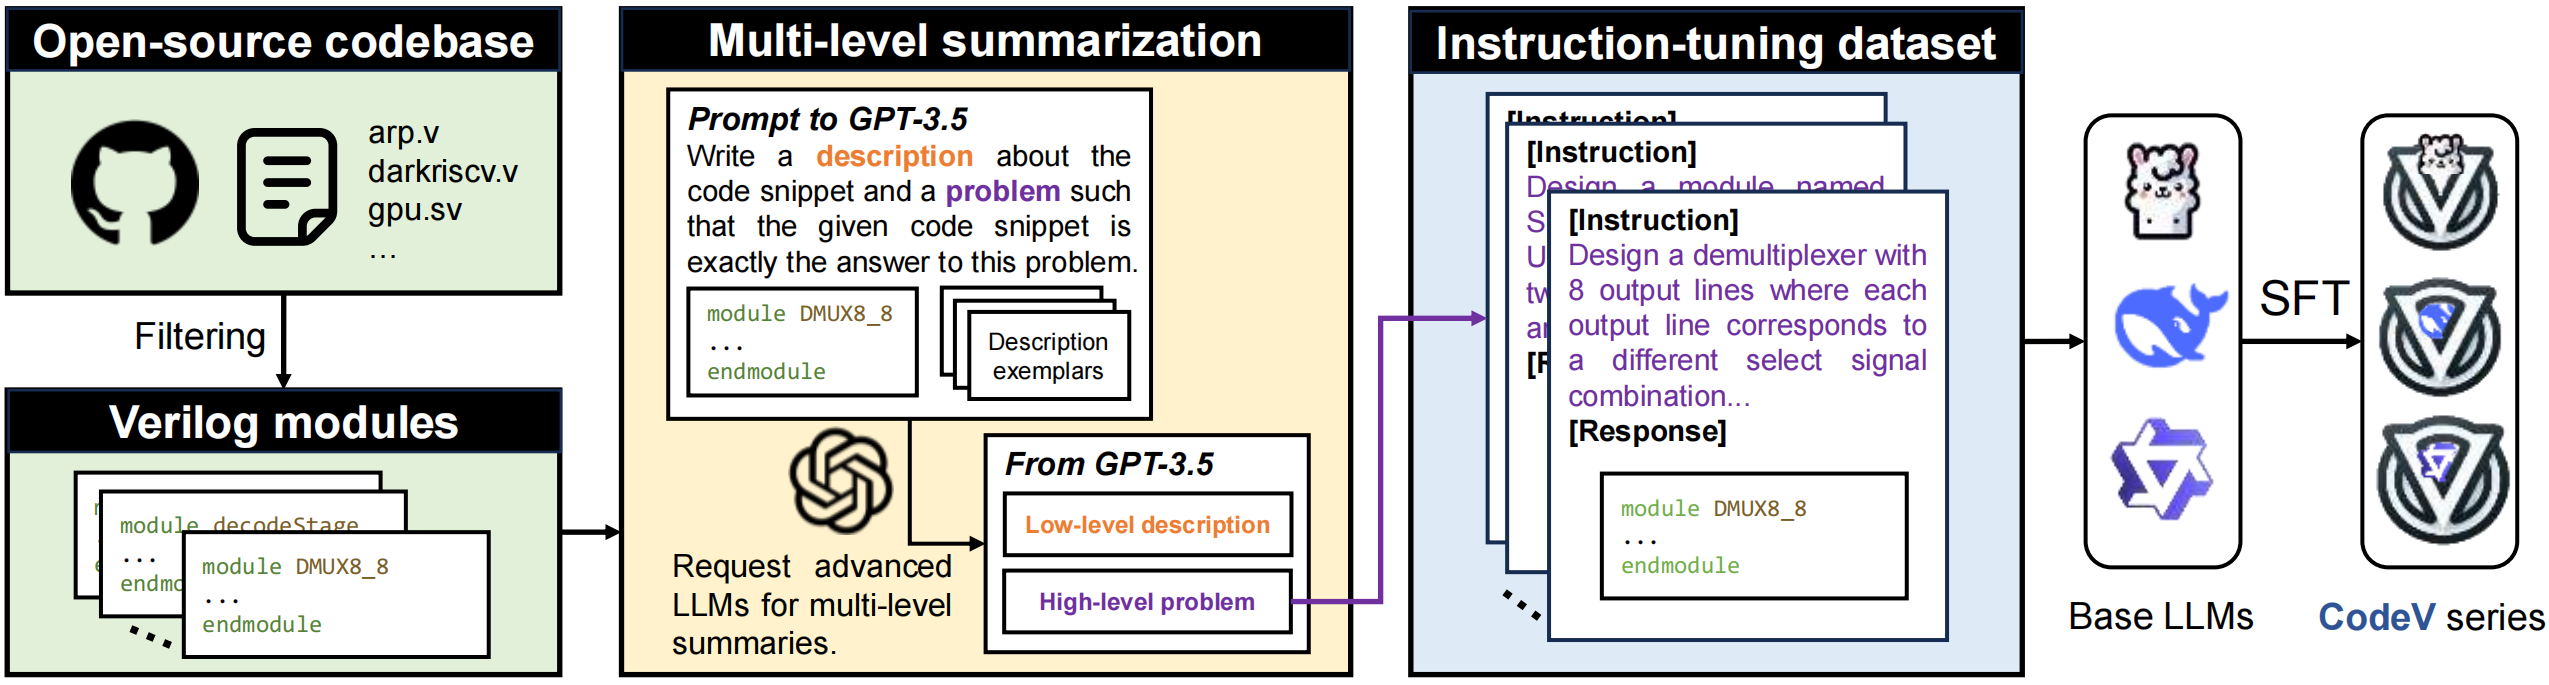
CodeV: Empowering LLMs for Verilog Generation through Multi-Level ...
GitHub - liohunter1/llm-coding-benchmark: Rigorous evaluation framework ...
Free Video: LLMs Coding RAG Applications? Evaluating Cursor, Aider ...
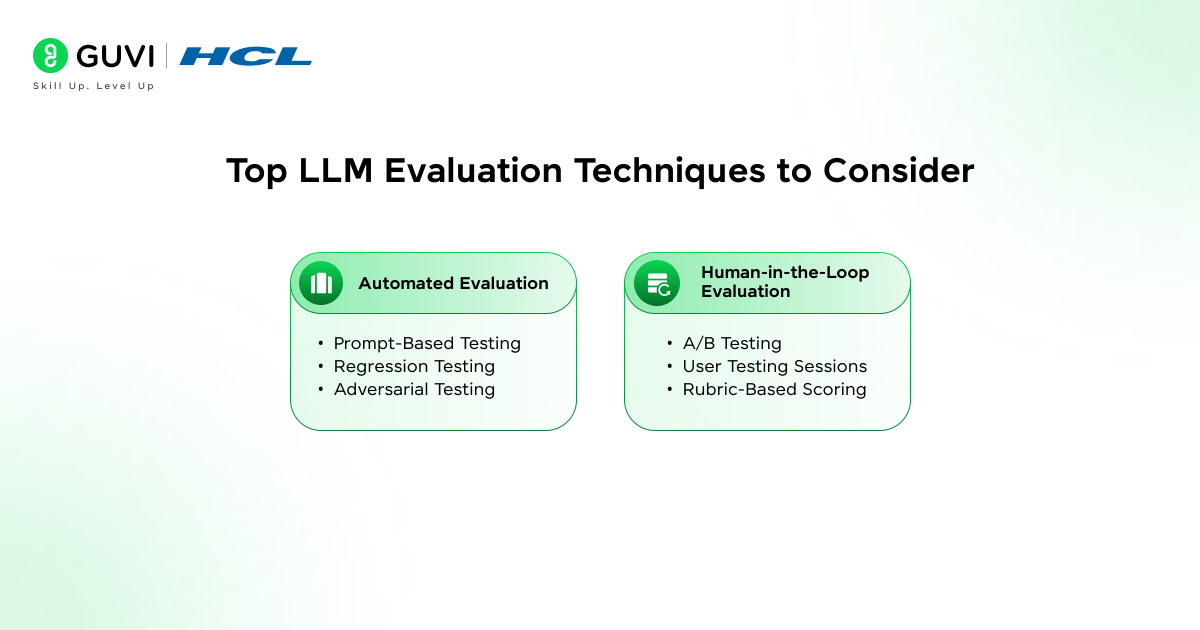
Evaluating LLMs for Production Beyond Benchmarks