
Github Mega Icectranslate2 Rocm Fast Inference Engine For
GitHub - mega-ice/CTranslate2-rocm: Fast inference engine for ...
ctranslate2 4.7.1 - Fast inference engine for Transformer models ...

[Revisión de artículo] MNN-LLM: A Generic Inference Engine for Fast ...
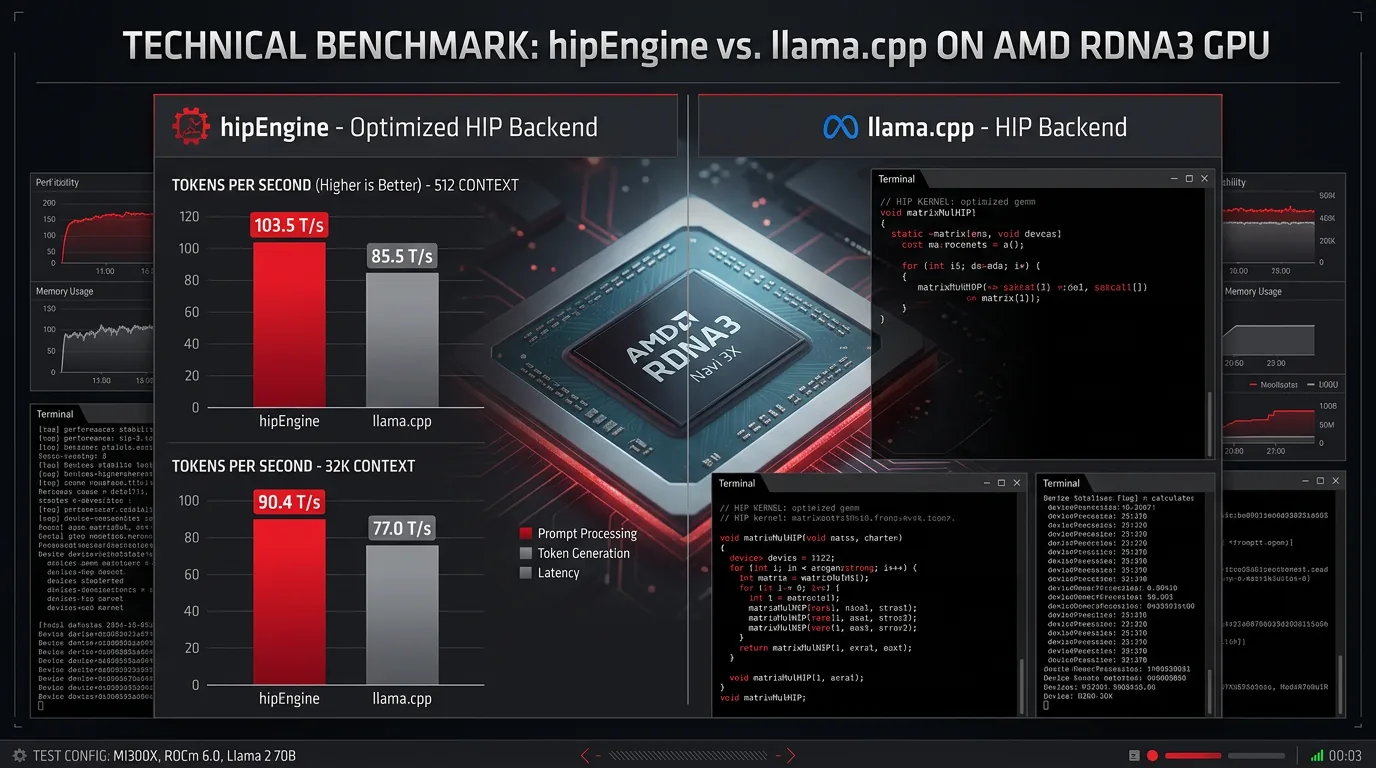
hipEngine – ROCm-native inference engine for AMD RDNA3 og Strix Halo ...
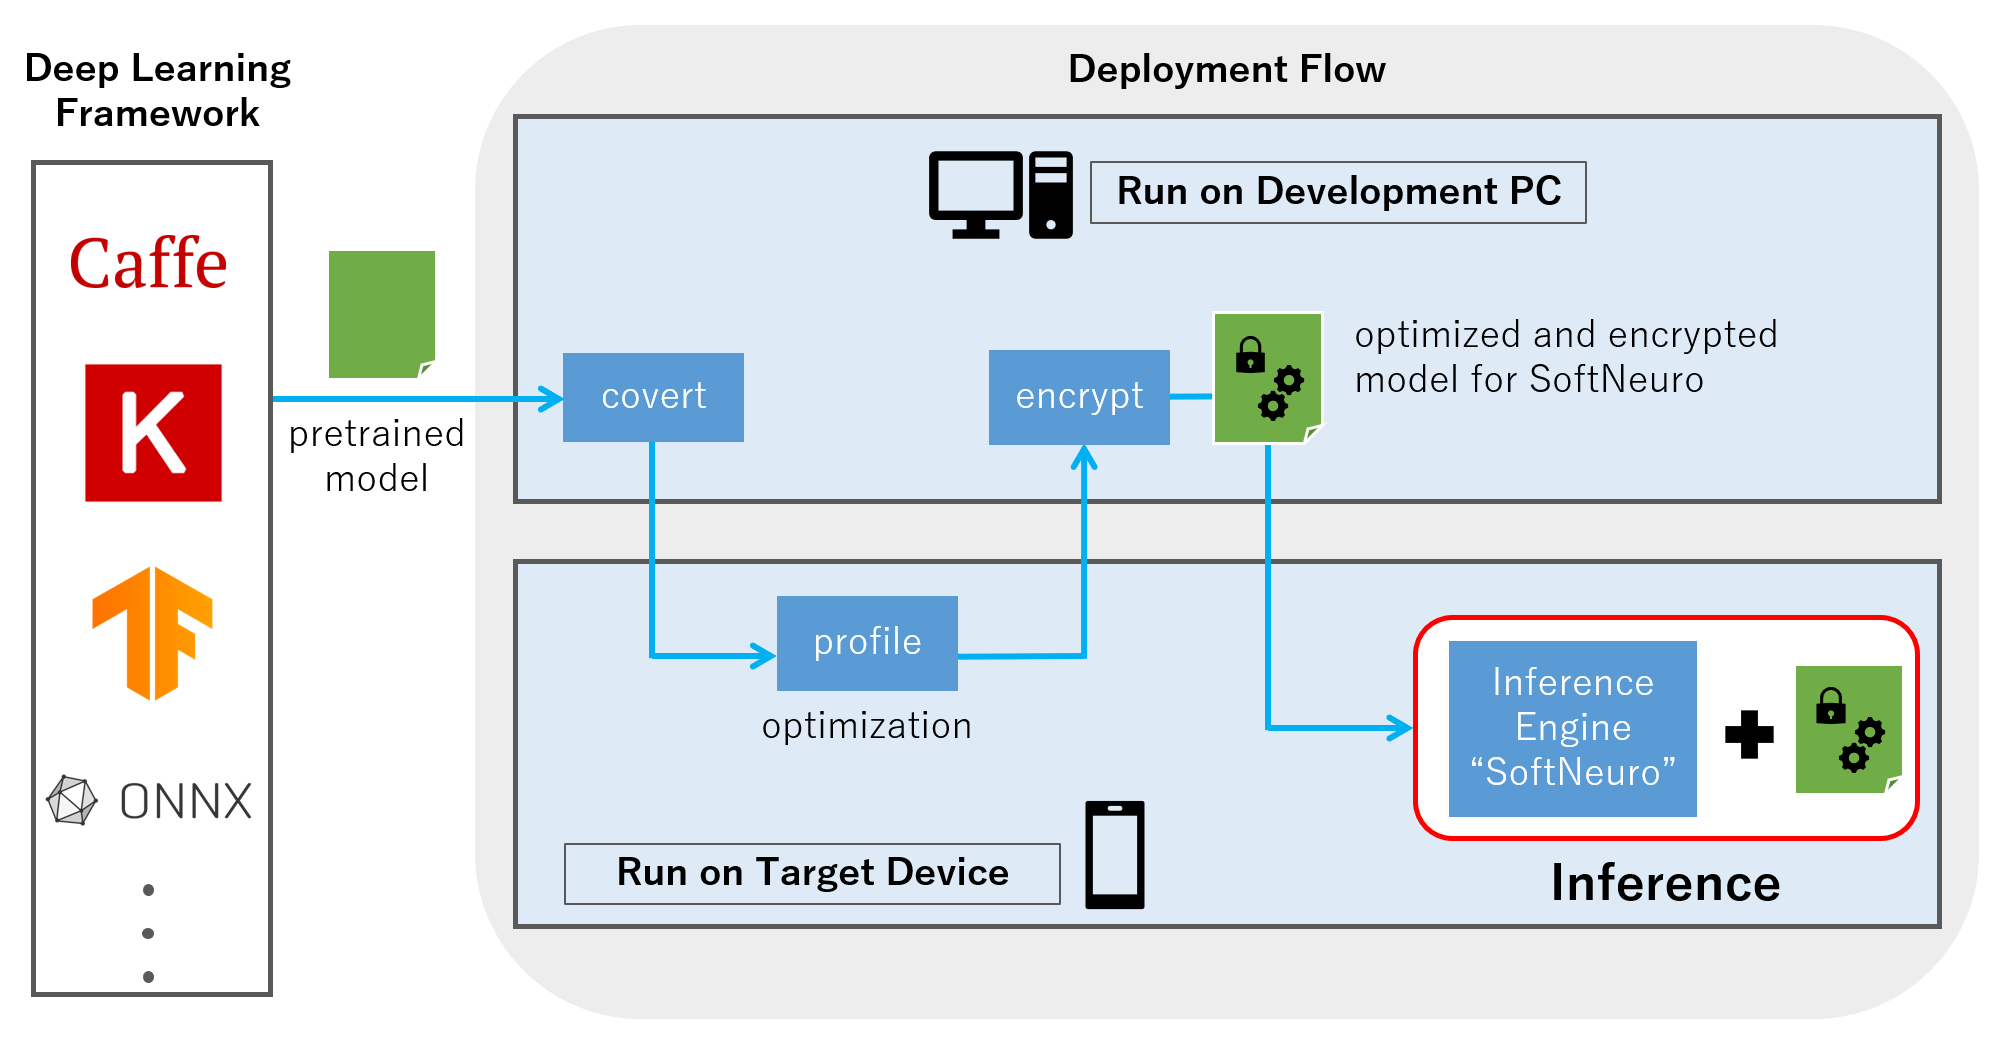
Fast AI Inference Engine | Technology | Morpho, Inc
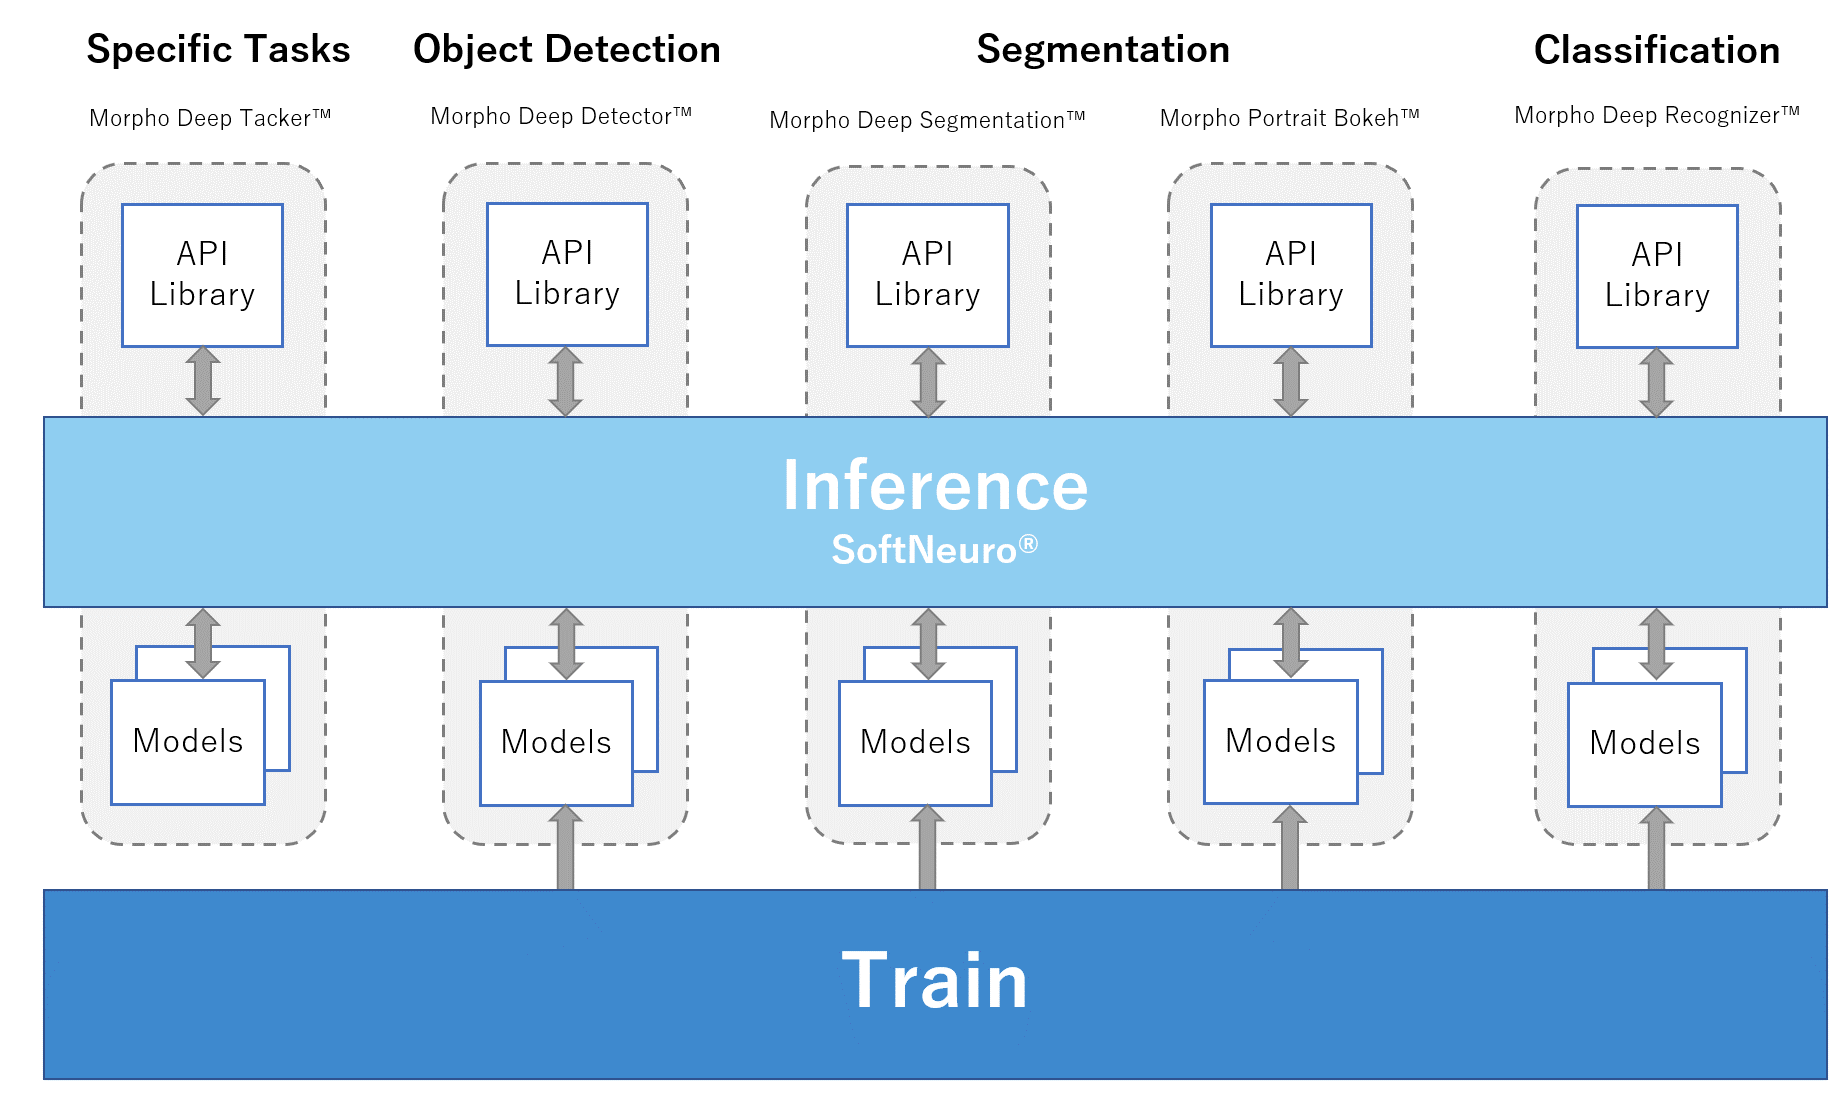
Fast AI Inference Engine | Technology | Morpho, Inc
hipEngine – ROCm-native inference engine for AMD RDNA3 og Strix Halo ...

Inference Engine by GMI Cloud: Fast multimodal-native inference at scale
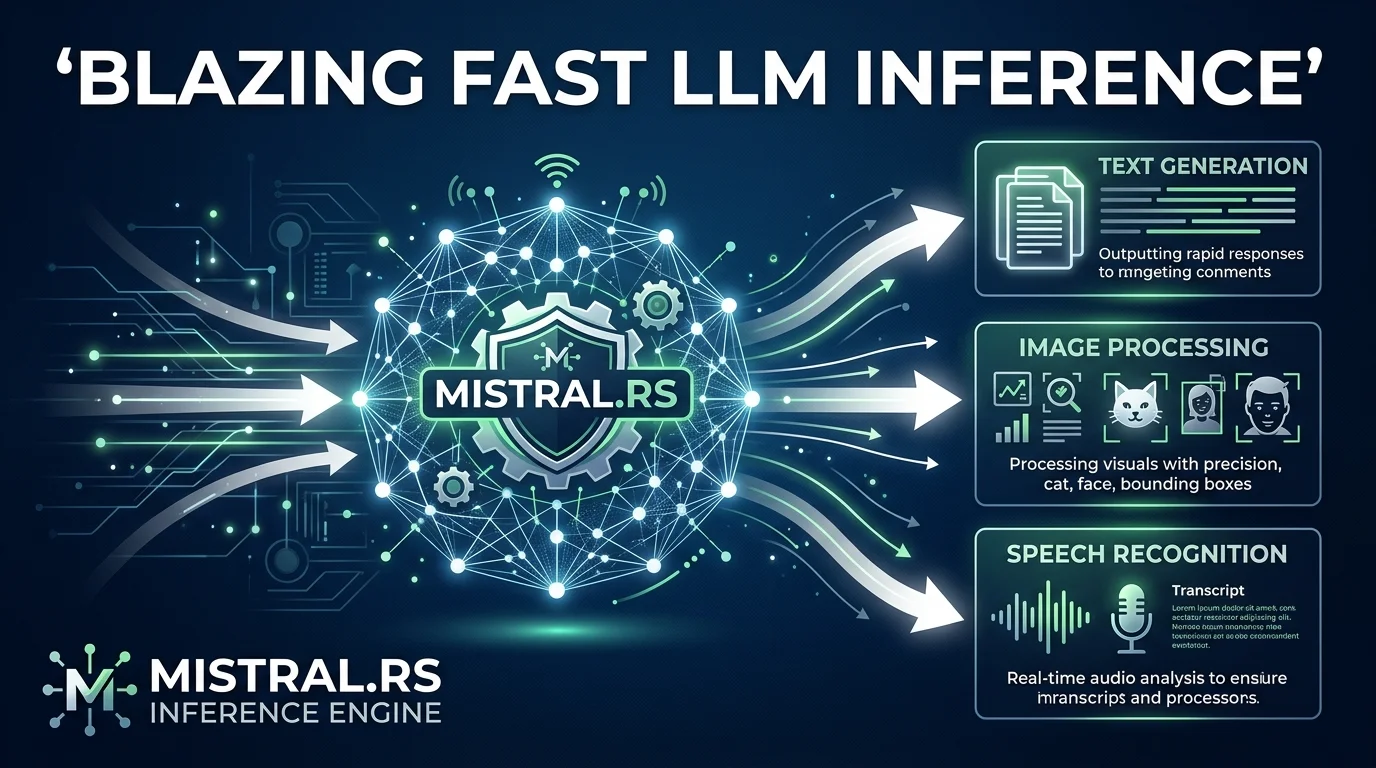
Mistral.rs: Blazingly Fast LLM Inference Engine in Rust...
GitHub - ZhangLabTJU/fastBCR: A heuristic method for fast BCR clonal ...
Advertisement Space (300x250)

GUIDE: A Global Unified Inference Engine for Deploying Large Language ...
DwarfStar 4 is a standalone inference engine built specifically for ...
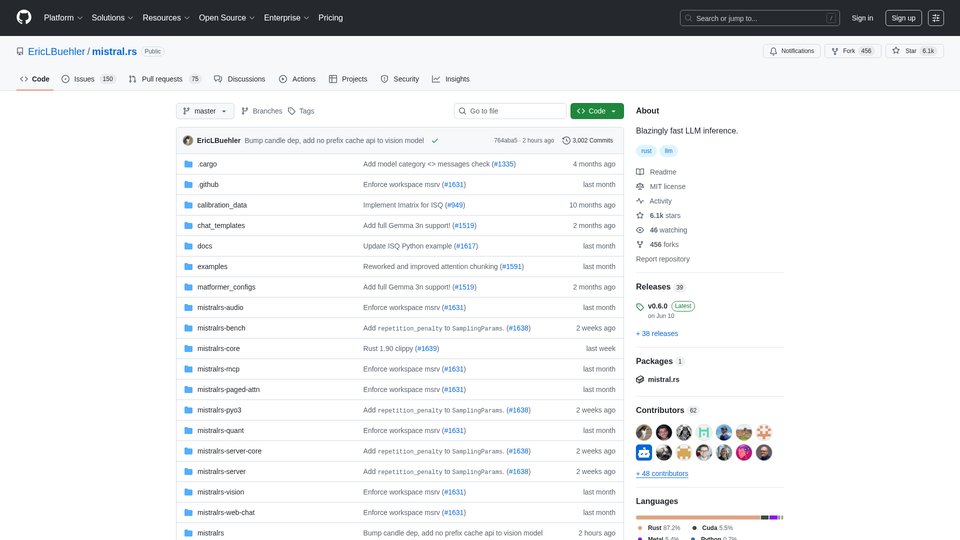
mistral.rs: Blazingly Fast LLM Inference Engine
GitHub - 0danny/Inference-Engine: The Inference Engine is a software ...
GitHub - PAA-NCIC/hipANS: HIP version of dietGPU for the ROCm platform ...
Groq: Fast LPU AI Inference Engine & API

AMD's ROCM_AITER_FA boosts inference engine performance with 3-path ...
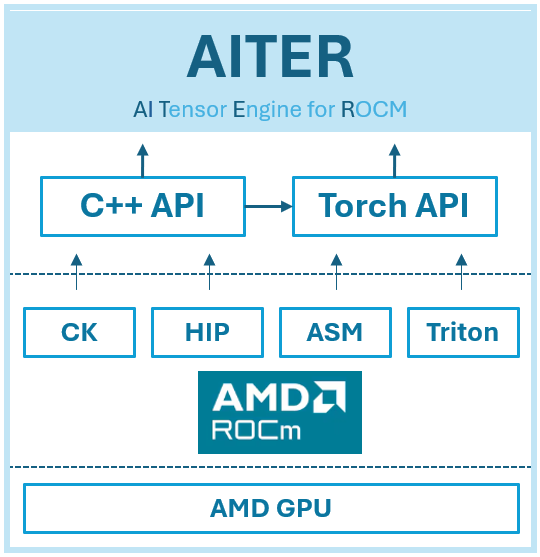
AITER 분석: AMD가 ROCm inference 성능을 2배로 올린 방법 | HyperAccel Tech Blog
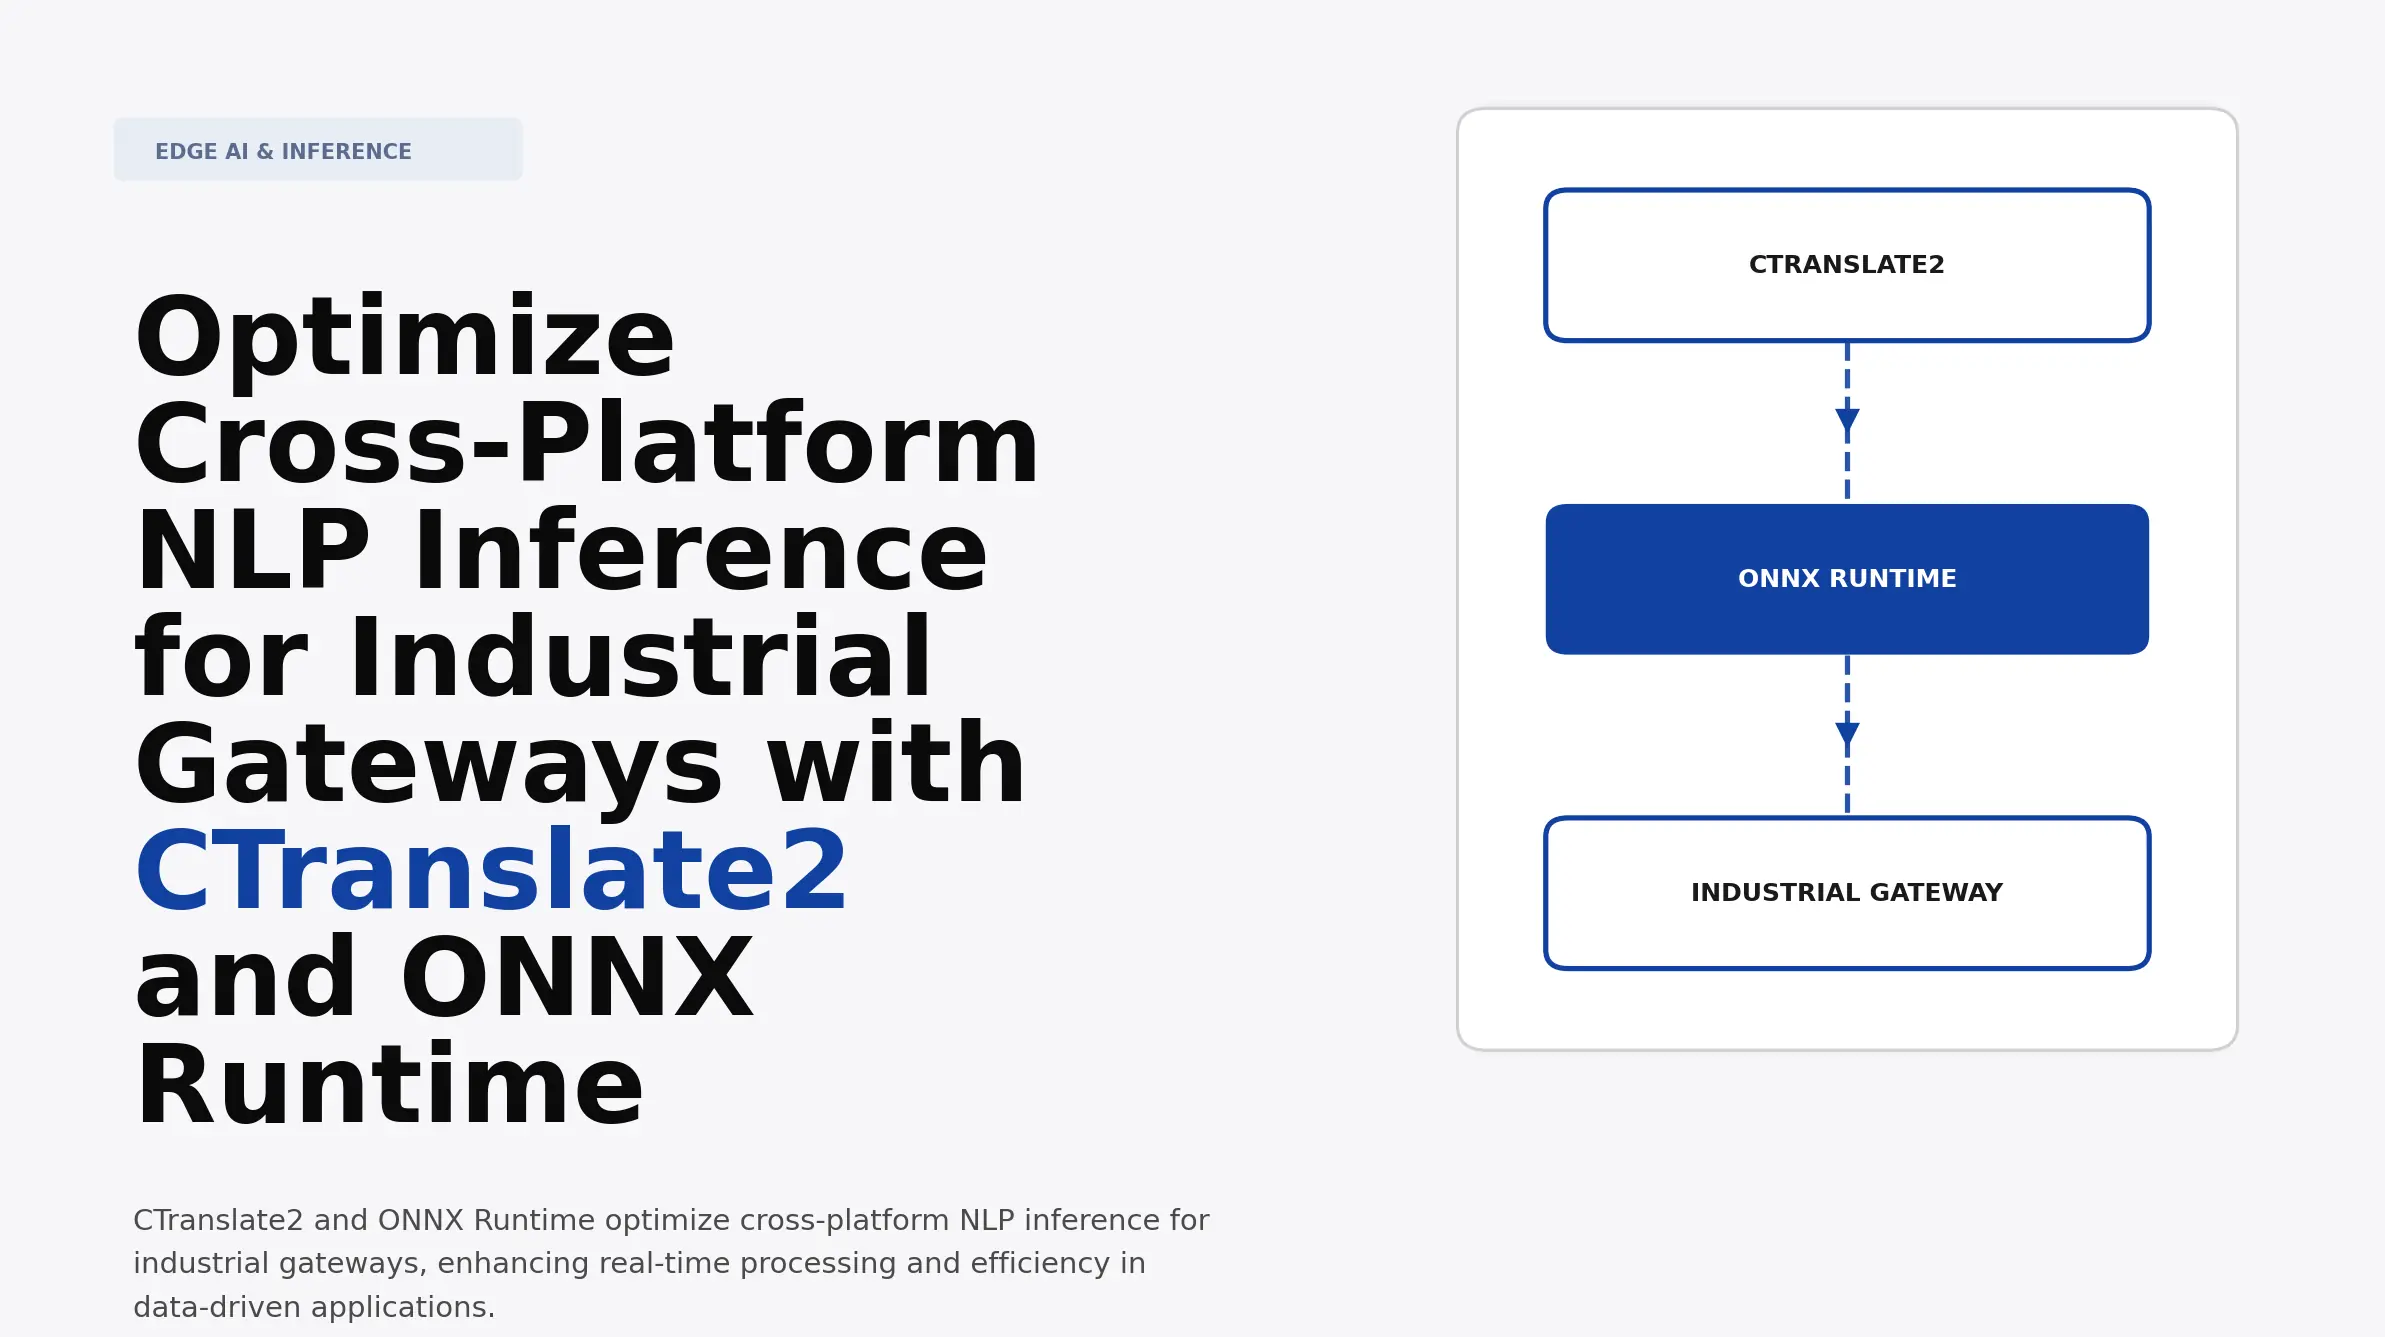
Optimize Cross-Platform NLP Inference for Industrial Gateways with ...
Inference Engine | Kush Singh
Advertisement Space (336x280)
Inference Engine | agentmorris/MegaDetector | DeepWiki
GitHub - kailums/flash-attention-rocm: Fast and memory-efficient exact ...
GitHub - R-SITES/llama-launcher: Web UI for launching llama.cpp ...
Upgrade to ROCm 5.4.1 · Issue #98 · Xilinx/inference-server · GitHub

Inference Compute Engine (ICE) | Download Scientific Diagram

Inference Compute Engine (ICE) | Download Scientific Diagram
Deploying DeepSeek-R1 Inference Service with SGLang ROCm at Only 2000 ...
Inference Engine Showdown: vLLM ROCm, TurboQuant, LLaMA.cpp · Technical ...
Free Video: How Fast Are LLM Inference Engines Anyway? from AI Engineer ...
GitHub - iGavroche/ROCm-ComfyUI-ReActor: Fast and Simple Face Swap ...
Advertisement Space (336x280)
Howto perform fast inference (realtime) · Issue #15 · MarvinTeichmann ...
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
[Documentation]: Need fny information for explain how work with ROCm ...
Inference Engine and Optimization | ai-dynamo/aiconfigurator | DeepWiki

GitHub - kailums/flash-attention-rocm: Fast and memory-efficient exact ...

GitHub - Ramy-osama/Hardware-FasterRCNN: This is the implementation for ...