
Github Mkaloertfservingcache Distributed Model Cache For Tf Serving
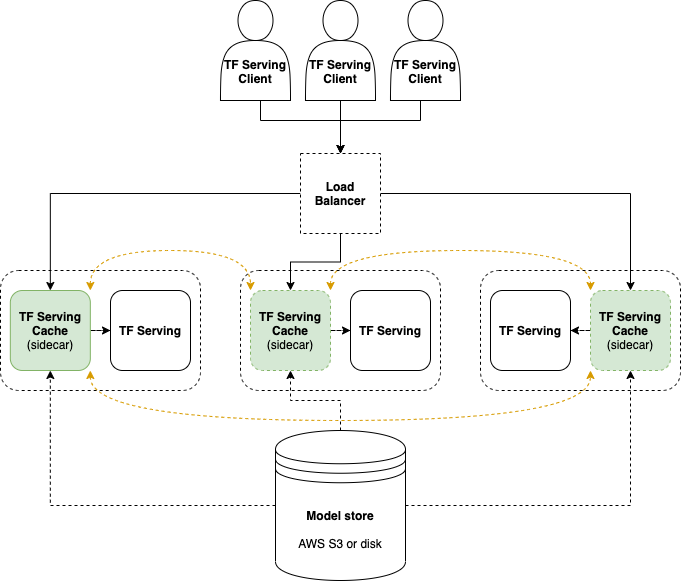
GitHub - mKaloer/TFServingCache: Distributed model cache for TF Serving
GitHub - kserve/modelmesh: Distributed Model Serving Framework · GitHub
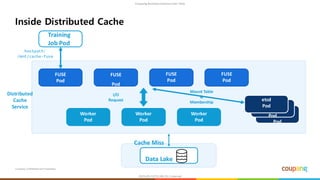
How Coupang Leverages Distributed Cache to Accelerate ML Model Training ...
GitHub - google-aai/tf-serving-k8s-tutorial: A Tutorial for Serving ...
TF DF model serving with TF Serving docker · Issue #27 · tensorflow ...
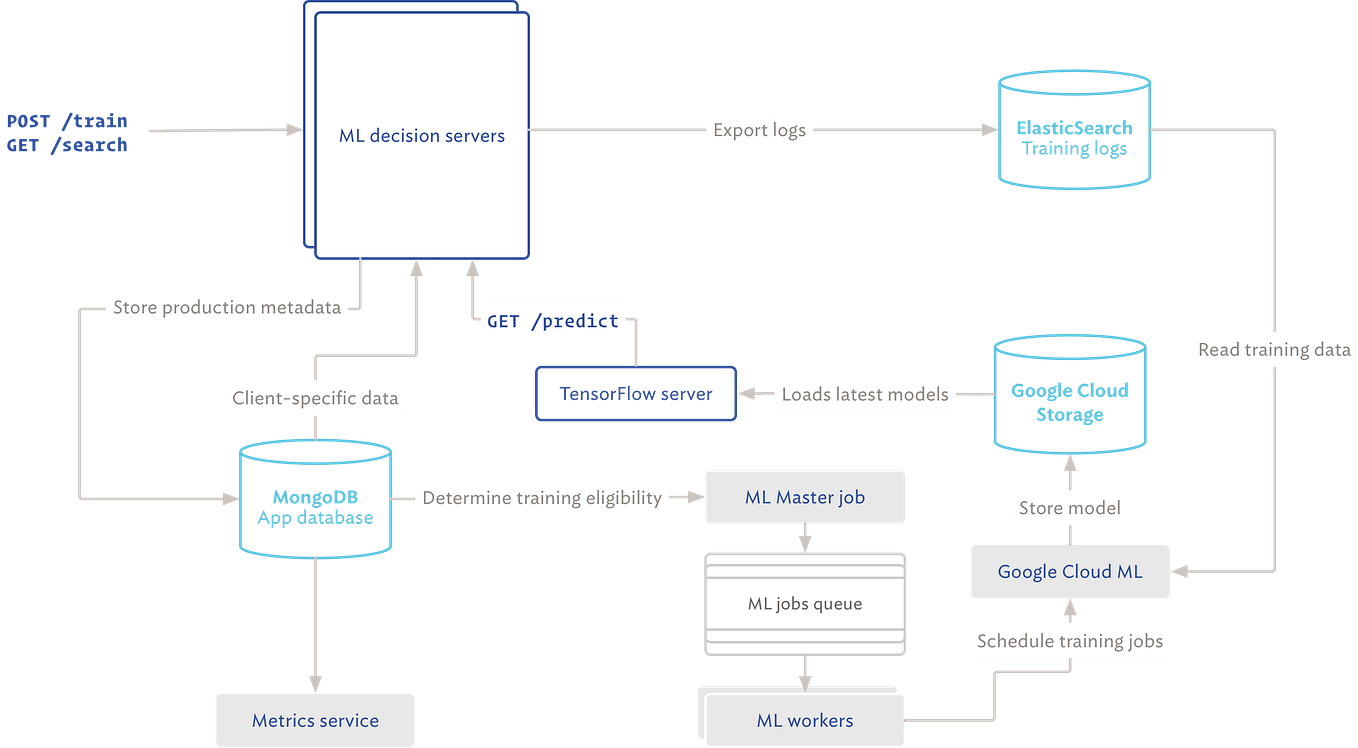
Taming Tensorflow Serving with Kubernetes for Dynamic Model Deployment ...
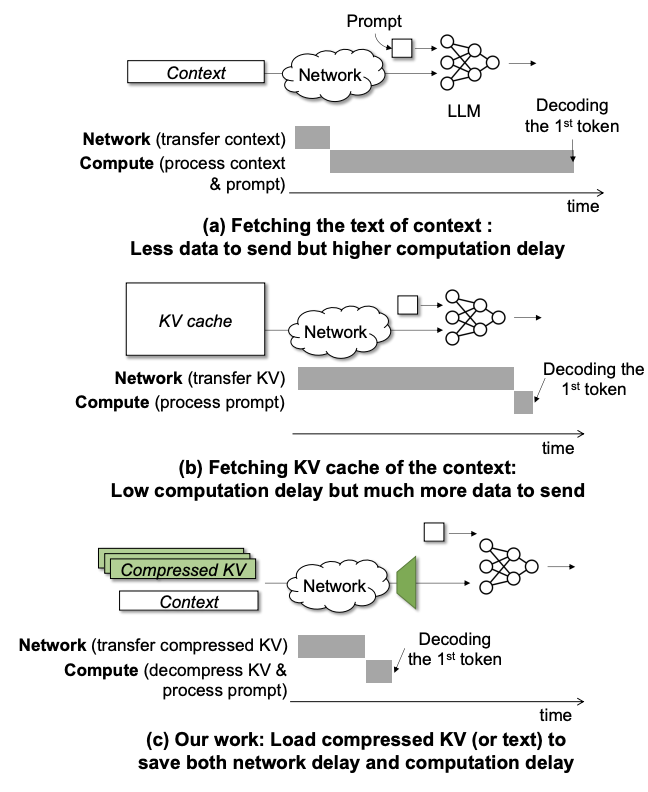
CacheGen: KV Cache Compression and Streaming for Fast Language Model ...
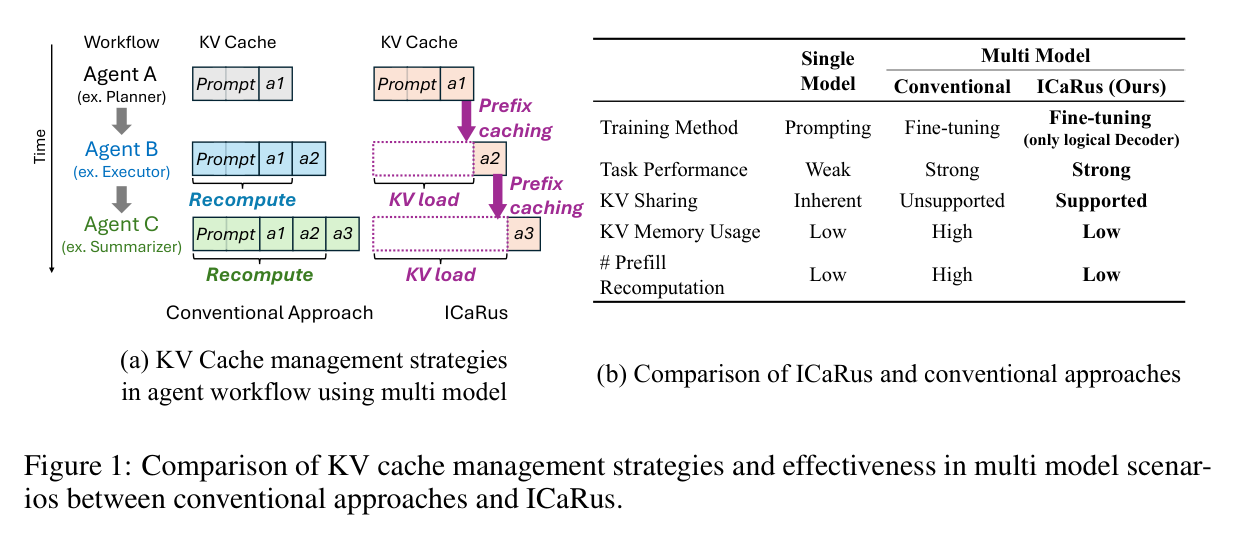
ICaRus: Identical Cache Reuse across Models for Multi-Model LLM Serving ...
Orca: A Distributed Serving System for Transformer-Based Generative ...

Autoscaling TensorFlow Model Deployments with TF Serving and Kubernetes
Advertisement Space (300x250)
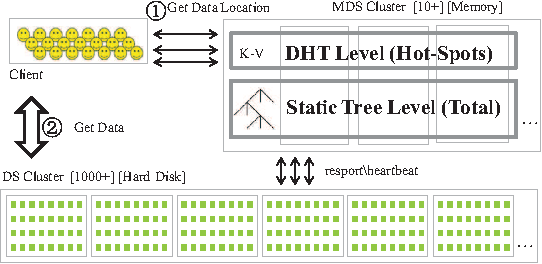
Figure 1 from A Distributed Cache Framework for Metadata Service of ...
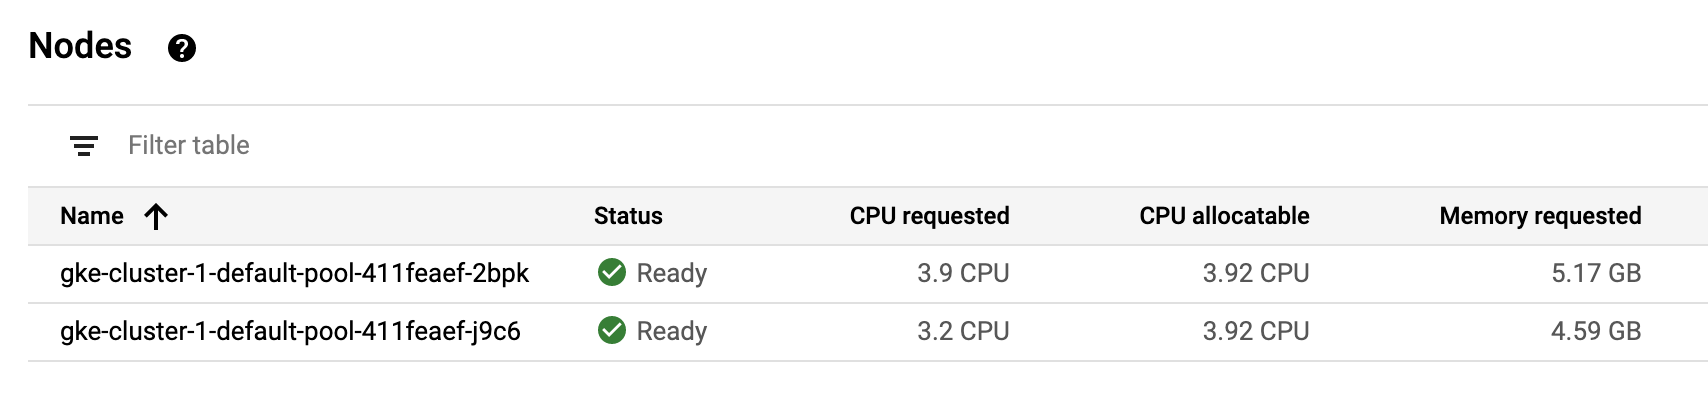
Autoscaling TensorFlow Model Deployments with TF Serving and Kubernetes ...
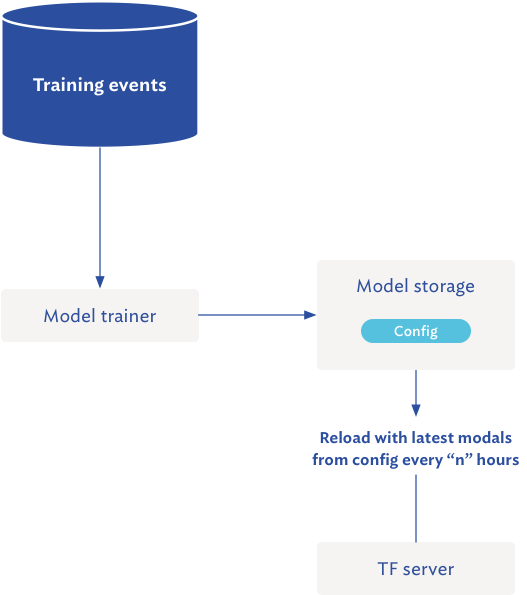
Taming Tensorflow Serving with Kubernetes for Dynamic Model Deployment ...

Adaptive KV Cache Reuse for Fast Long-Context LLM Serving

PRESERVE: Prefetching Model Weights and KV-Cache in Distributed LLM Serving
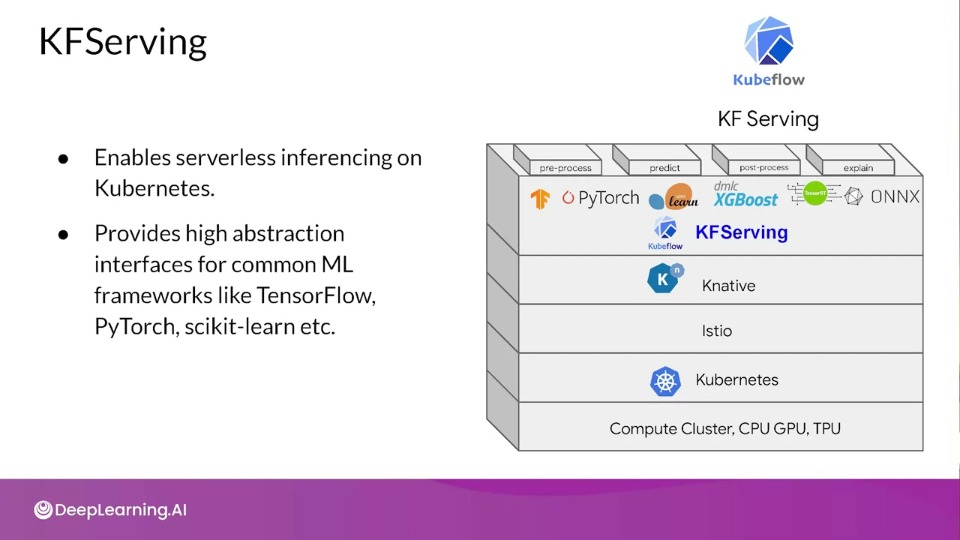
Week 2 — Model Serving Architecture, Scaling Infrastructure and More ...
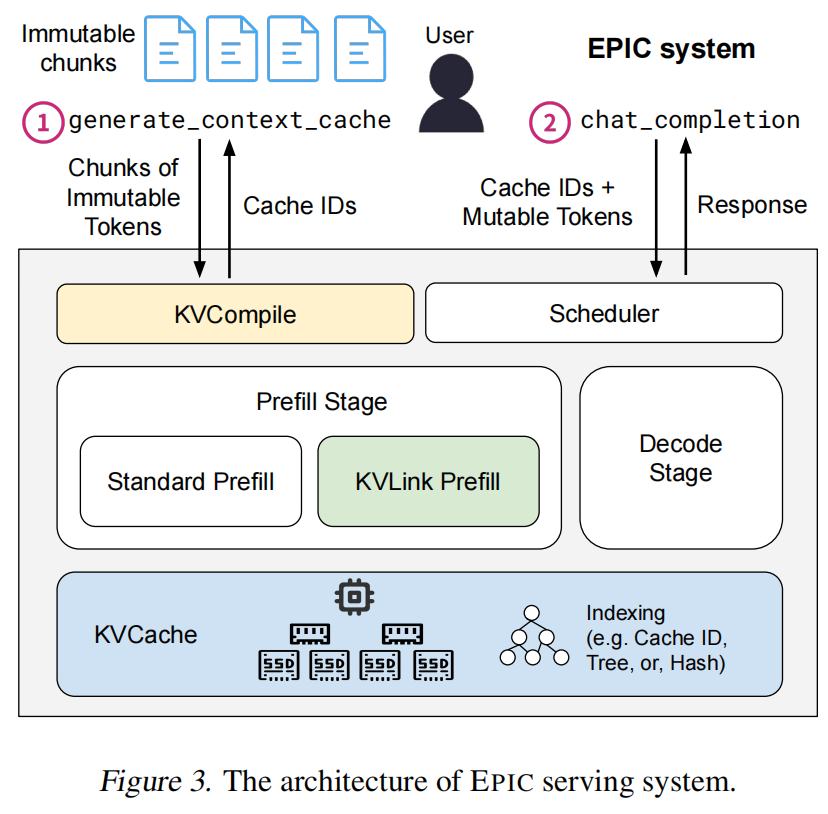
📝 EPIC: Efficient Position-Independent Caching for Serving Large ...
GitHub - holomodular/ServiceBricks-Cache: ServiceBricks Cache ...
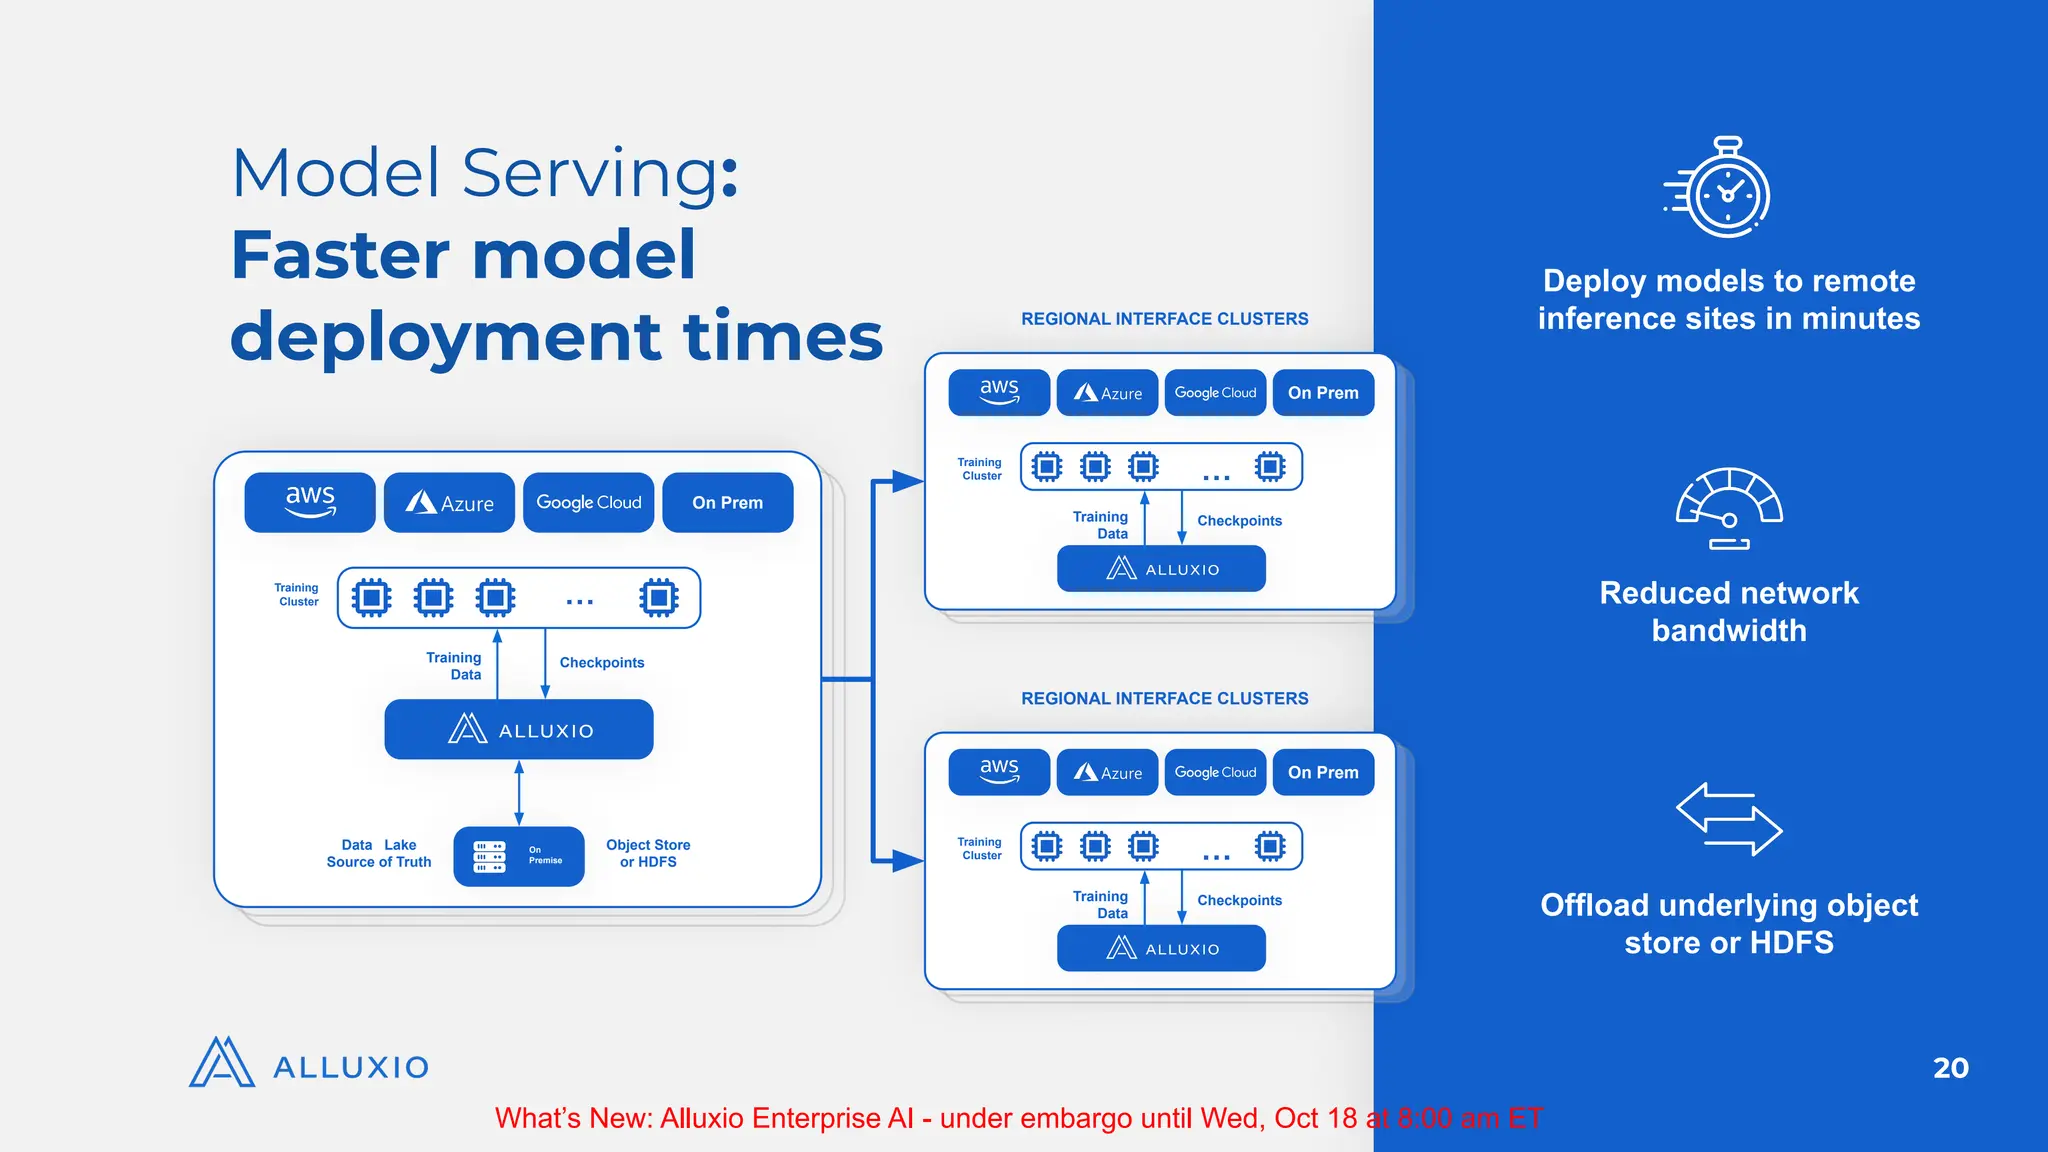
AI Infra Day | Accelerate Your Model Training and Serving with ...
SOSP 25 | IC-Cache: Efficient Large Language Model Serving via In ...
Advertisement Space (336x280)

DualMap: Enabling Both Cache Affinity and Load Balancing for ...

GitHub - filip-halt/gptcache: ⚡ GPT Cache is a powerful caching library ...
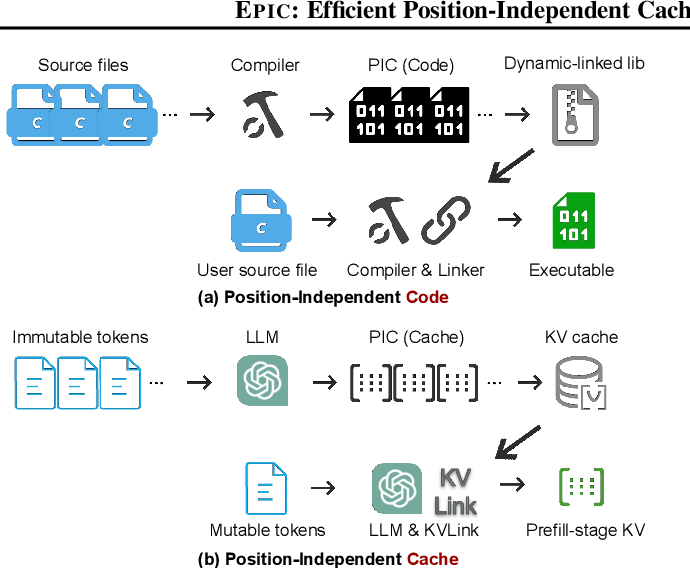
Figure 2 from EPIC: Efficient Position-Independent Caching for Serving ...
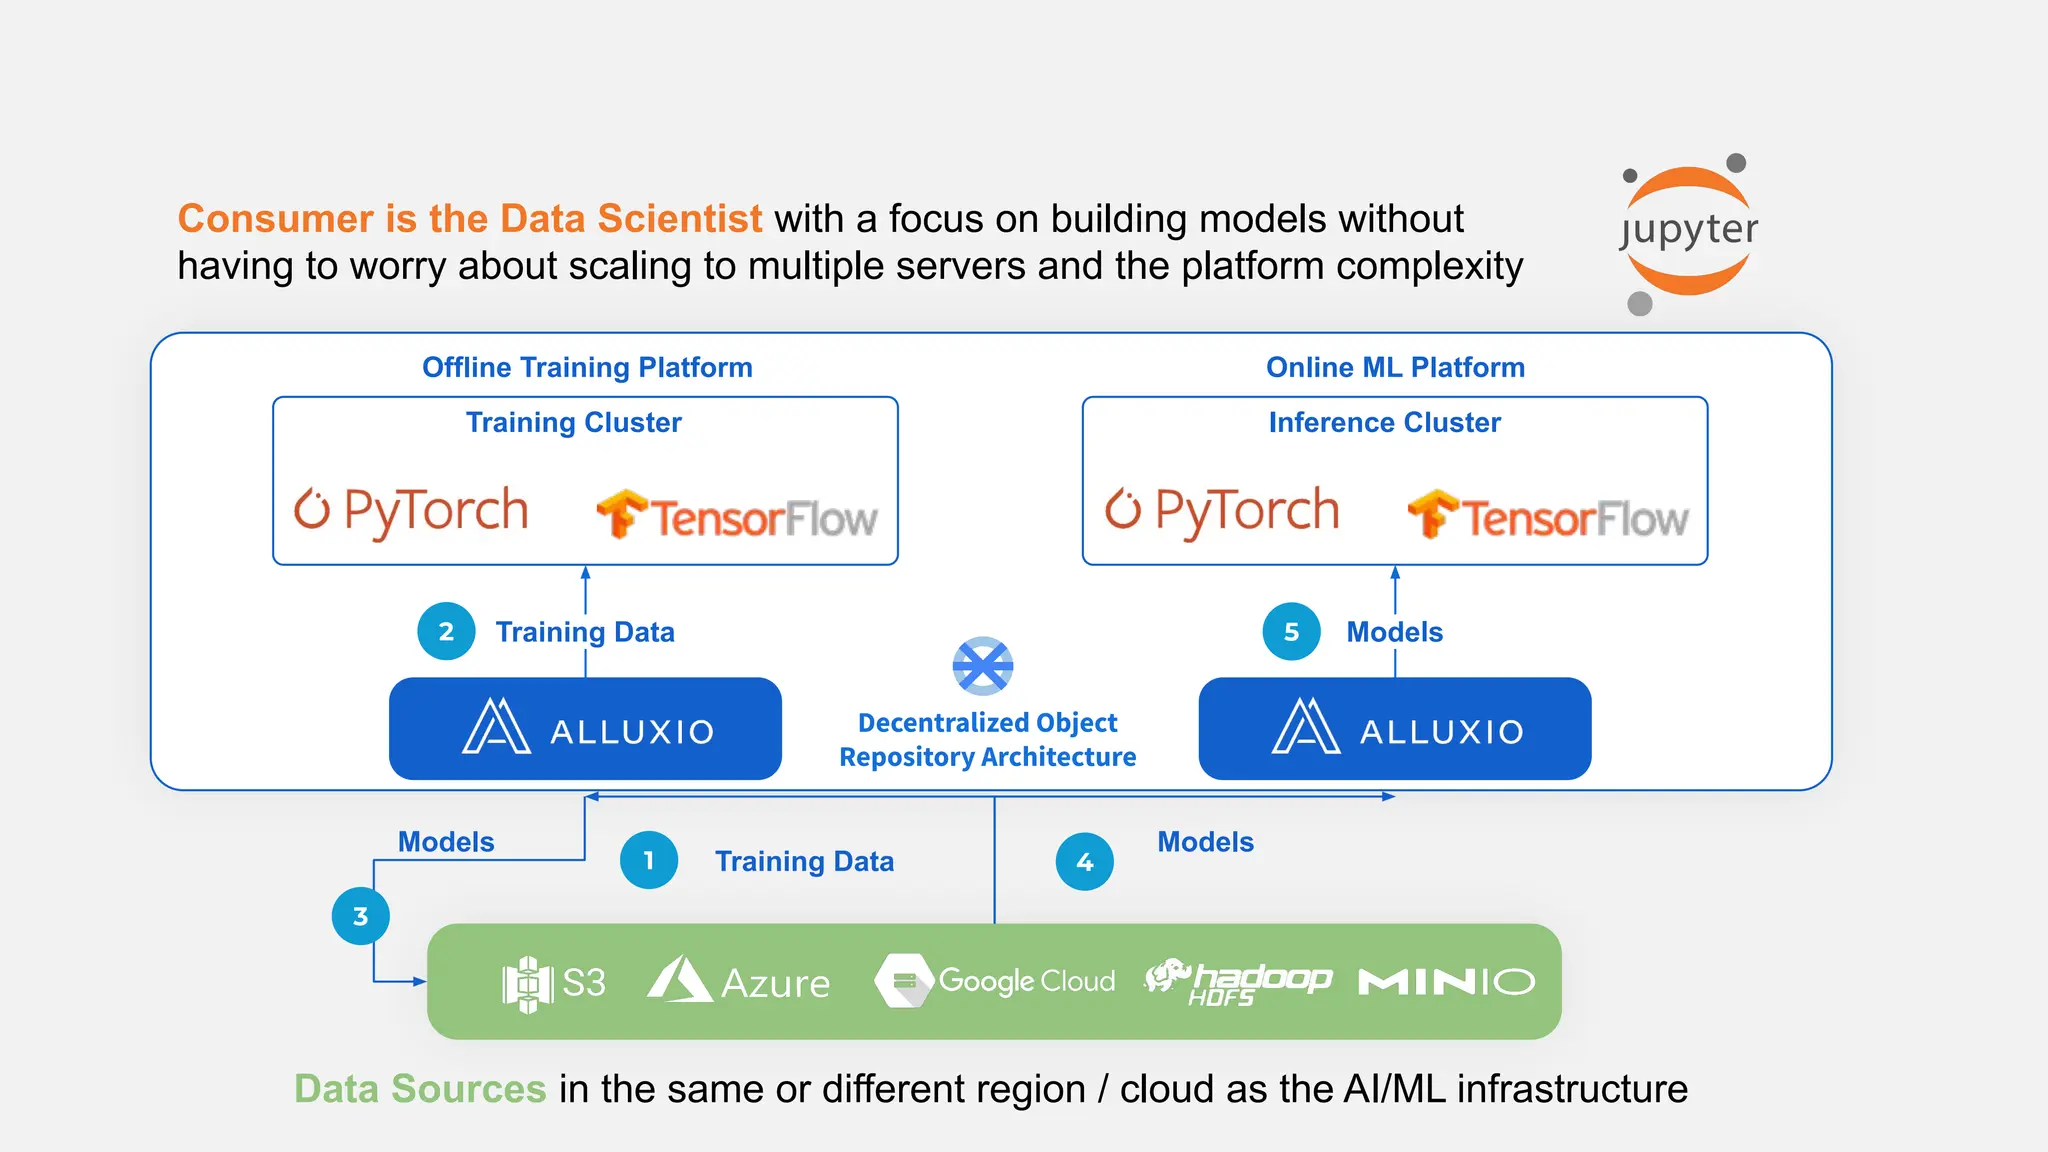
AI Infra Day | Accelerate Your Model Training and Serving with ...
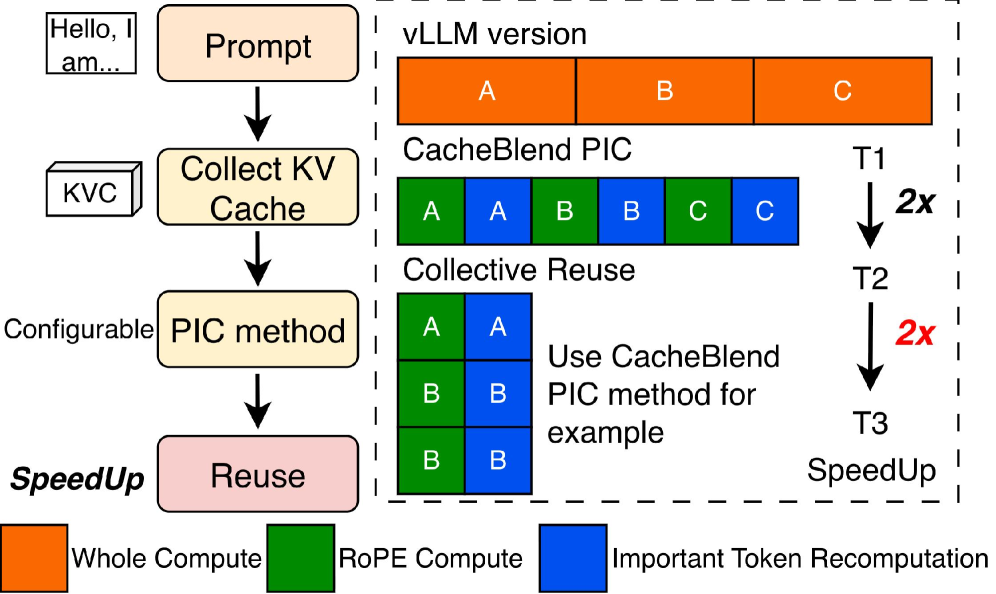
TokenDance: Scaling Multi-Agent LLM Serving via Collective KV Cache ...
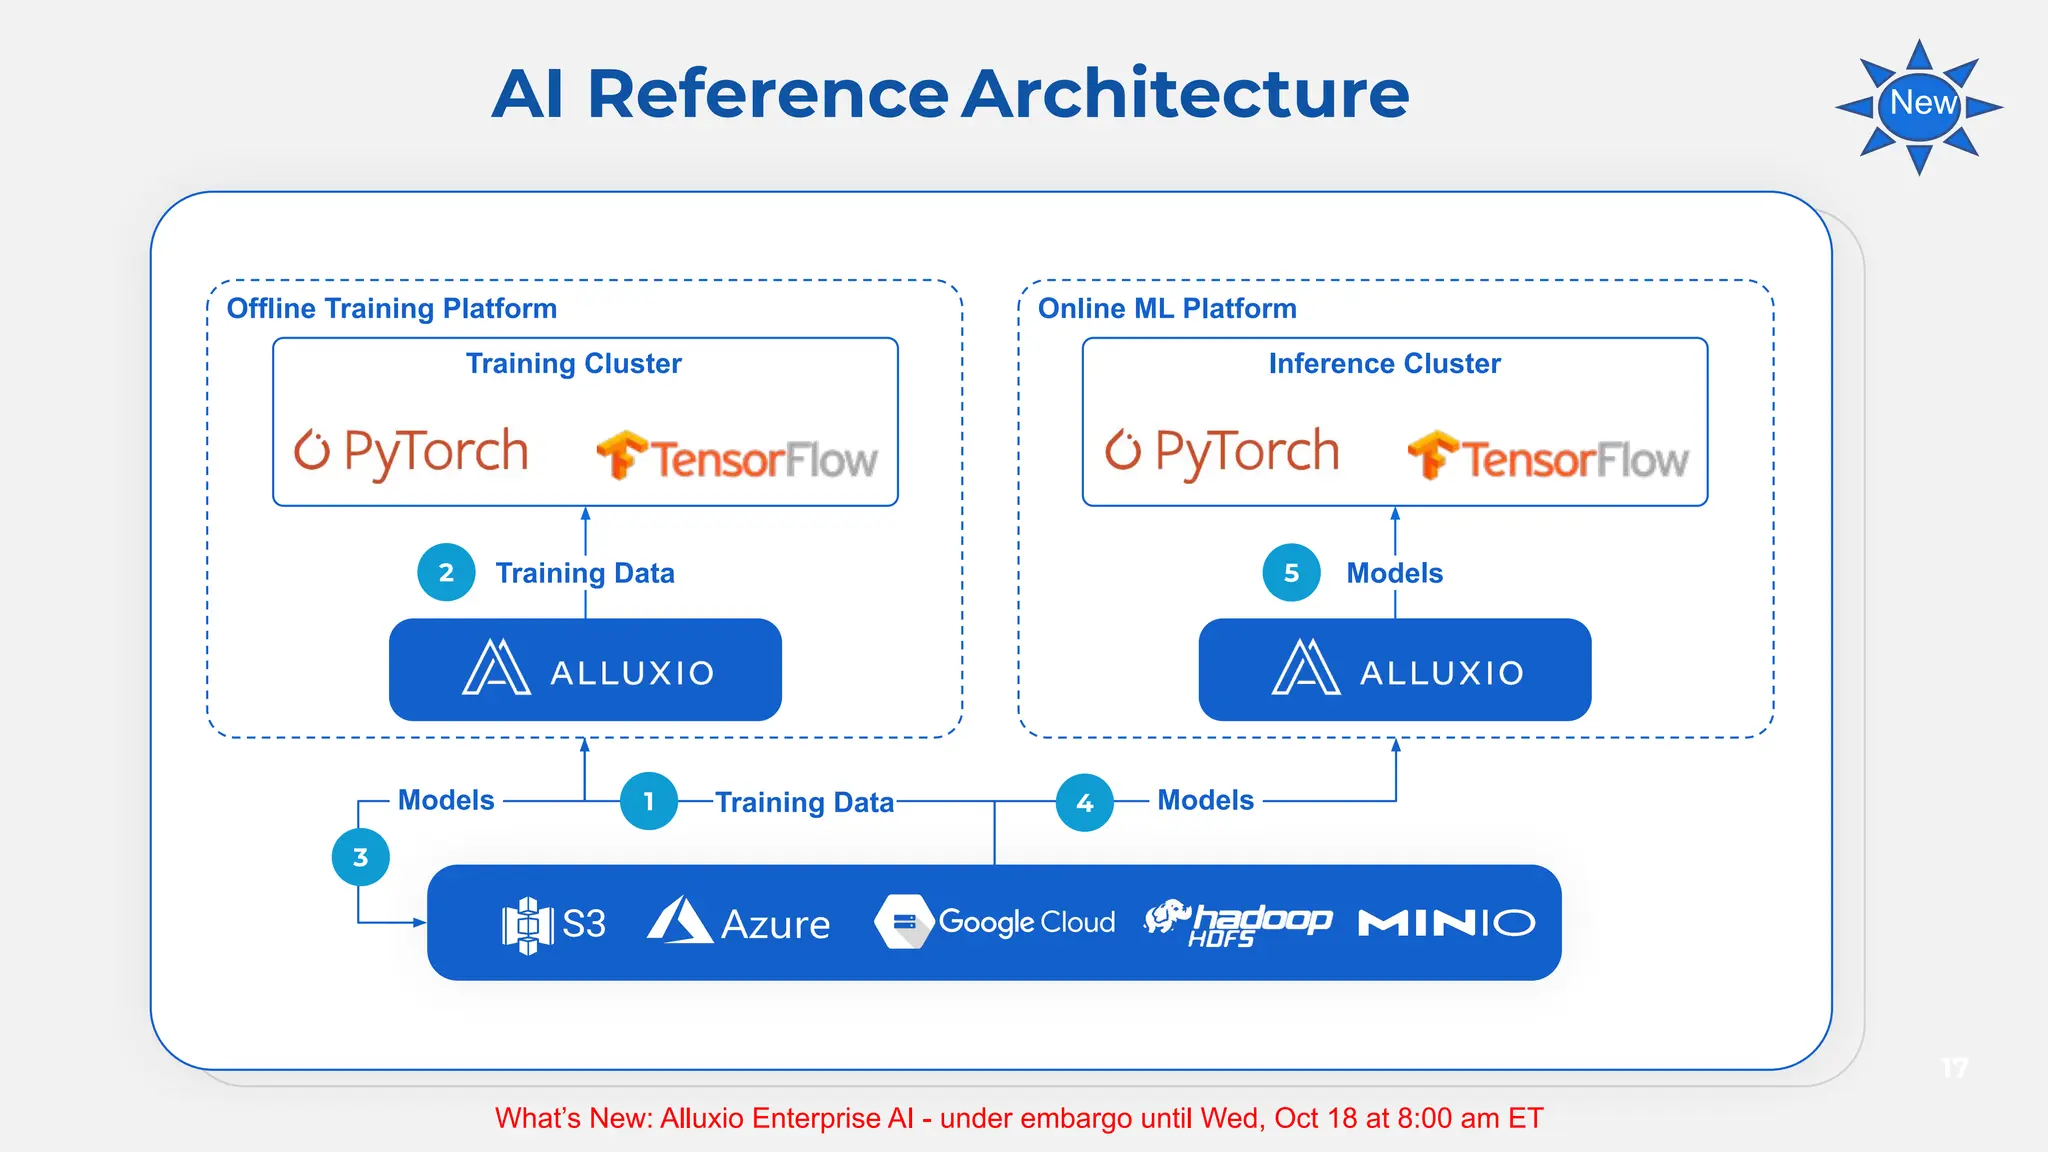
AI Infra Day | Accelerate Your Model Training and Serving with ...

Model Saved with TF-2.5.0 · Issue #576 · yahoo/TensorFlowOnSpark · GitHub
tf transform's "exported model" use in tf serving issue · Issue #76 ...
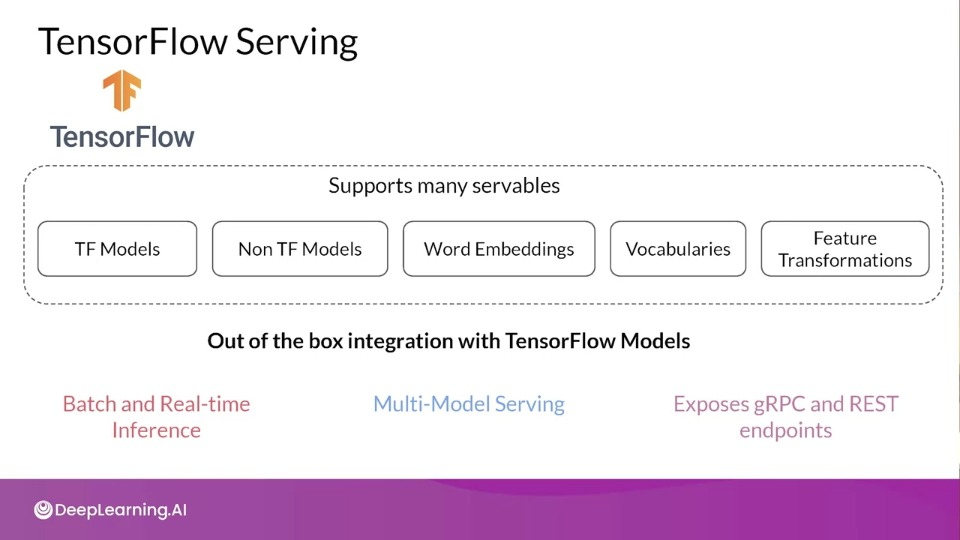
Week 2 — Model Serving Architecture, Scaling Infrastructure and More ...
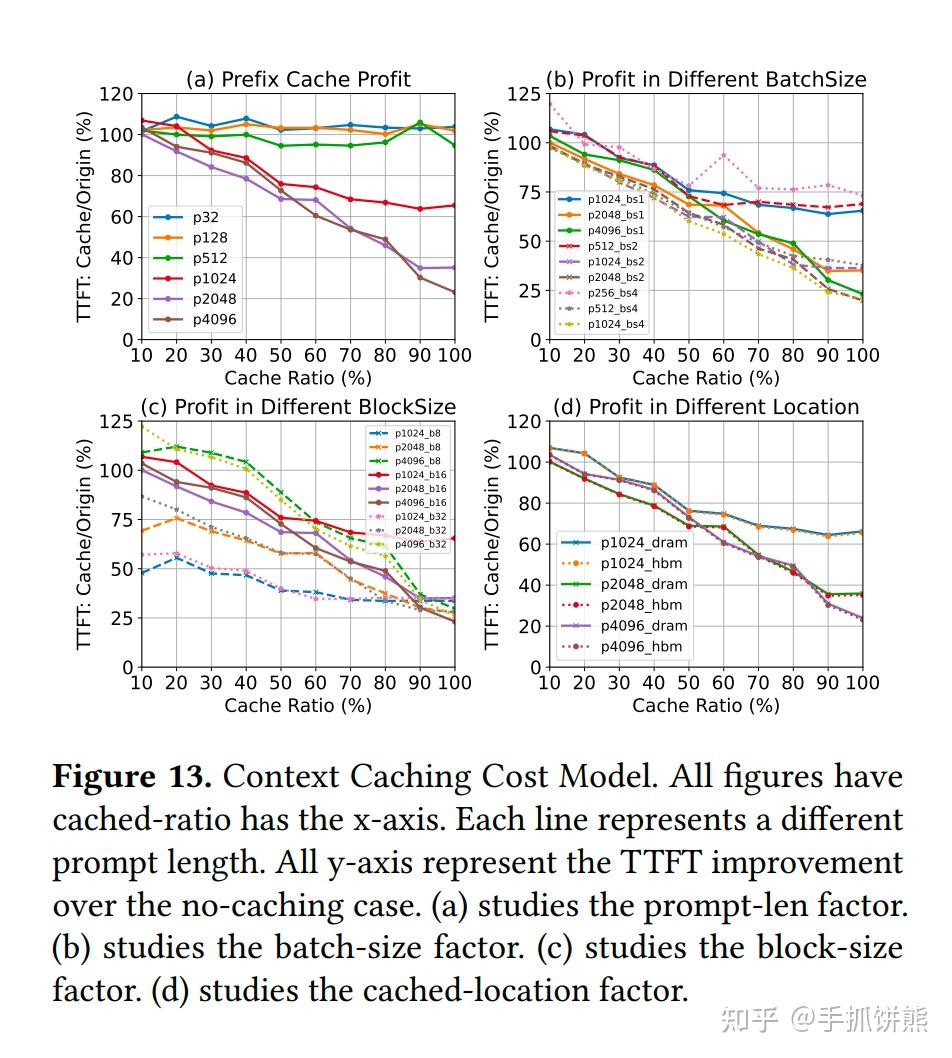
MemServe: Context Caching for Disaggregated LLM Serving with Elastic ...
Advertisement Space (336x280)
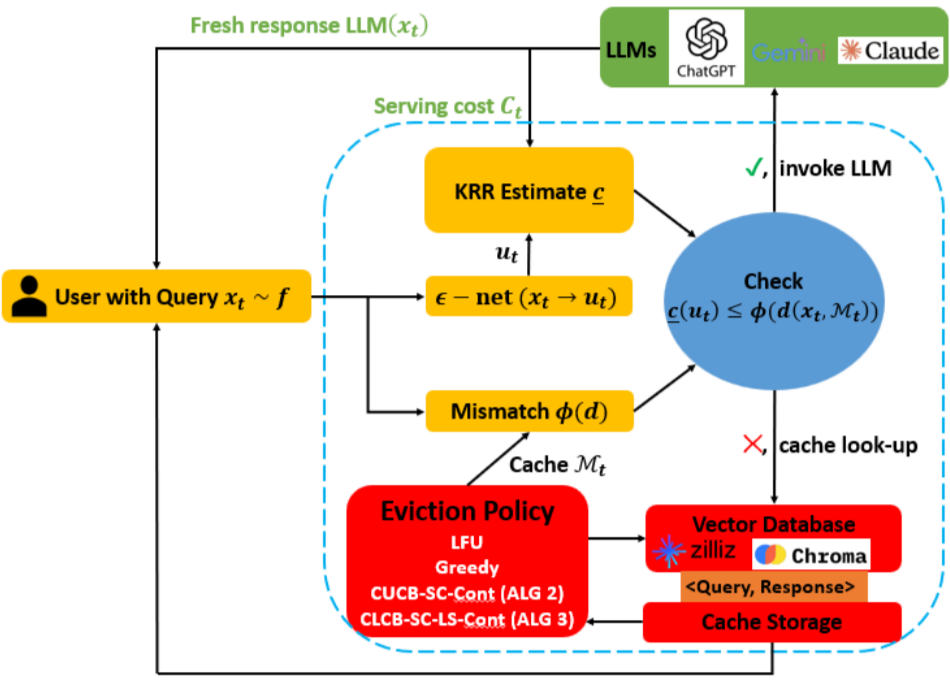
[논문 리뷰] Continuous Semantic Caching for Low-Cost LLM Serving

TokenDance: Scaling Multi-Agent LLM Serving via Collective KV Cache Sharing
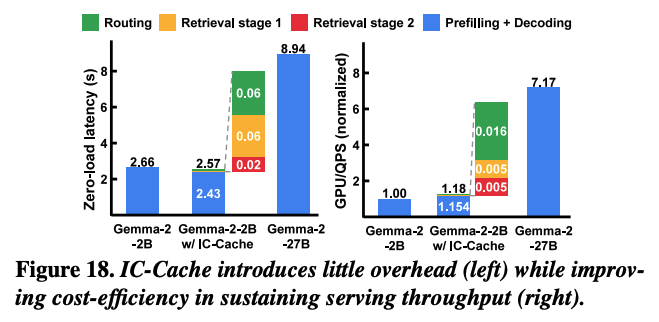
[SOPS'25] IC-Cache: Efficient Large Language Model Serving via In ...
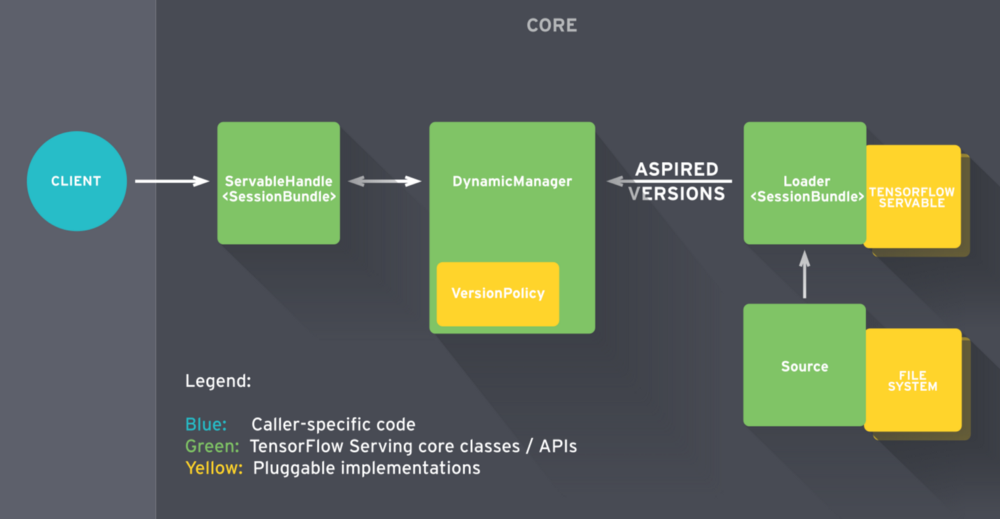
How to deploy TensorFlow models to production using TF Serving ...
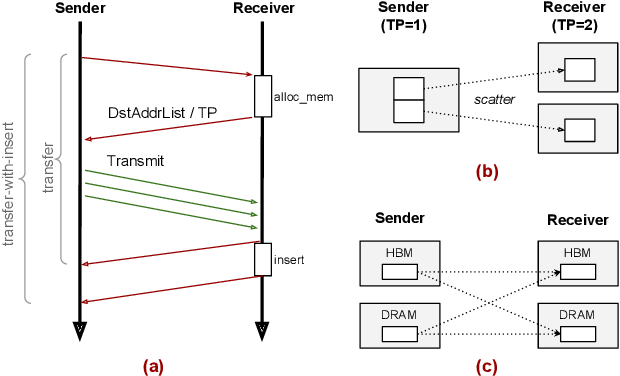
Figure 2 from MemServe: Context Caching for Disaggregated LLM Serving ...
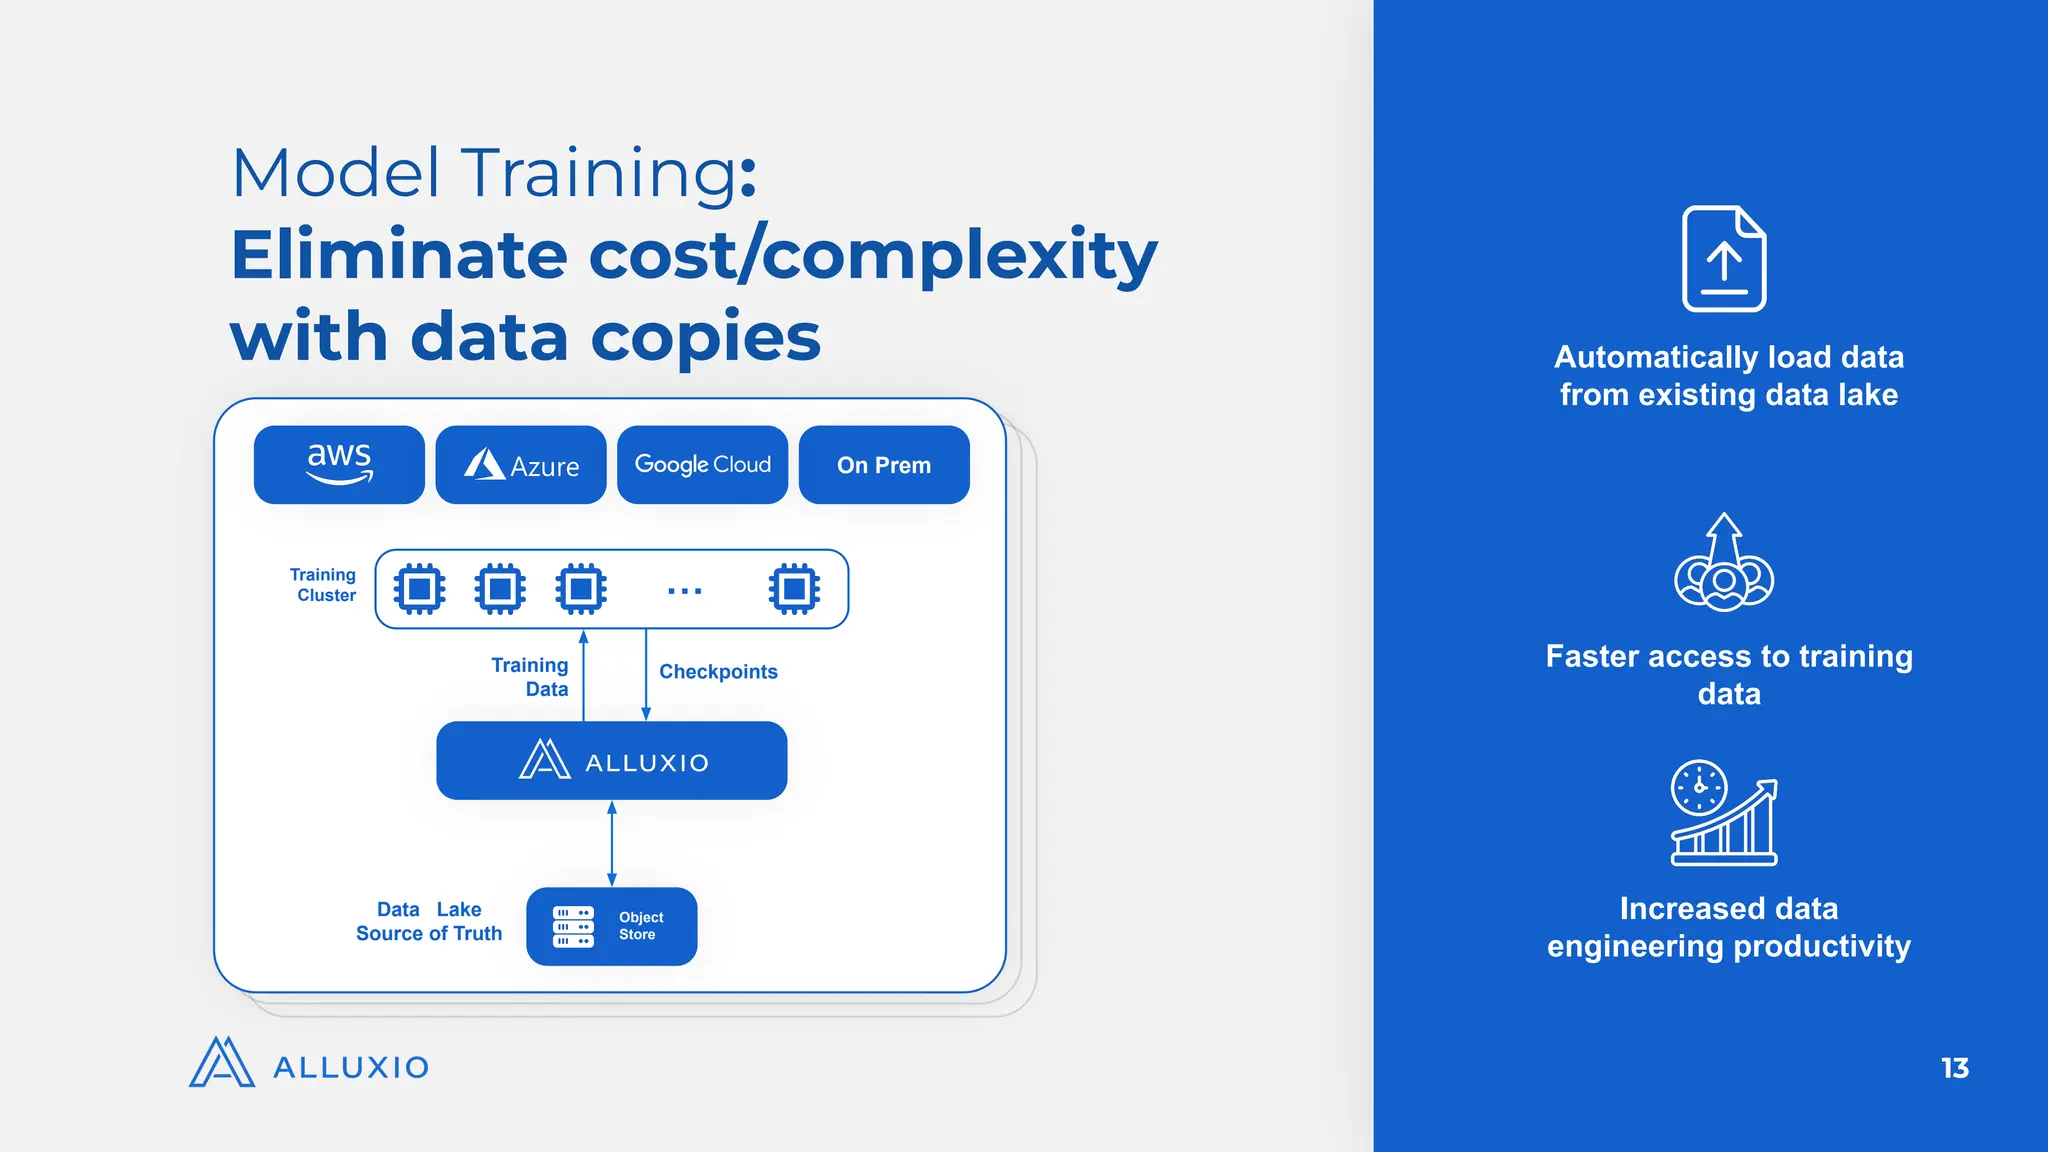
AI Infra Day | Accelerate Your Model Training and Serving with ...