
Github Nobelksemantic Cache Distributed Semantic Cache For Llm
GitHub - nobelk/semantic-cache: Distributed Semantic Cache for LLM ...

Design a Semantic Cache for LLM Applications - The HLD Handbook
GPTCache — Semantic Cache for LLM Queries | Open Awesome
GitHub - zilliztech/GPTCache: Semantic cache for LLMs. Fully integrated ...
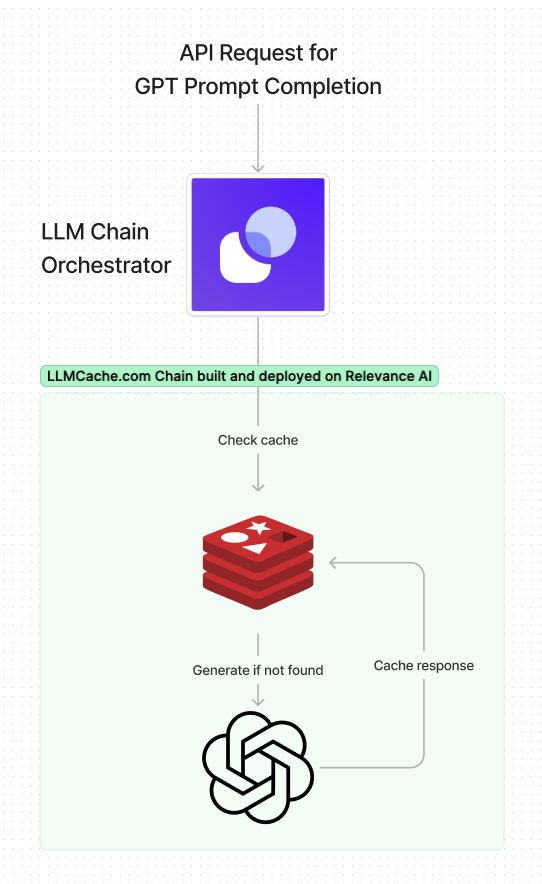
Gptcache : A Library For Creating Semantic Cache For Llm Queries – SRDT

Distributed Semantic Cache Coordination for Retrieval-Augmented ...
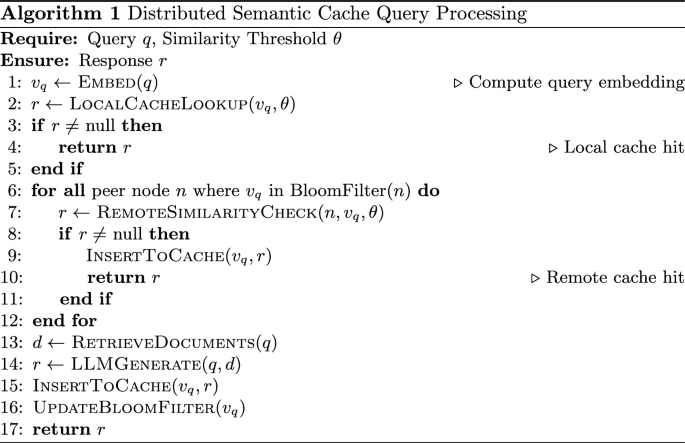
Distributed Semantic Cache Coordination for Retrieval-Augmented ...

What we learned building a Semantic Cache for LLMs
LLM Caching Strategies 2026: Prompt Cache, KV Cache, Semantic Cache ...
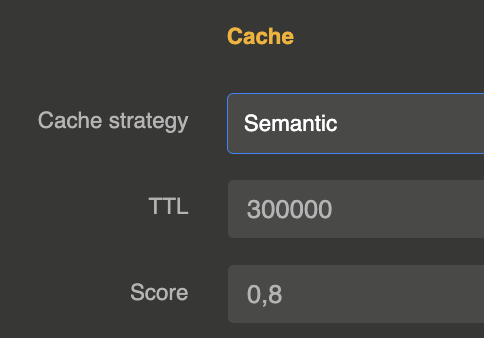
Semantic cache | Otoroshi LLM Extension
Advertisement Space (300x250)
GitHub - shivendrasoni/vector-cache: A simple semantic cache ...
GitHub - llm-d/llm-d-kv-cache: Distributed KV cache scheduling ...
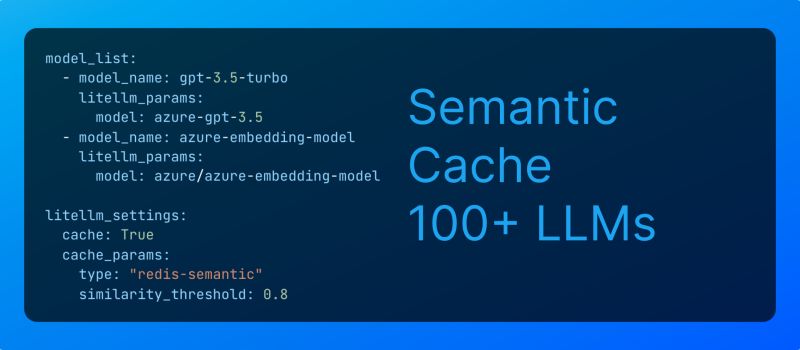
💰LiteLLM v1.22.10 - Save costs, semantic cache 100+ LLM responses 👉 get ...

Improve LLM Performance Using Semantic Cache with Cosmos DB ...

Semantic Cache Explained: A Simple Way to Optimize LLM Applications
GitHub - Jamalianpour/semantic-llm-cache: Semantic caching for LLM API ...

Improve LLM Performance Using Semantic Cache with Cosmos DB ...
GitHub - devanmolsharma/cachelm: A semantic caching layer for LLM apps ...

Semantic Cache คืออะไร? กลไกและวิธีลดค่าใช้จ่าย LLM ด้วย AI Gateway ...

GPTCache - Semantic Cache for LLM: Save Costs, Boost Speed - Aitoolnet
Advertisement Space (336x280)
Semantic Cache Collision Hijack | LLM Security Database
GitHub - Weilun-Hub/llm-d-kv-cache-manager: Distributed KV cache ...
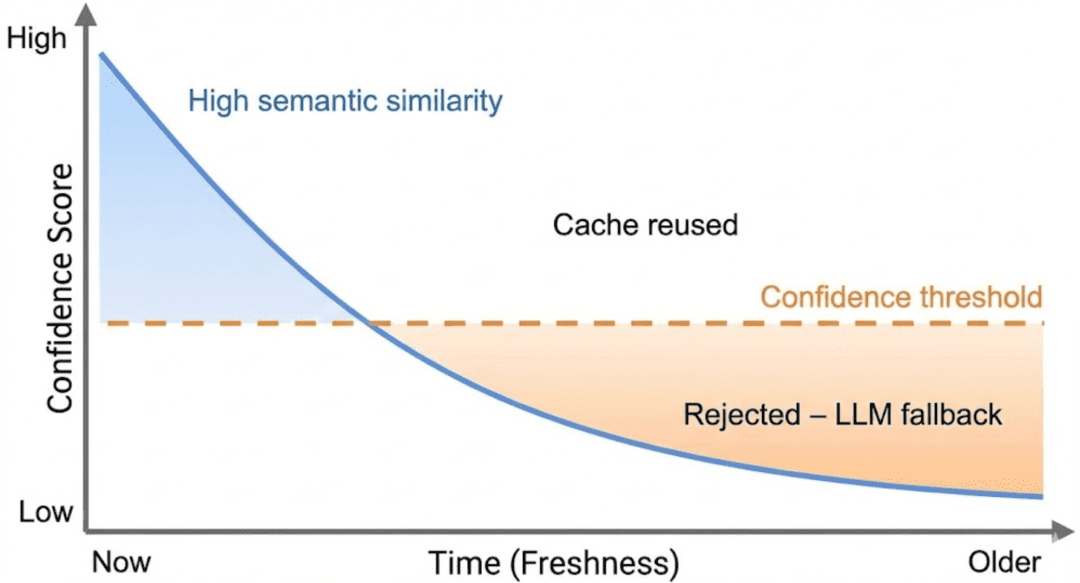
Semantic Caching for LLMs: TTLs, Confidence, and Cache Safety ...
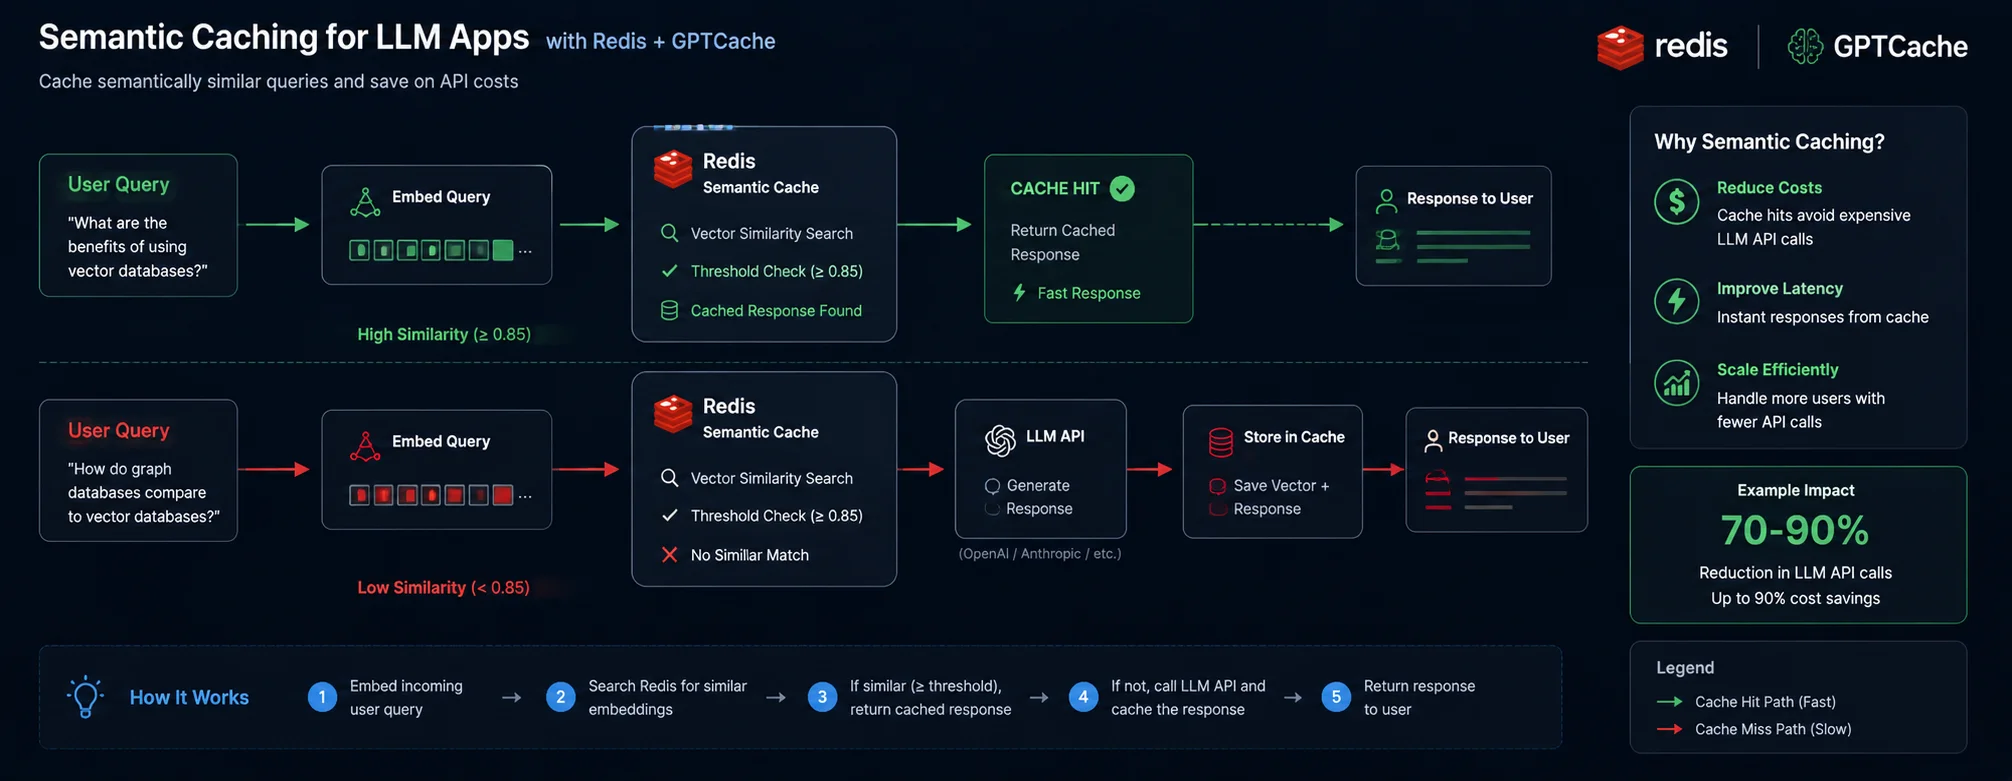
Semantic Caching for LLM Apps — Cut API Costs with Redis and GPTCache ...
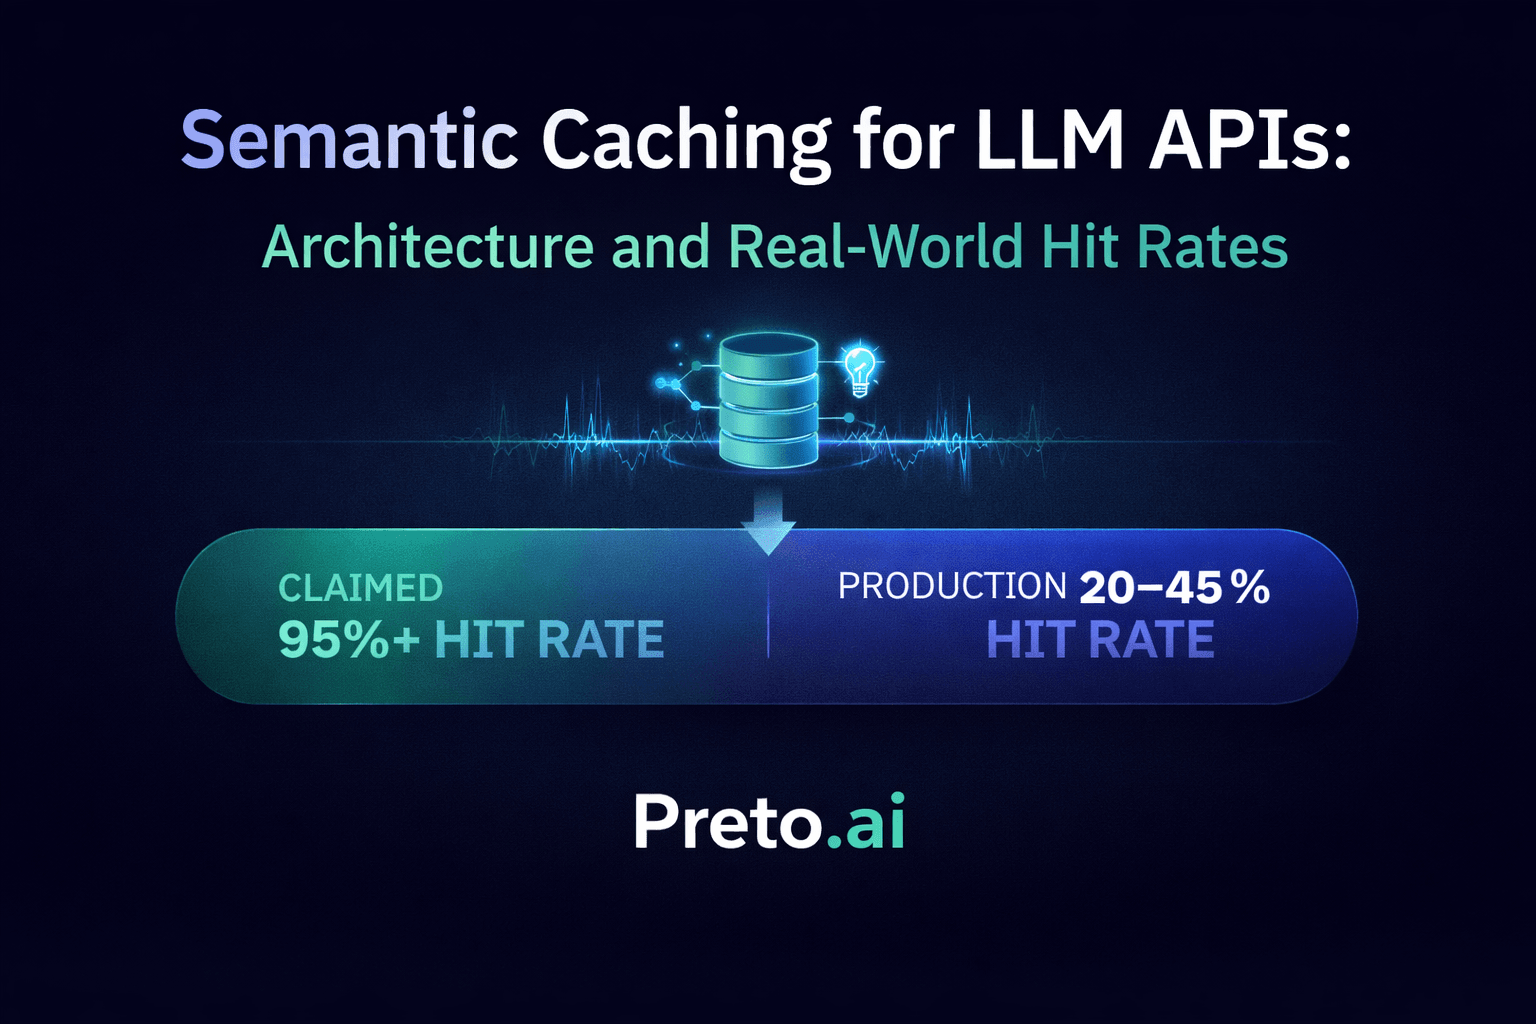
Semantic Caching for LLM APIs: Architecture and Real-World Hit Rates ...
Semantic Cache
GitHub - codefuse-ai/ModelCache: A LLM semantic caching system aiming ...
GitHub - SimFG/gpt-cache: ⚡ GPTCache is a library for creating semantic ...

GitHub - codefuse-ai/ModelCache: A LLM semantic caching system aiming ...
Оптимизация производительности LLM с Cache LM: архитектуры, стратегии и ...
Advertisement Space (336x280)
Semantic Caching for LLM Inference: GPTCache, Redis Vector Cache, and ...
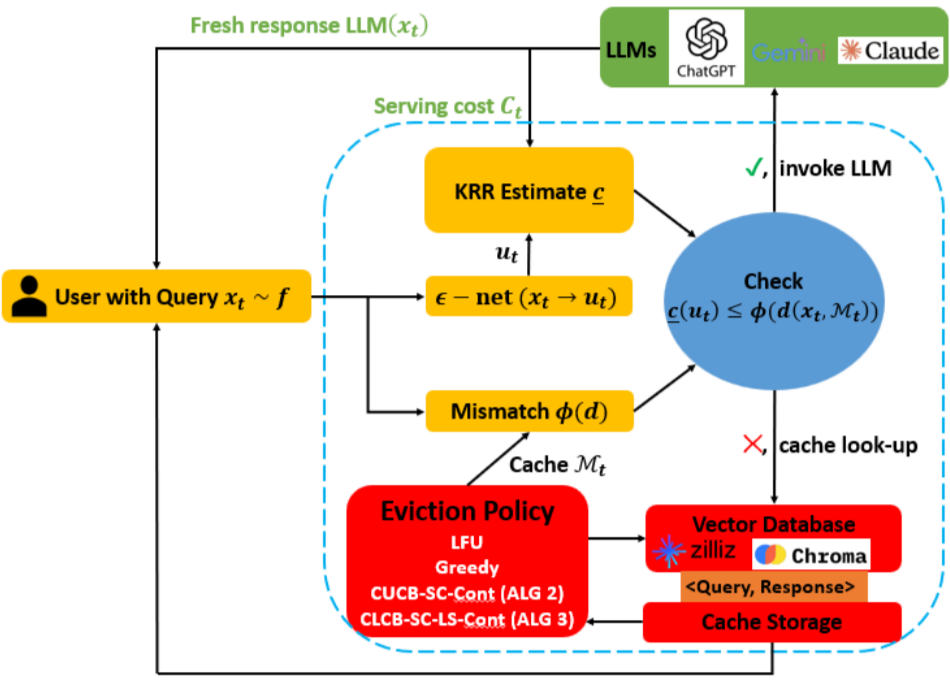
[논문 리뷰] Continuous Semantic Caching for Low-Cost LLM Serving

Semantic Cache

Caching Strategies for LLM Systems: Exact-Match & Semantic Caching ...

Build Semantic caching for LLM applications
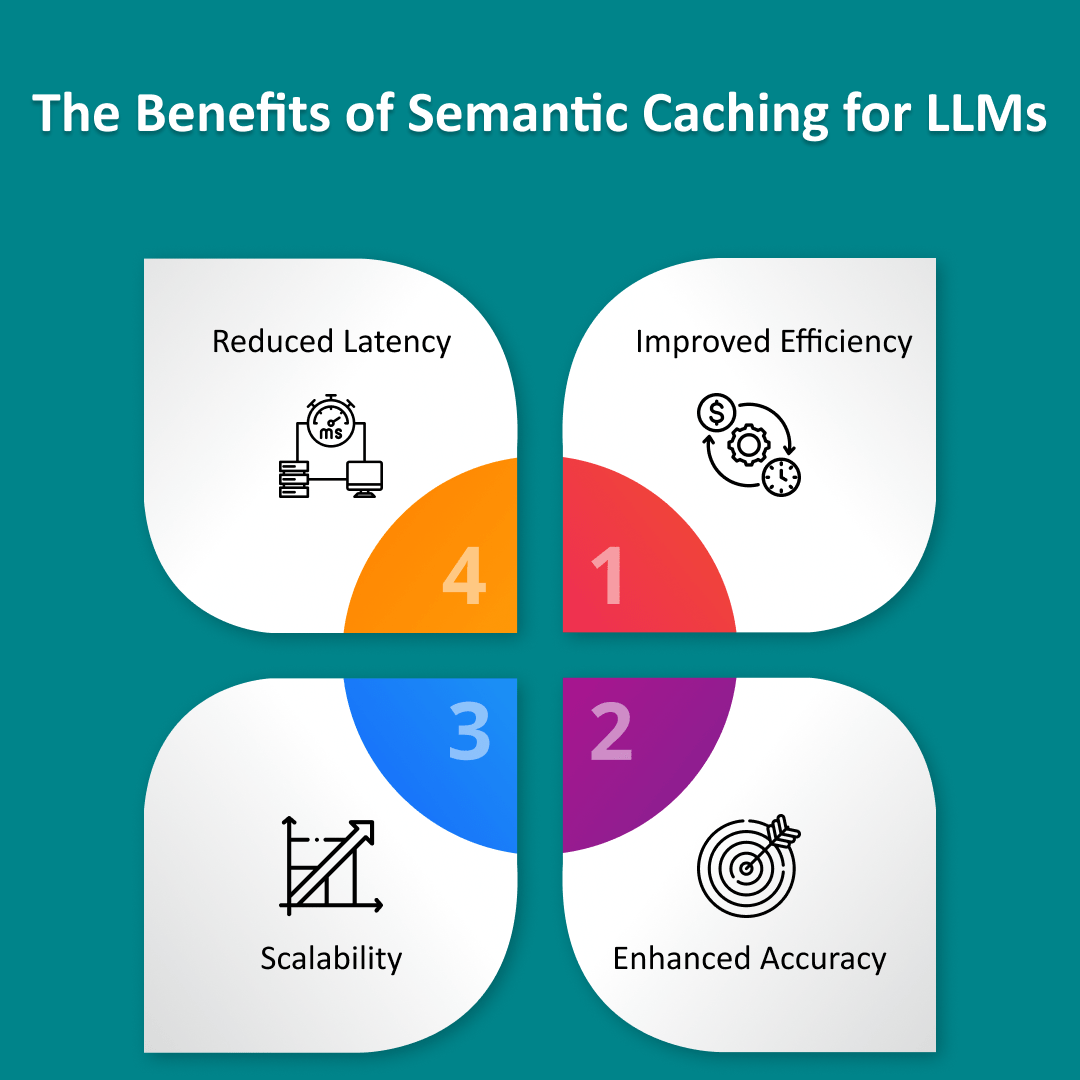
Boost LLM Performance with Semantic Caching for Speed and Accuracy