
Github Nvidiakvpress Llm Kv Cache Compression Made Easy Github
GitHub - NVIDIA/kvpress: LLM KV cache compression made easy

GitHub - NVIDIA/kvpress: LLM KV cache compression made easy · GitHub
GitHub - hilllief/polarquant-kv: LLM KV Cache compression - K+V dual ...
GitHub - sjtu-zhao-lab/ClusterKV: ClusterKV: Manipulating LLM KV Cache ...
GitHub - Zefan-Cai/KVCache-Factory: Unified KV Cache Compression ...

GitHub - opengear-project/GEAR: GEAR: An Efficient KV Cache Compression ...

GitHub - IsaacRe/vllm-kvcompress: KV cache compression for high ...
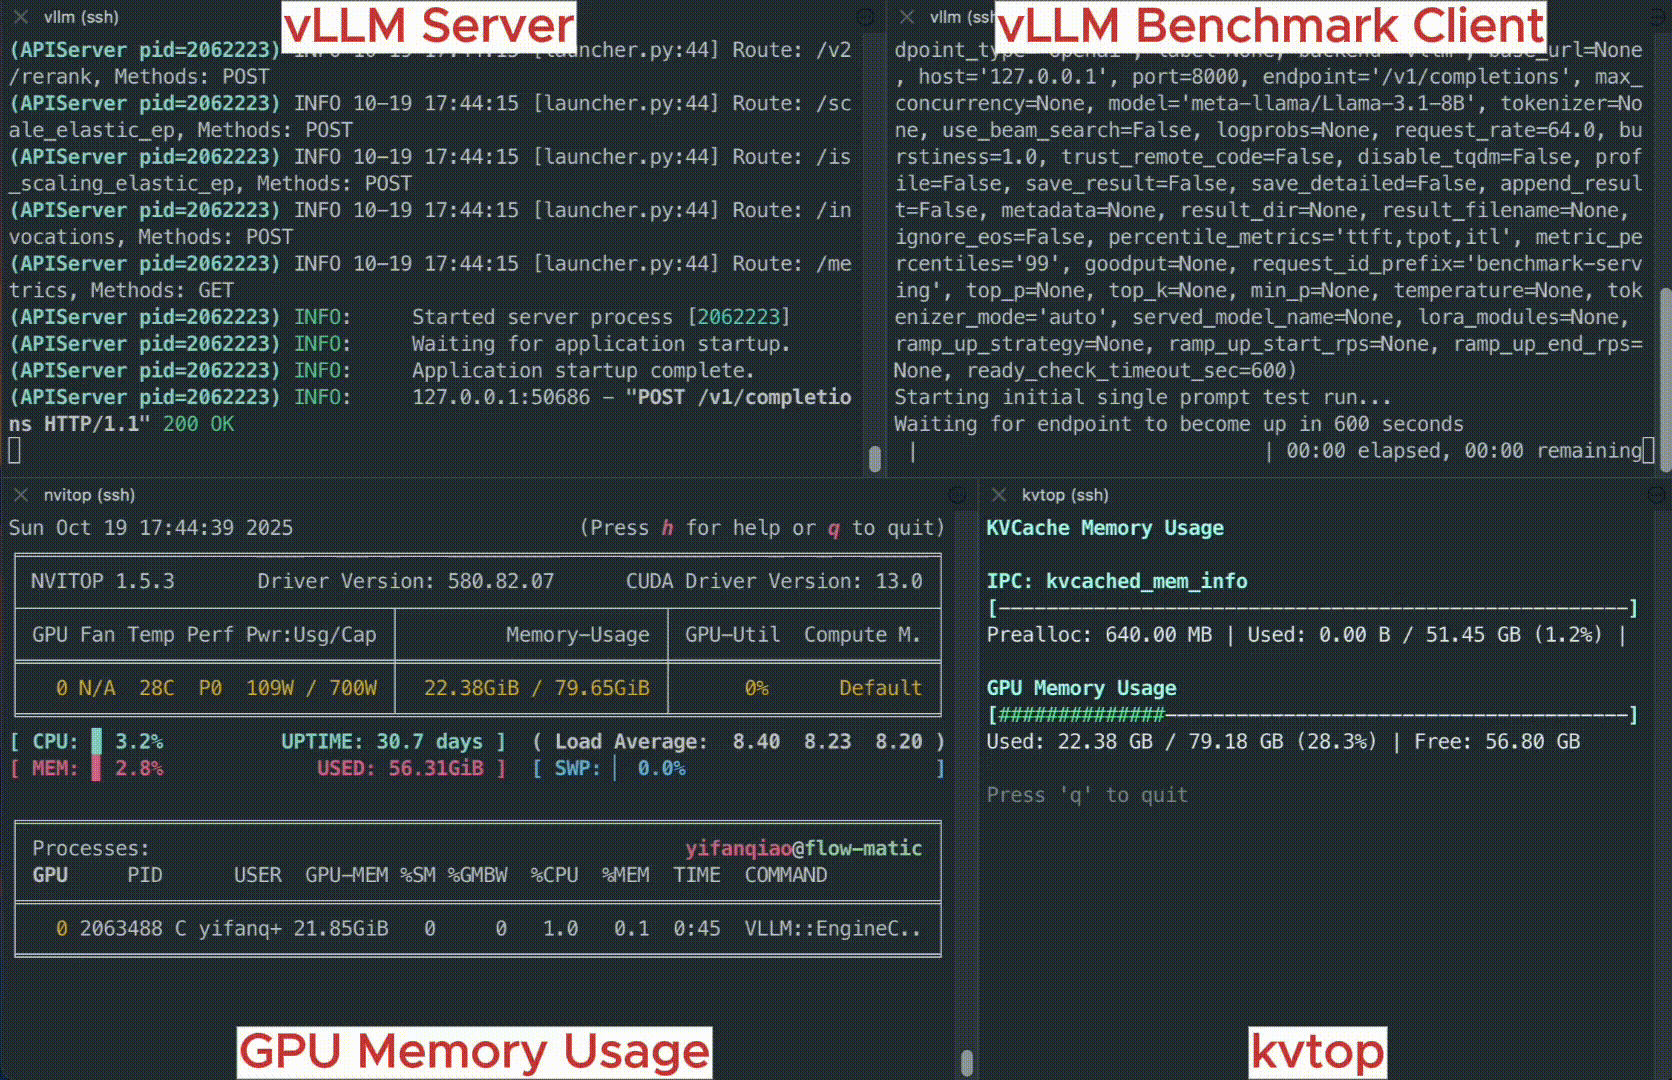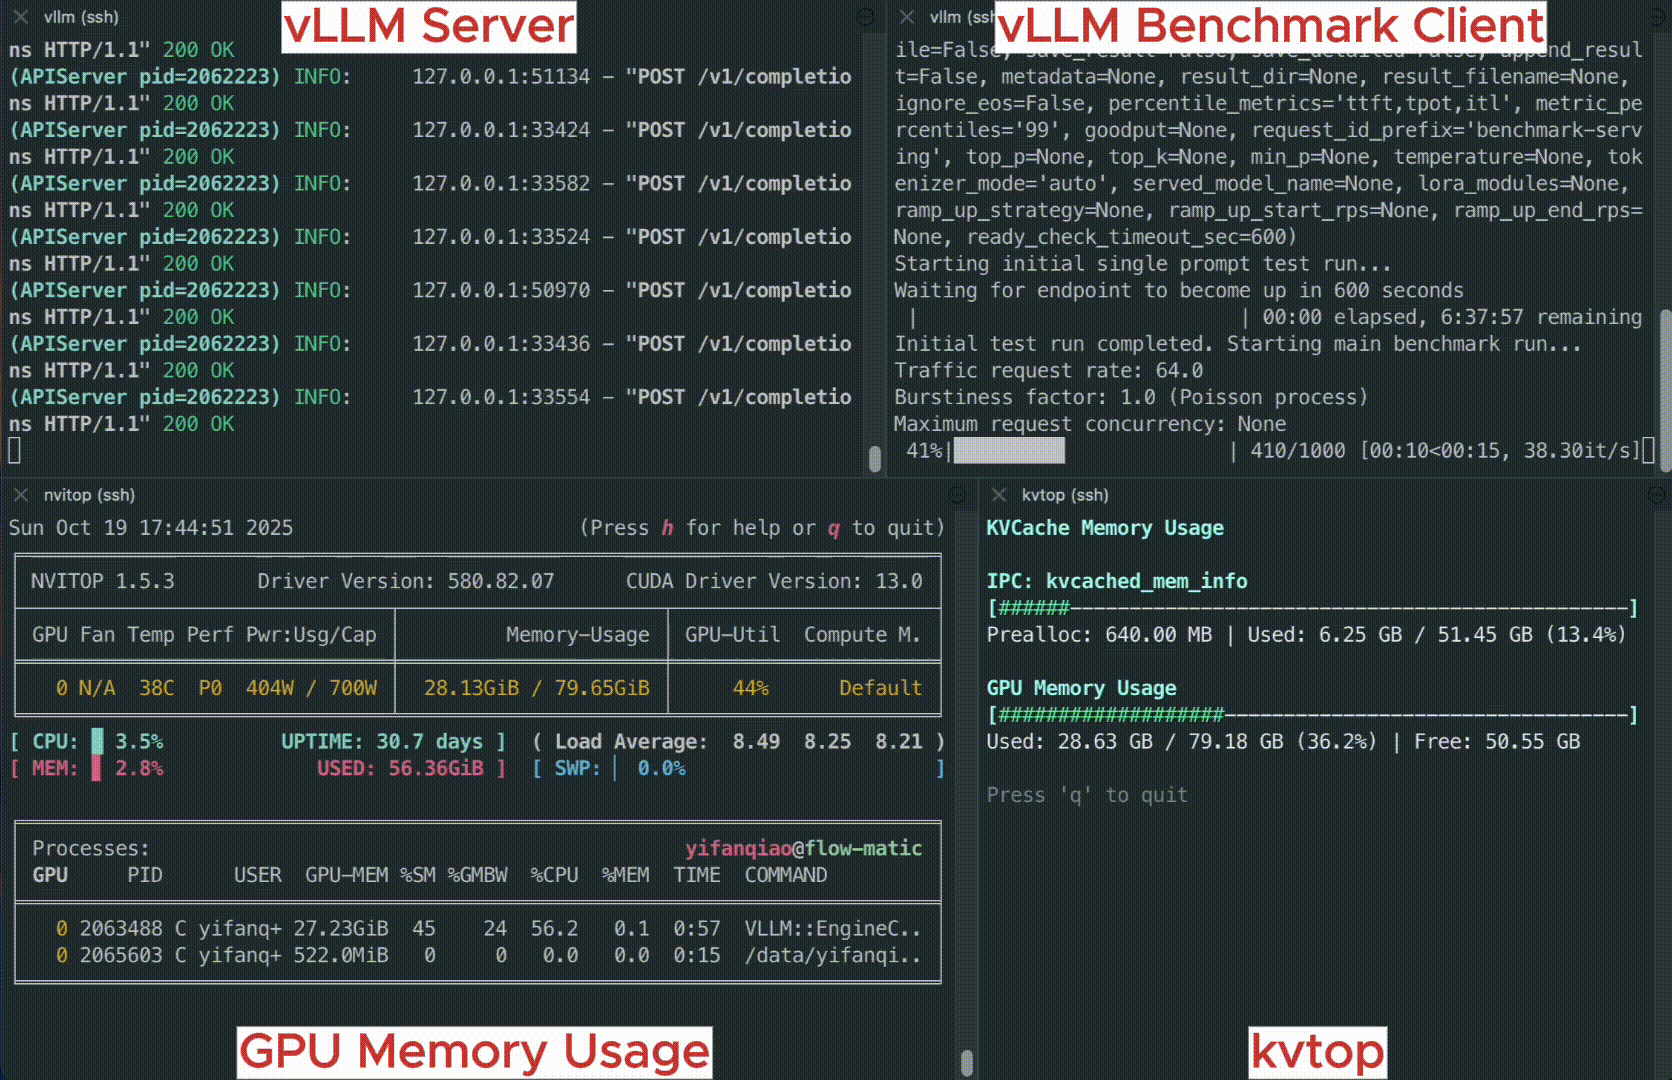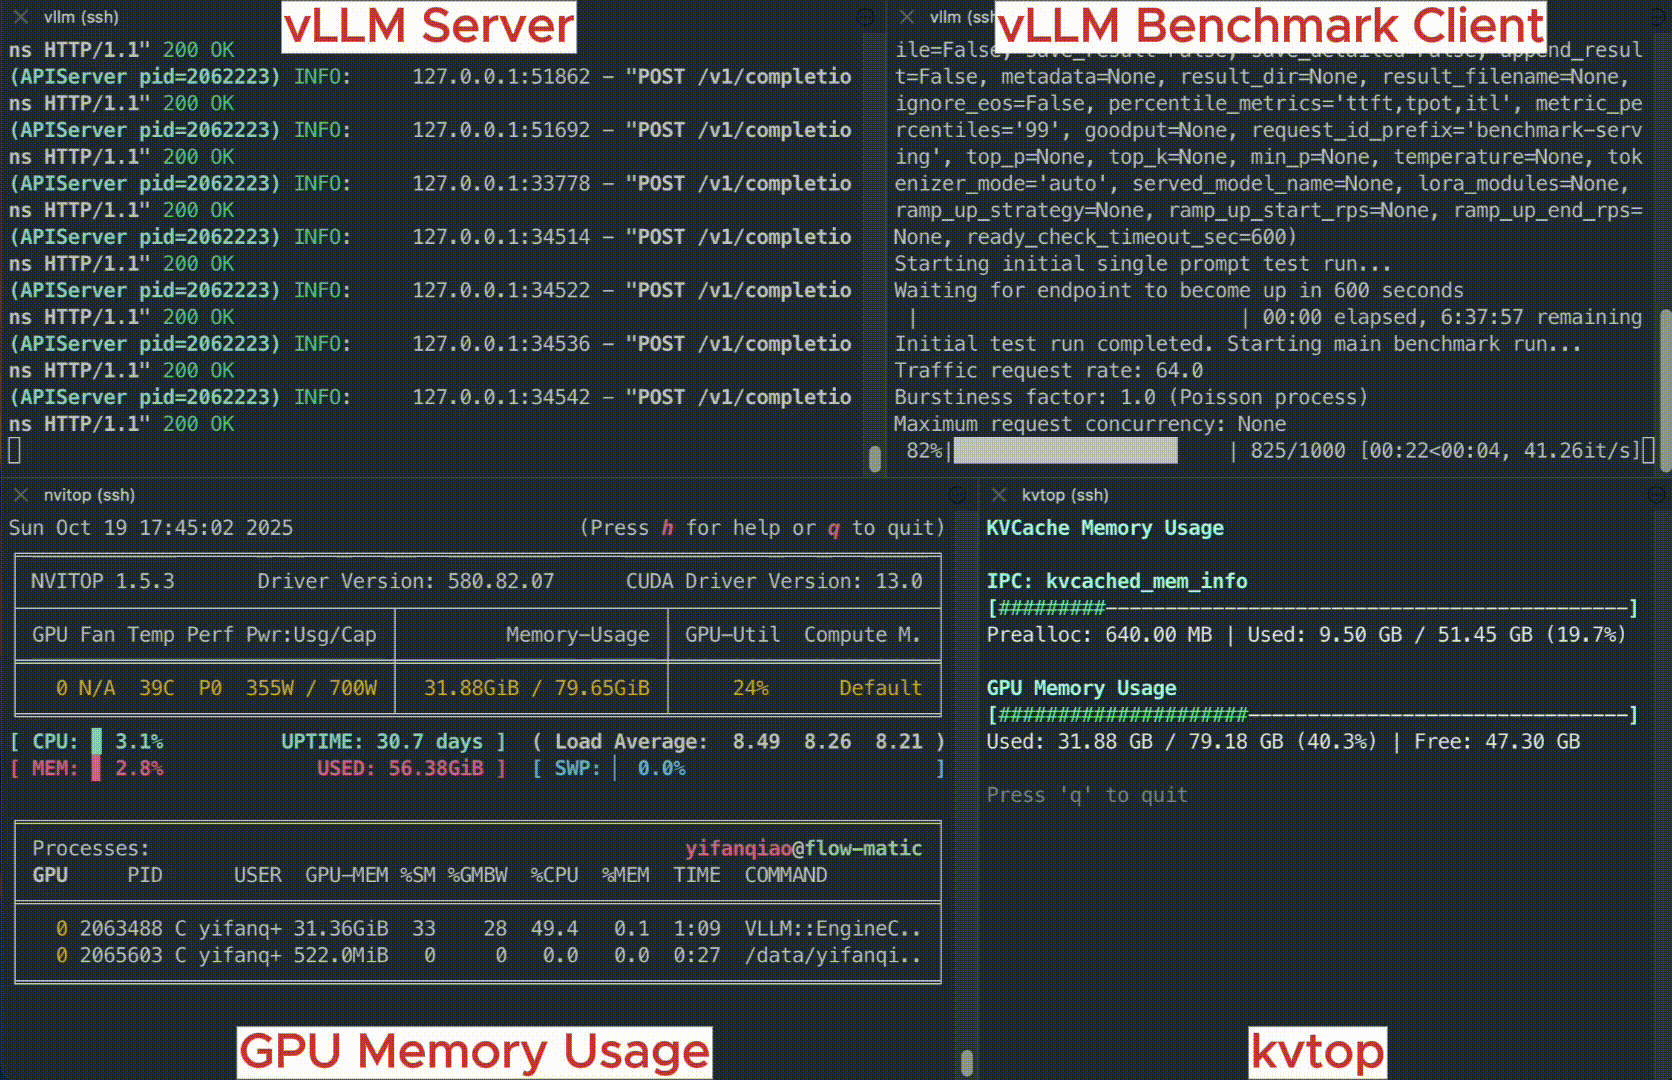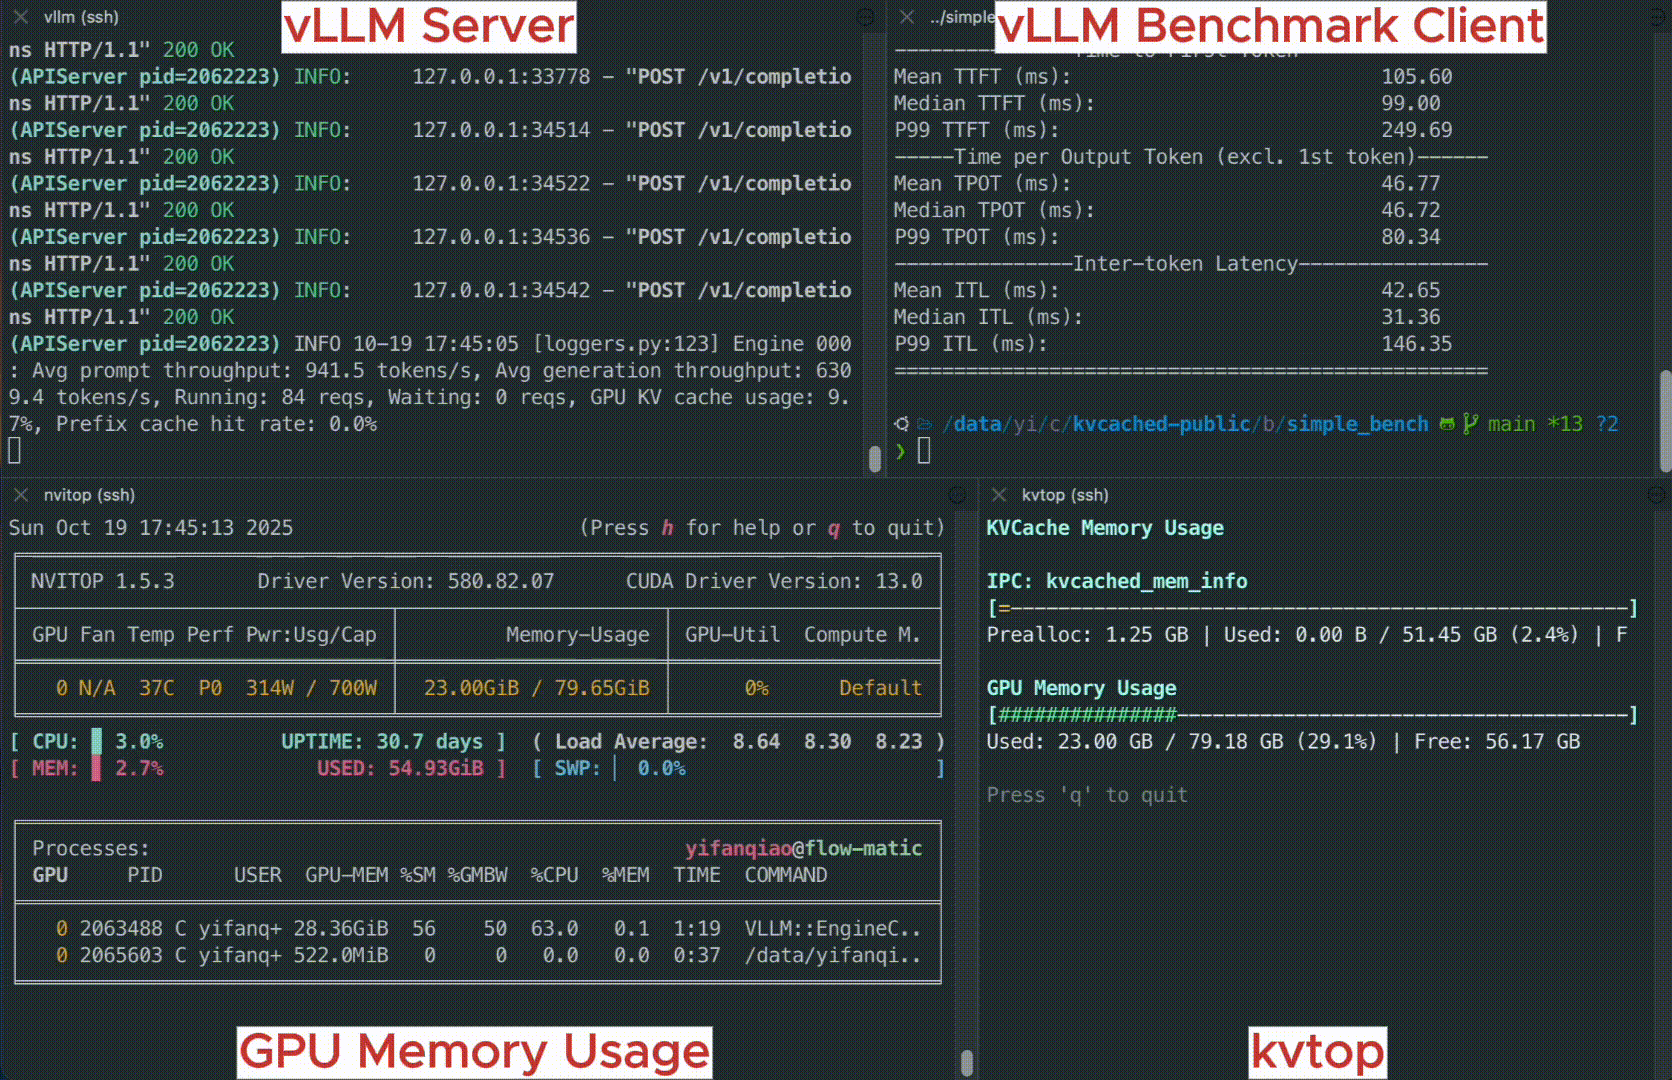
GitHub - ovg-project/kvcached: Virtualized Elastic KV Cache for Dynamic ...
Speculative KV Coding Achieves 4× Lossless Compression of LLM Cache ...
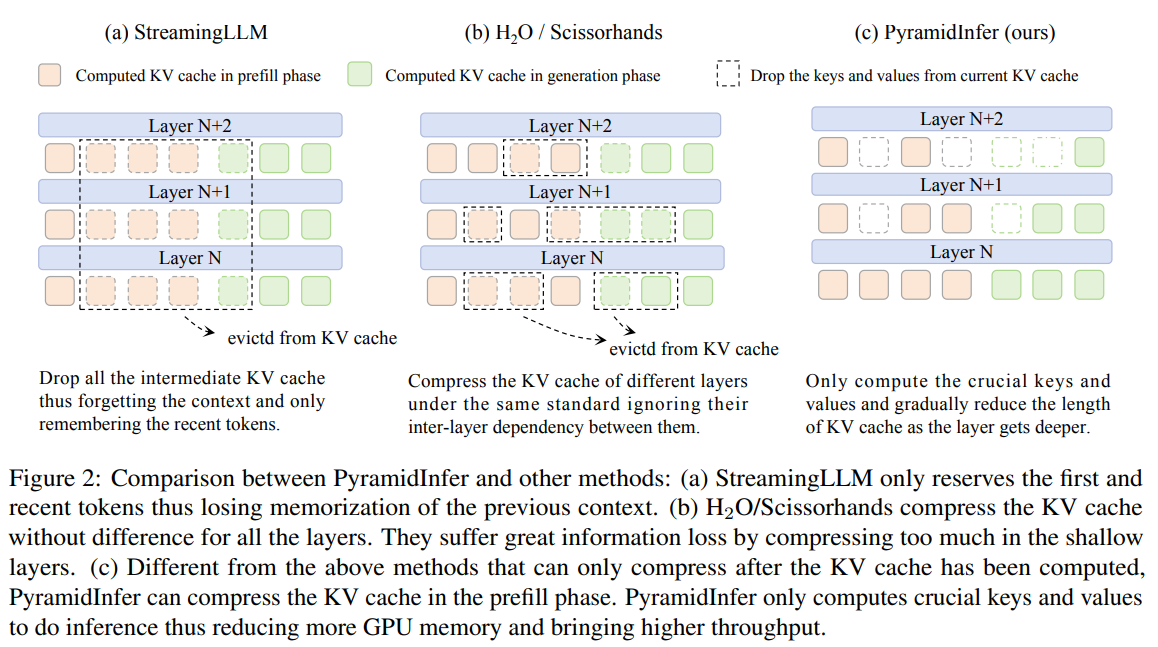
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
Advertisement Space (300x250)

TurboQuant Reducing LLM Memory Footprint via KV Cache Compression ...
Top 10 KV Cache Compression Techniques for LLM Inference: Reducing ...
GitHub - LMCache/LMCache: Supercharge Your LLM with the Fastest KV ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...

KVCompose: Efficient Structured KV Cache Compression with Composite ...
GitHub - llmsresearch/kvcompress: KV-cache compression for LLMs ...

ReCalKV: Low-Rank KV Cache Compression via Head Reordering and Offline ...

Lossless KV Cache Compression to 2% | AI Research Paper Details

ClusterKV: Manipulating LLM KV Cache in Semantic Space for Recallable ...

HCAttention: Extreme KV Cache Compression via Heterogeneous Attention ...
Advertisement Space (336x280)

KV Cache Compression for Inference Efficiency in LLMs: A Review | AI ...
[RFC]: Dynamic KV Cache compression based on vLLM framework · Issue ...

GEAR: An Efficient KV Cache Compression Recipe for Near-Lossless ...
KV Cache Compression Concepts | NVIDIA/kvpress | DeepWiki
How to disable KV cache for LLM · Issue #1976 · NVIDIA/TensorRT-LLM ...
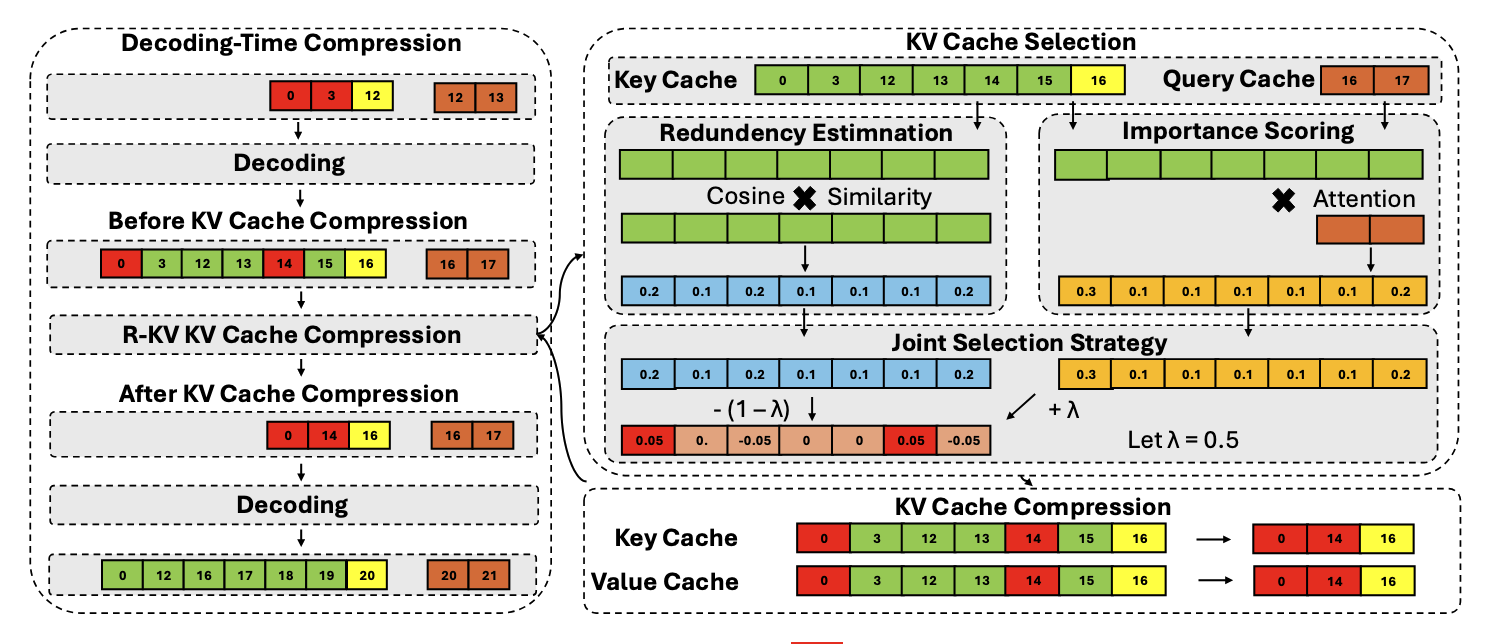
R-KV: Redundancy-aware KV Cache Compression for Reasoning Models

KVReviver: Reversible KV Cache Compression with Sketch-Based Token ...
When to Remember: Distilling Dynamic KV Cache Compression for Reasoning ...
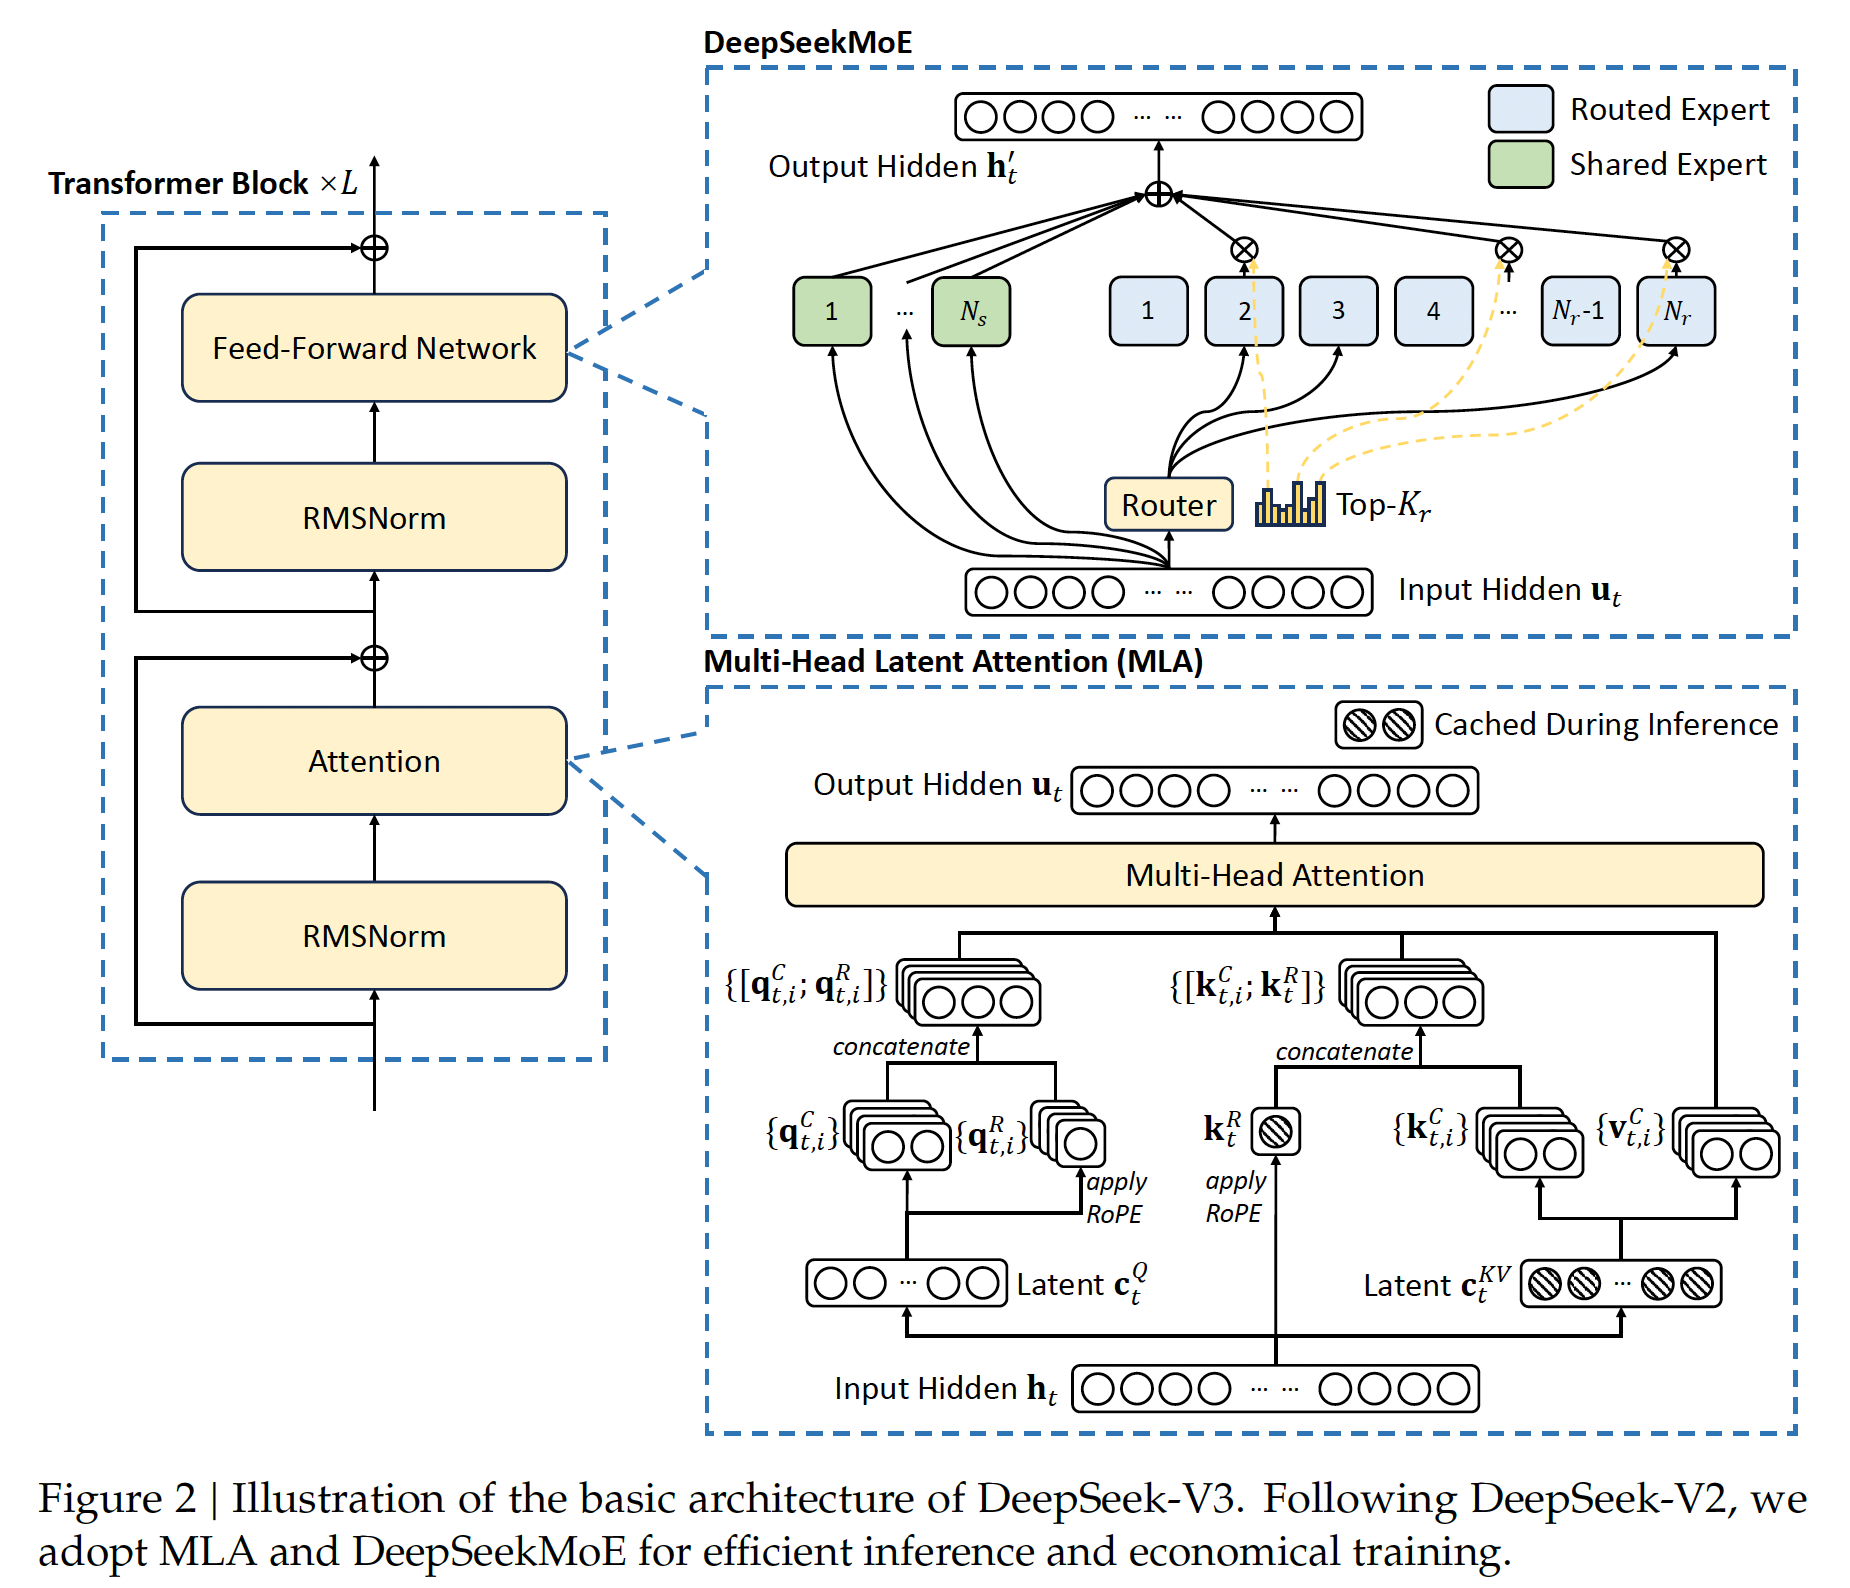
LLM —— KV Cache | 一直进步 做喜欢的

LLM Inference: Accelerating Long Context Generation with KV Cache ...
Advertisement Space (336x280)
KV Cache Compression Revolution: Deep Dive into NVIDIA's 20x ...

[논문 리뷰] Lossless KV Cache Compression to 2%
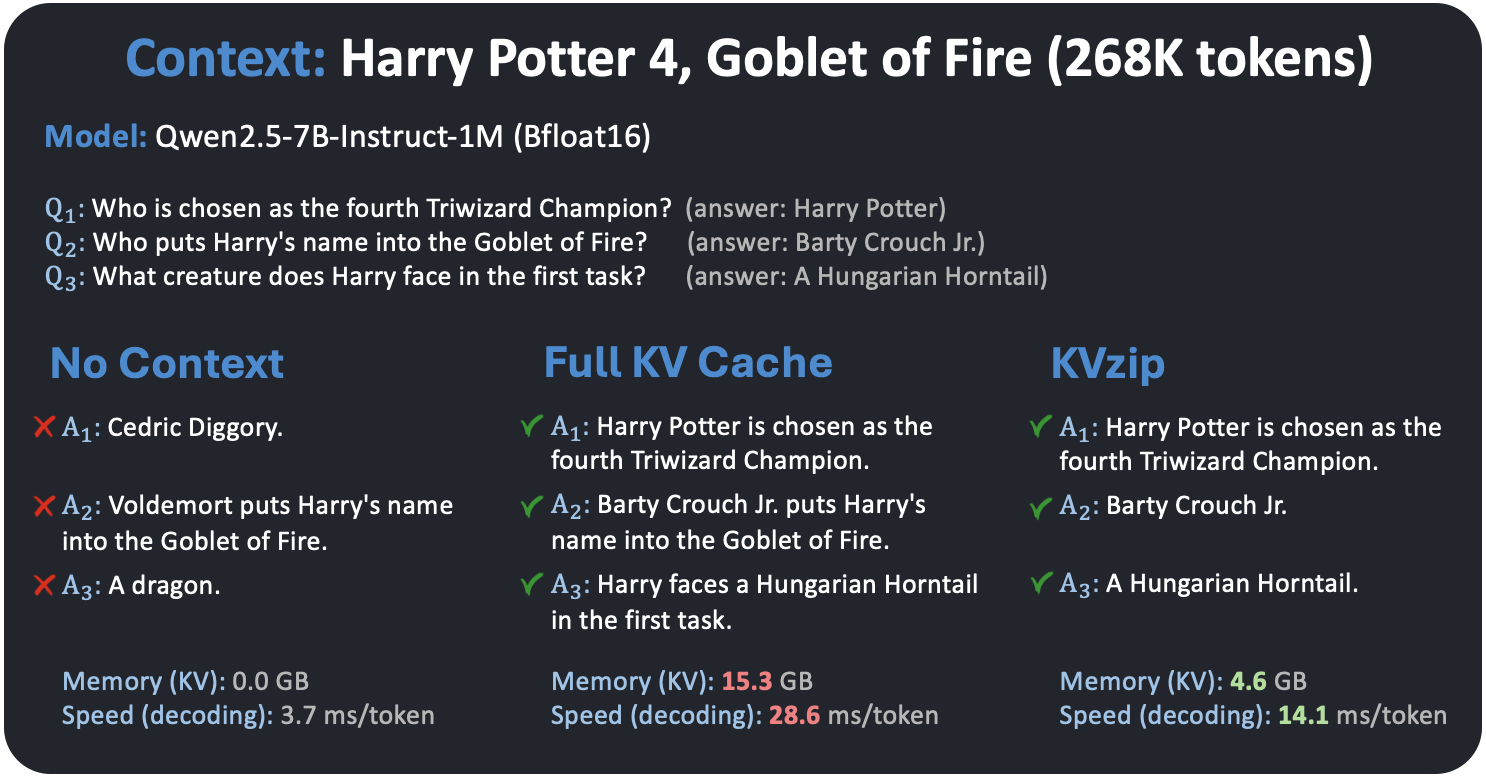
KVzip: Query-Agnostic KV Cache Compression with Context Reconstruction
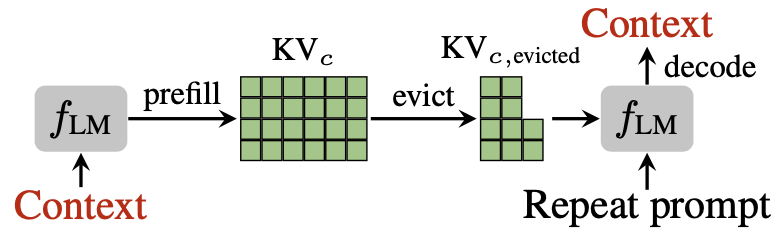
KVzip: Query-Agnostic KV Cache Compression with Context Reconstruction
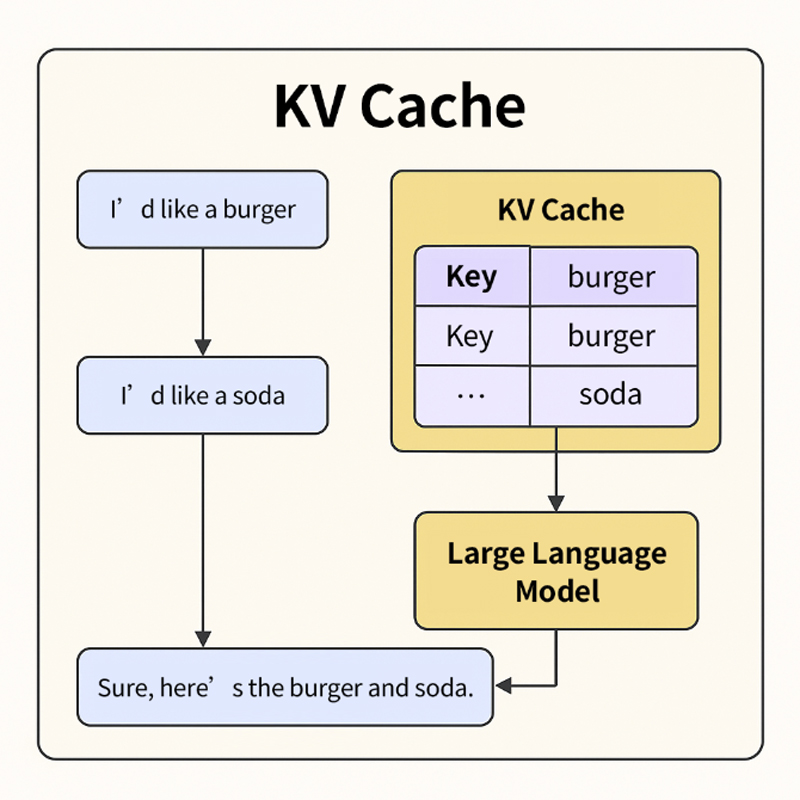
KV Cache Meets NVMe: The Key to Accelerating LLM Inference

KV CACHE Compression - a giulio98 Collection