
Github Qtaeonnxcppruntimeinference Onnx Runtime Gpu Inference
GitHub - Qtae/onnx_cpp_runtime_inference: onnx runtime gpu inference ...
GitHub - leimao/ONNX-Runtime-Inference: ONNX Runtime Inference C++ Example

The GPU Inference Stack: TensorRT, vLLM, Triton, and ONNX Runtime ...
Multithreaded Inference on GPU with only one session in Onnx Runtime ...

ONNX Runtime GPU inference on DGX Spark (GX10) — build guide and ...
GitHub - trainyolo/YOLO-ONNX: YOLO inference with ONNX runtime · GitHub
Deploy AI/ML Inference Pipeline with ONNX Runtime and FastAPI on Rocky ...

Optimizing and deploying transformer INT8 inference with ONNX Runtime ...
GTC 2020: Deploying your Models to GPU with ONNX Runtime for ...
TensorRT vs. ONNX Runtime | Inference Engine Comparison | Inference Systems
Advertisement Space (300x250)
ONNX Runtime Inference on GPU: Failed to create CUDAExecutionProvider ...
ONNX runtime produces different inference results for the same input ...
How to use GPU for inference on onnx model · Issue #5755 · ultralytics ...

ONNX Runtime : Inference Runtime for Portability, Performance, and ...
GPU Inference · Issue #25 · tpoisonooo/llama.onnx · GitHub
ONNX runtime inference slower than PyTorch for DBNet · Issue #475 ...
GitHub - WWandP/miniONNXRuntime: A minimal ONNX Runtime implementation ...
ONNX Runtime Inference | Peterande/D-FINE | DeepWiki
ONNX Runtime on GPU of an Android System · microsoft onnxruntime ...
Introduction to the inference server project using the ONNX Runtime ...
Advertisement Space (336x280)
scrfd.py onnx inference doesn't use GPU · Issue #2091 · deepinsight ...
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime

เปิดคอร์ส SLM Inference with ONNX Runtime at the edge สำหรับชาว Arise ...
Error Installing ONNX Runtime GPU with CUDA 12.0: The project does not ...
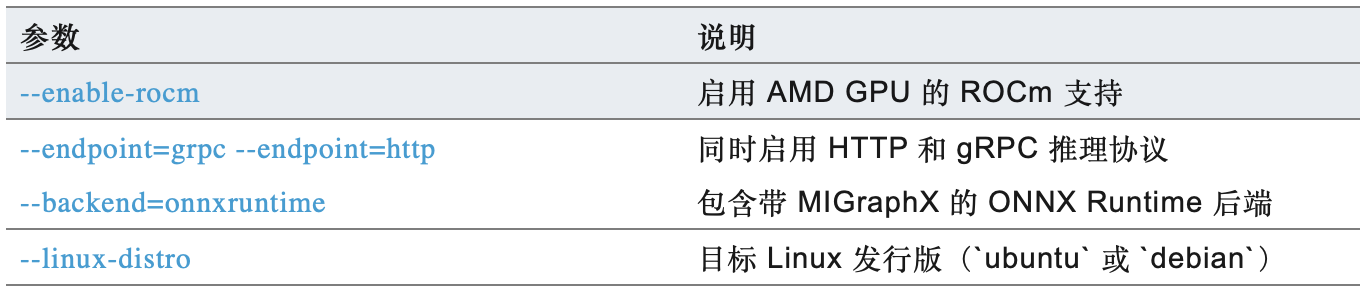
从构建到基准测试:在 AMD GPU 上使用 Triton Inference Server 部署 ONNX 模型 - 知乎

Kokoro-82M ONNX Runtime Inference Gradio Demo | kokoro-onnx

Python Quantization-Aware Inference with ONNX Runtime | by Nikulsinh ...
Cant get GPU to work with ONNX Runtime 1.19 Cuda 12.6 CuDNN 9 RTXA4000 ...

Inference Optimization with ONNX Runtime - YouTube
How to calling the ONNX Runtime model in QT (C++) with a GPU 4080 ...
Advertisement Space (336x280)
How to enable ONNX Runtime Windows GPU version into OpenCV CMake flag ...

ONNX Runtime | Home
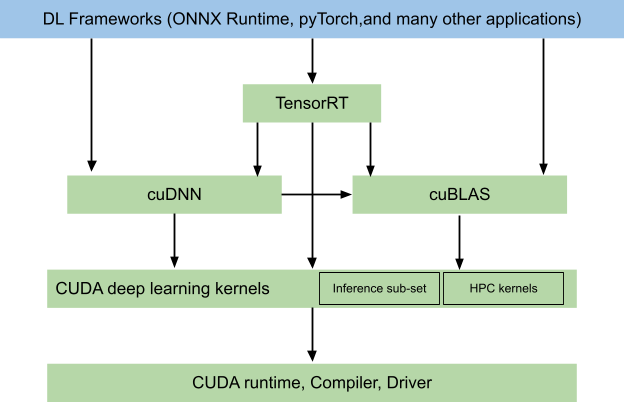
基于 NVIDIA 的 PC 的端到端 AI : ONNX Runtime 中的 CUDA 和 TensorRT 执行提供程序 ...
[Inference] ONNXRuntime inference crash on GPU without any log but not ...
ONNX Runtime: Cross-Platform AI Inference Engine | Inference Systems
Inference time of onnxruntime gpu increases at very high batch sizes ...