
Github Sunzxllama Cpp Turboquant Llm Inference In Cc Github
GitHub - sunzx/llama-cpp-turboquant: LLM inference in C/C++ · GitHub

TurboQuant & DFlash: Accelerating Local LLM Inference with Enhanced ...

Visualizing LLM Inference Flow with Turboquant KV Compression Following ...
llama.cpp - LLM inference in C/C++
How to Run LLM Inference with llama.cpp in Docker
GitHub - AI-Engineering-at/llama-cpp-turboquant-guide: Practical guide ...
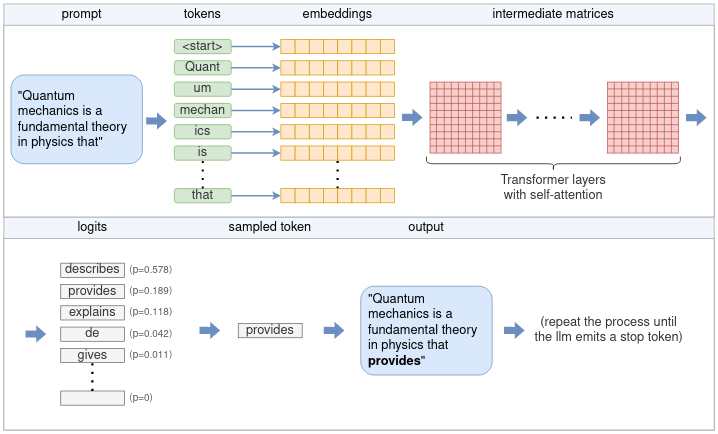
Understanding how LLM inference works with llama.cpp
TurboQuant: Best LLM KV Cache Compression for GPU Inference Engineers ...
LLM Inference Servers Compared - vLLM, SGLang, llama.cpp and Ollama ...
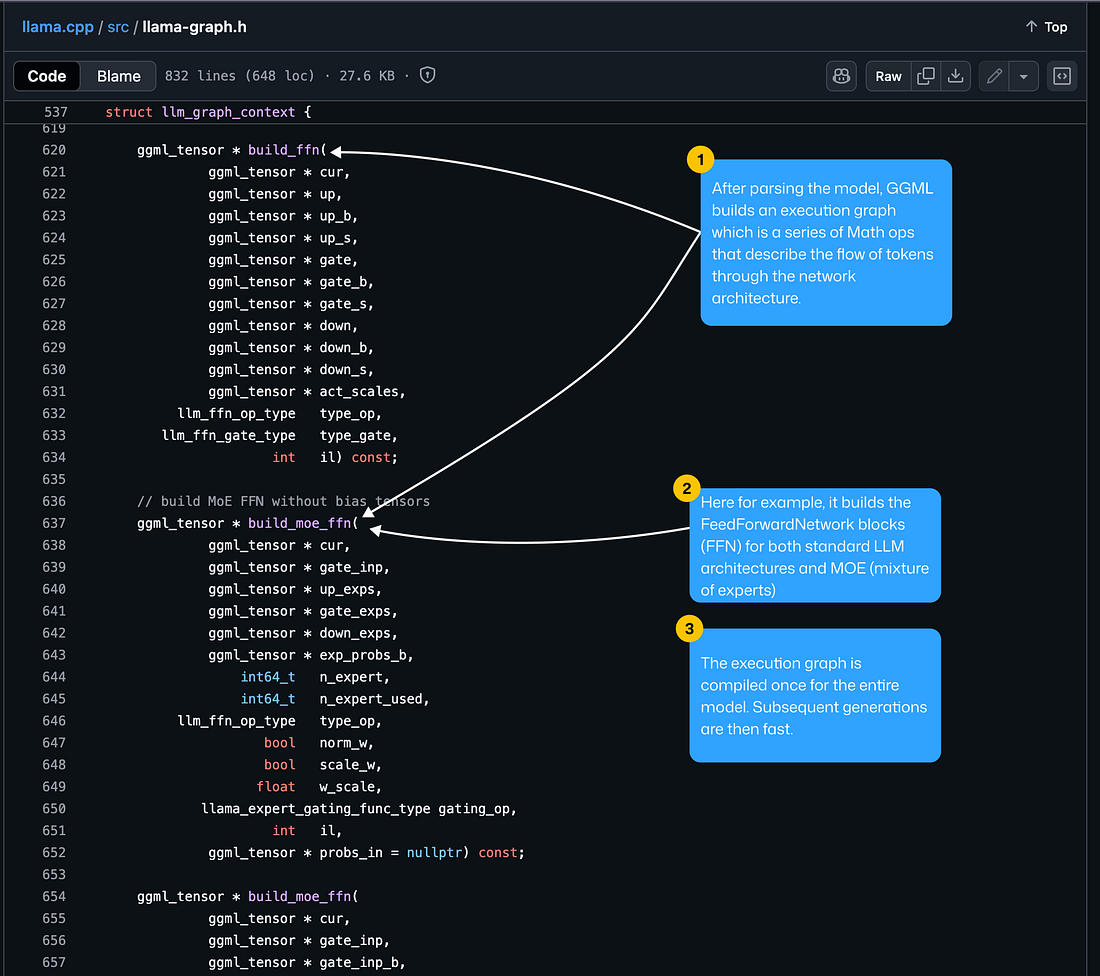
Local LLM Inference : llama.cpp, GGUF, Quantizations and GGML Explained
Advertisement Space (300x250)

TurboQuant K-V Cache Compression for Local llama.cpp inference - YouTube
llama.cpp: The Ultimate Guide to Efficient LLM Inference and ...
Llama.cpp Tutorial: A Complete Guide to Efficient LLM Inference and ...
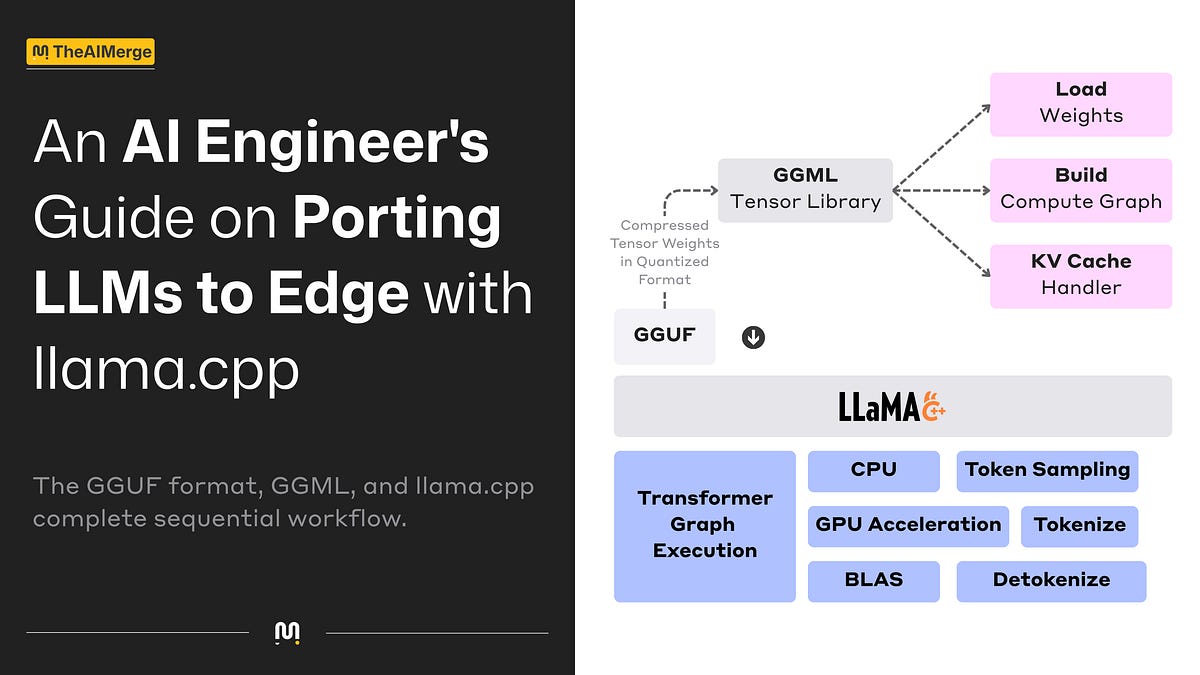
Local LLM Inference : llama.cpp, GGUF, Quantizations and GGML Explained
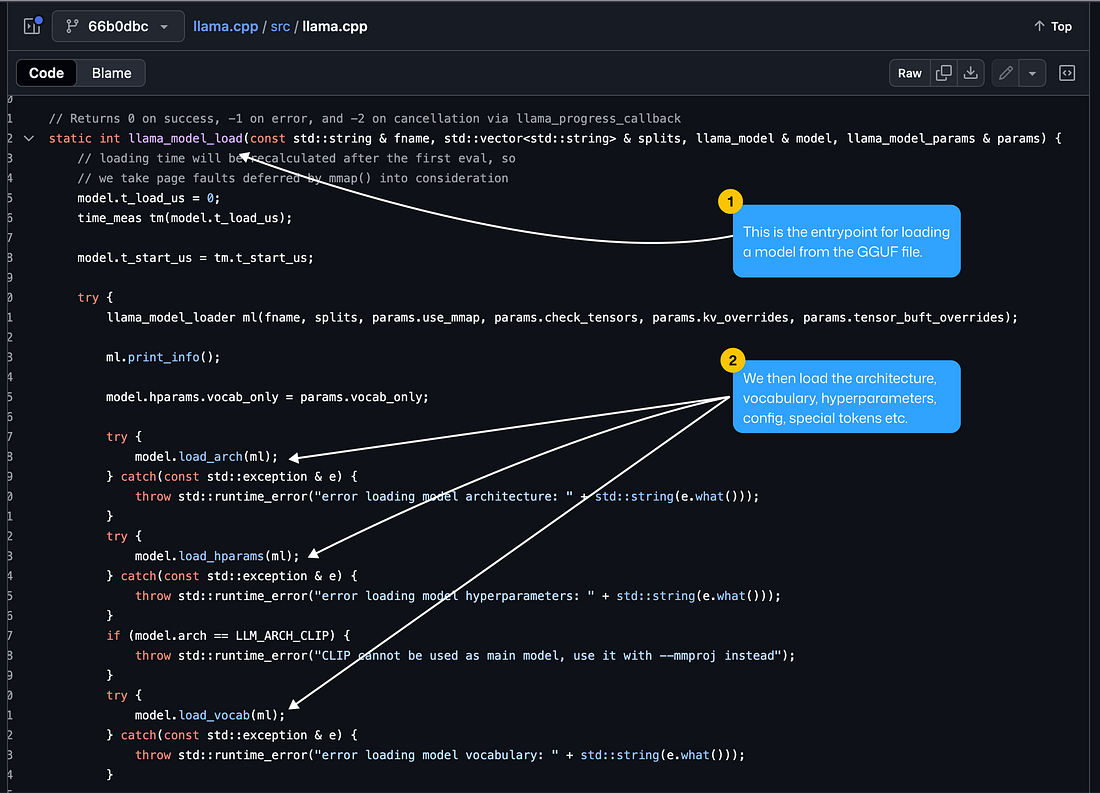
Local LLM Inference : llama.cpp, GGUF, Quantizations and GGML Explained
Local LLM Inference & Multi-Token Prediction: ik_llama.cpp | RavChat
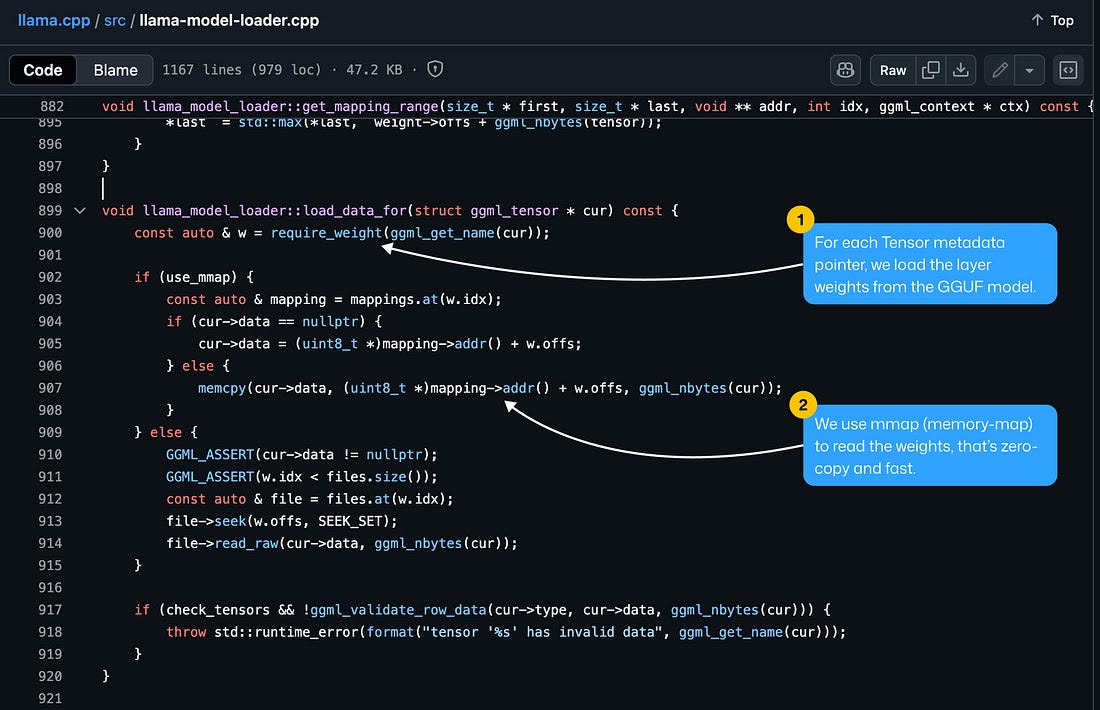
Local LLM Inference : llama.cpp, GGUF, Quantizations and GGML Explained
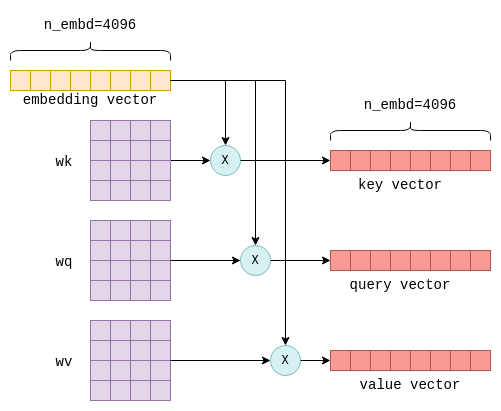
Understanding how LLM inference works with llama.cpp
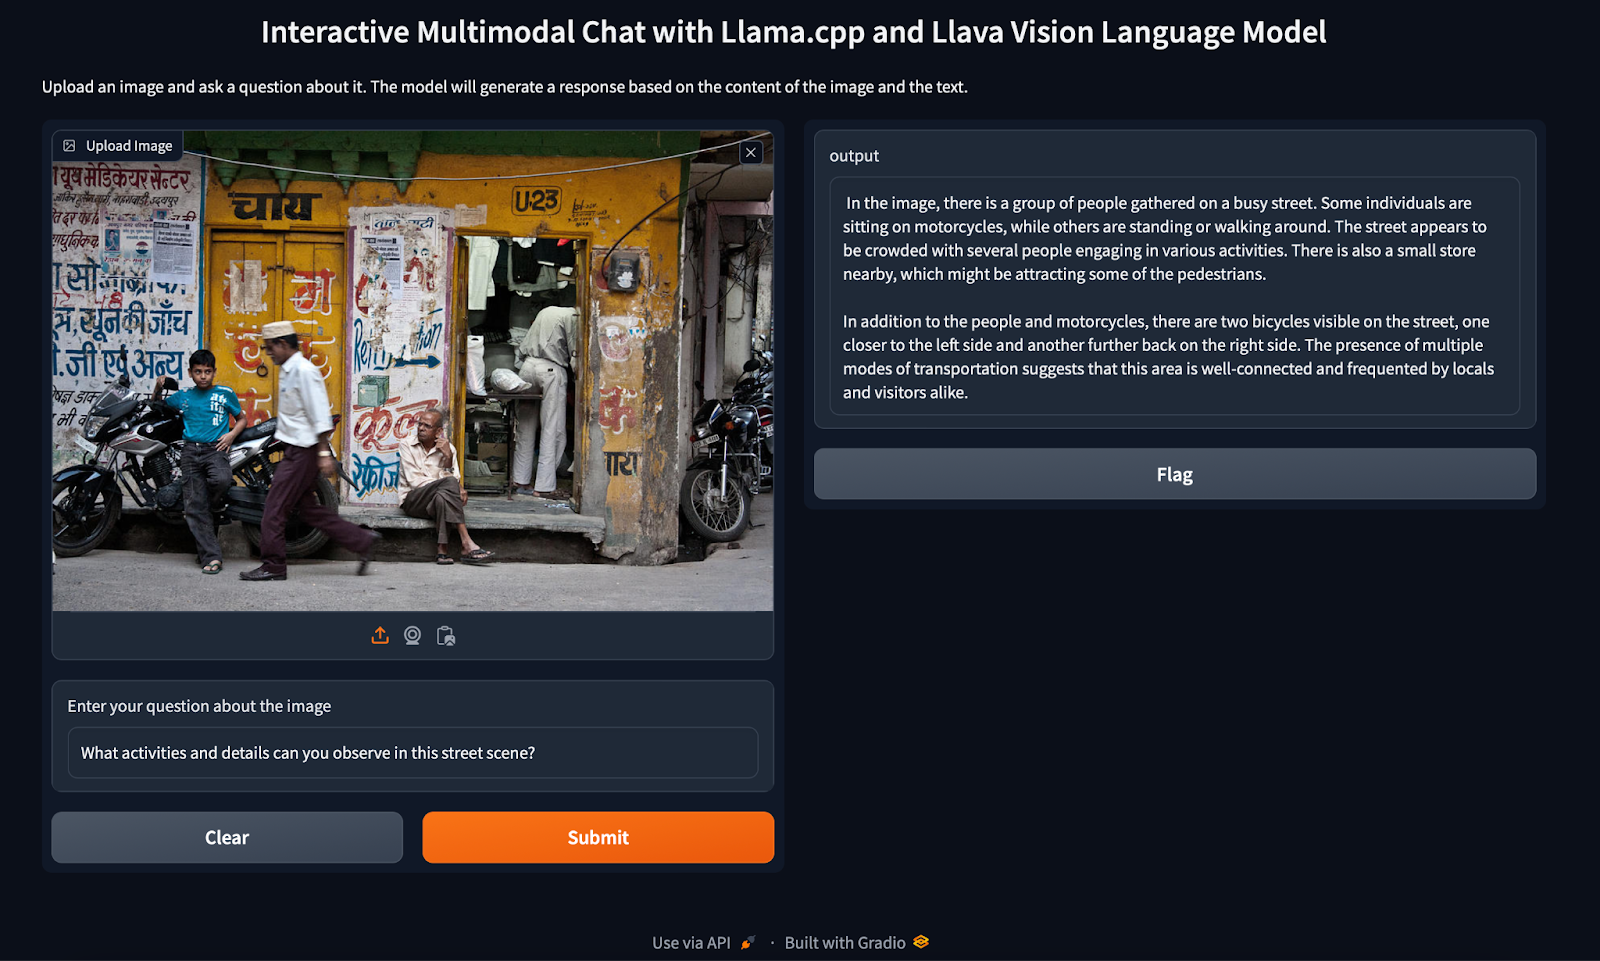
llama.cpp: The Ultimate Guide to Efficient LLM Inference and ...

Llama.cpp and Square Codex for Local LLM Inference
Advertisement Space (336x280)
Speeding up LLM inference using SparQ Attention & llama.cpp - Graphcore ...

llama.cpp - LLM Inference C/C++ Library | EveryDev.ai
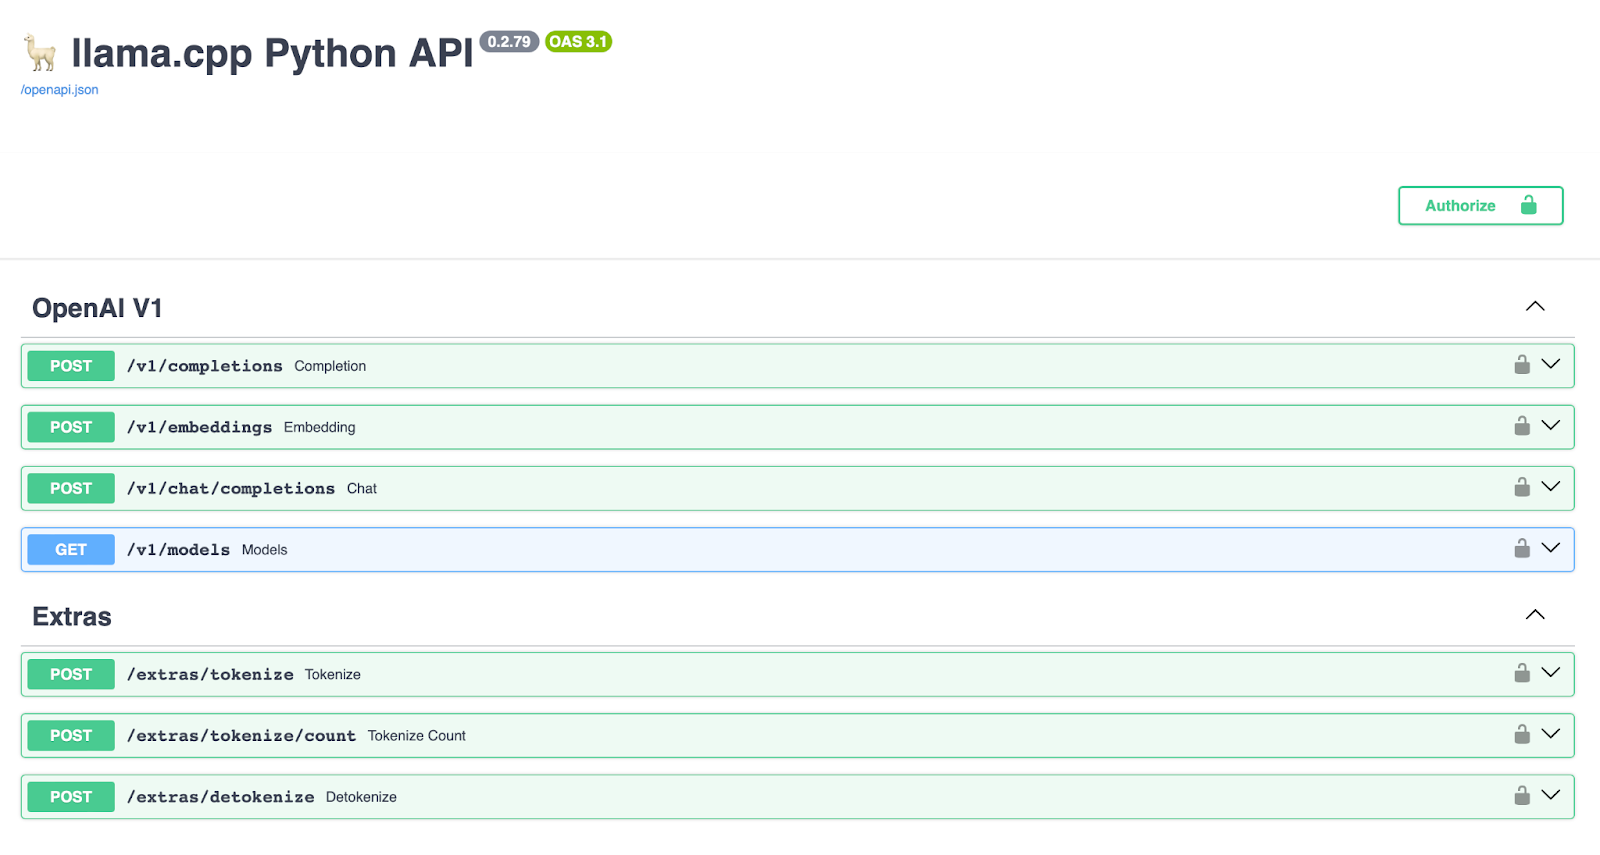
llama.cpp: The Ultimate Guide to Efficient LLM Inference and ...
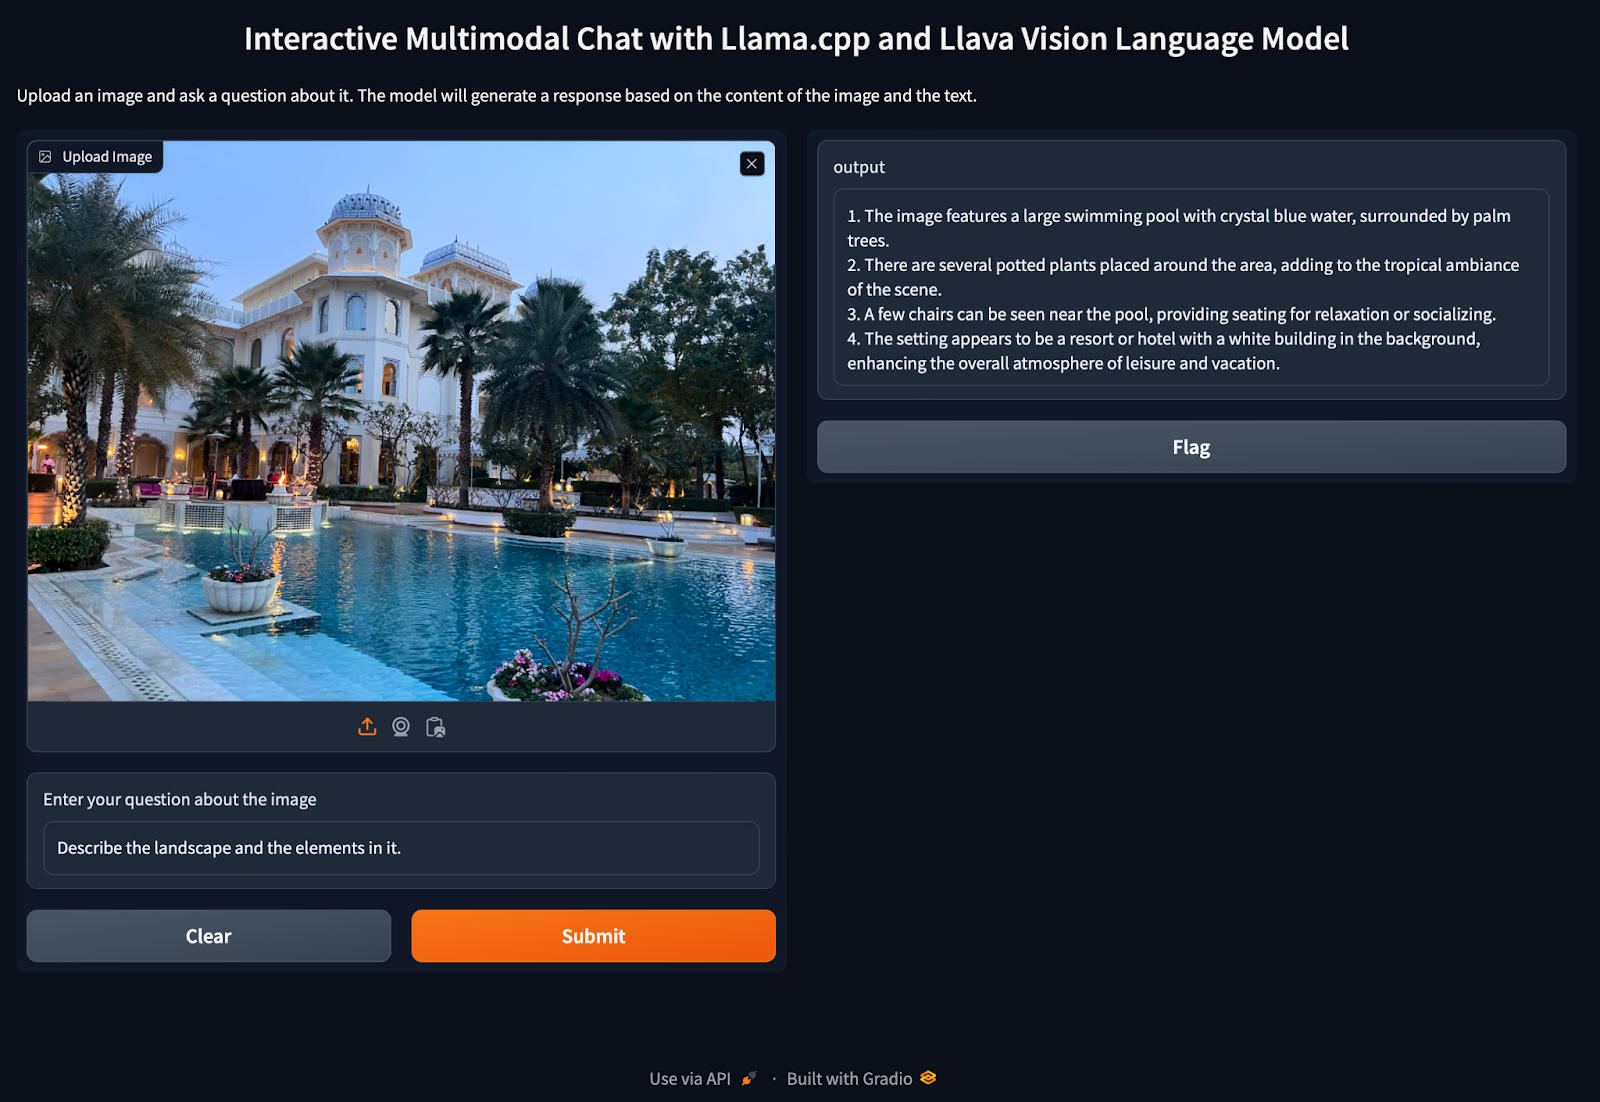
llama.cpp: The Ultimate Guide to Efficient LLM Inference and ...
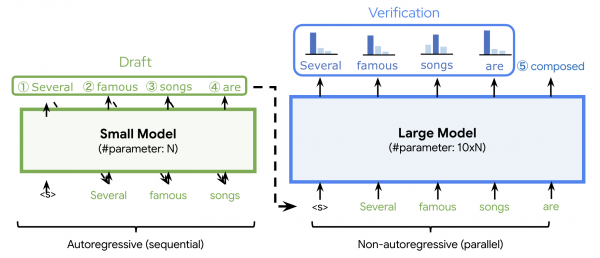
llama.cpp vs. vLLM: Choosing the right local LLM inference engine | Red ...
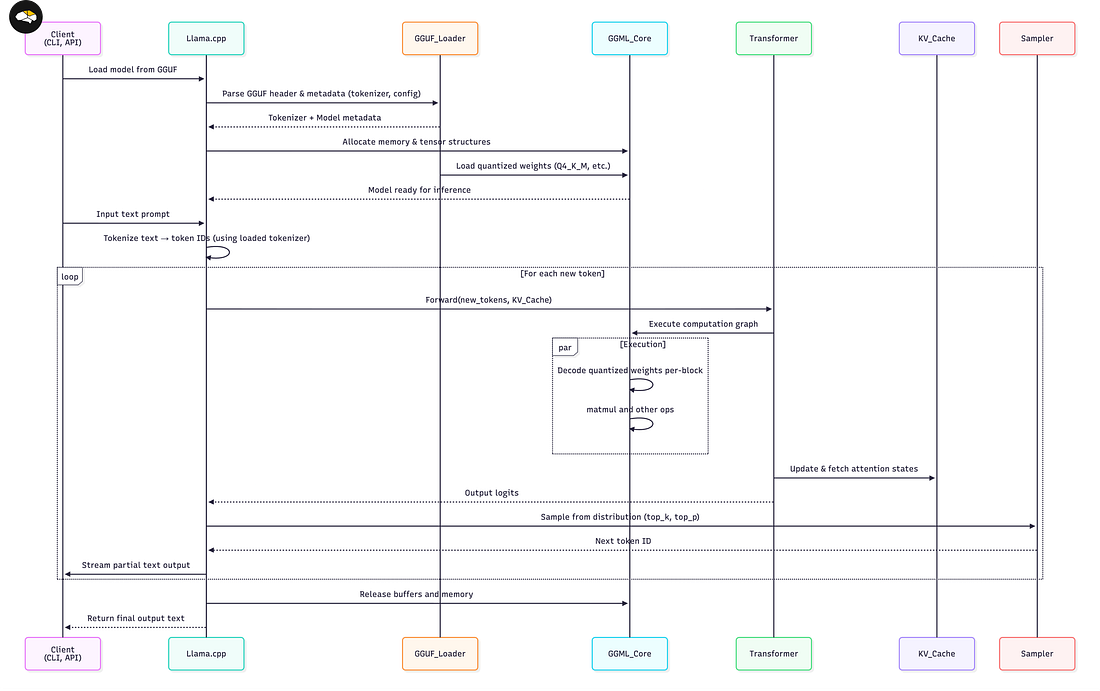
Local LLM Inference : llama.cpp, GGUF, Quantizations and GGML Explained
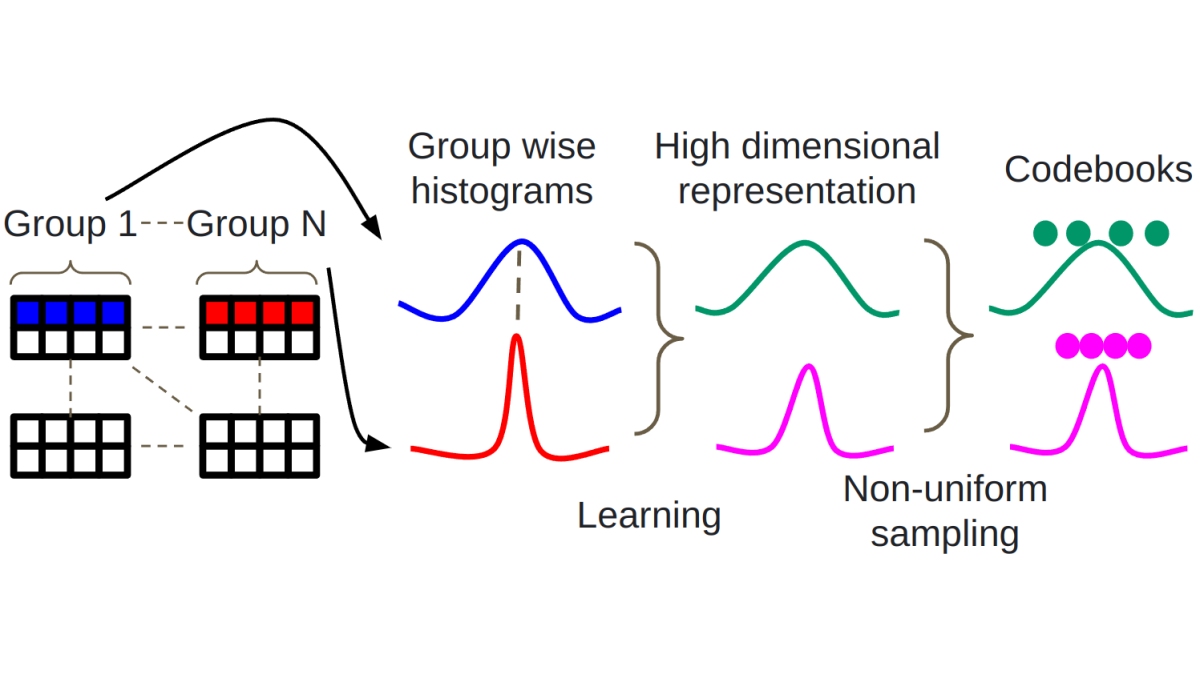
LLM Inference with Codebook-based Q4X Quantization using the Llama.cpp ...
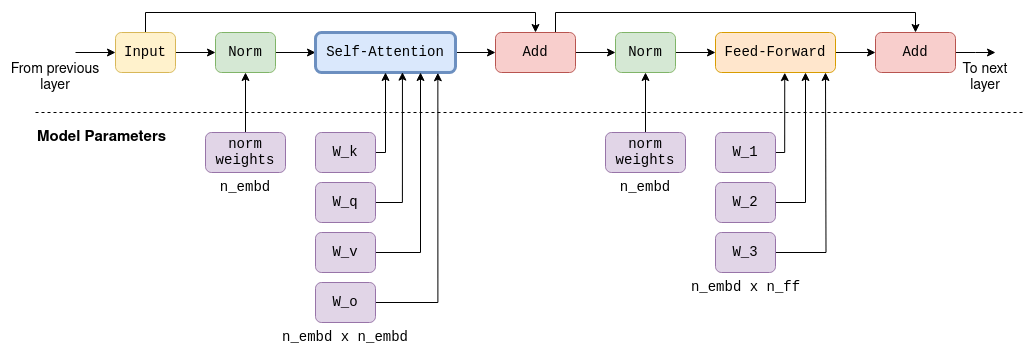
Understanding how LLM inference works with llama.cpp
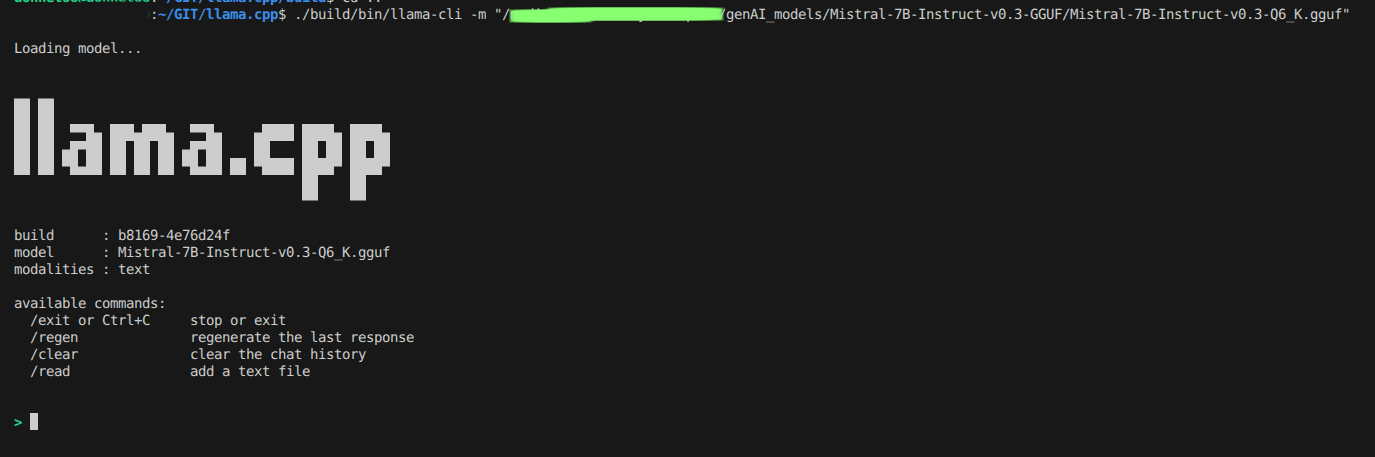
Just another post of local LLM models

Open Inference Engine Comparison | Features and Functionality of TGI ...
Advertisement Space (336x280)

TurboQuant 在 llama.cpp 的进展 — Issue #20977、PR #21089 与 tbq3_0 ...

AILAB Blog: Distributed Inference with Llama.cpp: A New Era of Multi ...
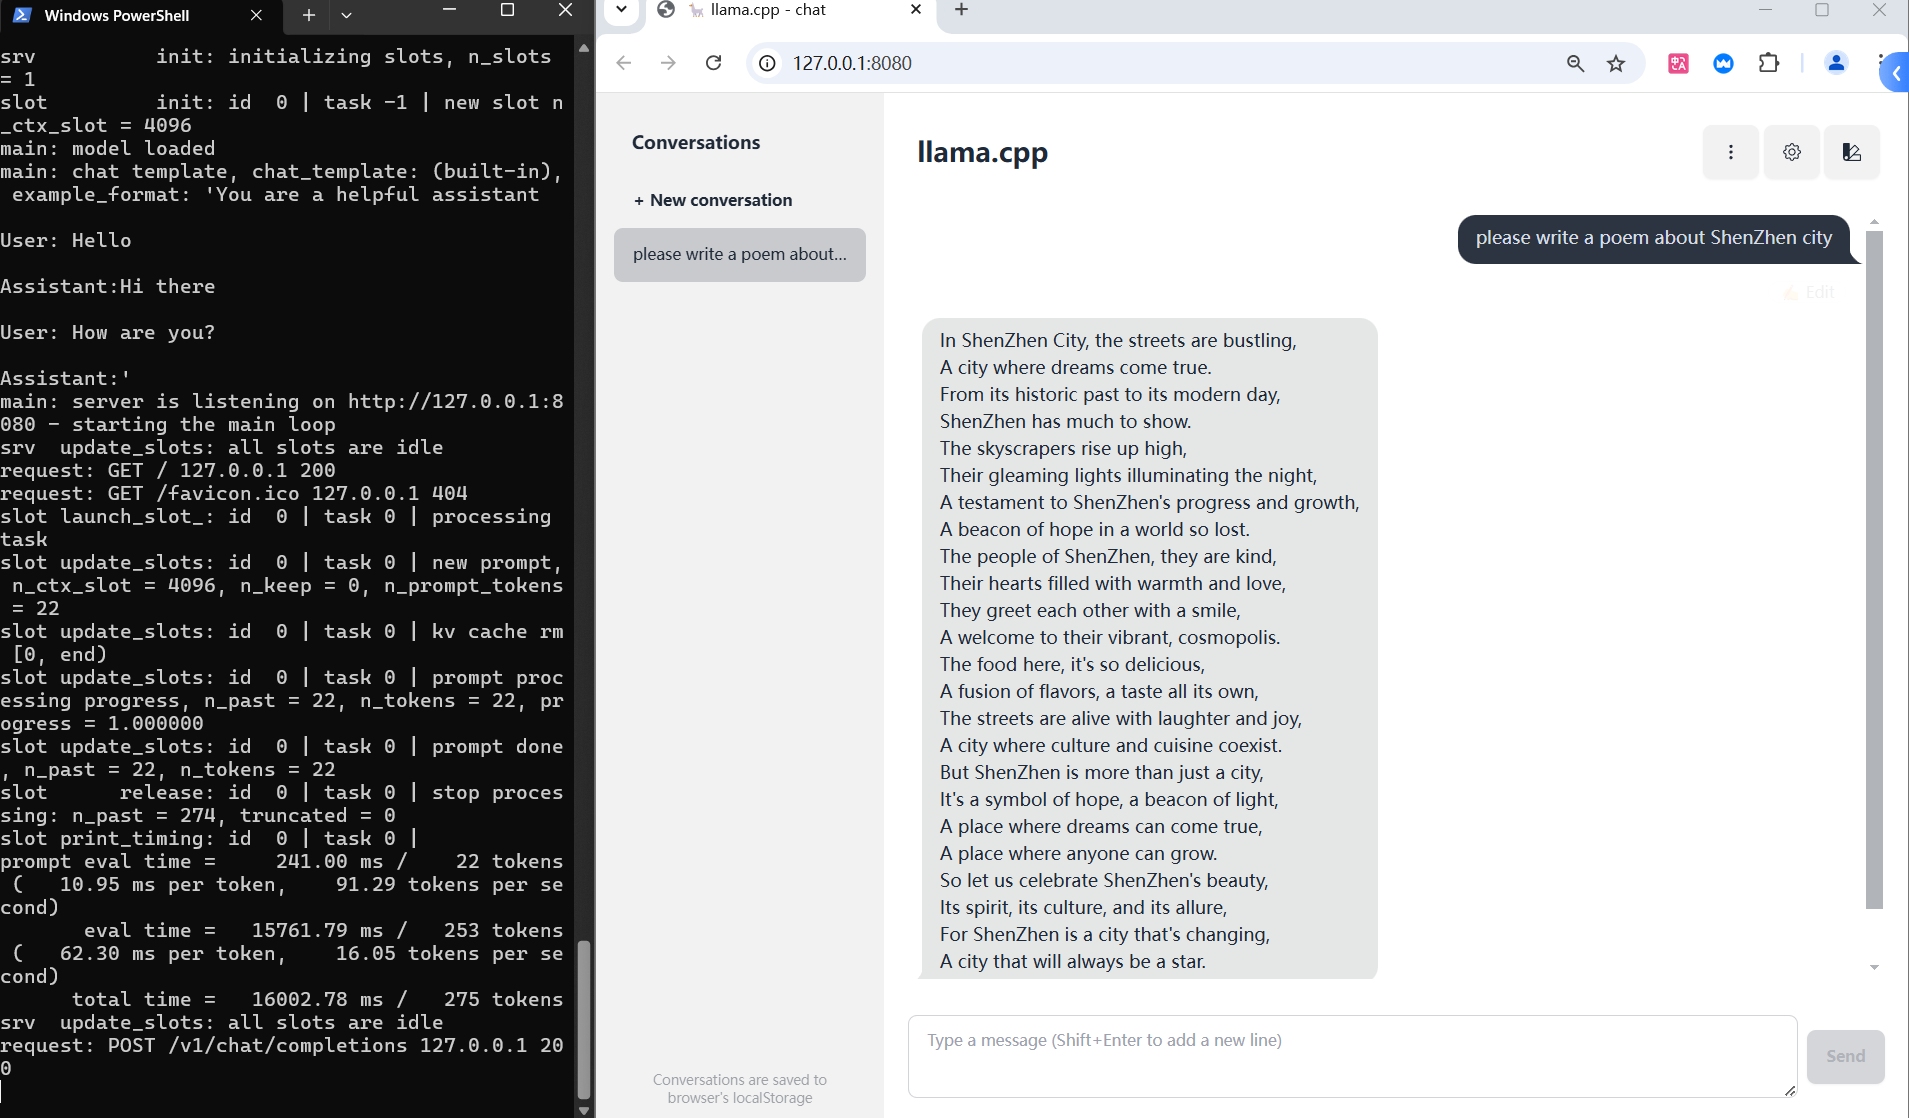
llama.cpp Inference
Core Inference Engine | spiritbuun/llama-cpp-turboquant-cuda | DeepWiki
turboquant by 0xSero - SourcePulse

Google Just Dropped TurboQuant — And It Changes Everything for Local ...