
Github Thudmindexcache Indexcache Accelerating Sparse Attention
GitHub - THUDM/IndexCache: IndexCache: Accelerating Sparse Attention ...
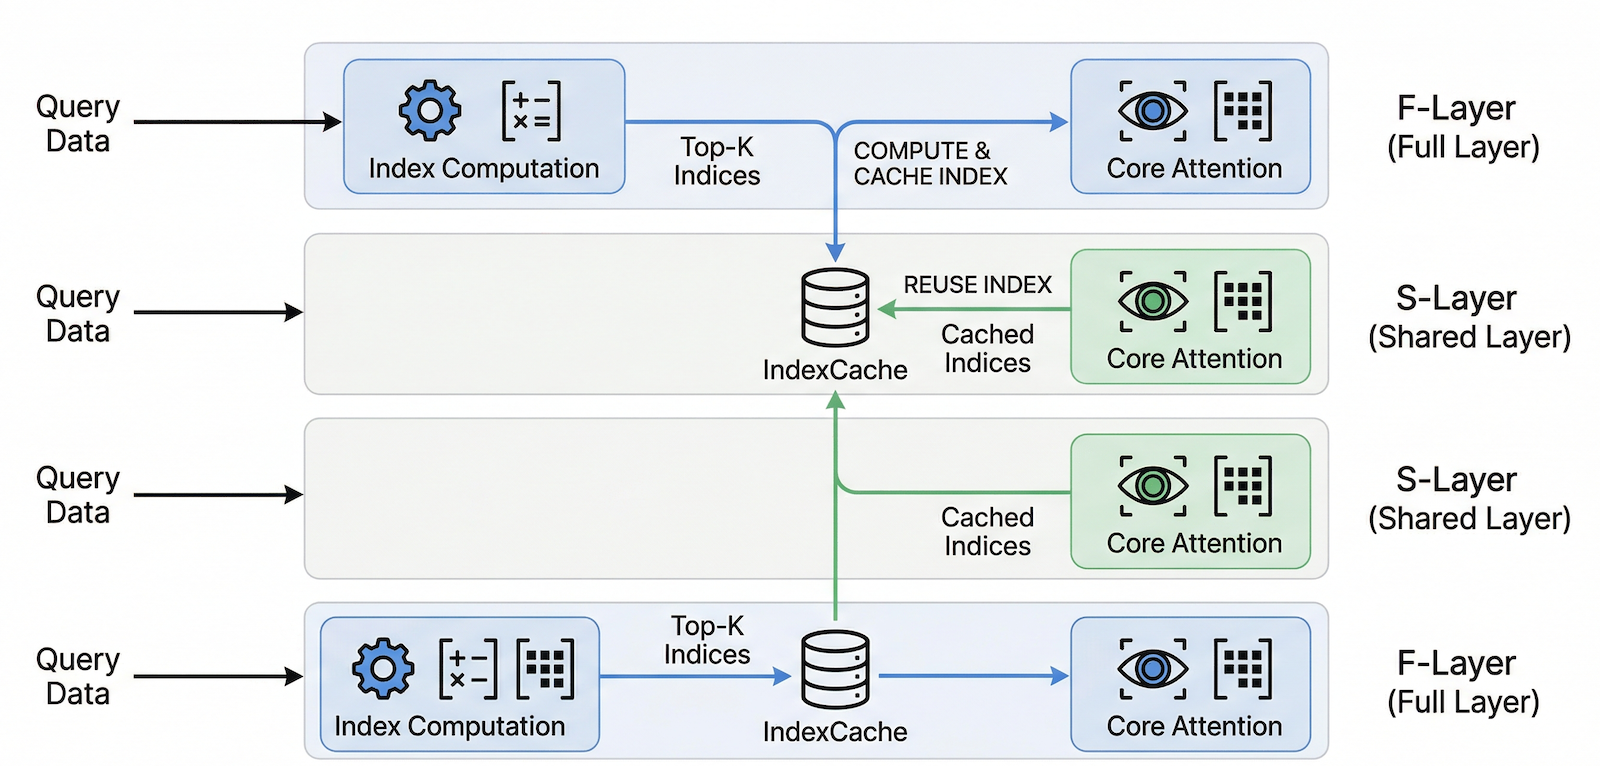
IndexCache turbocharges sparse attention speeds | NodeDrift

IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse ...

IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse

IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse ...

IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse

IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse
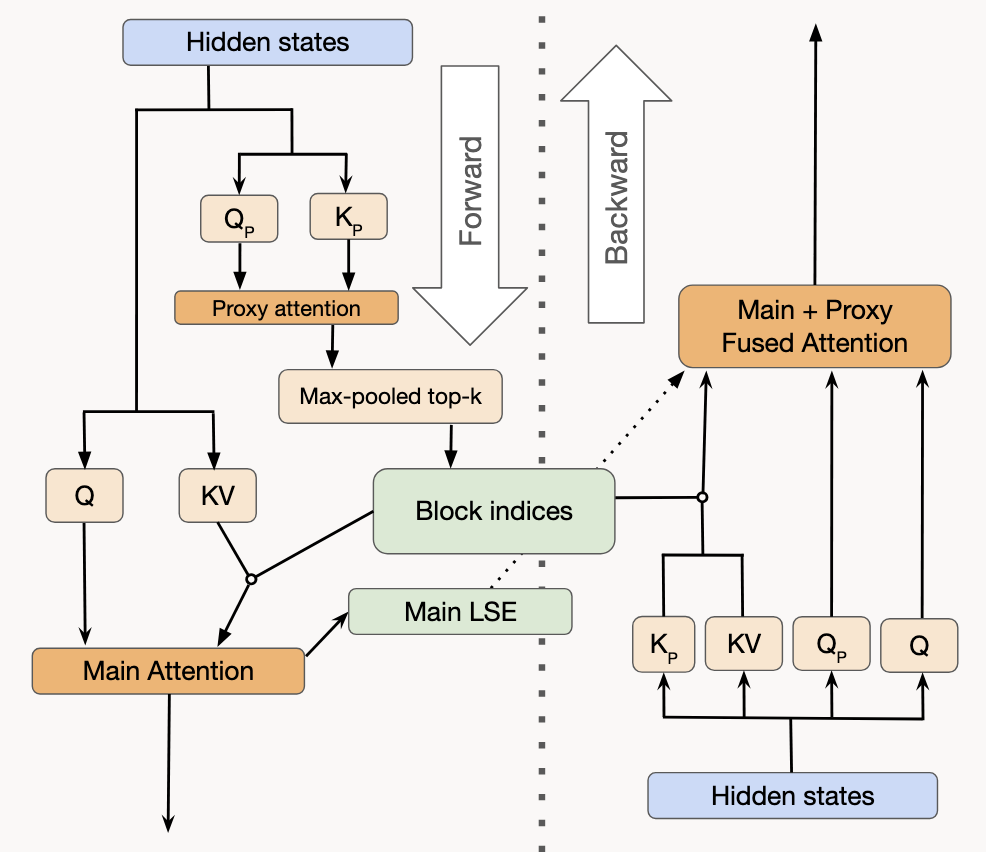
Flash-MSA: Accelerating Million-Token Training With Sparse Attention ...

Paper page - IndexCache: Accelerating Sparse Attention via Cross-Layer ...

Accelerating Text-to-Video Generation with Calibrated Sparse Attention
Advertisement Space (300x250)
IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse ...
IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse ...

IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse ...
GitHub - mit-han-lab/Block-Sparse-Attention: A sparse attention kernel ...

IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse ...

Paper page - IndexCache: Accelerating Sparse Attention via Cross-Layer ...

VecAttention: Vector-wise Sparse Attention for Accelerating Long ...

SpargeAttn: Accurate Sparse Attention Accelerating Any Model Inference ...
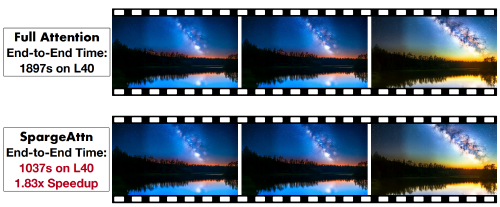
SpargeAttn: Accurate Sparse Attention Accelerating Any Model Inference
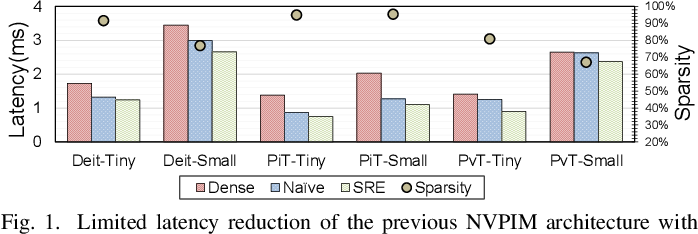
Figure 1 from Accelerating Sparse Attention with a Reconfigurable Non ...
Advertisement Space (336x280)
GitHub - openai/sparse_attention: Examples of using sparse attention ...

AI Sparse Attention Still Had a Hidden Long-Context Tax - And ...
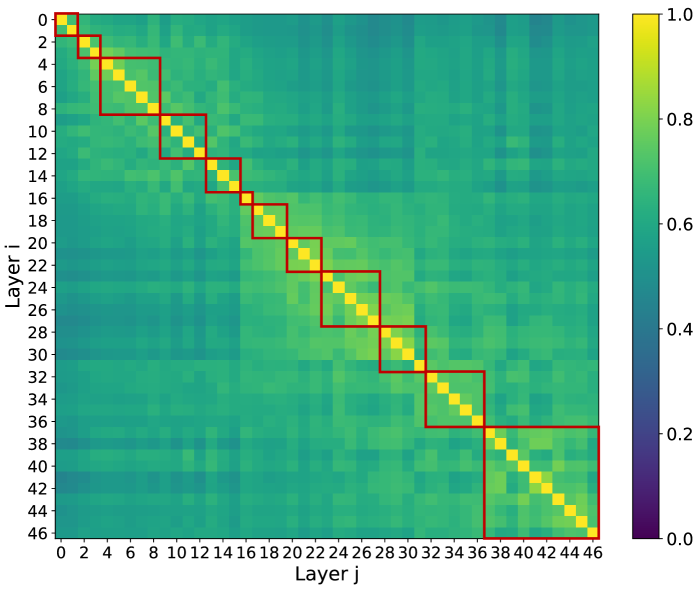
IndexCache:跨层索引复用,让稀疏注意力推理再快一倍_indexcache: accelerating sparse ...
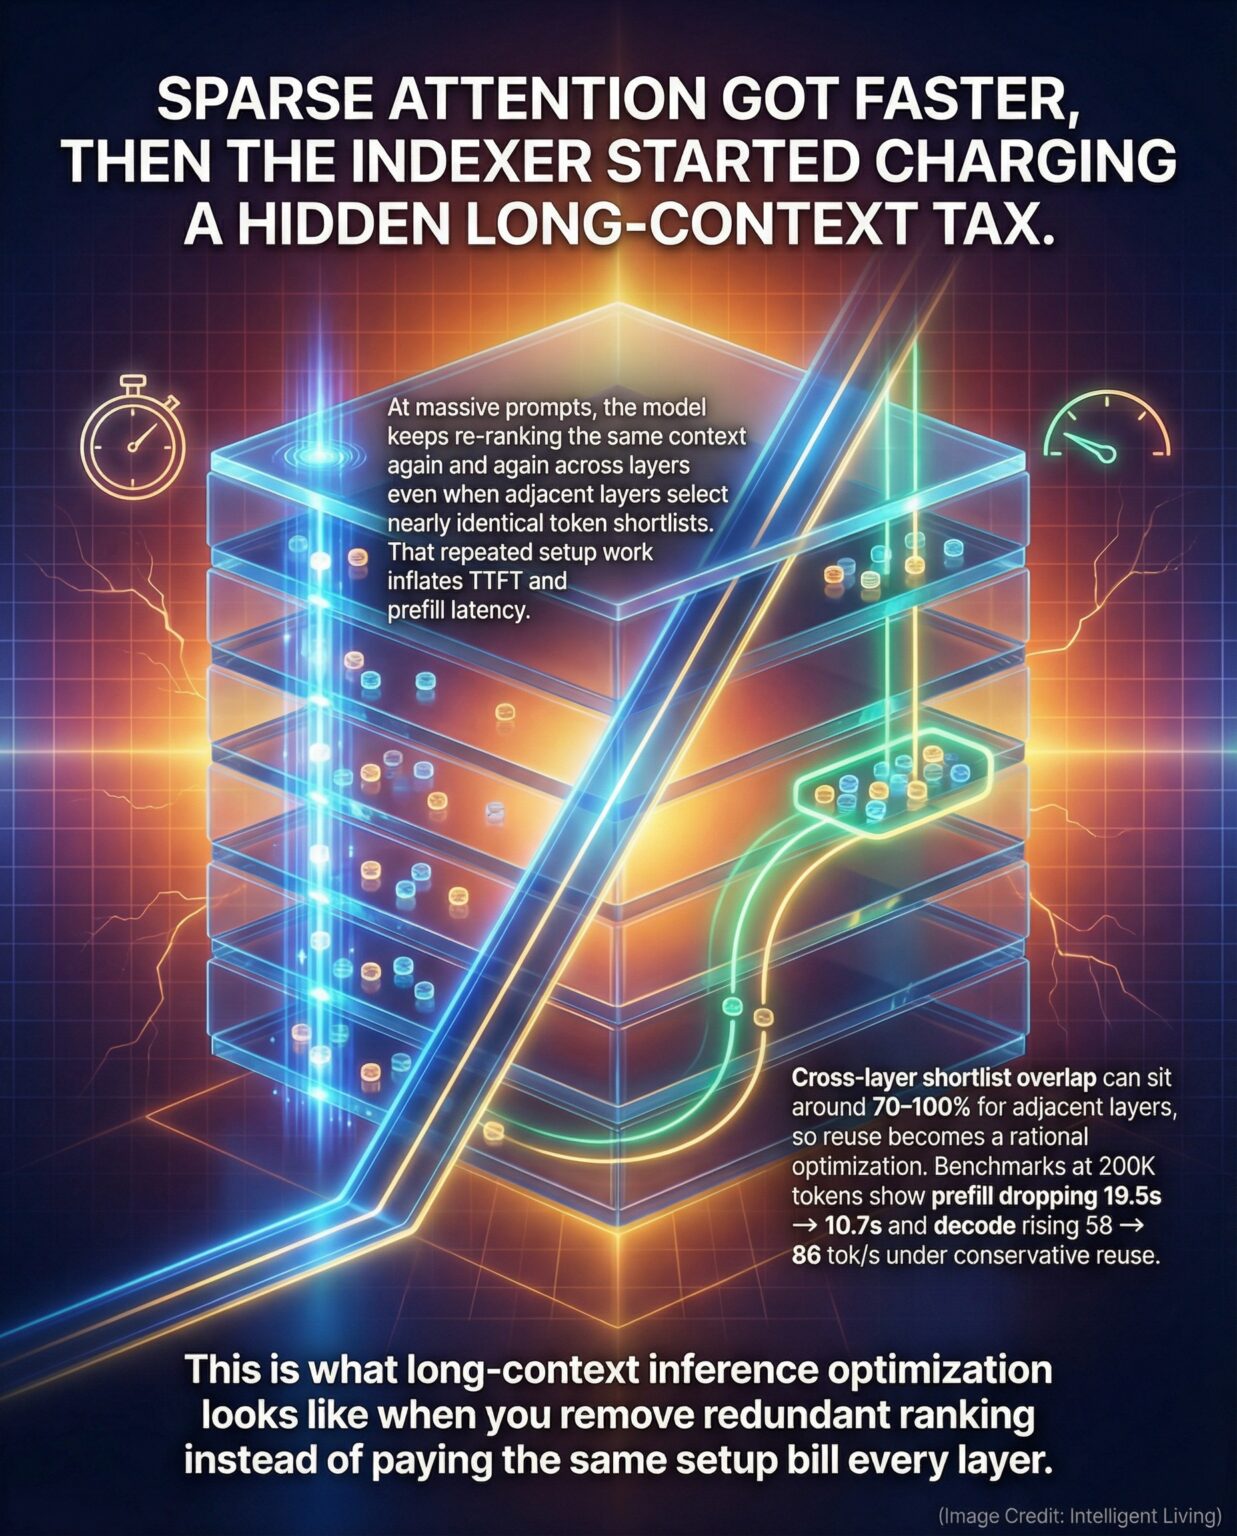
AI Sparse Attention Still Had a Hidden Long-Context Tax - And ...
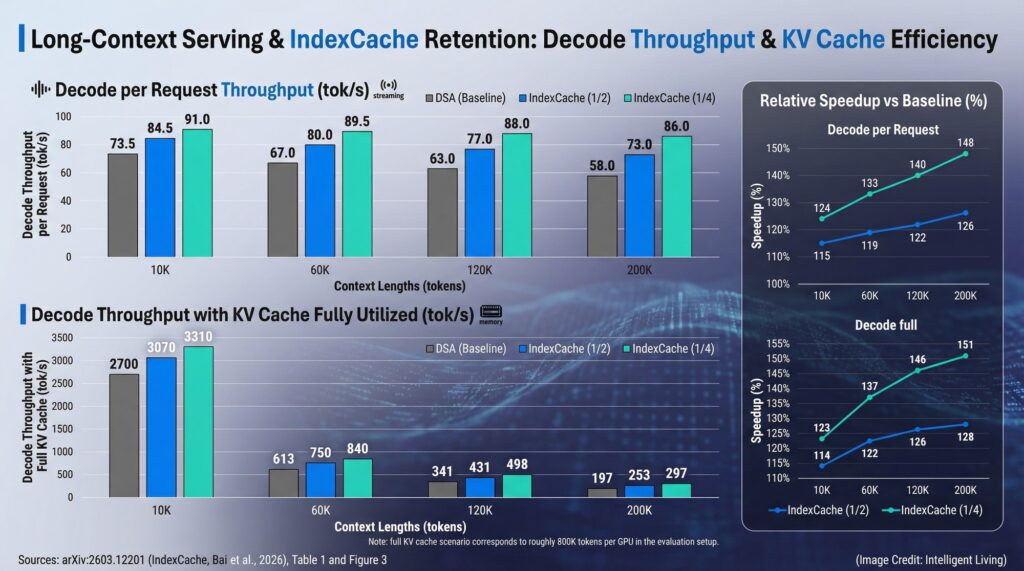
AI Sparse Attention Still Had a Hidden Long-Context Tax - And ...
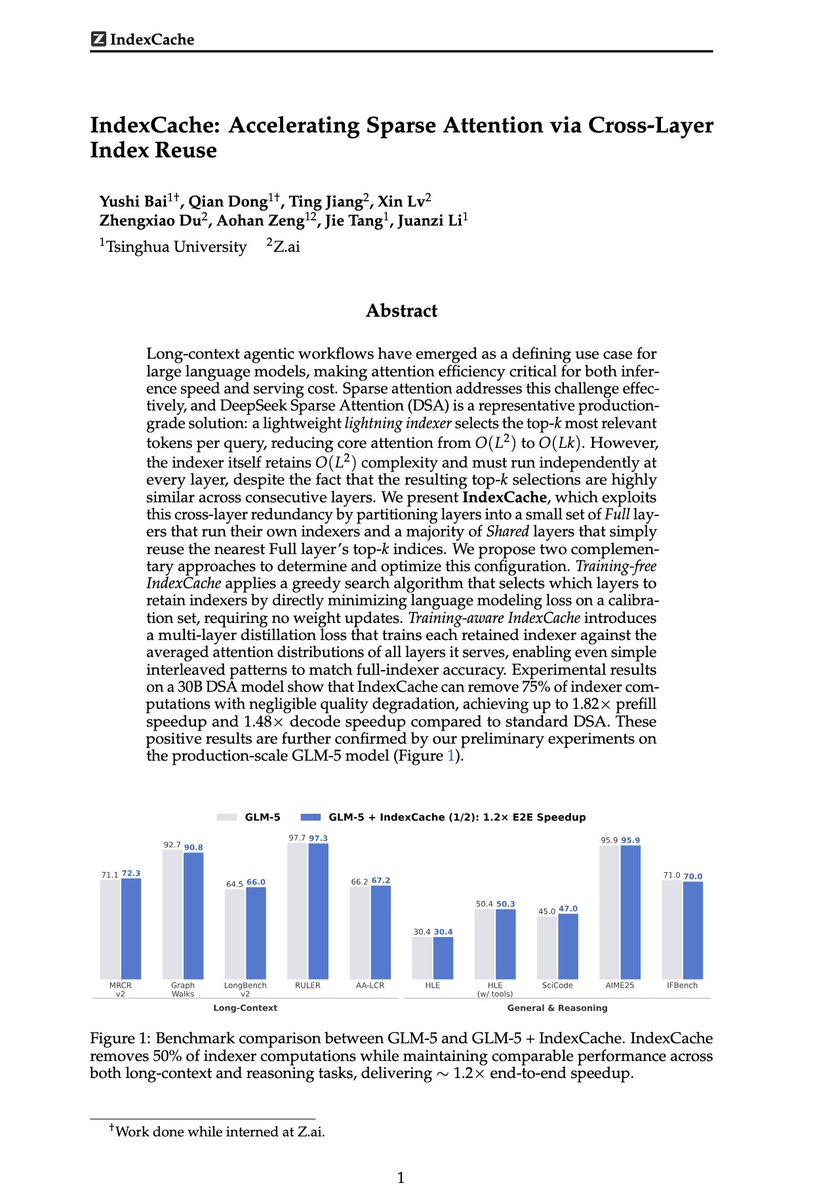
A really cool paper from @Zai_org "IndexCache: Accelerating Sparse ...

Sparse VideoGen2: Accelerate Video Generation with Sparse Attention via ...

IndexCache, a new sparse attention optimizer, delivers 1.82x faster ...
Sparse Attention Framework | ModelEngine-Group/unified-cache-management ...
GitHub - xgbj/sparse-mask-attention: 高性能短序列稀疏Mask Attention CUDA算子,针对
Advertisement Space (336x280)

GitHub - mit-han-lab/x-attention: [ICML 2025] XAttention: Block Sparse ...
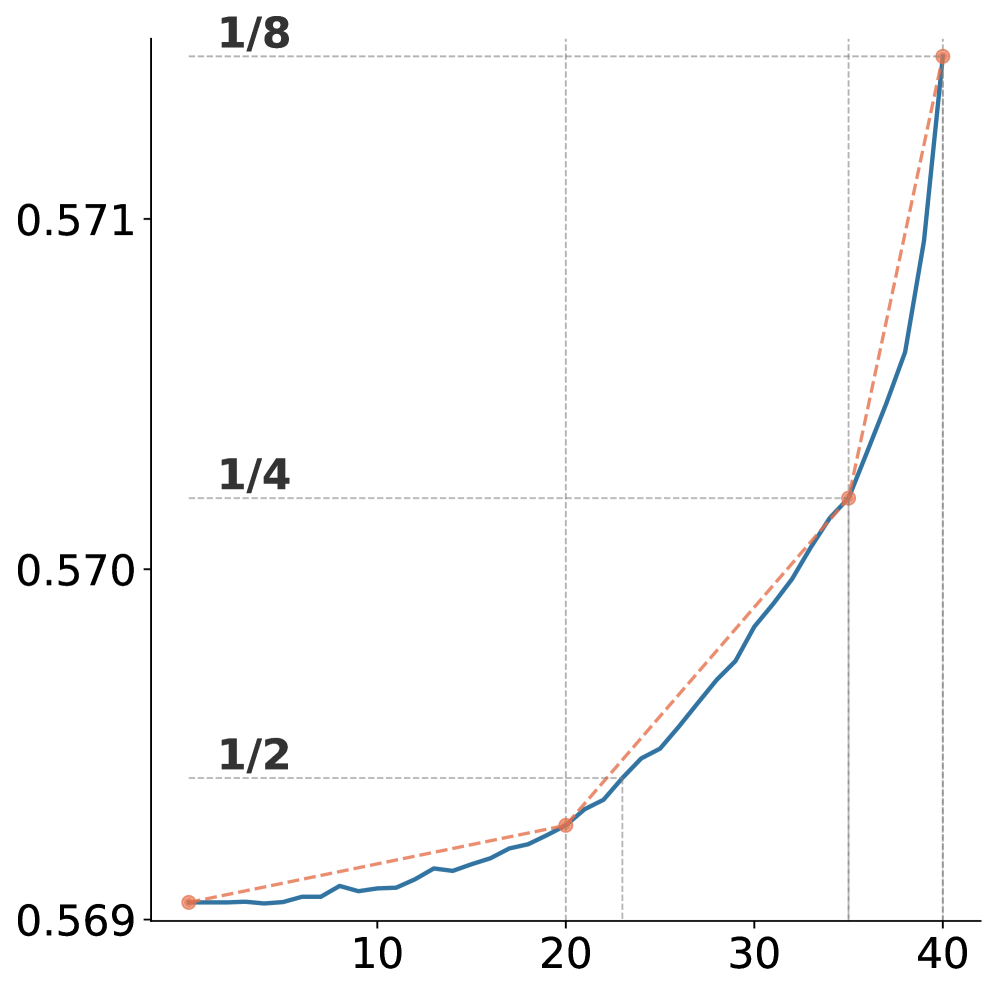
IndexCache:跨层索引复用,让稀疏注意力推理再快一倍_indexcache: accelerating sparse ...
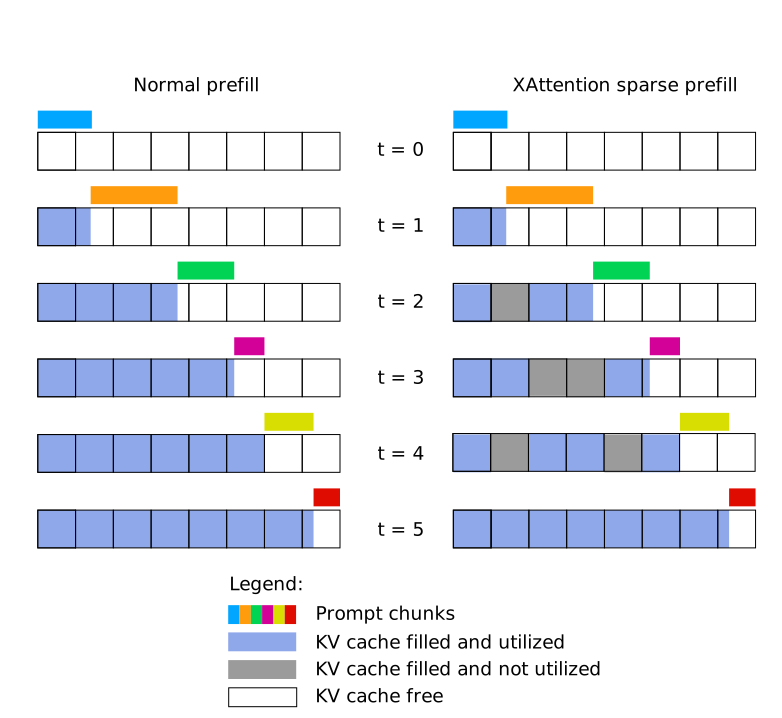
Sparse Attention prefill algorithms | OpenVINO GenAI

Sparse attention 4 -- previous token head | Ziming Liu
IndexCache: The New Sparse Attention Optimizer That Delivers 1.82x ...
GitHub - kyegomez/SparseAttention: Pytorch Implementation of the sparse ...