
How The Vllm Inference Engine Works Youtube

How the vLLM inference engine works? - YouTube

How the VLLM inference engine works? - YouTube
nano-vLLM: The 1,200-Line Inference Engine That Teaches You How vLLM Works

How the vLLM inference engine works? - DevOps Video | Pulse

Learn how LLM inference actually works under the hood. vLLM has 100k ...

How vLLM Works + Journey of Prompts to vLLM + Paged Attention - YouTube
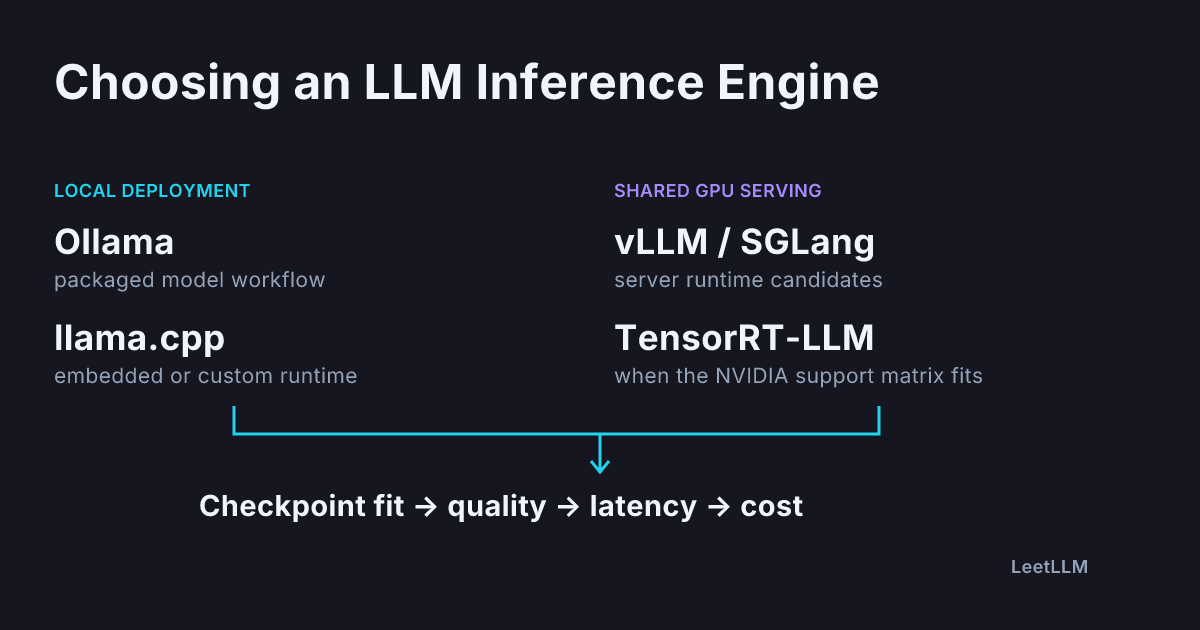
vLLM vs SGLang vs TensorRT-LLM vs Ollama: The 2026 Inference Engine ...

The Rise of vLLM: Building an Open Source LLM Inference Engine - YouTube

VLLM: The Only Inference Engine You Need To Know! - YouTube
SGLang vs vLLM — The New Inference Engine Challenger (2026)
Advertisement Space (300x250)

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...

The Inference Engine - YouTube

How vLLM Became the Standard for Fast AI Inference | Simon Mo, Inferact ...

How LLM Inference Engine Works in 9 Steps | Kartik Kaushik posted on ...

LLMOPS : vLLM Inference LLM Server Engine #machinelearning #datascience ...
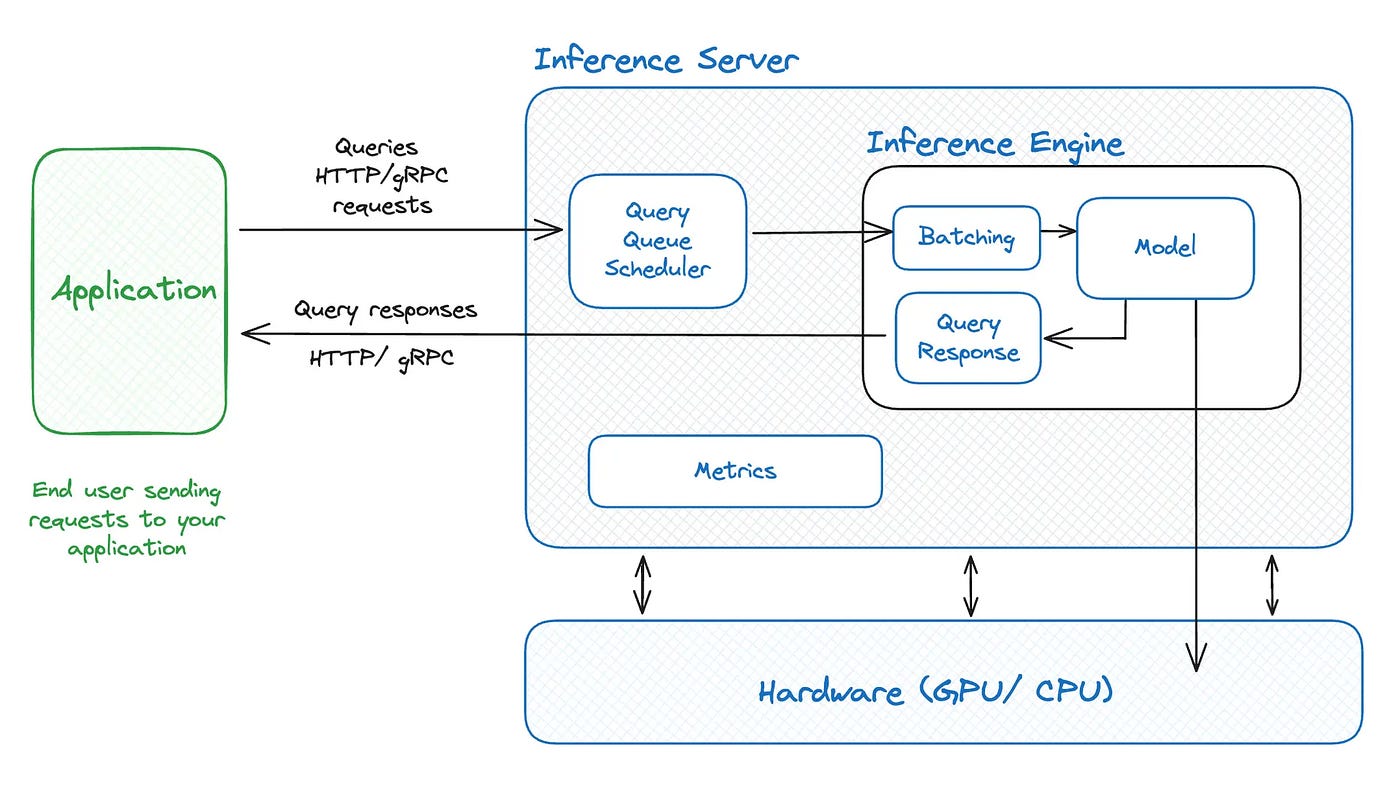
Nano vLLM: A Tiny Inference Engine that Teaches you the Big Ideas ...

vllm turbo charge your llm inference - YouTube

Accelerating LLM Inference with vLLM - YouTube

VLLM Inference Engine | omni-ai-npu/omni-infer | DeepWiki

vLLM vs TensorRT-LLM: Which Inference Engine Should You Use in 2026 ...
Advertisement Space (336x280)
vLLM 2026: Open Source LLM Inference Engine im Detail

vLLM - Inference & Vision Capabilities - [Sub EN] #vllm #ai - YouTube

Paris - meet-up #1 - vLLM & inference - YouTube
Optimize LLM inference with vLLM - YouTube

Serving Online Inference with vLLM API on Vast.ai - YouTube

Accelerating LLM Inference with vLLM (and SGLang) - Ion Stoica - YouTube

vLLM - Turbo Charge your LLM Inference - YouTube

Want to deploy open models using vLLM as the inference engine? We just ...
[Paper Review] vLLM Infernce Engine & KV Cache Managing - YouTube

vLLM Inference Engine Boosts AI App Performance | SwathiLakshmi B ...
Advertisement Space (336x280)

Getting Started with vLLM (Llama 3 Inference for Dummies) - YouTube

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

The Rise of vLLM in Modern Cloud Development: Revolutionizing AI Inference
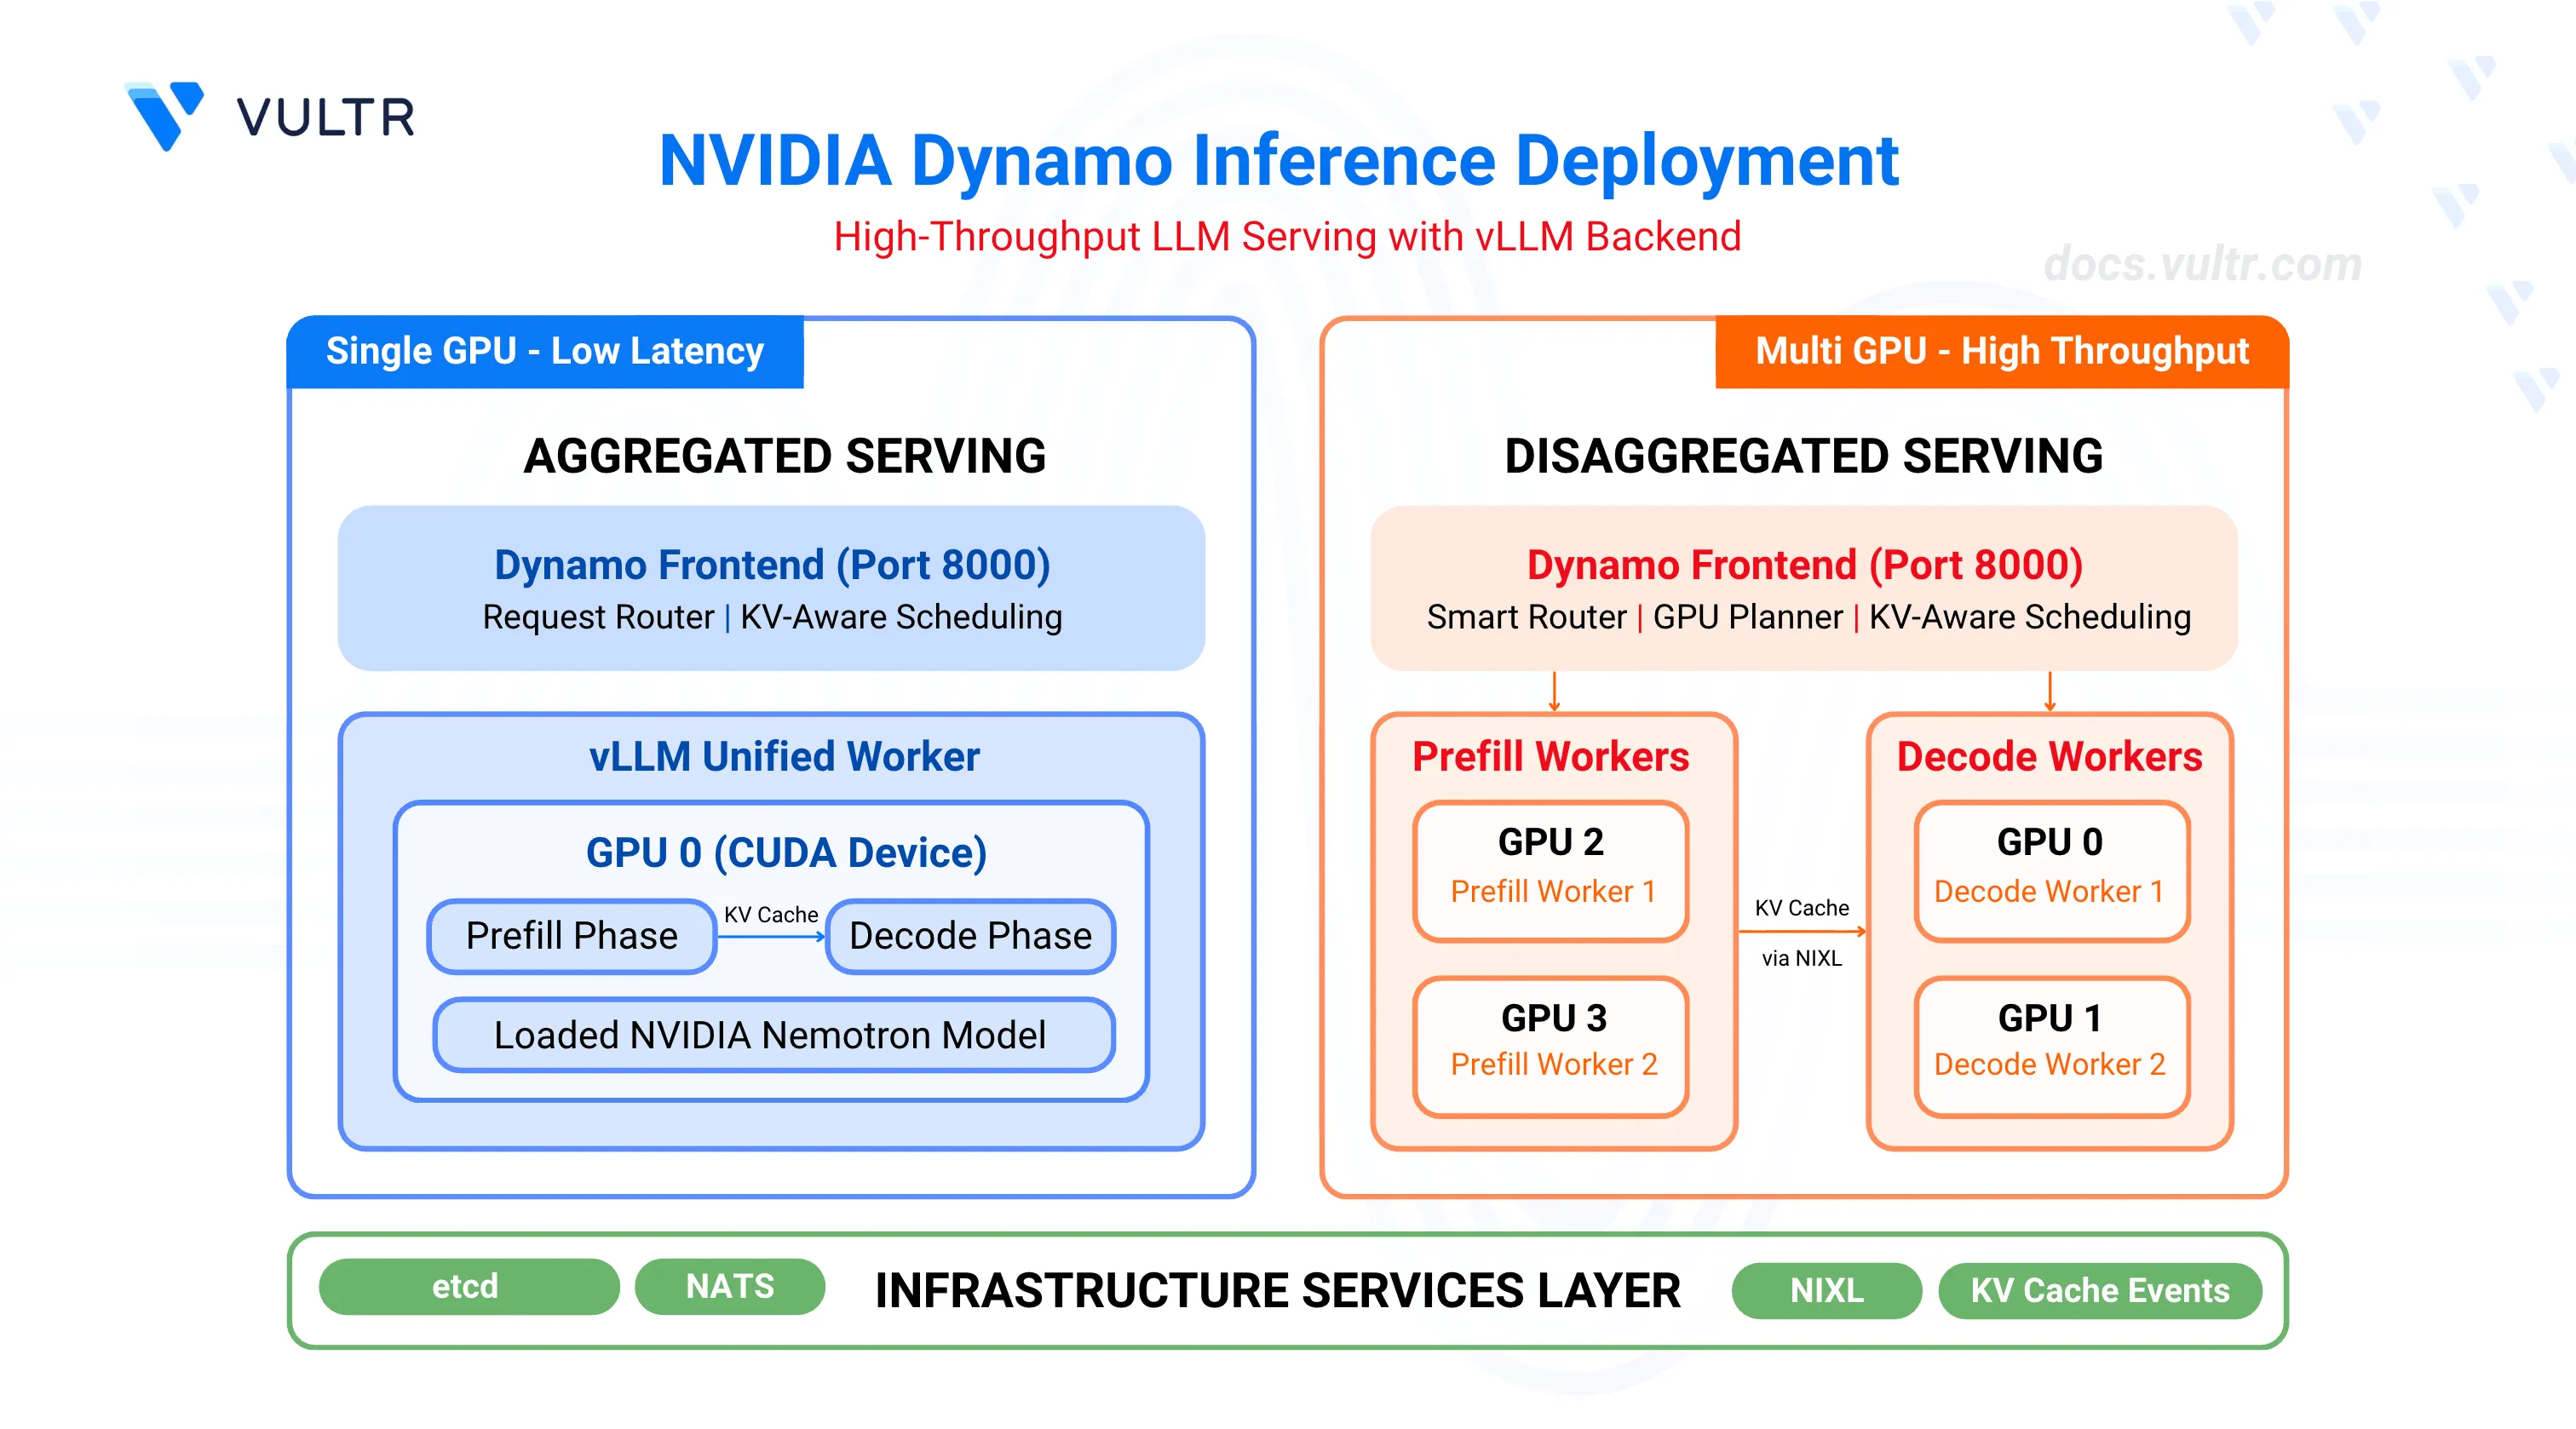
How to Deploy Inference Using NVIDIA Dynamo and vLLM | Vultr Docs

How Ray and vLLM work together for LLM inference | Robert Nishihara ...
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...