
How To Deploy Inference Using Nvidia Dynamo And Vllm Vultr Docs
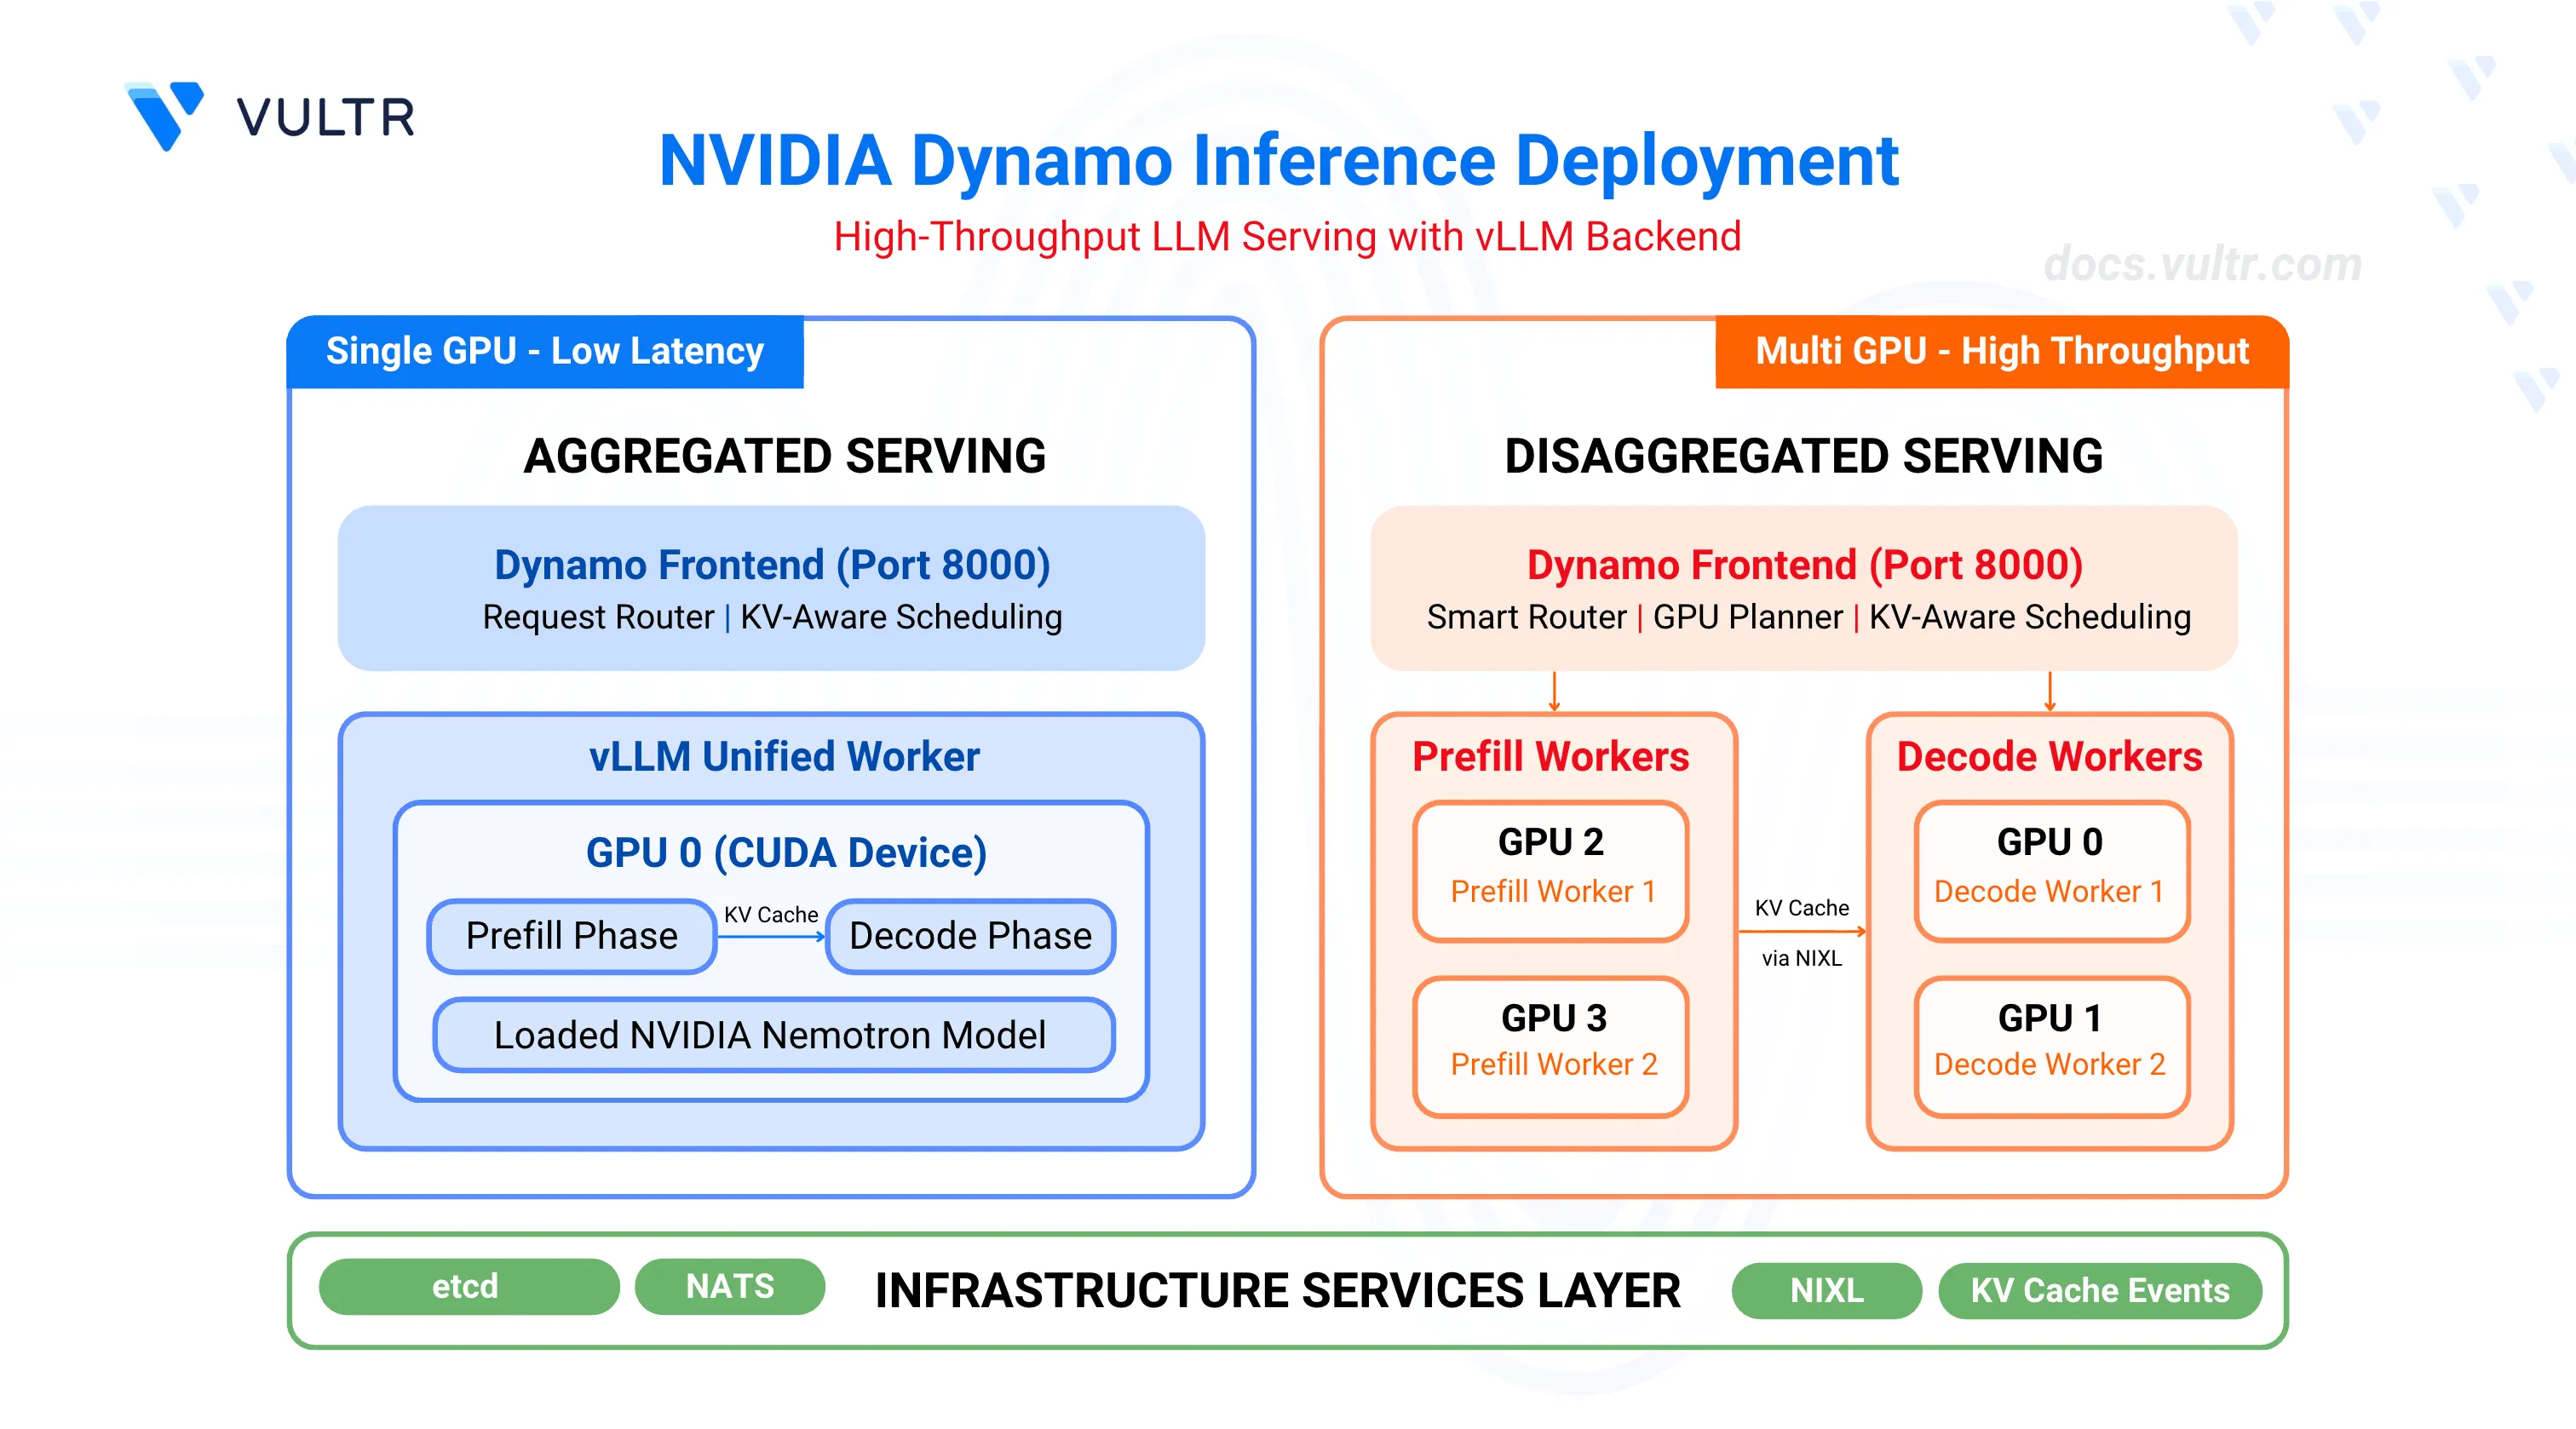
How to Deploy Inference Using NVIDIA Dynamo and vLLM | Vultr Docs
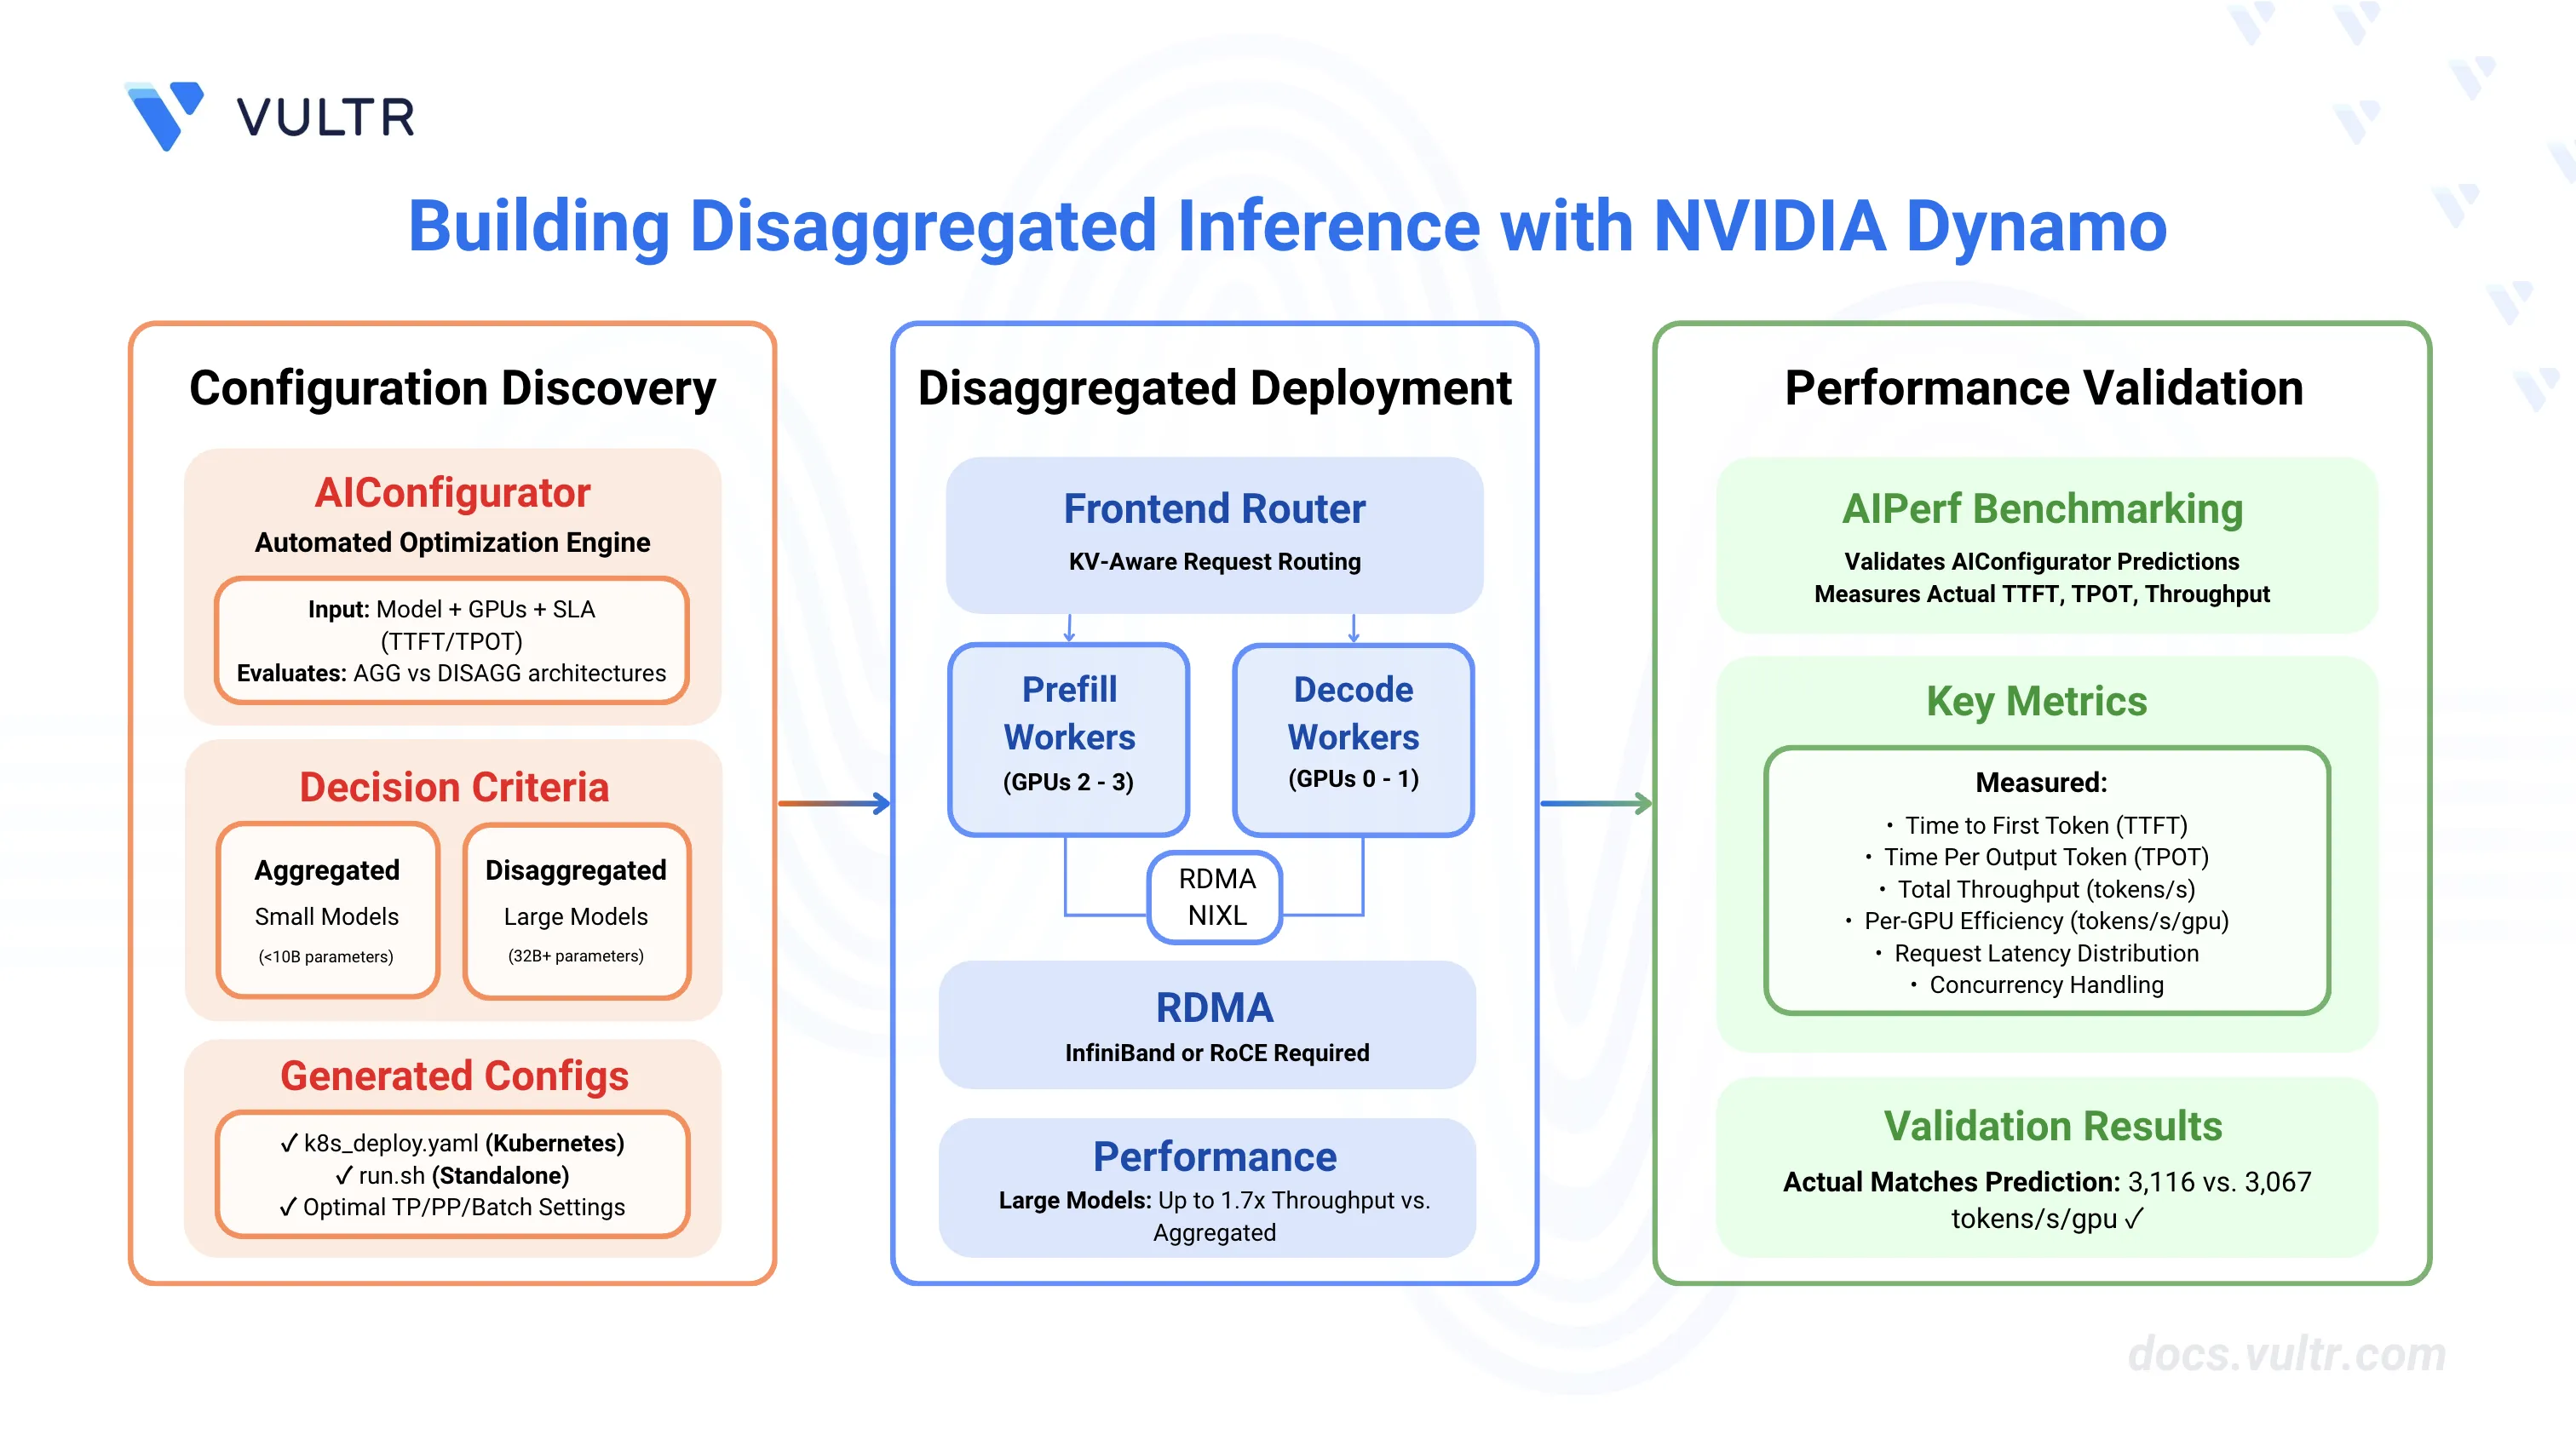
How to Build Disaggregated Inference with NVIDIA Dynamo | Vultr Docs
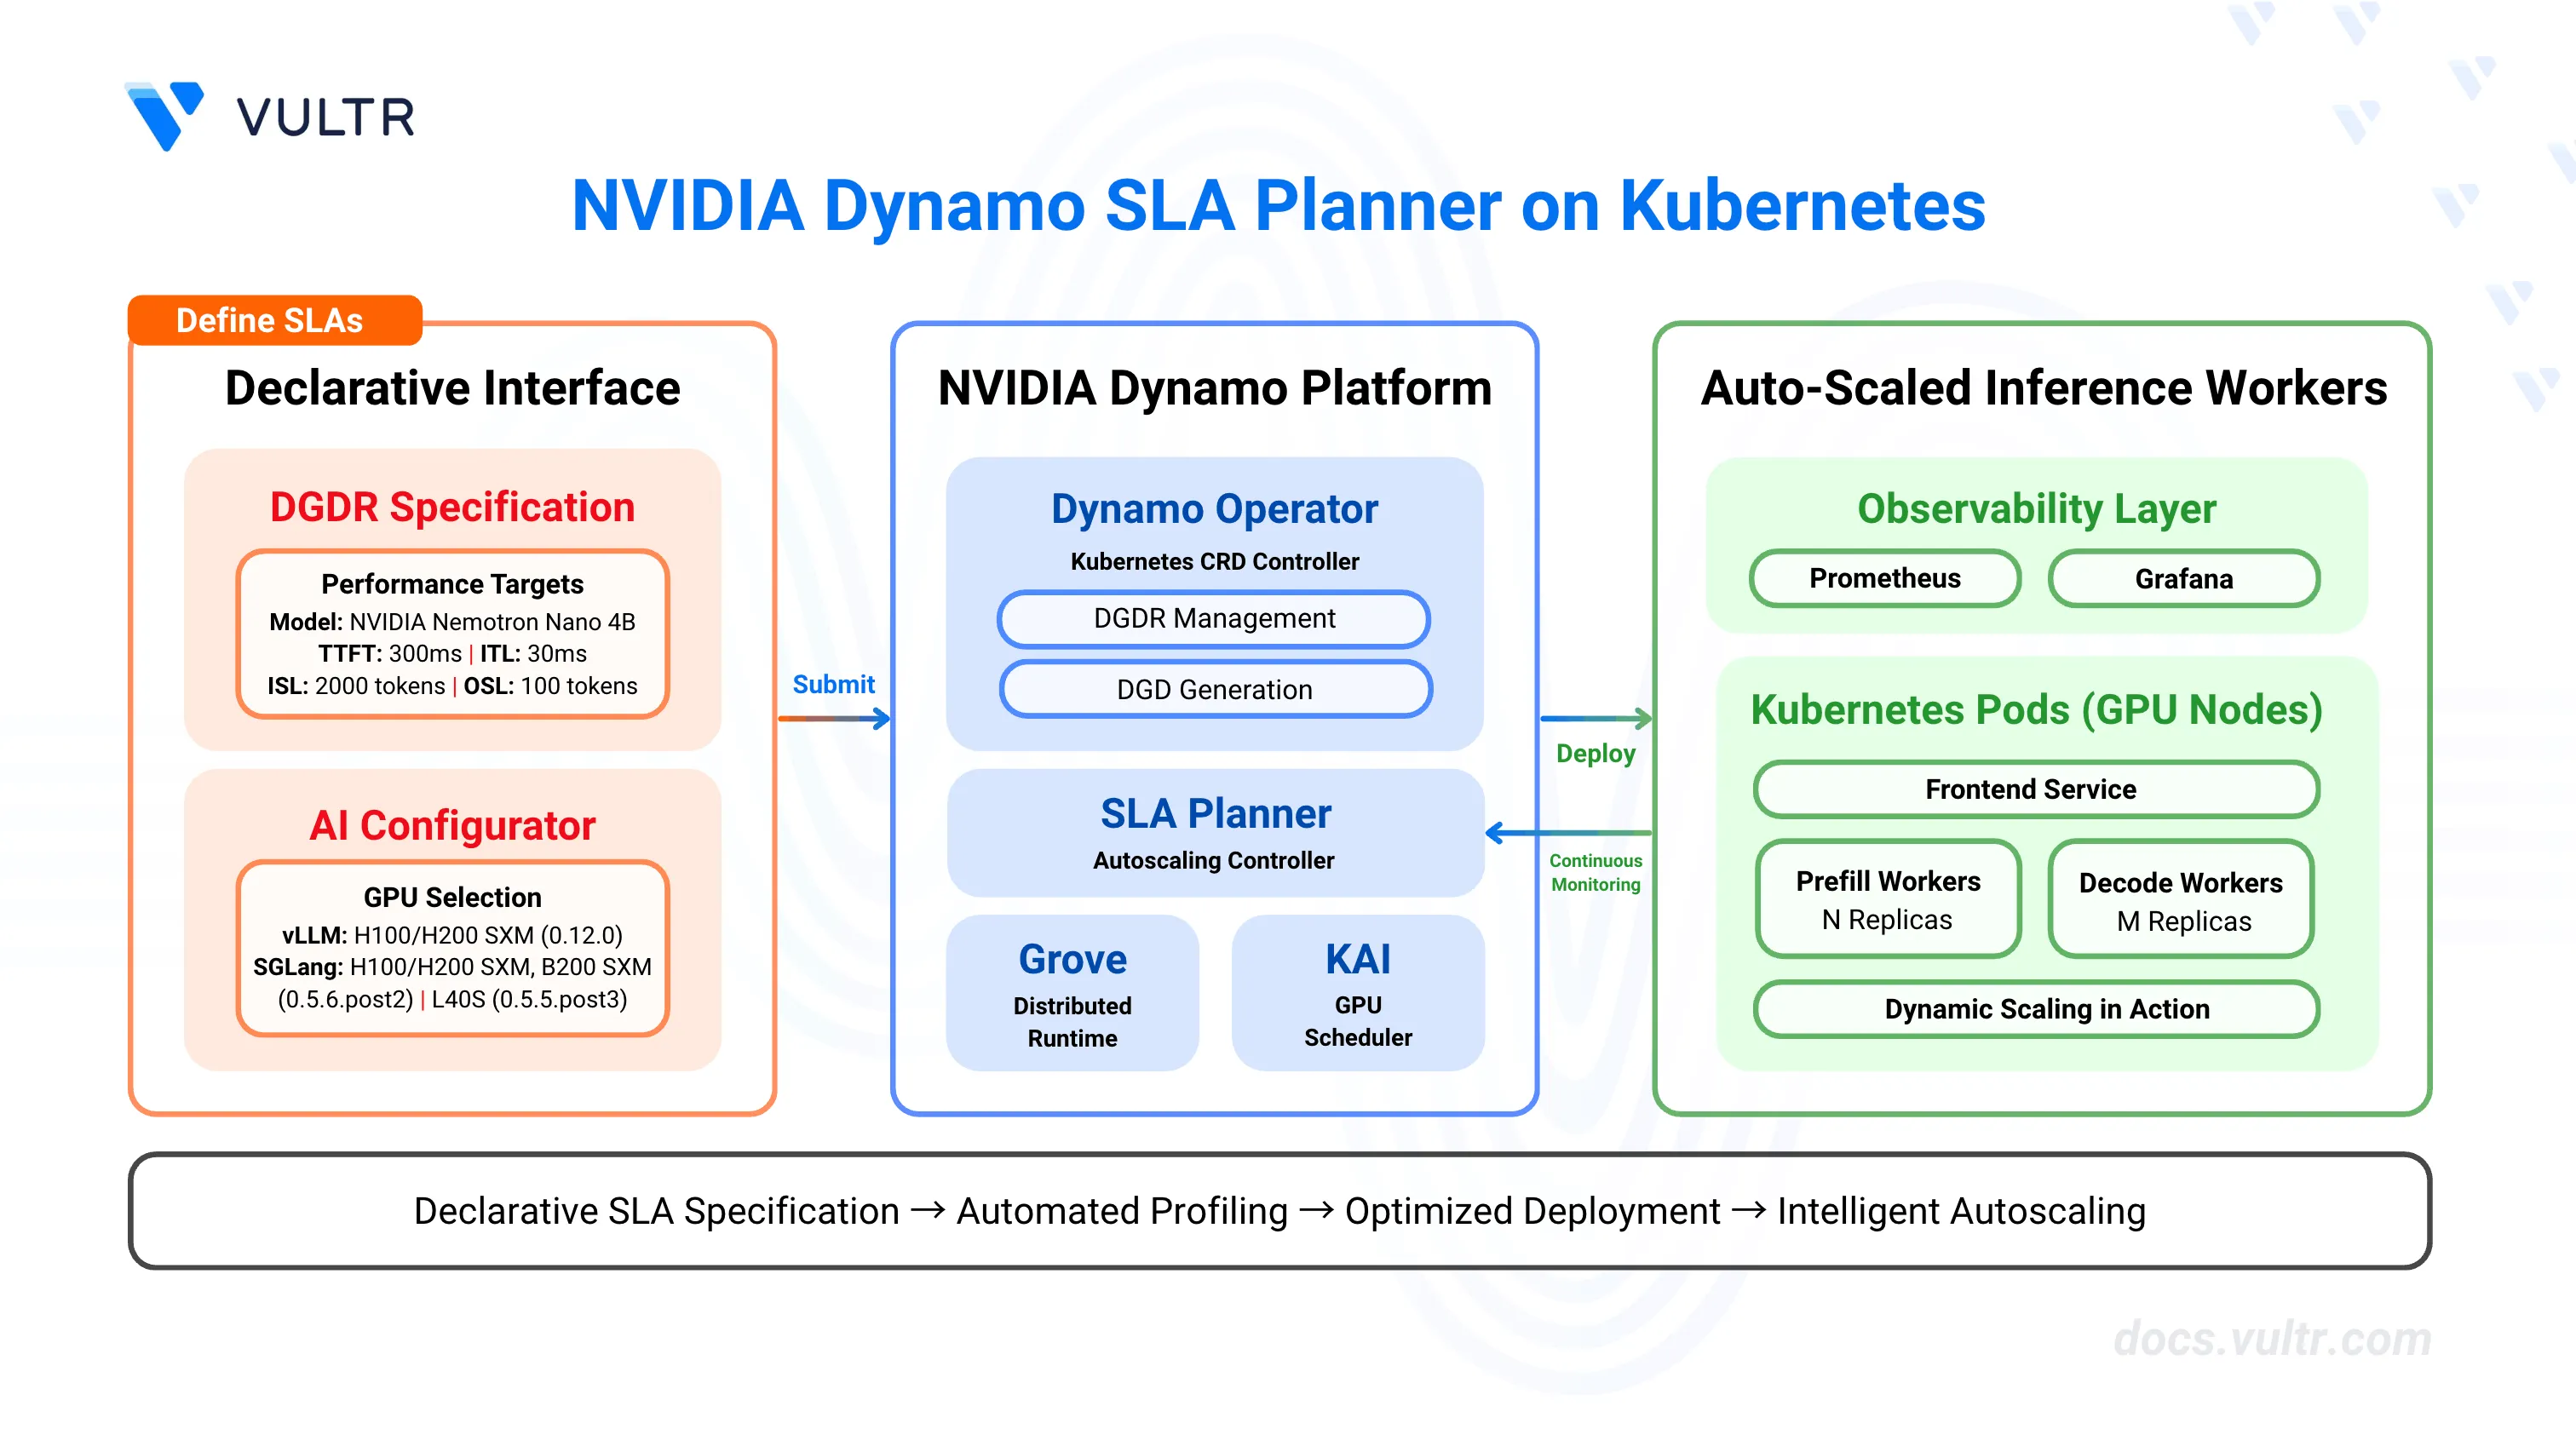
How to Optimize GPU Resource Planning with NVIDIA Dynamo | Vultr Docs
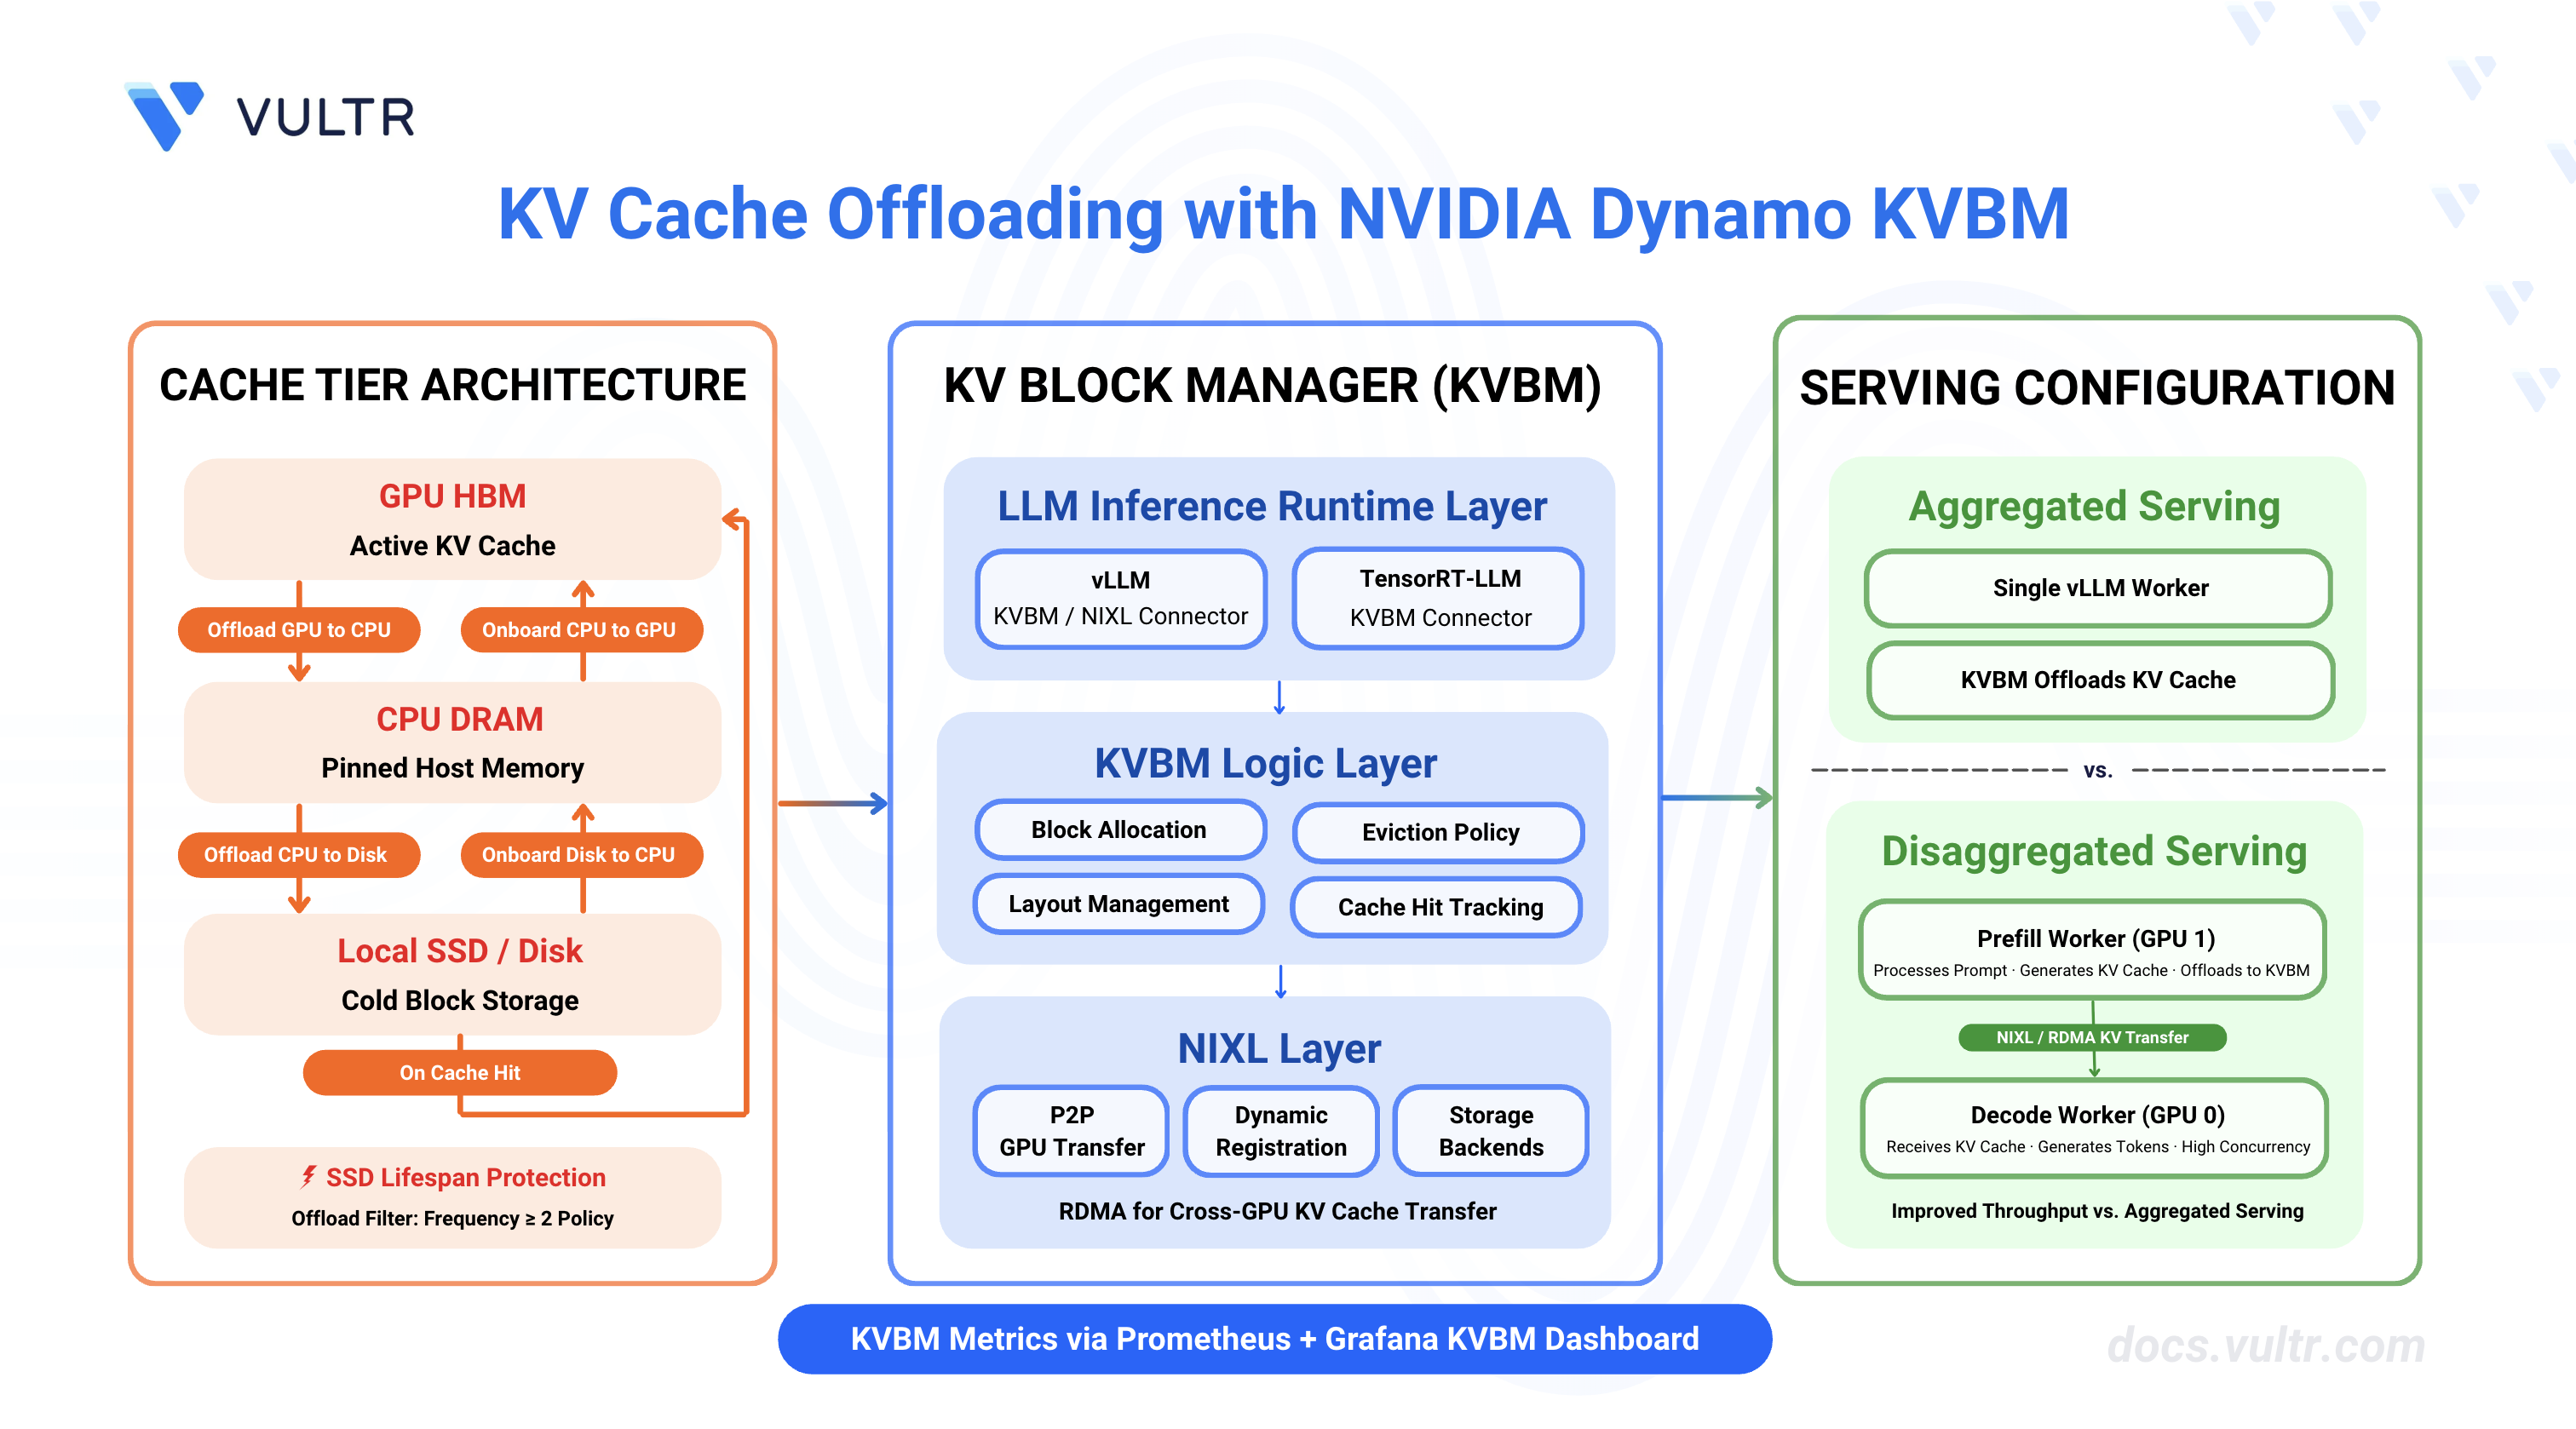
How to Manage KV Cache in NVIDIA Dynamo | Vultr Docs
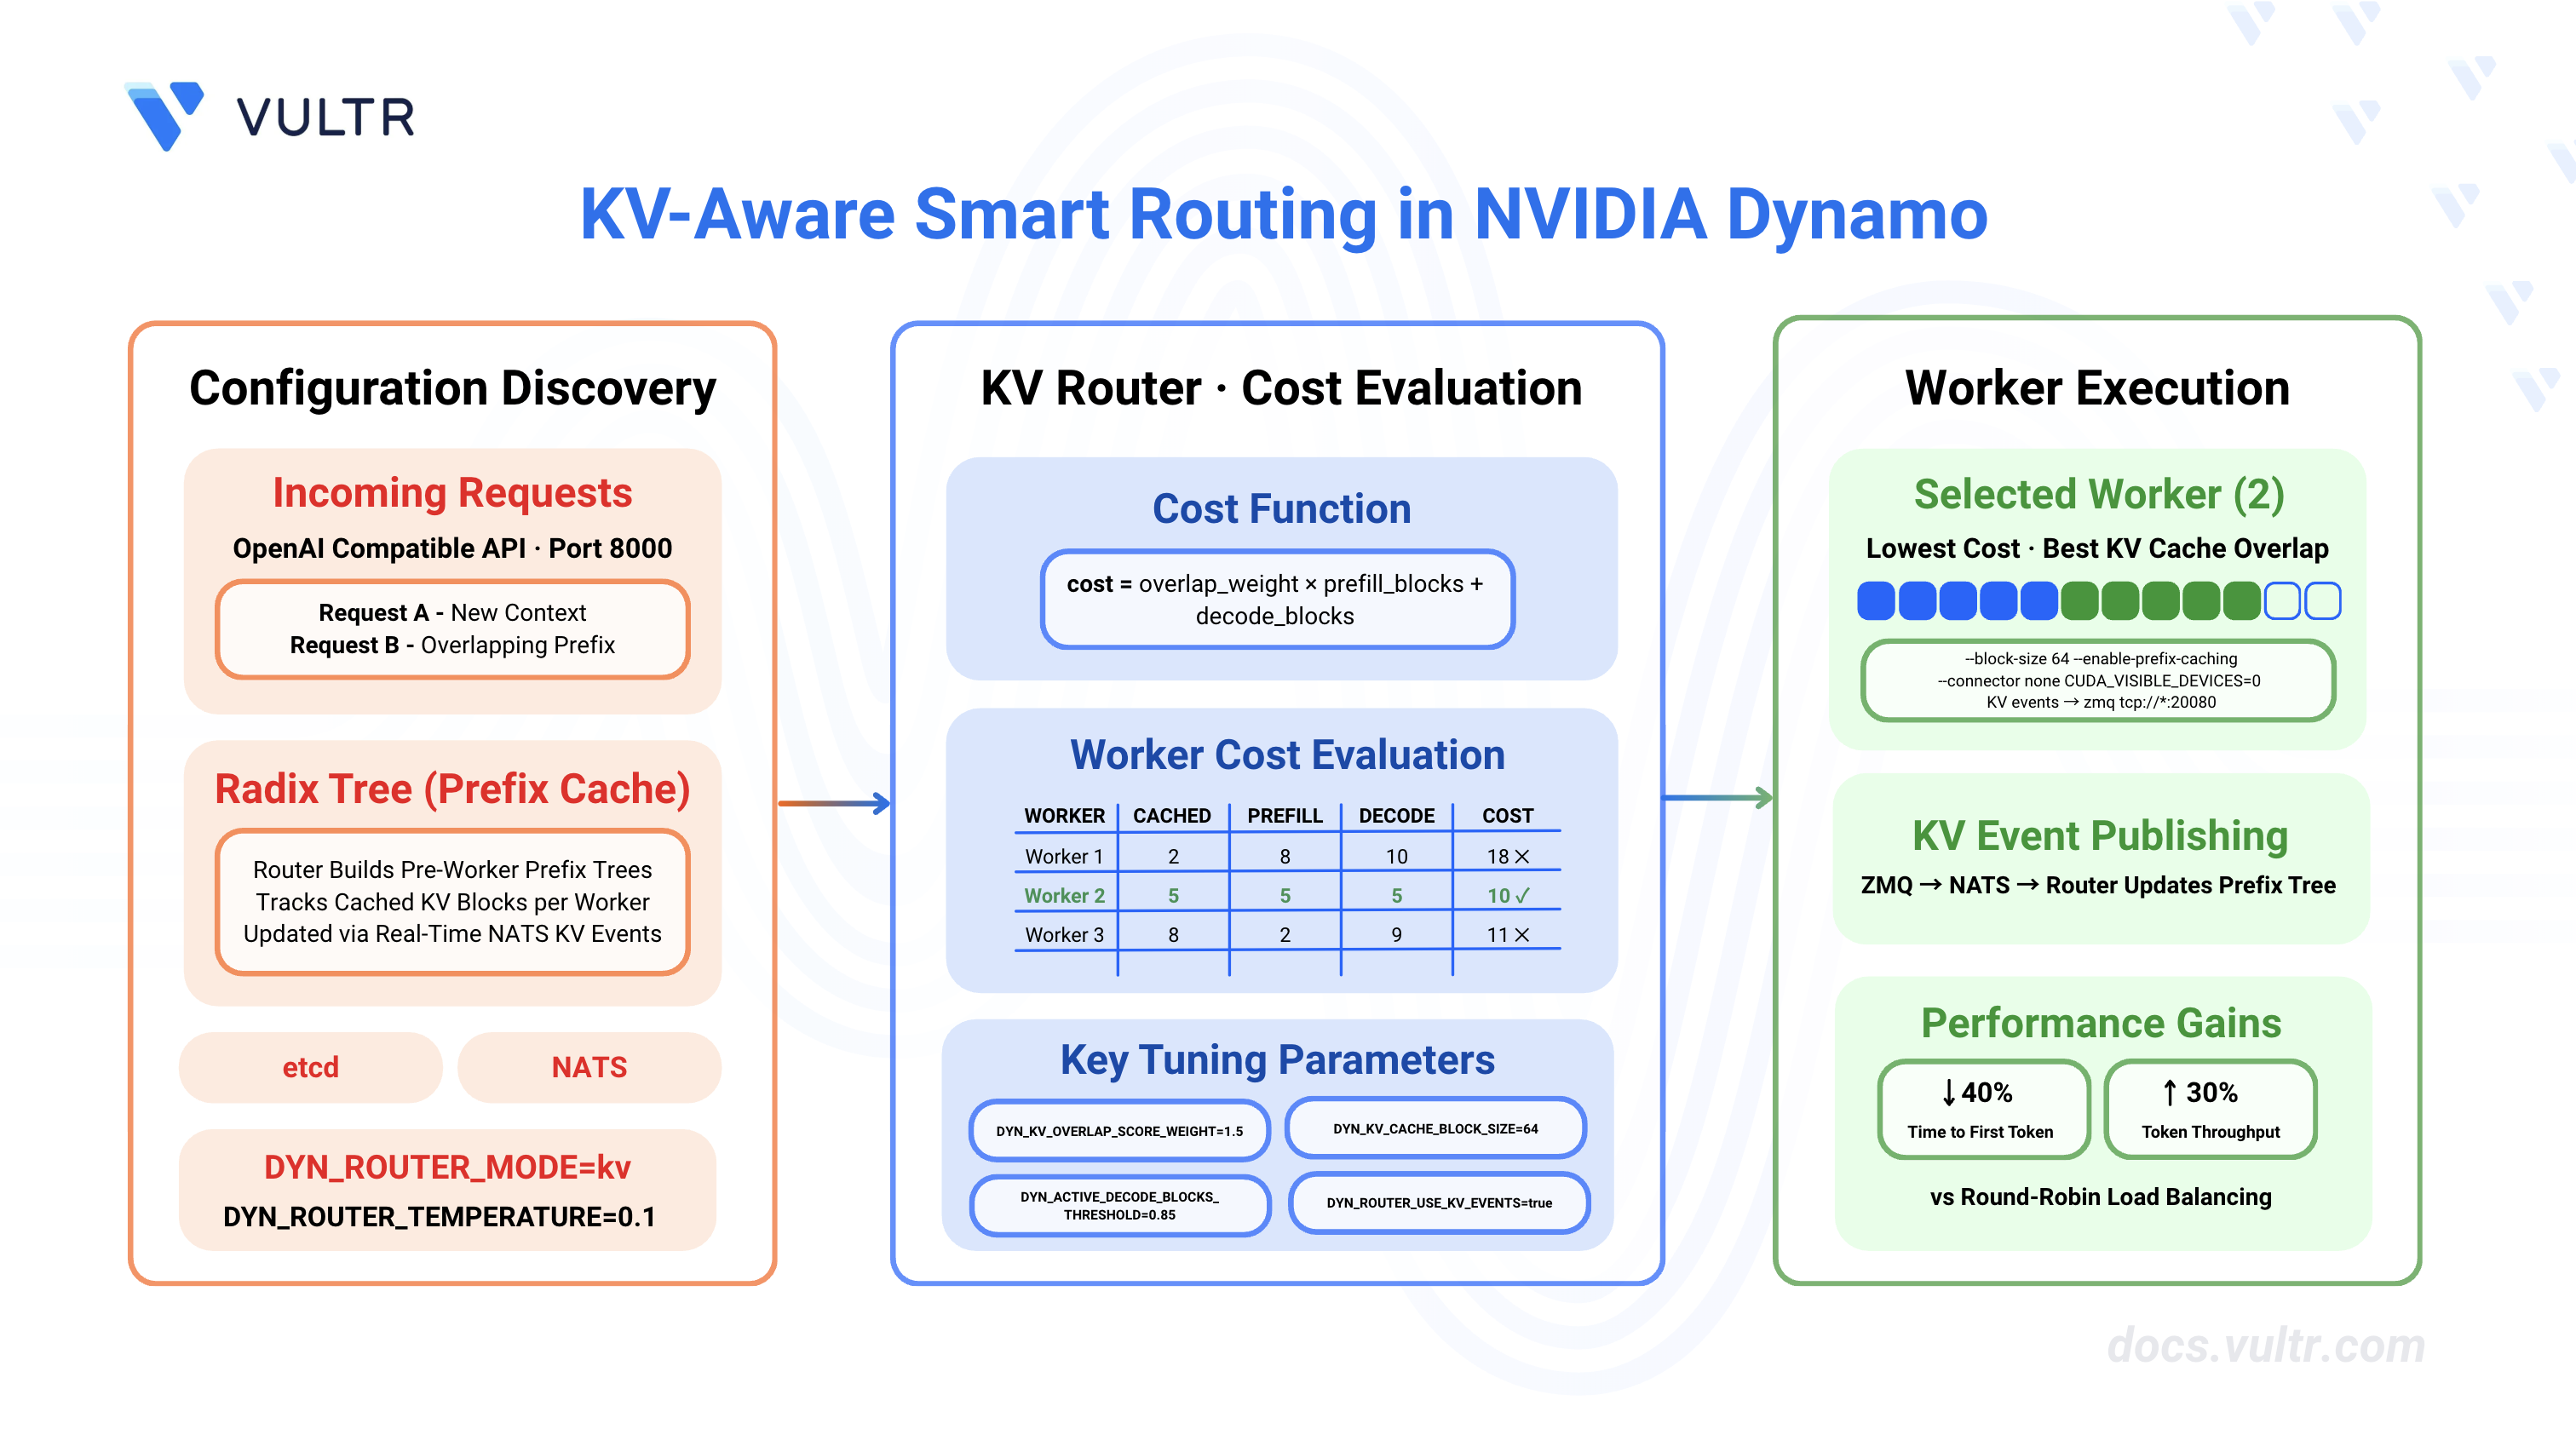
How to Configure Smart Routing in NVIDIA Dynamo | Vultr Docs
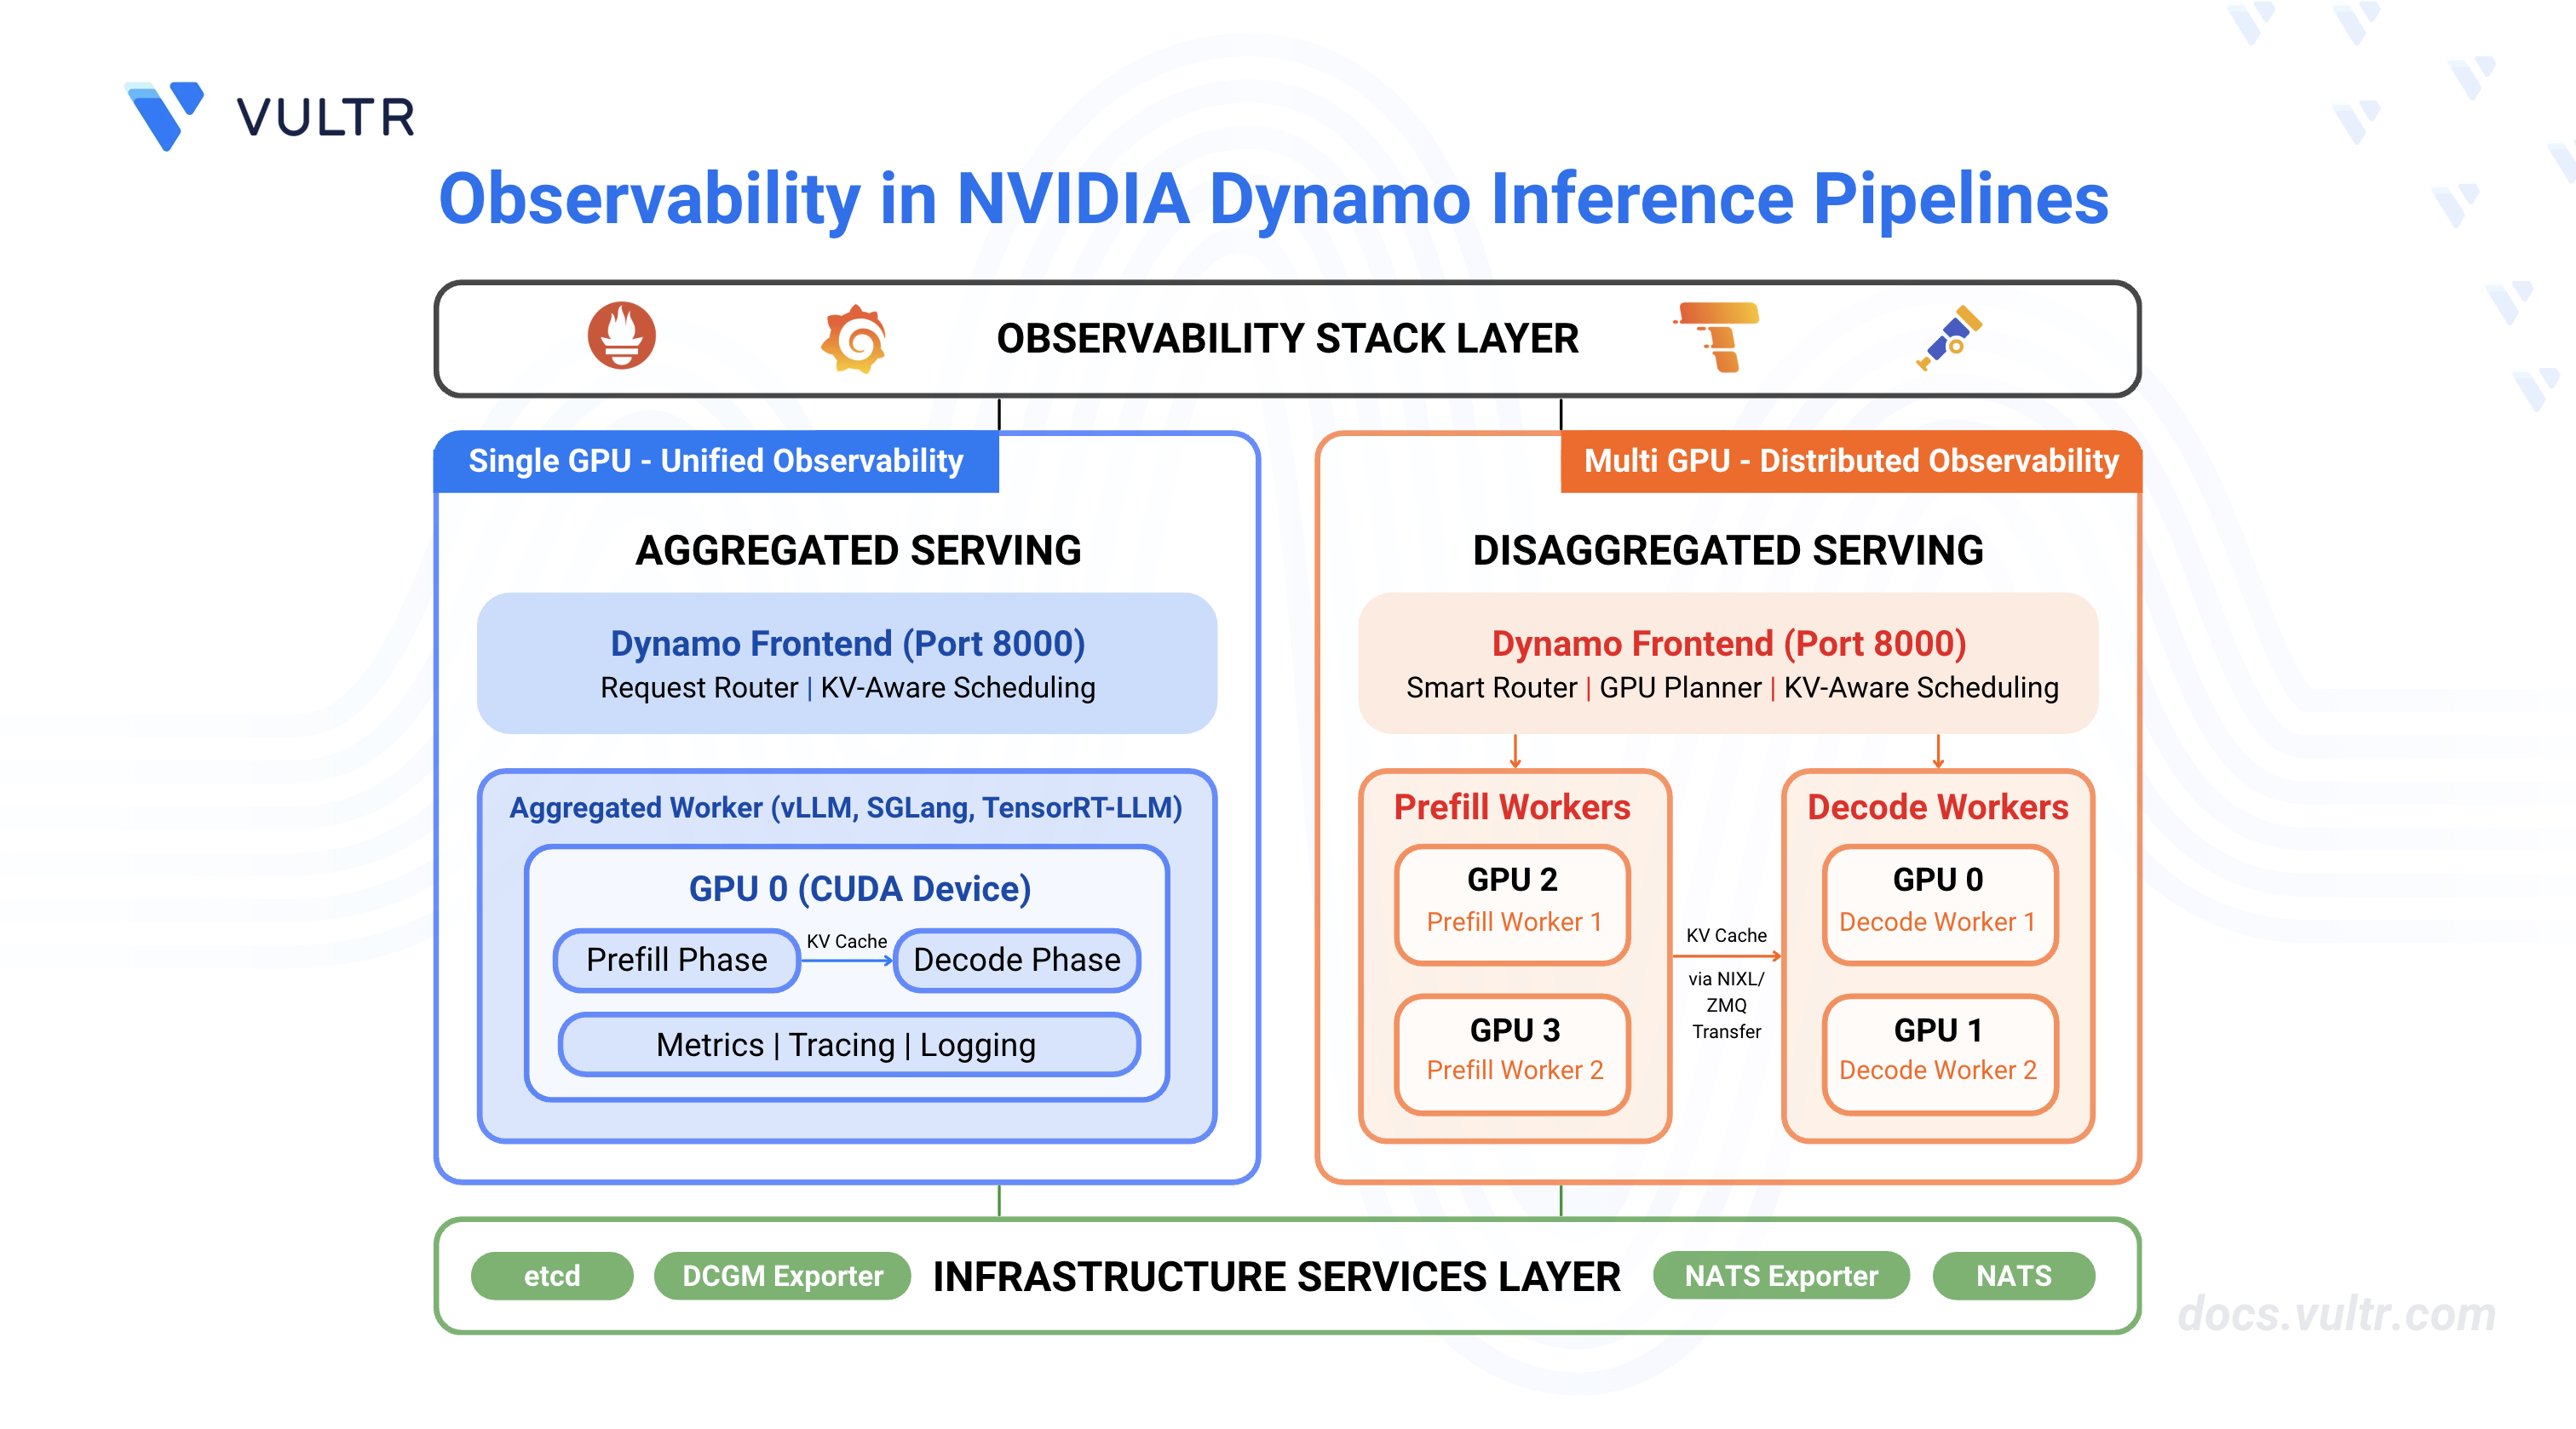
How to Enable Observability in NVIDIA Dynamo Inference Pipelines ...
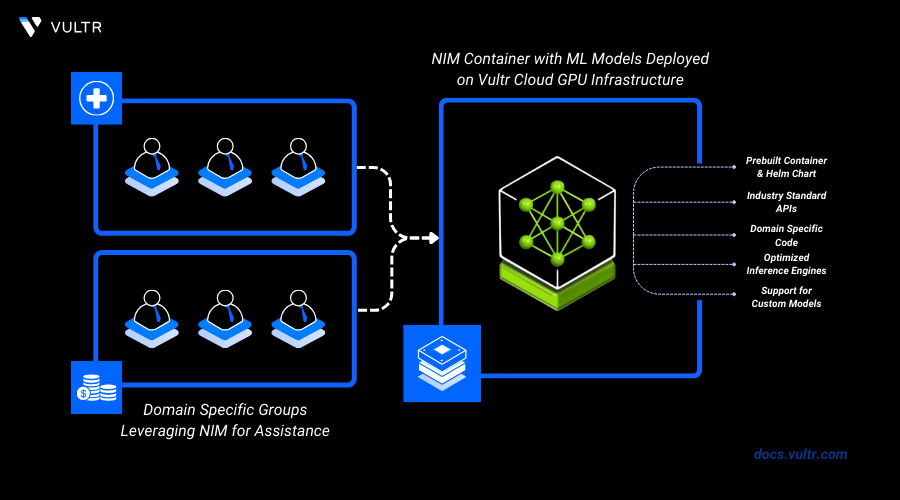
Deploy NVIDIA Inference Microservices on Vultr Platform | Vultr Docs

How NVIDIA GB200 NVL72 and NVIDIA Dynamo Boost Inference Performance ...
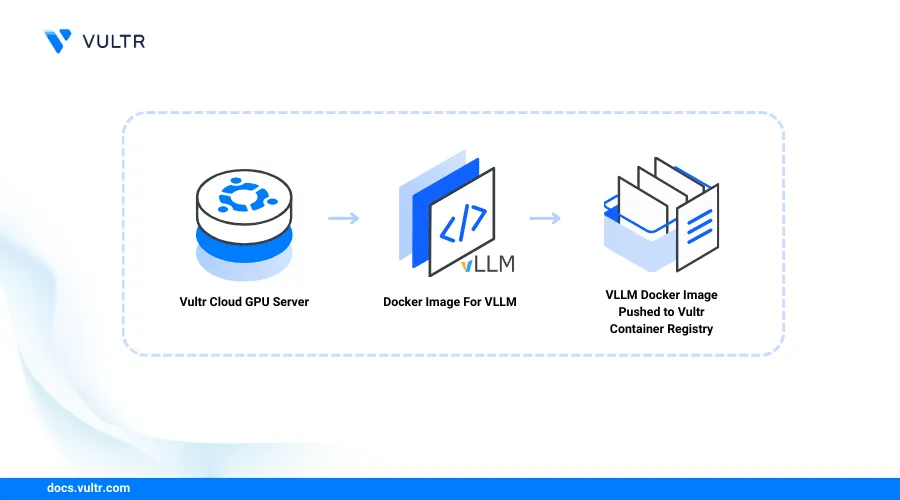
How to Build a vLLM Container Image for LLM Deployment | Vultr Docs
How to Deploy Dynamo Inference Pipelines | SaaS | Run:ai Documentation
Advertisement Space (300x250)
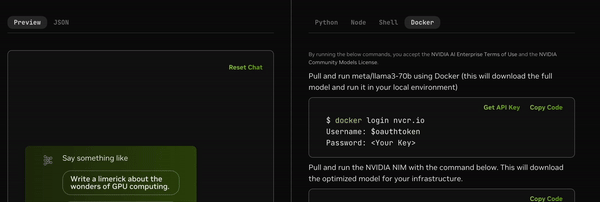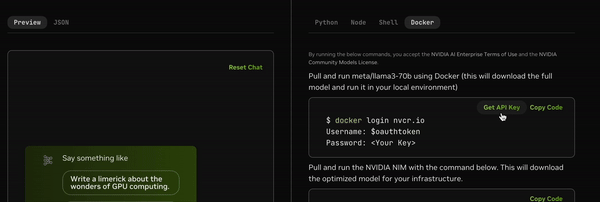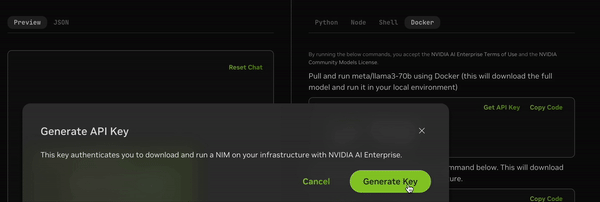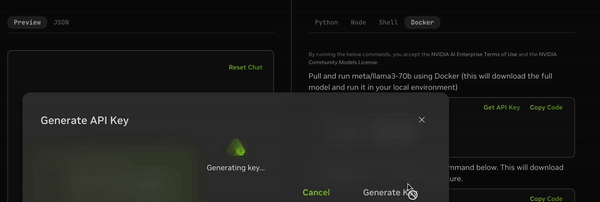
Deploy NVIDIA Inference Microservices on Vultr Platform | Vultr Docs

Want to deploy open models using vLLM as the inference engine? We just ...
How to Deploy NVIDIA NIM on Kubernetes for Fast LLM Inference | DevOpsBoys

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...

Accelerate generative AI inference with NVIDIA Dynamo and Amazon EKS ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...

Accelerate generative AI inference with NVIDIA Dynamo and Amazon EKS ...
Advertisement Space (336x280)
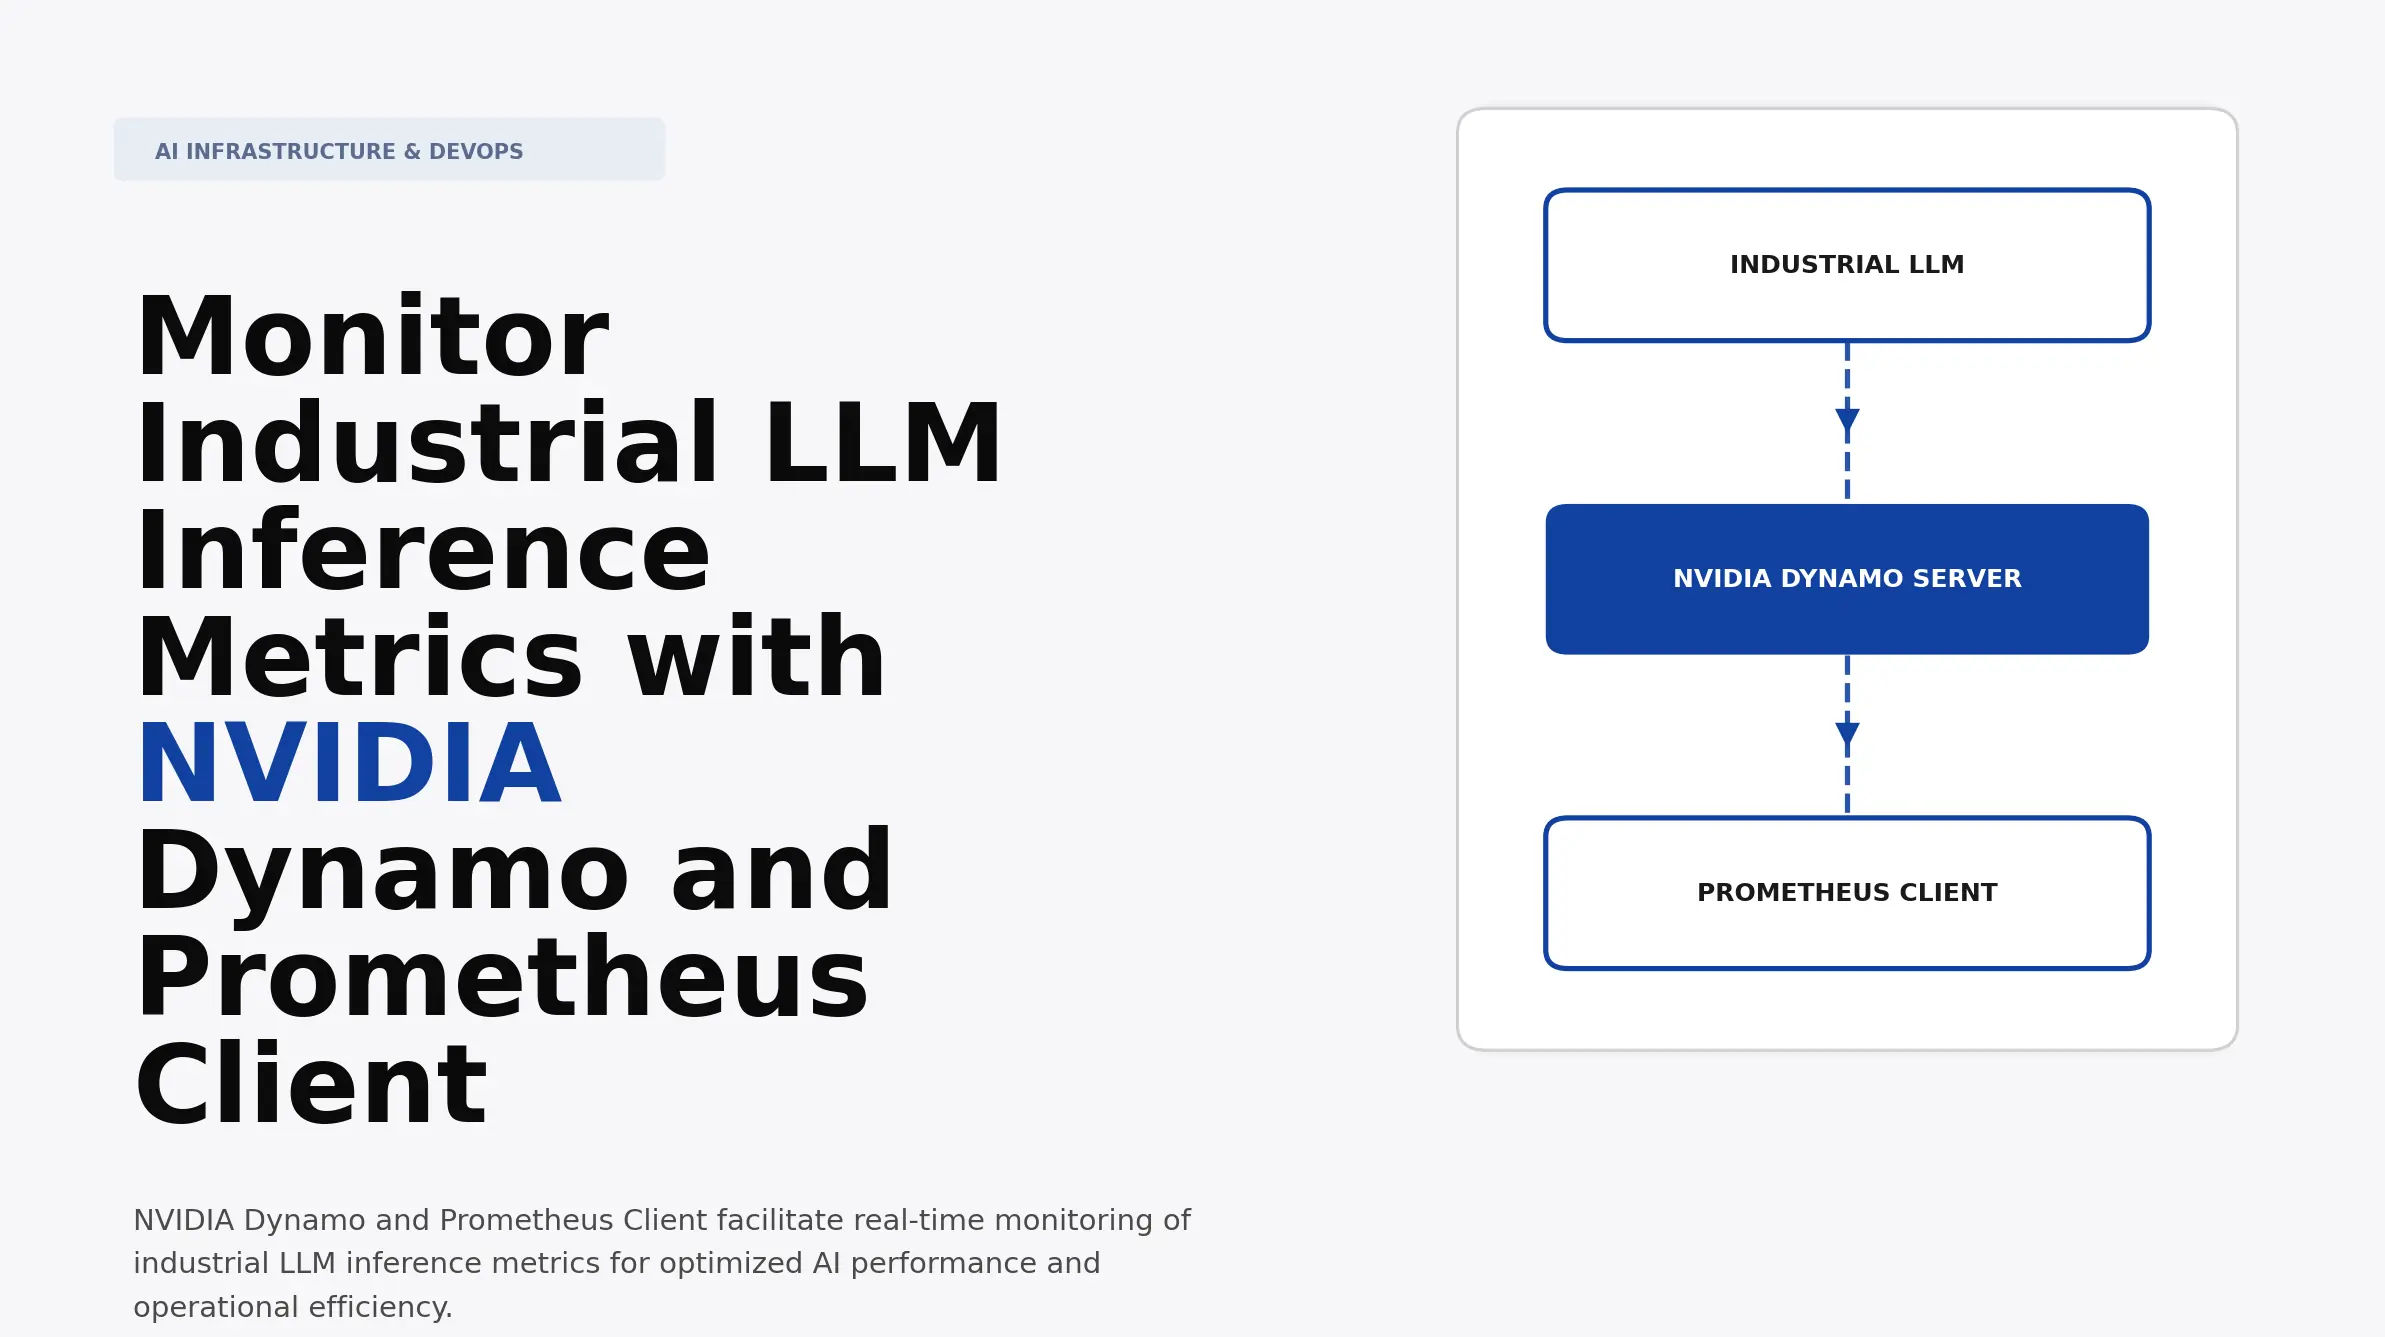
Monitor Industrial LLM Inference Metrics with NVIDIA Dynamo and ...

Accelerate generative AI inference with NVIDIA Dynamo and Amazon EKS ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...
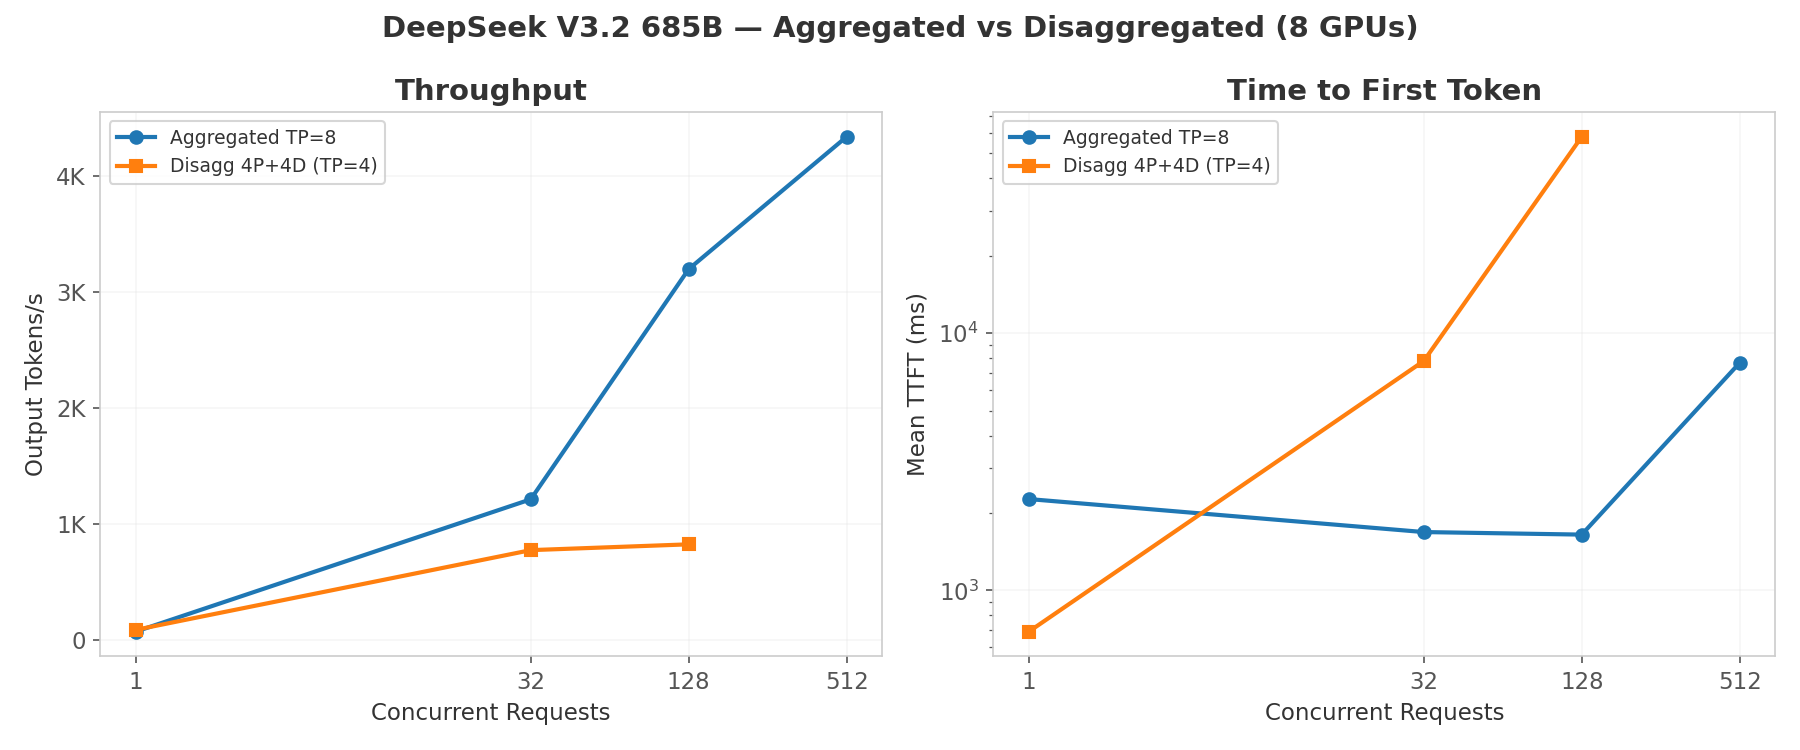
NVIDIA Dynamo | Vultr Docs

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

How NVIDIA Dynamo 1.0 Powers Multi-Node Inference at Production Scale ...
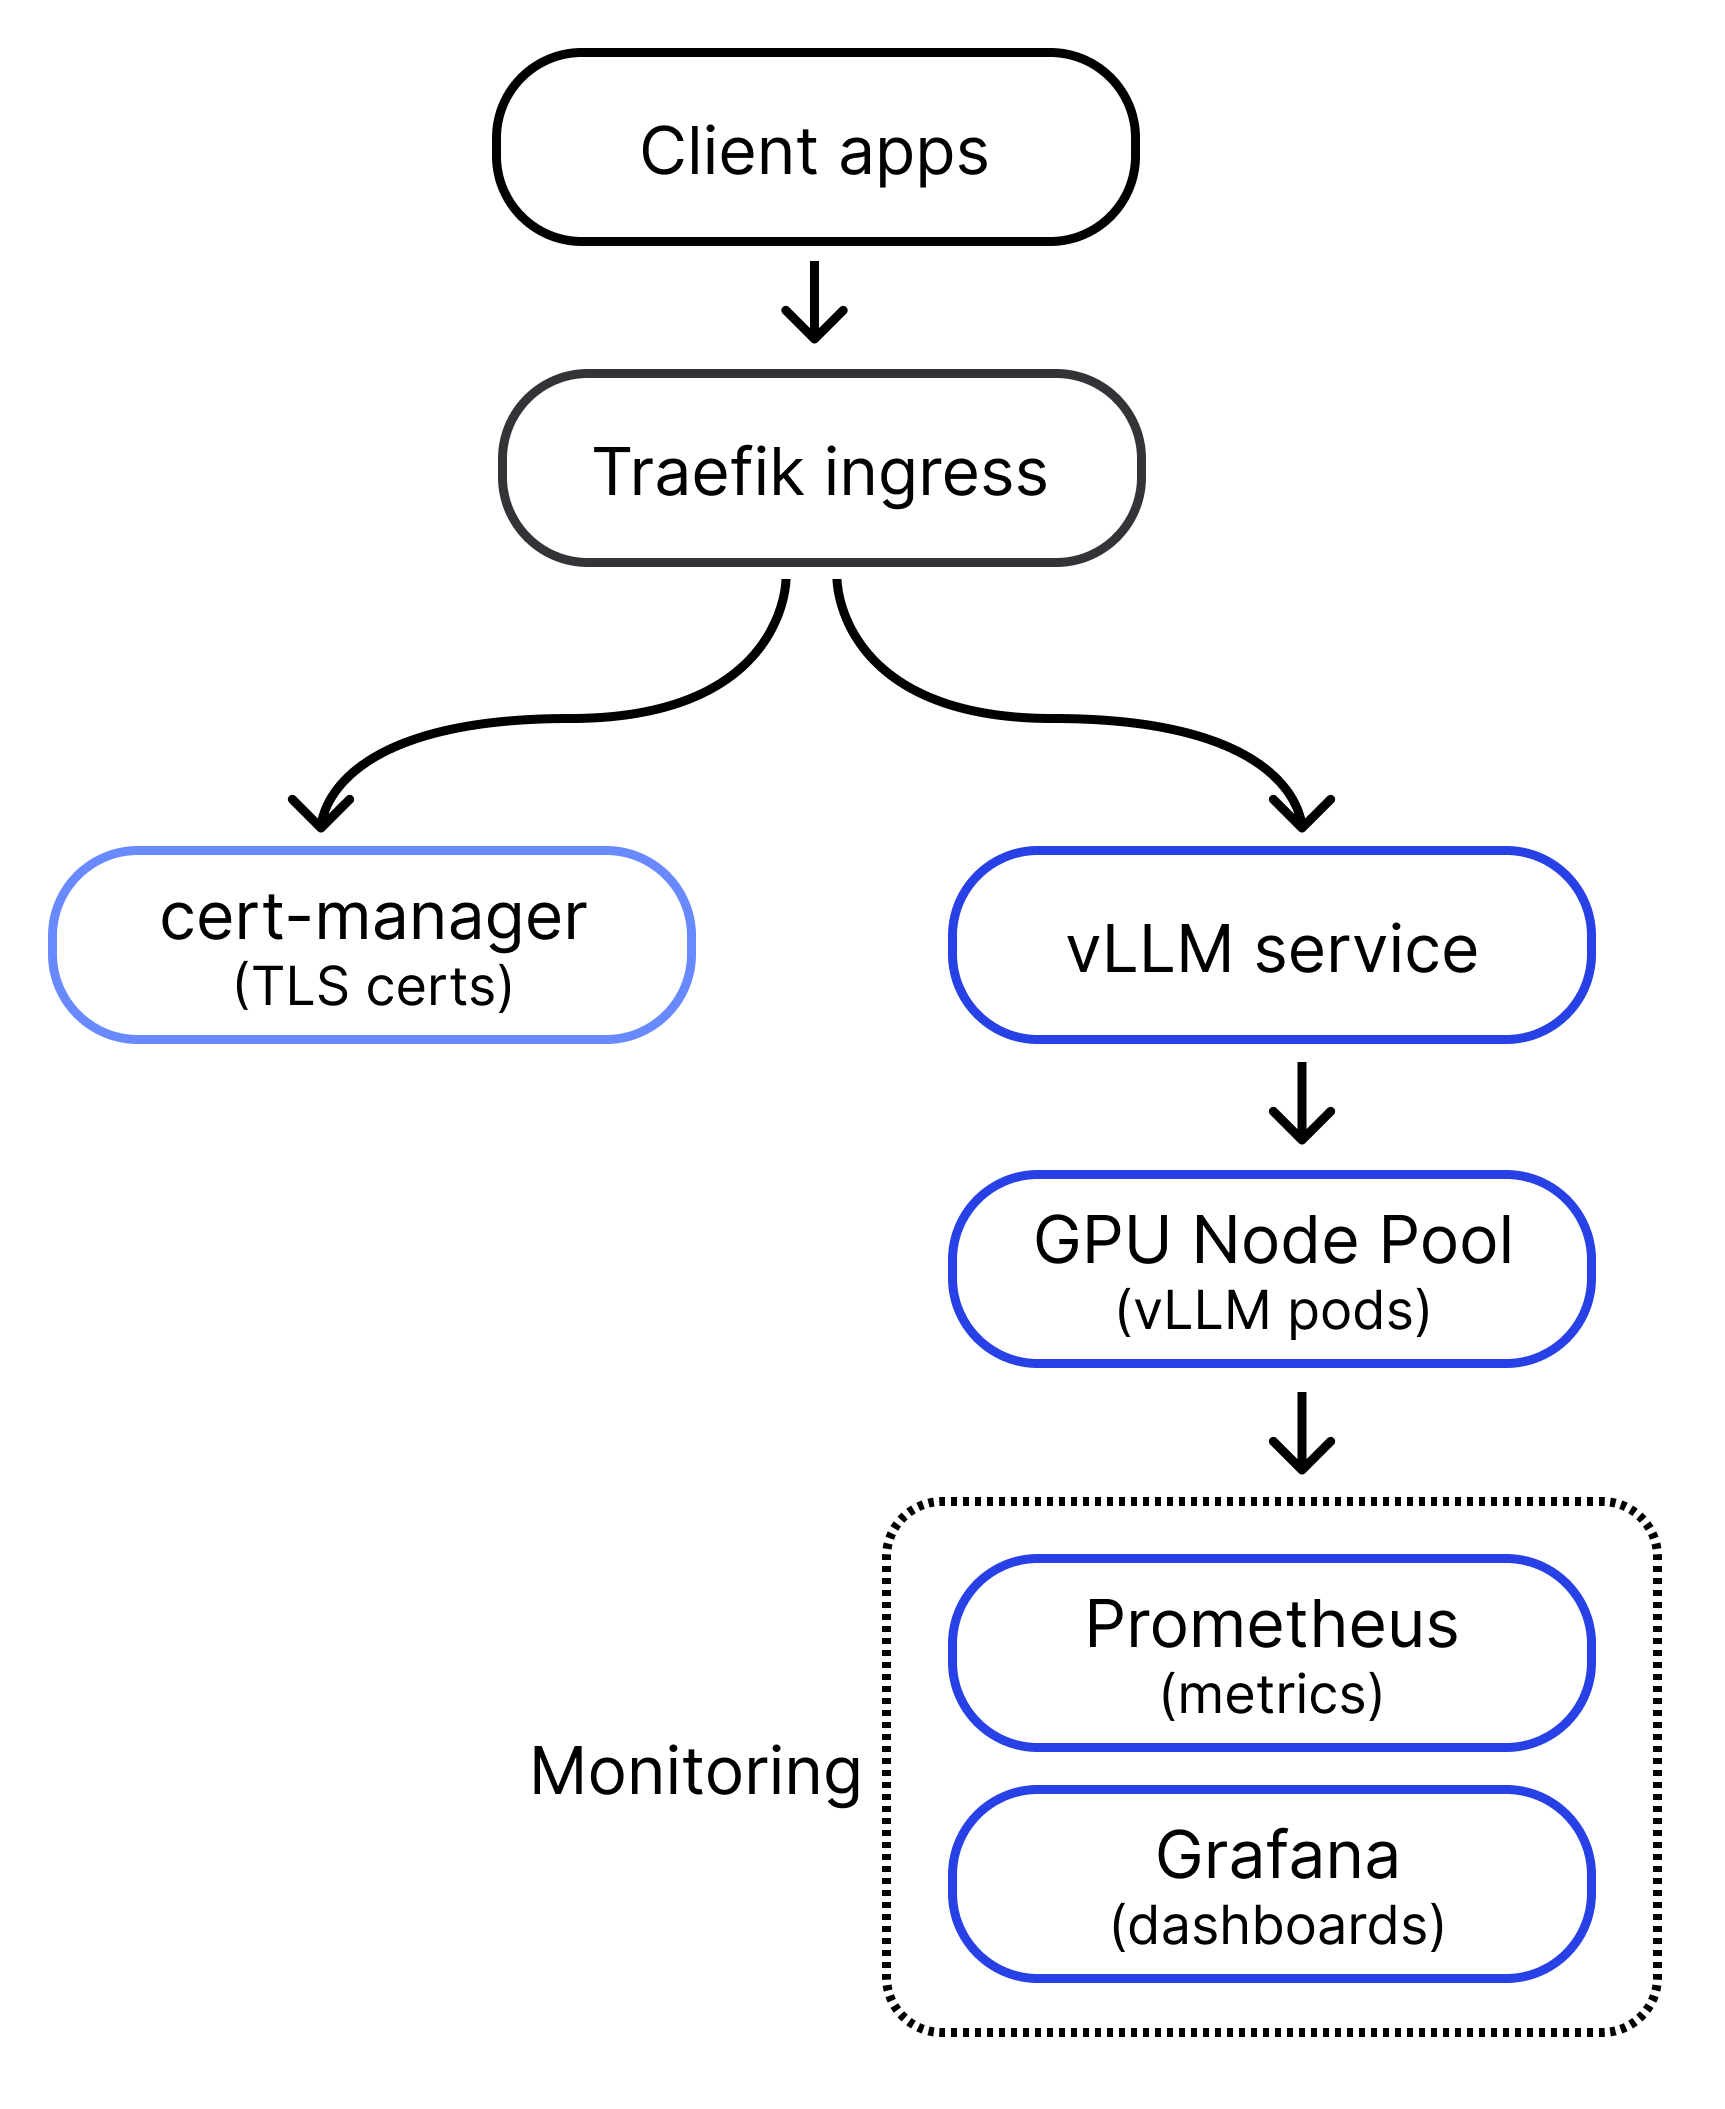
Deploy vLLM for inference - CoreWeave Docs

AI Inference recipe using NVIDIA Dynamo with AI Hypercomputer | Google ...

Scaling multi-node LLM inference with NVIDIA Dynamo and NVIDIA GPUs on ...
Advertisement Space (336x280)

Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...
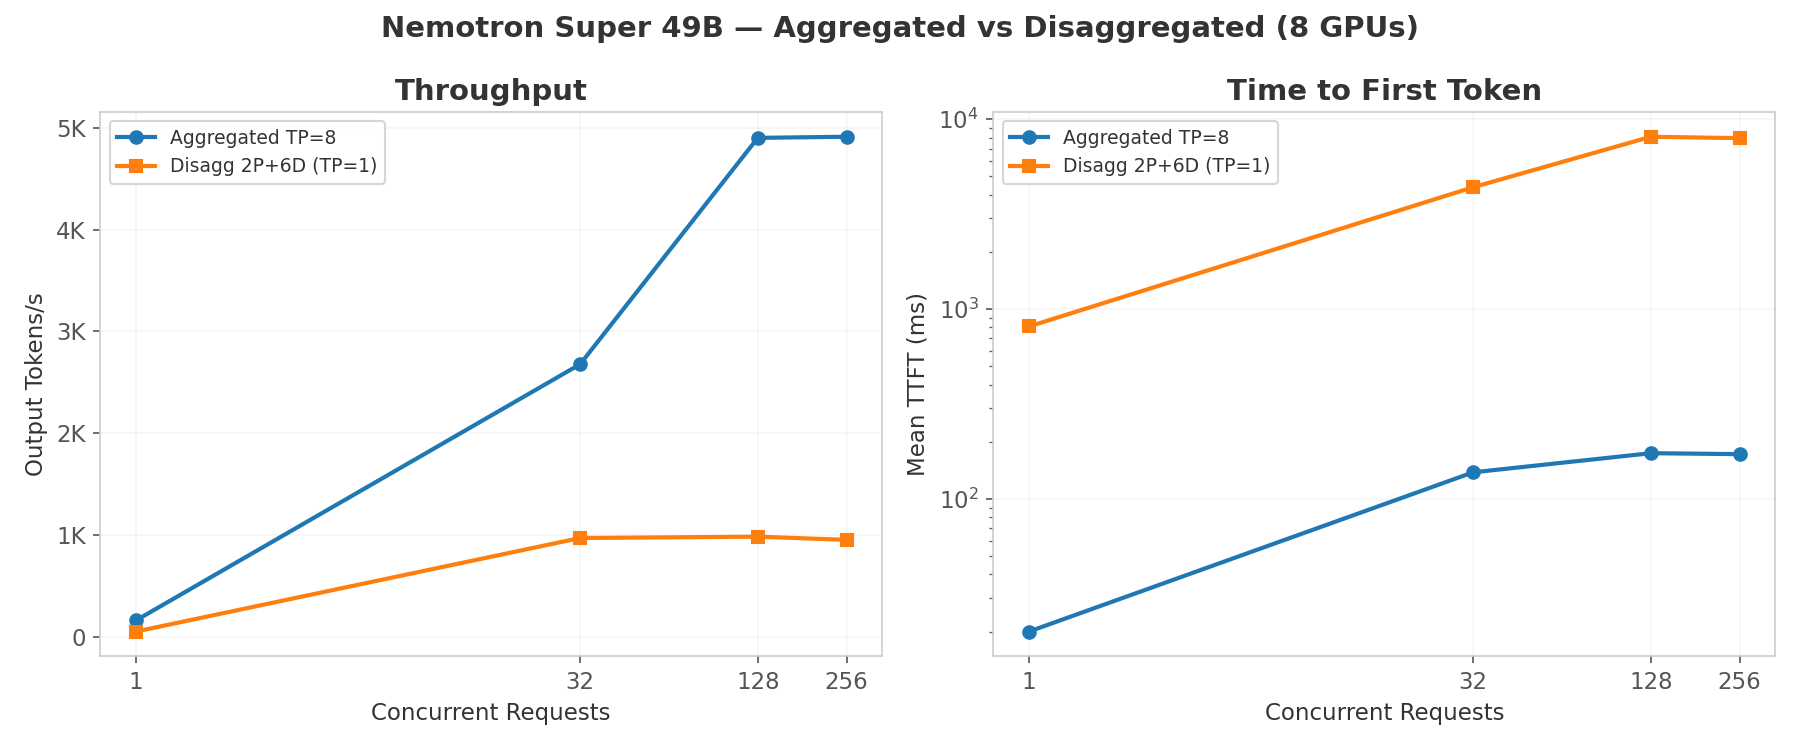
NVIDIA Dynamo | Vultr Docs
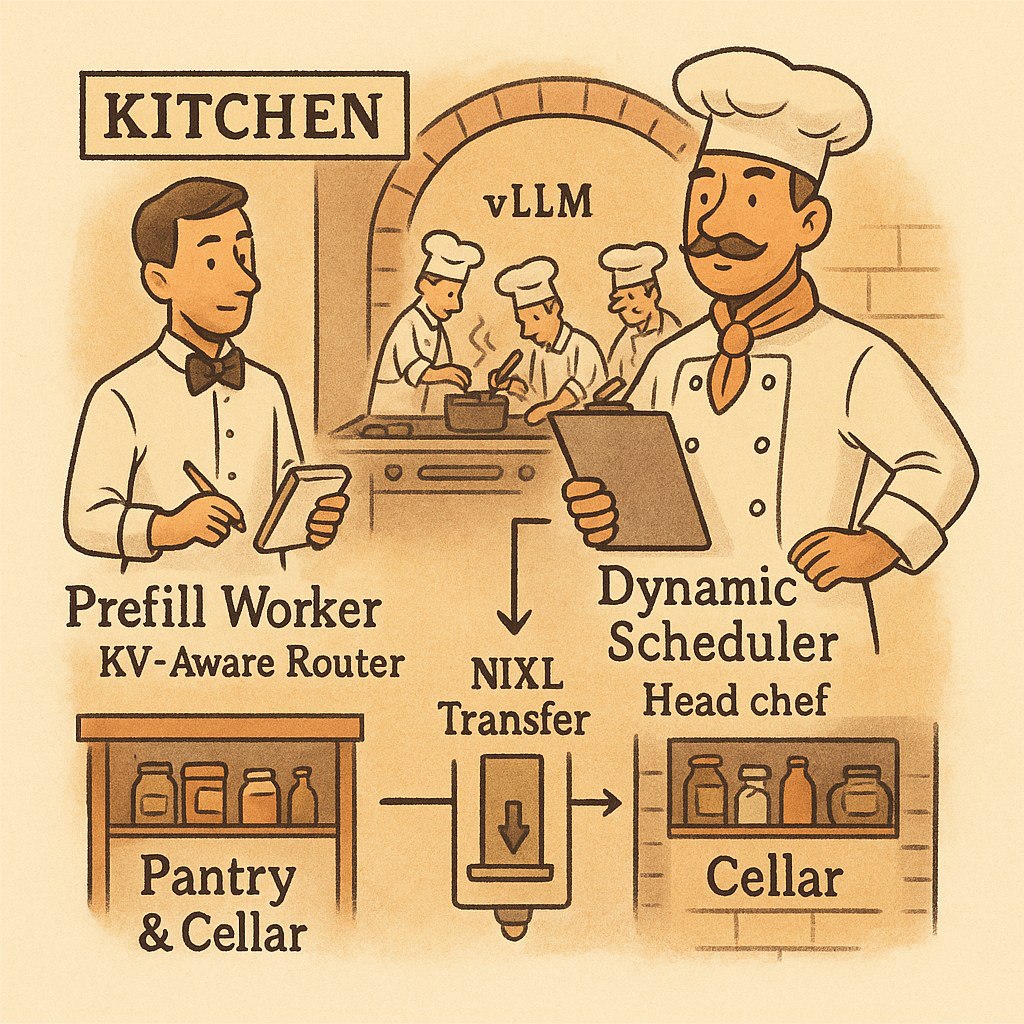
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...
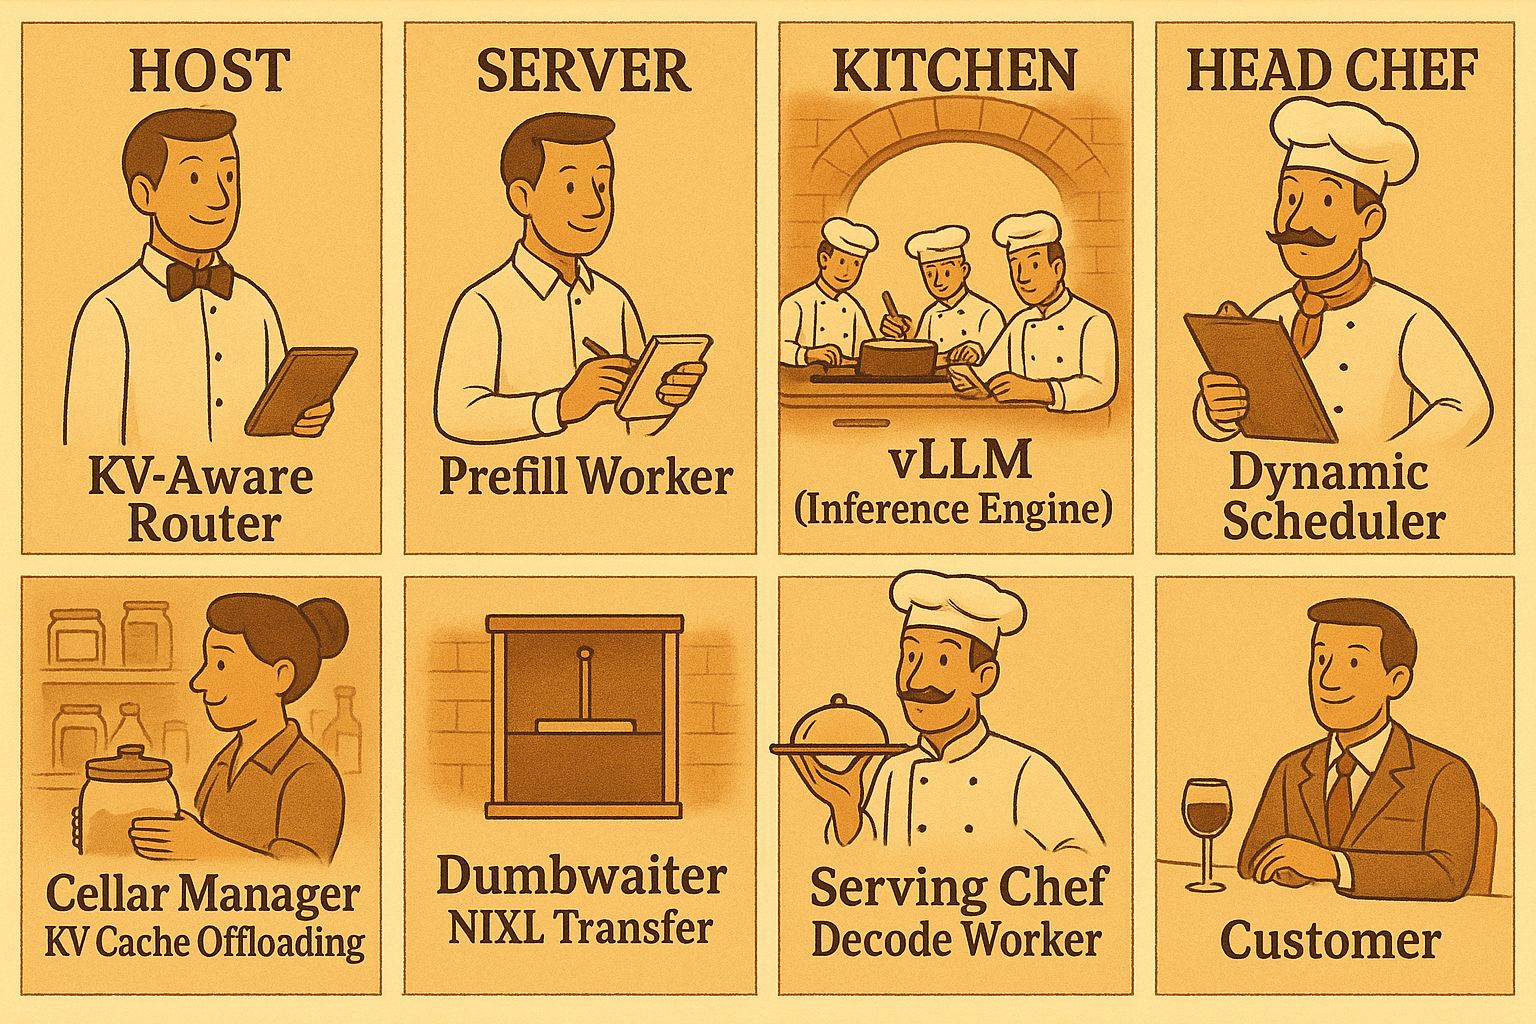
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...