
How To Find Out Why The Results Are Inconsistent With Vllm Issue 77
How to find out why the results are inconsistent with vllm · Issue #77 ...
The inference results of vllm and HF are inconsistent · Issue #2189 ...
Why Your LLM Outputs Are Inconsistent (And How to Fix It) | Blog ...
[Bug]: Why are the vLLM and Hugging Face Transformers inference results ...
chatglm3 inference results are inconsistent with huggingface · Issue ...
[Usage]: How to determine whether the vllm engine is full with requests ...
[Installation]: How to reduce the vllm image · Issue #27154 · vllm ...
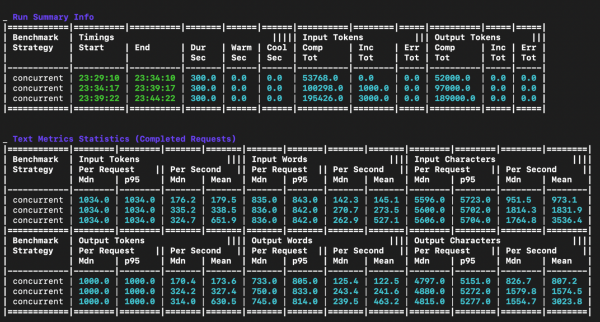
How to deploy and benchmark vLLM with GuideLLM on Kubernetes | Red Hat ...
why the transformers vicuna-7b-v1.1 results is different from vllm ...
Inconsistent results between HuggingFace Transformers and vllm · Issue ...
Advertisement Space (300x250)
[Usage]: How to reproduce the results of `vllm` using `transformers ...
[Usage]: how to acquire logits in vllm · Issue #8762 · vllm-project ...
[Usage]: How to stop VLLM during generation ? · Issue #8332 · vllm ...
[Bug]: Issue Running Qwen2.5-VL-7B-Instruct with vLLM Due to ...
[Bug]: vllm failed to run two instance with one gpu · Issue #10533 ...

Reproduce the given benchmark results · vllm-project vllm · Discussion ...
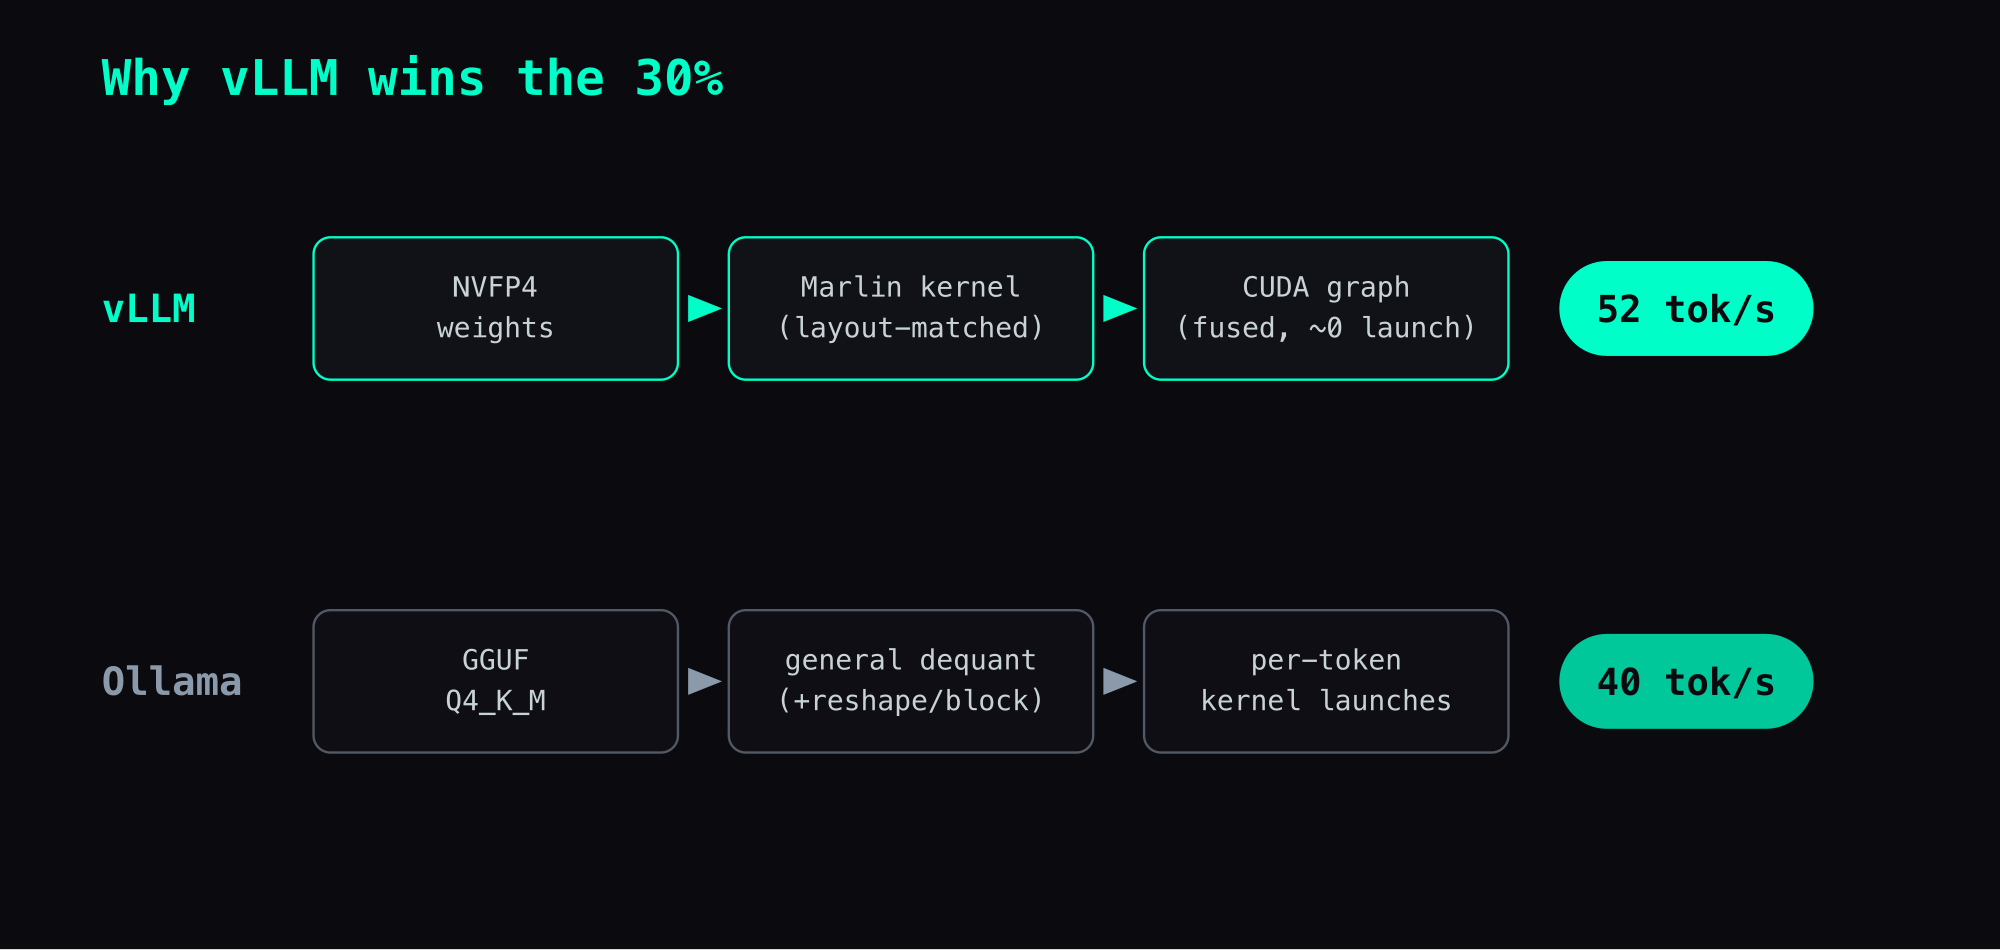
[Benchmark] vLLM vs Ollama on the Same Model: Why 30% Faster on GB10 ...
Why is the result variable when using vllm for inference, even though I ...
[Performance]: Context Length Problem with VLLM · Issue #11745 · vllm ...
Support vllm to use lm-eval to evaluate model accuracy · Issue #776 ...
Advertisement Space (336x280)
[Bug]: Unexpected non-determinism with vLLM 0.5.4 and Llama 3.1 · Issue ...
[Doc]: The precision of Minimax-2.5 is inconsistent with the paper(2*A2 ...
[Bug]:During the vllm 0.10.1 v1 benchmark test, only about 100 out of ...
why vllm don't use apex for Inference Acceleration? · Issue #1384 ...
[Usage]: why vllm takes as much ram as possible ? · Issue #4448 · vllm ...
[Bug]: The vllm is disconnected after running for some time · Issue ...
[Bug]: VLLM process dies when trying to profile with nsight systemss ...
[Bug]: VLLM_USE_V1=1 failed with deepseek-v3 · Issue #12956 · vllm ...
[Bug]: VLLM 0.11.1 Fails to recognize --rope-scaling arguement · Issue ...
Error in benchmark model with vllm backend · Issue #3230 · vllm-project ...
Advertisement Space (336x280)

vLLM V0 to V1: Correctness Before Corrections in RL
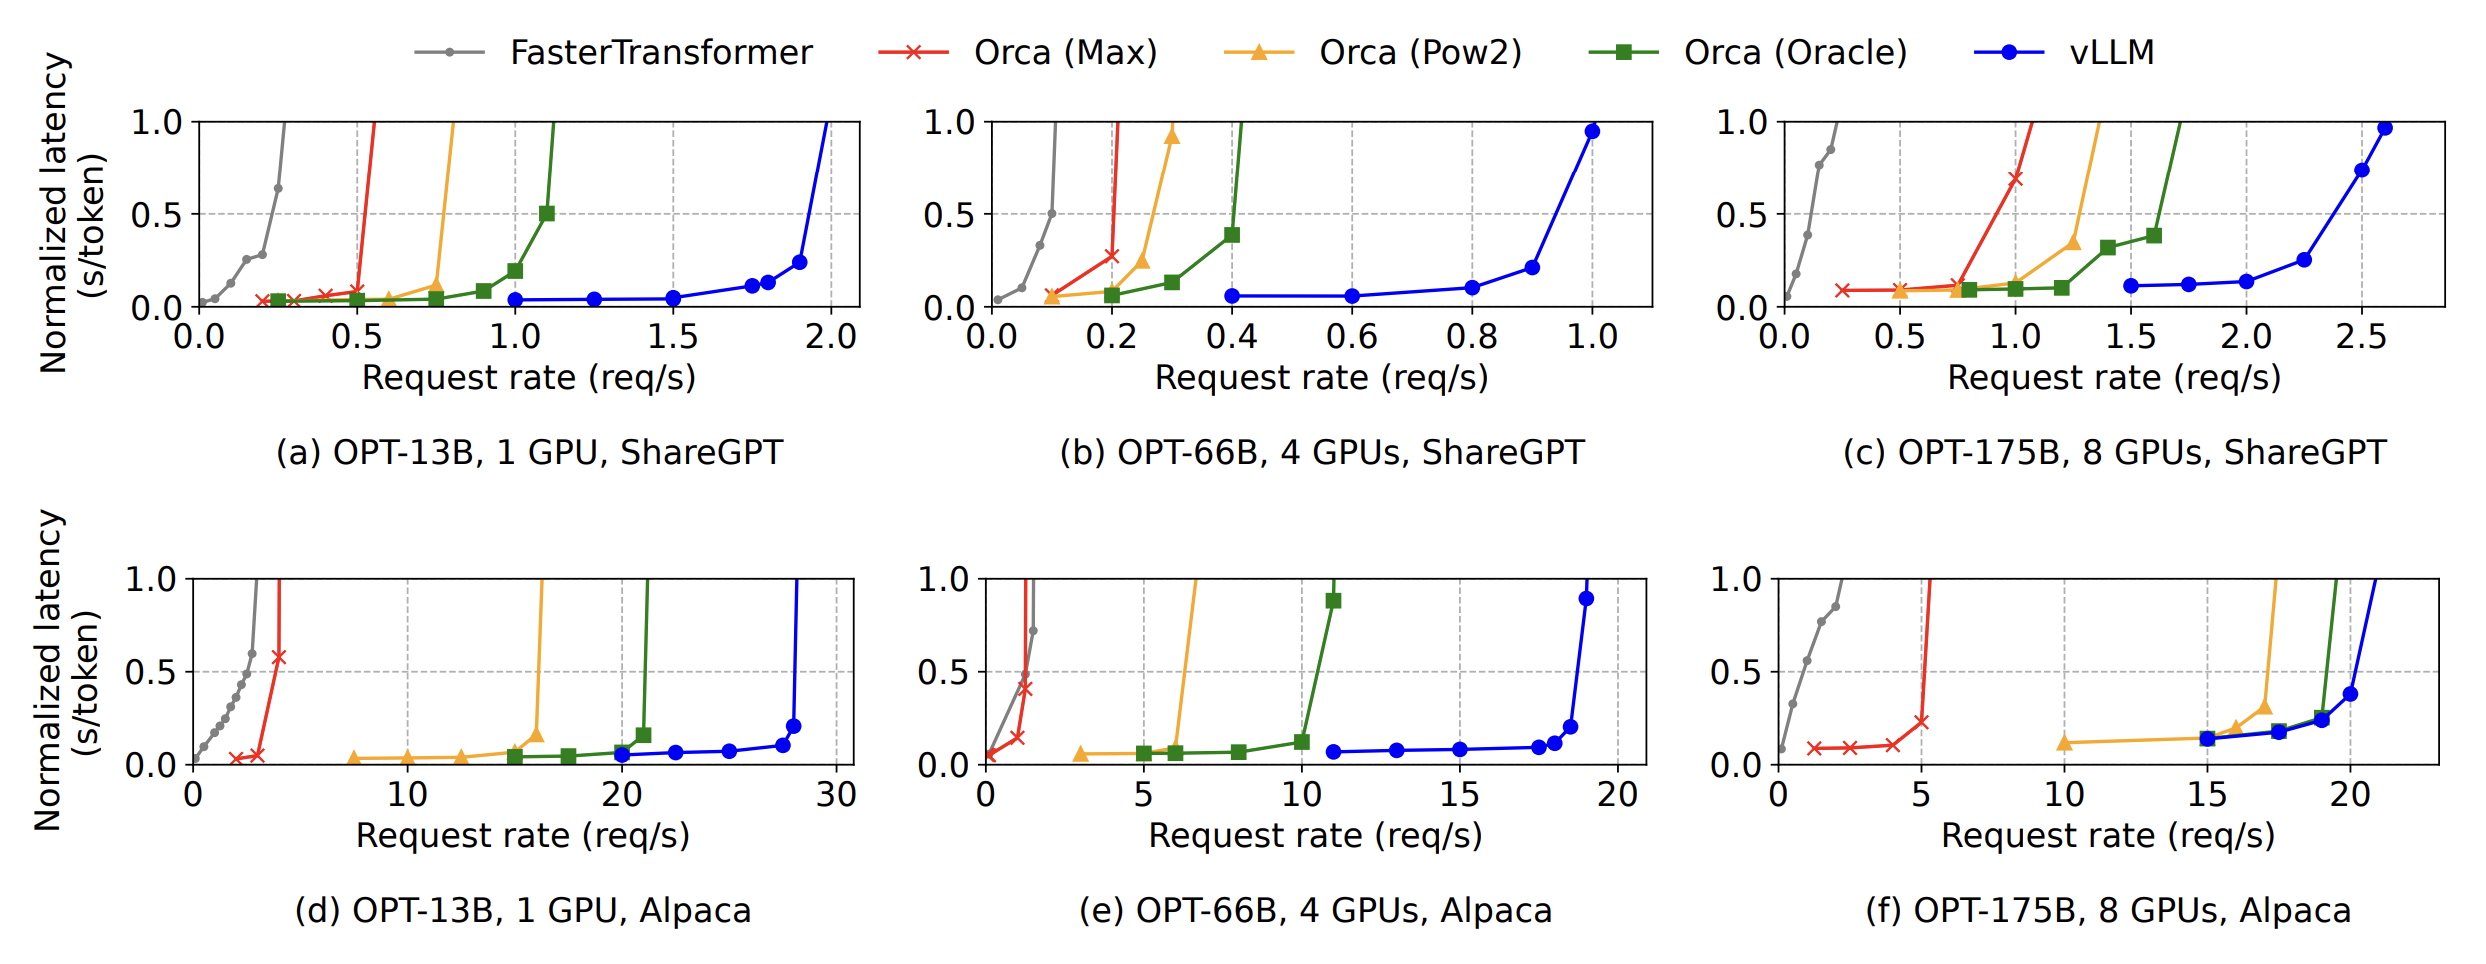
vLLM and PagedAttention: Why KV Cache Management Matters - Minseo’s Dev ...
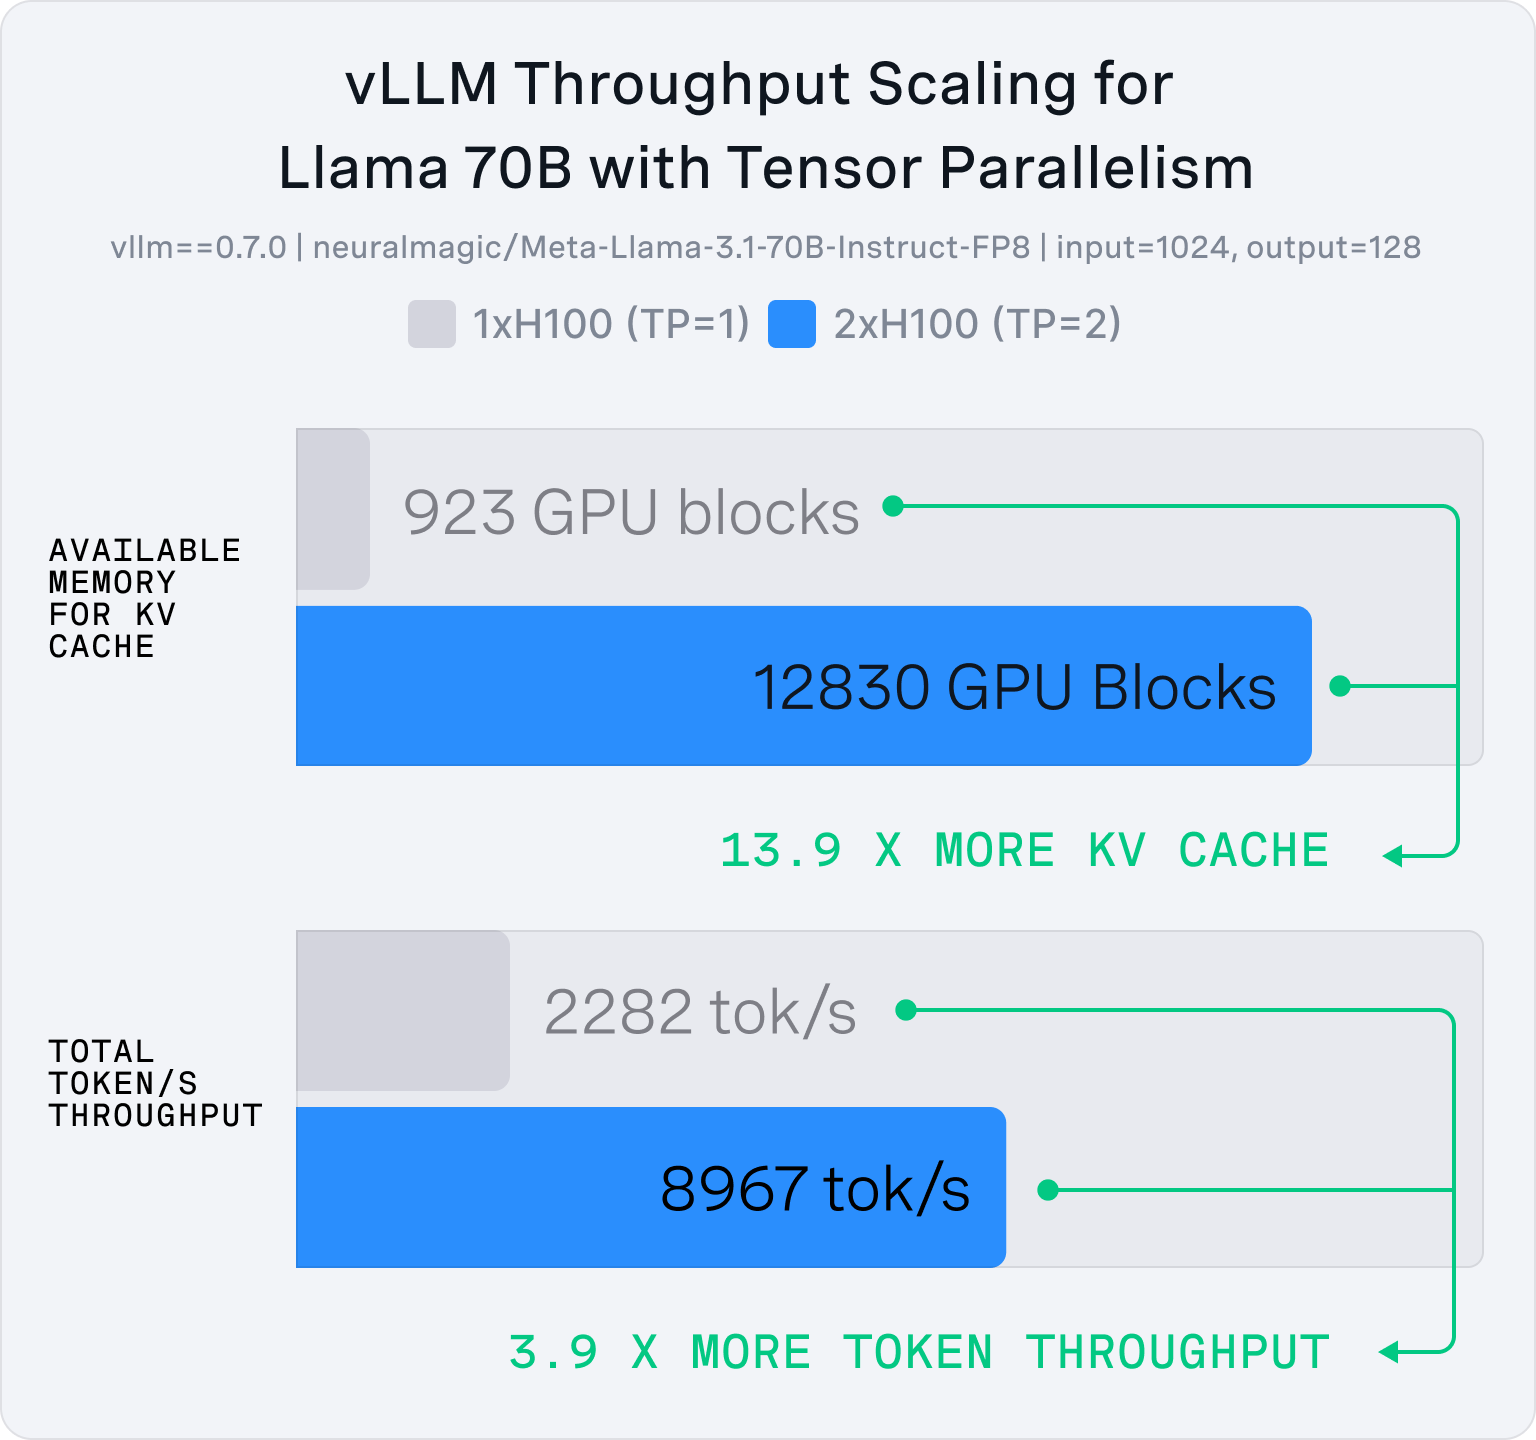
Distributed inference with vLLM | Red Hat Developer
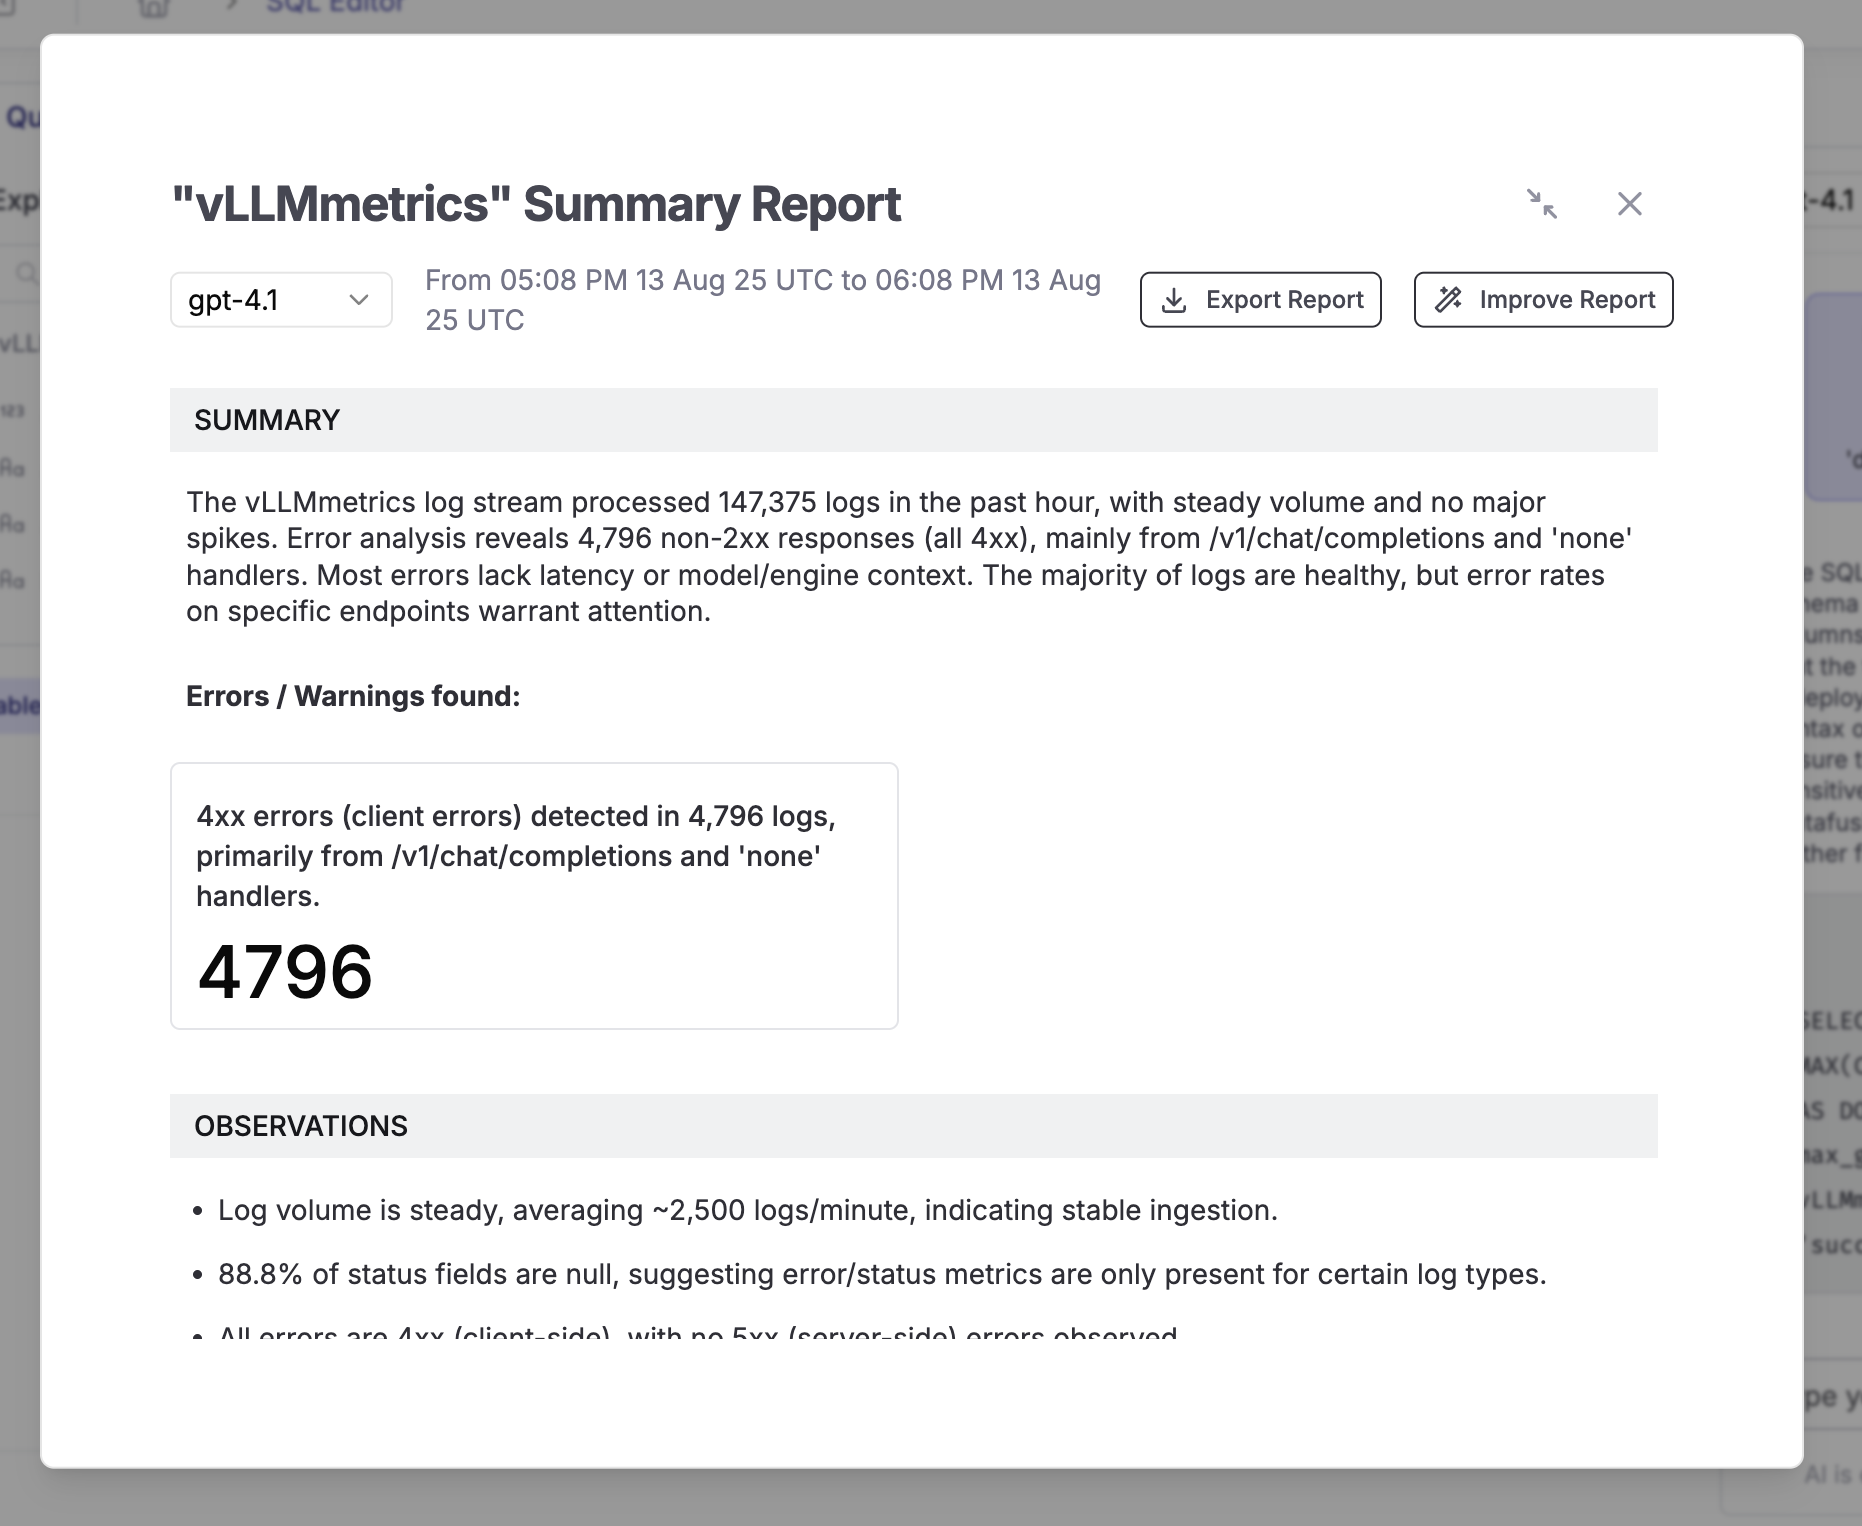
vLLM OpenTelemetry: Monitor LLM Inference Metrics with Parseable
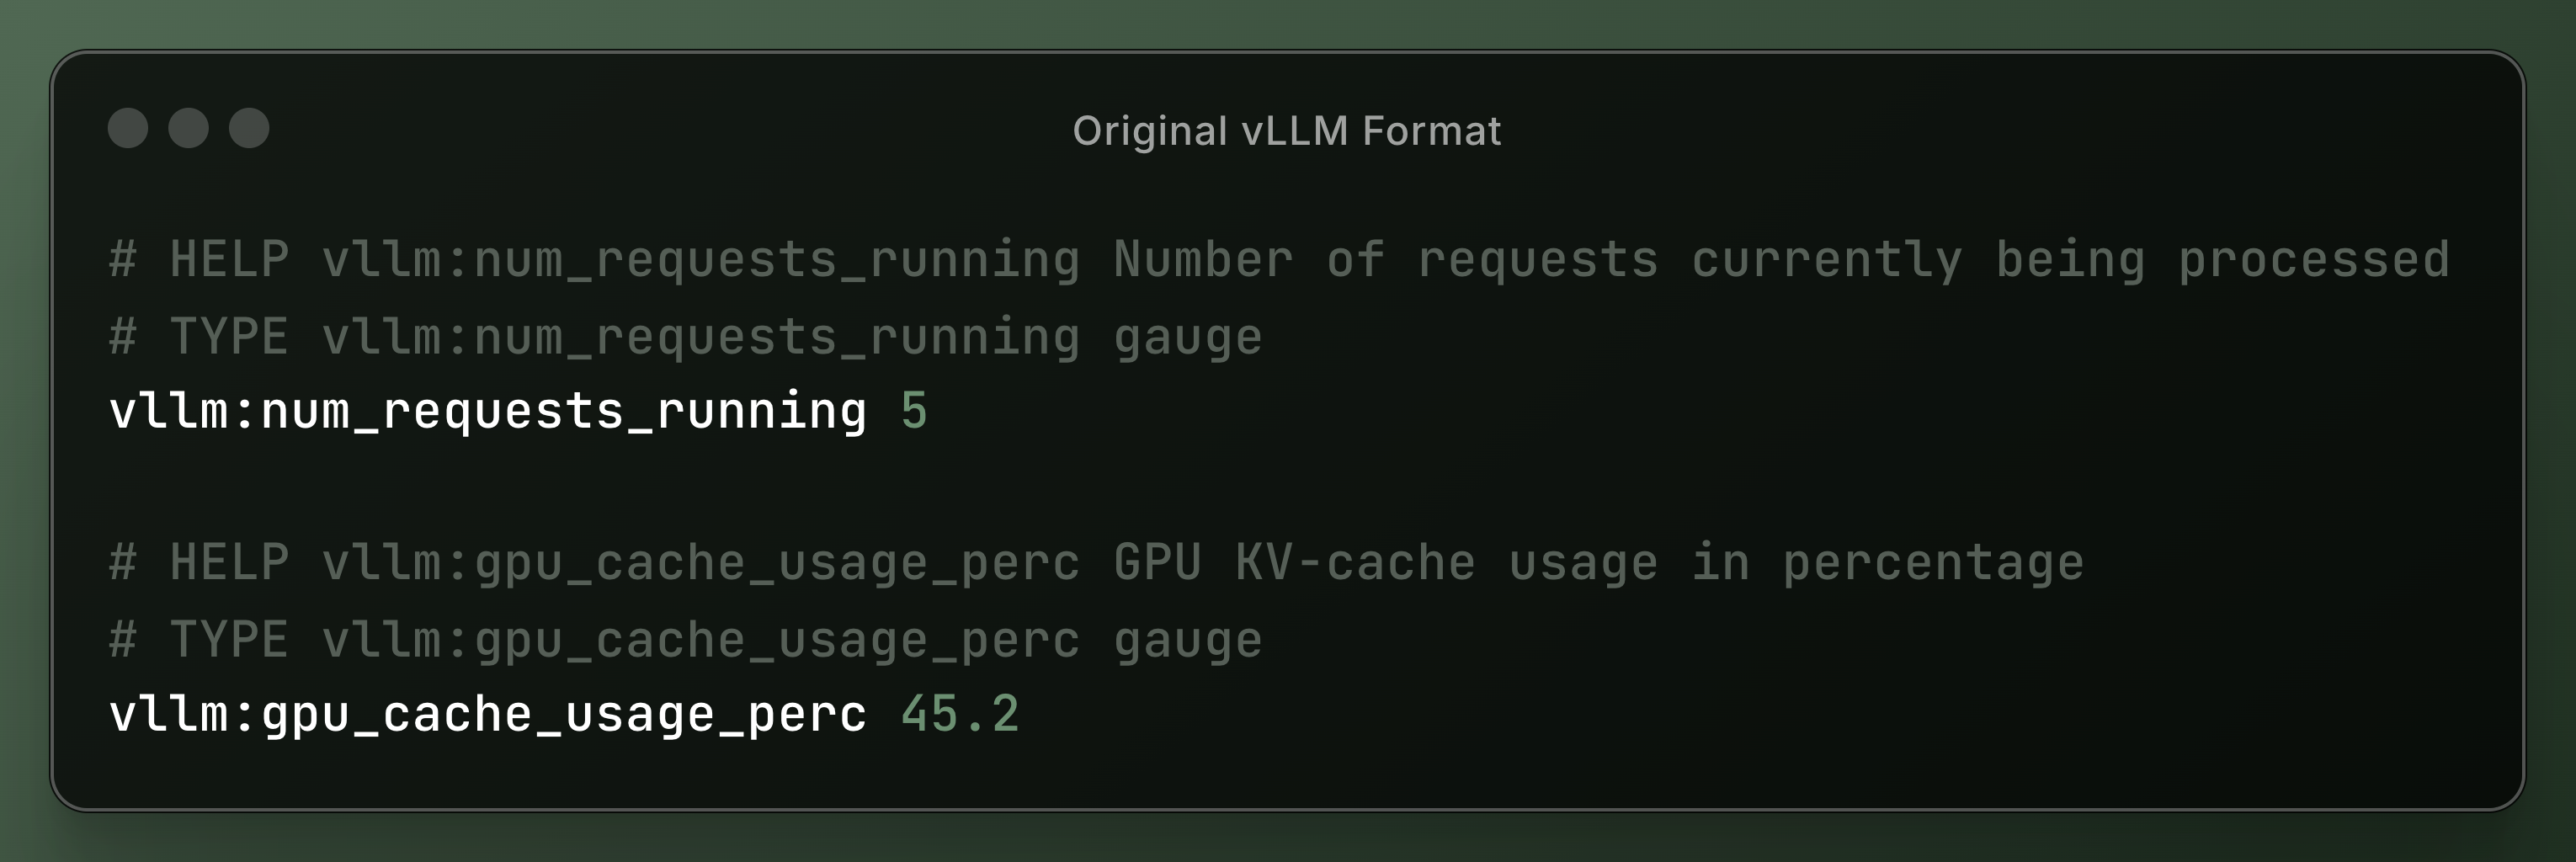
vLLM Observability: Monitor LLM Inference with OpenTelemetry ...
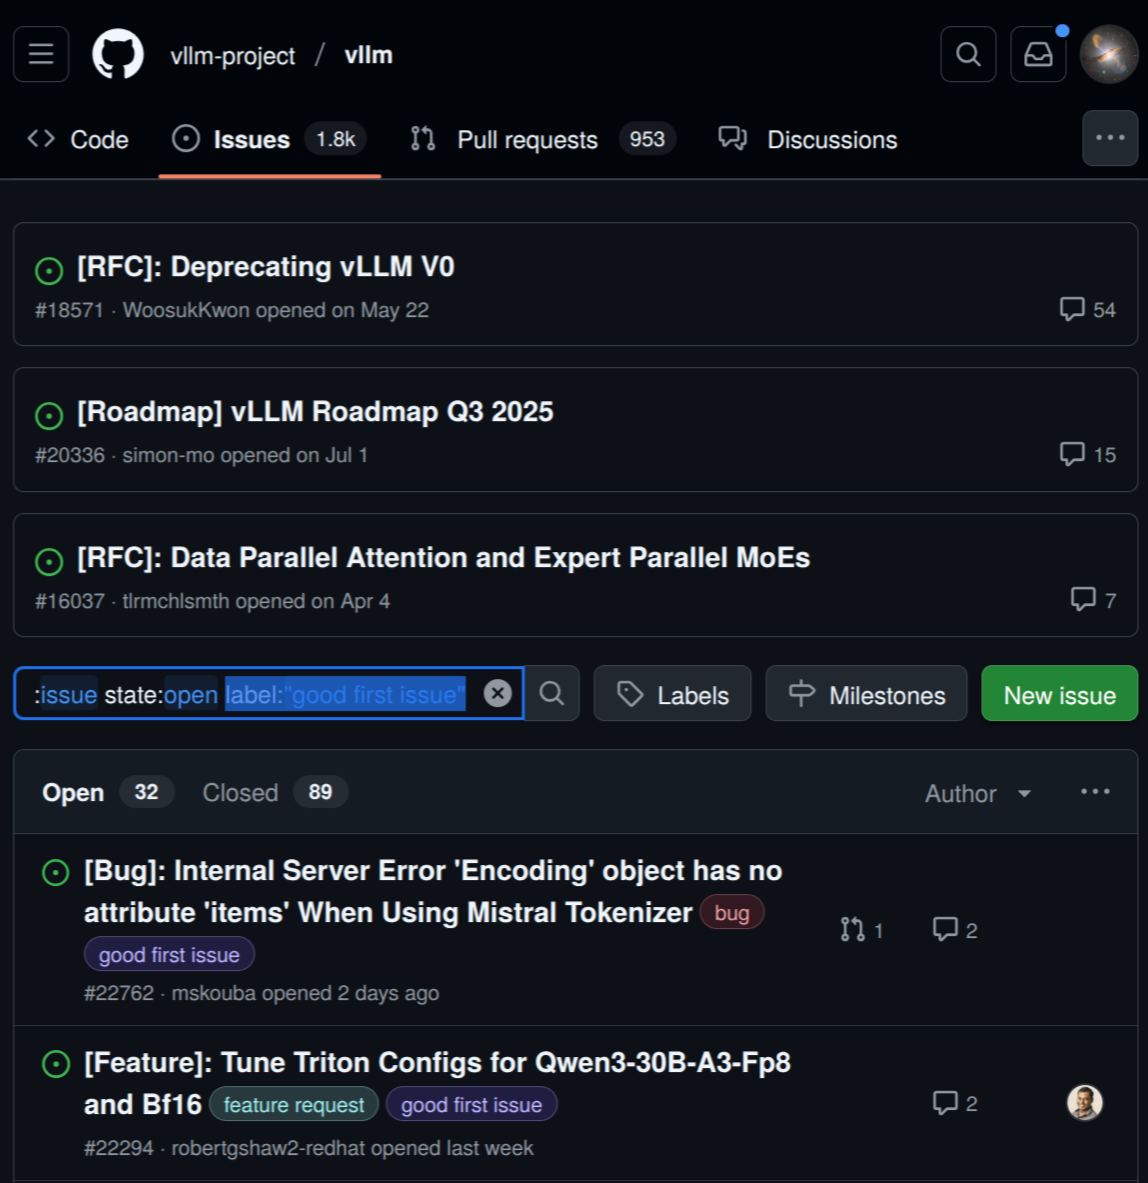
Building, Testing and Contributing to vLLM