
How To Make Llm Inference Faster Ml Ai In Action
How to Make LLM Inference Faster | ML & AI in Action
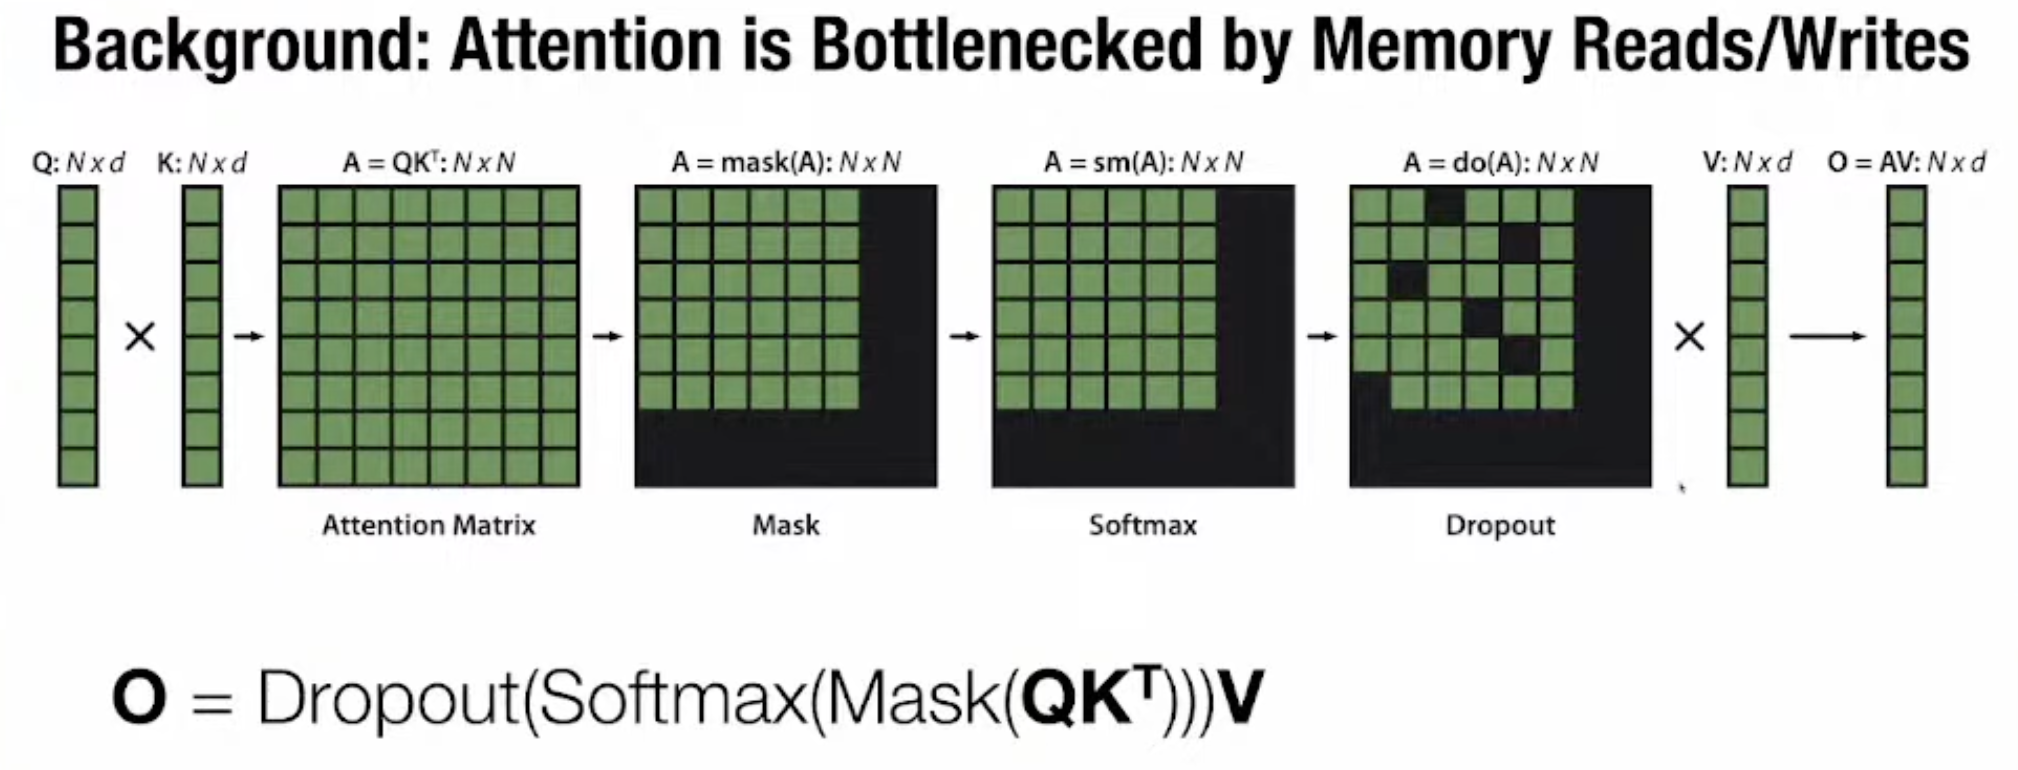
How to Make LLM Inference Faster | ML & AI in Action
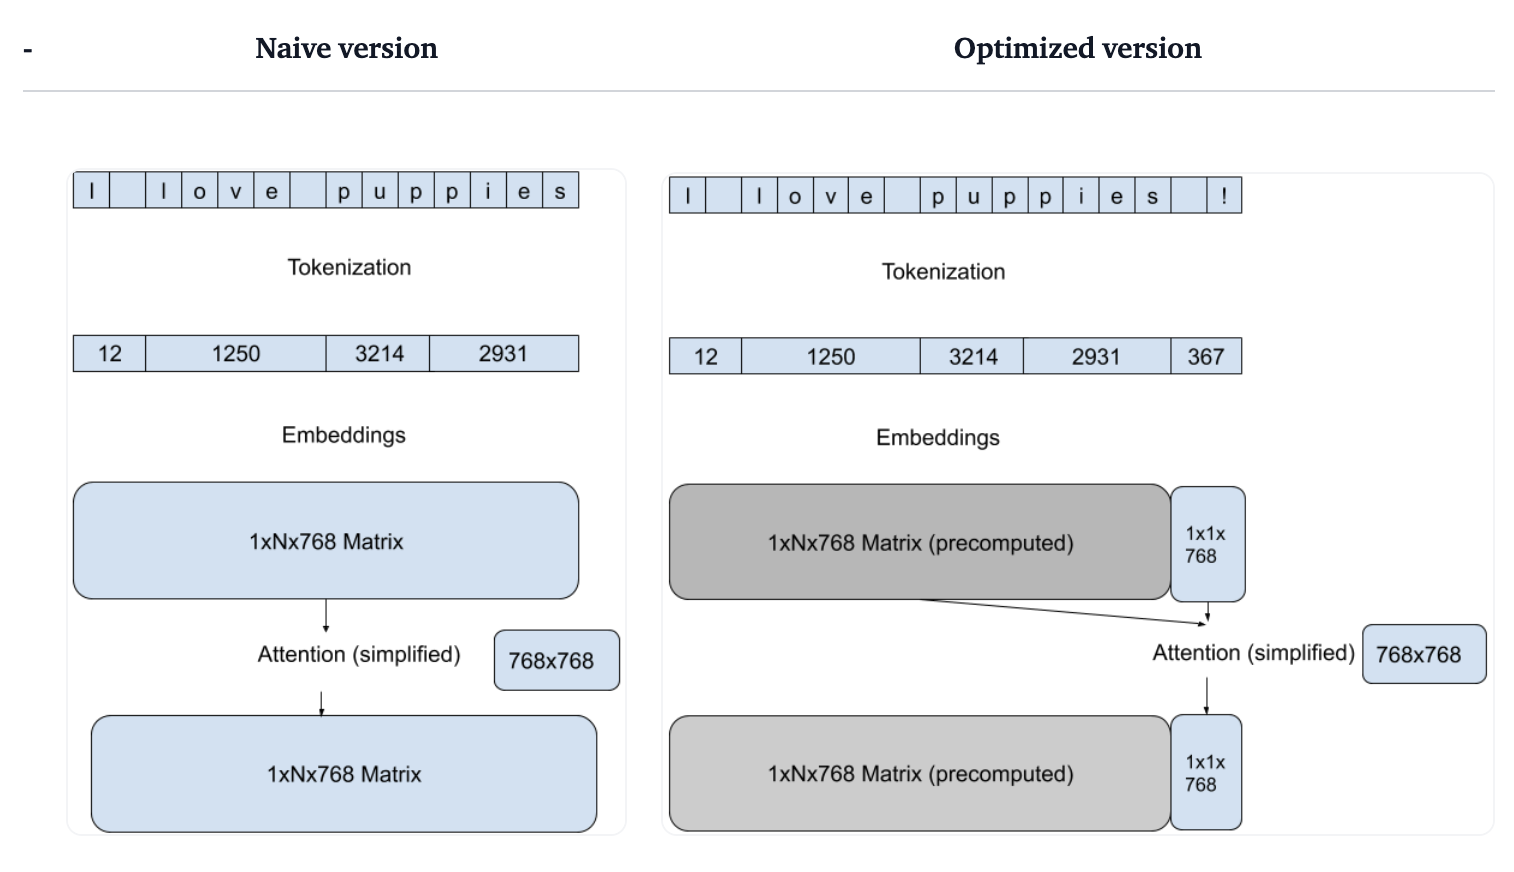
How to Make LLM Inference Faster | ML & AI in Action
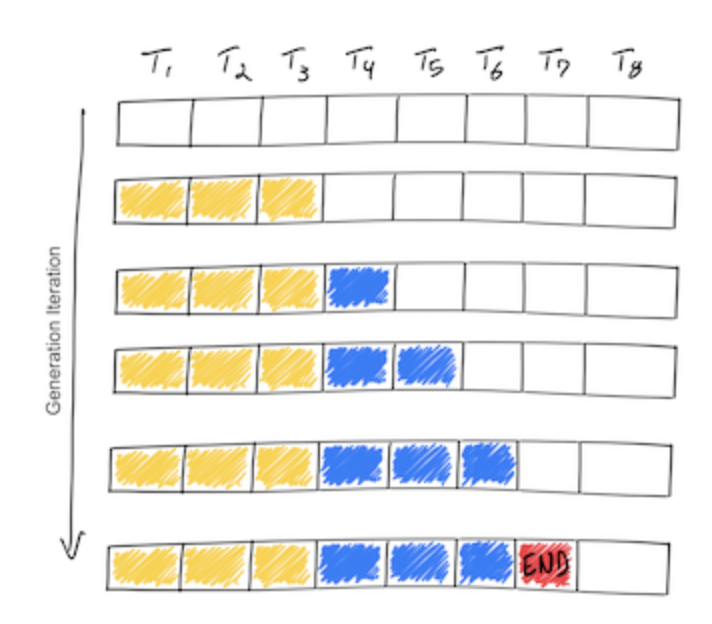
How to Make LLM Inference Faster | ML & AI in Action
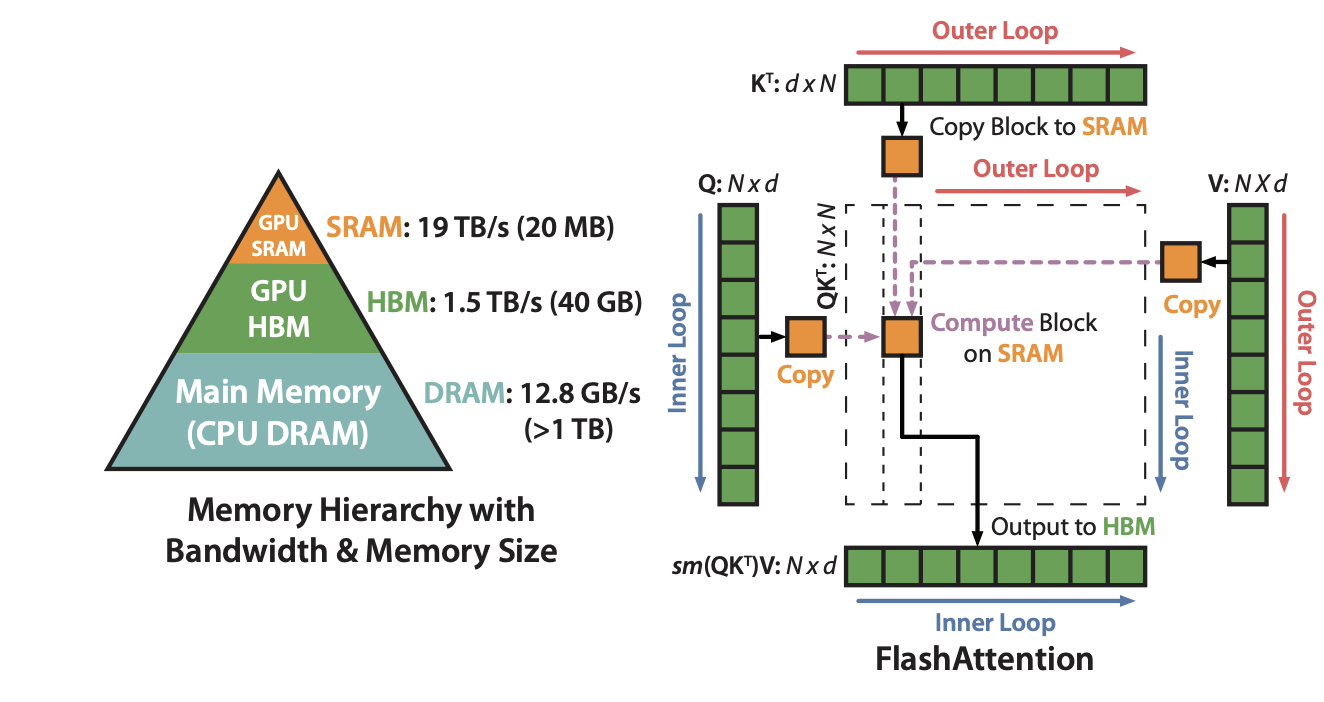
How to Make LLM Inference Faster | ML & AI in Action

LLM Optimization: How to Make AI Inference Faster and Pocket-Friendly!

LLM Optimization: How to Make AI Inference Faster and Pocket-Friendly!

A recipe for 50x faster local LLM inference | AI & ML Monthly - YouTube
LLM Inference Guide: 12 Proven Ways To Speed Up AI Models
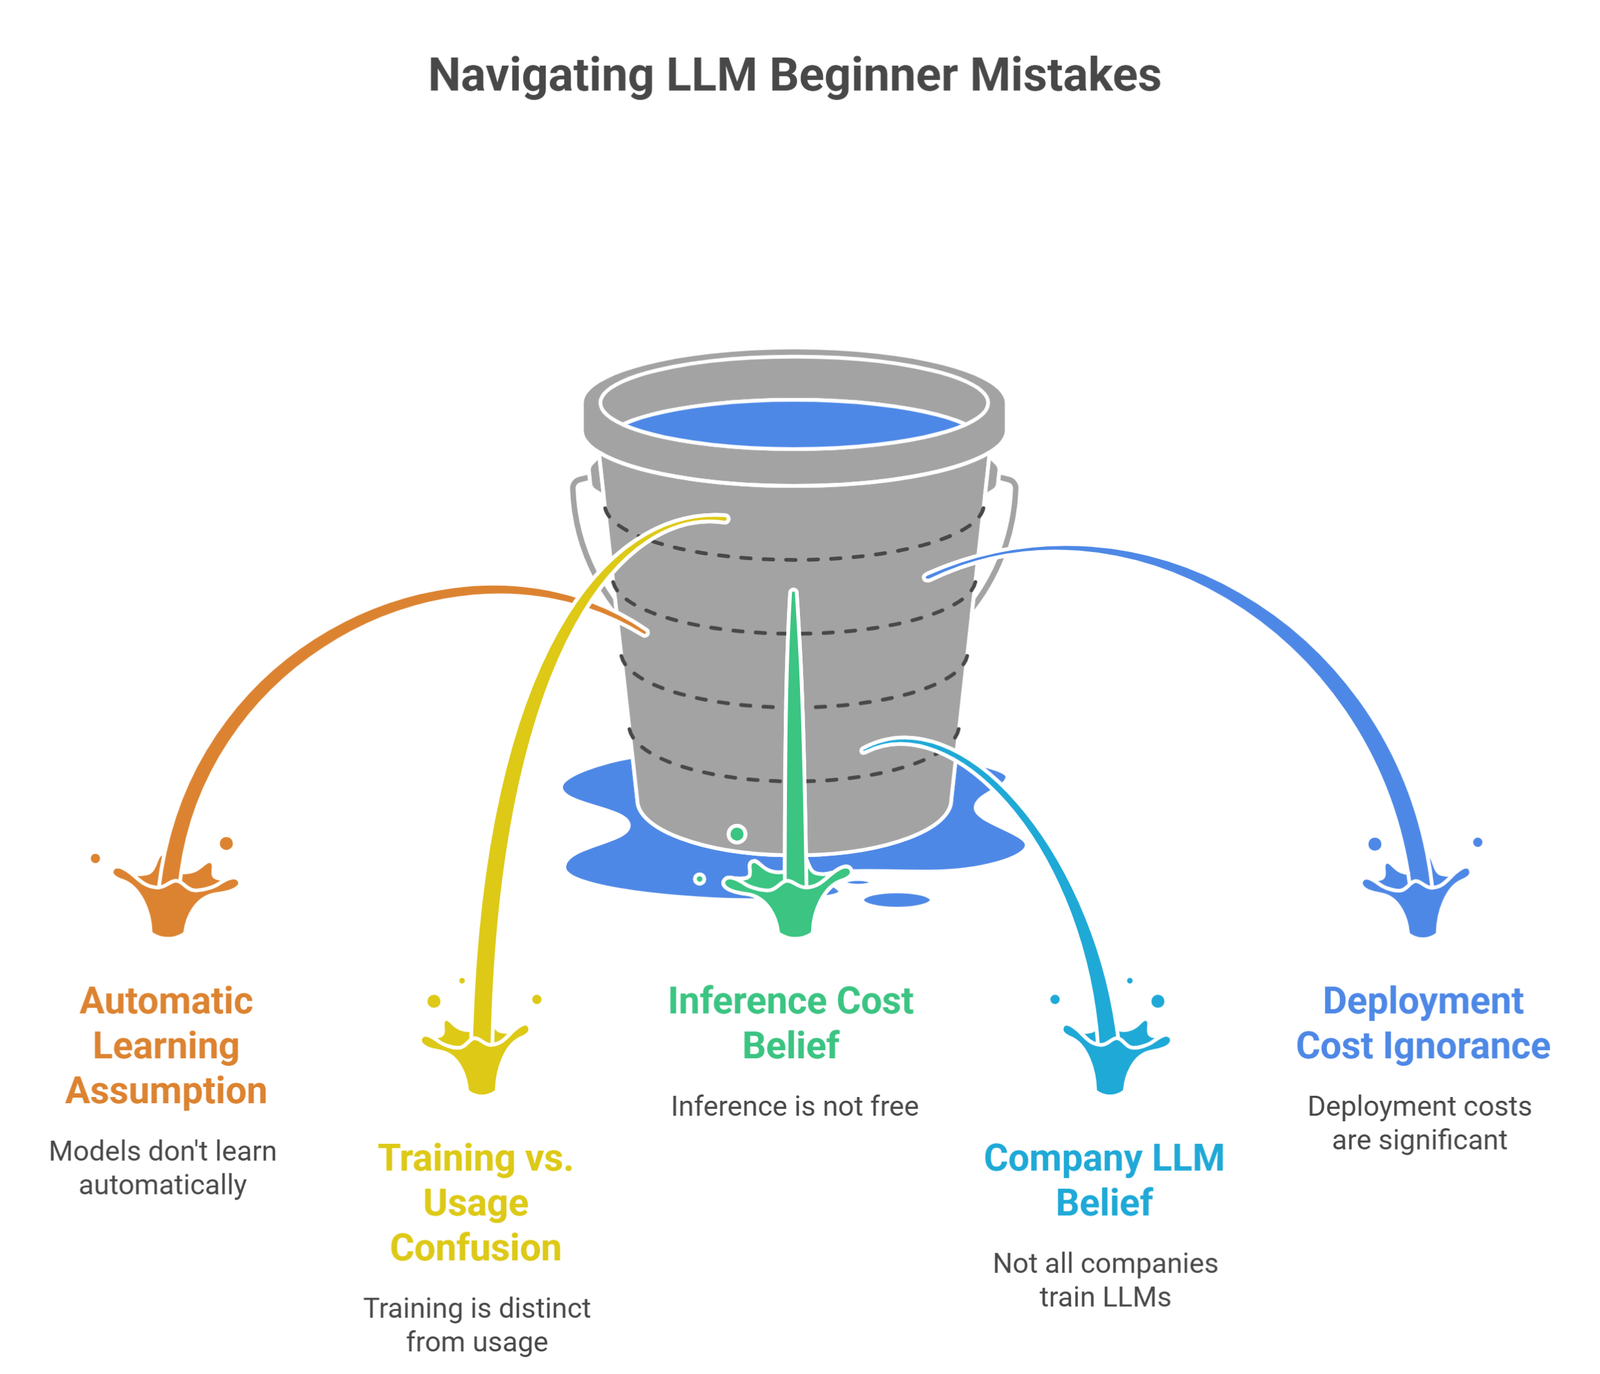
Ultimate Guide to LLM Training vs Inference in 2026 (Easy, Fast ...
Advertisement Space (300x250)

From Analytics to Gen AI: Understanding the AI & ML foundations of LLM ...
LLM Inference Explained for Developers — How AI Models Generate Text

Free Video: How Fast Are LLM Inference Engines Anyway? from AI Engineer ...

How to Select the Right LLM for Your Generative AI Use Case - DjamgaTech
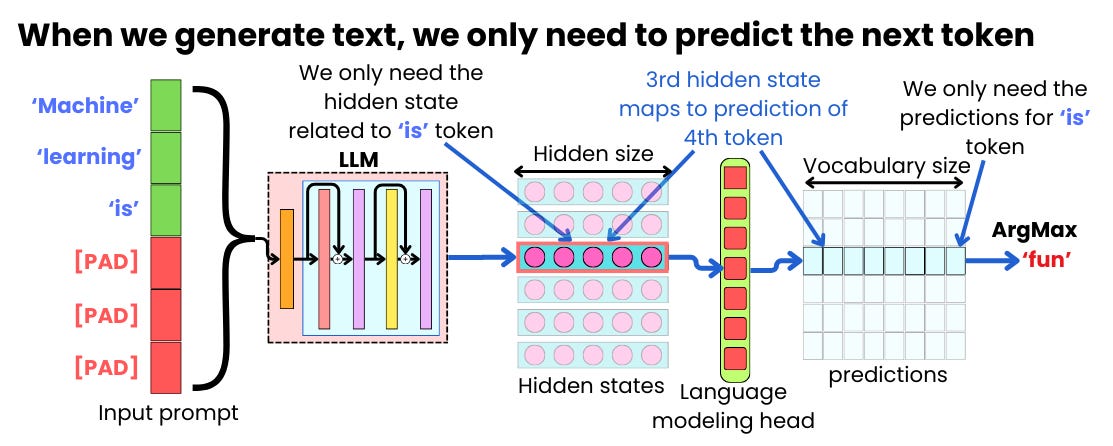
How to Scale LLM Inference - by Damien Benveniste

AI ML DL with LLM subset of deep learning | Leaders in Pharmaceutical ...
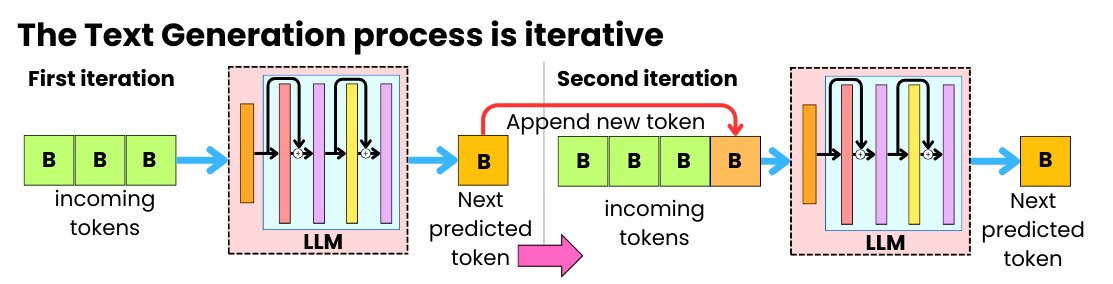
How to Scale LLM Inference - by Damien Benveniste
P-EAGLE: Faster LLM inference with Parallel Speculative Decoding in ...

Optimizing AI Performance: A Guide to Efficient LLM Deployment

Star Attention: Efficient LLM Inference over Long Sequences | AI ...
Advertisement Space (336x280)
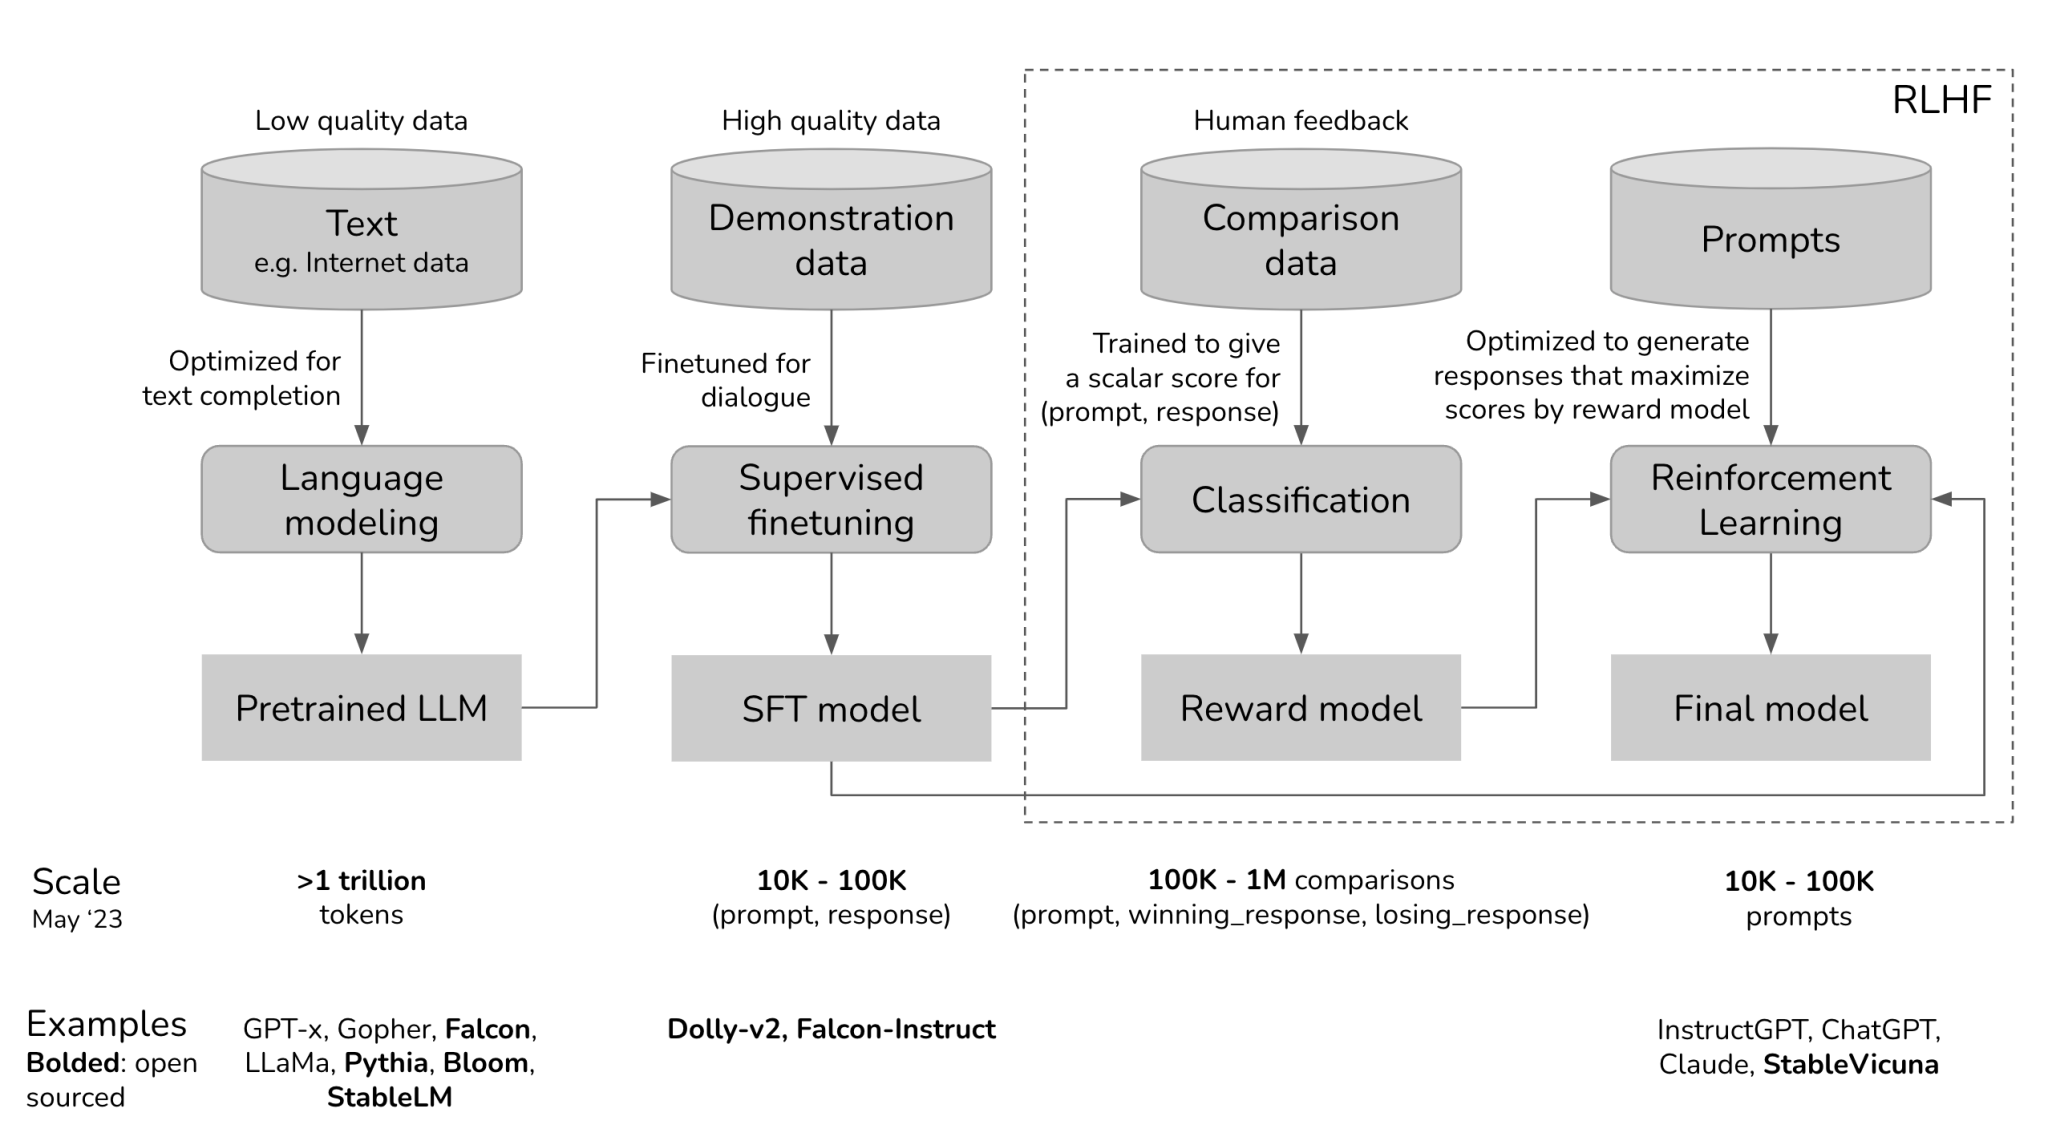
How To Build LLM (Large Language Models): A Definitive Guide

LLM Inference Acceleration via Efficient Operation Fusion | AI Research ...
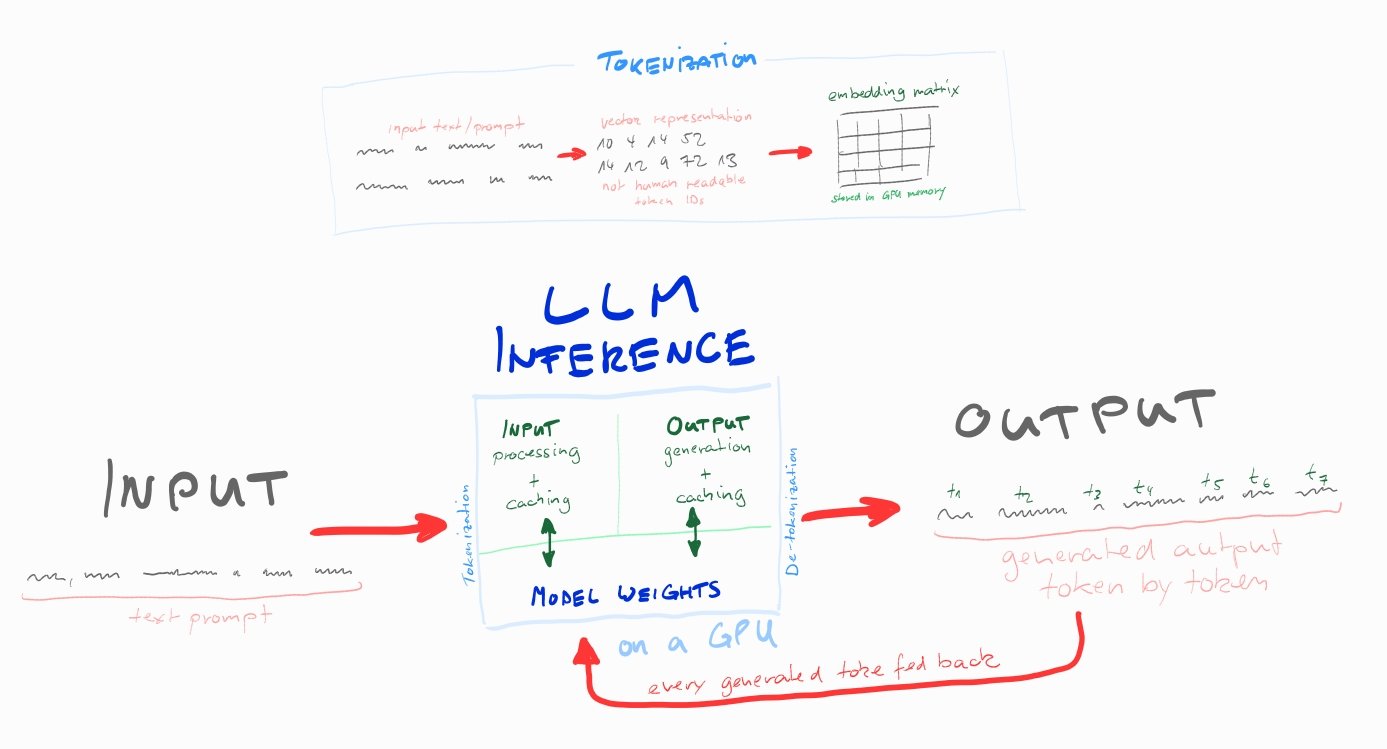
AI — LLM Inference Service – Victor Penso
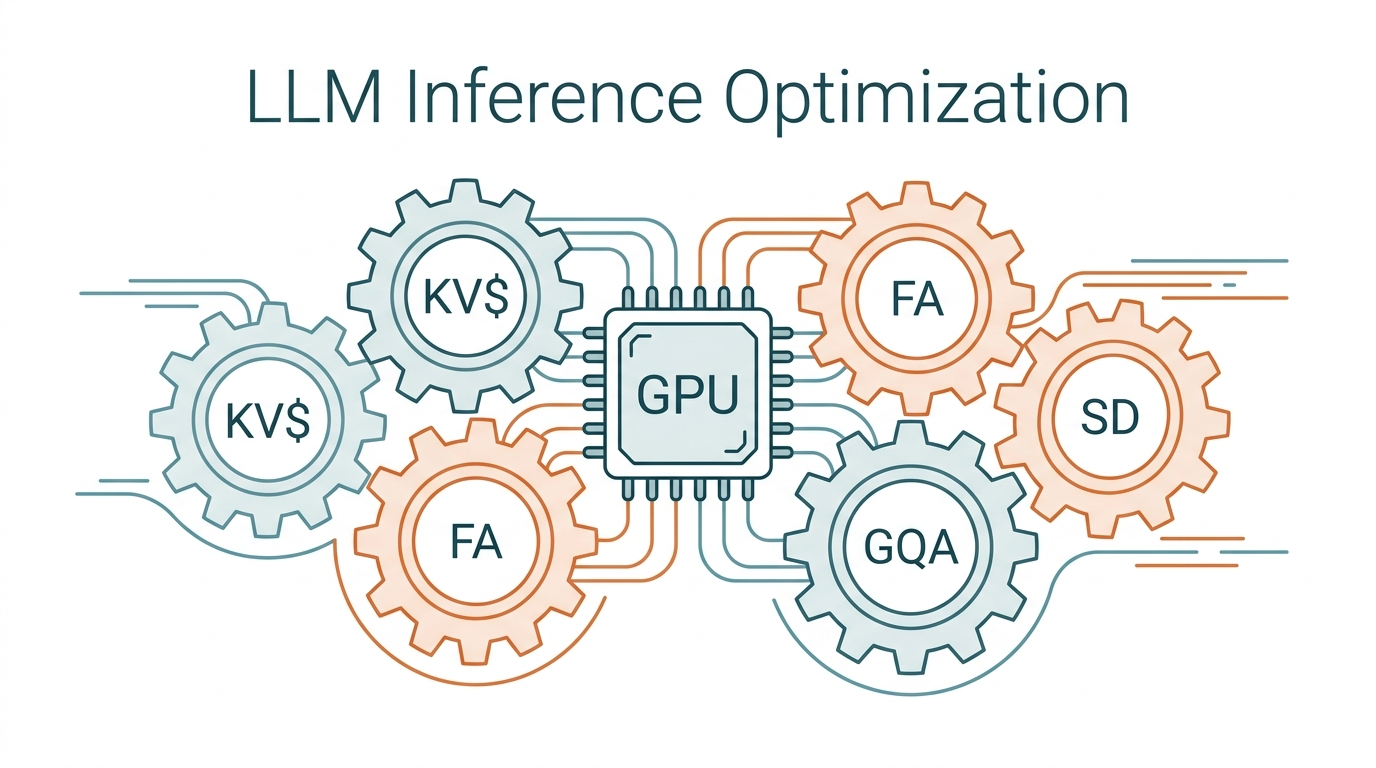
Why Is AI Getting Faster? Six Techniques Behind LLM Inference Acceleration
Why is LLM Inference Optimization Important in 2026?

Implementing ML & LLM in your Business | Inwedo Blog

🤖 AI vs ML vs LLM vs Generative AI: The Ultimate Simple Story That ...
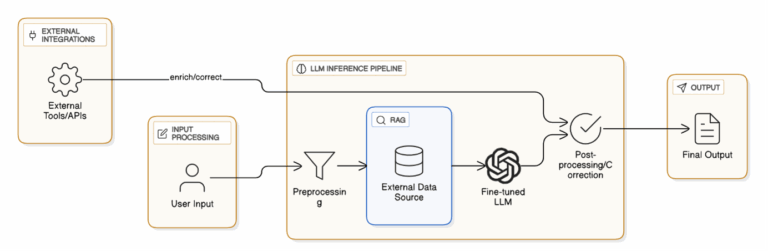
Taming the LLM Using AI Inference - Architecture & Governance Magazine
LLM Inference Basics — From Prompt to Response | tutorialQ
Understanding LLM Inference: How AI Generates Words | DataCamp
Advertisement Space (336x280)
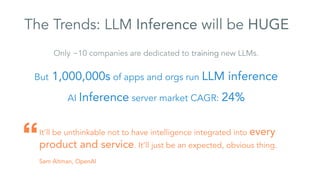
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
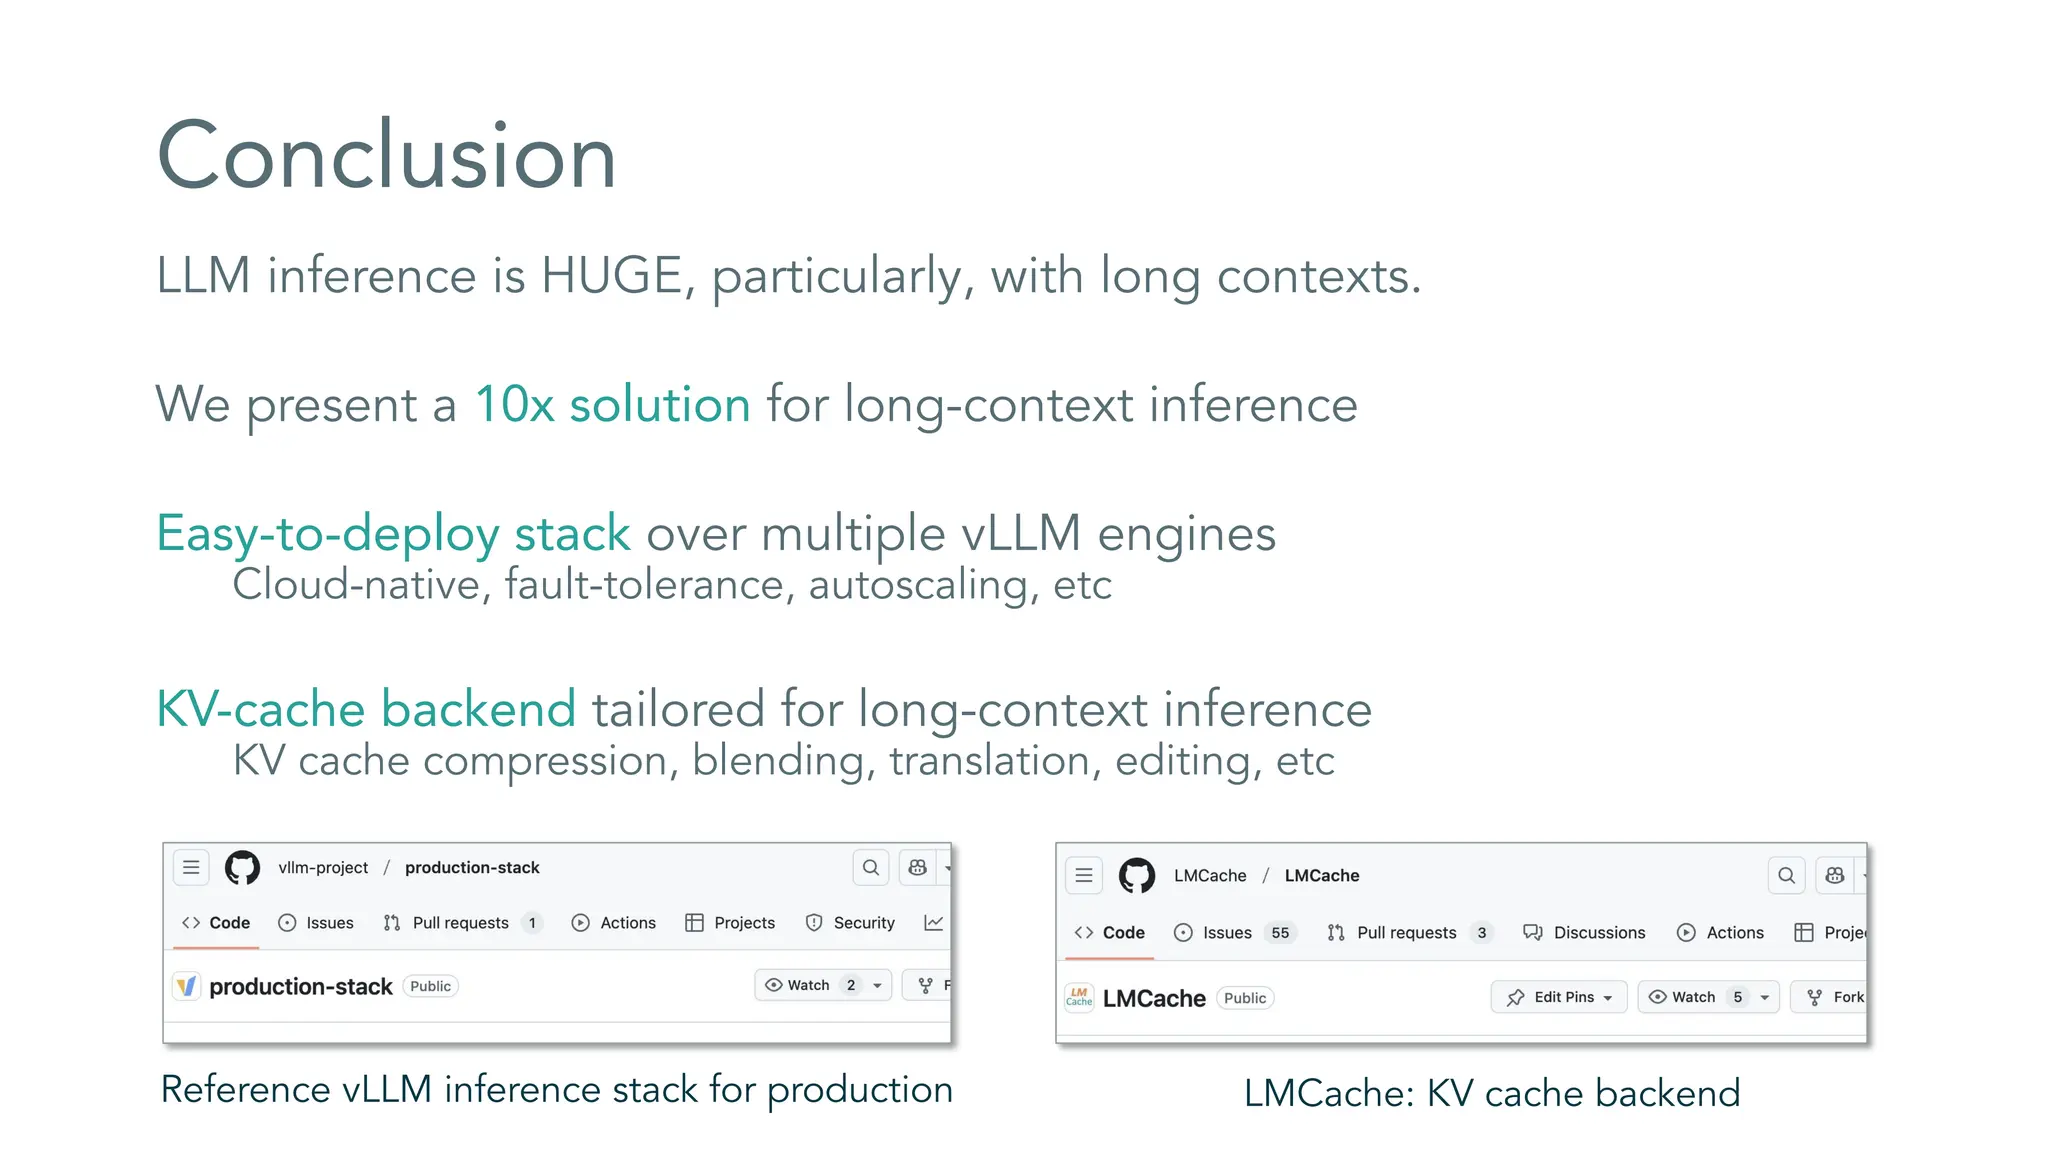
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

Achieve ~2x speed-up in LLM inference with Medusa-1 on Amazon SageMaker ...

KLLM: Fast LLM Inference with K-Means Quantization | AI Research Paper ...
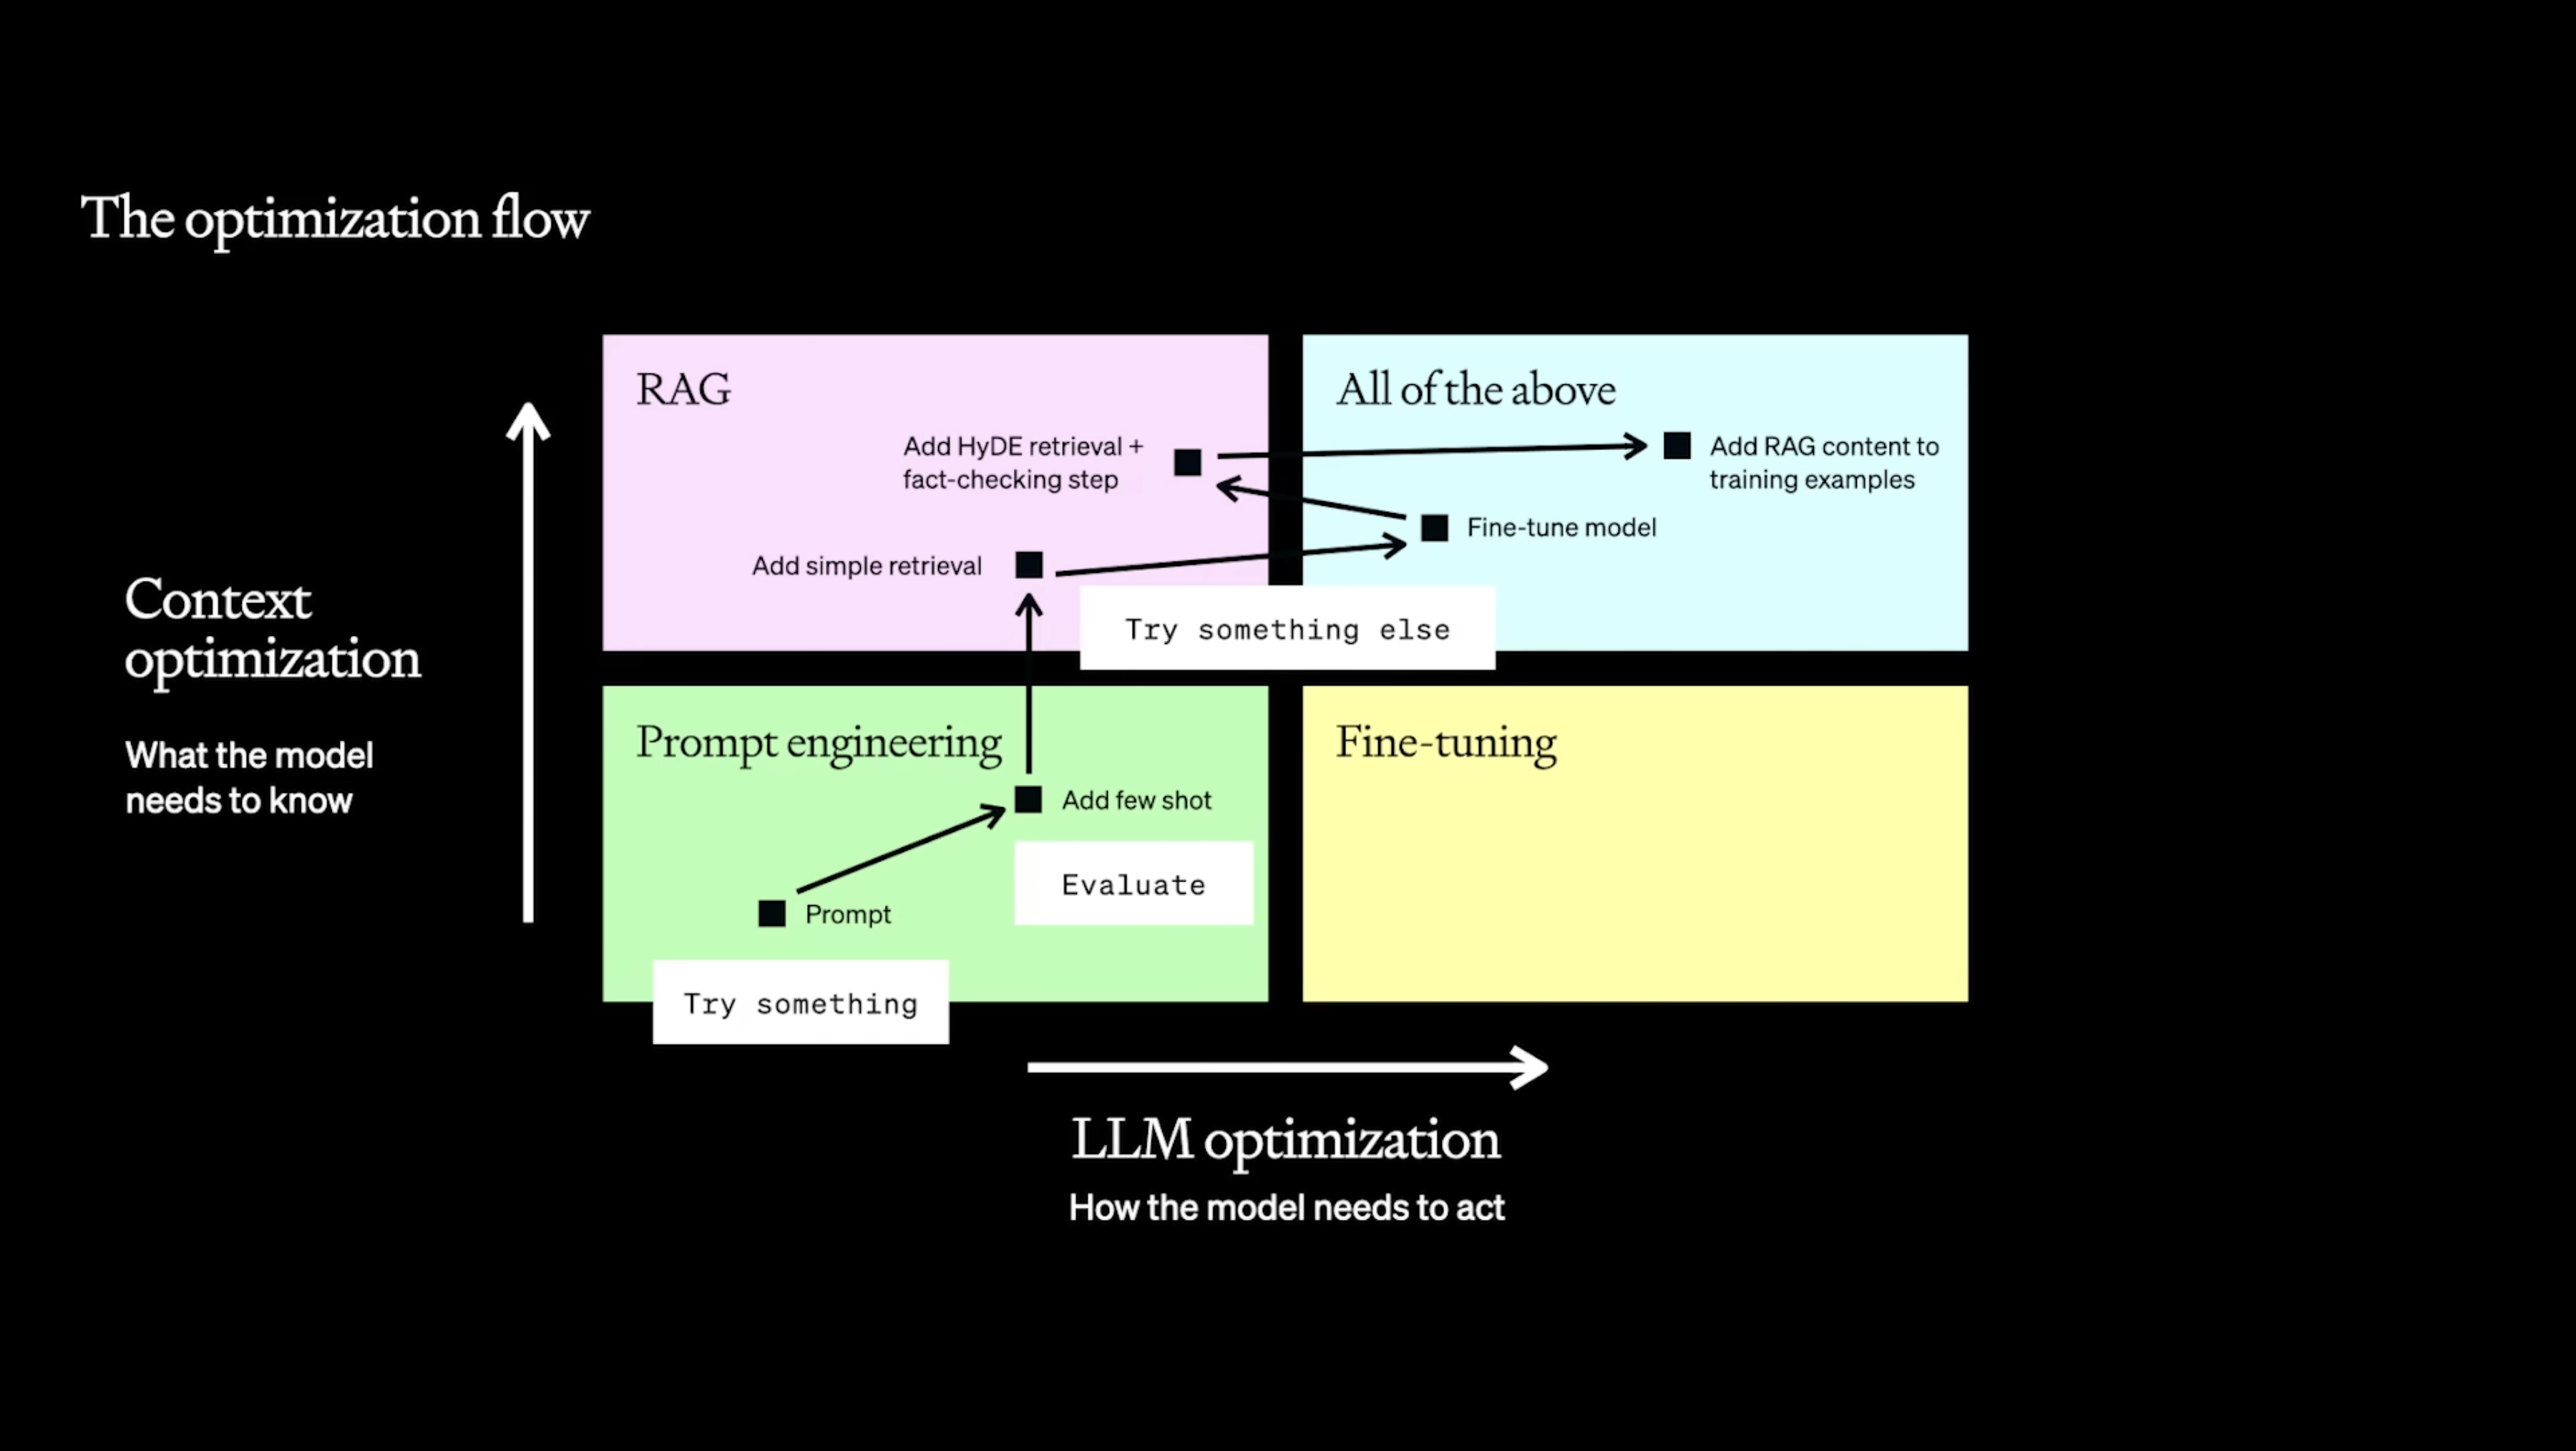
AI 系列:How to Maximize LLM Performance(原文) | ningg.top
Trace LLM Inference Pipelines for Factory AI with Langfuse and BentoML ...