
How To Run Llm Inference With Vllm In Docker
How to Run LLM Inference with vLLM in Docker

How to Deploy vLLM in Production with Docker (2026) | Yotta Labs

New Course! Enroll in Fast & Efficient LLM Inference with vLLM - News ...

Run OpenAI-compatible LLM inference with Qwen and vLLM | Modal Docs

How to easily migrate LLM inference serving from vLLM to Friendli ...

How To Run Models (LLM) Locally with Docker | Snyk
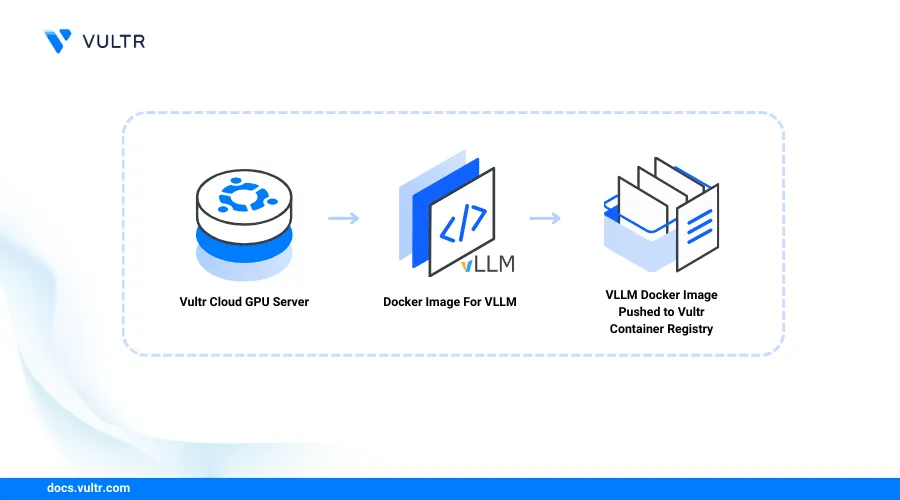
How to Build a vLLM Container Image for LLM Deployment | Vultr Docs
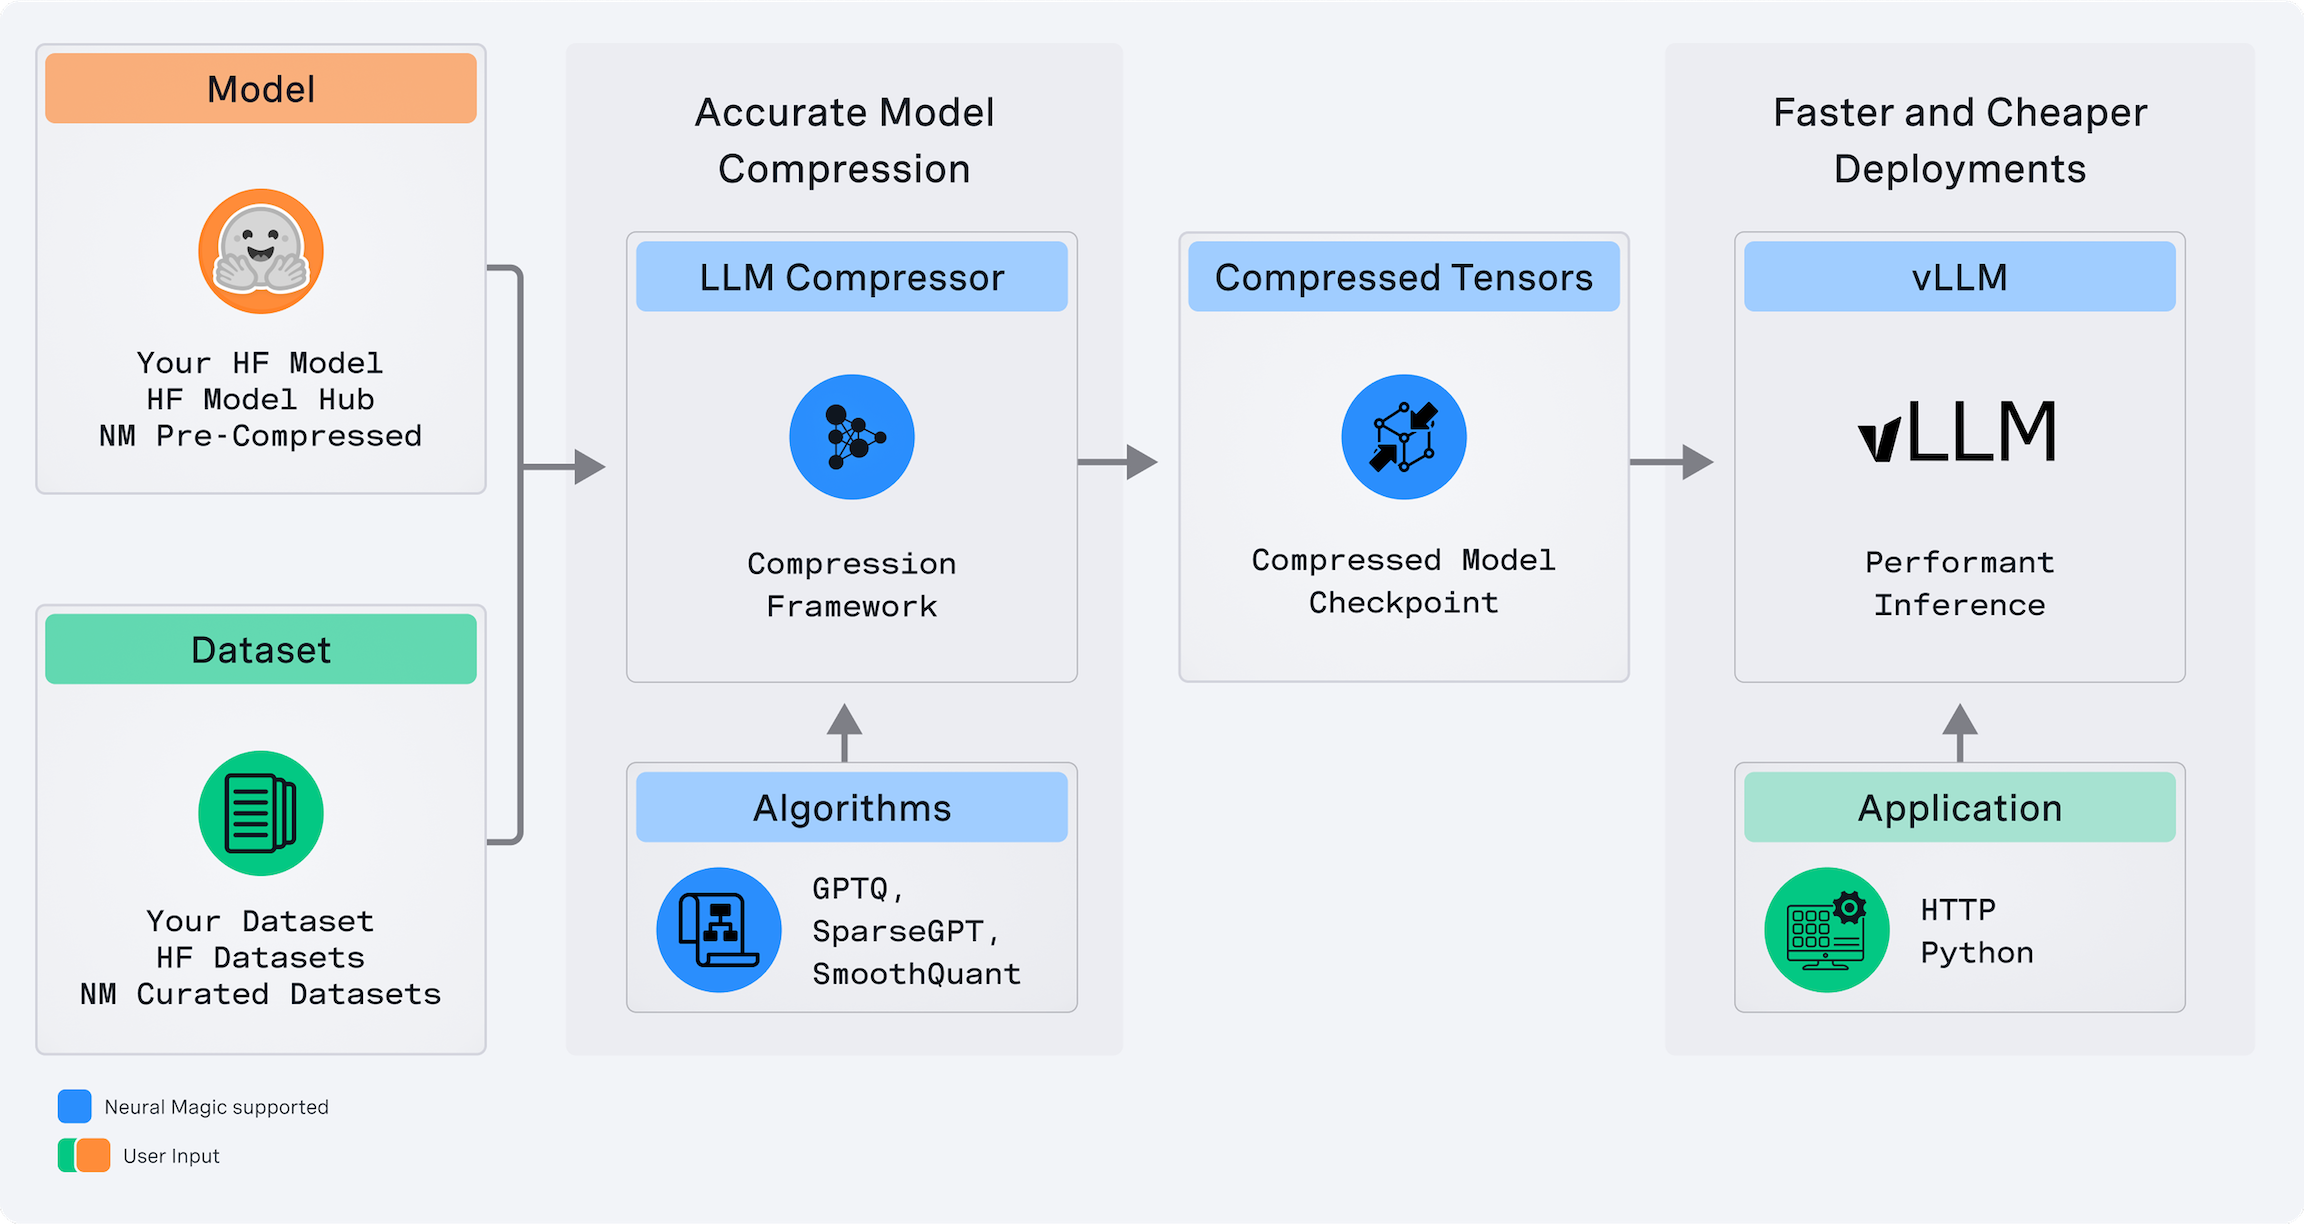
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

How vLLM and Docker are Changing the Game for LLM Deployments - Collabnix

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
Advertisement Space (300x250)

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...

How to Run VLLM on Windows Docker: Simple Guide - Novita
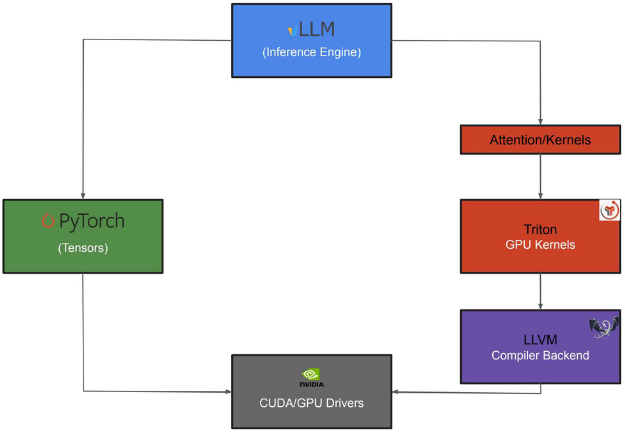
LLM Inference with vLLM Using GPU on Power9
Free Video: How to Deploy LLMs - LLMOps Stack with vLLM, Docker ...
Efficient LLM Inference and Serving with vLLM

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...

Deploying vLLM with Docker: The Complete Guide to Production-Ready LLM ...
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...

Supercharge LLM Inference with vLLM
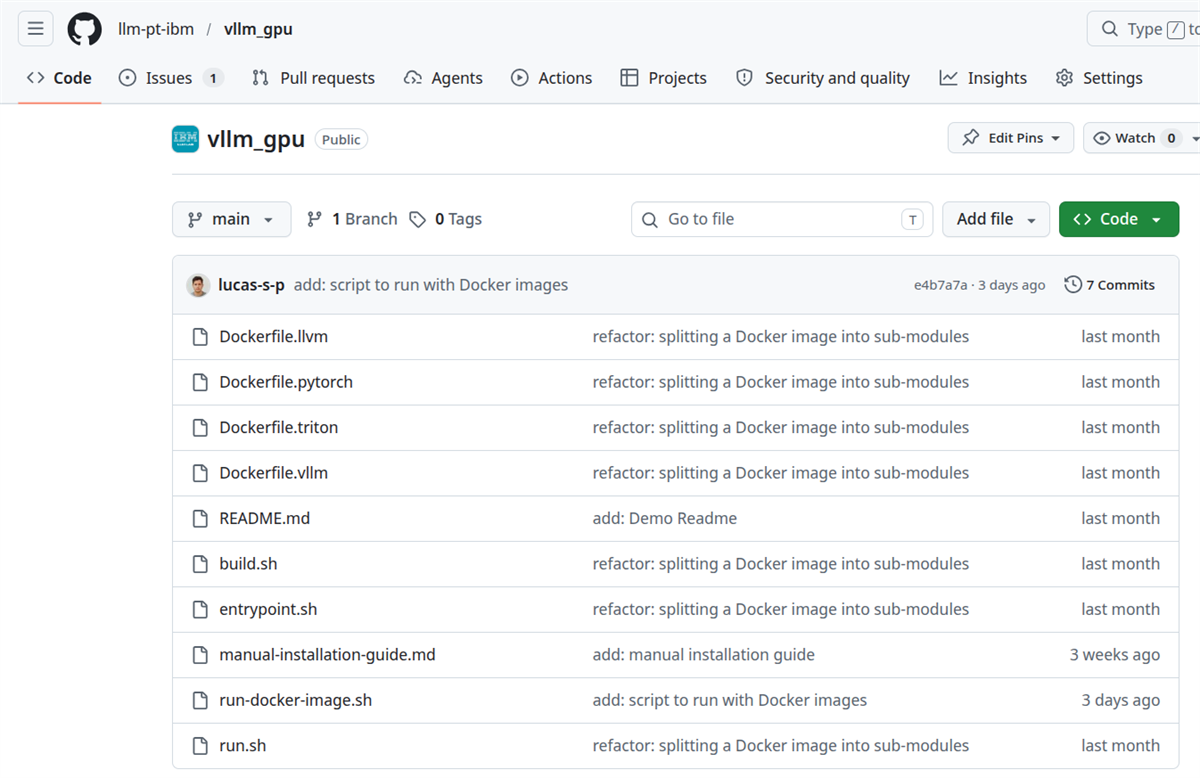
LLM Inference with vLLM Using GPU on Power9
Advertisement Space (336x280)

Scaling LLM inference with Ray and vLLM
Optimize LLM inference with vLLM - YouTube
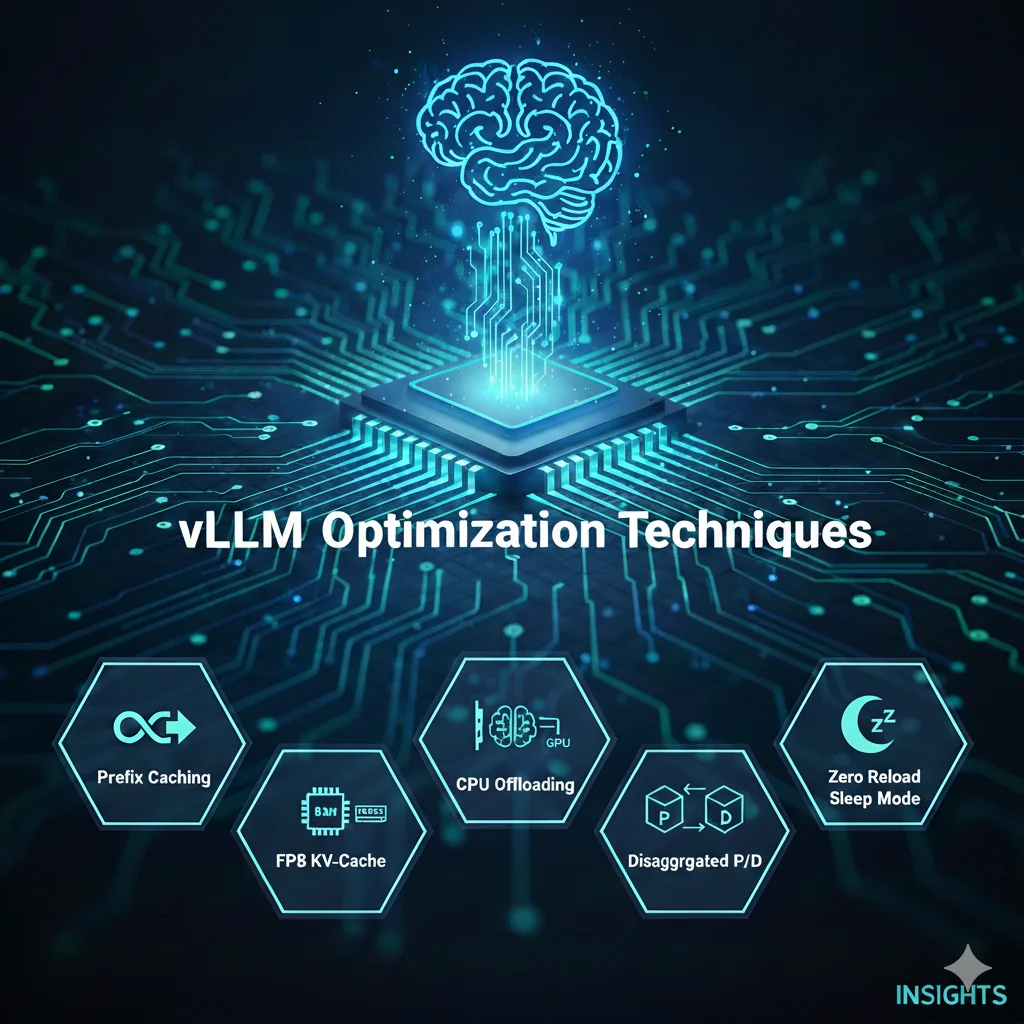
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
A Brief Introduction to Optimized Batched Inference with vLLM | by ...
Best LLM Inference Engines and Servers to Deploy LLMs in Production - Koyeb

Using Fine-Tuned LLM with vLLM. In this blog, I’ll show you a quick tip ...

Docker Model Runner Adds vLLM for Fast AI Inference
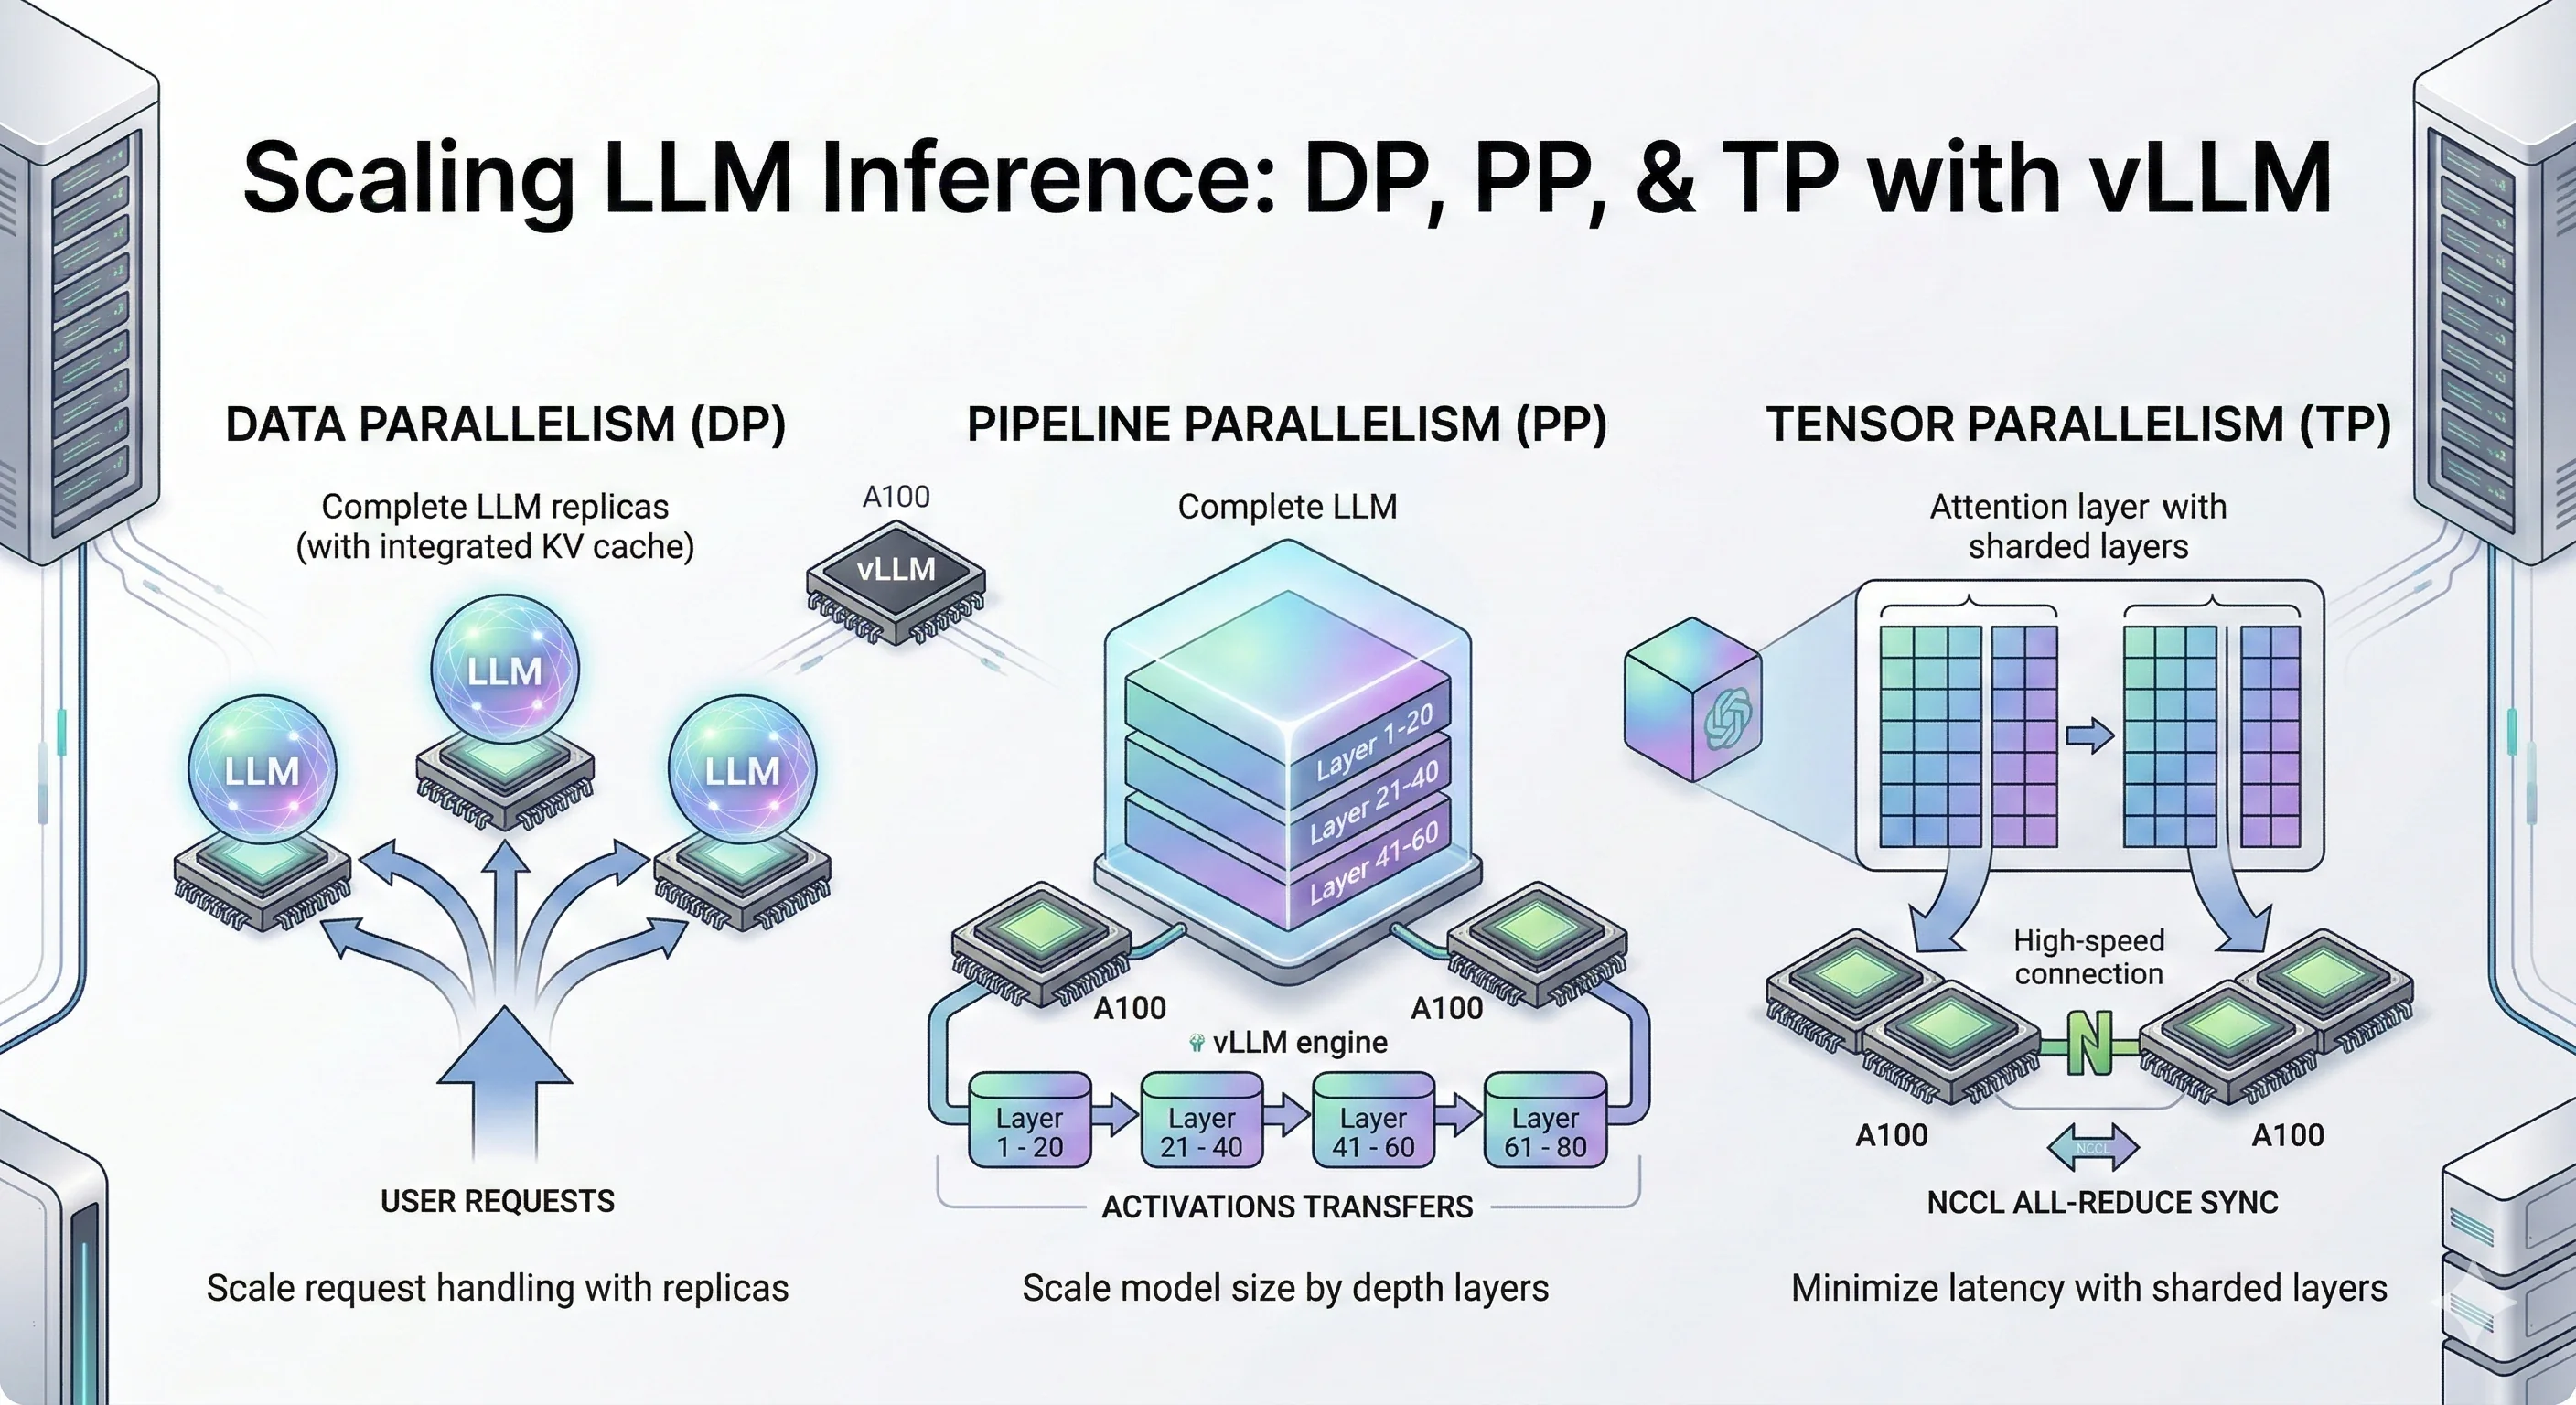
The Complete Guide to LLM Quantization with vLLM: Benchmarks & Best ...
Discussion on "Deploying vLLM with Docker: The Complete Guide to ...
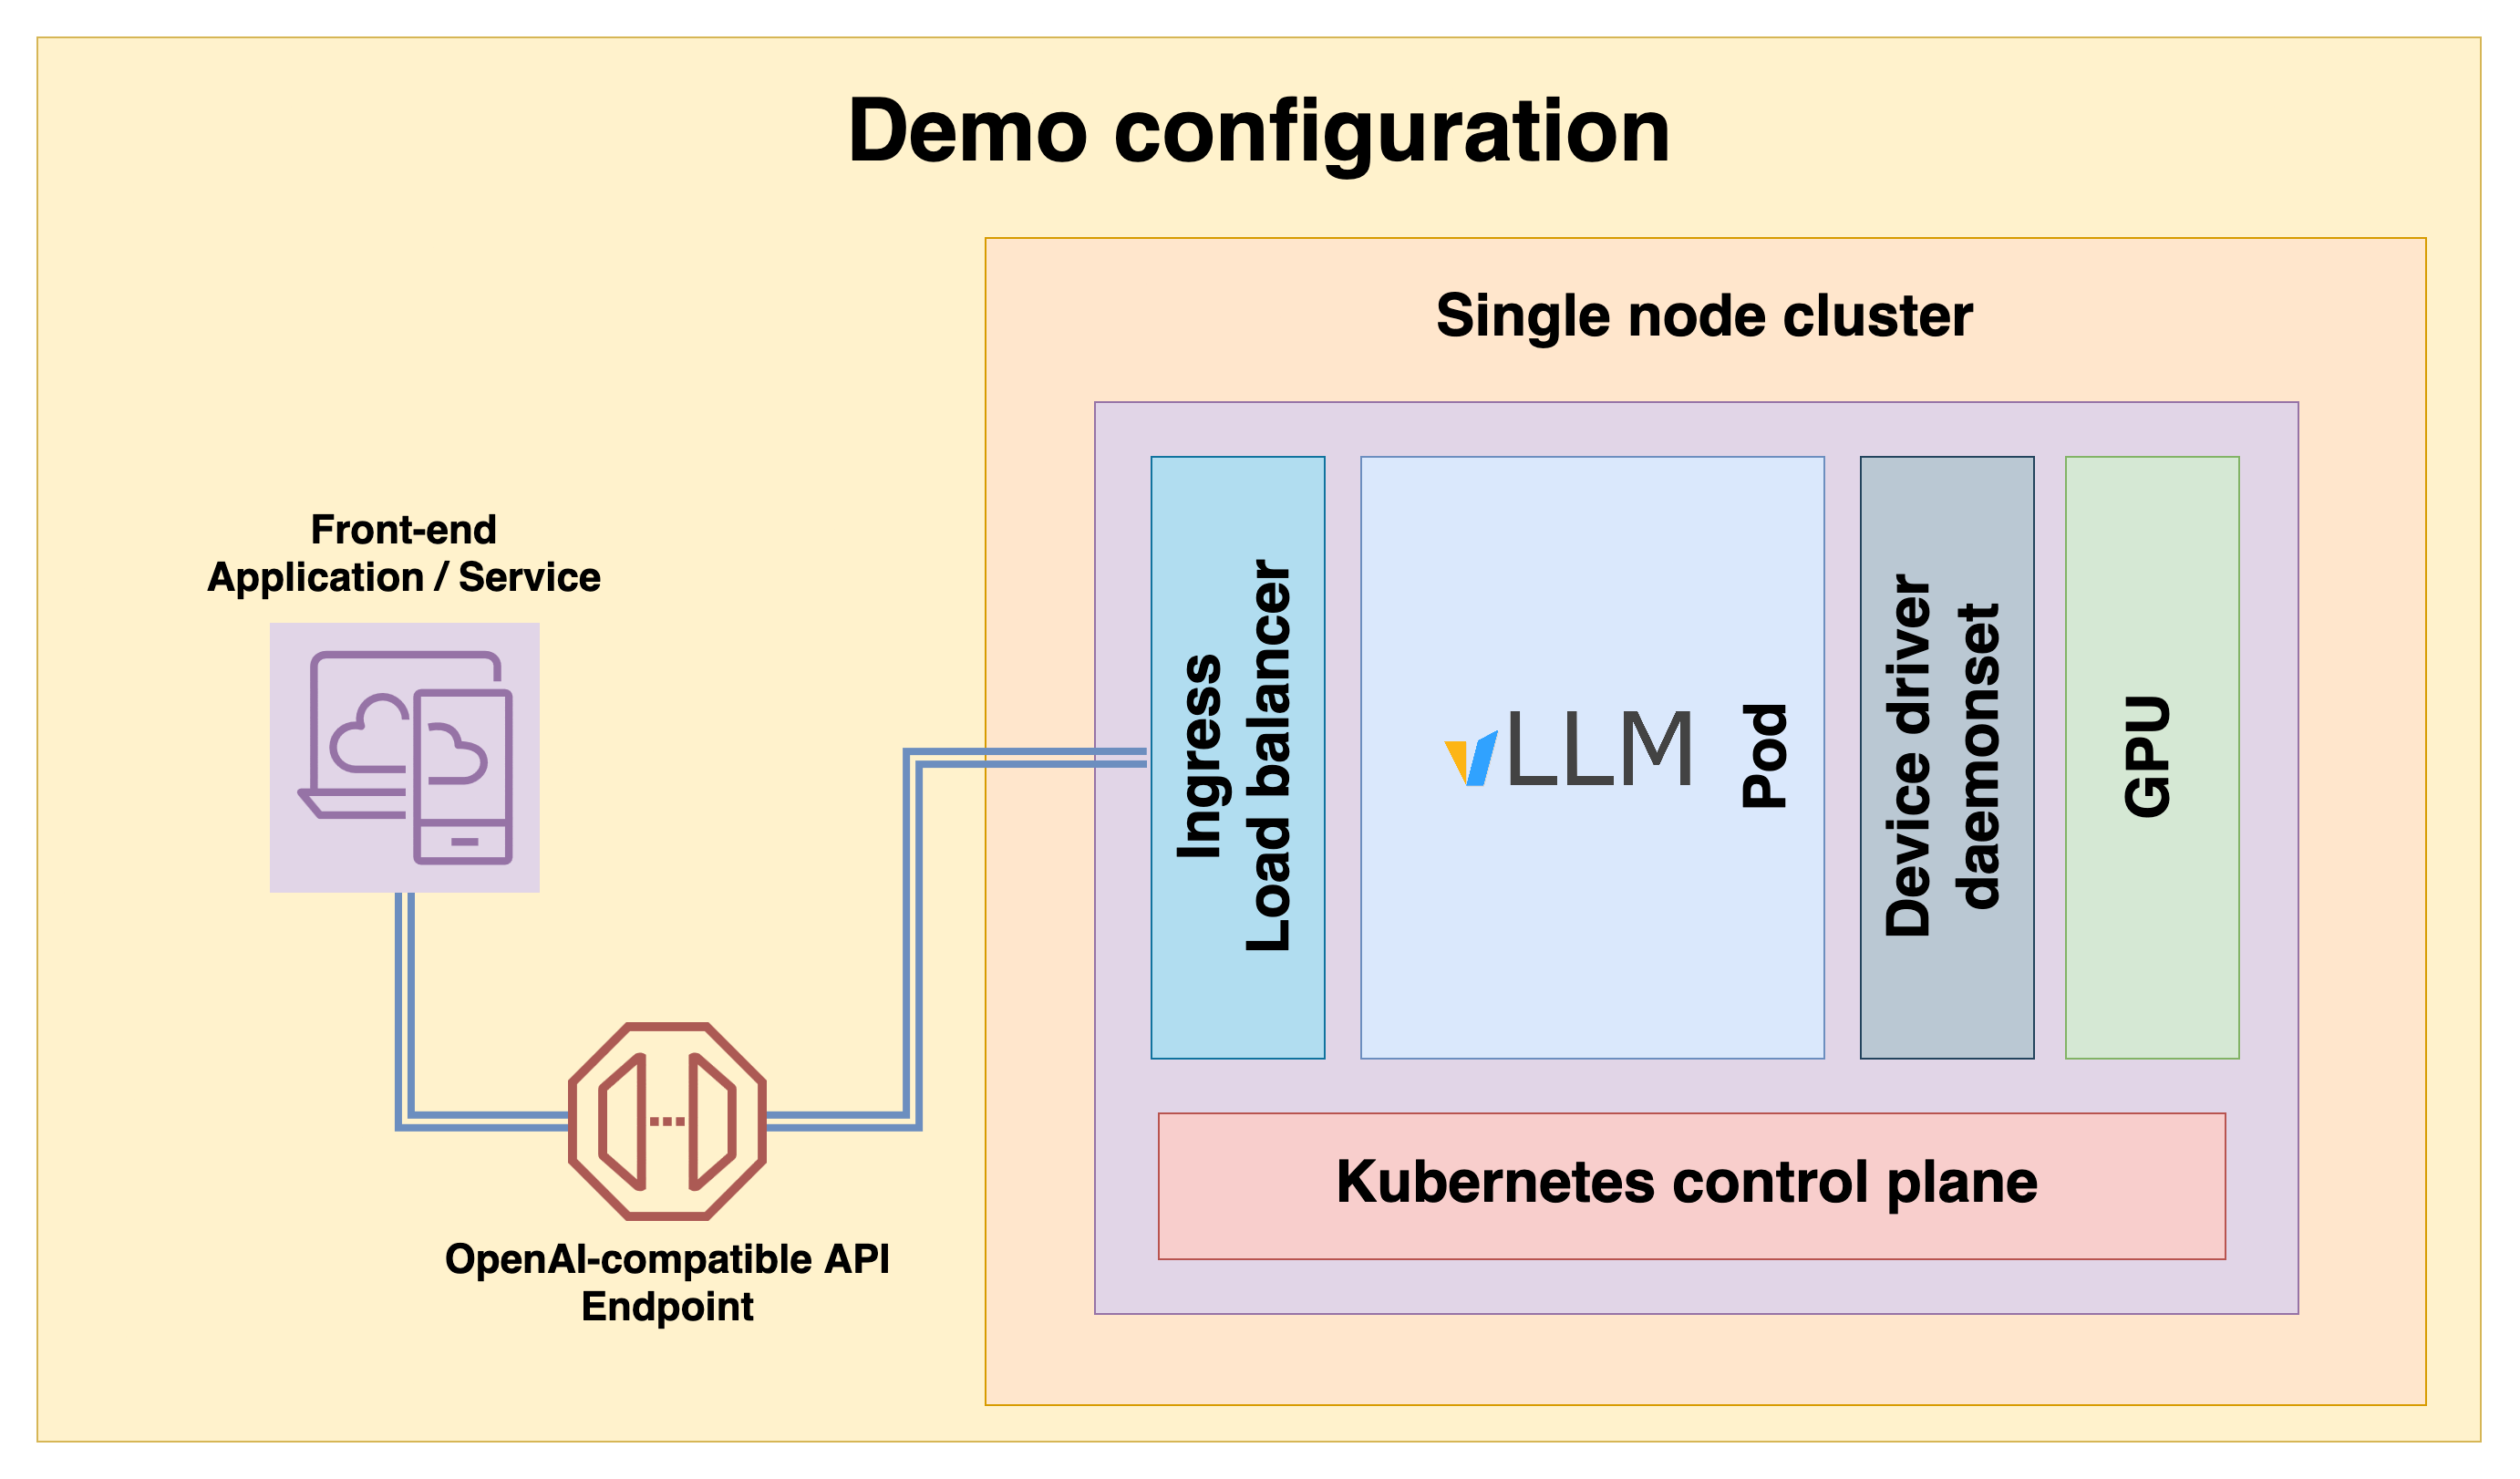
How to deploy LLMs in production • The Register
Advertisement Space (336x280)
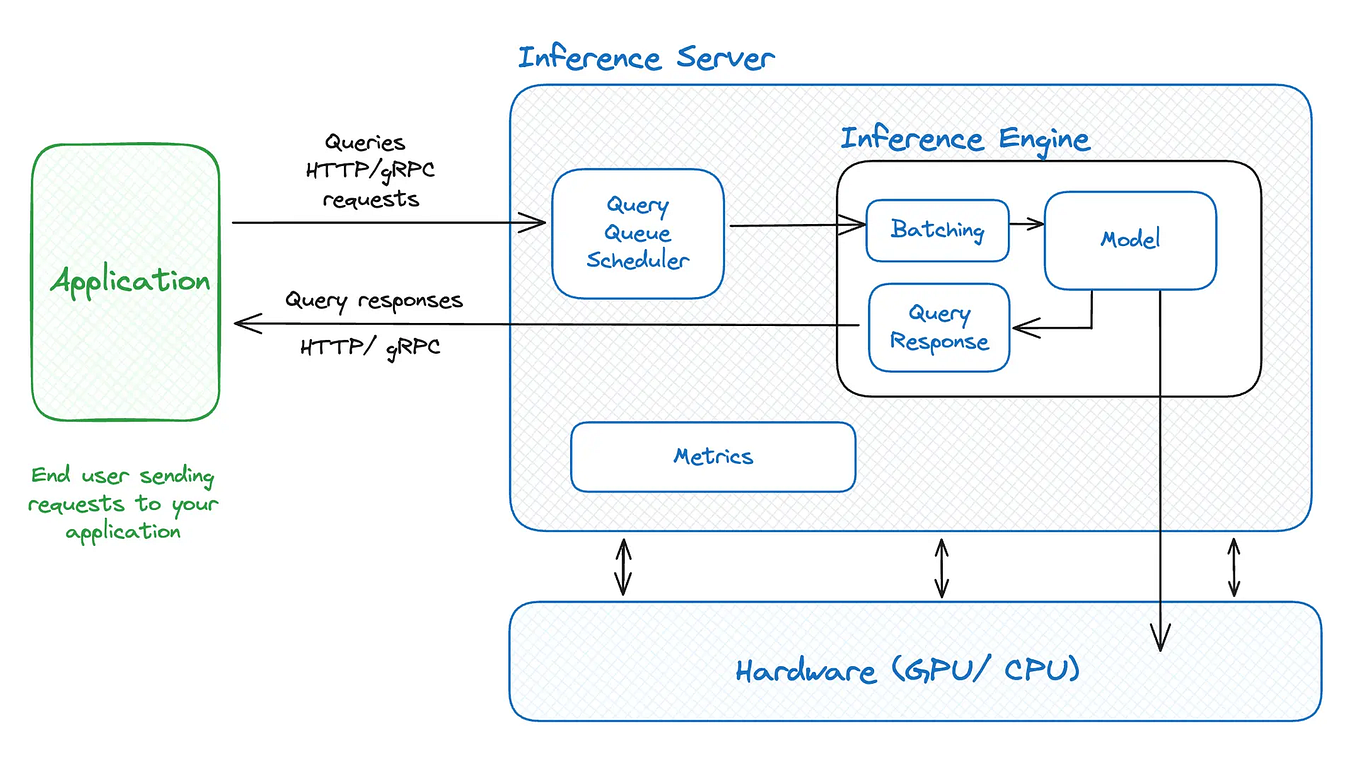
LLM Deployment with vLLM. In the rapidly evolving landscape of… | by ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

Run A Local LLM Across Multiple Computers! (vLLM Distributed Inference ...

vLLM Review: High-Performance LLM Inference Engine for GPU ...