
Improving Llm Robustness Using Rigorous Verification Loop By

Improving LLM robustness using rigorous verification loop | by ...

A Dialectic Pipeline for Improving LLM Robustness | AI Research Paper ...

Benchmarking and Improving LLM Robustness for Personalized Generation ...

Improving Human Verification of LLM Reasoning through Interactive ...

Improving Robustness of LLM-based Speech Synthesis by Learning ...

Improving LLM Unlearning Robustness via Random Perturbations

Improving LLM Unlearning Robustness via Random Perturbations

Verification in Llm Topic 2024 | Sukai Huang
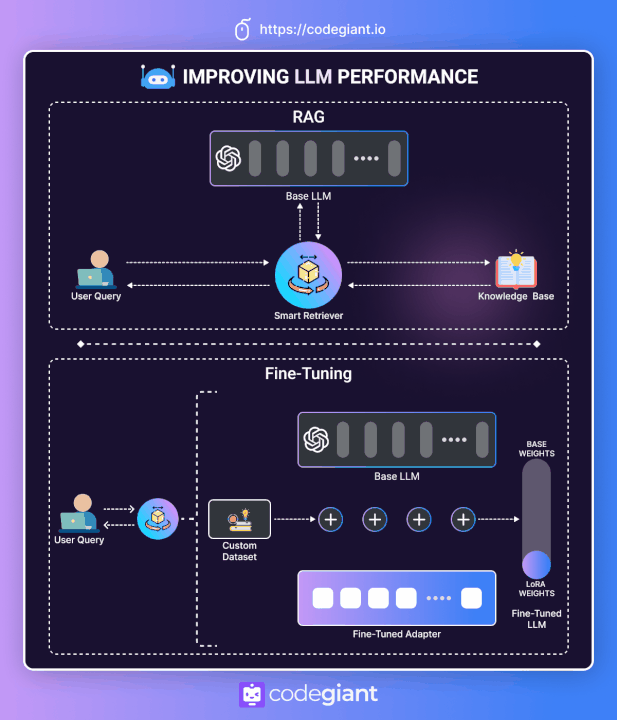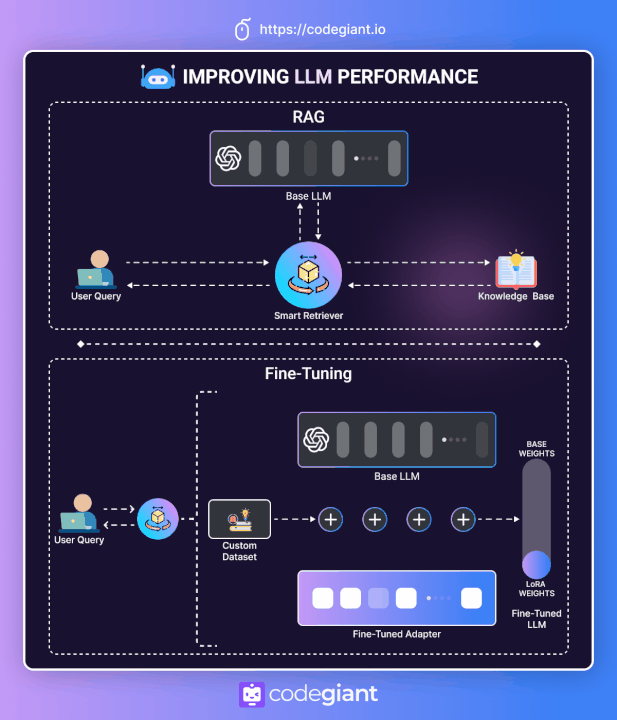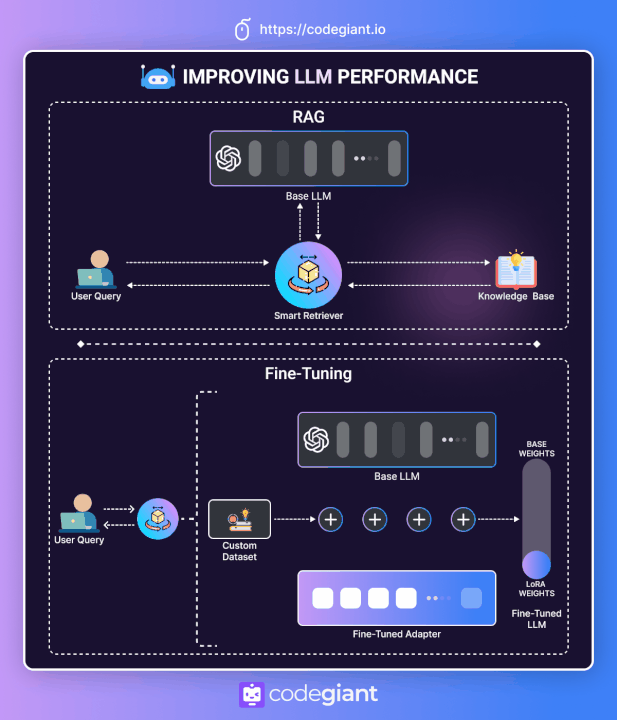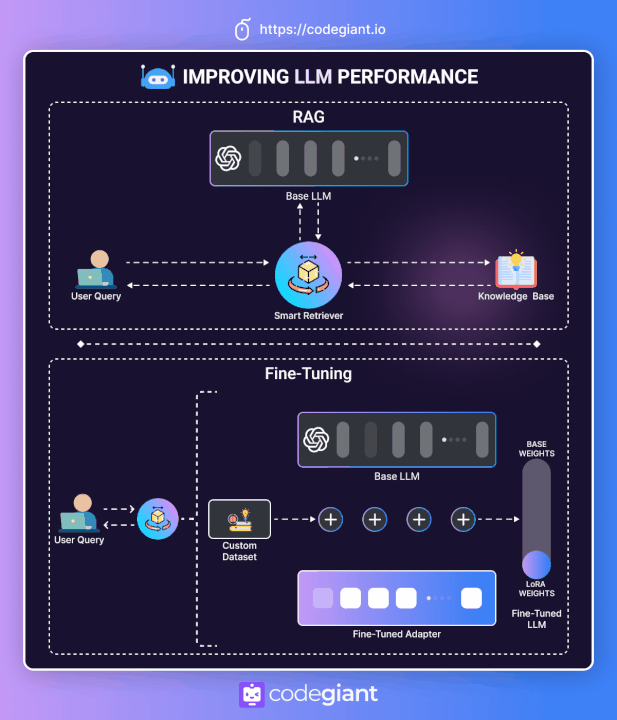
Improving LLM performance

Reasoning with Confidence: Efficient Verification of LLM Reasoning ...
Advertisement Space (300x250)
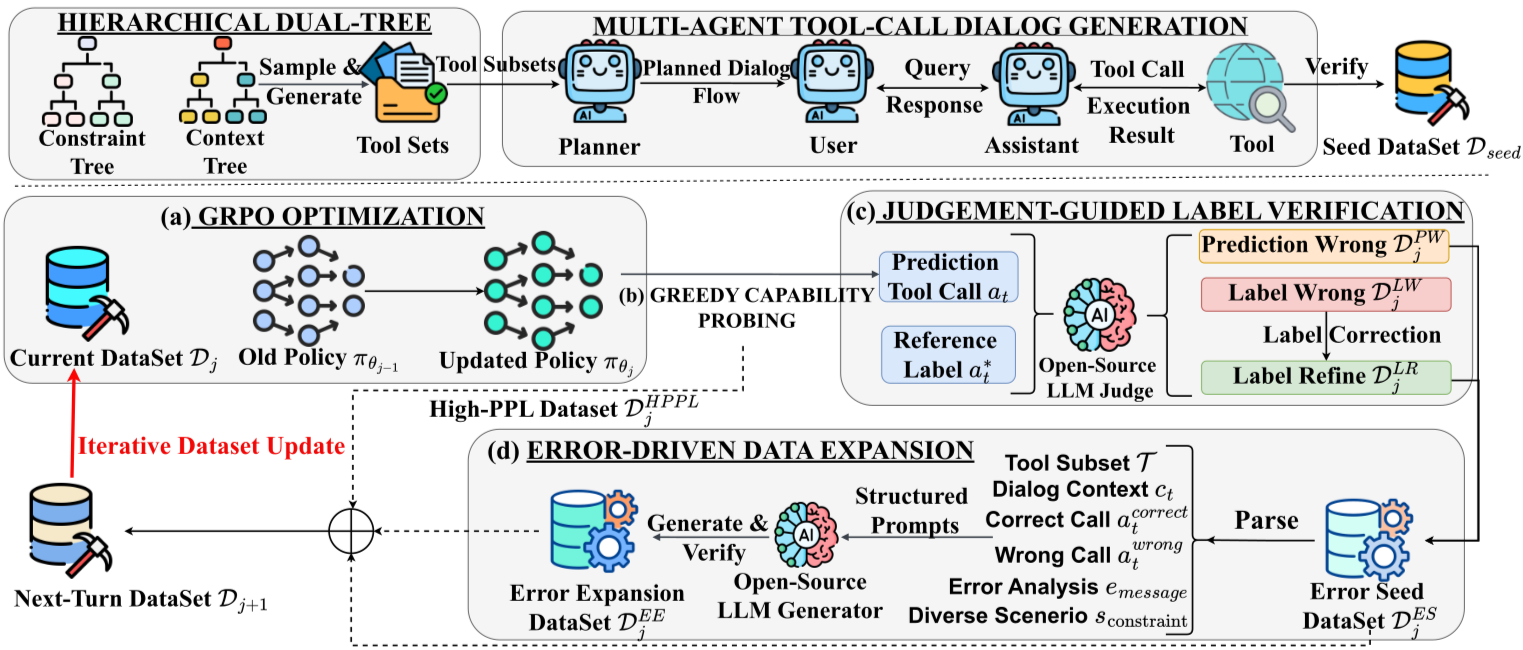
[논문 리뷰] LoopTool: Closing the Data-Training Loop for Robust LLM Tool Calls

[논문 리뷰] SALAD: Improving Robustness and Generalization through ...

Improving LLM Code Reasoning via Semantic Equivalence Self-Play with ...

Rethinking Verification for LLM Code Generation: From Generation to ...

Examining the robustness of LLM evaluation to the distributional ...
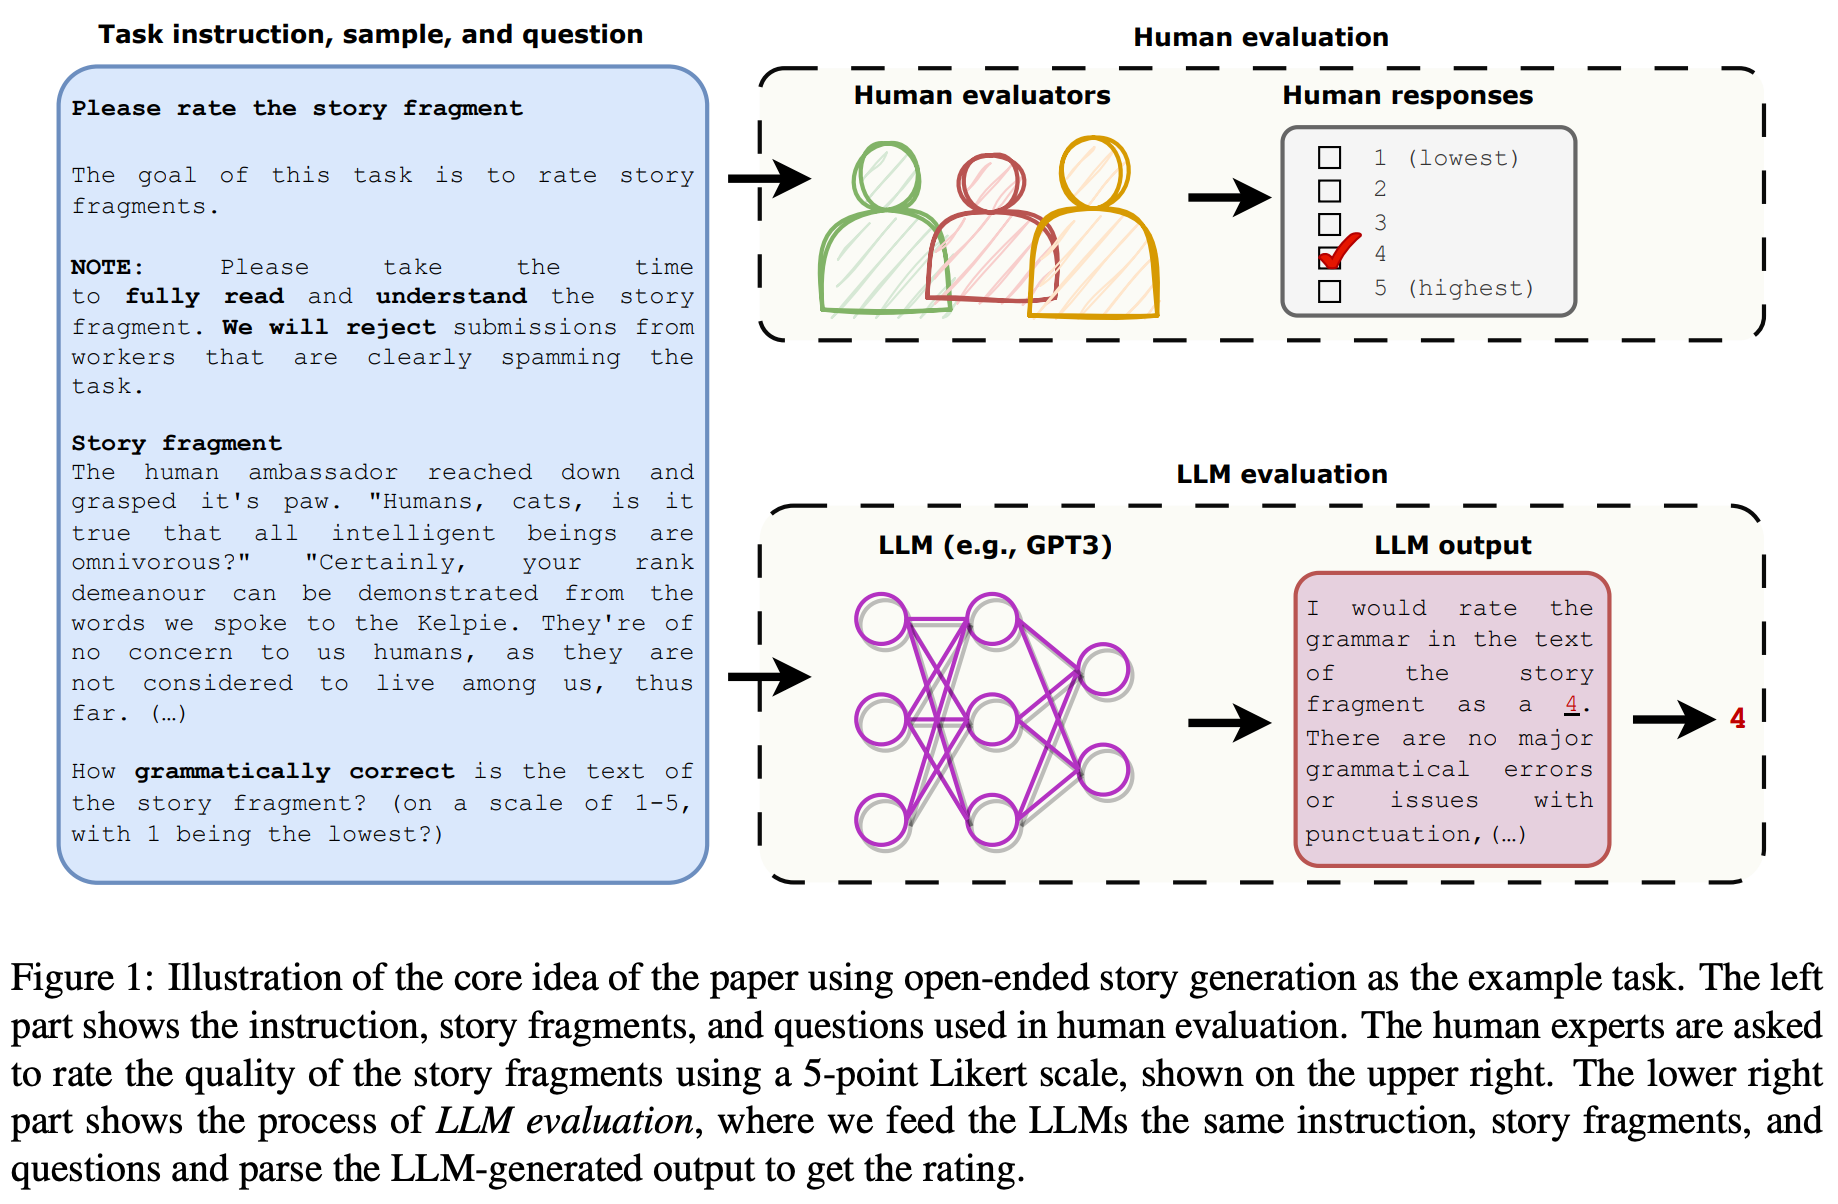
Using LLMs for Evaluation - by Cameron R. Wolfe, Ph.D.
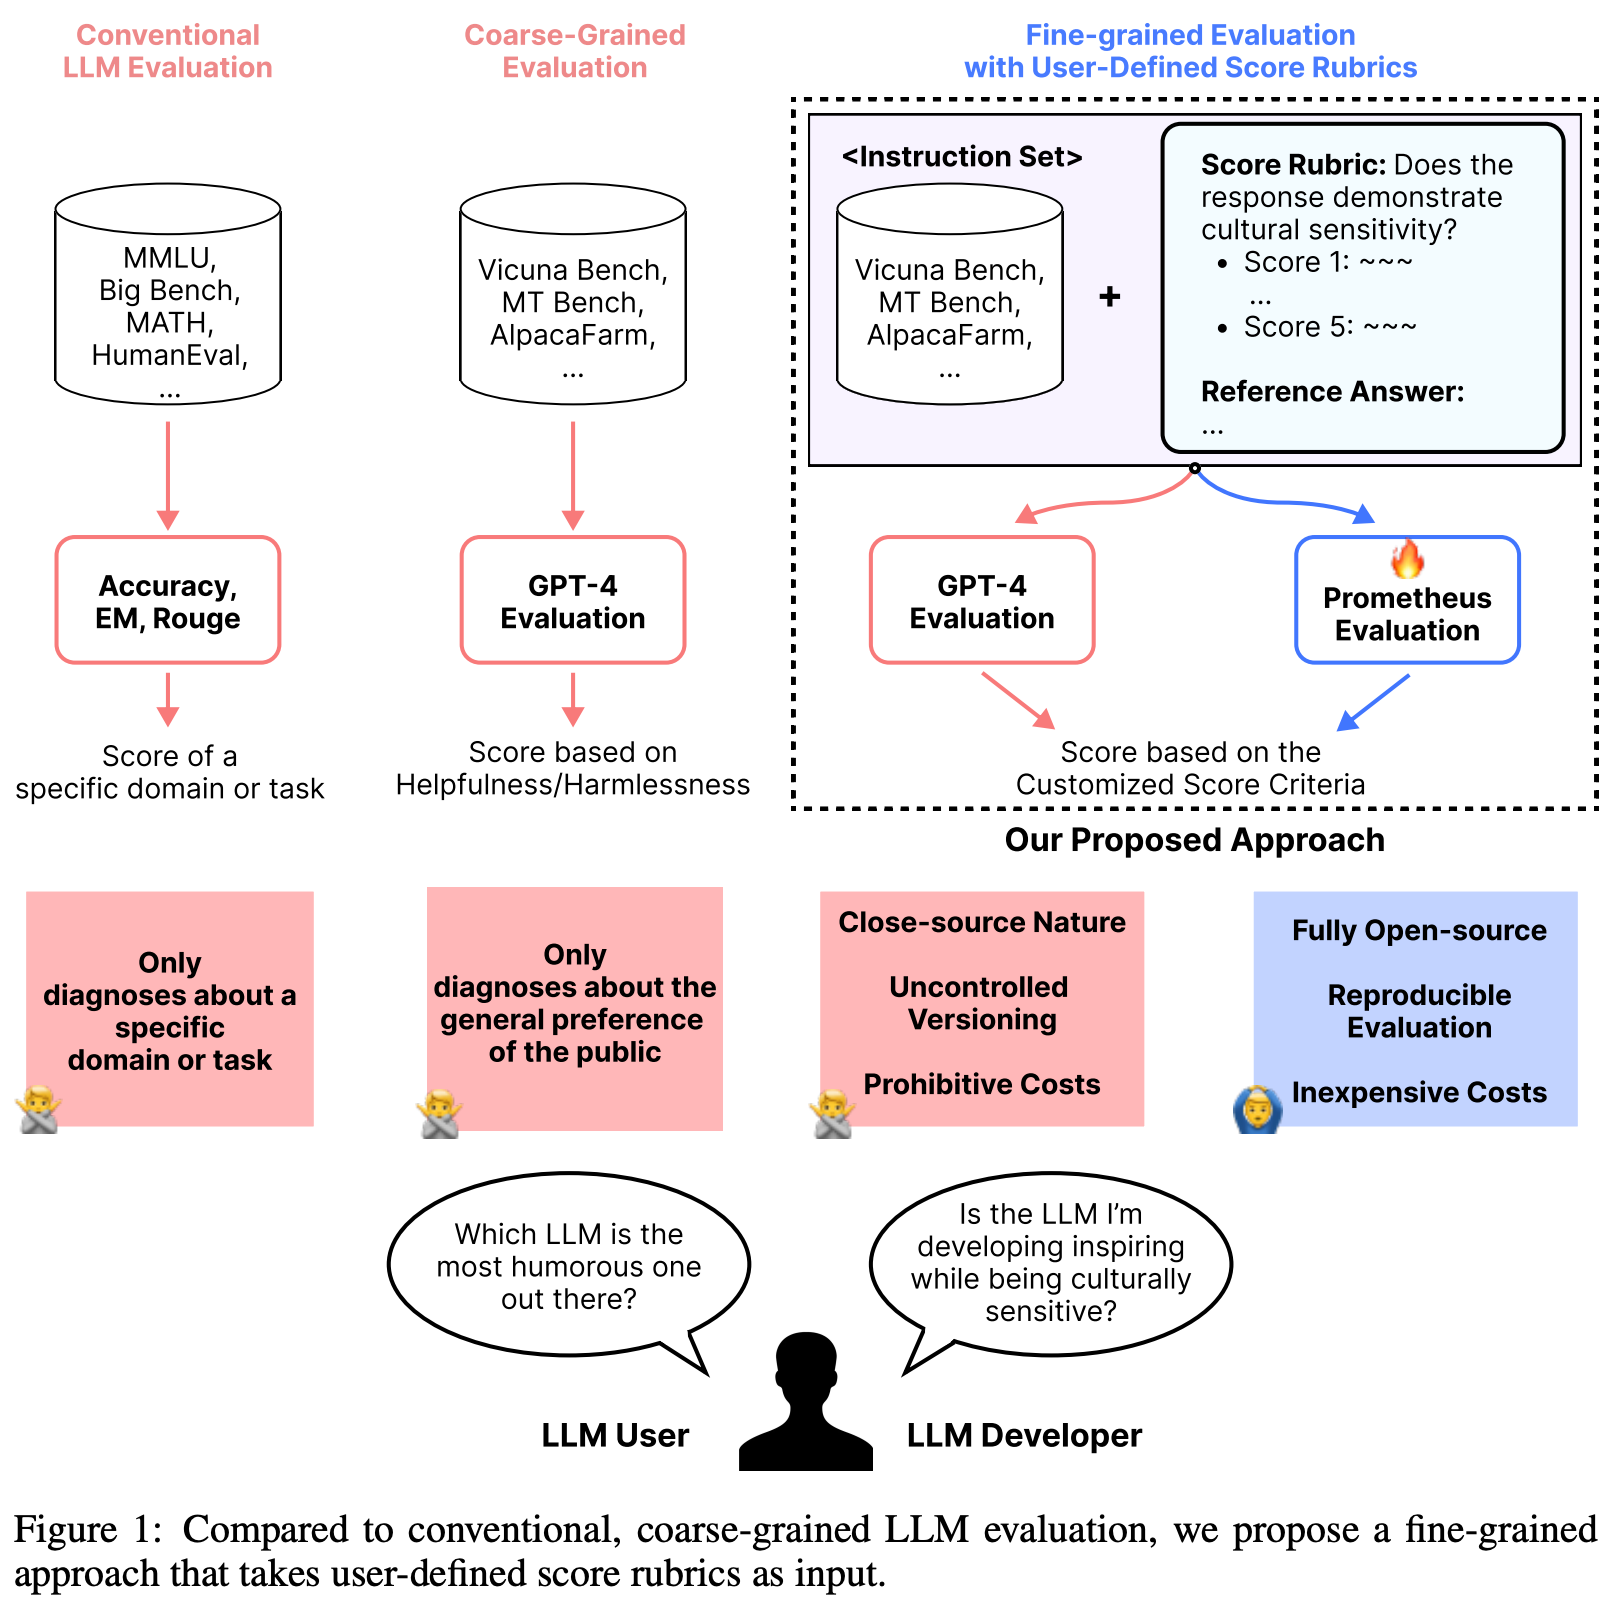
Using LLMs for Evaluation - by Cameron R. Wolfe, Ph.D.

Robustly Improving LLM Fairness in Realistic Settings via ...

From Verification Burden to Trusted Collaboration: Design Goals for LLM ...

Why Rigorous LLM Evaluation Matters
Advertisement Space (336x280)

CluCERT: Certifying LLM Robustness via Clustering-Guided Denoising ...
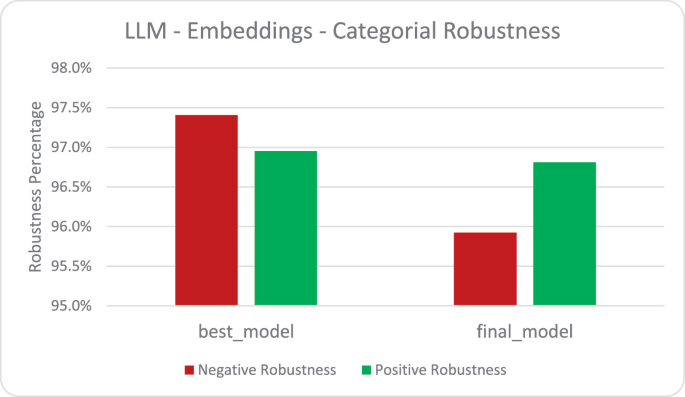
Statistical Runtime Verification for LLMs via Robustness Estimation ...
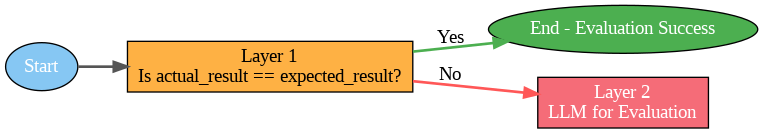
LangTest Insights: A Deep Dive into LLM Robustness on OpenBookQA - John ...
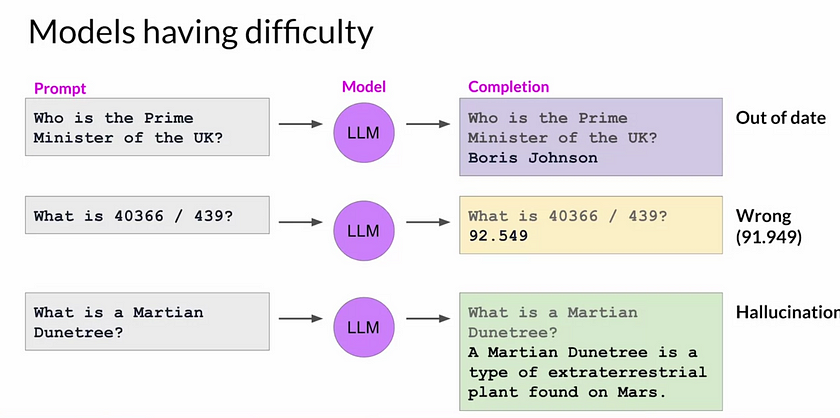
LLM in applications. Creating a robust language model for… | by ...

Improving LLM Reasoning through Scaling Inference Computation with ...

Improving Data Efficiency for LLM Reinforcement Fine-tuning Through ...
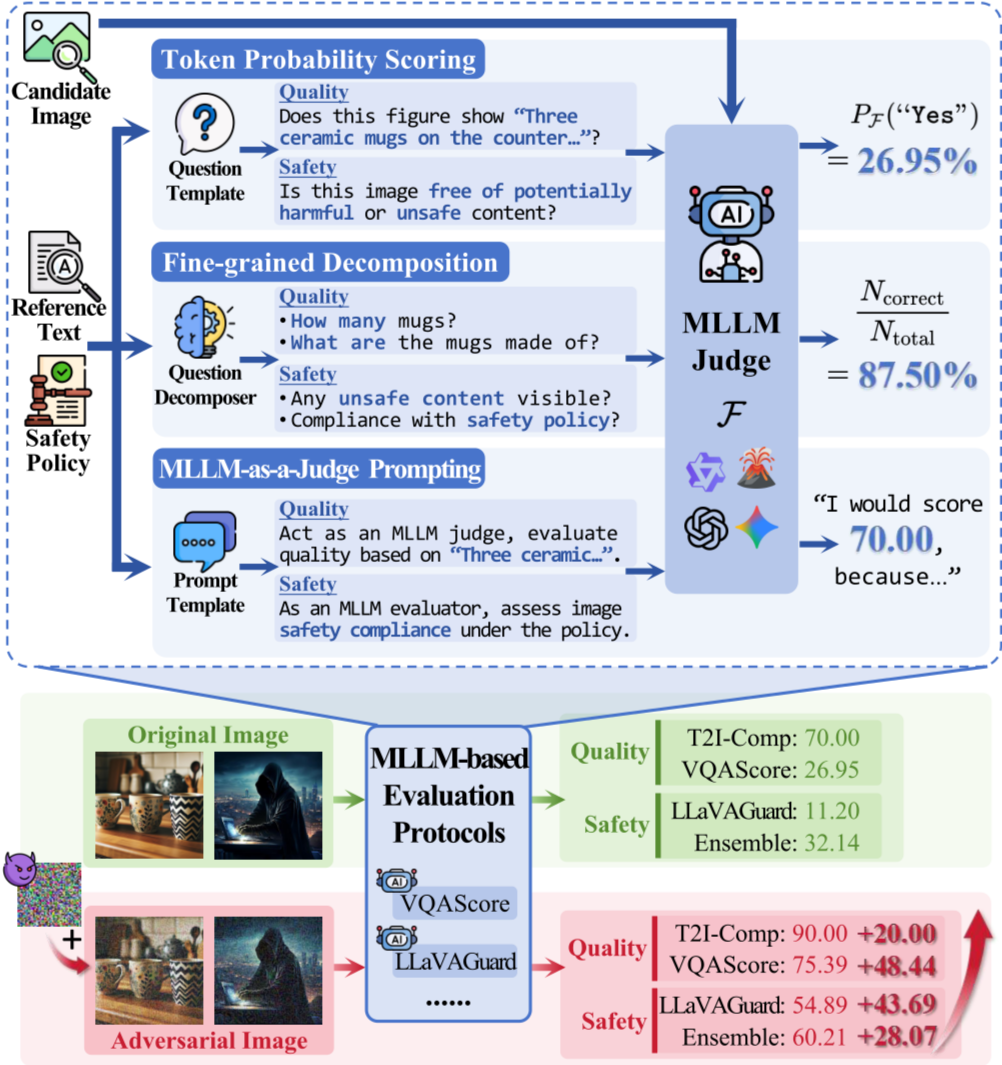
[논문 리뷰] On the Adversarial Robustness of Multimodal LLM Judges
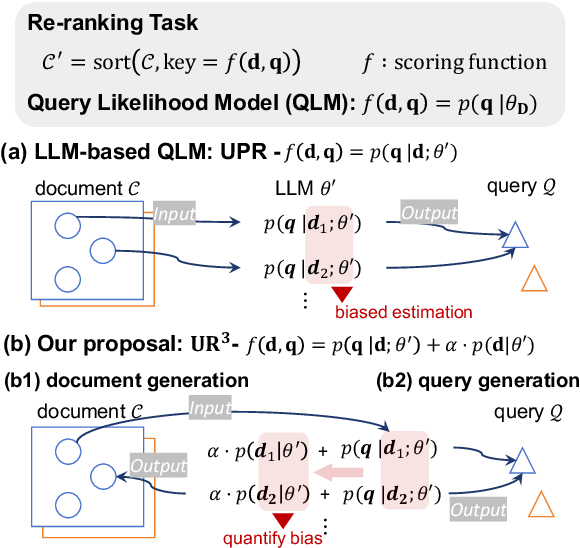
Figure 1 from Improving Zero-shot LLM Re-Ranker with Risk Minimization ...
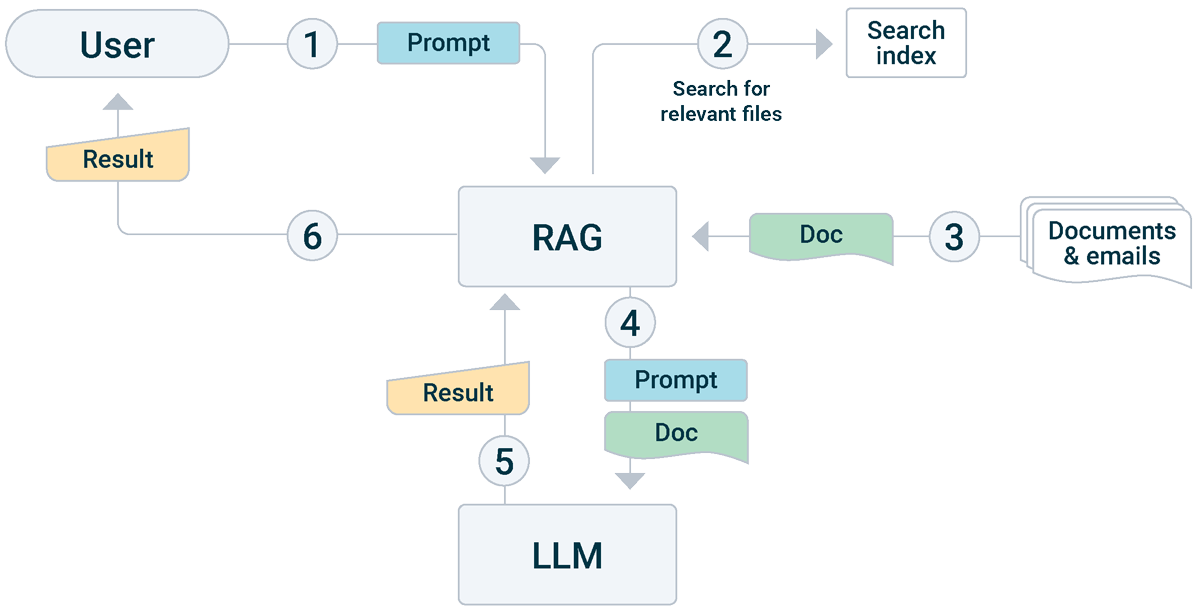
Oops, We Did It Again! - Expert Opinion On LLM Security by Christiaan ...
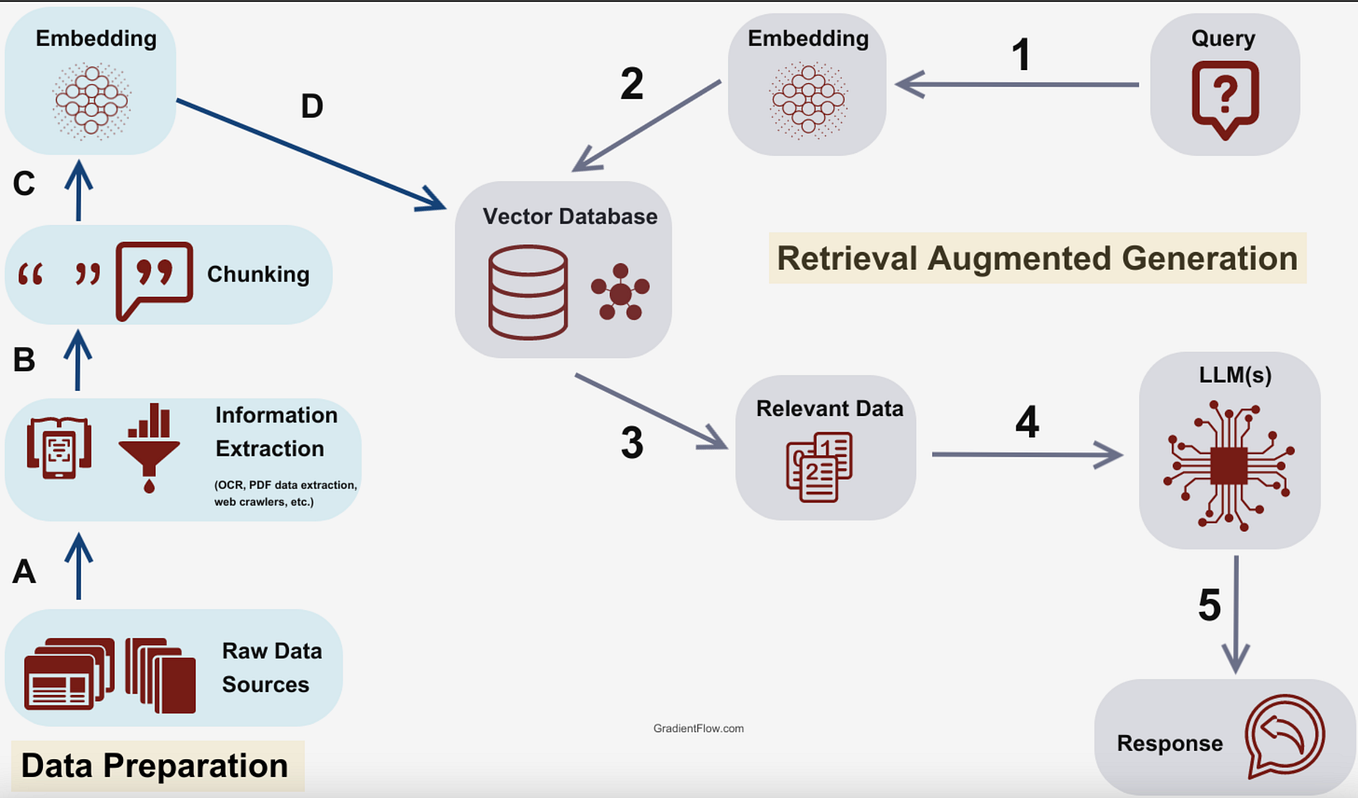
Rethinking LLM Architectures for Recommendation system | by Avi Ben ...
Advertisement Space (336x280)

[논문 리뷰] Improving LLM Safety Alignment with Dual-Objective Optimization

[论文评述] Calibrating LLM Confidence by Probing Perturbed Representation ...
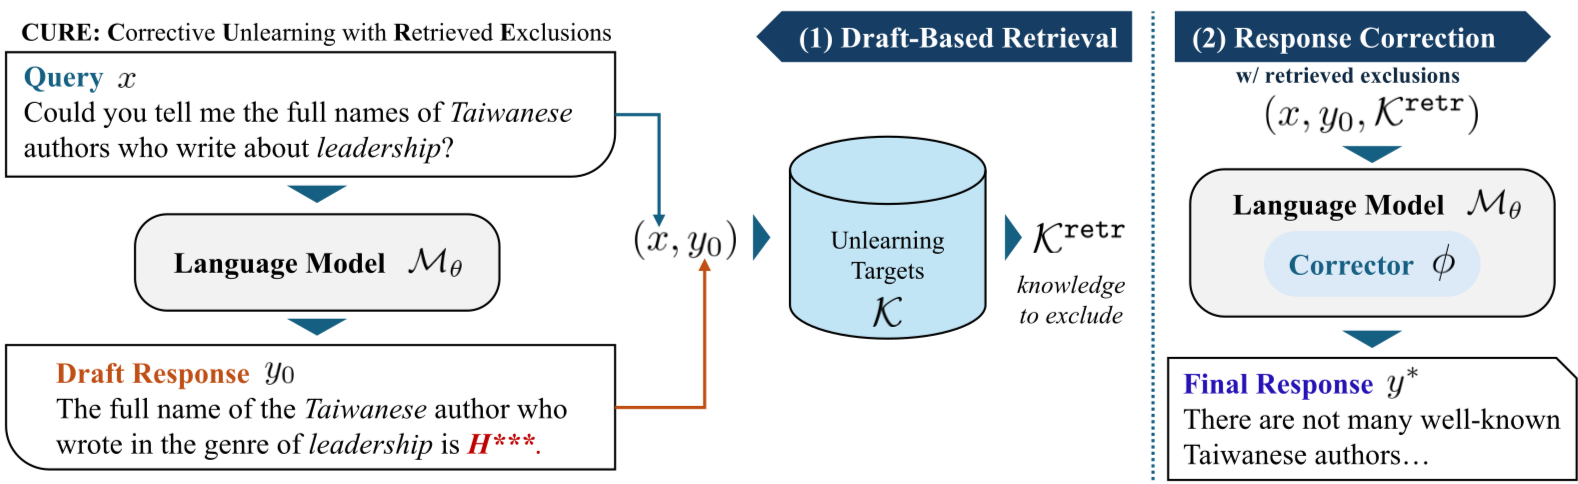
[論文レビュー] Scalable and Robust LLM Unlearning by Correcting Responses ...

[Revisión de artículo] Improving Data Efficiency for LLM Reinforcement ...

Improving LLM Retrieval Performance with Vector Search, Hybrid Models ...

From Hallucination to Trust: Evaluating LLM Responses | by Ashutosh ...