
Inference Latency For Sc And Offloading Efficient Ai Accelerators To

Inference Latency for SC and Offloading efficient AI accelerators to ...

vAccSOL: Efficient and Transparent AI Vision Offloading for Mobile Robots

Modern QA for Multi-Region AI Inference Platforms, Ensuring Latency and ...
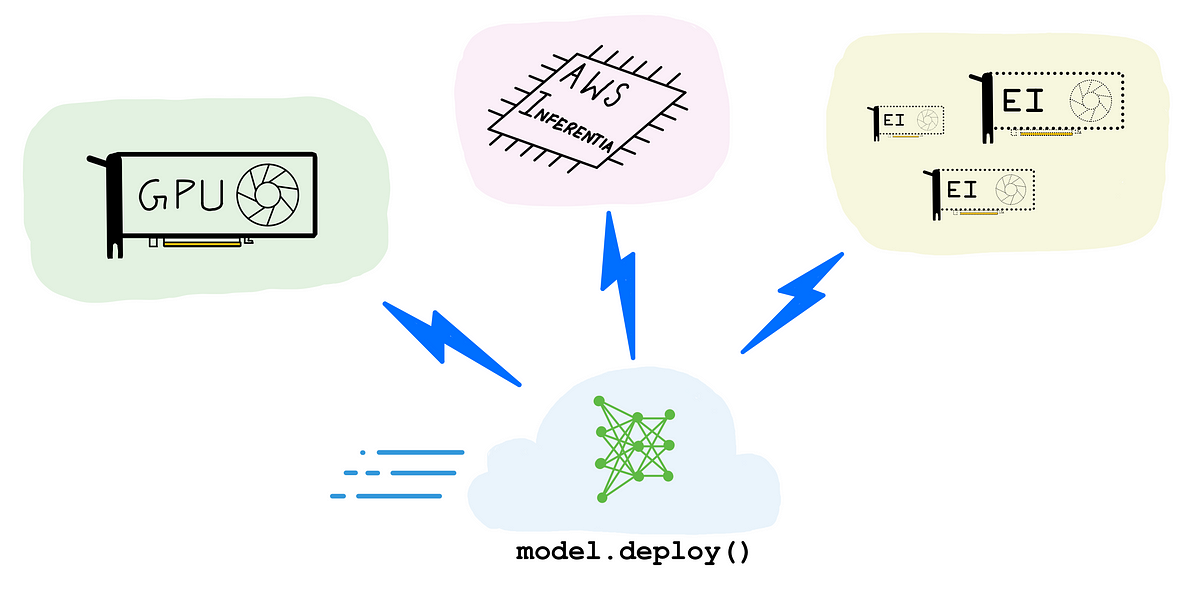
A complete guide to AI accelerators for deep learning inference — GPUs ...
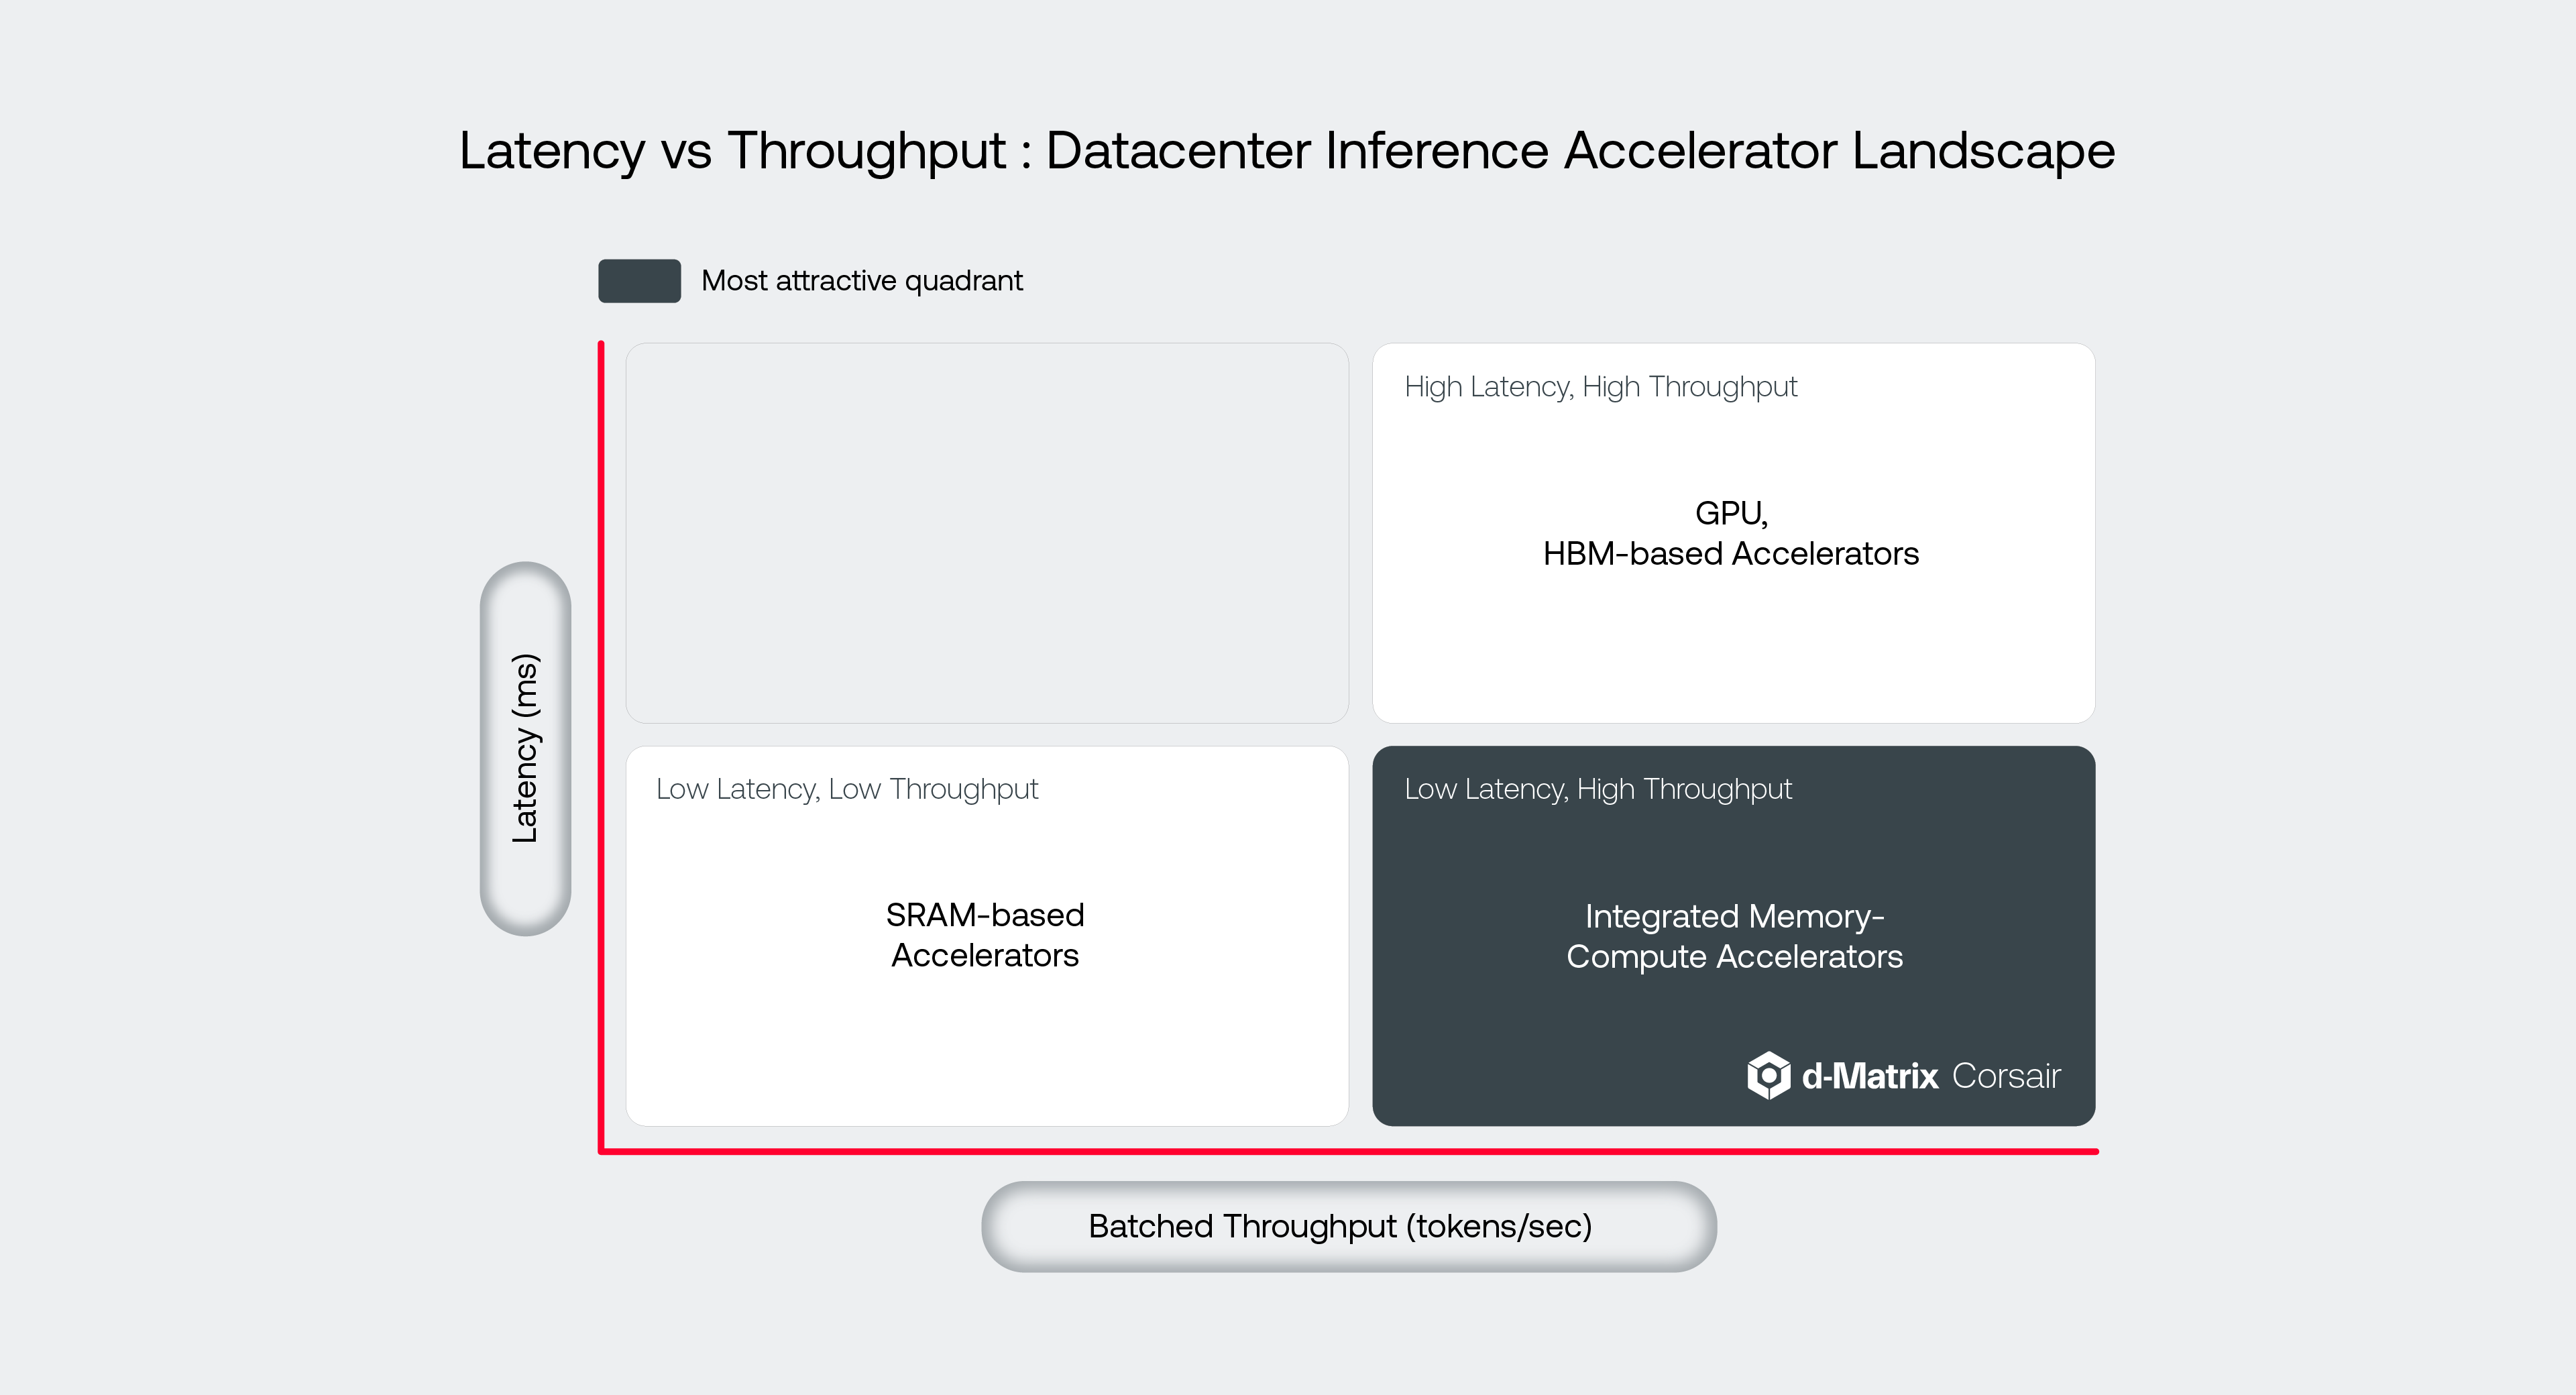
How to Bridge Speed and Scale: Redefining AI Inference with Ultra-Low ...
How to Reduce AI Inference Latency Effectively
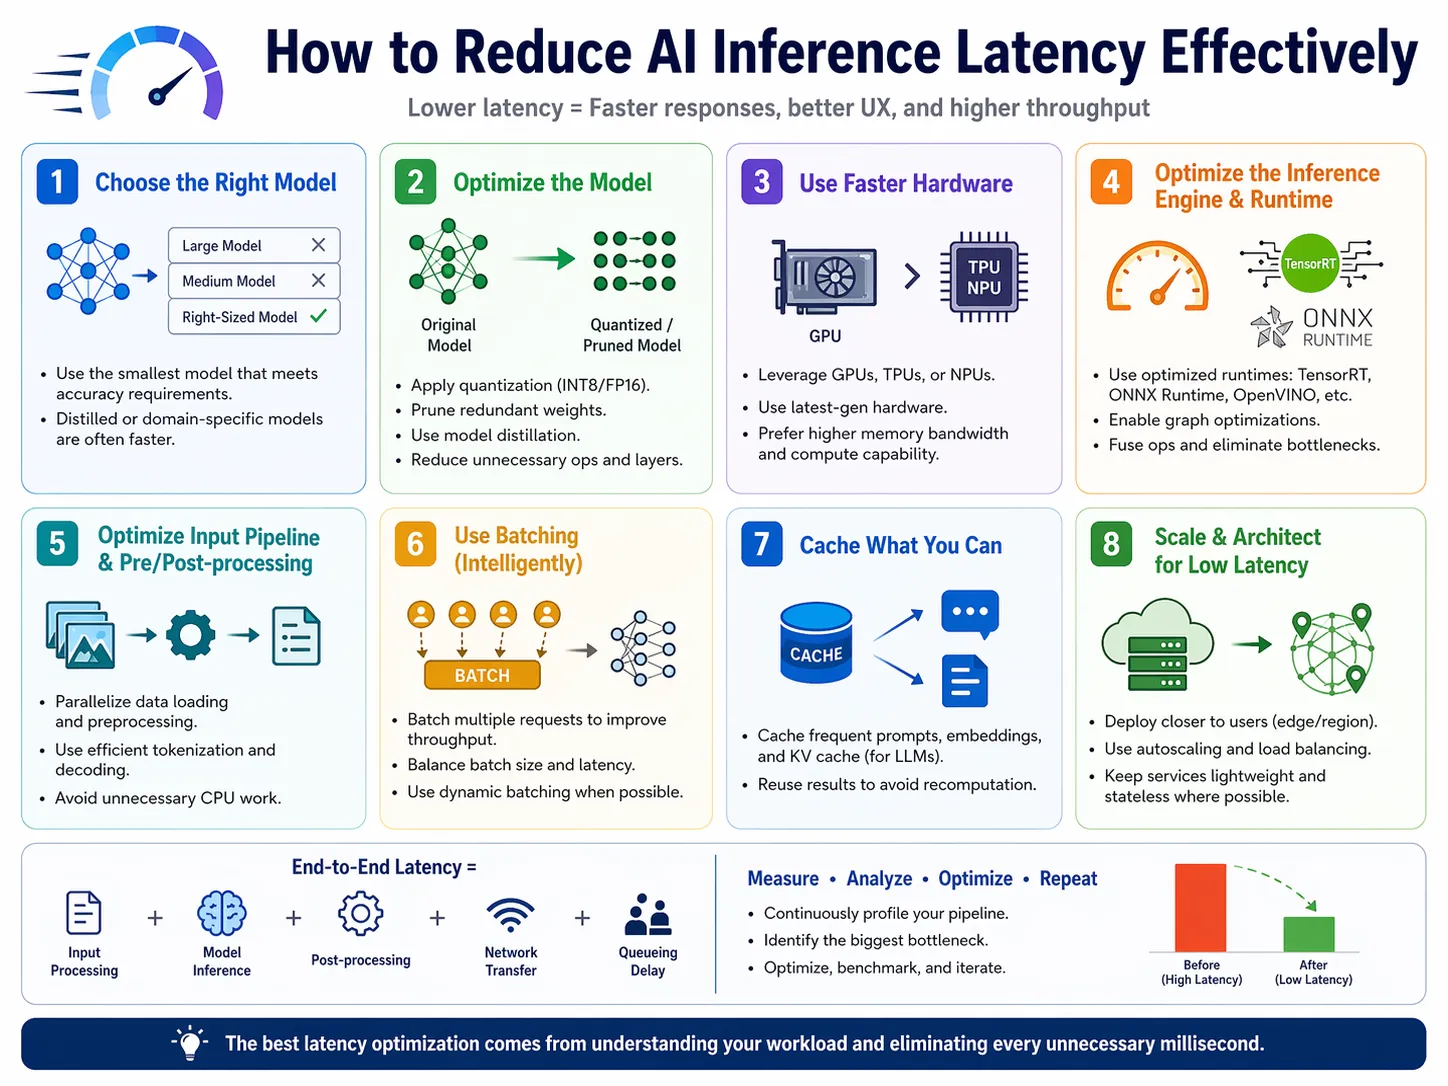
How to Reduce AI Inference Latency Effectively

3D Optimization for AI Inference Scaling: Balancing Accuracy, Cost, and ...

Empowering Low Latency AI Inference for Enhanced Efficiency

Fixstars Adds Autonomous Optimization Feature for Edge AI Inference to ...
Advertisement Space (300x250)

How to Balance Accuracy, Cost, and Latency in AI Systems?
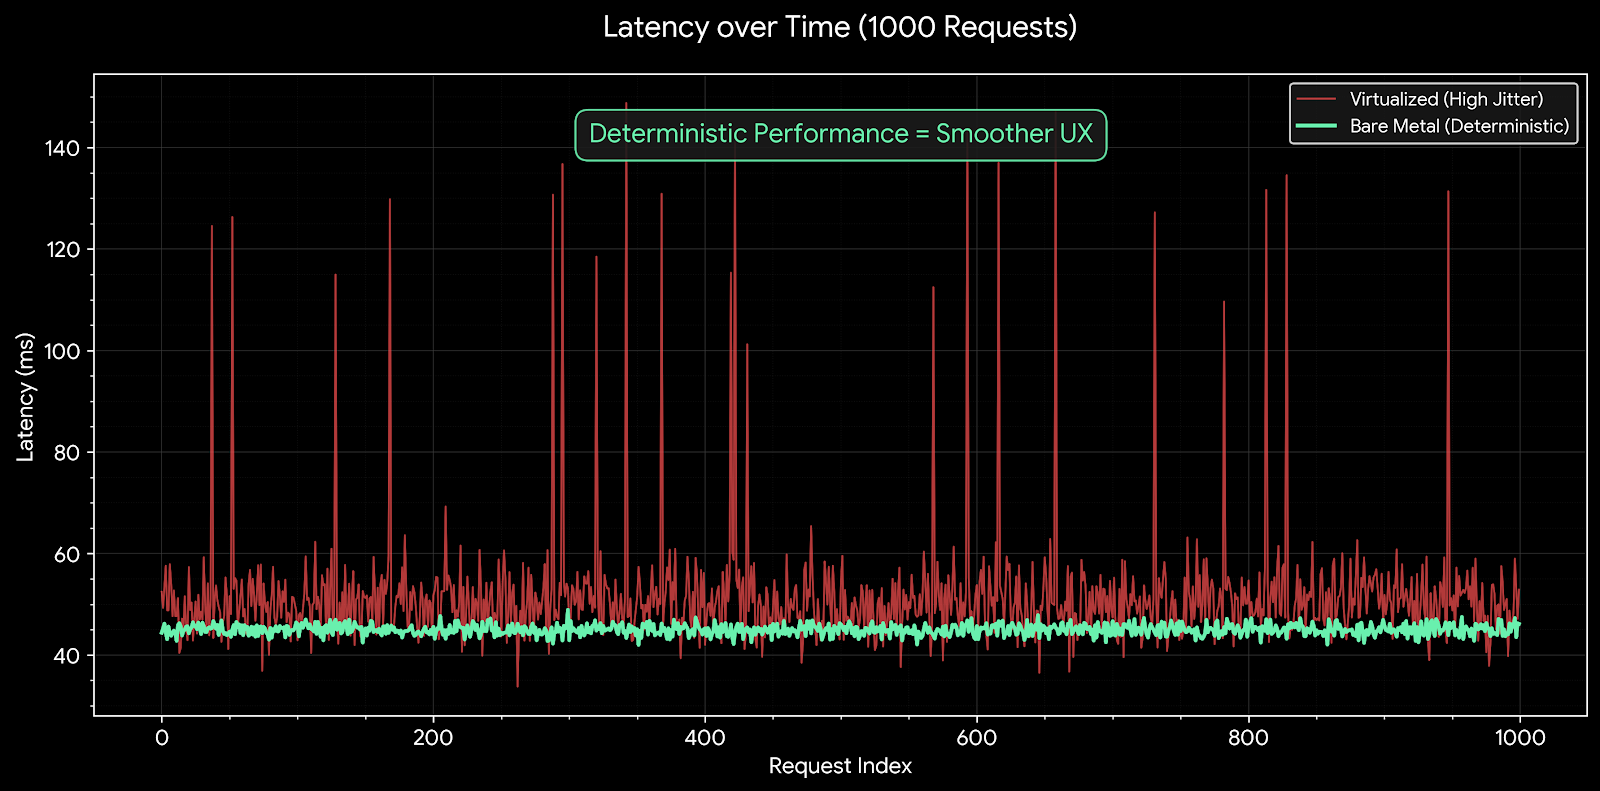
Lowest Latency AI Inference Provider for Open-Source LLMs

3D Optimization for AI Inference Scaling: Balancing Accuracy, Cost, and ...
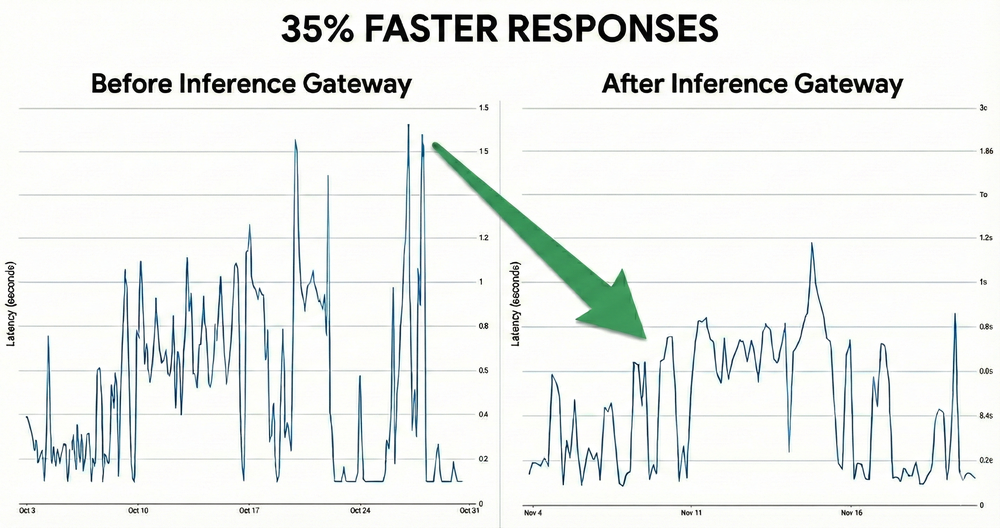
How we cut Vertex AI latency by 35% with GKE Inference Gateway – GIXtools

Efficient and Economic Large Language Model Inference with Attention ...

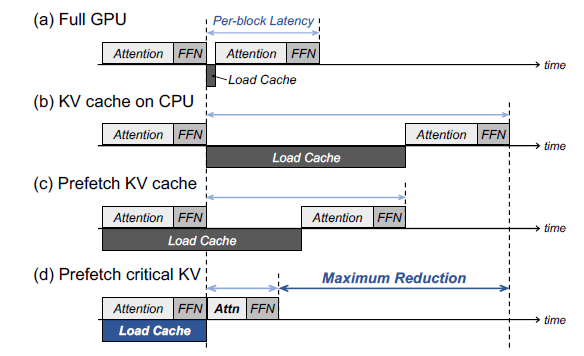
CLO: Efficient LLM Inference System with CPU-Light KVCache Offloading ...

Why AI Inference Latency Fails in Production Systems
Why AI Inference Latency Fails in Production Systems
The True Cost of Latency in Cloud-Only AI Inference | Inference Systems
Reducing Latency in AI Model Monitoring: Strategies and Tools
Advertisement Space (336x280)
How to optimize inference speed using batching, vLLM, and UbiOps | by ...

[2412.06198] SparseAccelerate: Efficient Long-Context Inference for Mid ...

Latency in AI Inferencing: Understanding the Impact and FPGA-based ...

Mastering AI Optimization: Techniques to Boost Accuracy, Latency, and ...

(PDF) Offloading Algorithms for Maximizing Inference Accuracy on Edge ...

Essential Tools for Observing AI Inference Latency: A Comprehensive ...

Figure 1 from Computation offloading for fast CNN inference in edge ...

[논문 리뷰] 3D Optimization for AI Inference Scaling: Balancing Accuracy ...

Comparison of end-to-end latency and energy consumption for ...

Energy-Efficient Joint Partitioning and Offloading for Delay-Sensitive ...
Advertisement Space (336x280)

Accelerate AI Inference with SoyNet: Optimizing Performance and ...

LLM Inference Acceleration via Efficient Operation Fusion | AI Research ...
The Race Against Time: Mastering Low Latency Inference in AI Applications"

Reducing Latency in AI Systems: From Token Generation to Distributed ...

Figure 2 from Task Offloading for Collaborative Inference of LLM Agents ...

Energy-Efficient Joint Partitioning and Offloading for Delay-Sensitive ...