
Inference Optimization And Model Serving Emberverse
Inference Optimization and Model Serving | Emberverse
AI Integration with Weights and Biases Model Serving | Inference Systems
Inference and Model Serving | run-ai/docs | DeepWiki
Model Serving Patterns and Inference Paths | COMPEL Framework

Combined Model Inference Time Graph Before and After Optimization ...
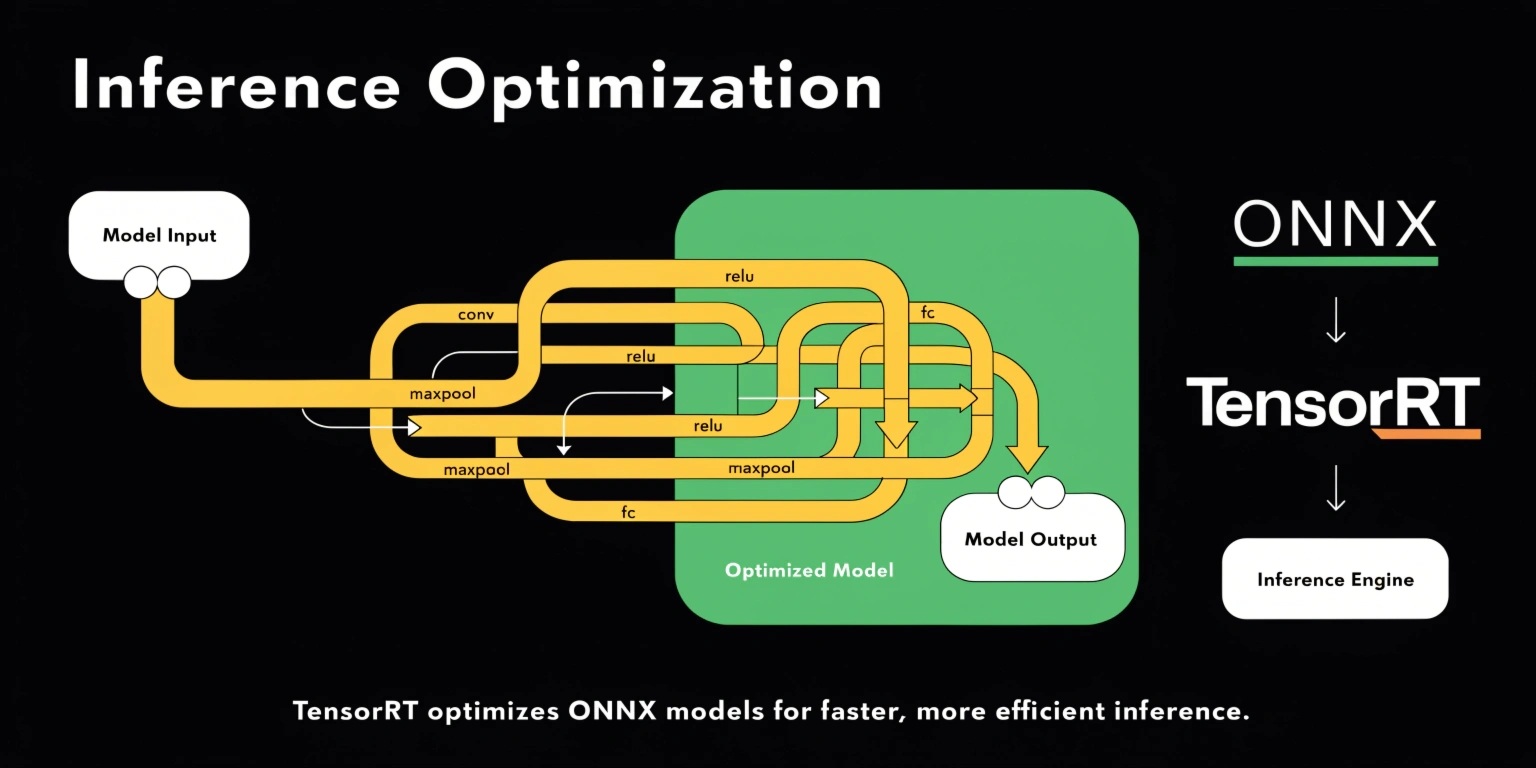
Inference Optimization Using TensorRT and ONNX for Faster AI Model ...
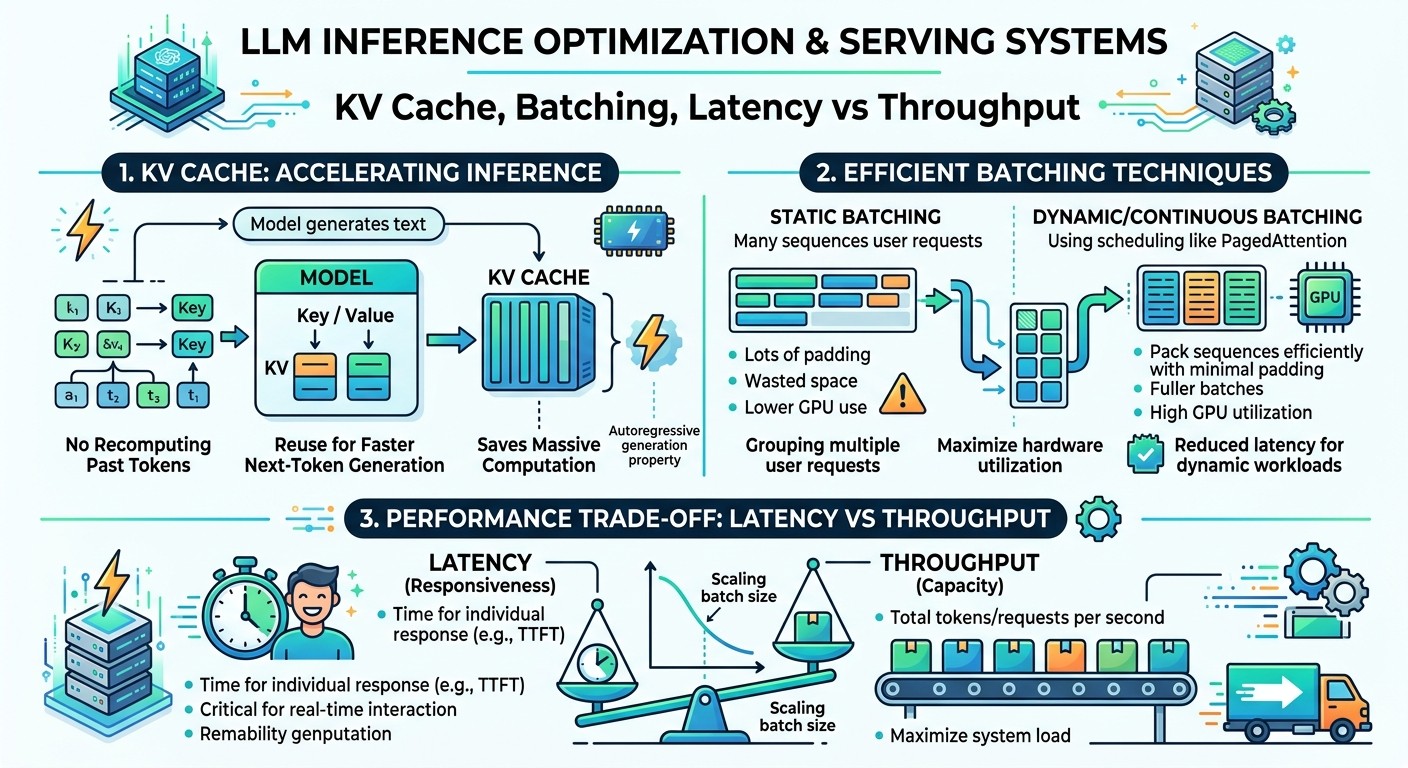
LLM Inference Optimization & Serving Systems – Billion Hopes

Exploring AI Model Inference: Servers, Frameworks, and Optimization ...

Robust Scene Text Detection and Recognition: Inference Optimization ...
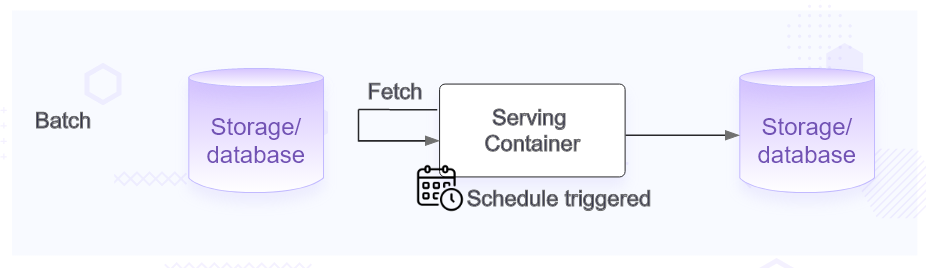
Exploring AI Model Inference: Servers, Frameworks, and Optimization ...
Advertisement Space (300x250)
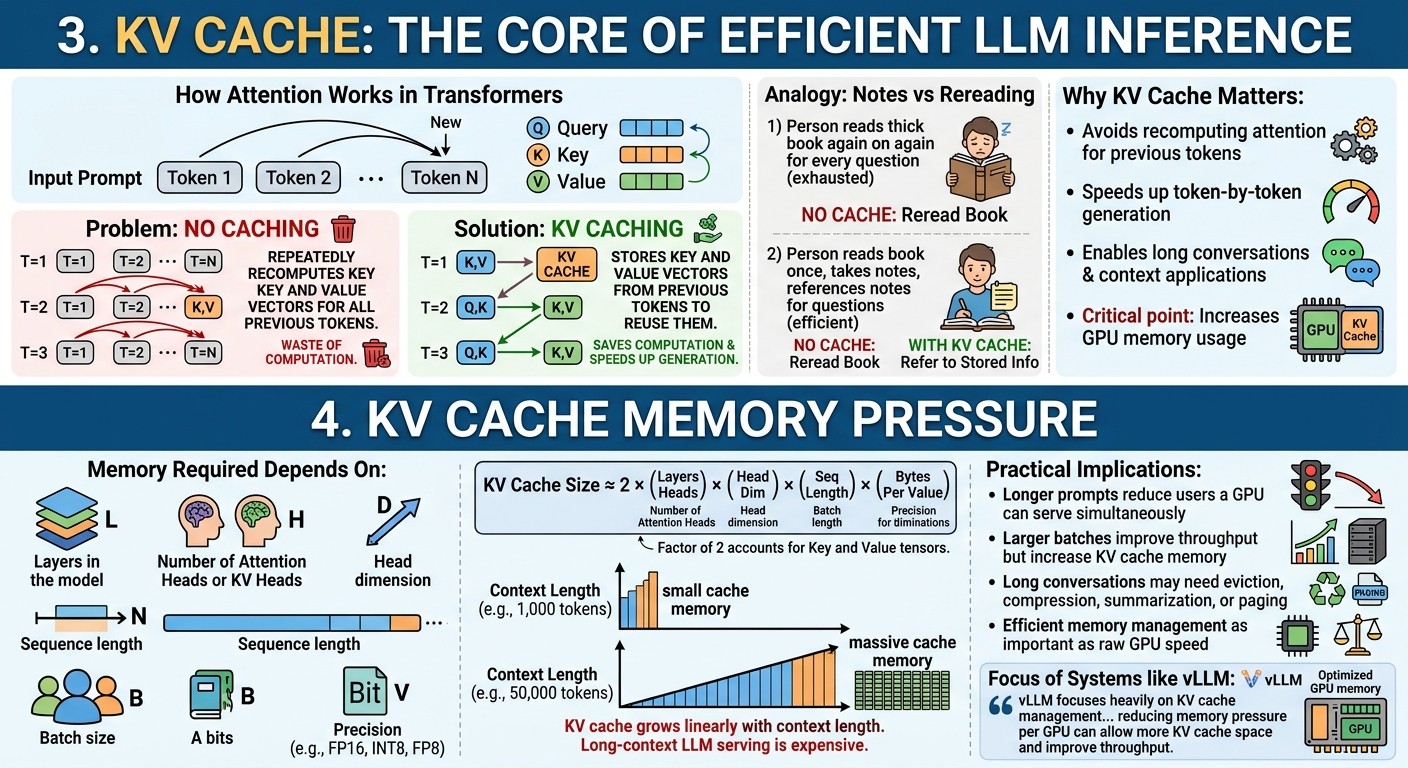
LLM Inference Optimization & Serving Systems – Billion Hopes
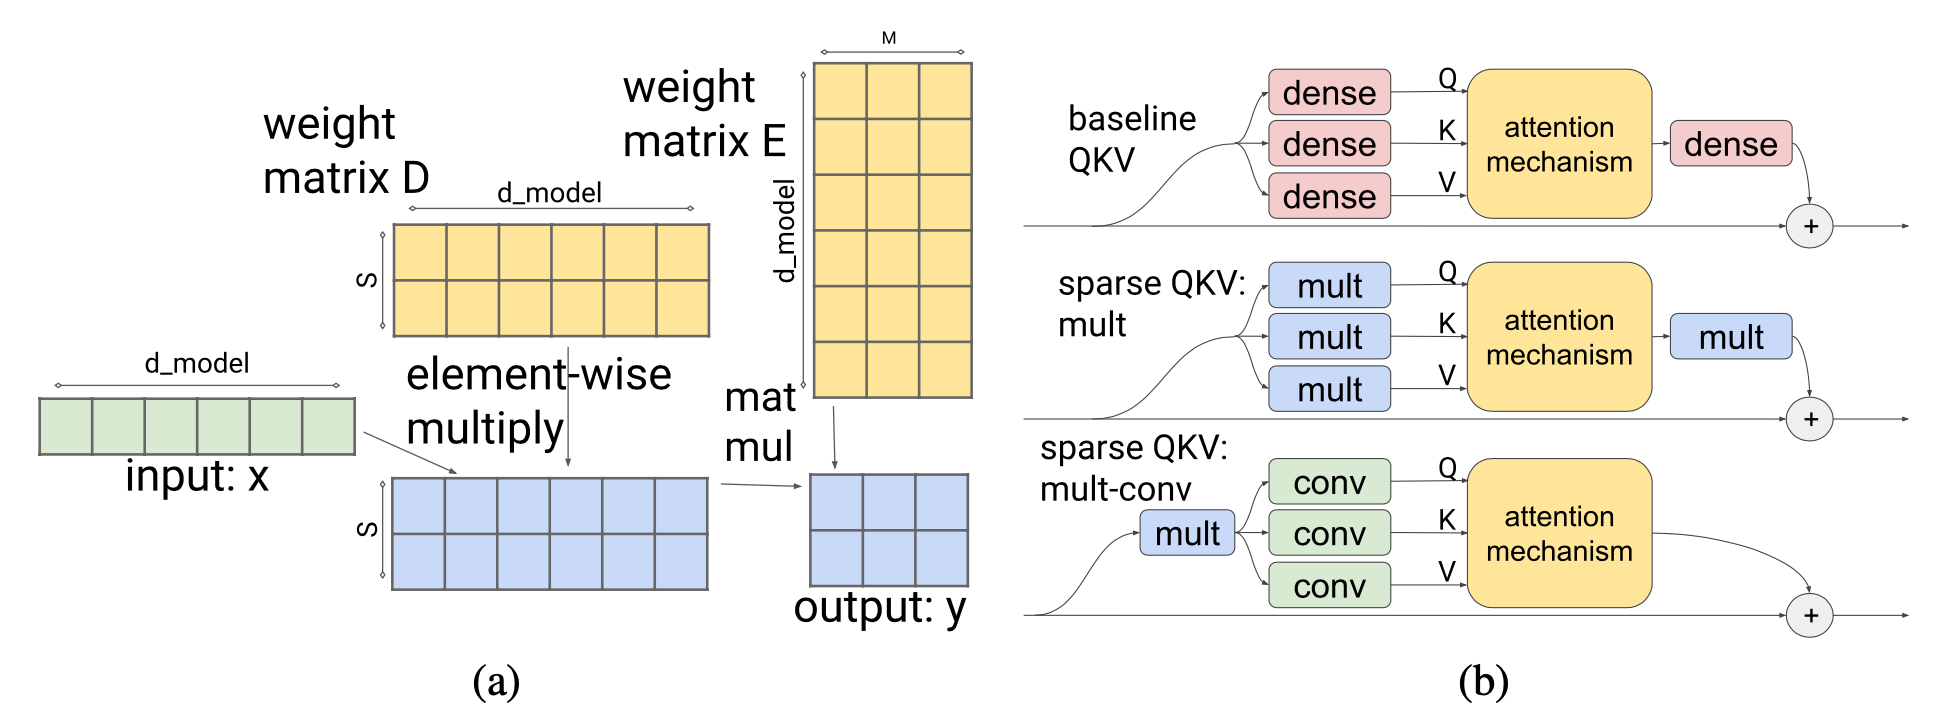
Large Transformer Model Inference Optimization | Lil'Log
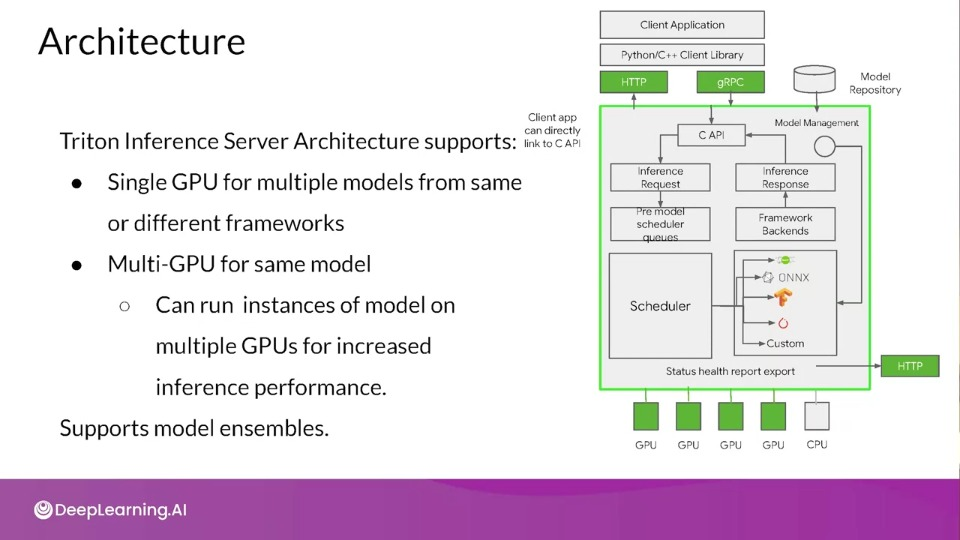
Week 2 — Model Serving Architecture, Scaling Infrastructure and More ...
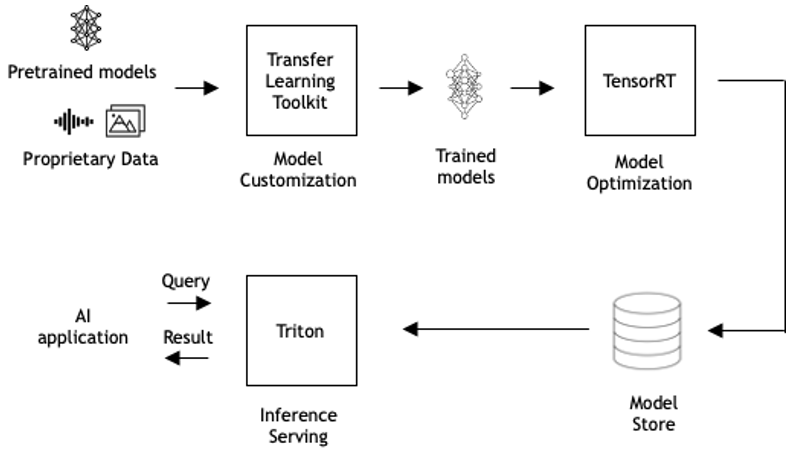
Simplifying and Scaling Inference Serving with NVIDIA Triton 2.3 ...

Production Model Serving in 2026 — A Tour of the Inference ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
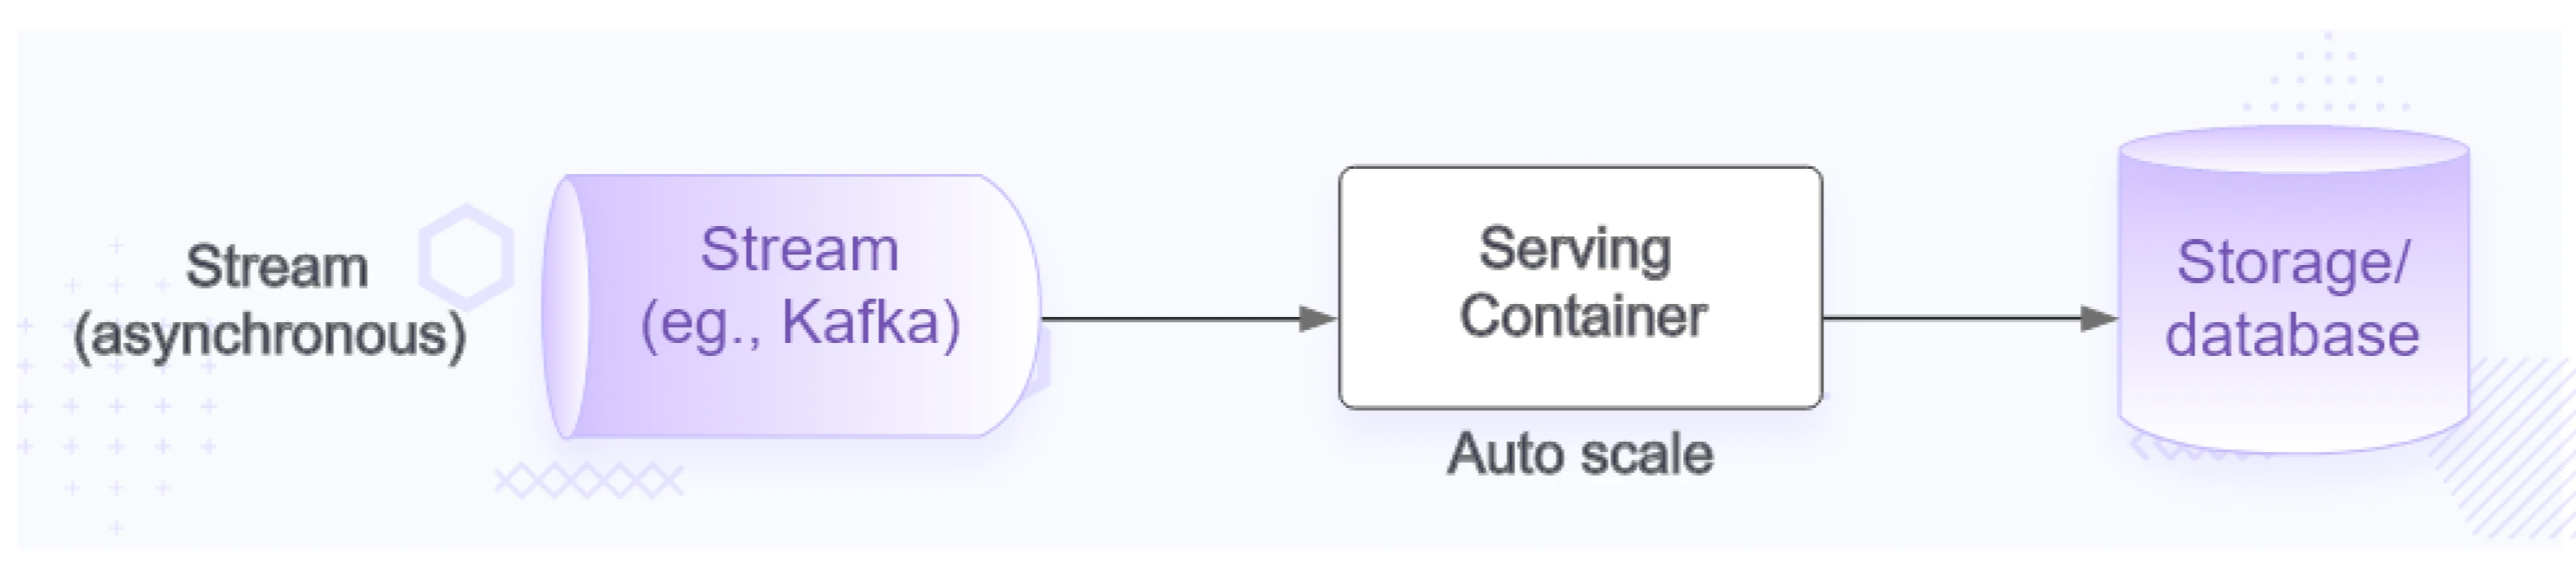
Exploring AI Model Inference: Servers, Frameworks, and Optimization ...
Sidecar Pattern in AI: Microservices for Model Serving | Inference Systems

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
Quantization Bitwidth: Definition & AI Model Optimization | Inference ...
Advertisement Space (336x280)
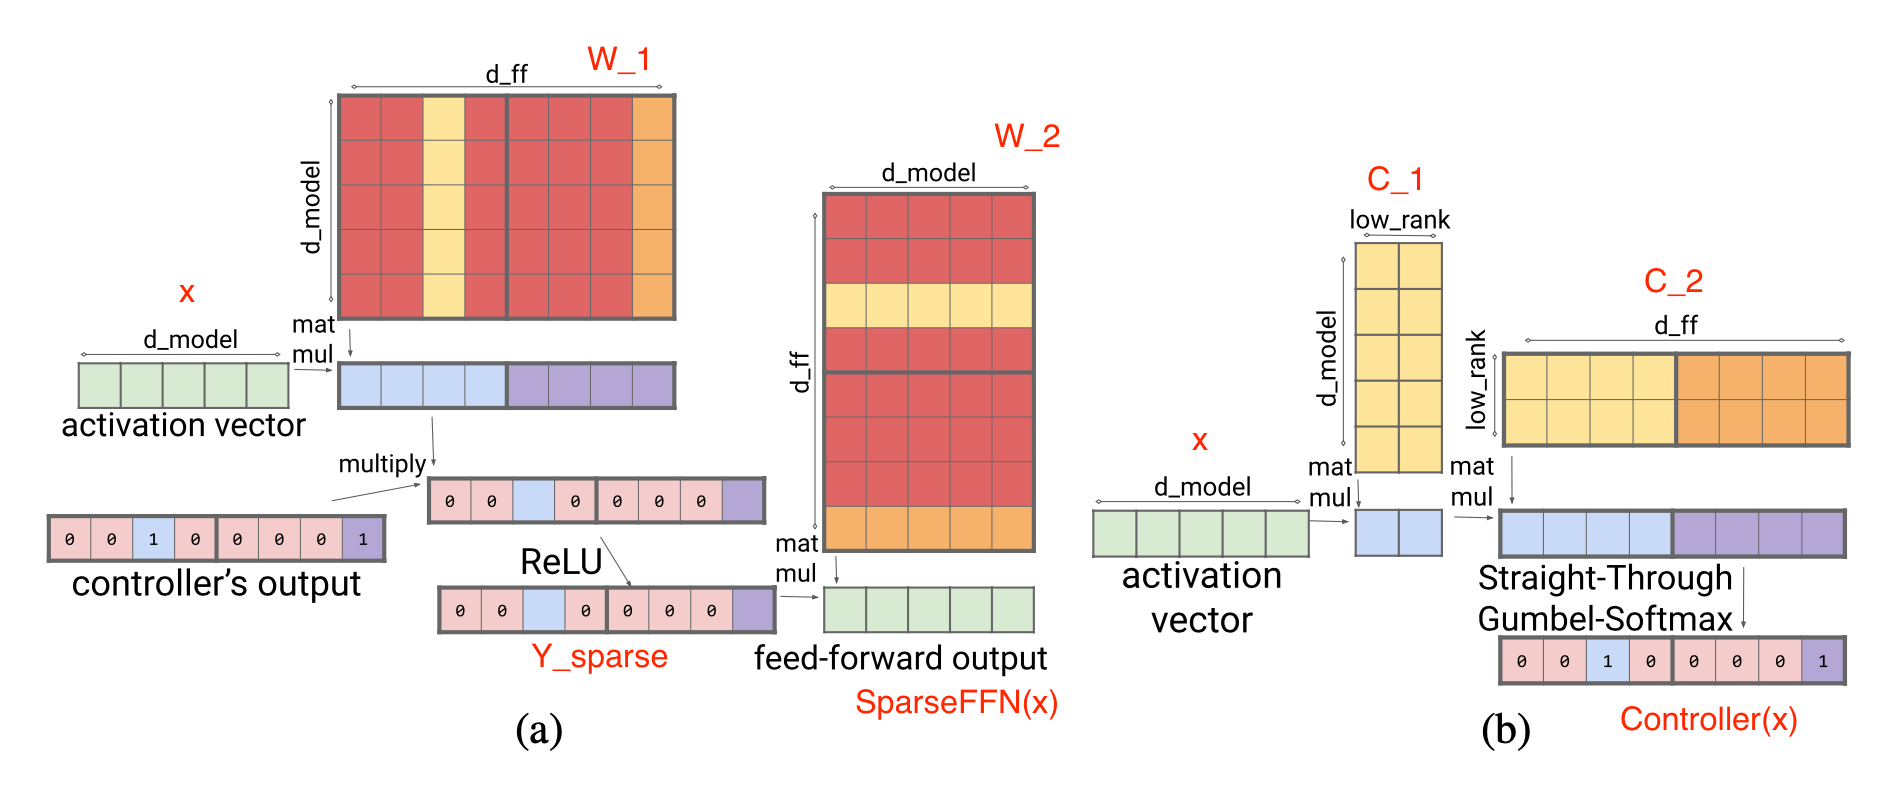
Large Transformer Model Inference Optimization | Lil'Log

(PDF) AI MODEL SERVING AT SCALE: KUBERNETES- BASED ORCHESTRATION AND ...

Model Serving & Inference Infrastructure | Engineering Playbook
Deepspeed in Production: INFERENCE OPTIMIZATION AND MODEL: Deploy LLMs ...
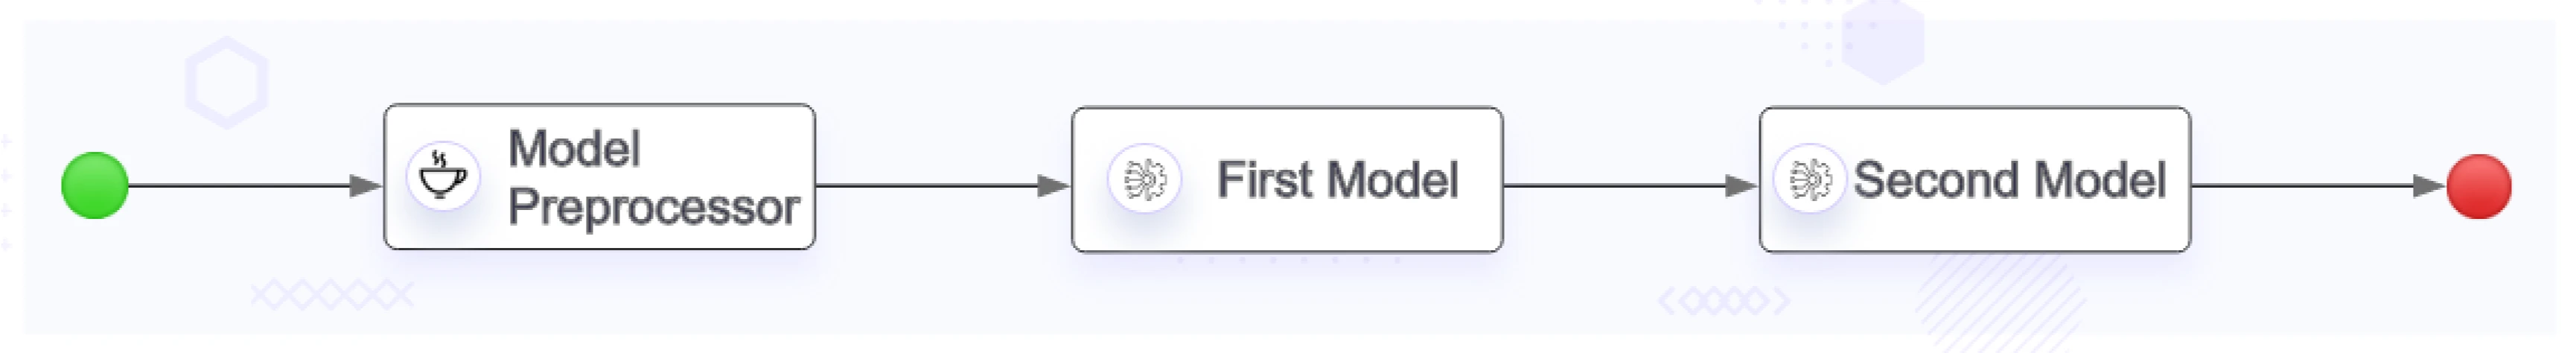
Exploring AI Model Inference: Servers, Frameworks, and Optimization ...
Inference Optimization vs. Model Downgrading: Where Should Leaders Cut ...
The Case for Centralized AI Model Inference Serving
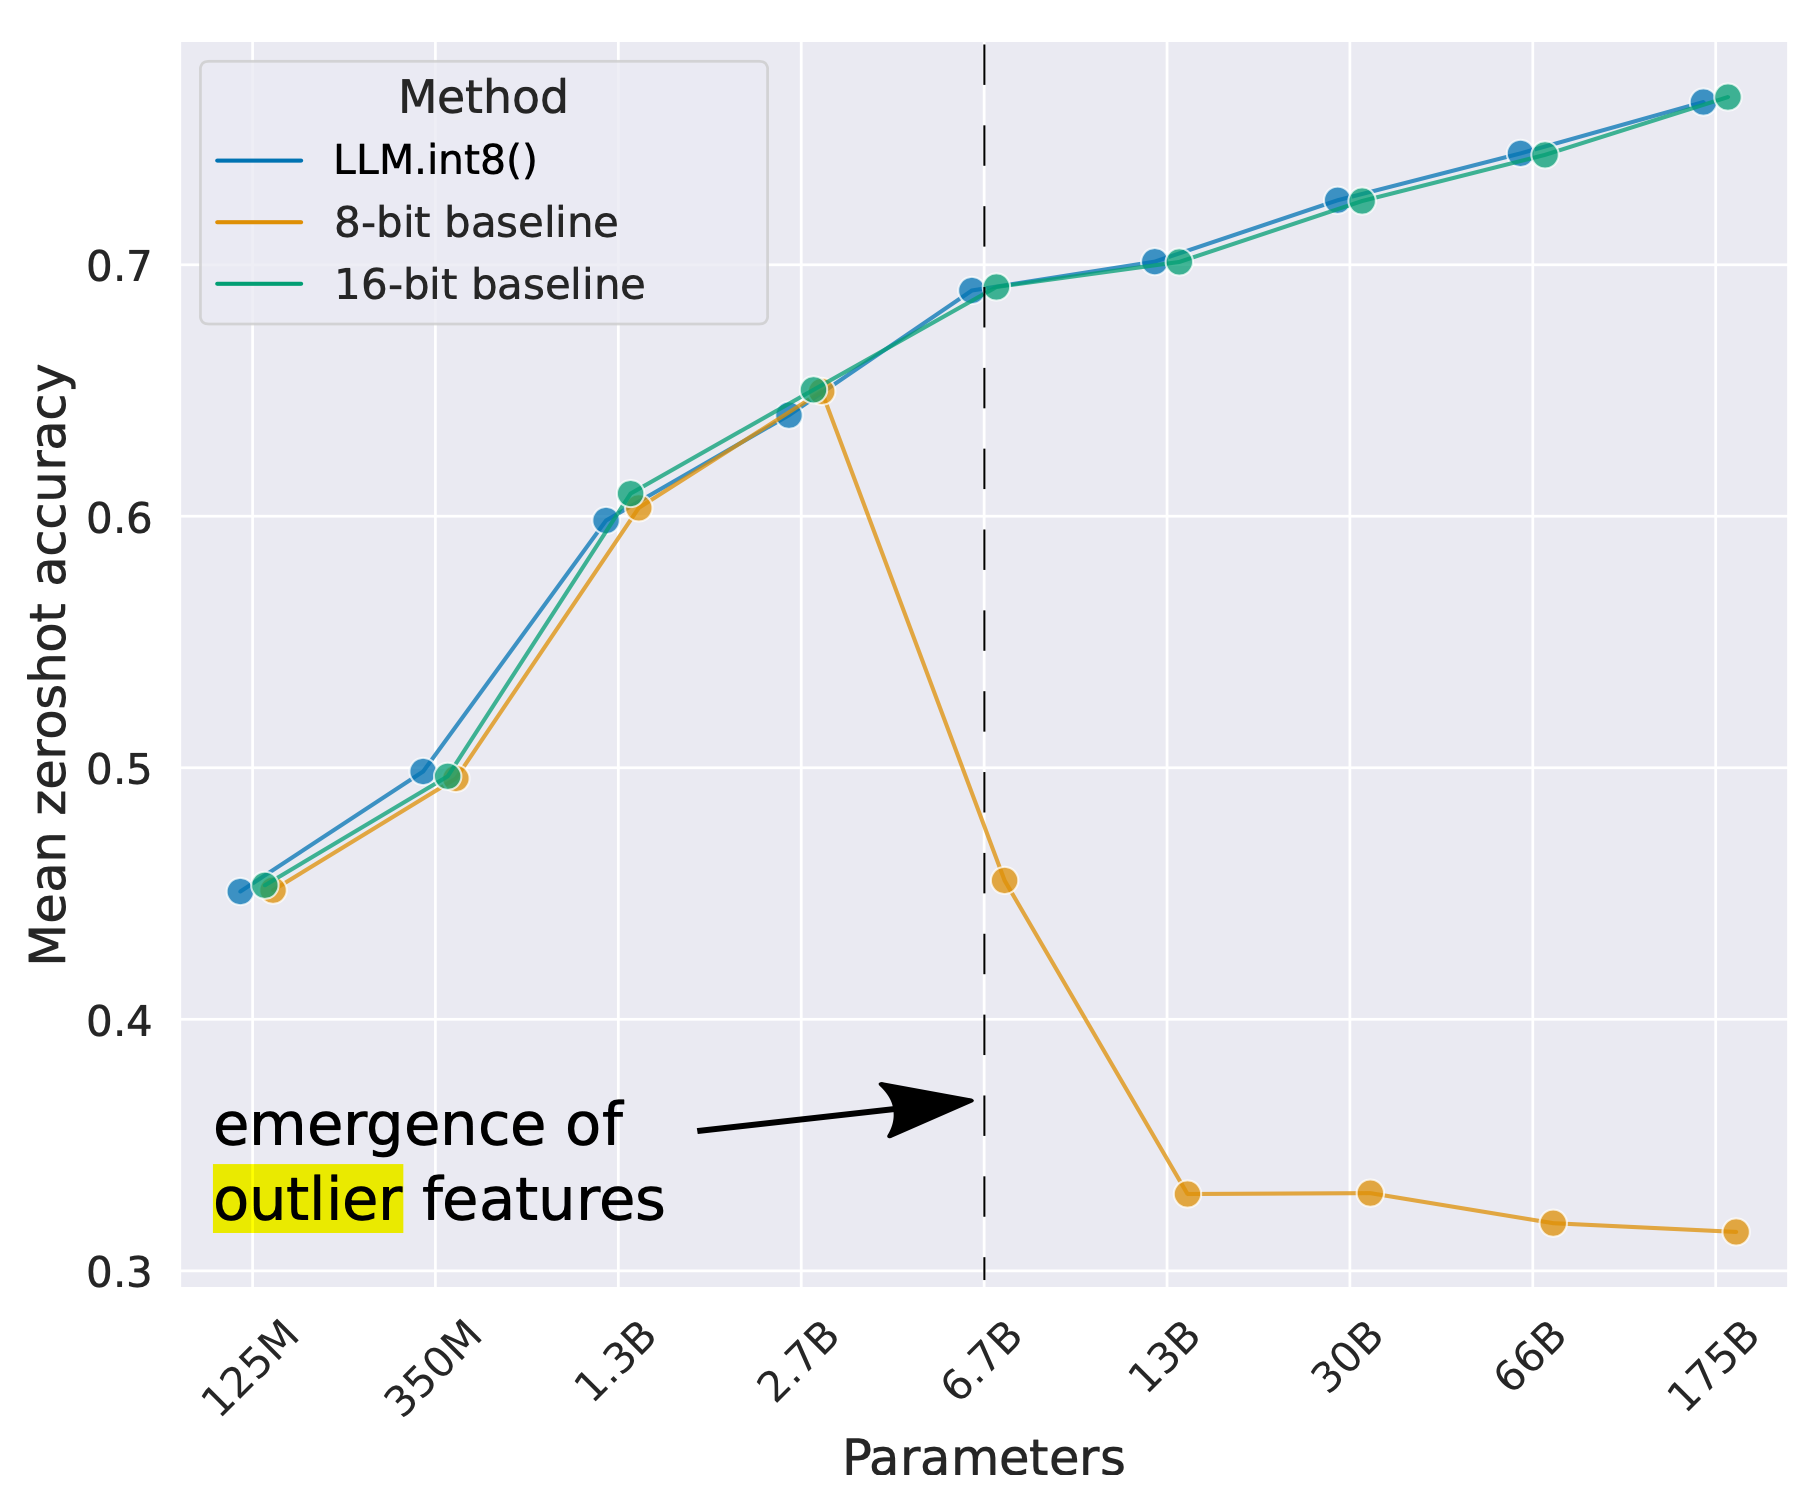
Large Transformer Model Inference Optimization | Jessica's Homepage
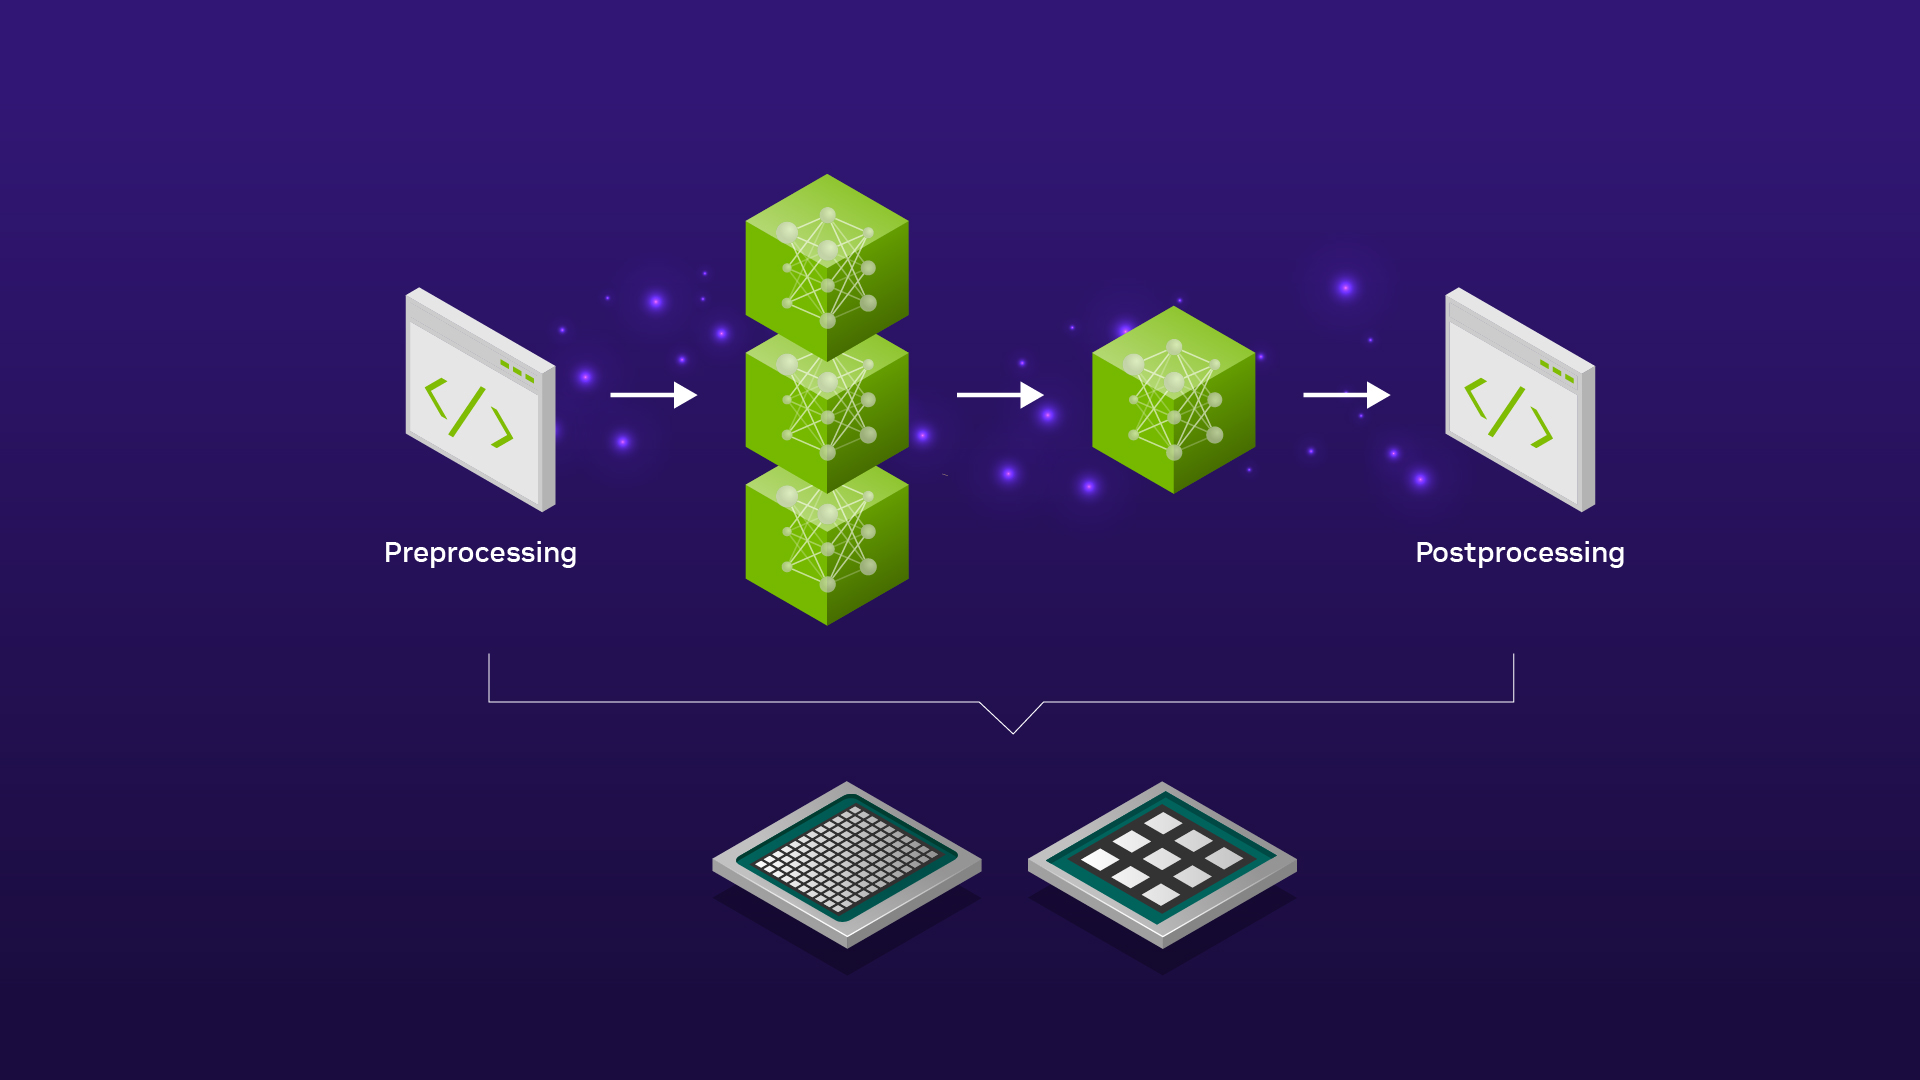
Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

MLOps deployment best practices for real-time inference model serving ...
Advertisement Space (336x280)

Top 10 AI Inference Serving Platforms Model Serving Features, Pros ...

VEGAH | AI Inference & Serving Optimization

Exploring AI Model Inference: Servers, Frameworks, and Optimization ...
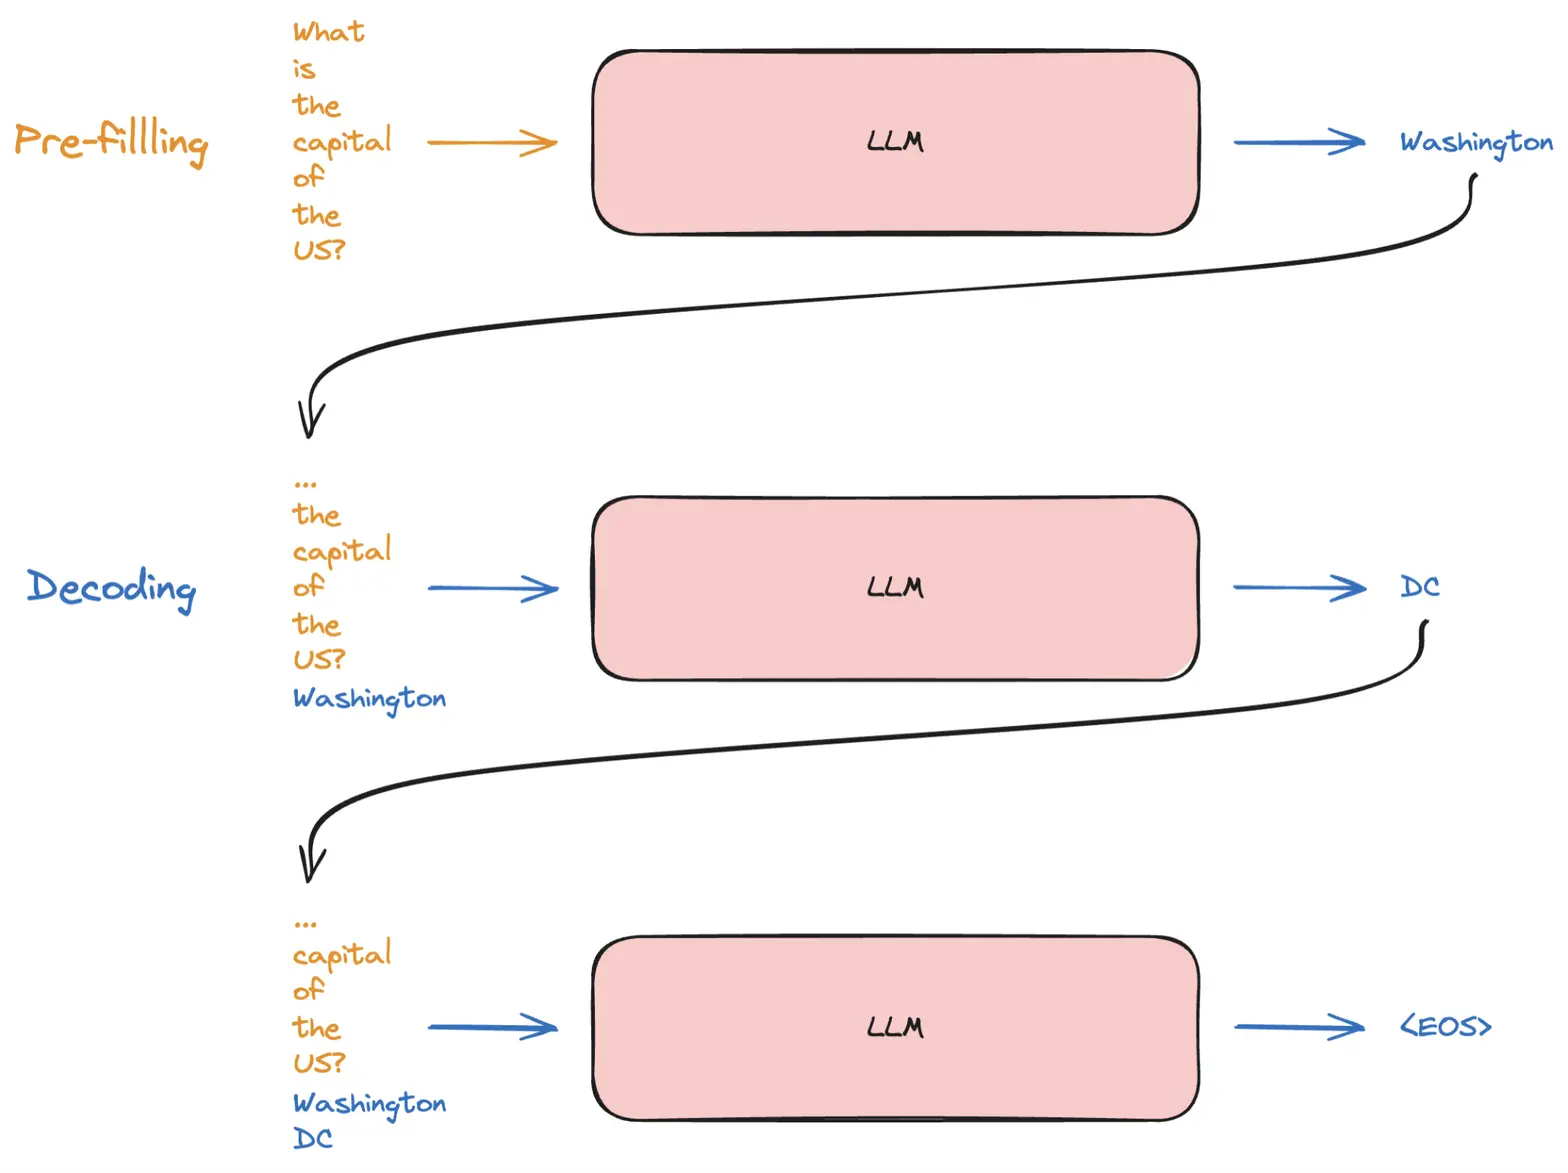
Large Transformer Model - Inference Optimization | Wei’s Learning Notes
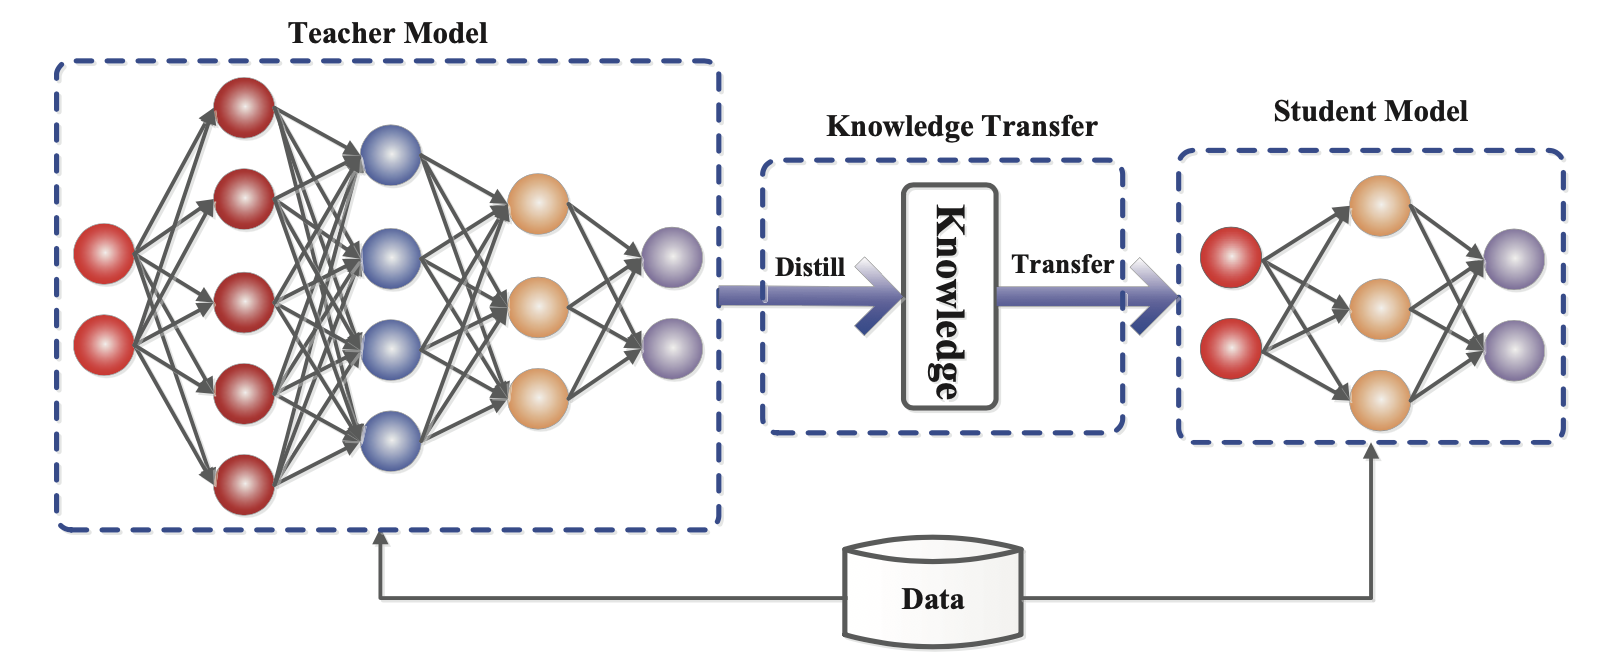
Large Transformer Model Inference Optimization | Jessica's Homepage

LLM inference optimization: Model Quantization and Distillation - YouTube