
Instruction Tuning Free Visual Token Complement For Multimodal Llms

ECCV2024 Instruction Tuning free Visual Token Complement for Multimodal ...

Instruction Tuning-free Visual Token Complement for Multimodal LLMs

Instruction Tuning-free Visual Token Complement for Multimodal LLMs
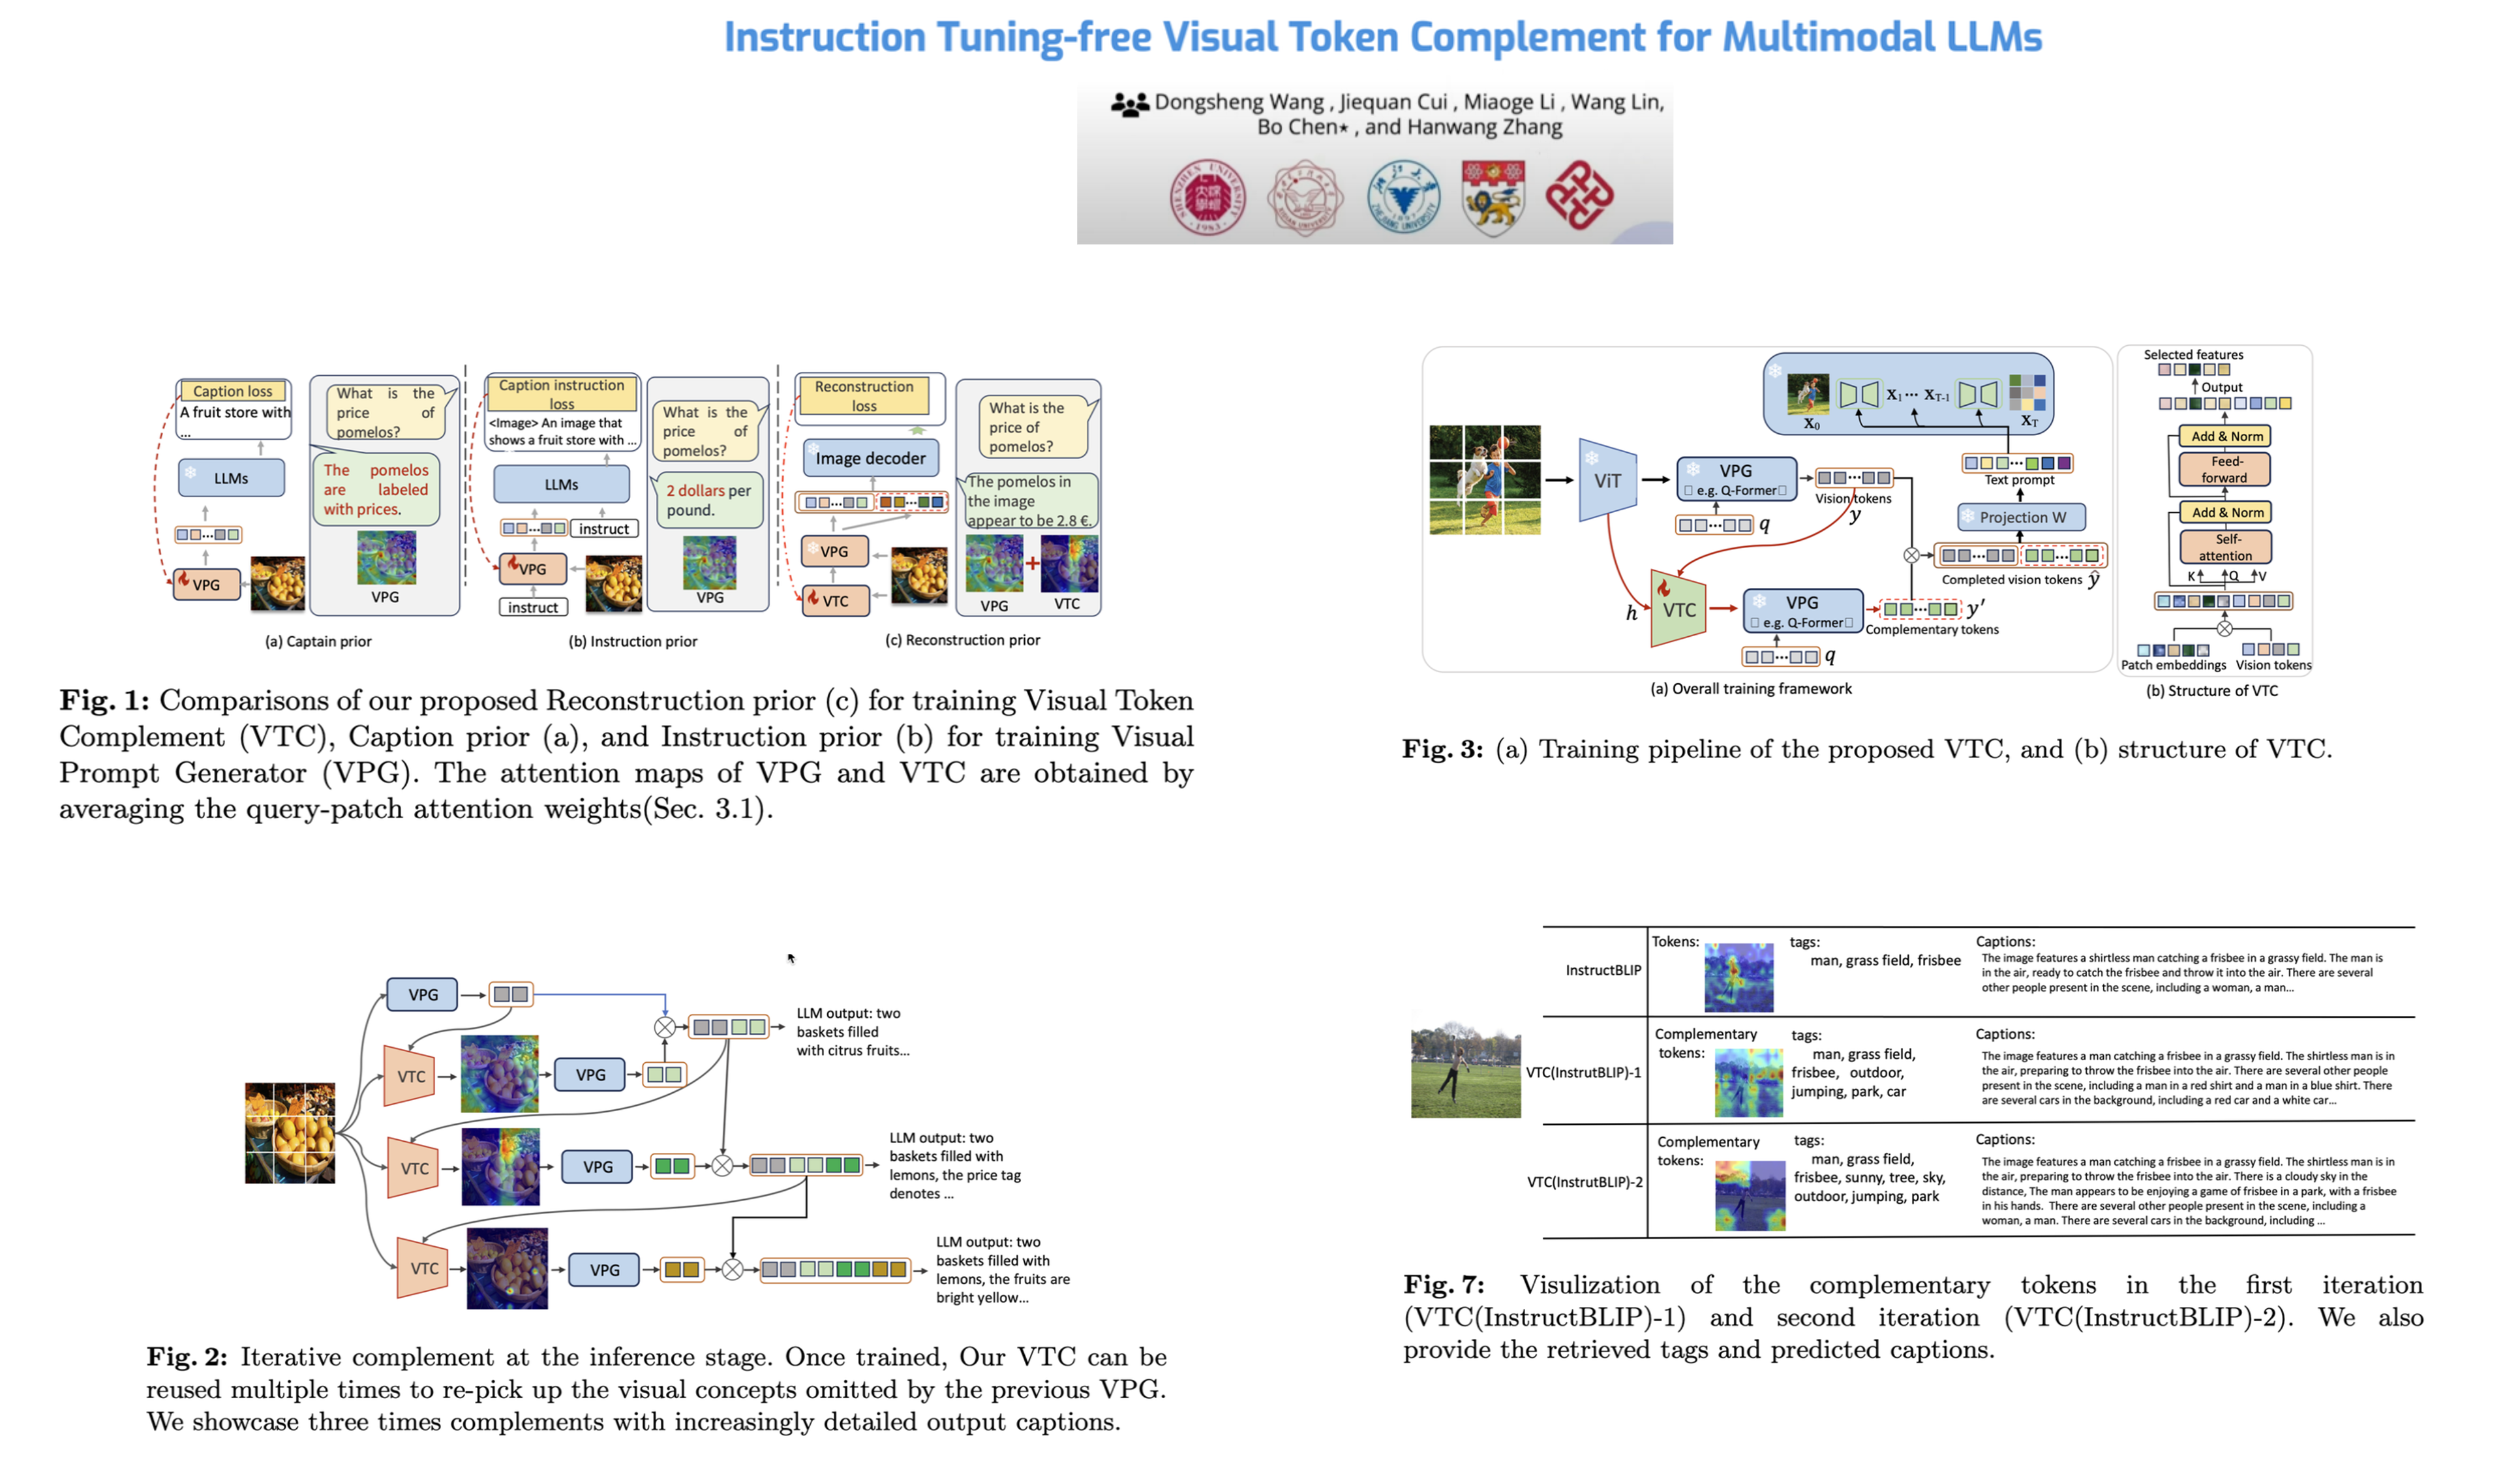
ECCV Poster Instruction Tuning-free Visual Token Complement for ...

Figure 1 from Instruction Tuning-free Visual Token Complement for ...

Multimodal LLM using Federated Visual Instruction Tuning for Visually ...

[2408.05019] Instruction Tuning-free Visual Token Complement for ...

Multimodal LLM using Federated Visual Instruction Tuning for Visually ...

[2408.05019] Instruction Tuning-free Visual Token Complement for ...
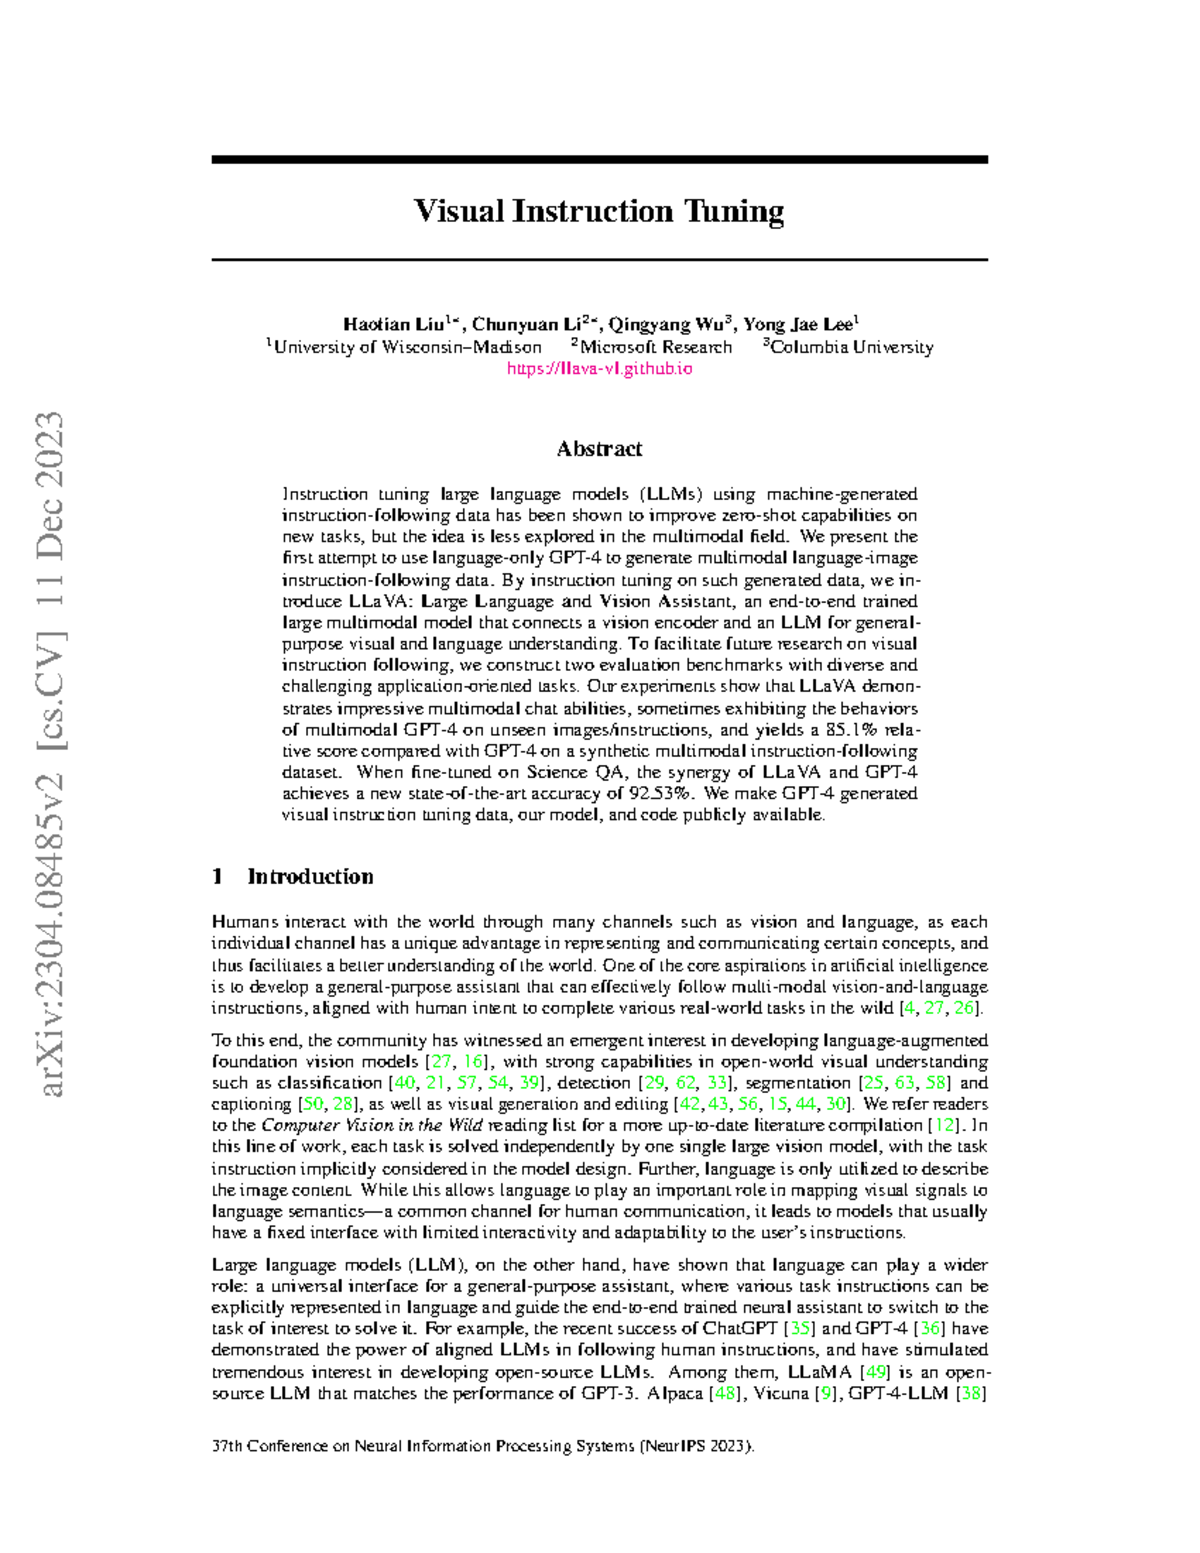
Visual Instruction Tuning for Multimodal Models: LLaVA Overview (2304 ...
Advertisement Space (300x250)

Paper page - Position-Enhanced Visual Instruction Tuning for Multimodal ...

论文翻译:Position-Enhanced Visual Instruction Tuning for Multimodal Large ...

[2408.05019] Instruction Tuning-free Visual Token Complement for ...
Visual Instruction Tuning towards General-Purpose Multimodal Large ...

[论文评述] Video Token Sparsification for Efficient Multimodal LLMs in ...

Blink: Dynamic Visual Token Resolution for Enhanced Multimodal ...

[논문 리뷰] Blink: Dynamic Visual Token Resolution for Enhanced Multimodal ...

Reconstructive Visual Instruction Tuning
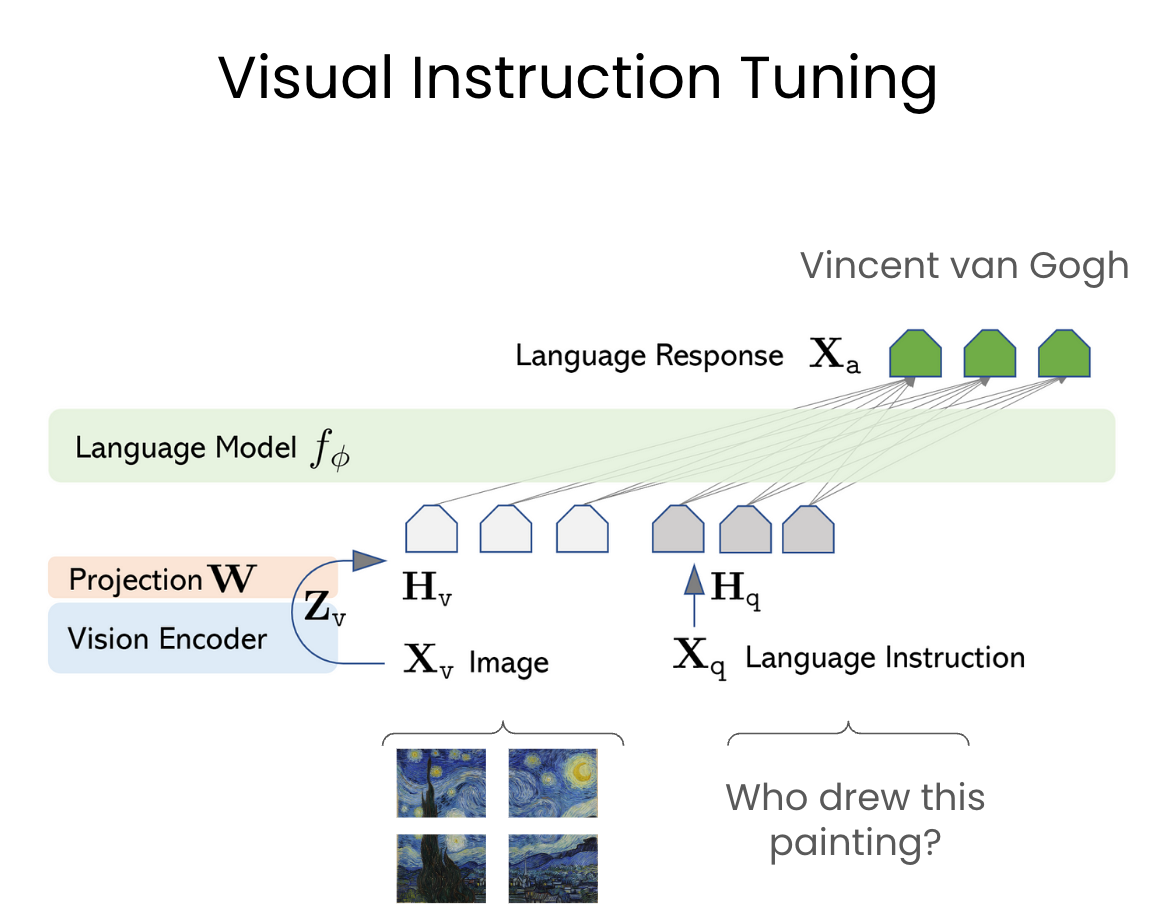
Visual Instruction Tuning | Weaviate
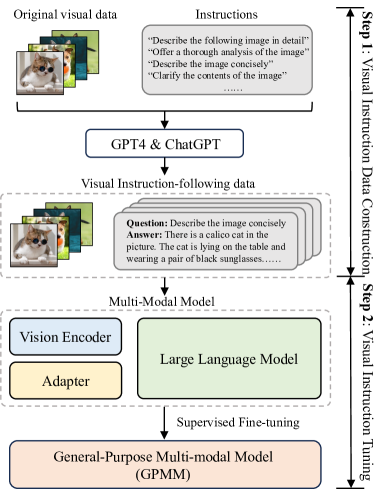
[2312.16602] Visual Instruction Tuning towards General-Purpose ...
Advertisement Space (336x280)

(PDF) Reconstructive Visual Instruction Tuning
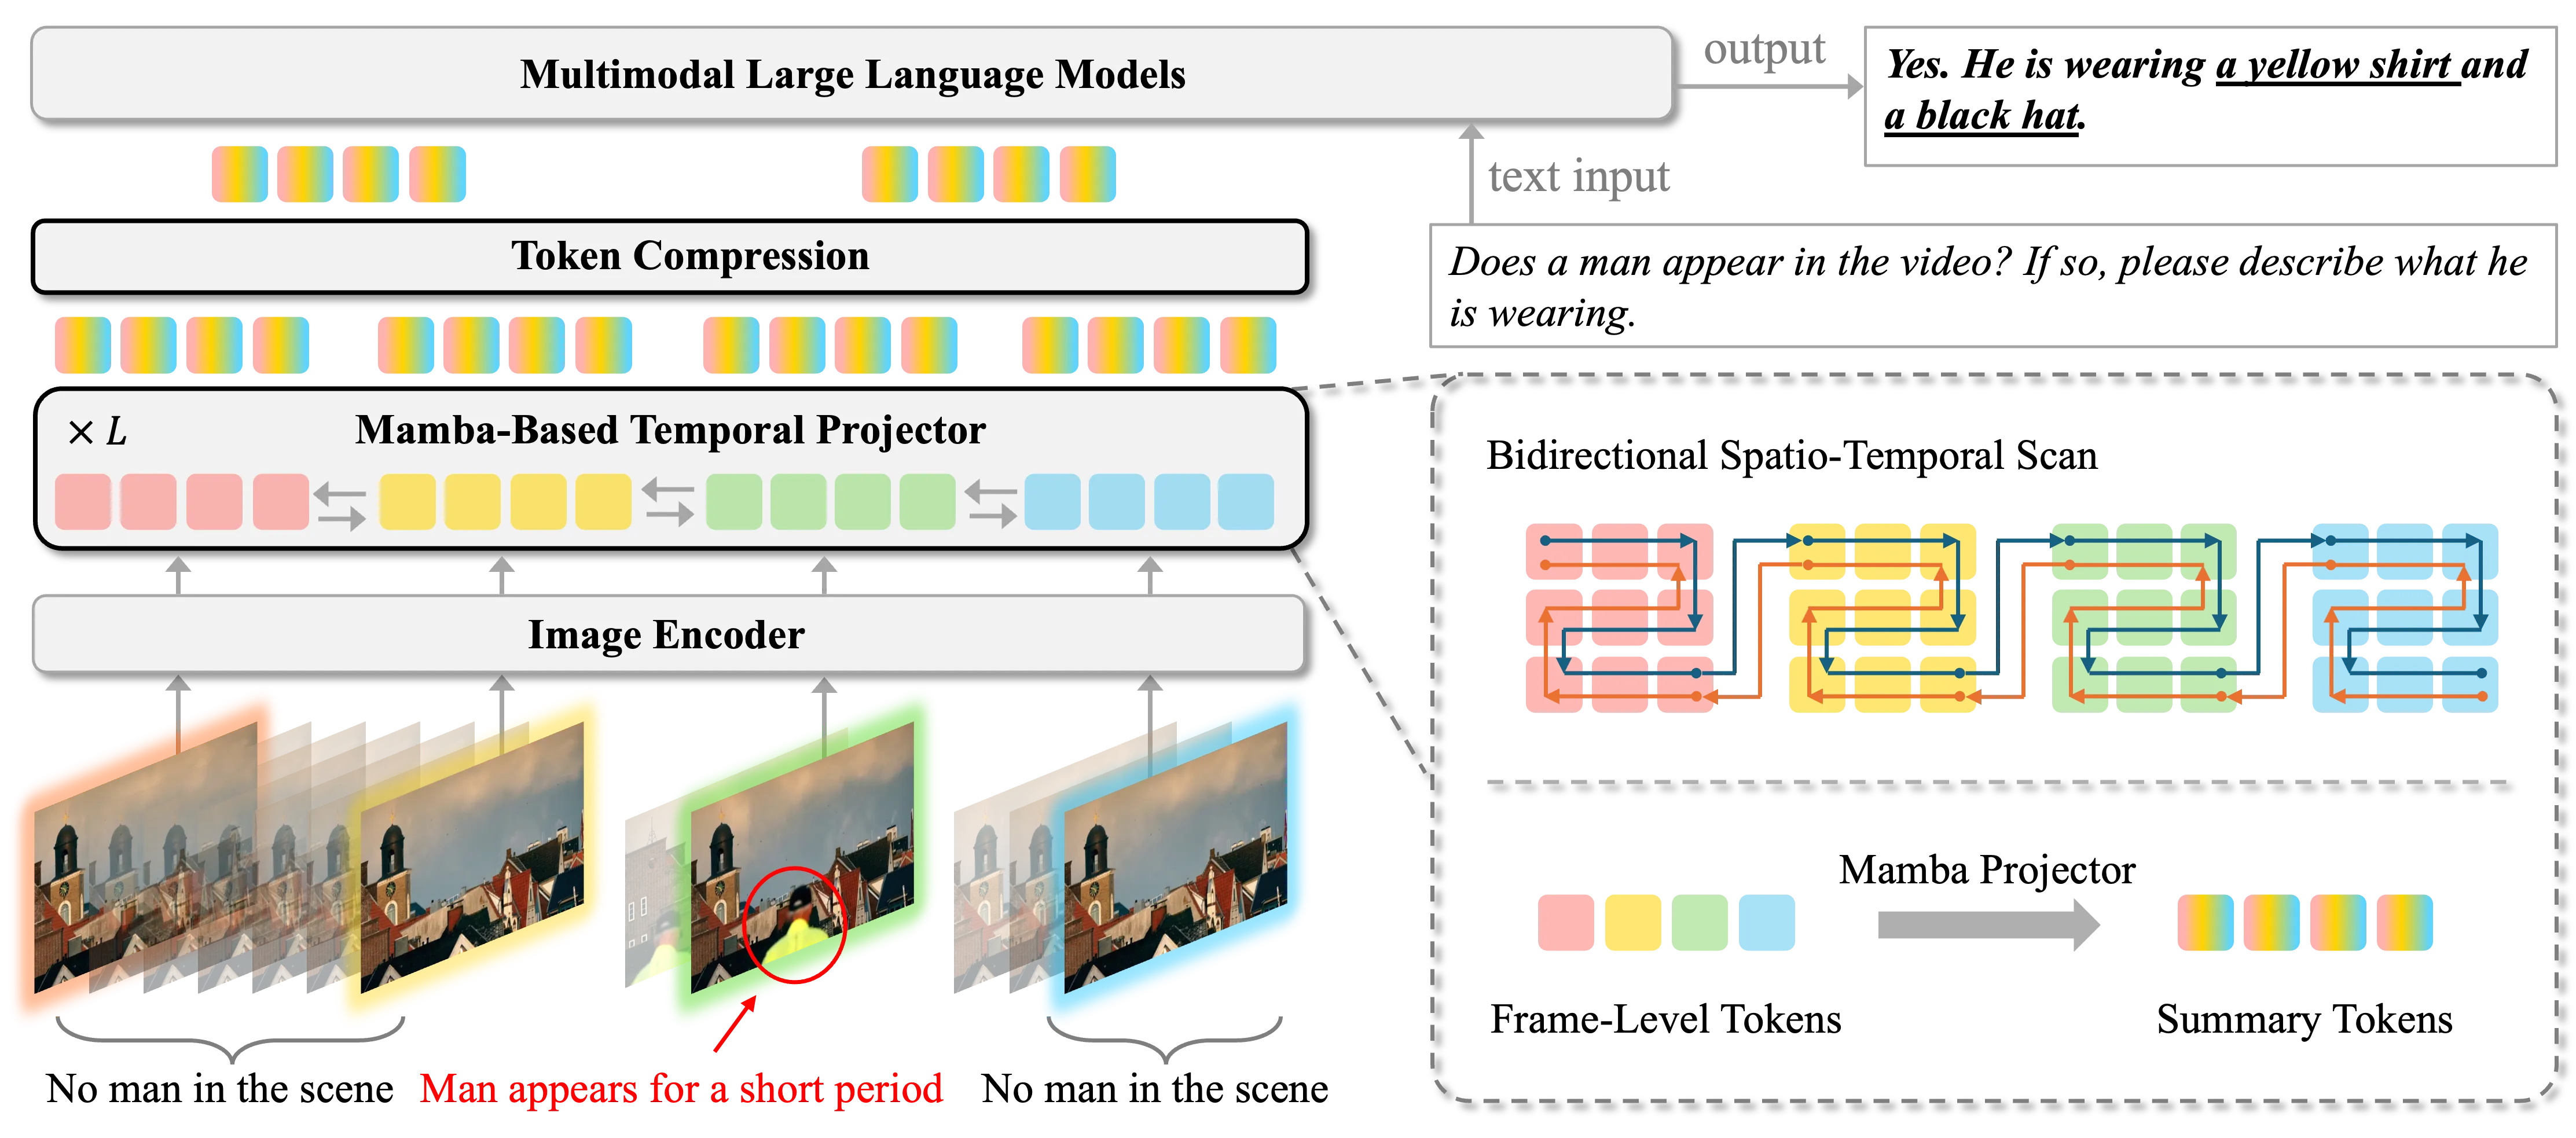
Token-Efficient Long Video Understanding for Multimodal LLMs

Paper page - Learning Free Token Reduction for Multi-Modal LLM

Paper page - TokenPacker: Efficient Visual Projector for Multimodal LLM

(PDF) Learning Free Token Reduction for Multi-Modal LLM
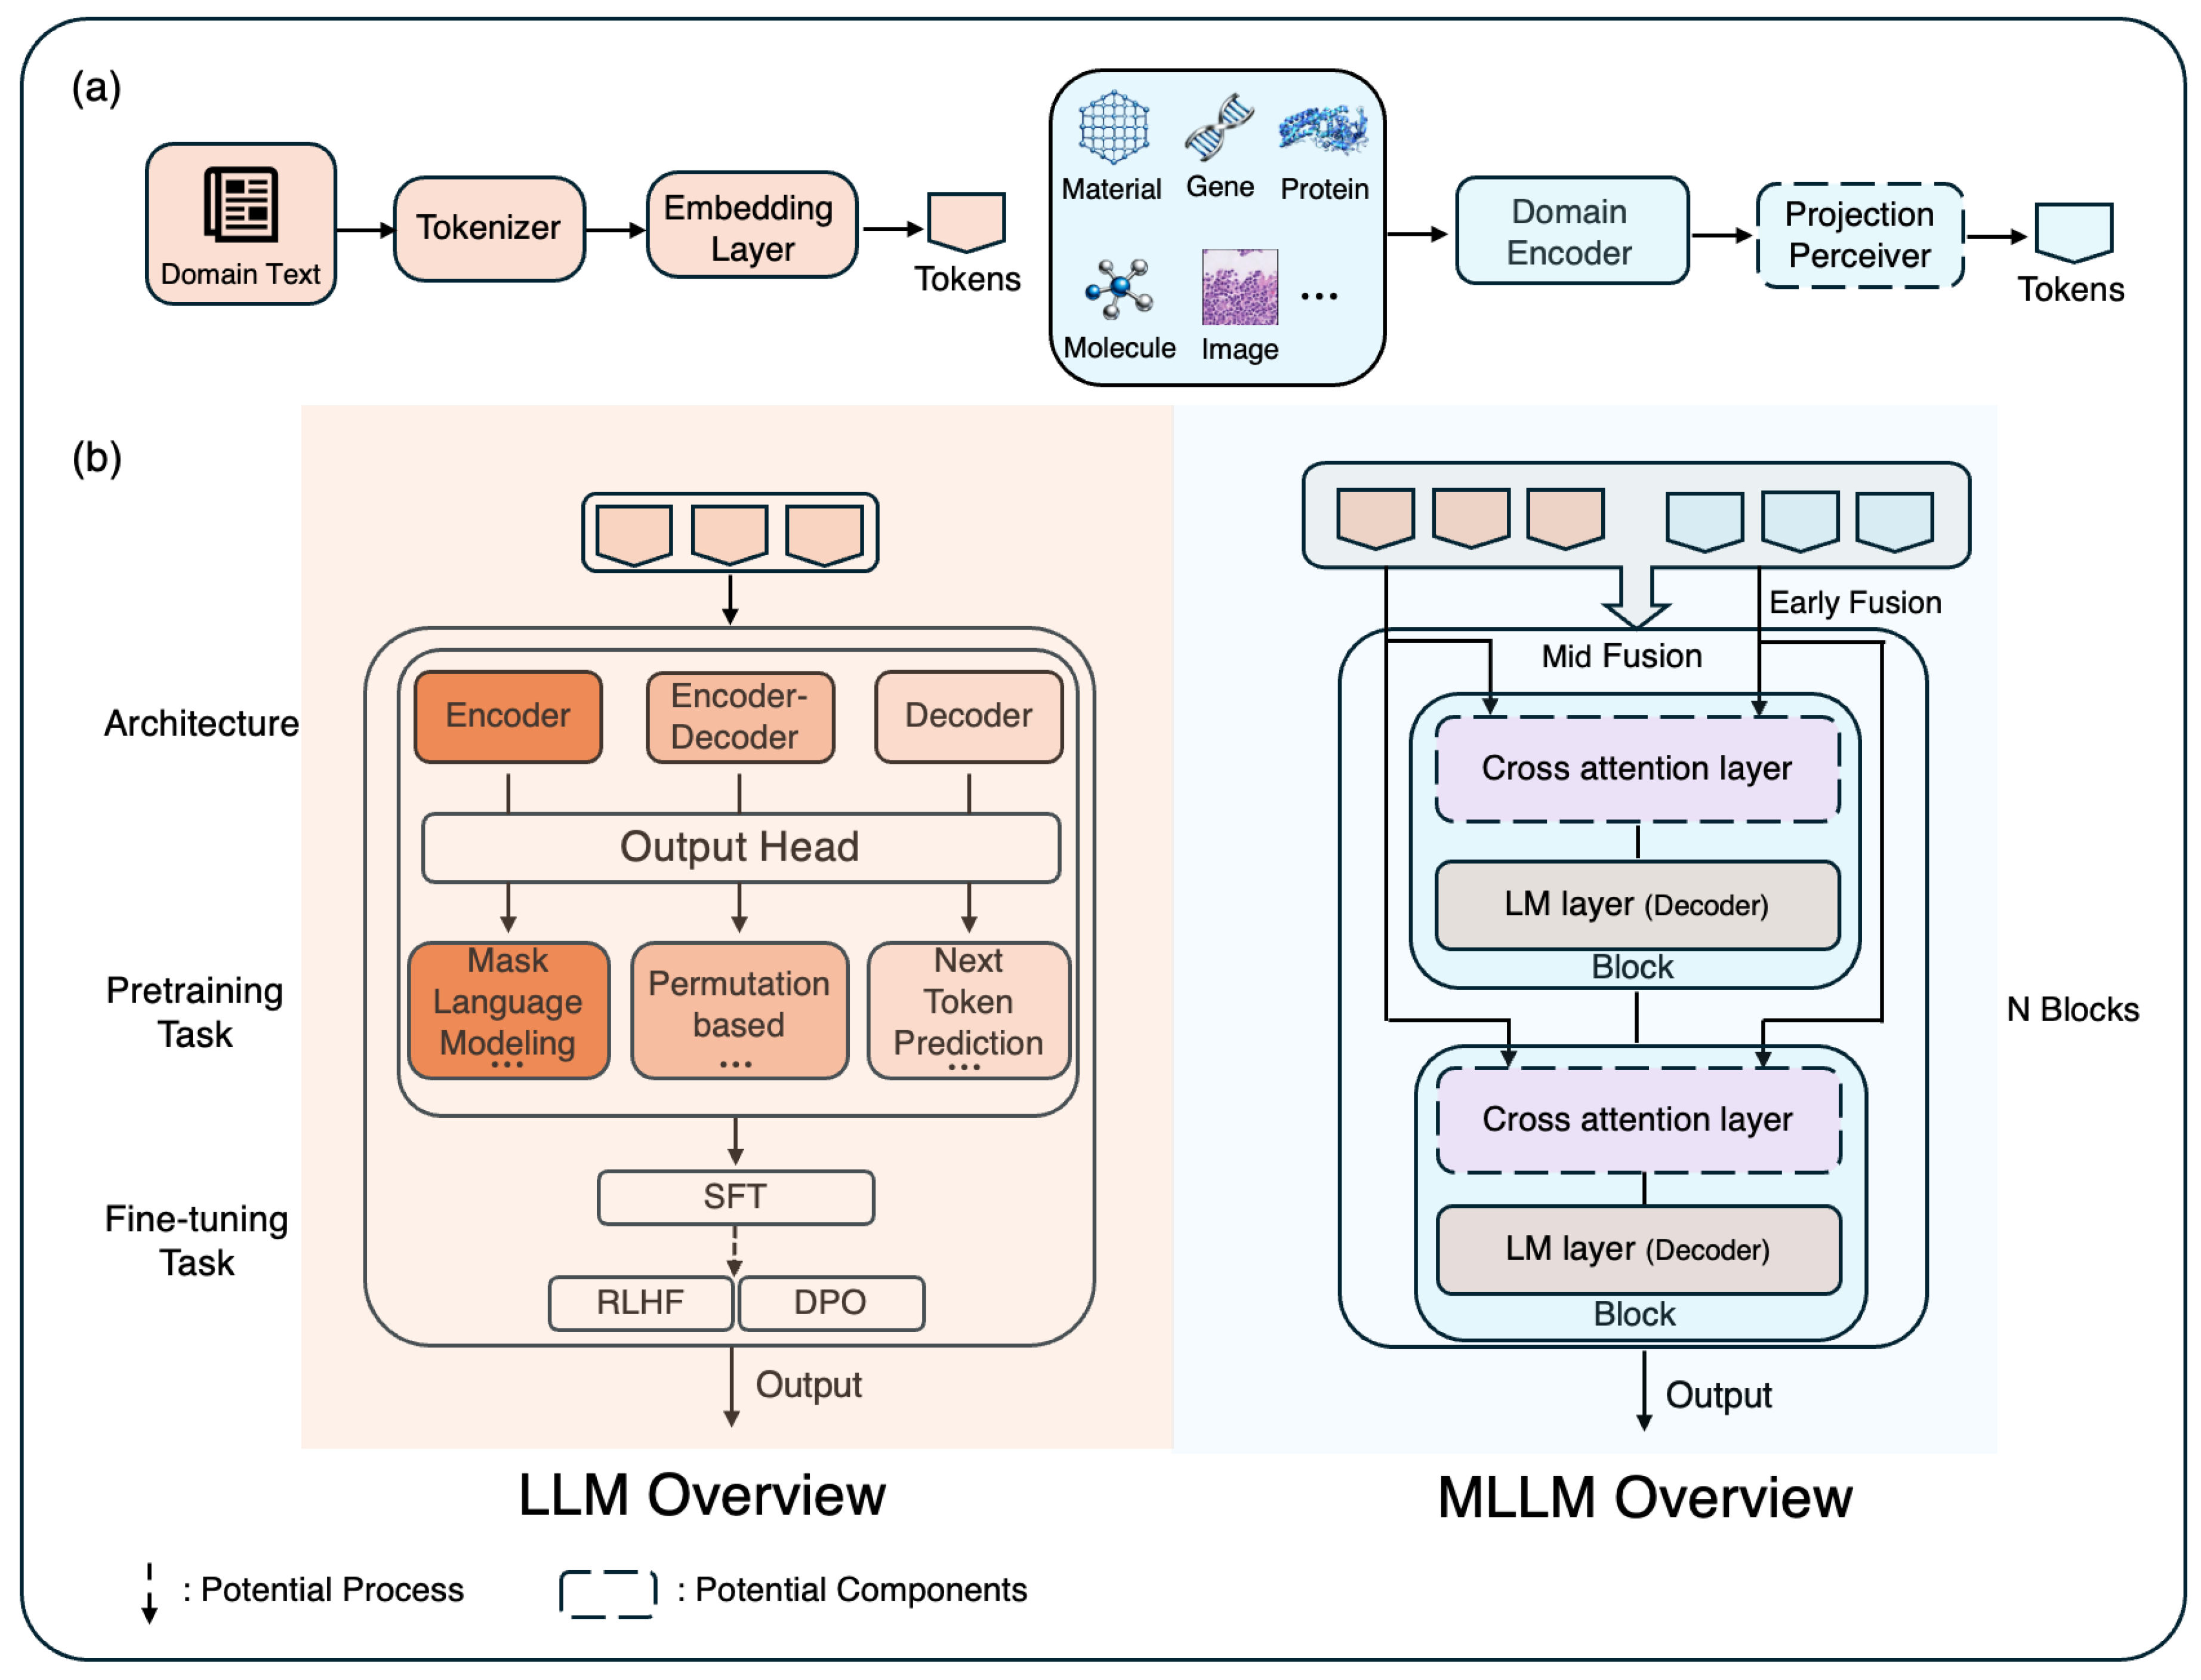
A Comprehensive Survey of Multimodal LLMs for Scientific Discovery[v1 ...

Paper page - Visual Instruction Tuning

Boosting Visual Instruction Tuning with Self-Supervised Guidance

Augmenting Multimodal LLMs with Self-Reflective Tokens for Knowledge ...

Token Activation Map to Visually Explain Multimodal LLMs | alphaXiv
Advertisement Space (336x280)

GitHub - arvindmvepa/mpLLM: Multimodal LLM for visual question ...

MiniGPT4-Video: Advancing Multimodal LLMs for Video Understanding with ...

LLMs From Scratch - Chapter 7: Fine-tuning for Instruction Following ...

Augmenting Multimodal LLMs with Self-Reflective Tokens for Knowledge ...

[논문 리뷰] Unlocking Pretrained LLMs for Motion-Related Multimodal ...

Paper page - Token Activation Map to Visually Explain Multimodal LLMs