
Int8 Inference In C Tensorrt Api Without Onnx Model Issue 659
Int8 Inference in C++ TensorRT API without Onnx Model · Issue #659 ...
Failed to convert ONNX model to TensorRT in int8 mode · Issue #2606 ...
INT8 inference in TensorRT 8.0 get wrong answer · Issue #1289 · NVIDIA ...
INT8 and FP32 in the same ONNX model · Issue #1973 · NVIDIA/TensorRT ...

INT8 and FP32 in the same ONNX model · Issue #1973 · NVIDIA/TensorRT ...
Deploy model to TensorRT failed in conversion to ONNX · Issue #55 ...
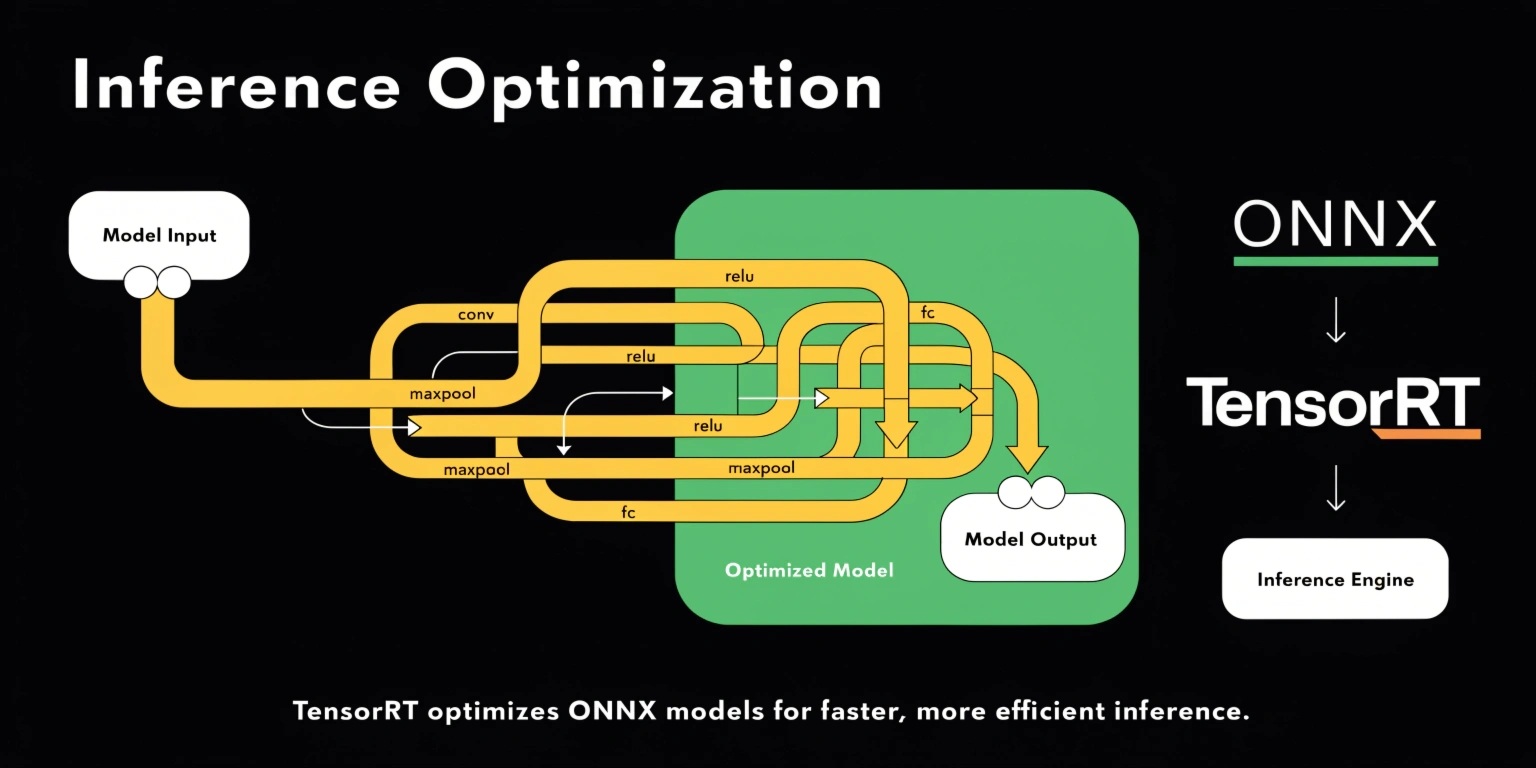
Inference Optimization Using TensorRT and ONNX for Faster AI Model ...
Unable to convert an onnx model to tensorrt using int8 with calibration ...
How to deploy an ONNX model with int8 calibration? · Issue #557 ...
How does TensorRT implements the `Add` in INT8 mode ? · Issue #1144 ...
Advertisement Space (300x250)
ONNX -> TensorRT FP32 model with INT8 input produces error: Calibration ...
TensorRT INT8 calibration python API · Issue #2322 · NVIDIA/TensorRT ...
Error when converting the ONNX model to TensorRT · Issue #866 · NVIDIA ...
Segmentation fault for TensorRT 8.6 when loading ONNX model via C++ API ...
Problem converting ONNX model to TensorRT 7.2.1(dien.onnx) · Issue #670 ...
Fail when I try to export onnx model to int8 engine · Issue #2397 ...
Onnx int8 model running error · Issue #1627 · NVIDIA/TensorRT · GitHub

how to run inference with a quantified onnx model ? · Issue #1370 ...
Question about quantized INT8 model inference · Issue #2404 · NVIDIA ...
ONNX model produces different results in tensorRT 7 compared to onnx ...
Advertisement Space (336x280)
Failing to convert int8 onnx model to trt engine · Issue #3360 · NVIDIA ...
Using TensorRT with ONNX Models in Jetson Inference - Help Docs for ...
will input be quantified in tensorrt int8 mode · Issue #2927 · NVIDIA ...
Problem making inference with TensorRT model · Issue #568 · openpifpaf ...
Quantize an onnx model with int8 and fp16 · Issue #3352 · NVIDIA ...
onnx tensorrt model infer results are different in some special shapes ...
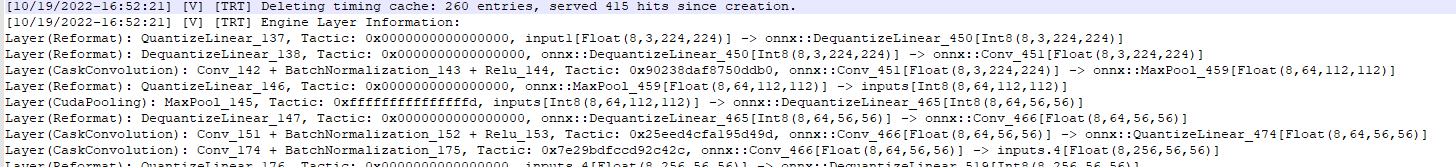
Question about quantized INT8 model inference · Issue #2404 · NVIDIA ...
Building TensorRT 8 engine from ONNX quantized model fails · Issue ...

Building TensorRT 8 engine from ONNX quantized model fails · Issue #751 ...

How does TensorRT implements the `Add` in INT8 mode ? · Issue #1144 ...
Advertisement Space (336x280)
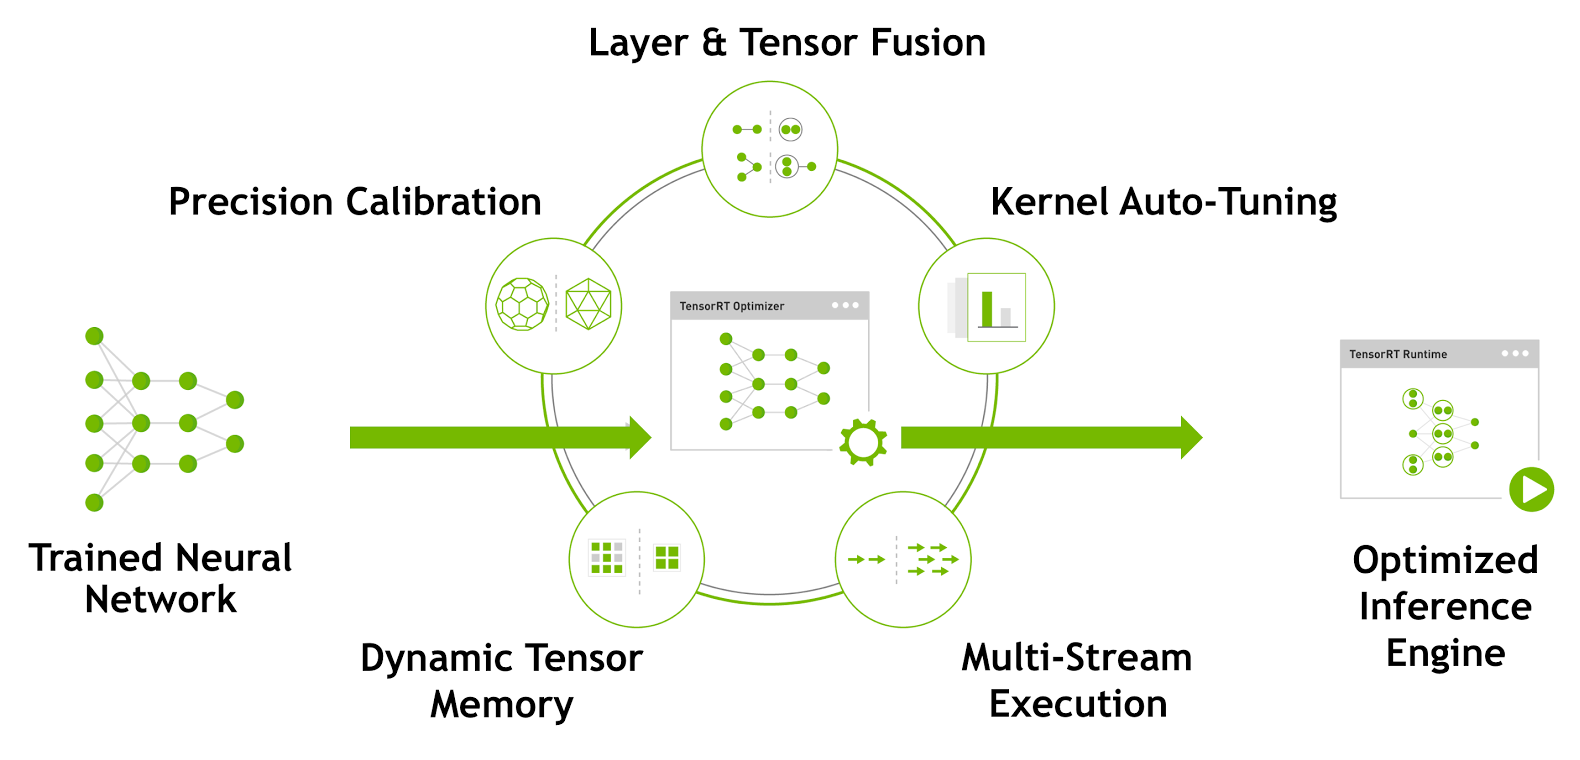
Fast INT8 Inference for Autonomous Vehicles with TensorRT 3 | NVIDIA ...
TensorRT Quantization: NVIDIA's INT8 Inference SDK | Inference Systems

Comparison of inference speed with and without TensorRT deployment ...

How To Run Inference Using TensorRT C++ API | LearnOpenCV
When I use the TensorRT to infer MoblieNet in the INT8 mode,I meet the ...
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime