
Interaction Dynamics As A Reward Signal For Llms Ai Research Paper

Interaction Dynamics as a Reward Signal for LLMs | AI Research Paper ...

A General-Purpose Device for Interaction with LLMs | AI Research Paper ...

A General-Purpose Device for Interaction with LLMs | AI Research Paper ...

Confidence as a Reward: Transforming LLMs into Reward Models | AI ...

Sample-Efficient Alignment for LLMs | AI Research Paper Details

Dynamic Evaluation for Oversensitivity in LLMs | AI Research Paper Details

Figure 1 from Multimodal LLMs as Customized Reward Models for Text-to ...

Sample-Efficient Alignment for LLMs · HF Daily Paper Reviews by AI

[논문 리뷰] Confidence as a Reward: Transforming LLMs into Reward Models

Sample-Efficient Alignment for LLMs · HF Daily Paper Reviews by AI
Advertisement Space (300x250)

Belief Offloading in Human-AI Interaction | AI Research Paper Details

Test reward curves of G-DDPG and DDPG [47] with LLMs interaction ...
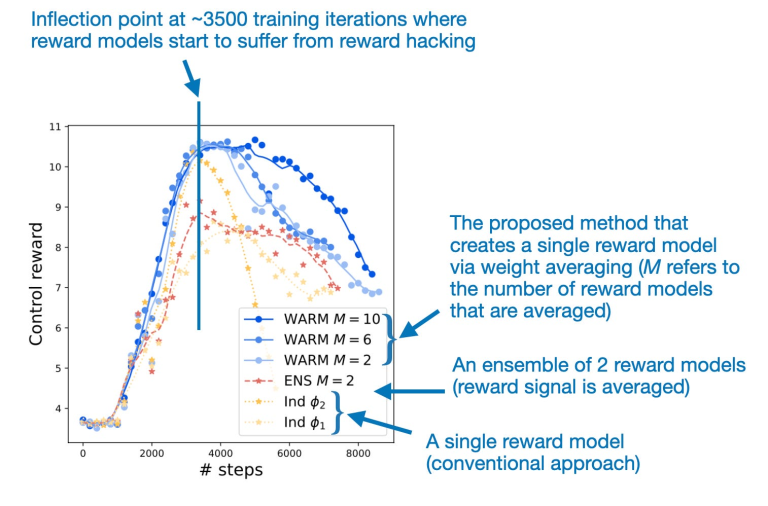
4 LLMs Research Paper in January 2025 - Analytics Vidhya
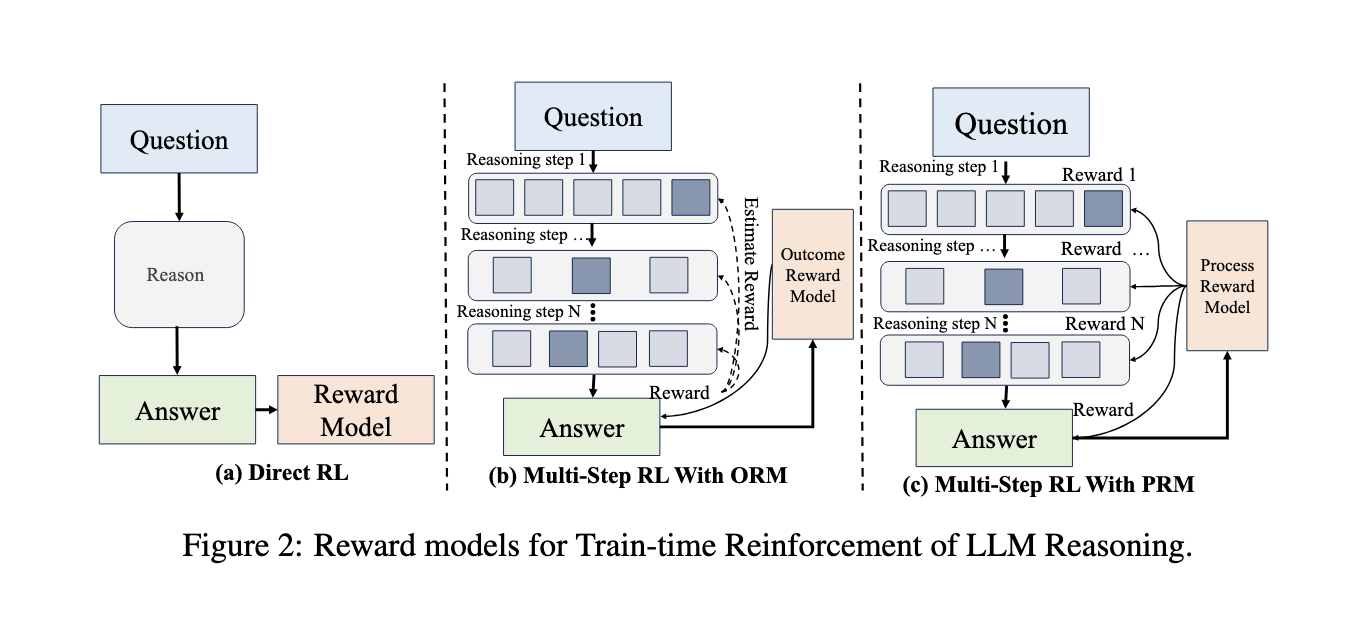
This AI Paper Explores Reinforced Learning and Process Reward Models ...

SALMON: Self-Alignment with Instructable Reward Models | AI Research ...

Reward Is Enough: LLMs Are In-Context Reinforcement Learners | AI ...
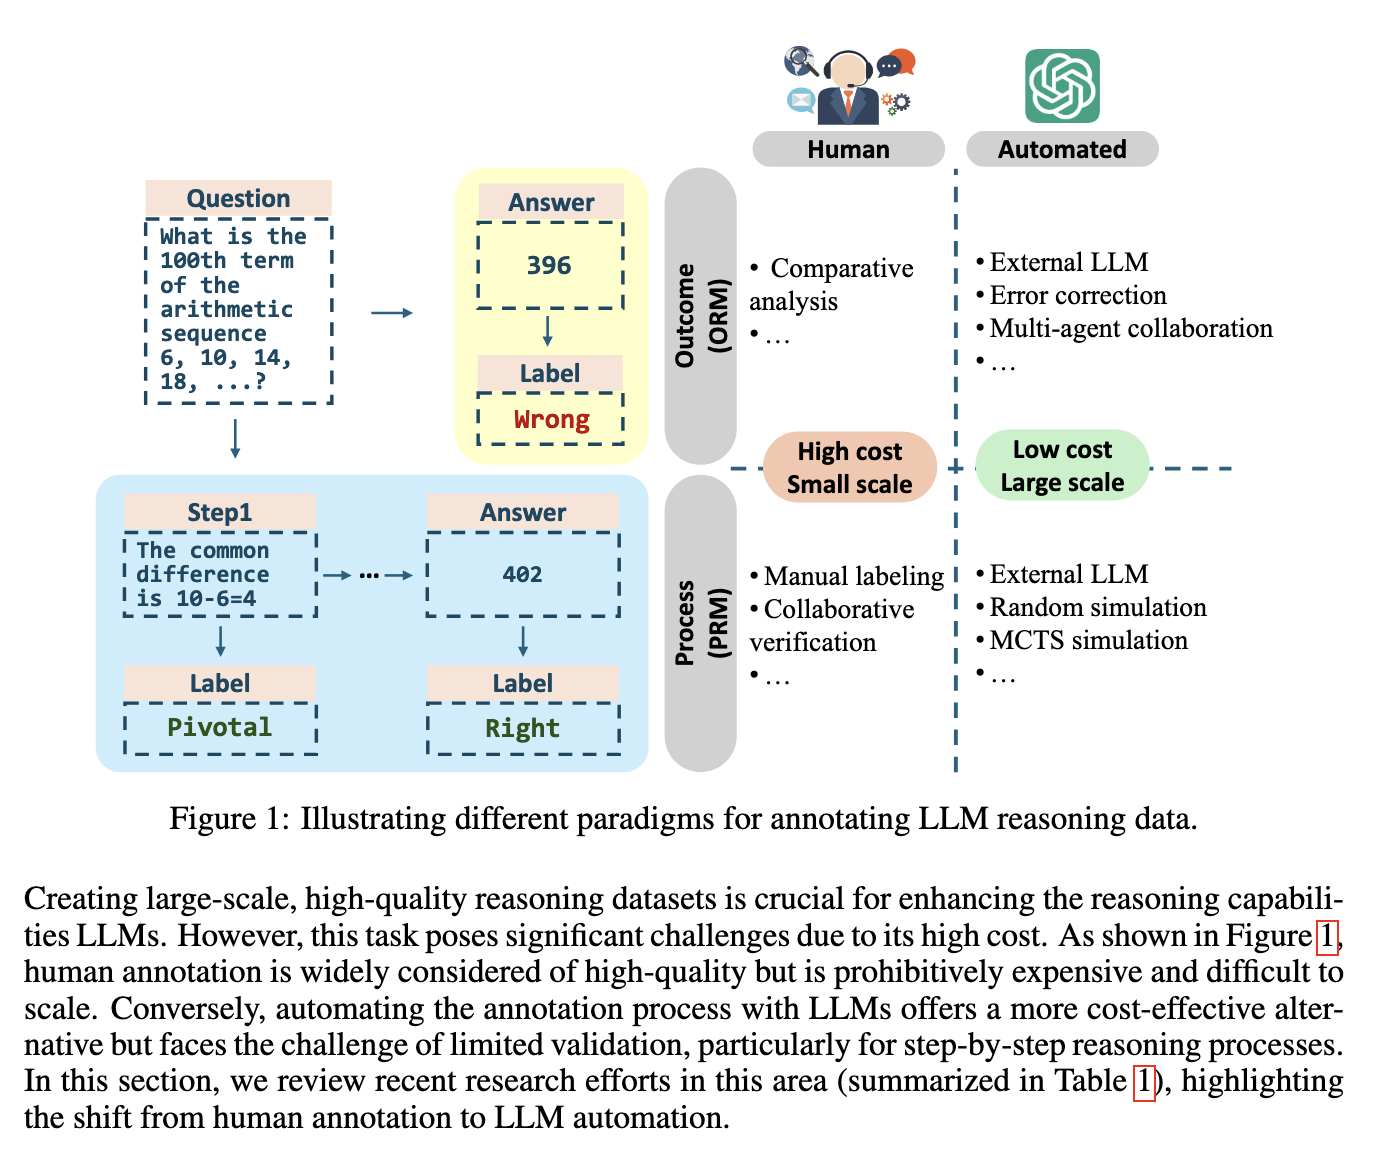
This AI Paper Explores Reinforced Learning and Process Reward Models ...

(PDF) A Framework for Robot Learning During Child-Robot Interaction ...
4 LLMs Research Paper in January 2025 - Analytics Vidhya

Do LLMs Favor LLMs? Quantifying Interaction Effects in Peer Review | AI ...
Advertisement Space (336x280)

This AI Paper Introduces SuperContext: An SLM-LLM Interaction Framework ...

Paper page - One Adapts to Any: Meta Reward Modeling for Personalized ...

This AI Research Proposes a Framework to Model User Interactions with ...

(PDF) Temporal Dynamics of the Interaction between Reward and Time ...
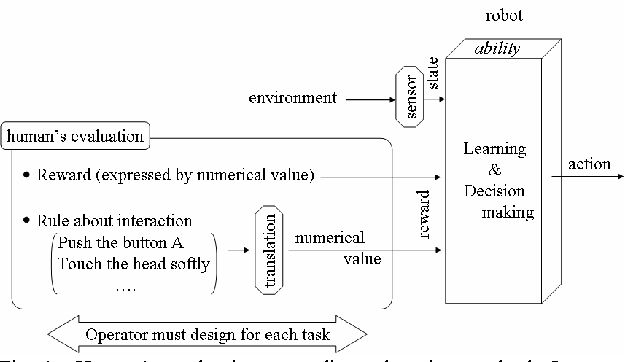
Figure 1 from A simple rule how to make a reward for learning with ...

Figure 1 from Exploiting Interaction Dynamics for Learning ...

Paper page - MINT: Evaluating LLMs in Multi-turn Interaction with Tools ...
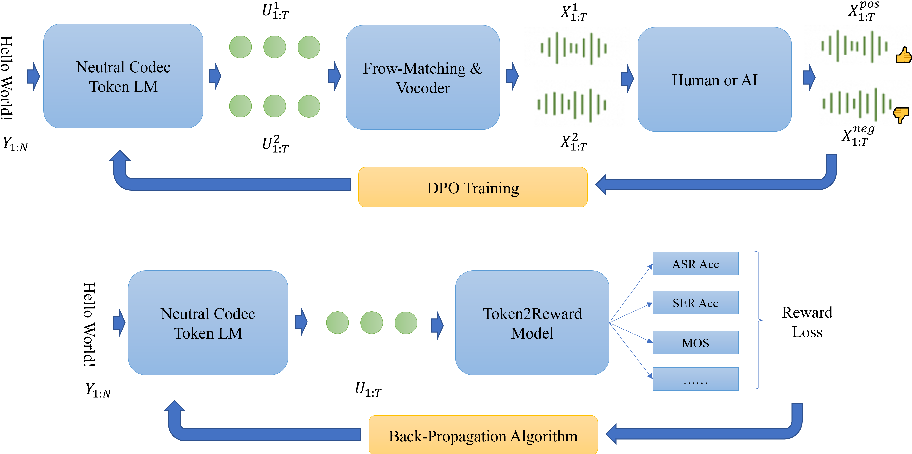
Figure 1 from Differentiable Reward Optimization for LLM based TTS ...
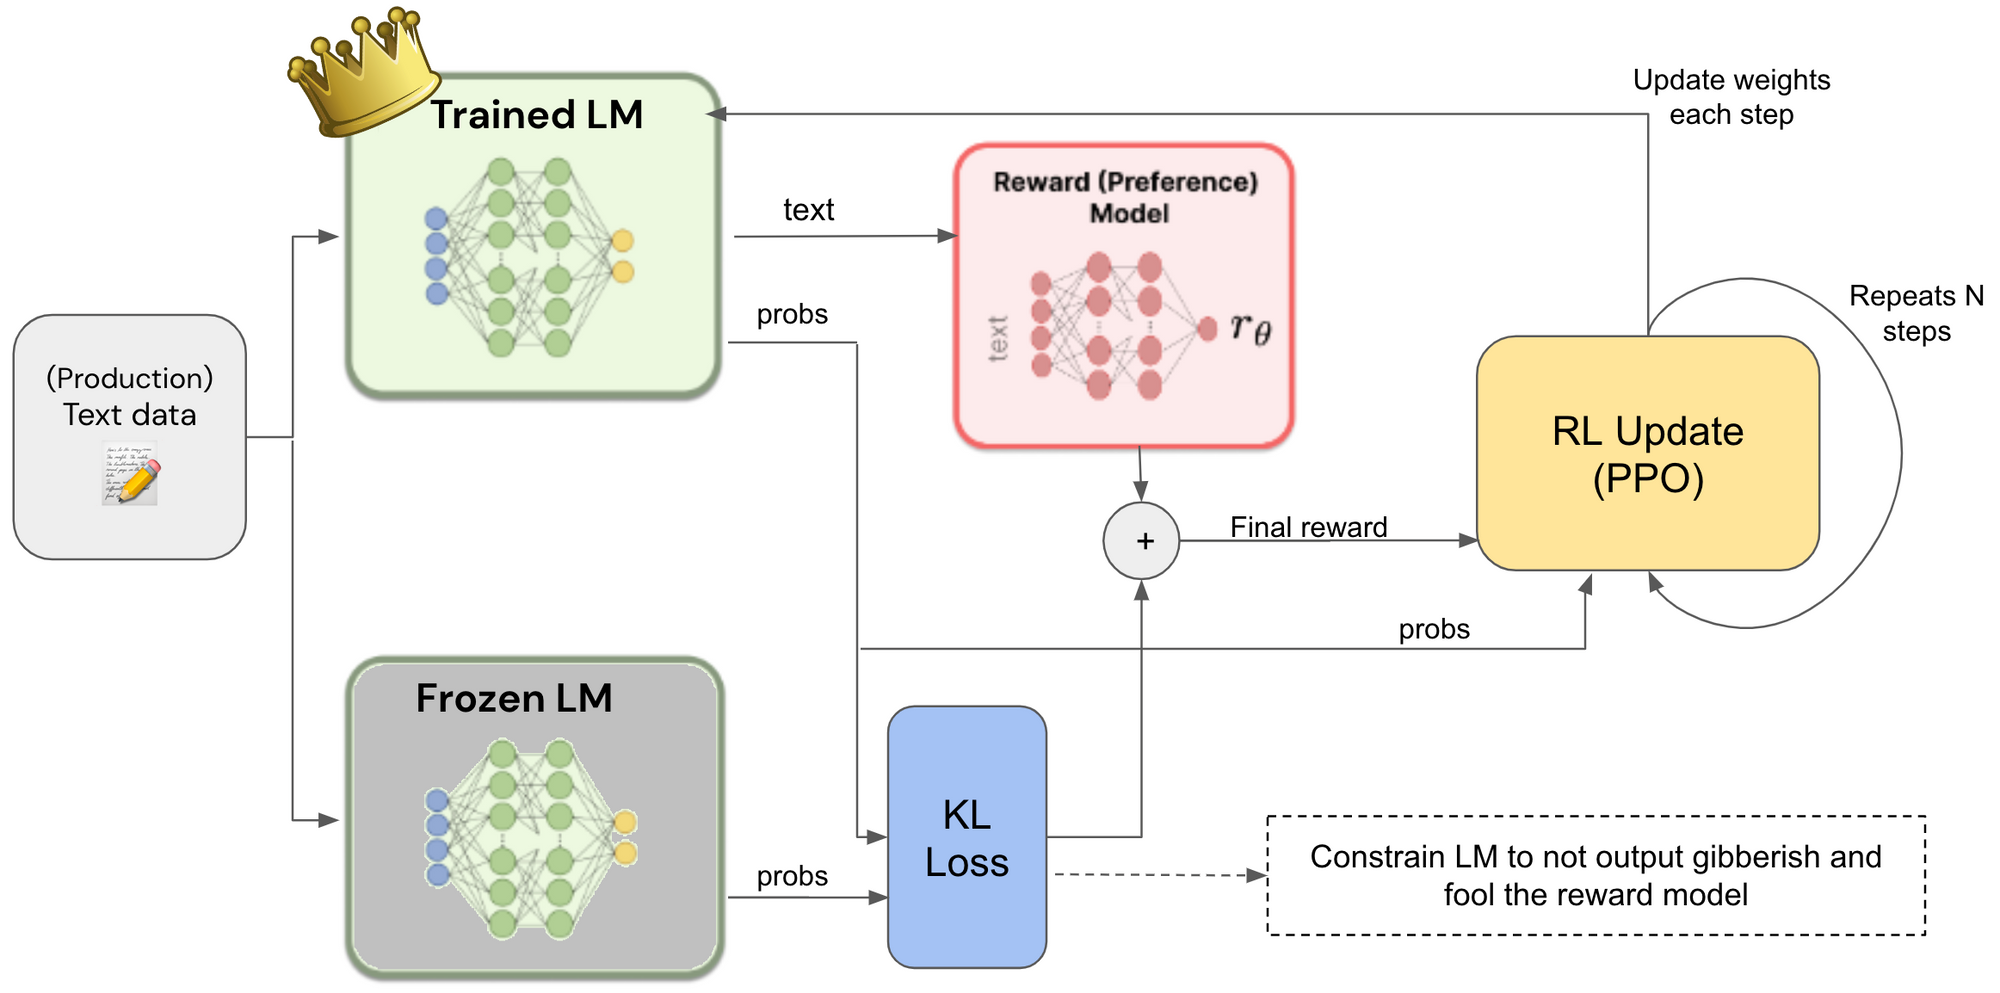
Reinforcement learning with human feedback (RLHF) for LLMs

[论文评述] TIPS: Turn-Level Information-Potential Reward Shaping for Search ...
Advertisement Space (336x280)

Reinforcement learning with human feedback (RLHF) for LLMs | SuperAnnotate
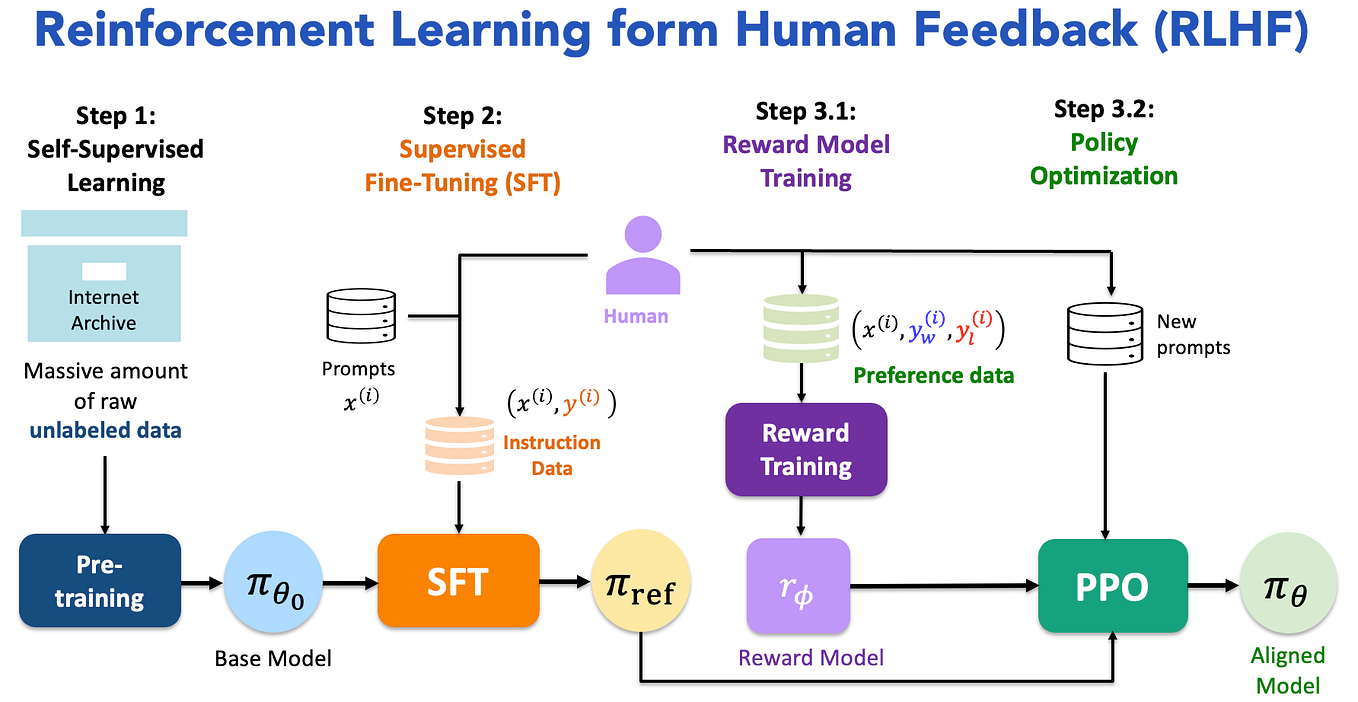
RLHF Reward Model Training. A popular technique to finetune large… | by ...

OpenRubrics: Towards Scalable Synthetic Rubric Generation for Reward ...

[Literature Review] SimBench: A Rule-Based Multi-Turn Interaction ...

Paper page - Enhancing High-order Interaction Awareness in LLM-based ...

Structured knowledge from LLMs improves prompt learning for visual ...