
Kv Cache From First Principles
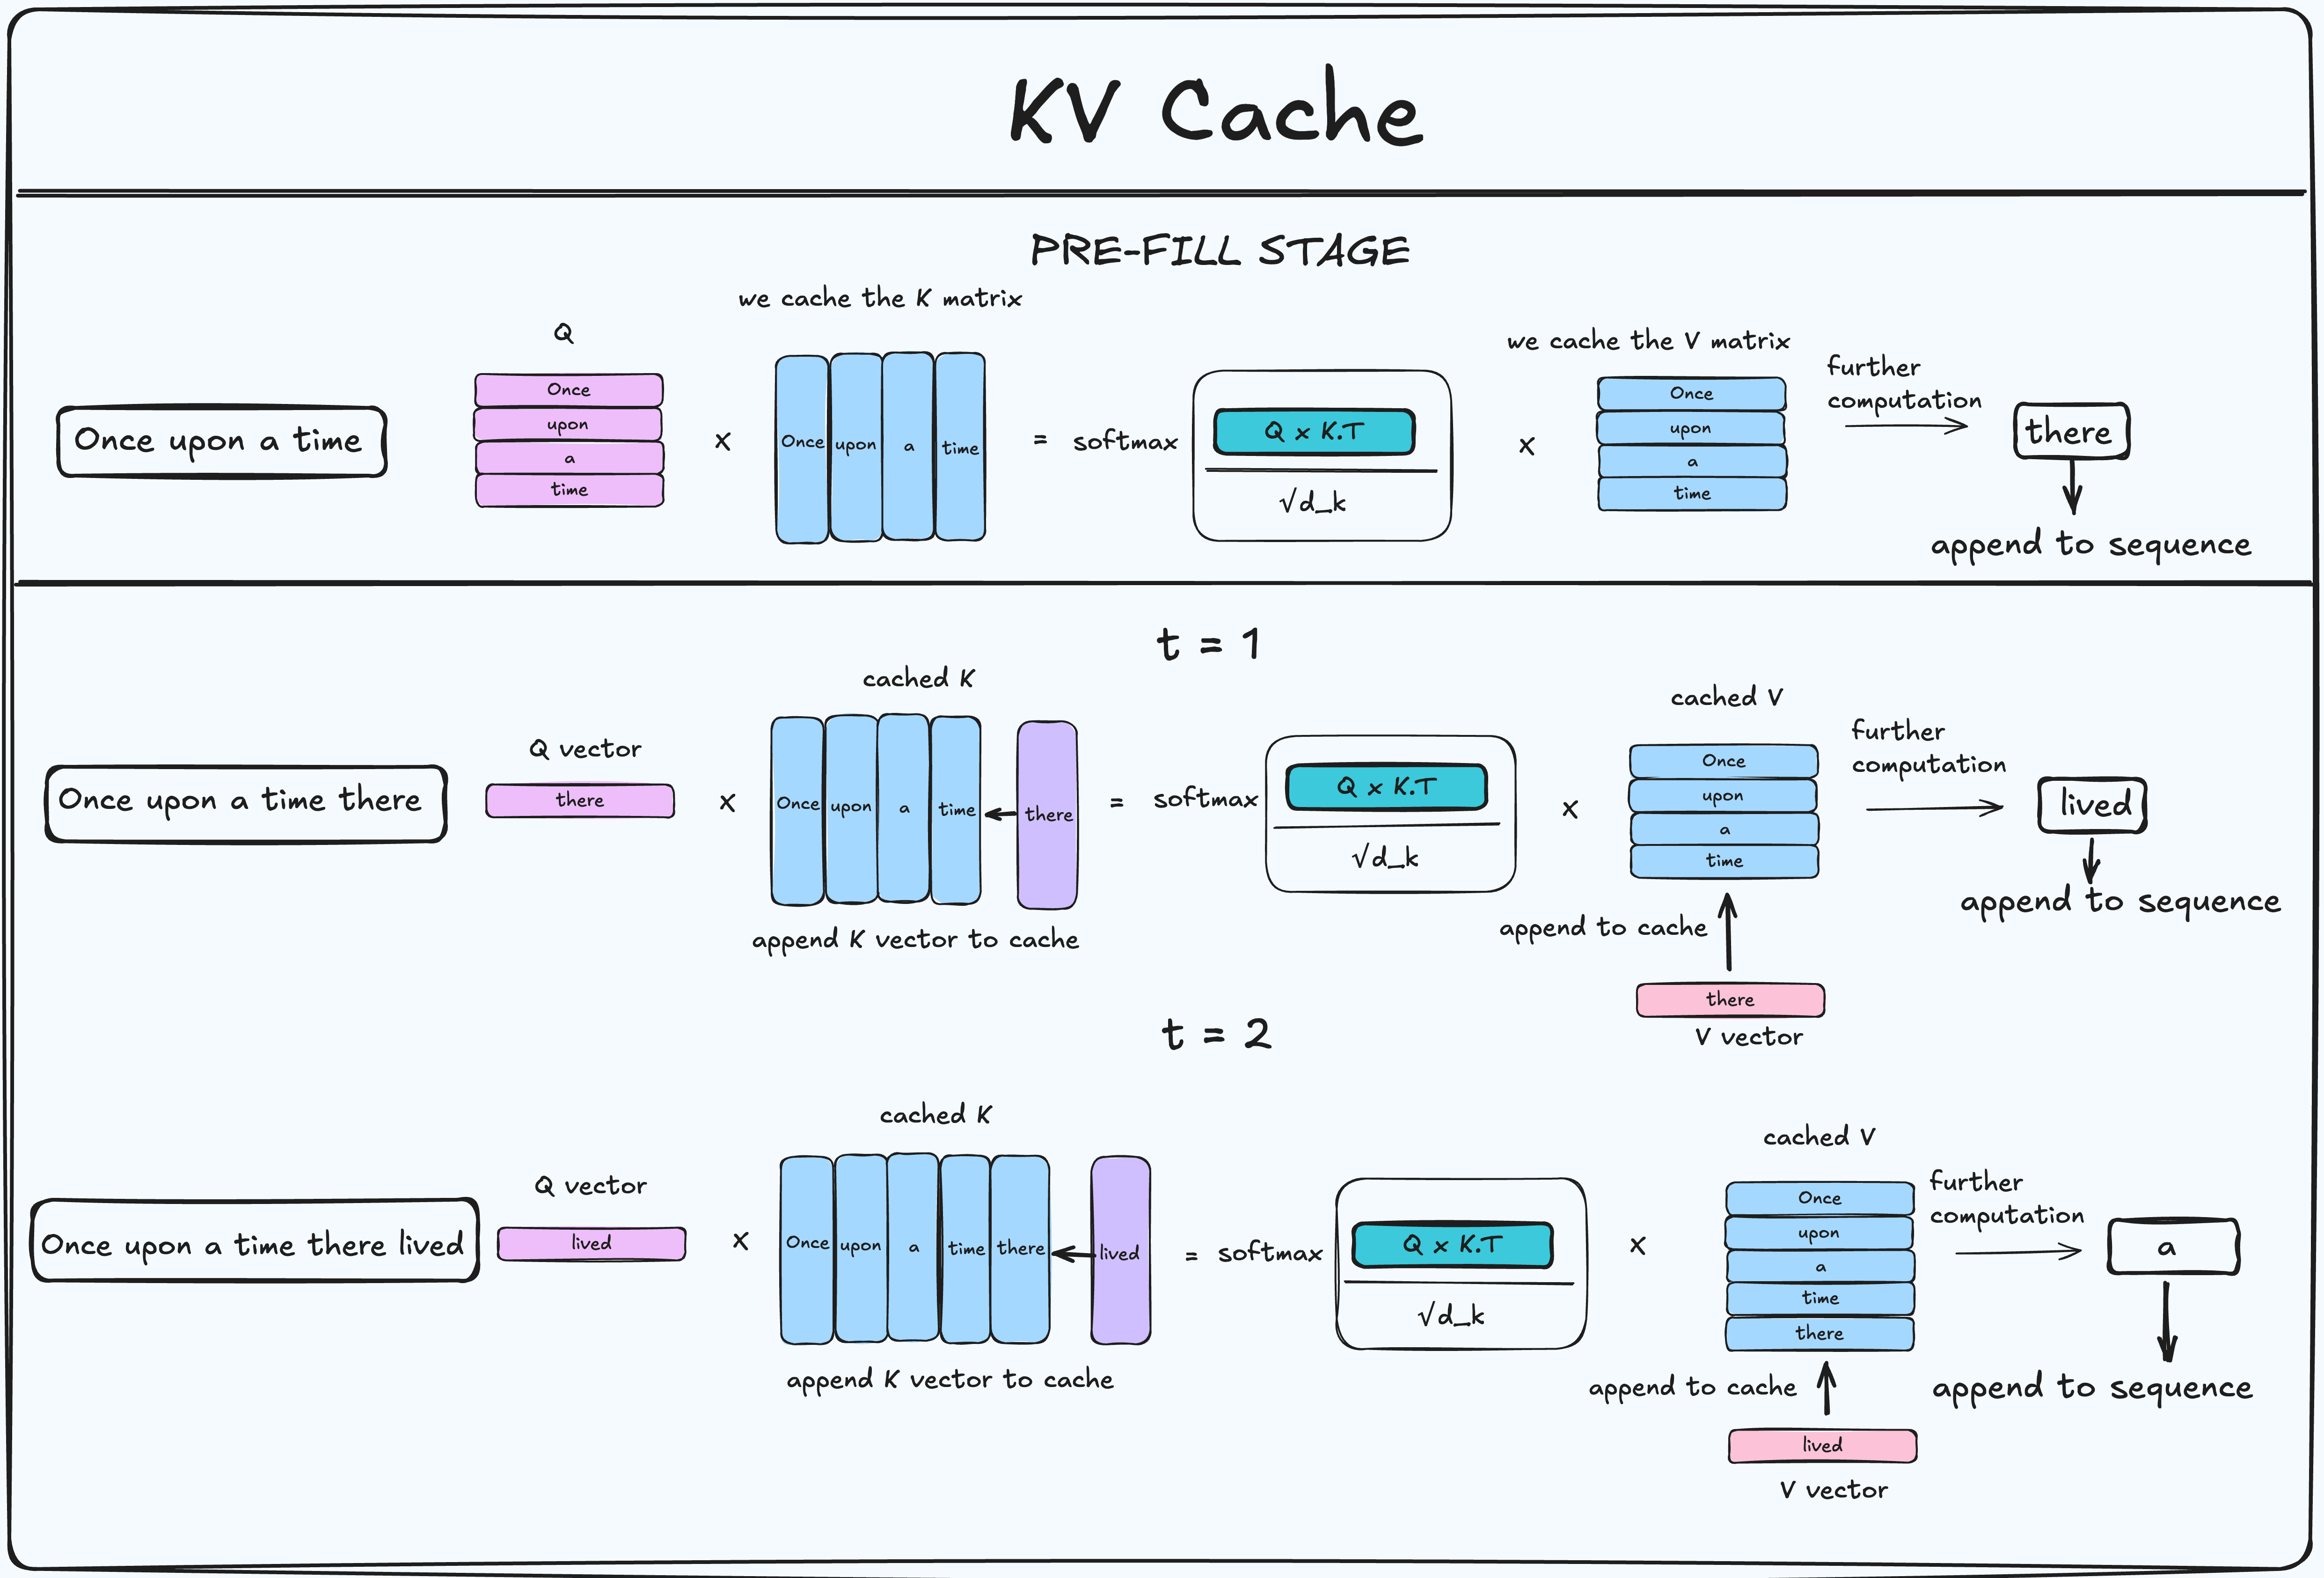
KV Cache From First Principles

KV Cache From First Principles

5x Faster Time to First Token with NVIDIA TensorRT-LLM KV Cache Early ...
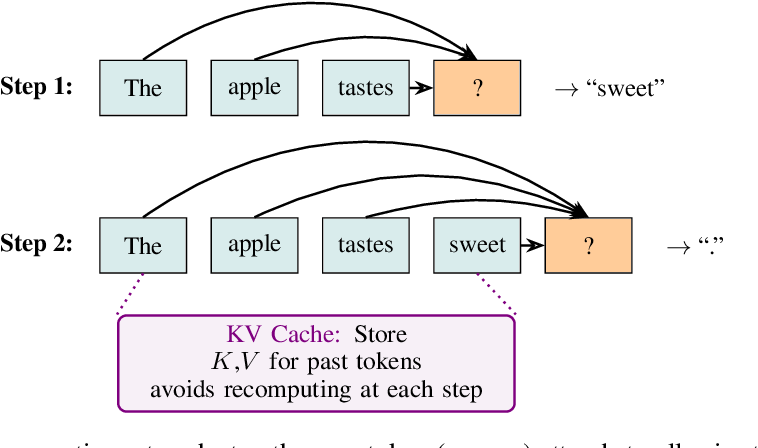
Figure 1 from KV Cache Optimization Strategies for Scalable and ...

Understanding and Coding the KV Cache in LLMs from Scratch

KV Cache and Prompt Caching: How to Leverage them to Cut Time and Costs ...

KV Cache and Prompt Caching: How to Leverage them to Cut Time and Costs ...
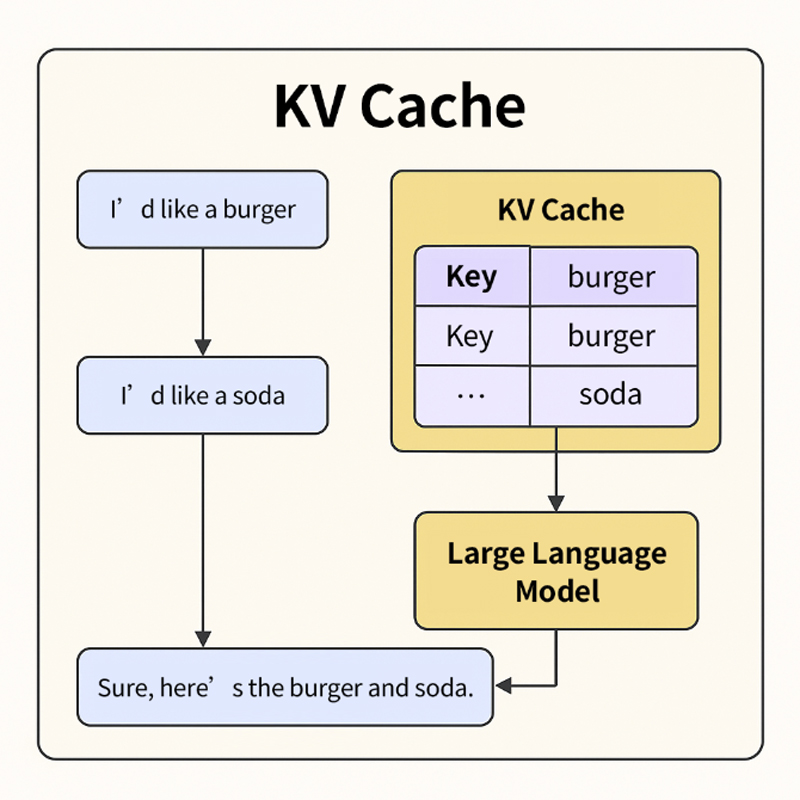
KV Cache Meets NVMe: The Key to Accelerating LLM Inference
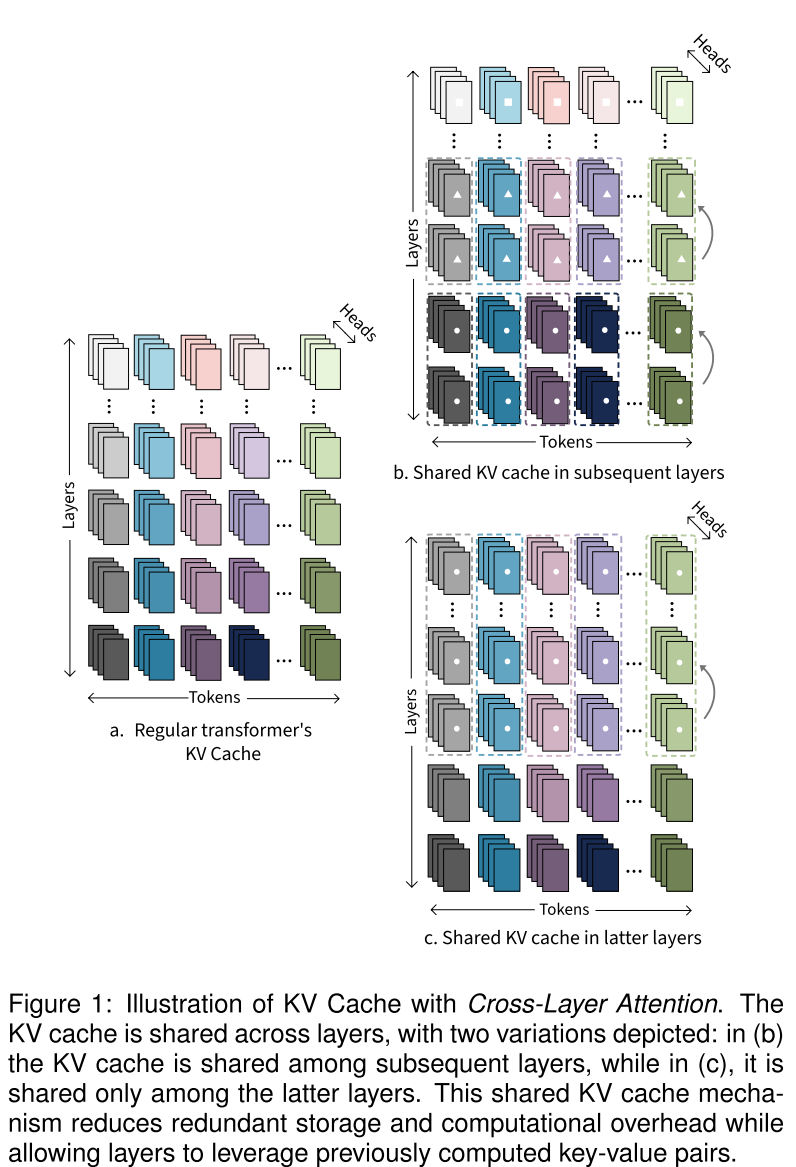
【文献阅读】Key, Value, Compress: A Systematic Exploration of KV Cache ...
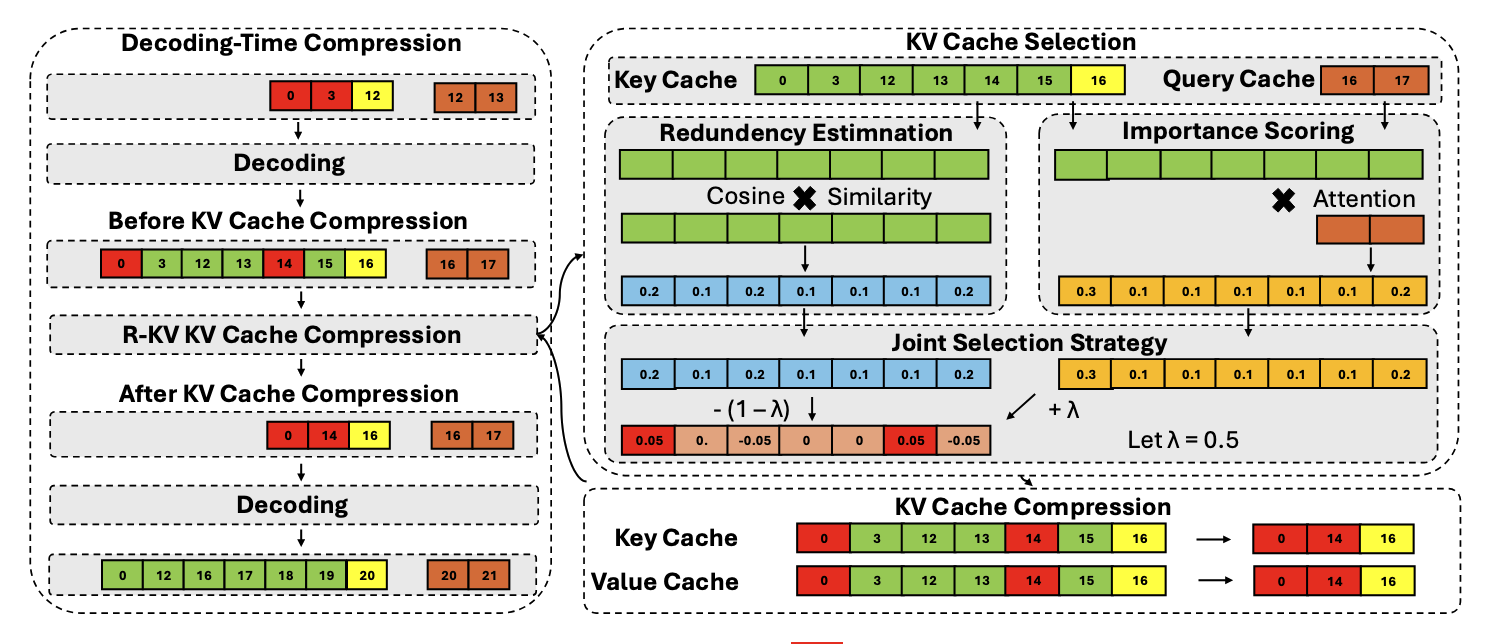
R-KV: Redundancy-aware KV Cache Compression for Reasoning Models
Advertisement Space (300x250)
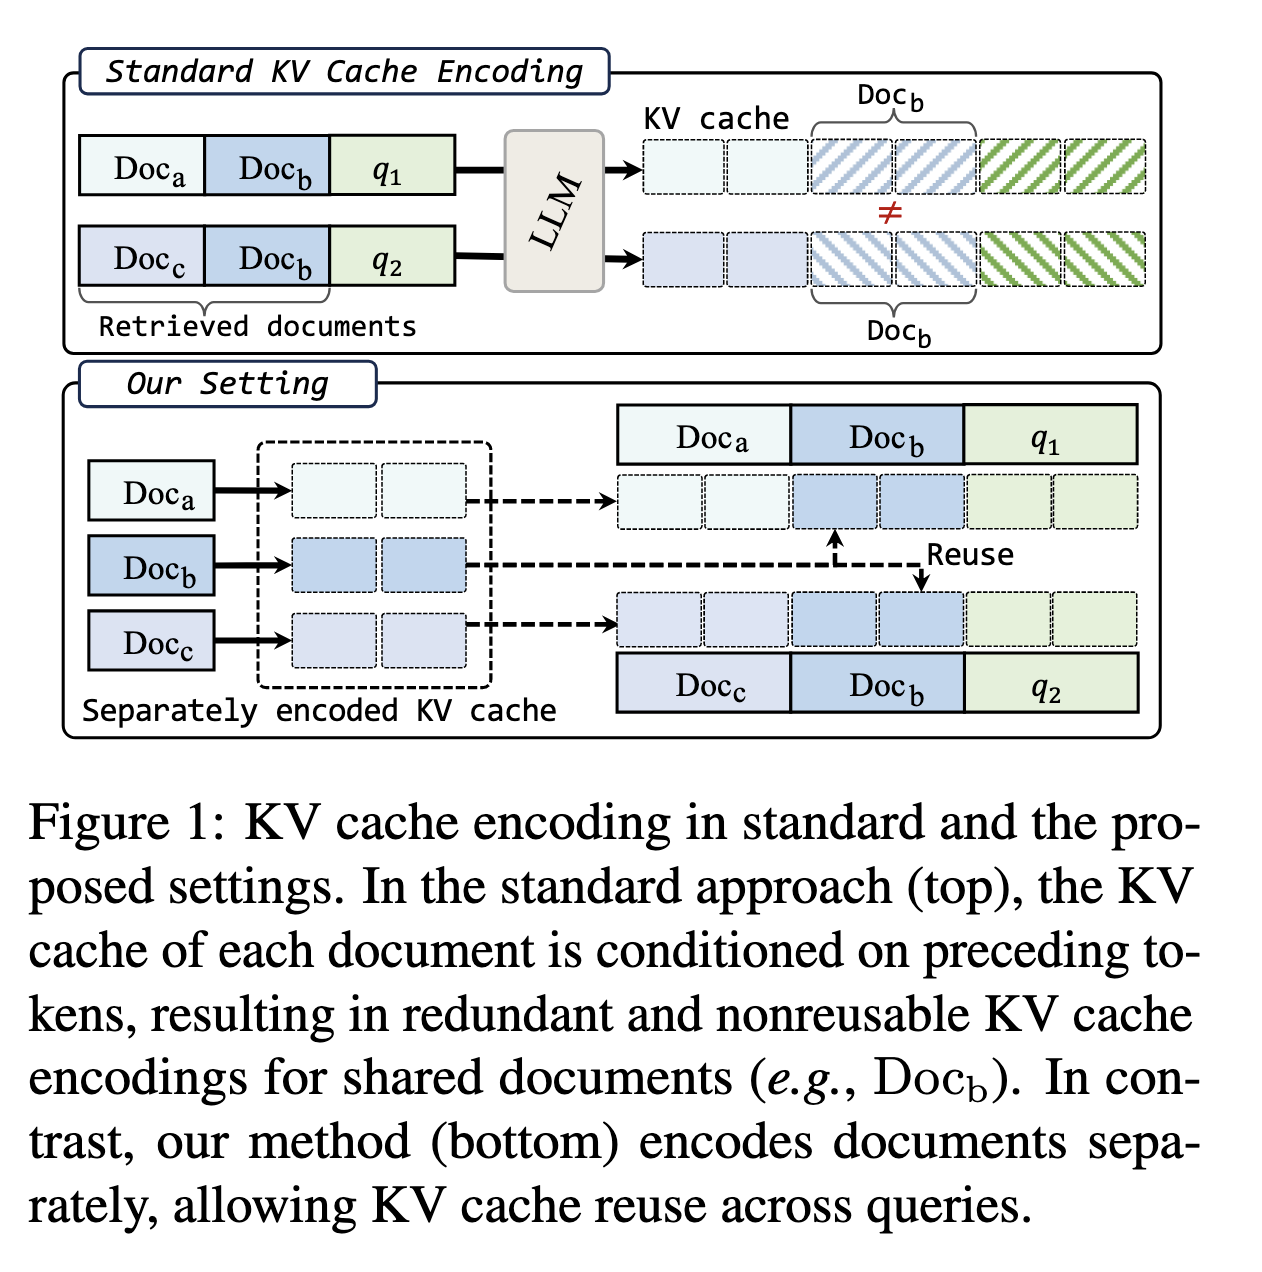
KV Cache in one passage. | Daily Jaredan
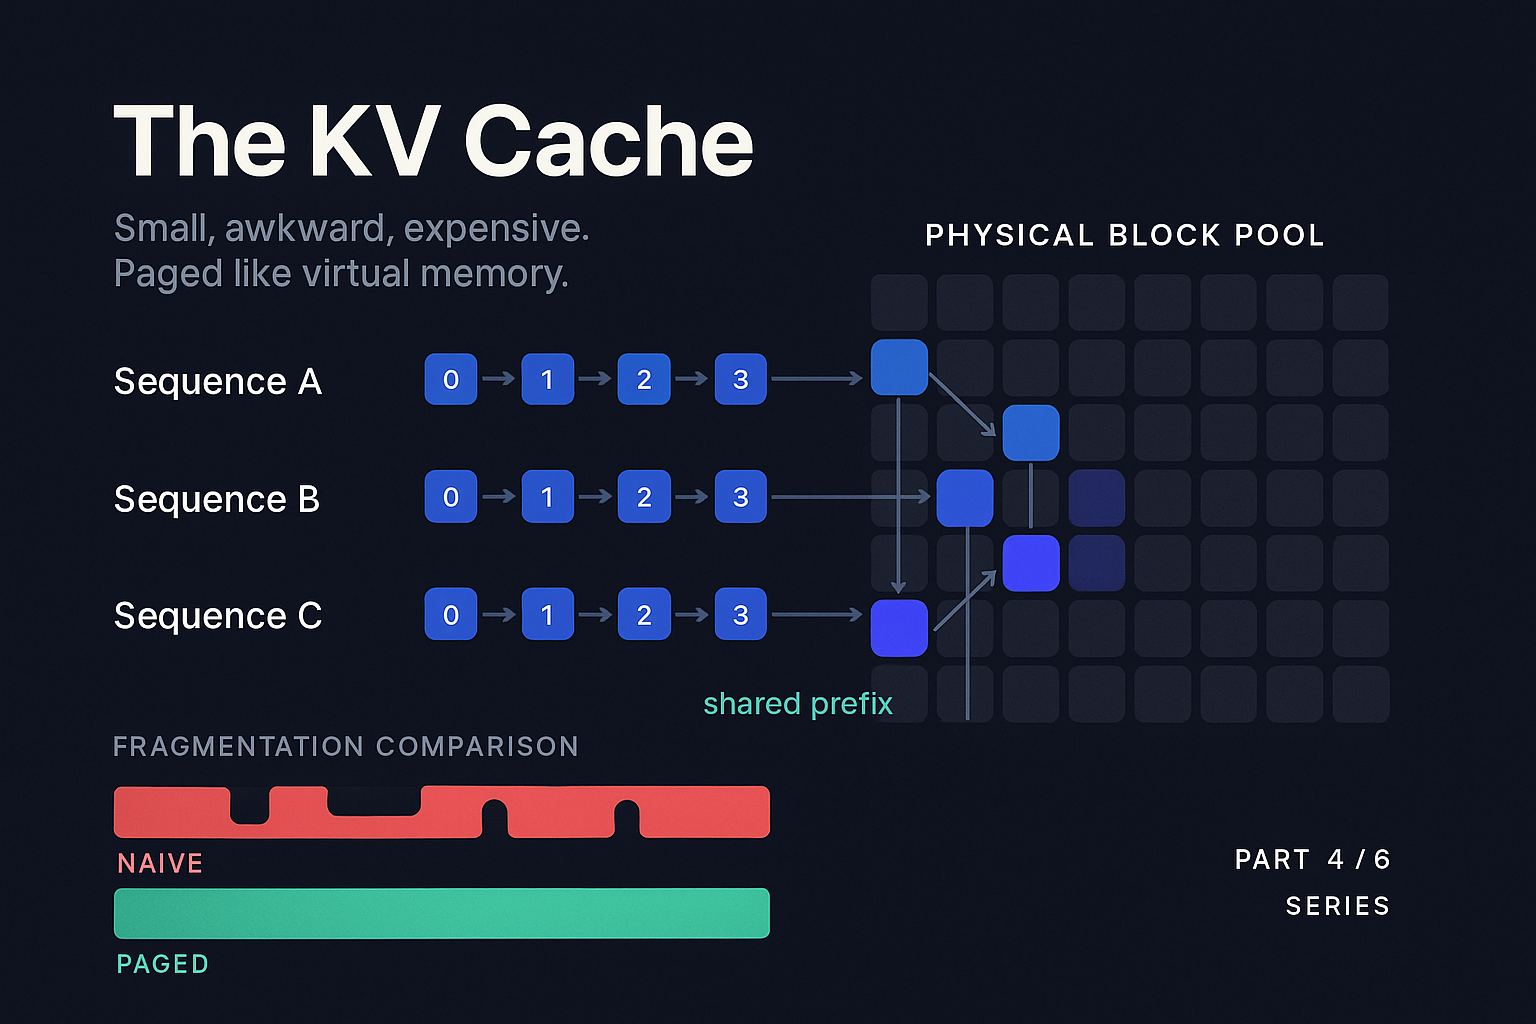
The KV Cache - Part 4 of 6 - Strongly.AI

[论文评述] KVSharer: Efficient Inference via Layer-Wise Dissimilar KV Cache ...
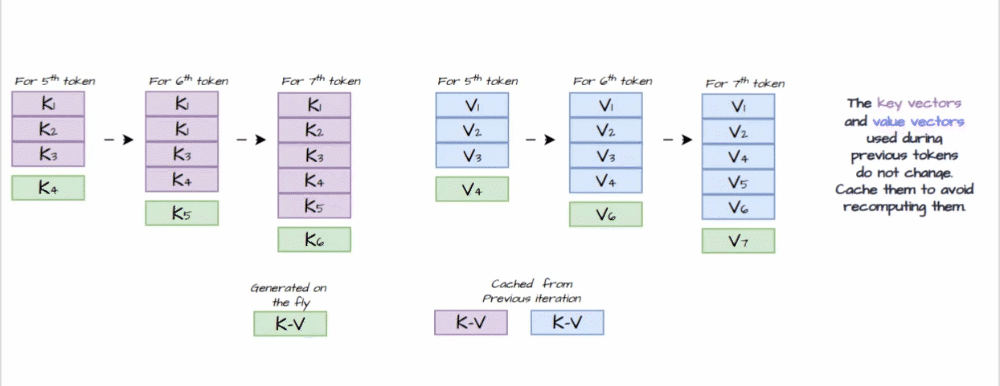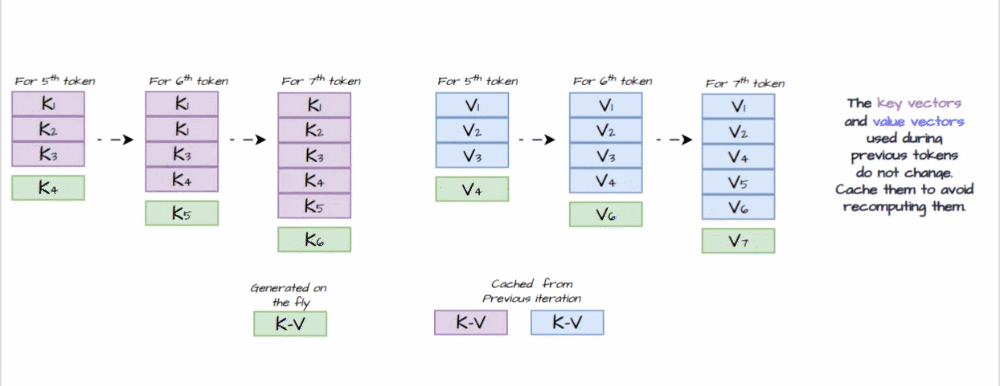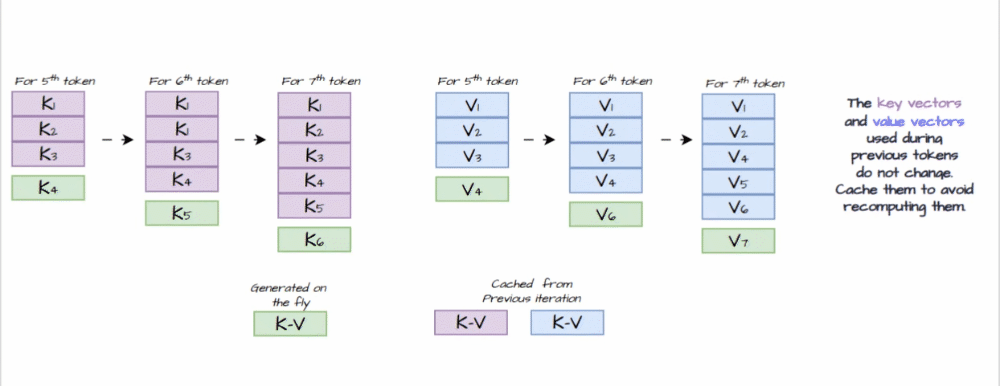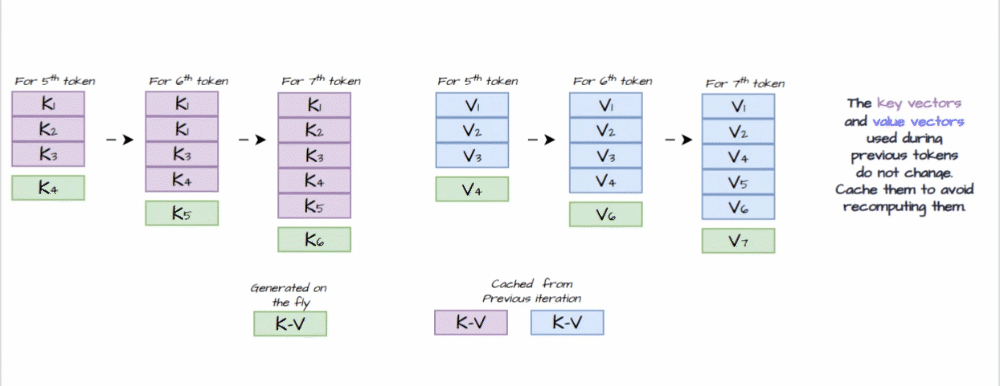
LLM 推理为什么这么快?一文搞懂 KV Cache 的原理与加速机制 - 知乎
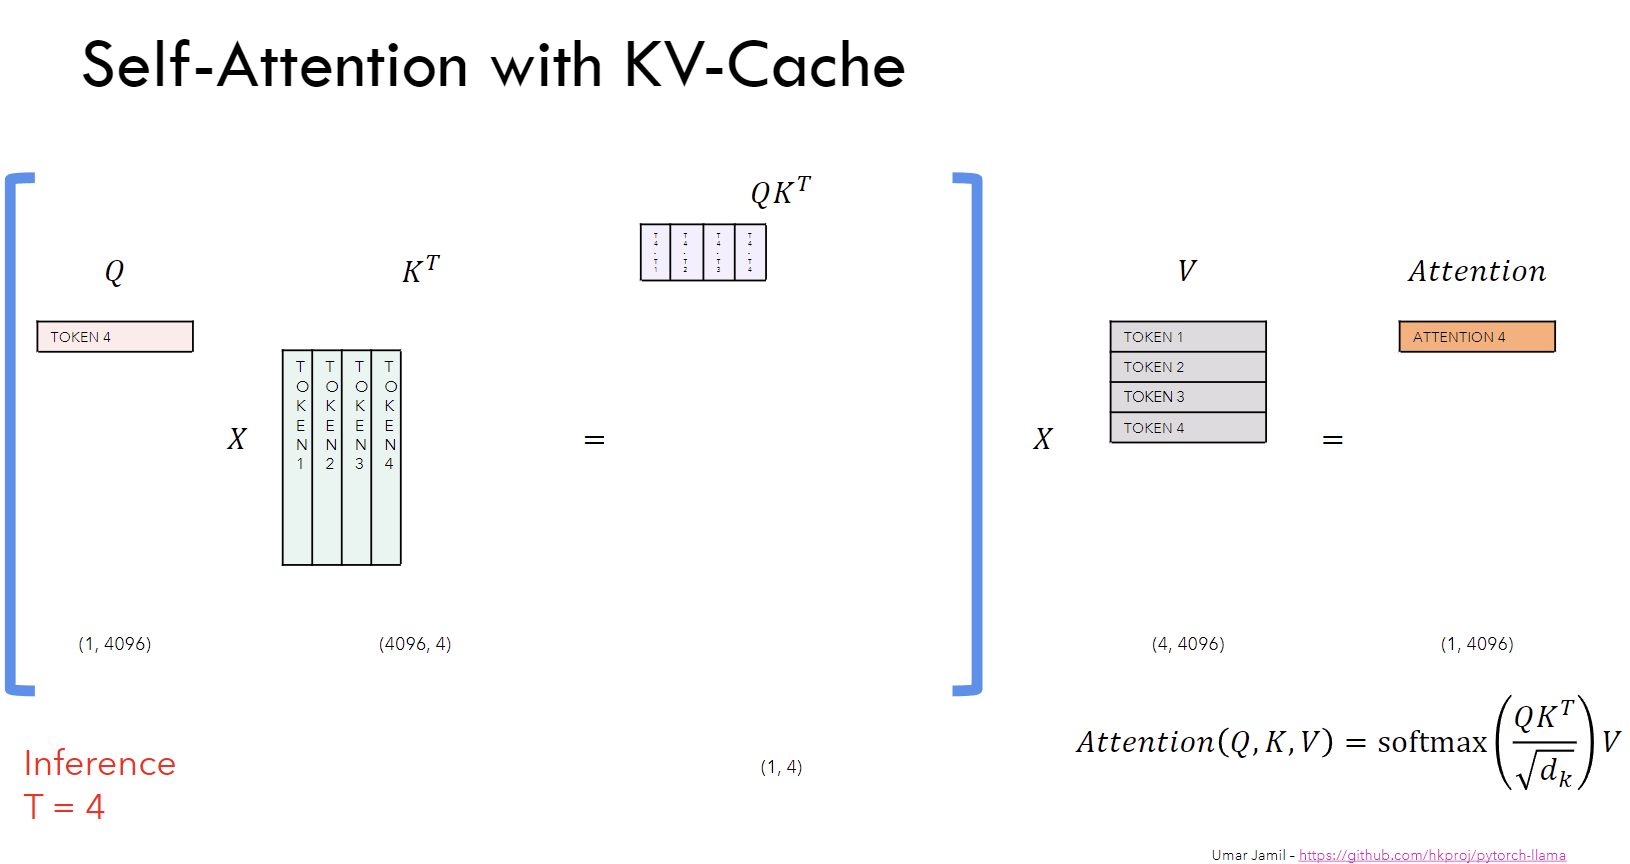
Welcome to my blog! - Understanding KV Cache
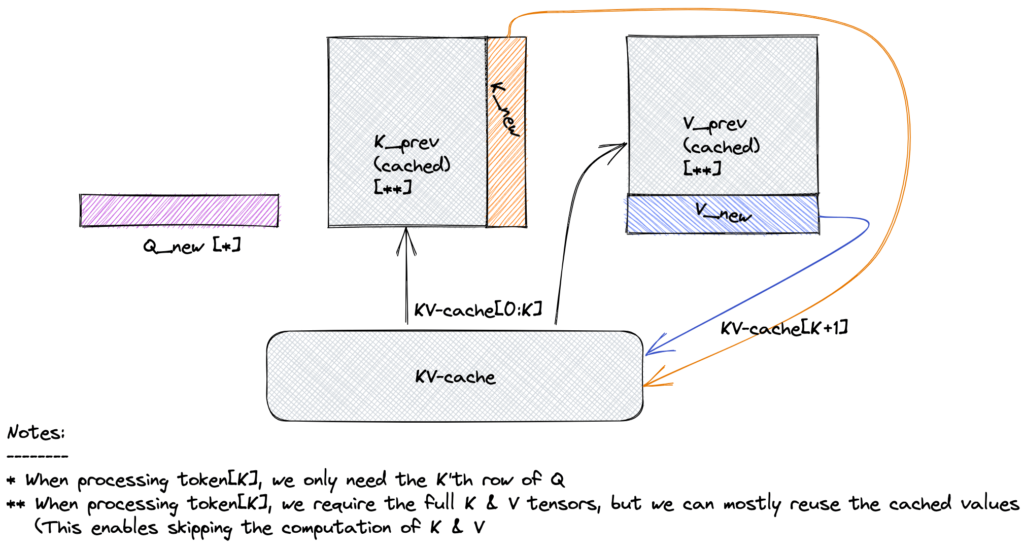
KV Cache in Transformer Models - Data Magic AI Blog

Crystal-KV: Efficient KV Cache Management for Chain-of-Thought LLMs via ...
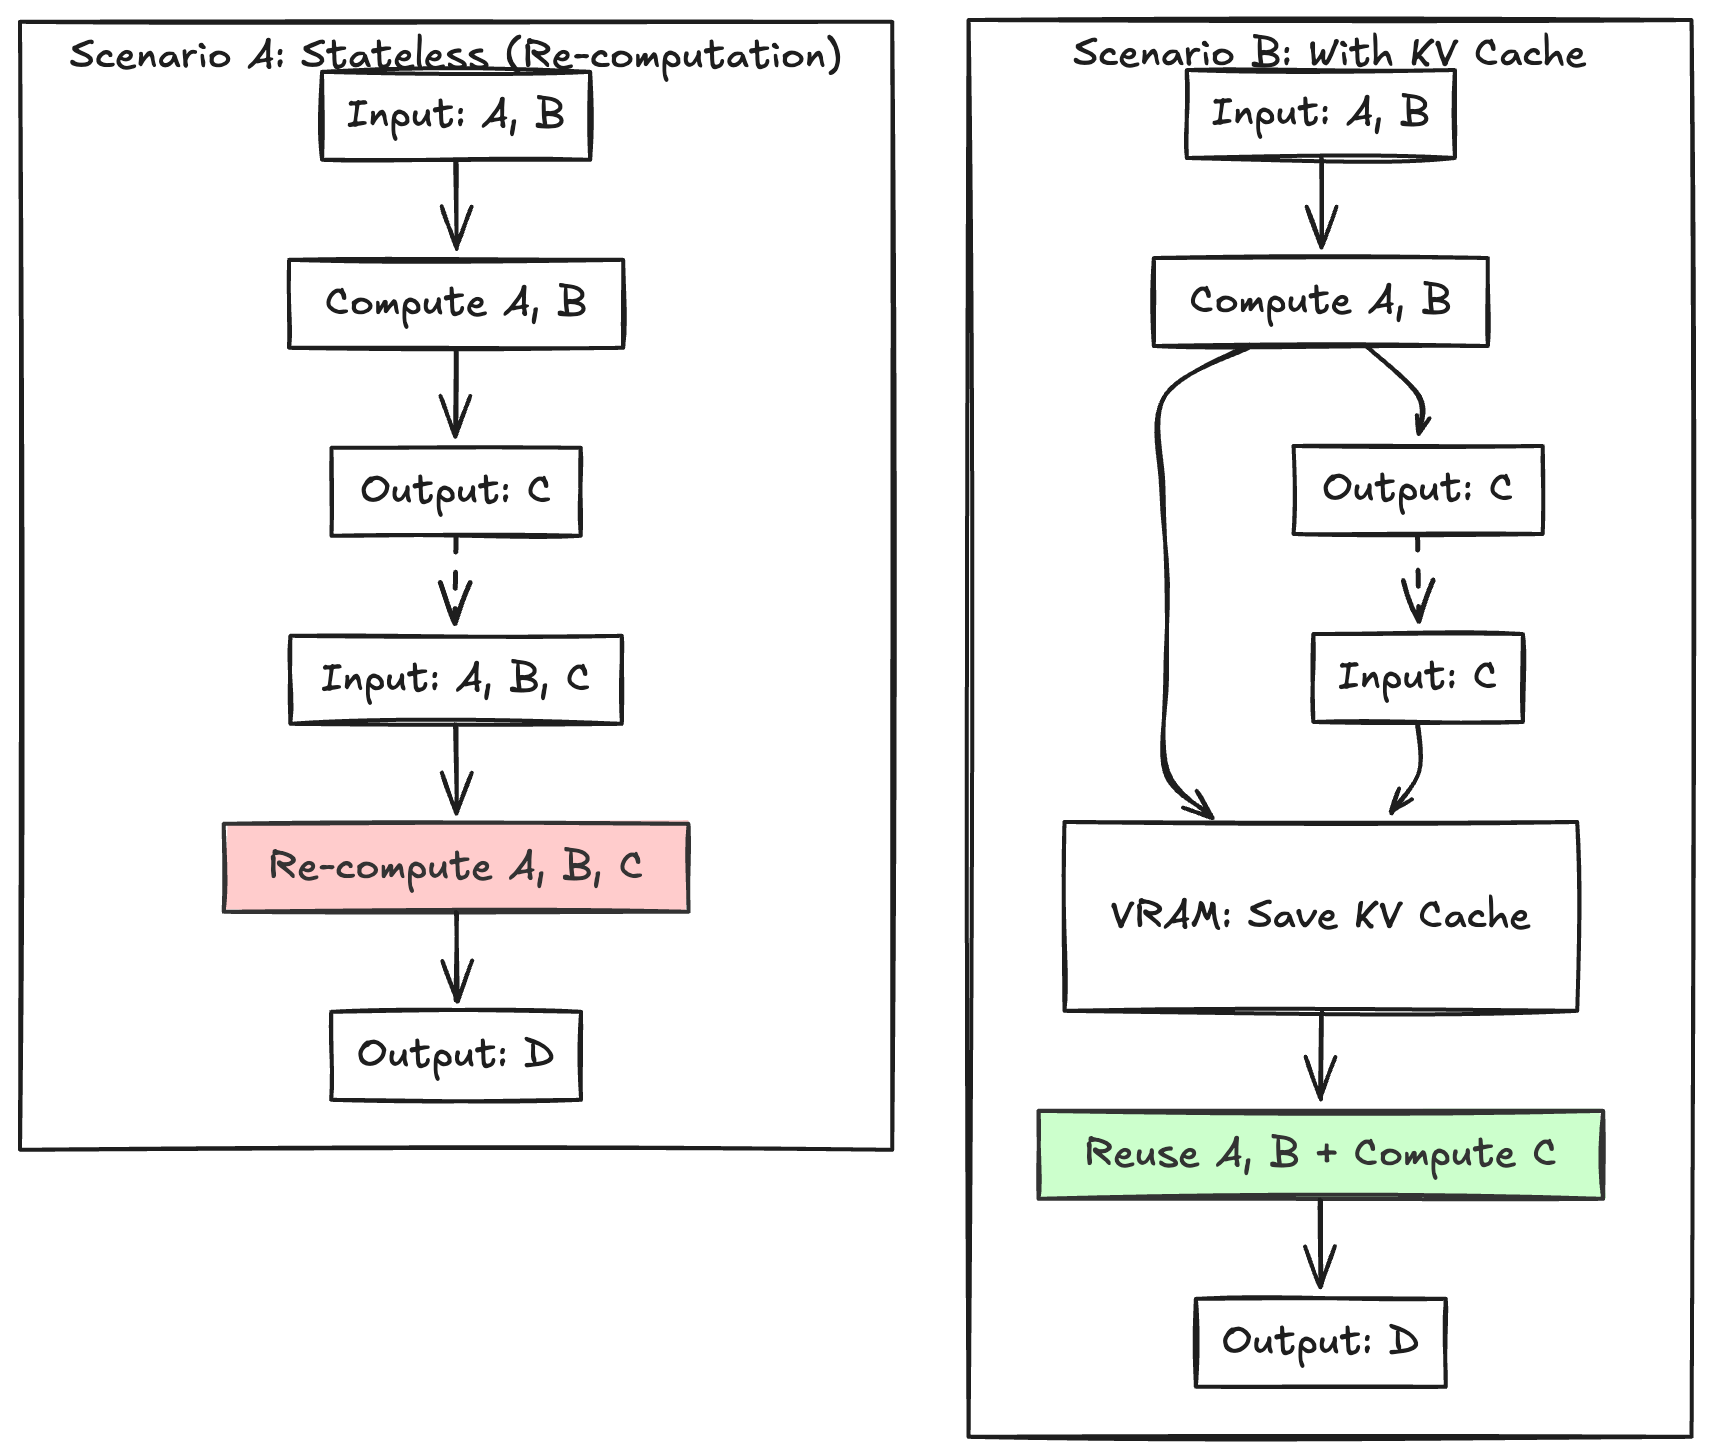
The KV Cache Dilemma: Why LLM Inference Needs to "Forget" to Scale ...
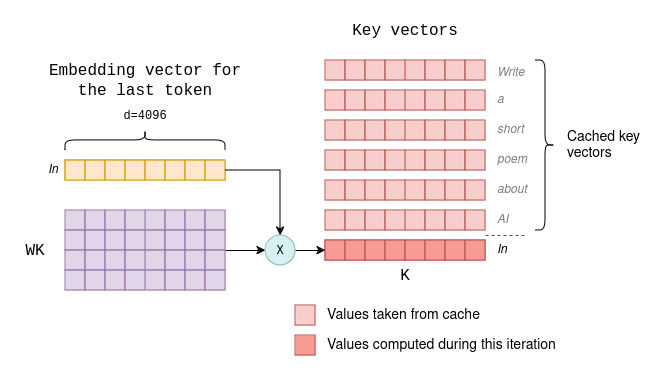
Techniques for KV Cache Optimization in Large Language Models

KV Cache Demystified: Speeding Up Large Language Models - YouTube
Advertisement Space (336x280)

LLM Jargons Explained: Part 4 - KV Cache - YouTube
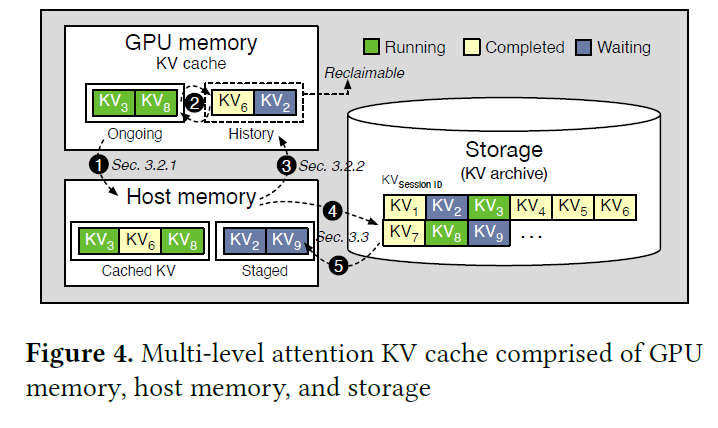
How KV Cache Works & Why It Eats Memory | by M | Foundation Models Deep ...
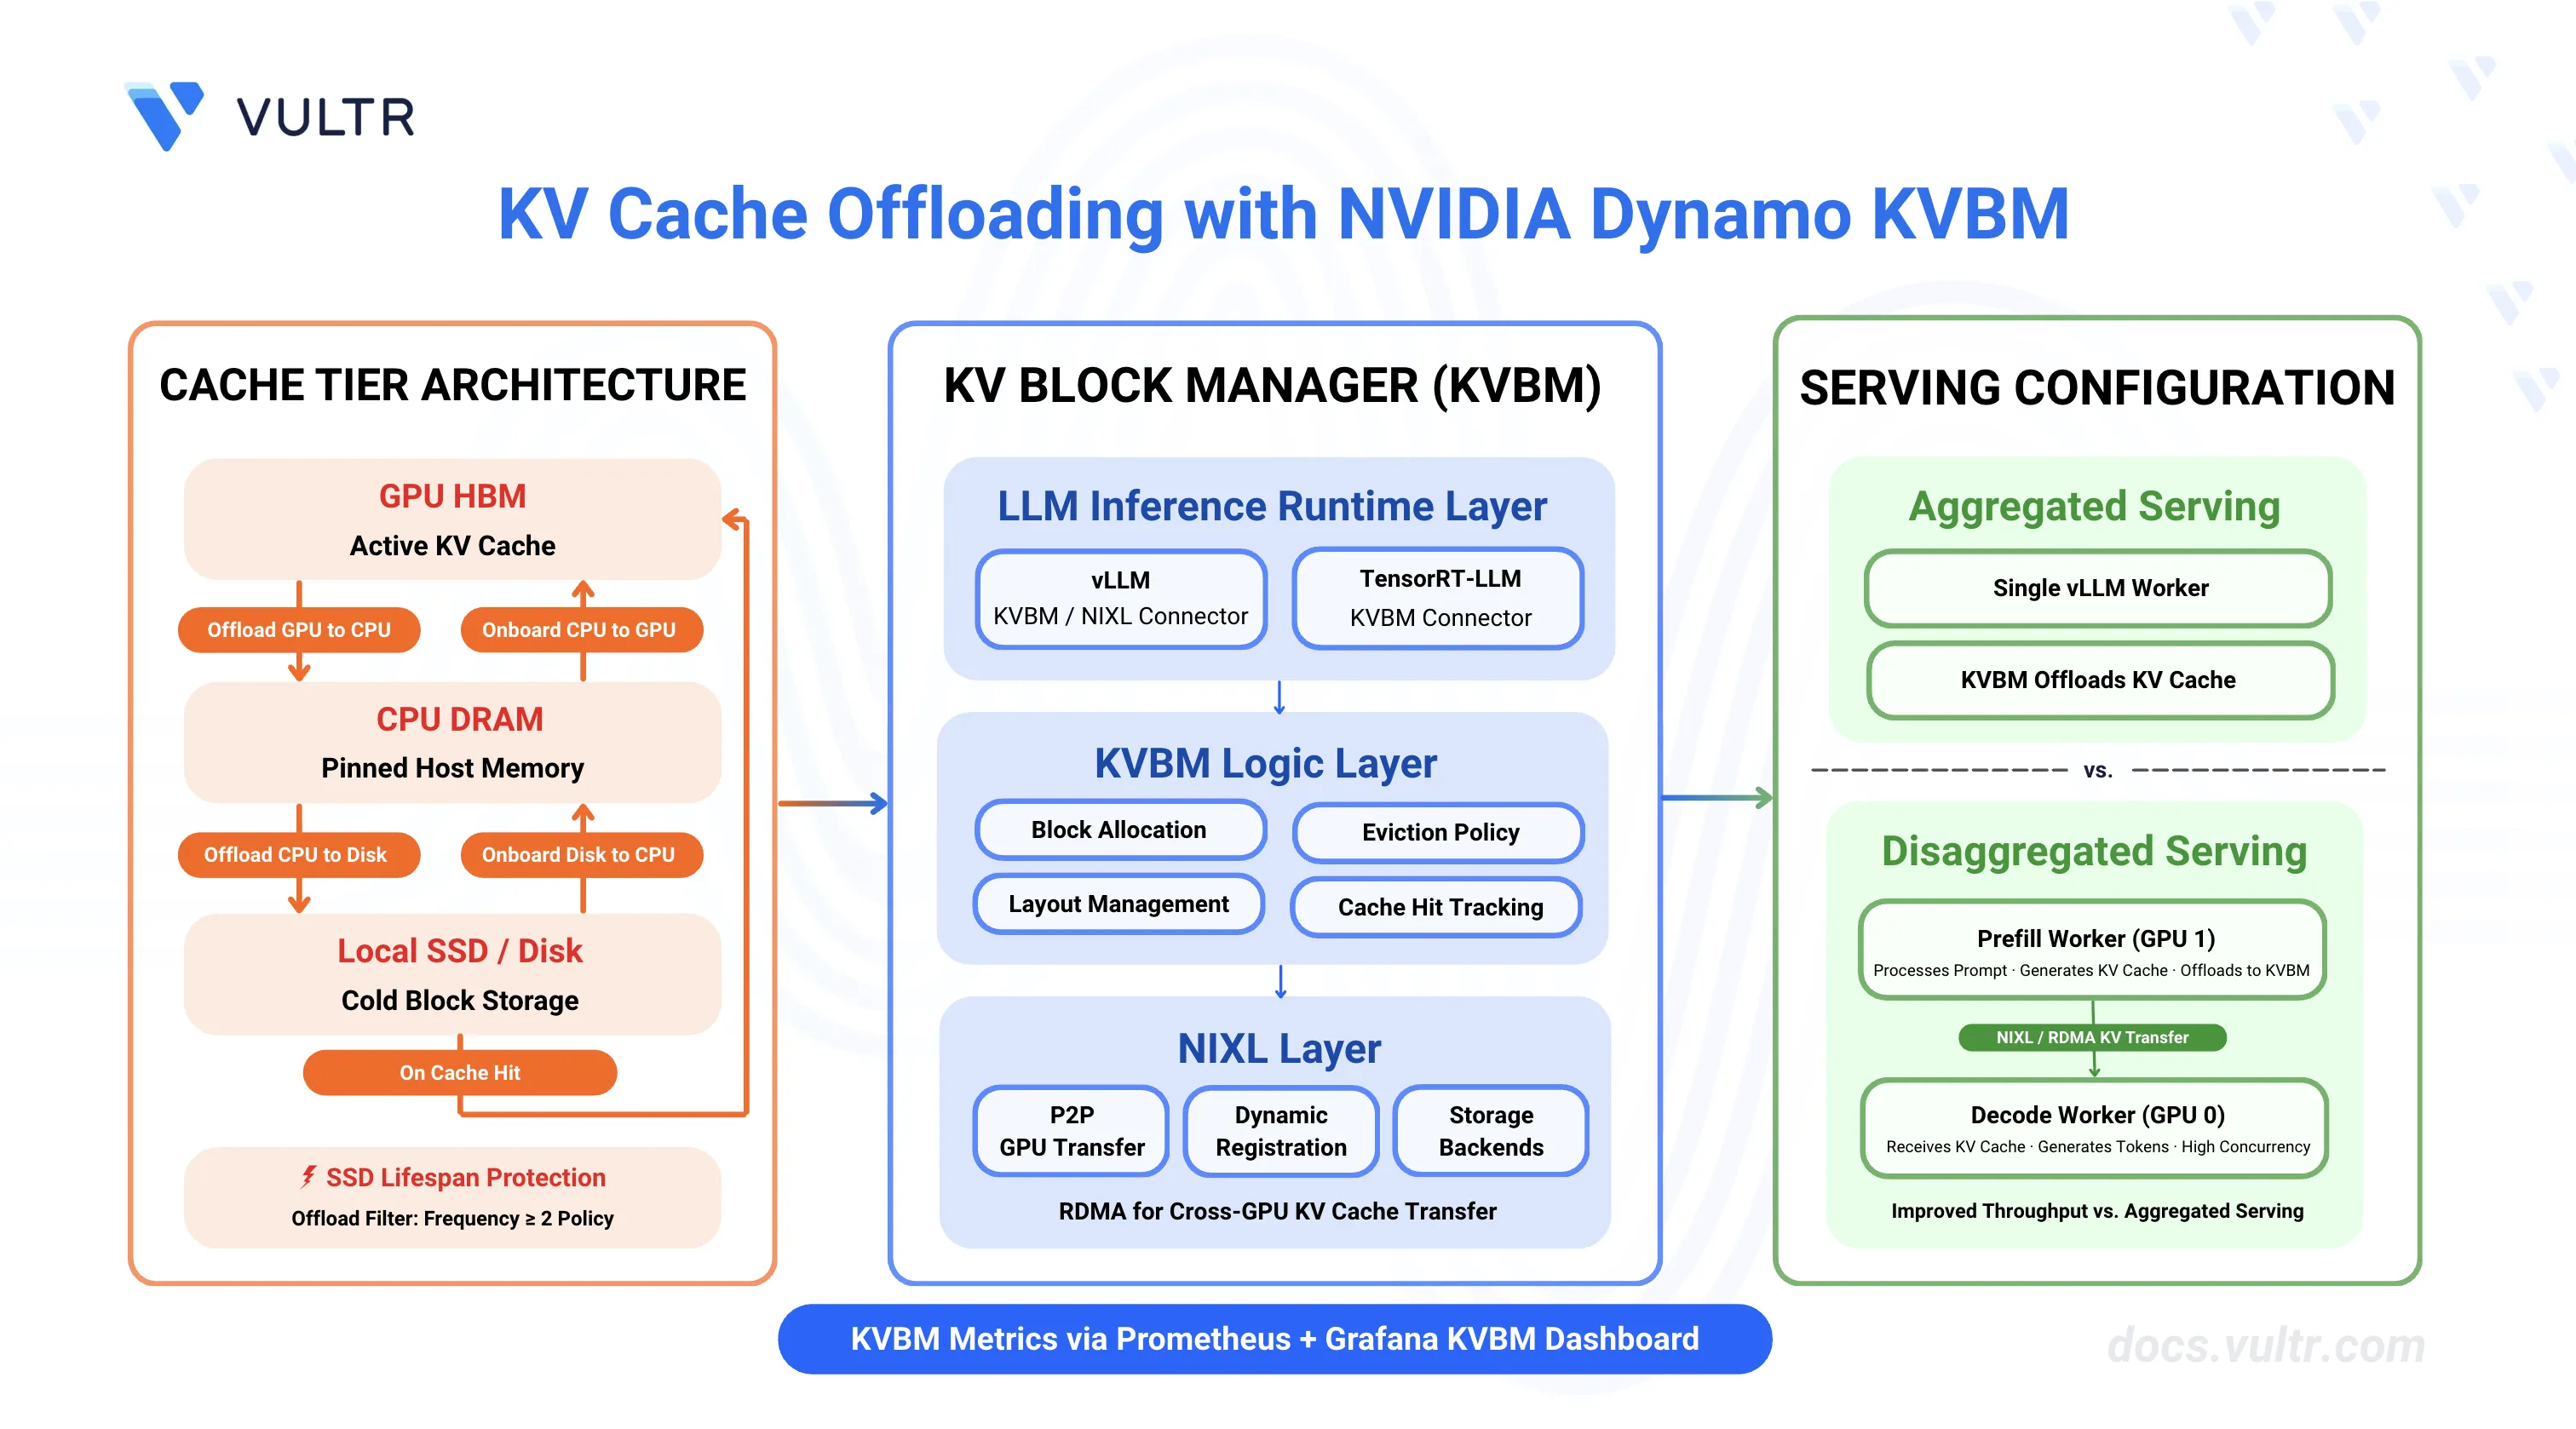
How to Manage KV Cache in NVIDIA Dynamo | Vultr Docs
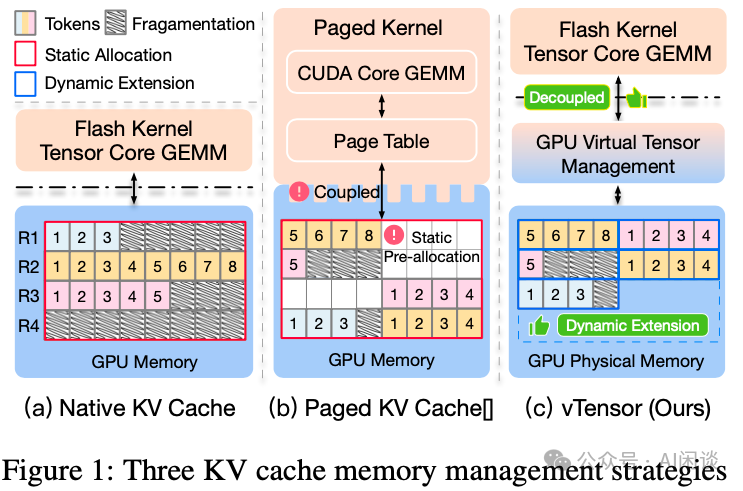
LLM 推理的 Attention 计算和 KV Cache 优化:PagedAttention、vAttention 等_paged ...
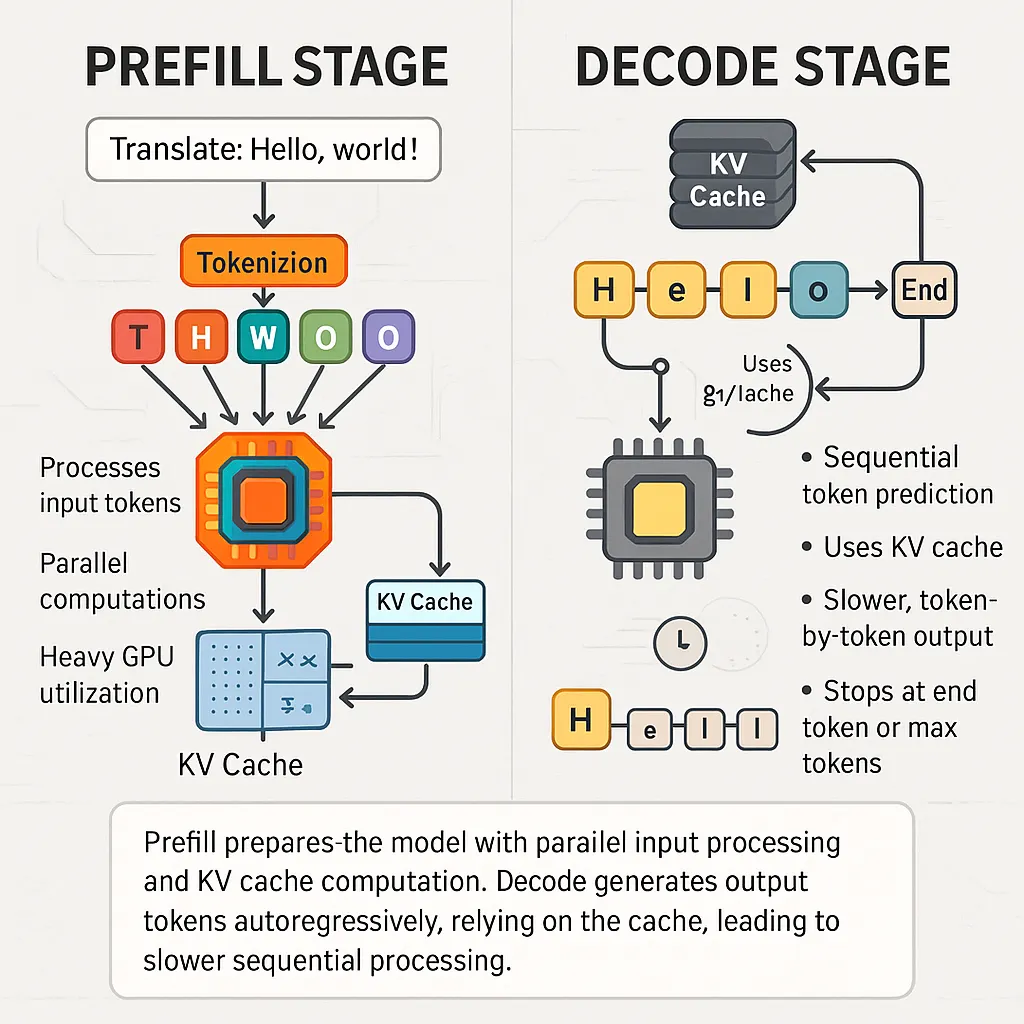
How KV Cache Works & Why It Eats Memory | by M | Foundation Models Deep ...
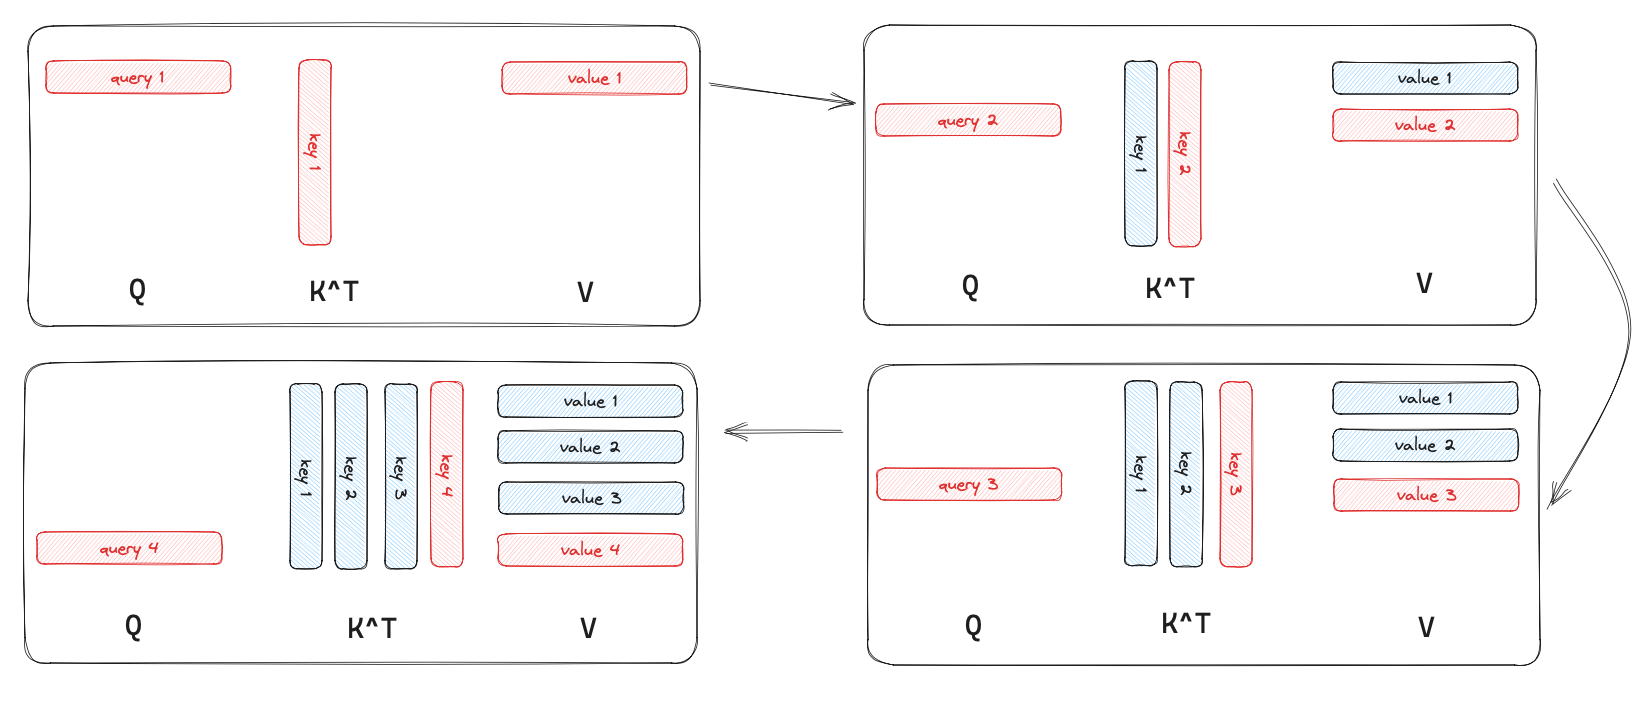
LLM inference optimization (1): KV Cache - MartinLwx's Blog
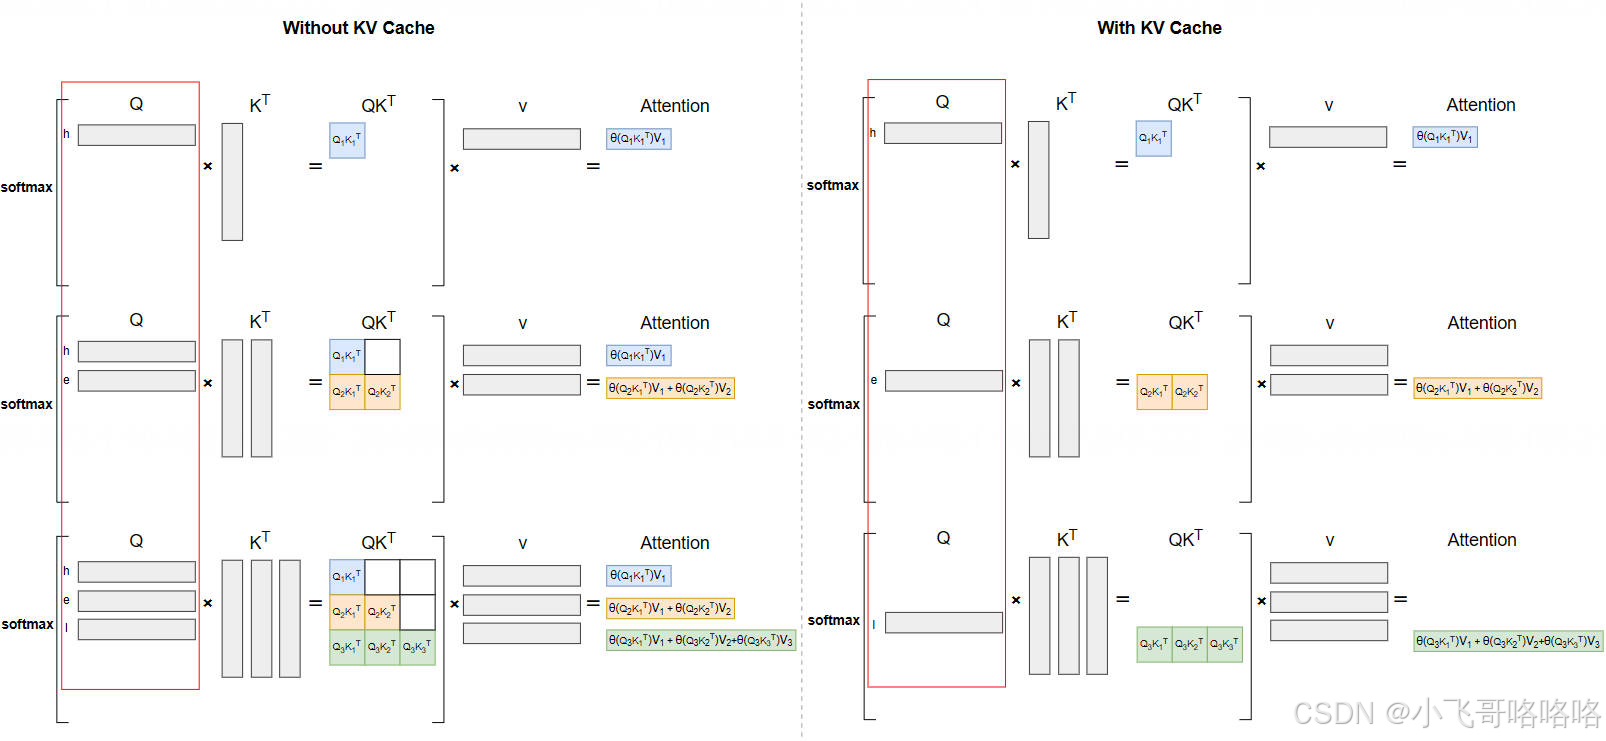
KV Cache - 技术栈
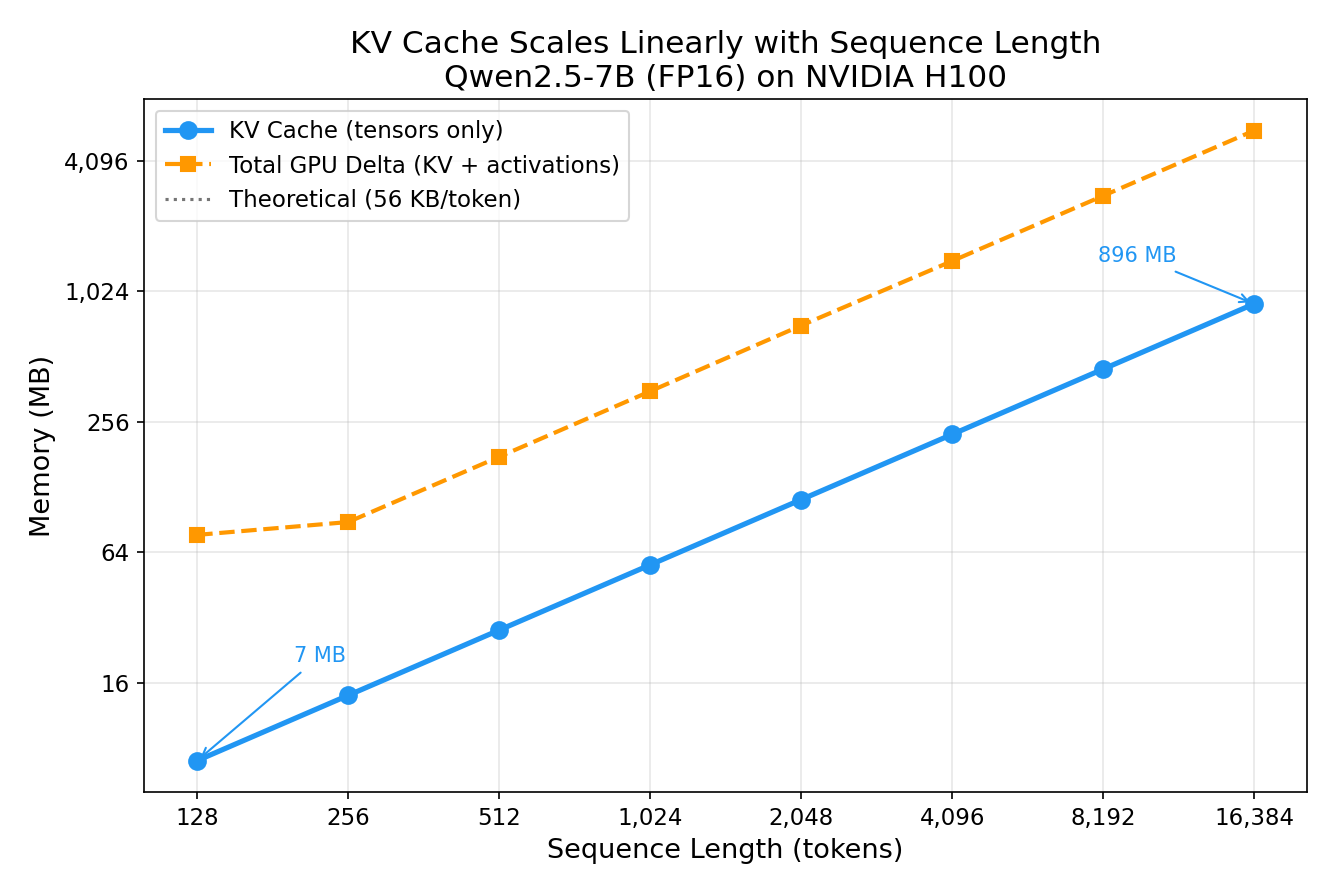
Understanding KV Cache in LLM Inference - Jingchao’s Website

TokenDance: Scaling Multi-Agent LLM Serving via Collective KV Cache Sharing
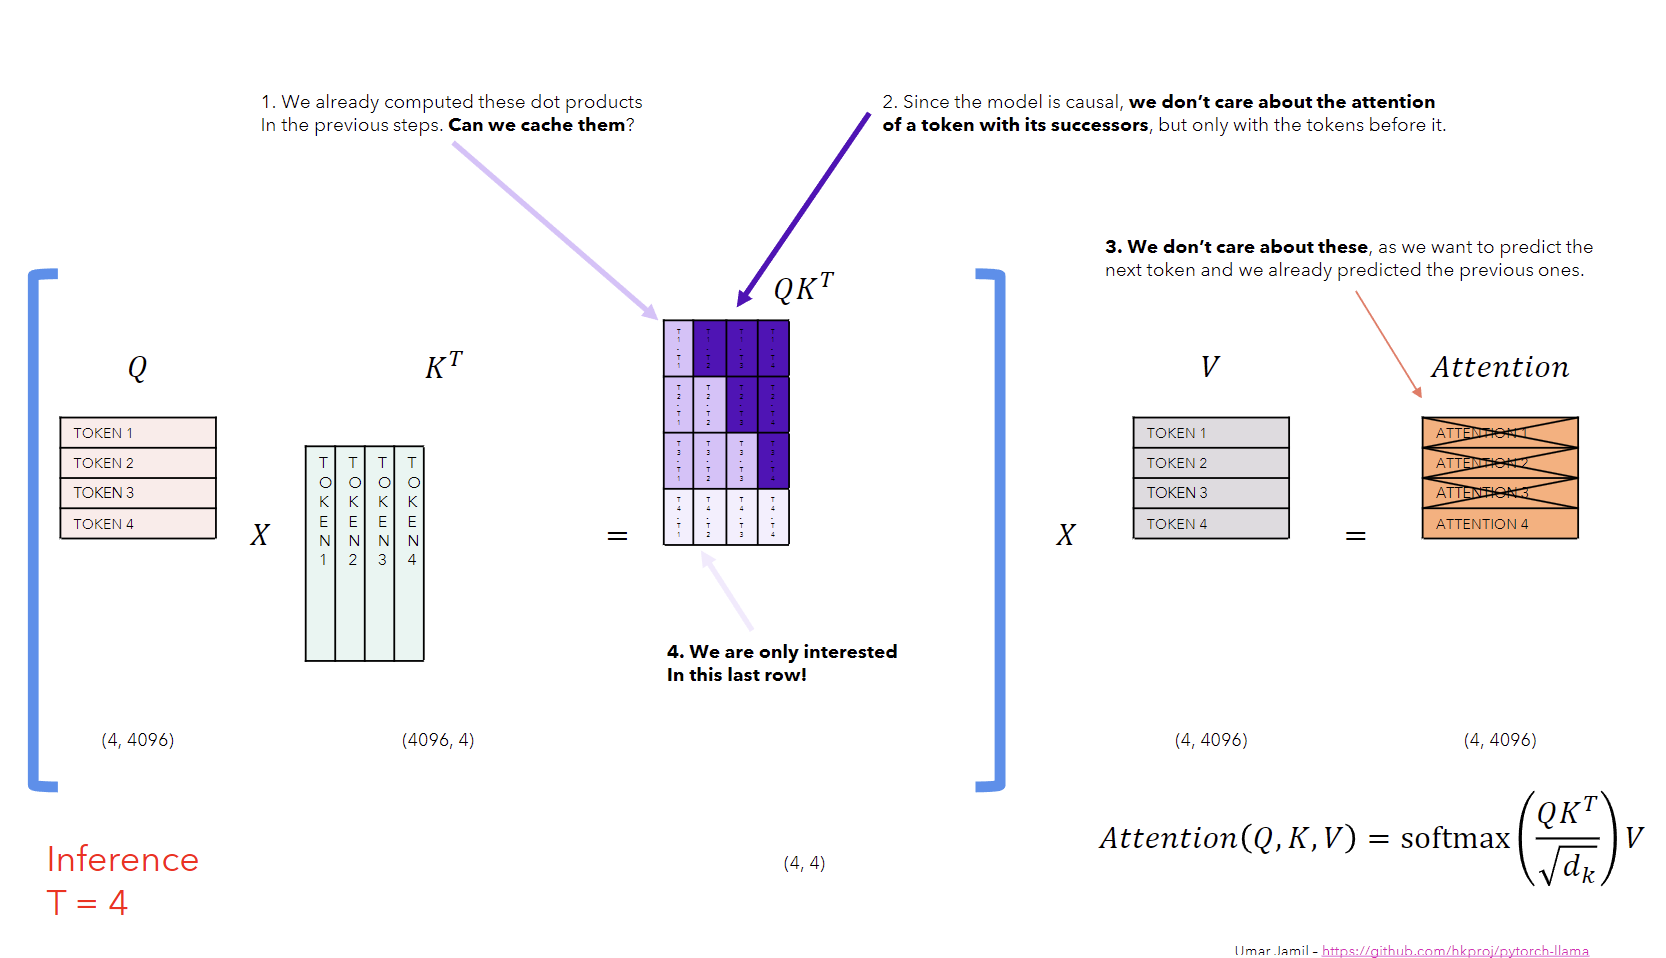
Welcome to my blog! - Understanding KV Cache
Advertisement Space (336x280)
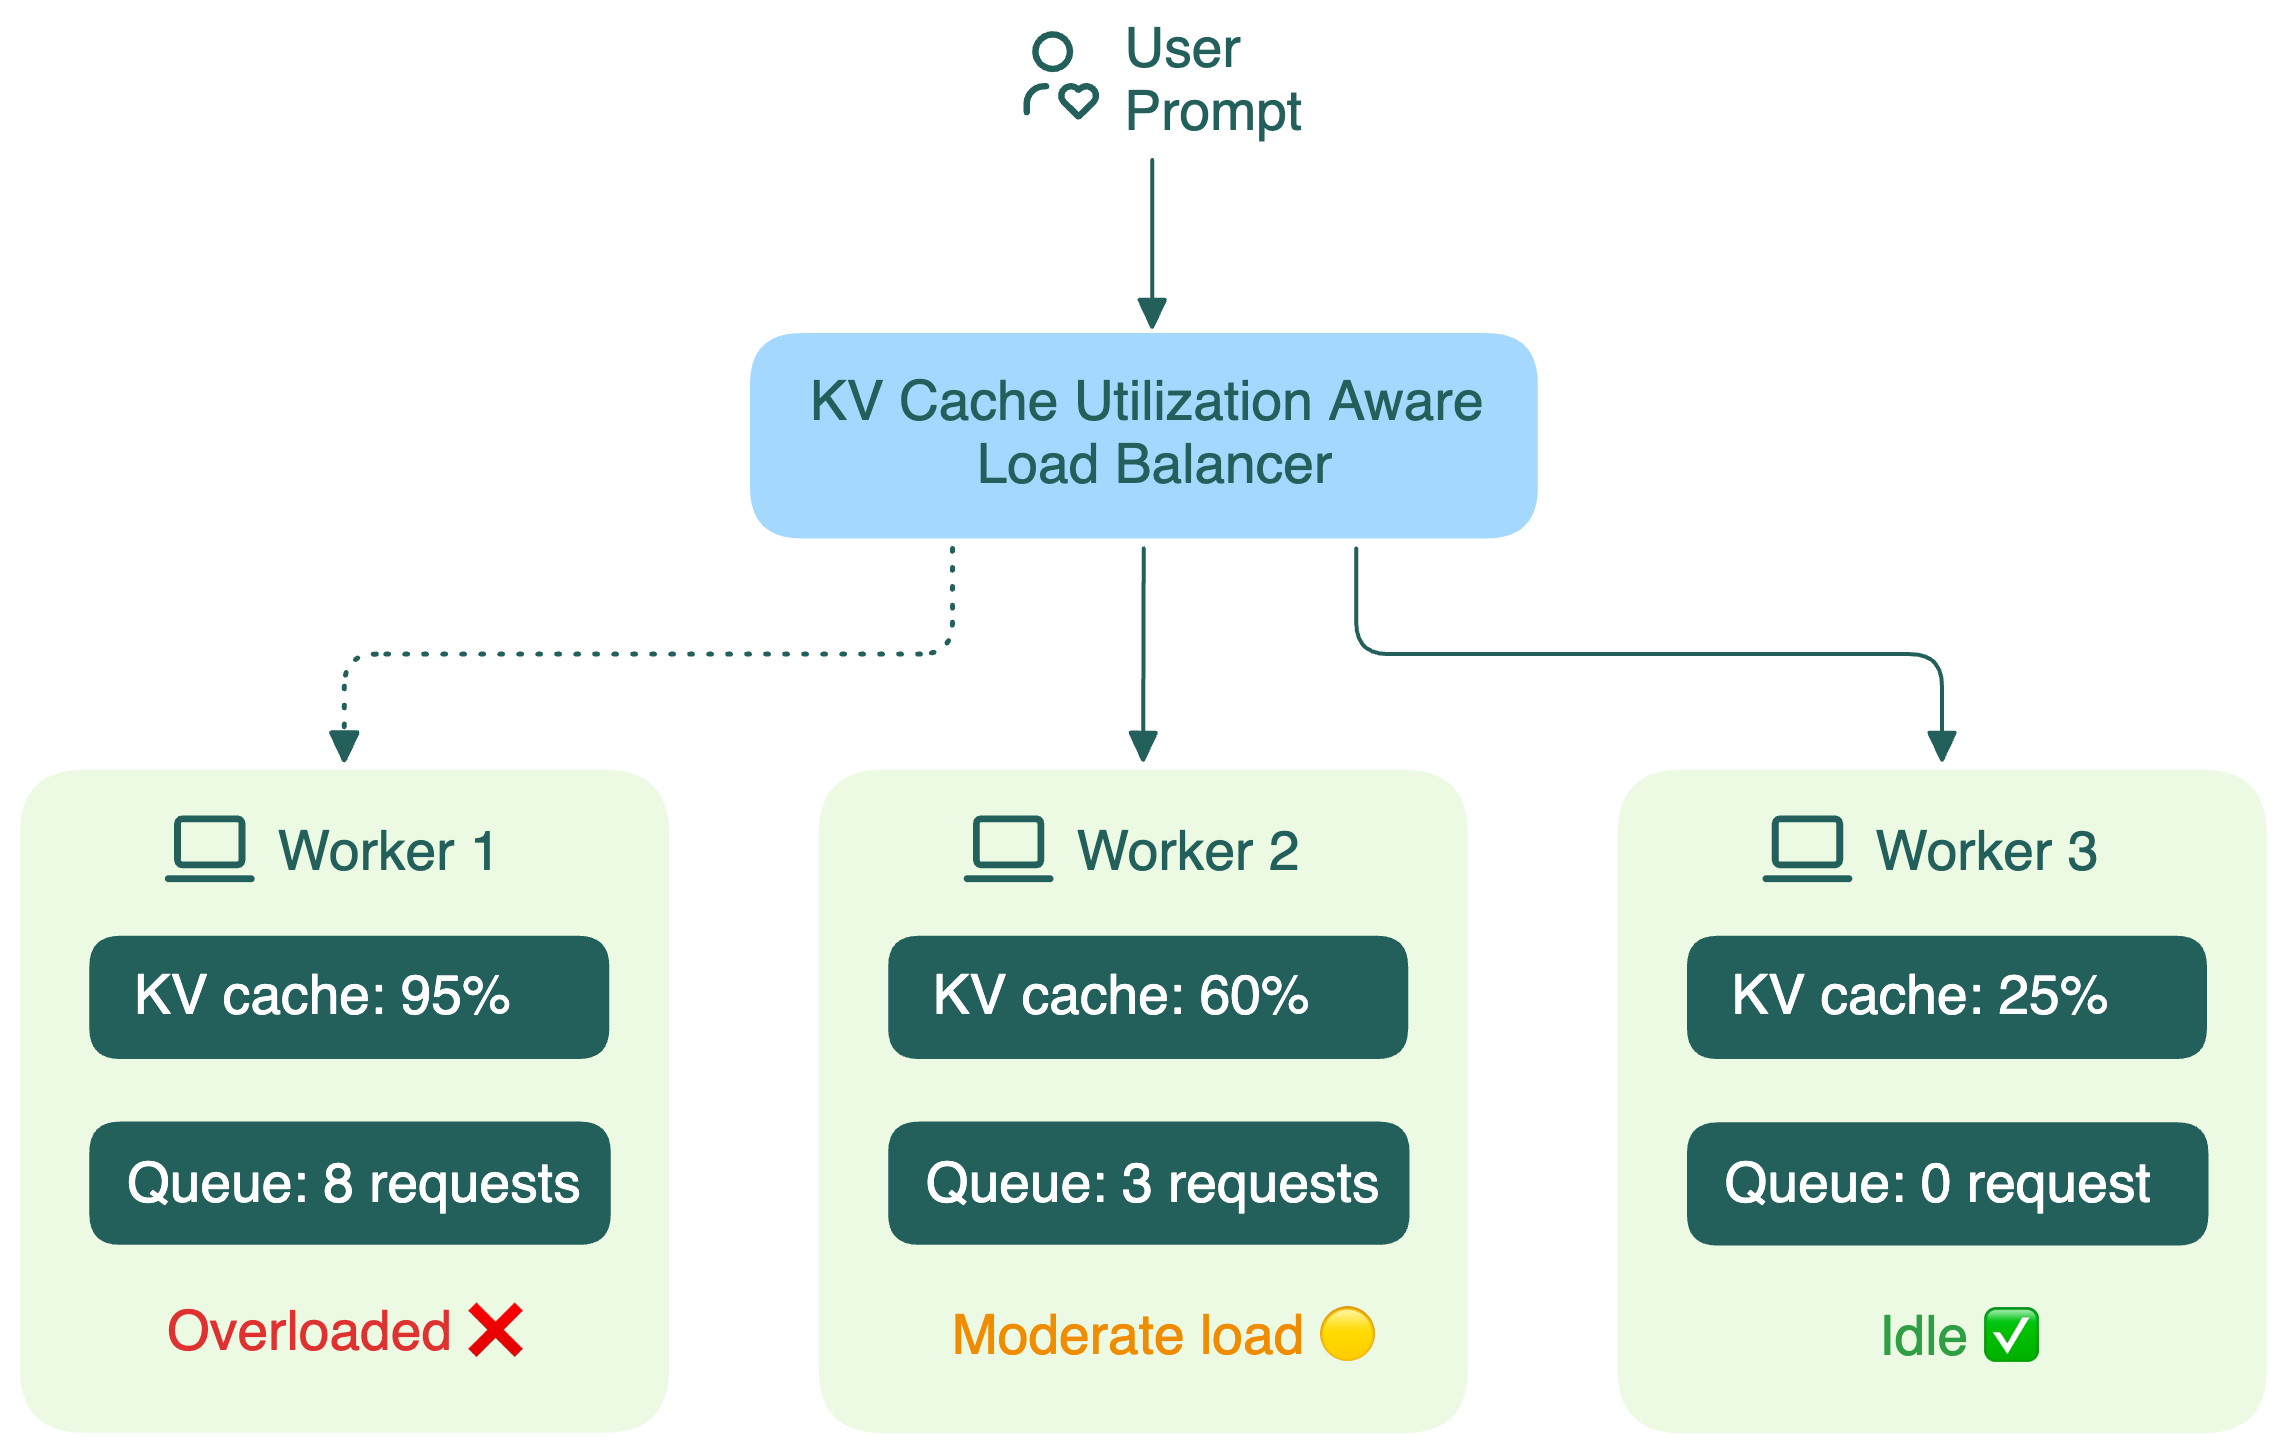
KV cache utilization-aware load balancing | LLM Inference Handbook

14. KV Cache 是什么?Prompt Caching 的原理是什么? | 小林面试笔记

KV Cache Explained
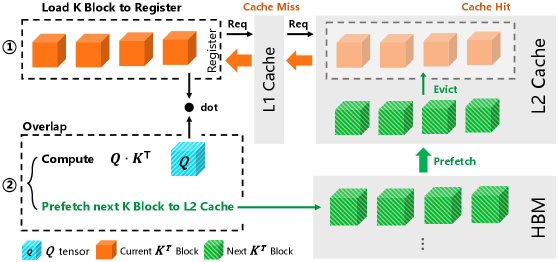
Accelerating LLM Inference Throughput via Asynchronous KV Cache Prefetching
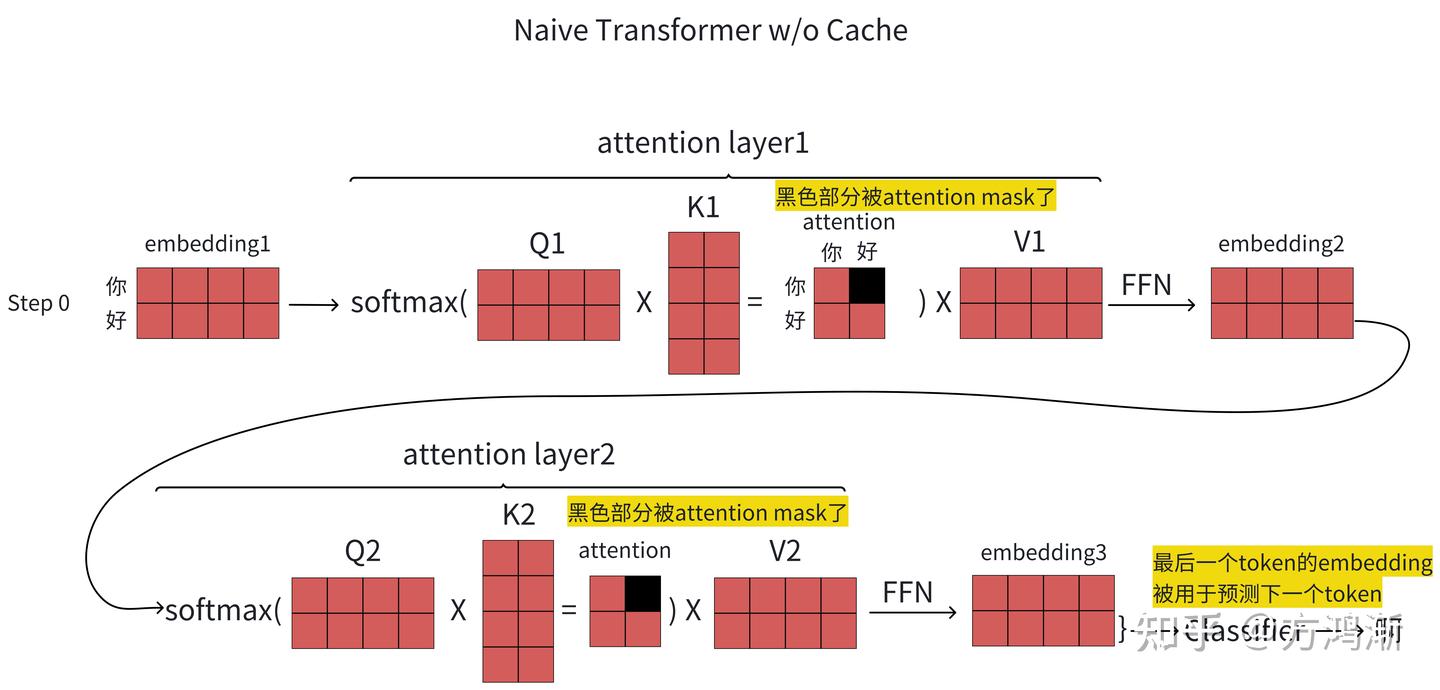
KV Cache - 从矩阵运算的角度理解 - 知乎
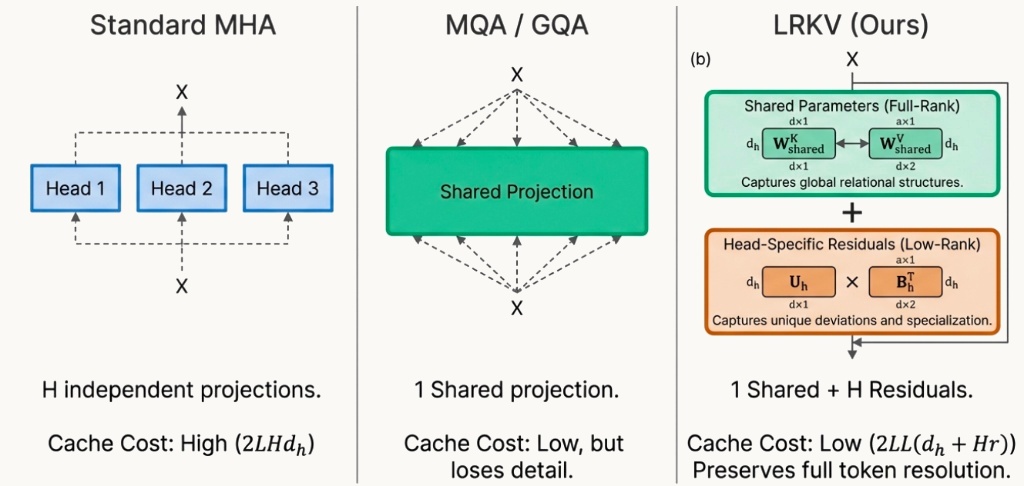
Low-Rank Key Value Attention: Reducing KV Cache Memory and Maintaining ...