
Figure 1 From Kv Cache Optimization Strategies For Scalable And

Figure 1 from KV Cache Optimization Strategies for Scalable and ...

Figure 1 from KV Cache Optimization Strategies for Scalable and ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
KV Cache Optimization Strategies for Scalable and Efficient LLM ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

Figure 1 from MiniCache: KV Cache Compression in Depth Dimension for ...

Figure 1 from User-centric Optimization of Caching and Recommendations ...

Figure 1 from A Flash-Based Cache Optimization Strategy | Semantic Scholar
Advertisement Space (300x250)

Caching Strategies for LLM Systems (Part 2): KV Cache and the ...
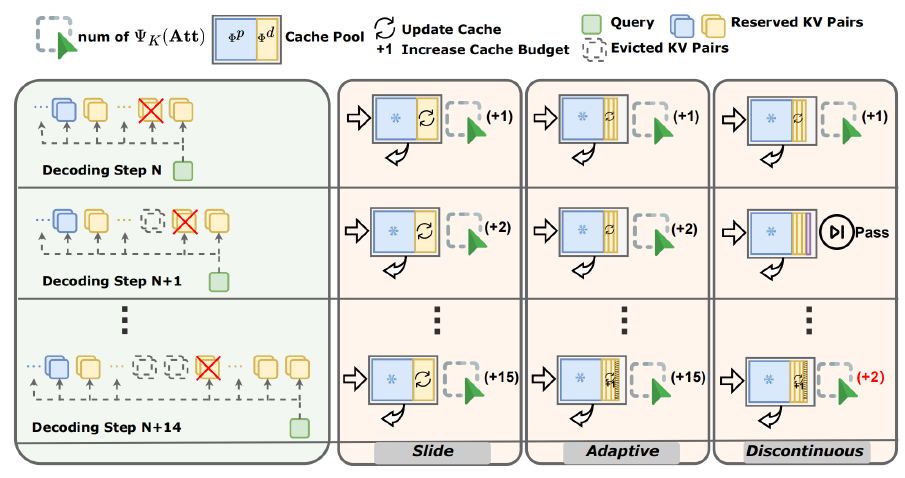
SCOPE: KV Cache optimization framework for long-context generation in ...
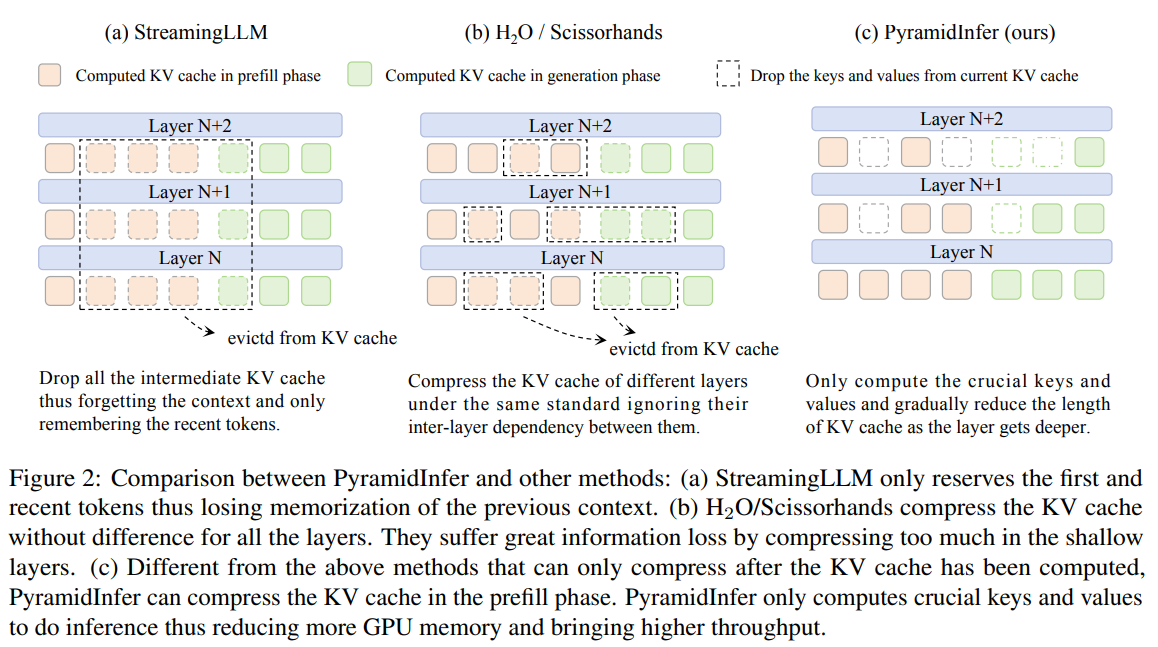
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal ...

Efficiency at Scale: Analyzing TurboQuant and KV Cache Optimization
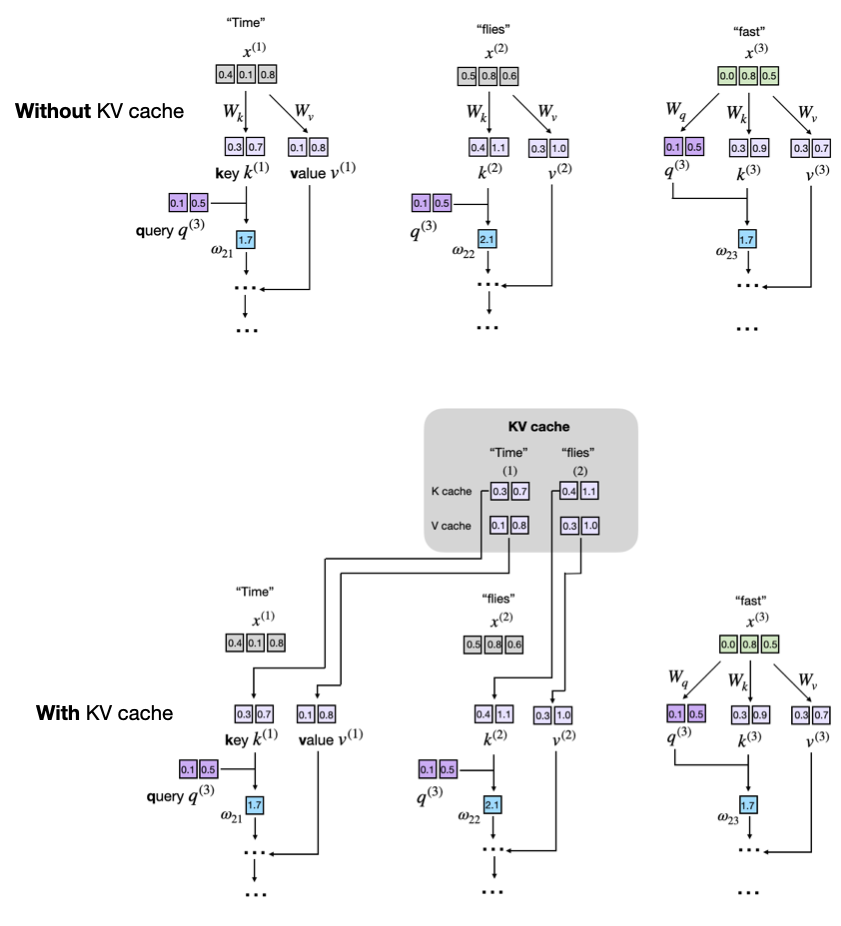
Understanding and Coding the KV Cache in LLMs from Scratch
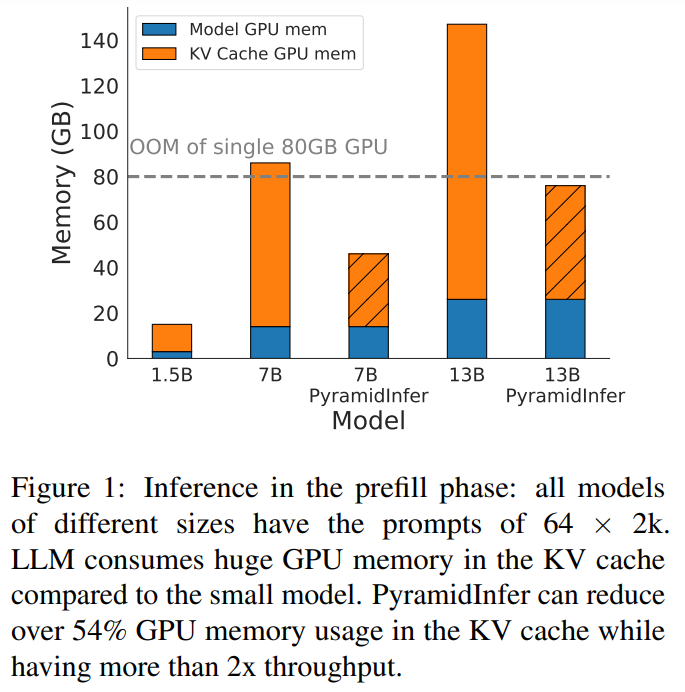
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

Figure 1 from SCOPE: Optimizing Key-Value Cache Compression in Long ...
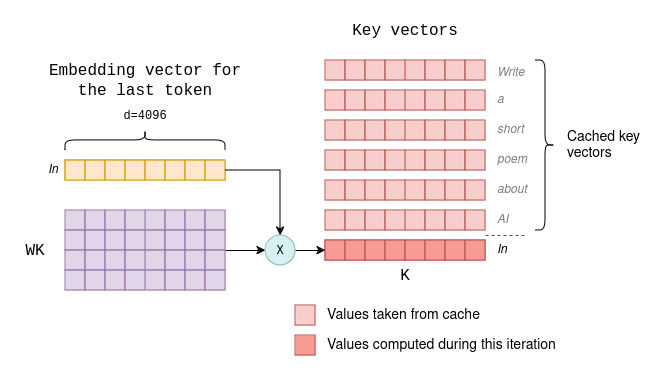
Techniques for KV Cache Optimization in Large Language Models
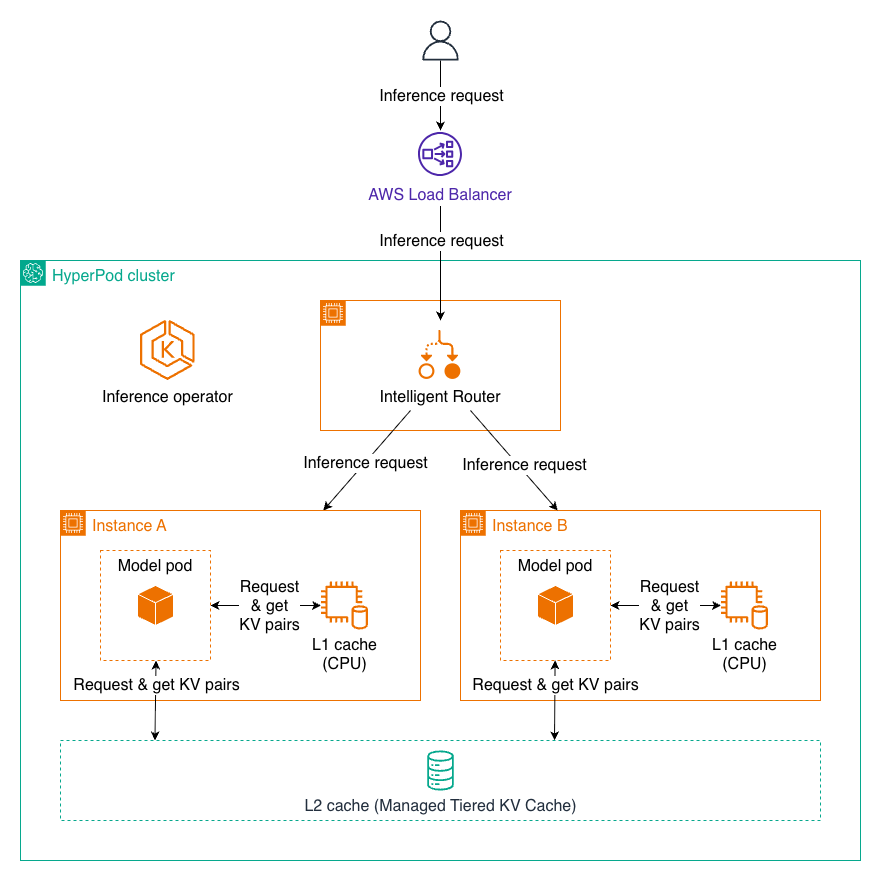
Managed Tiered KV Cache and Intelligent Routing for Amazon SageMaker ...
Advertisement Space (336x280)
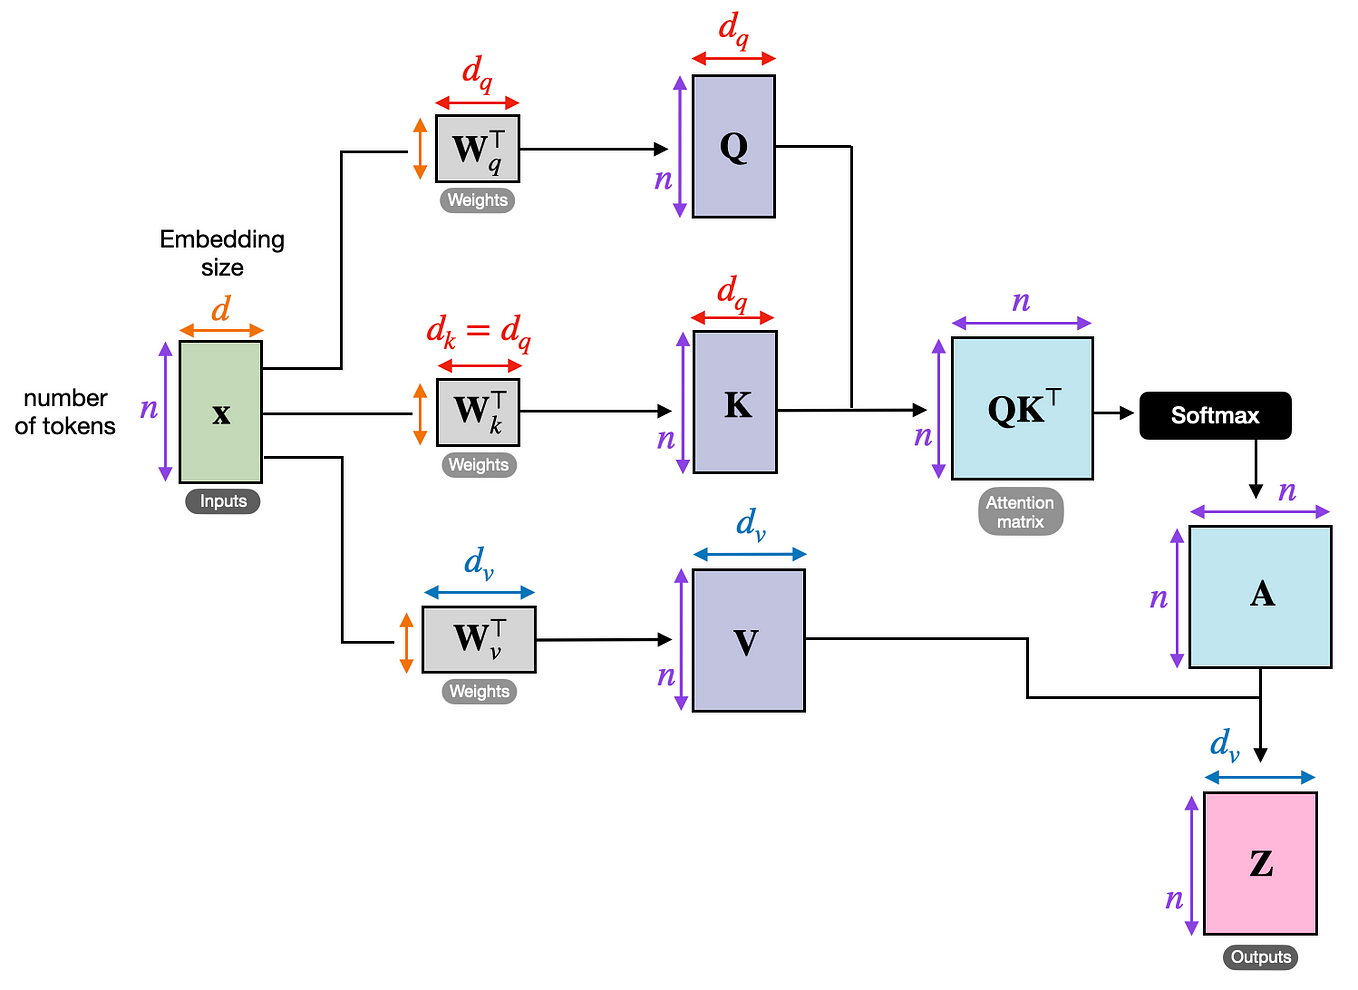
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
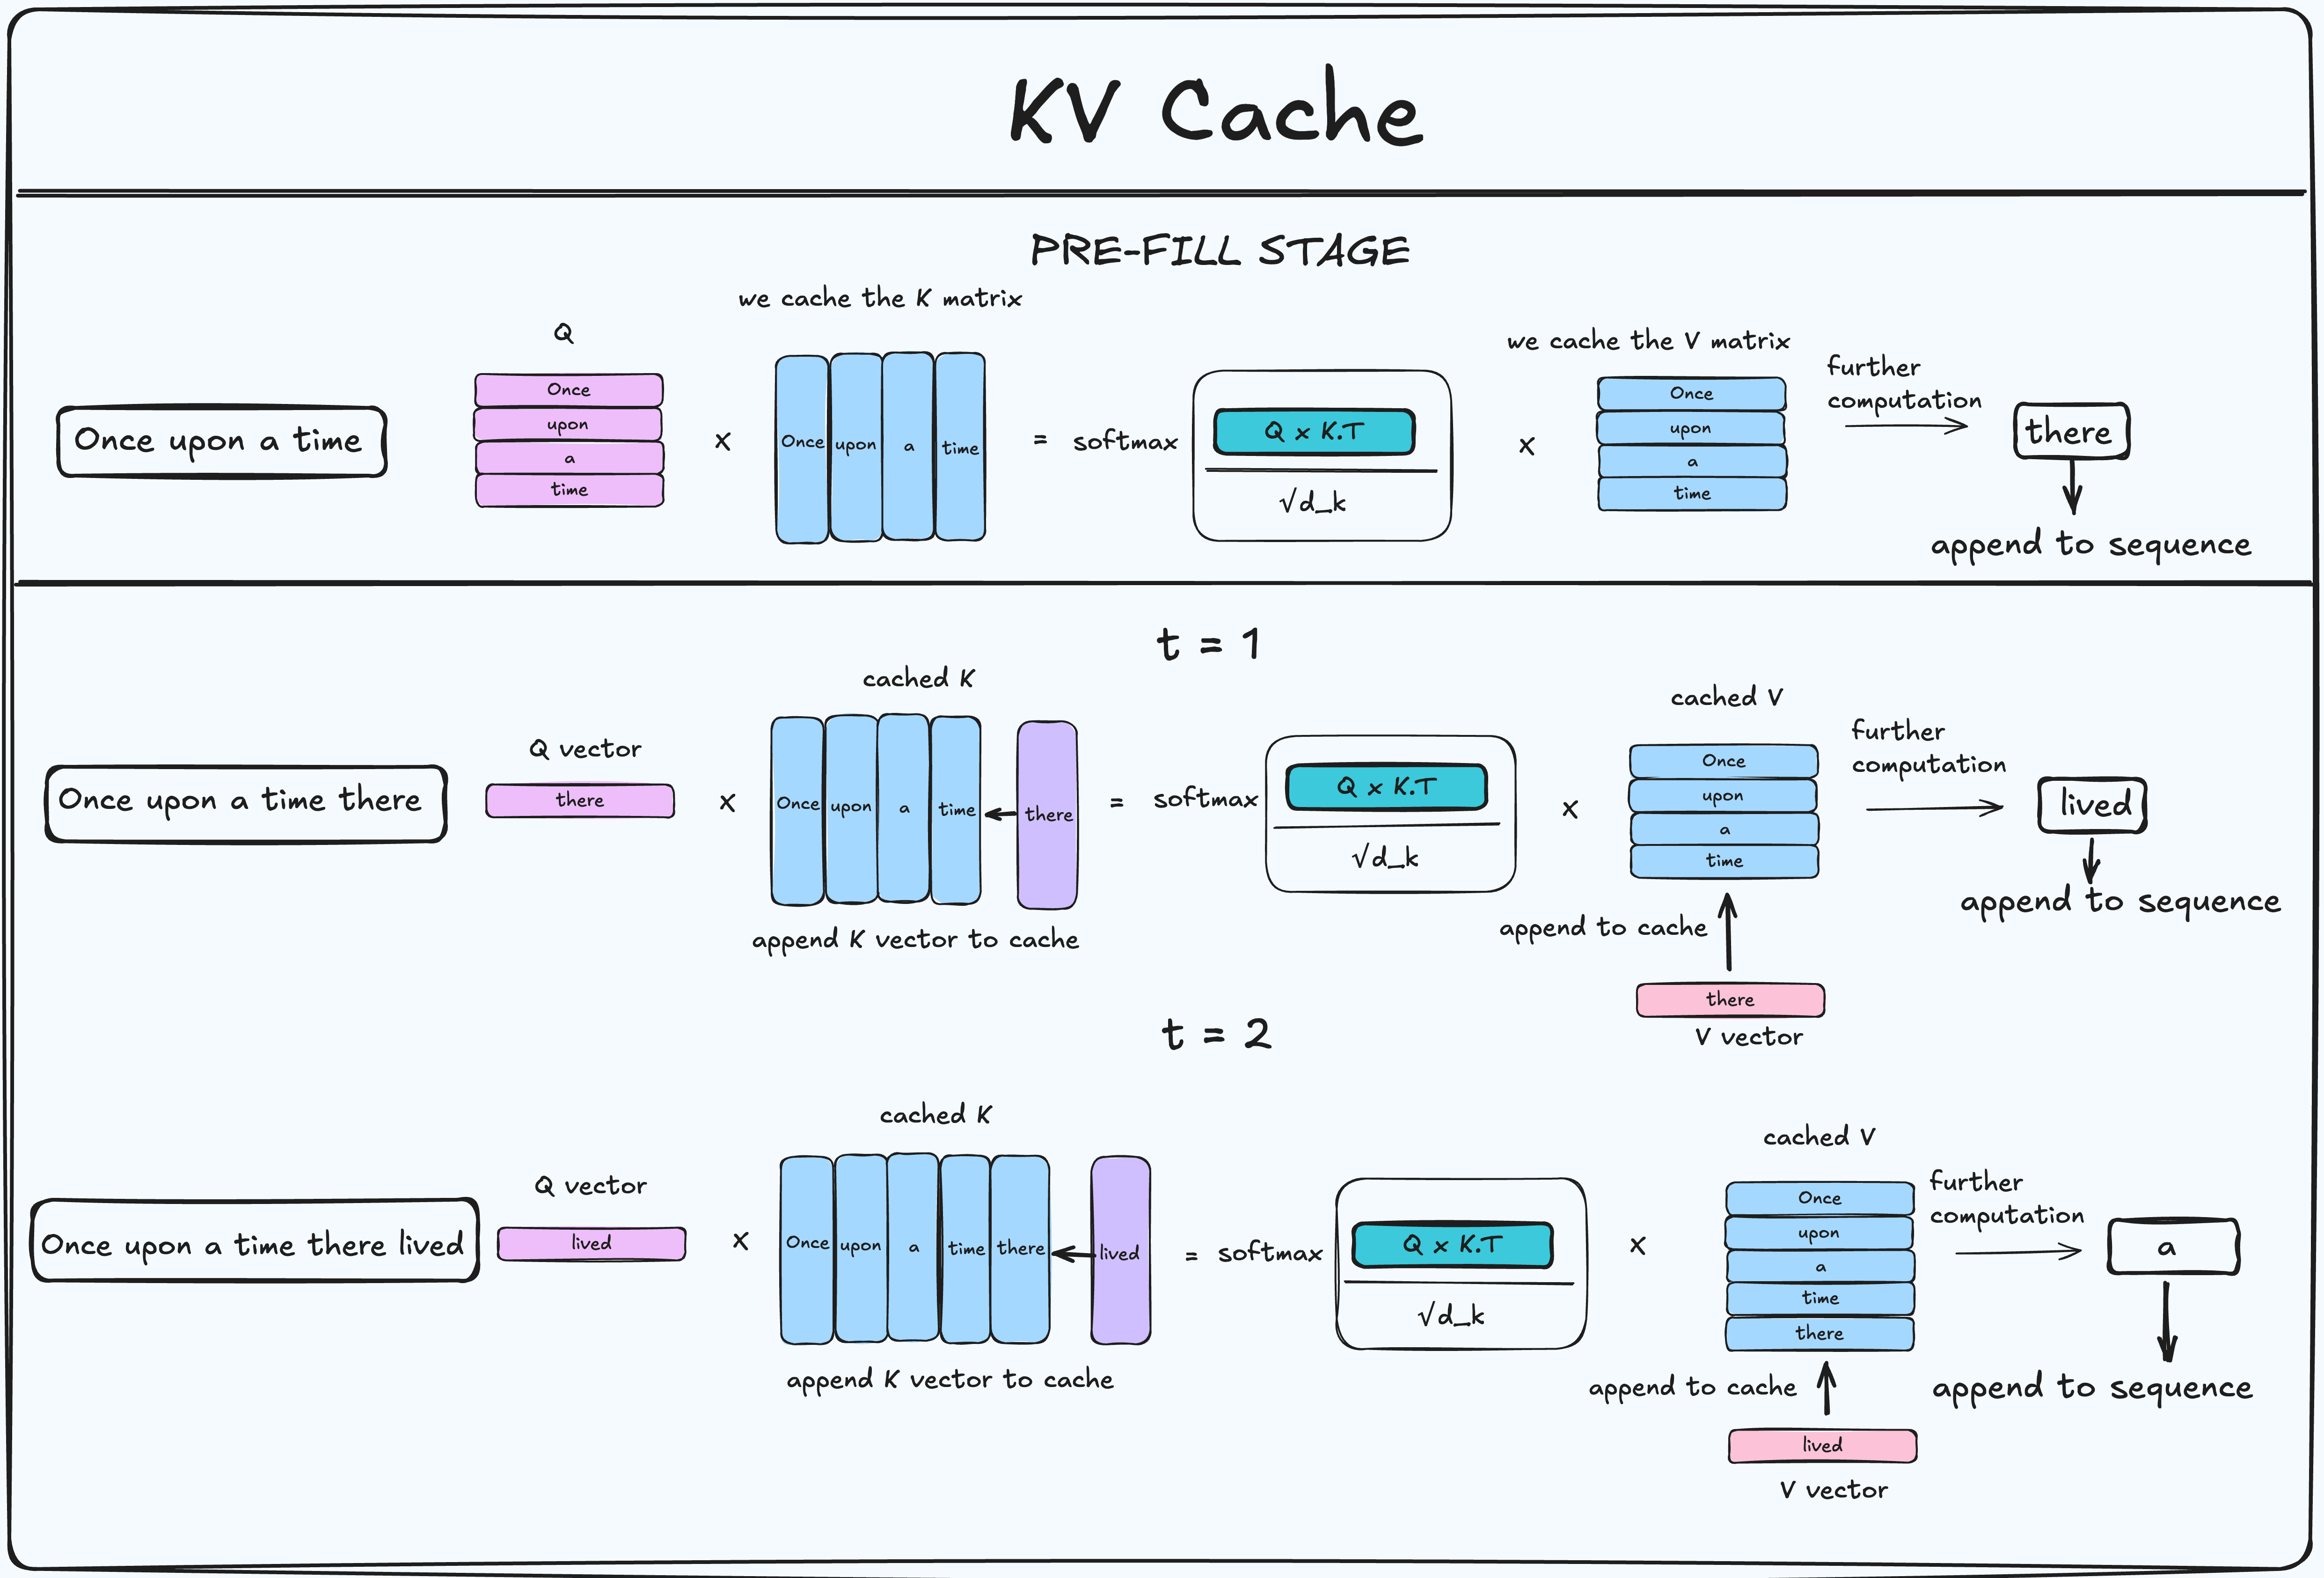
KV Cache From First Principles

KV Cache and Prompt Caching: How to Leverage them to Cut Time and Costs ...

KV Cache and Prompt Caching: How to Leverage them to Cut Time and Costs ...

Advancements in Efficient KV Cache Quantization and Management — AI ...
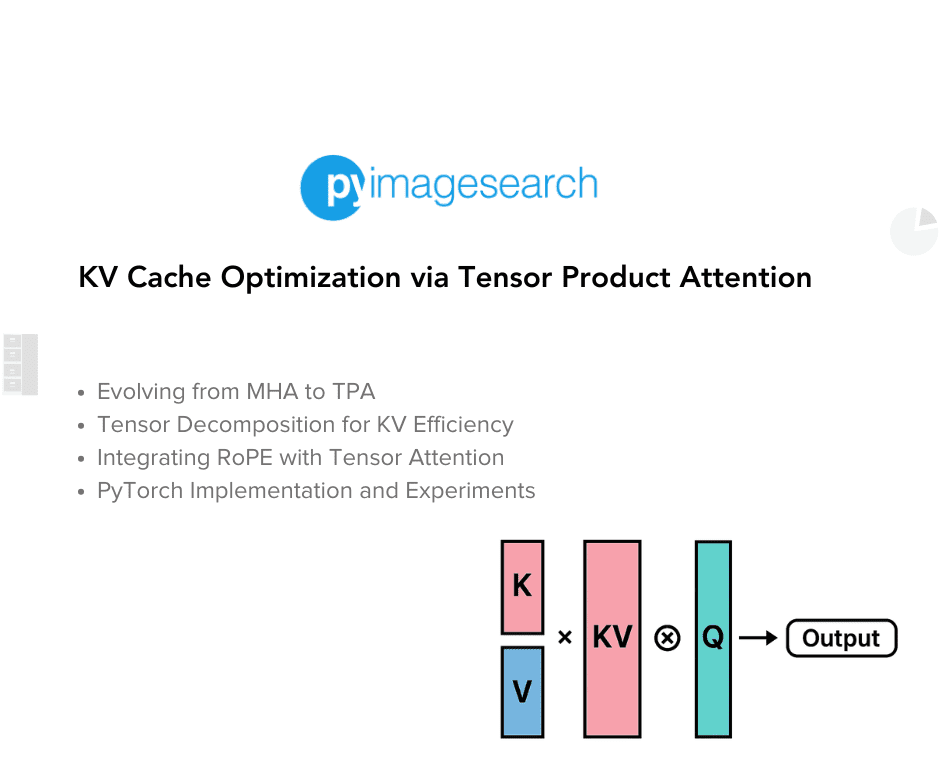
KV Cache Optimization via Tensor Product Attention - PyImageSearch
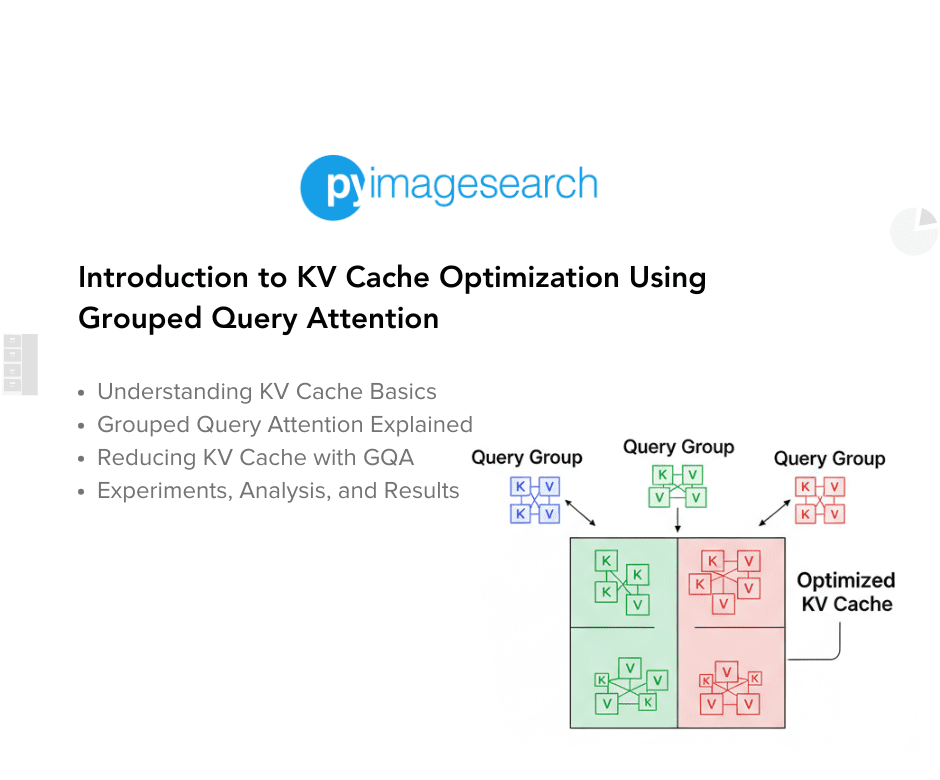
Introduction to KV Cache Optimization Utilizing Grouped Question ...
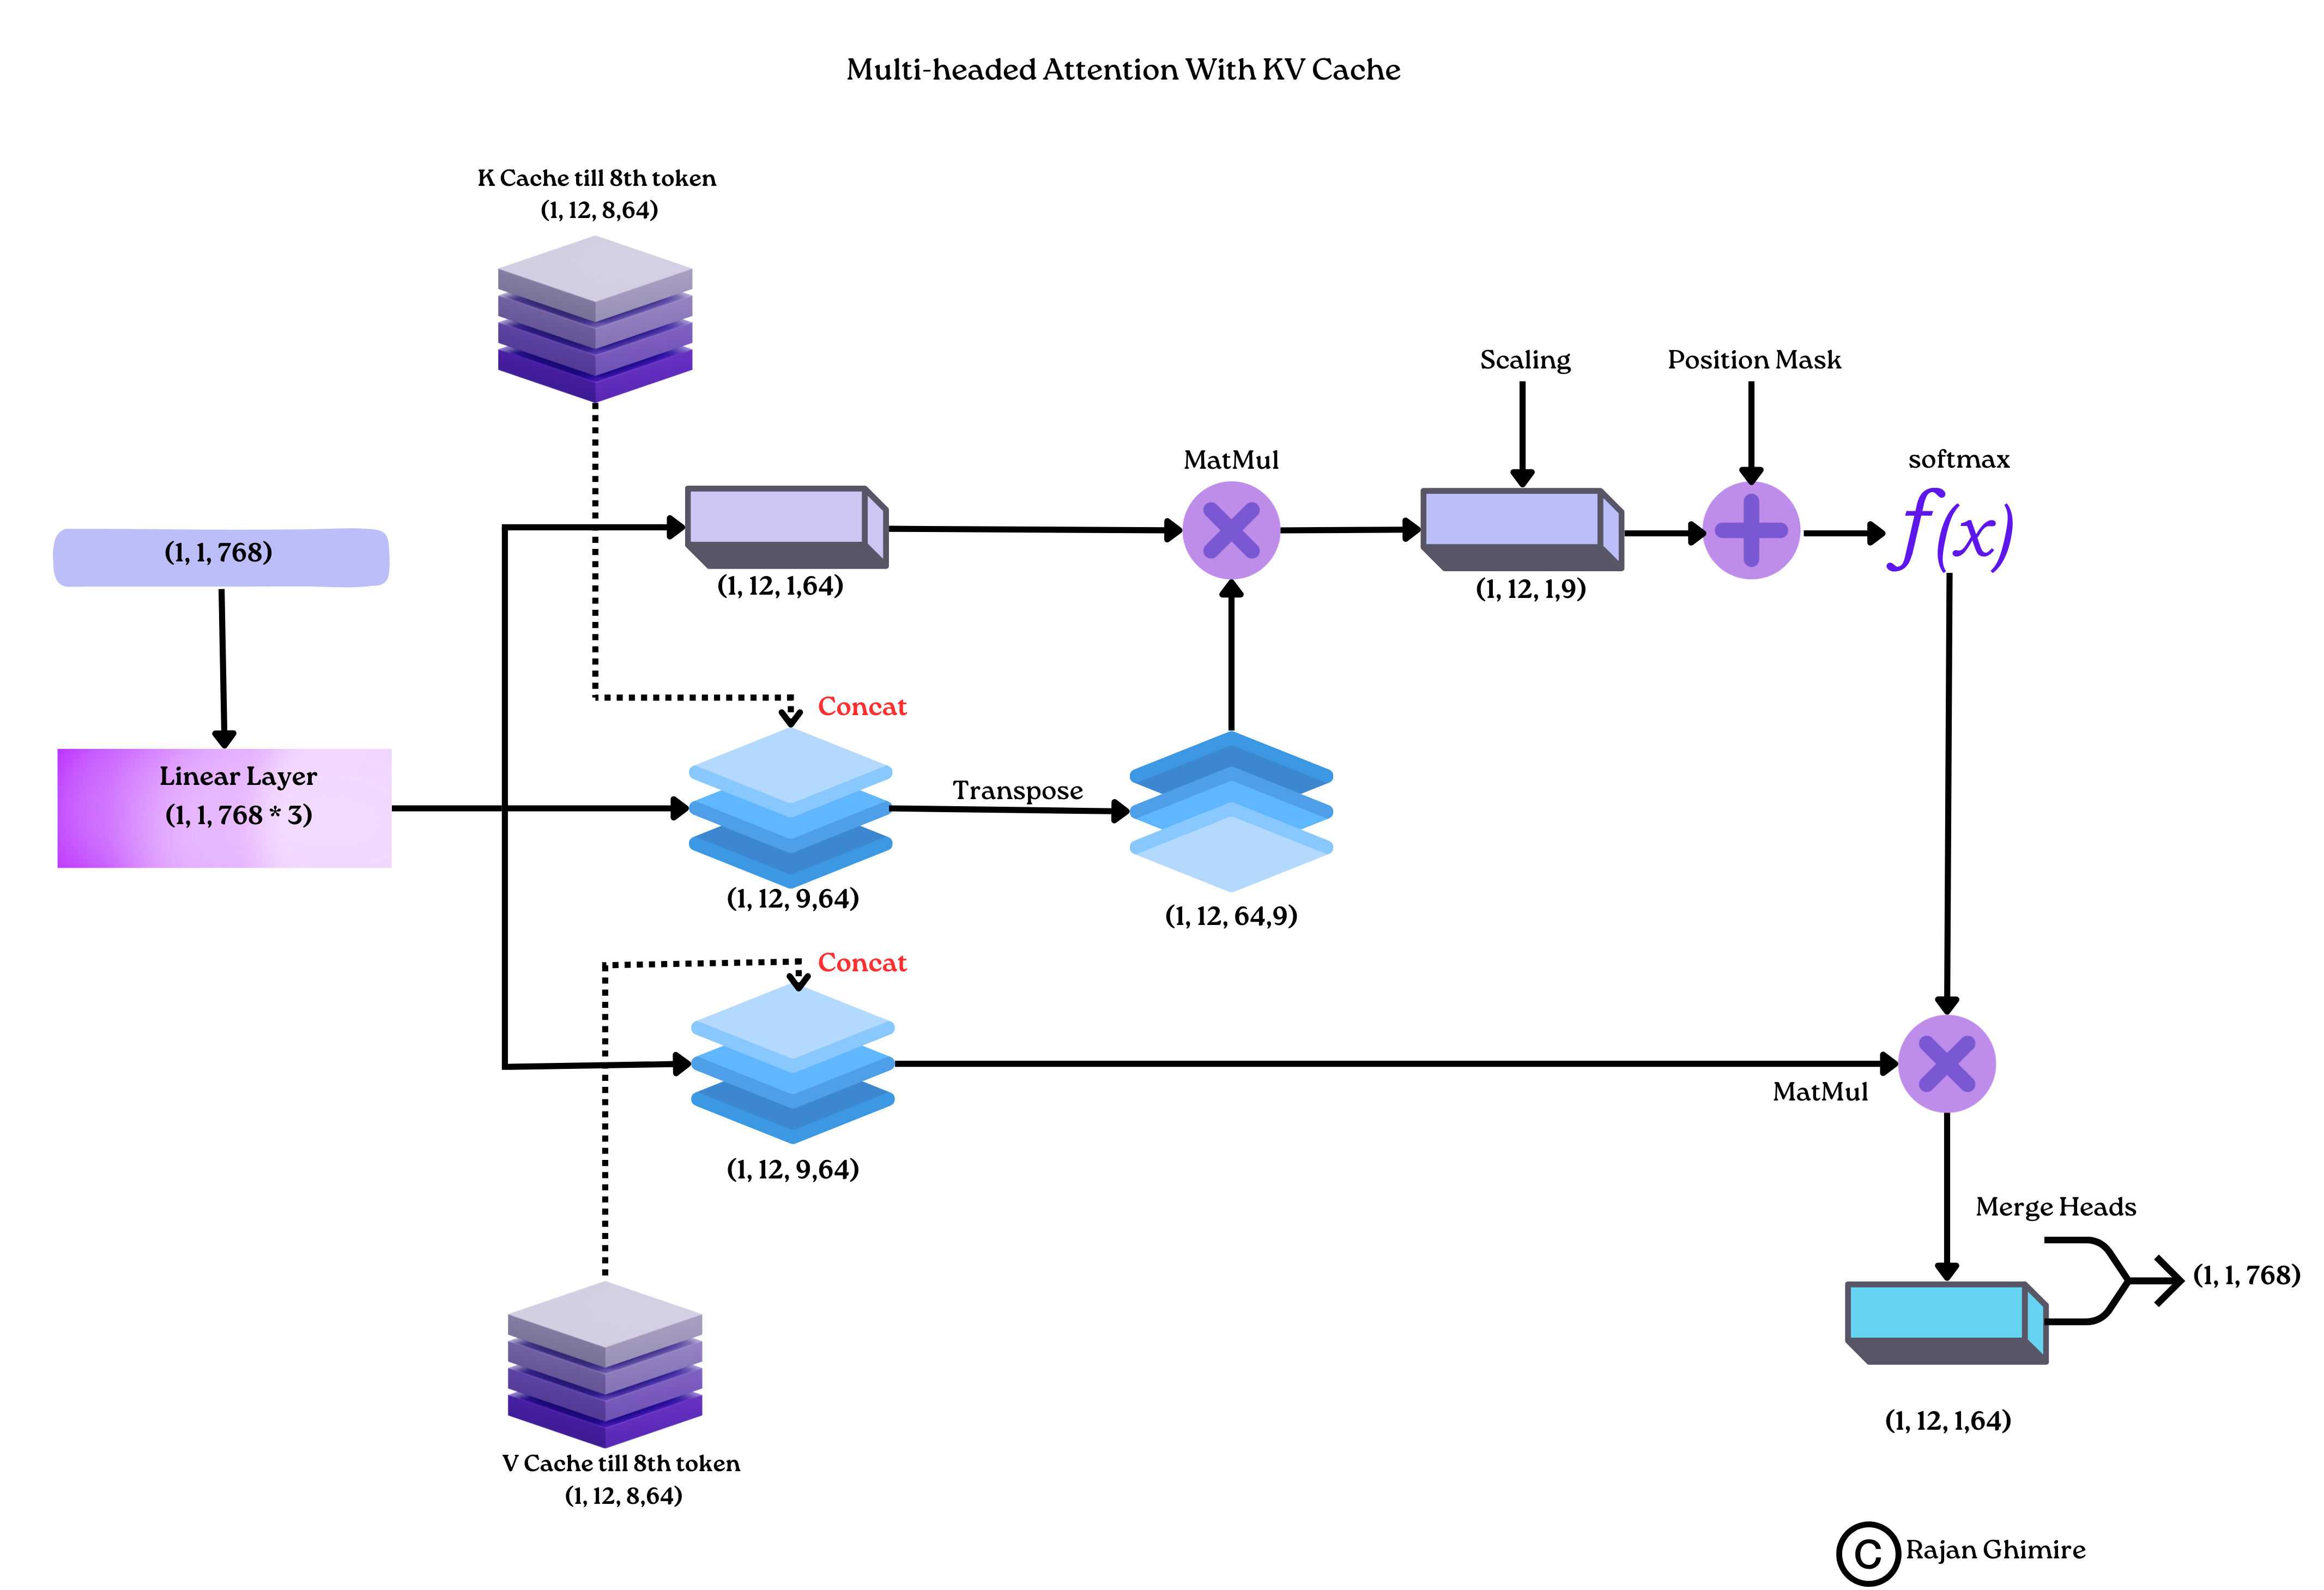
Transformers Optimization: Part 1 - KV Cache | Rajan Ghimire

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

[Literature Review] EliteKV: Scalable KV Cache Compression via RoPE ...
Advertisement Space (336x280)
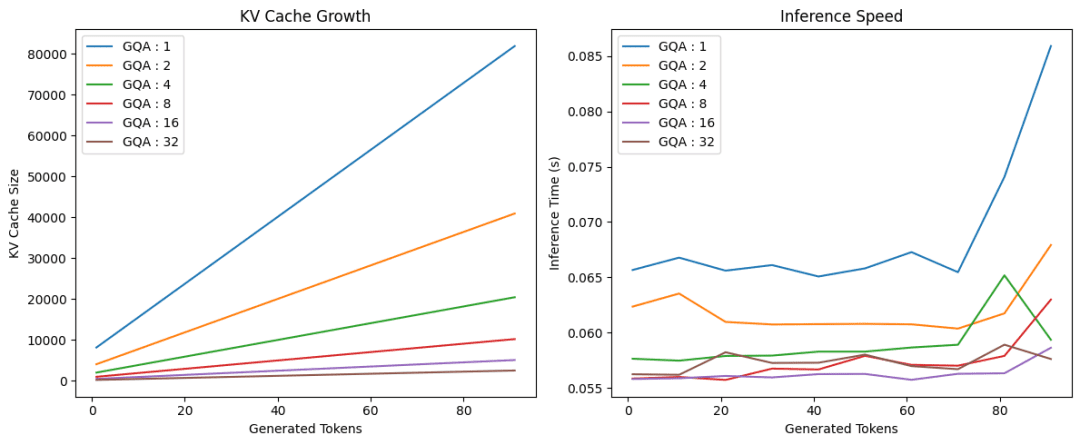
Introduction to KV Cache Optimization Utilizing Grouped Question ...

KV Cache from scratch in nanoVLM
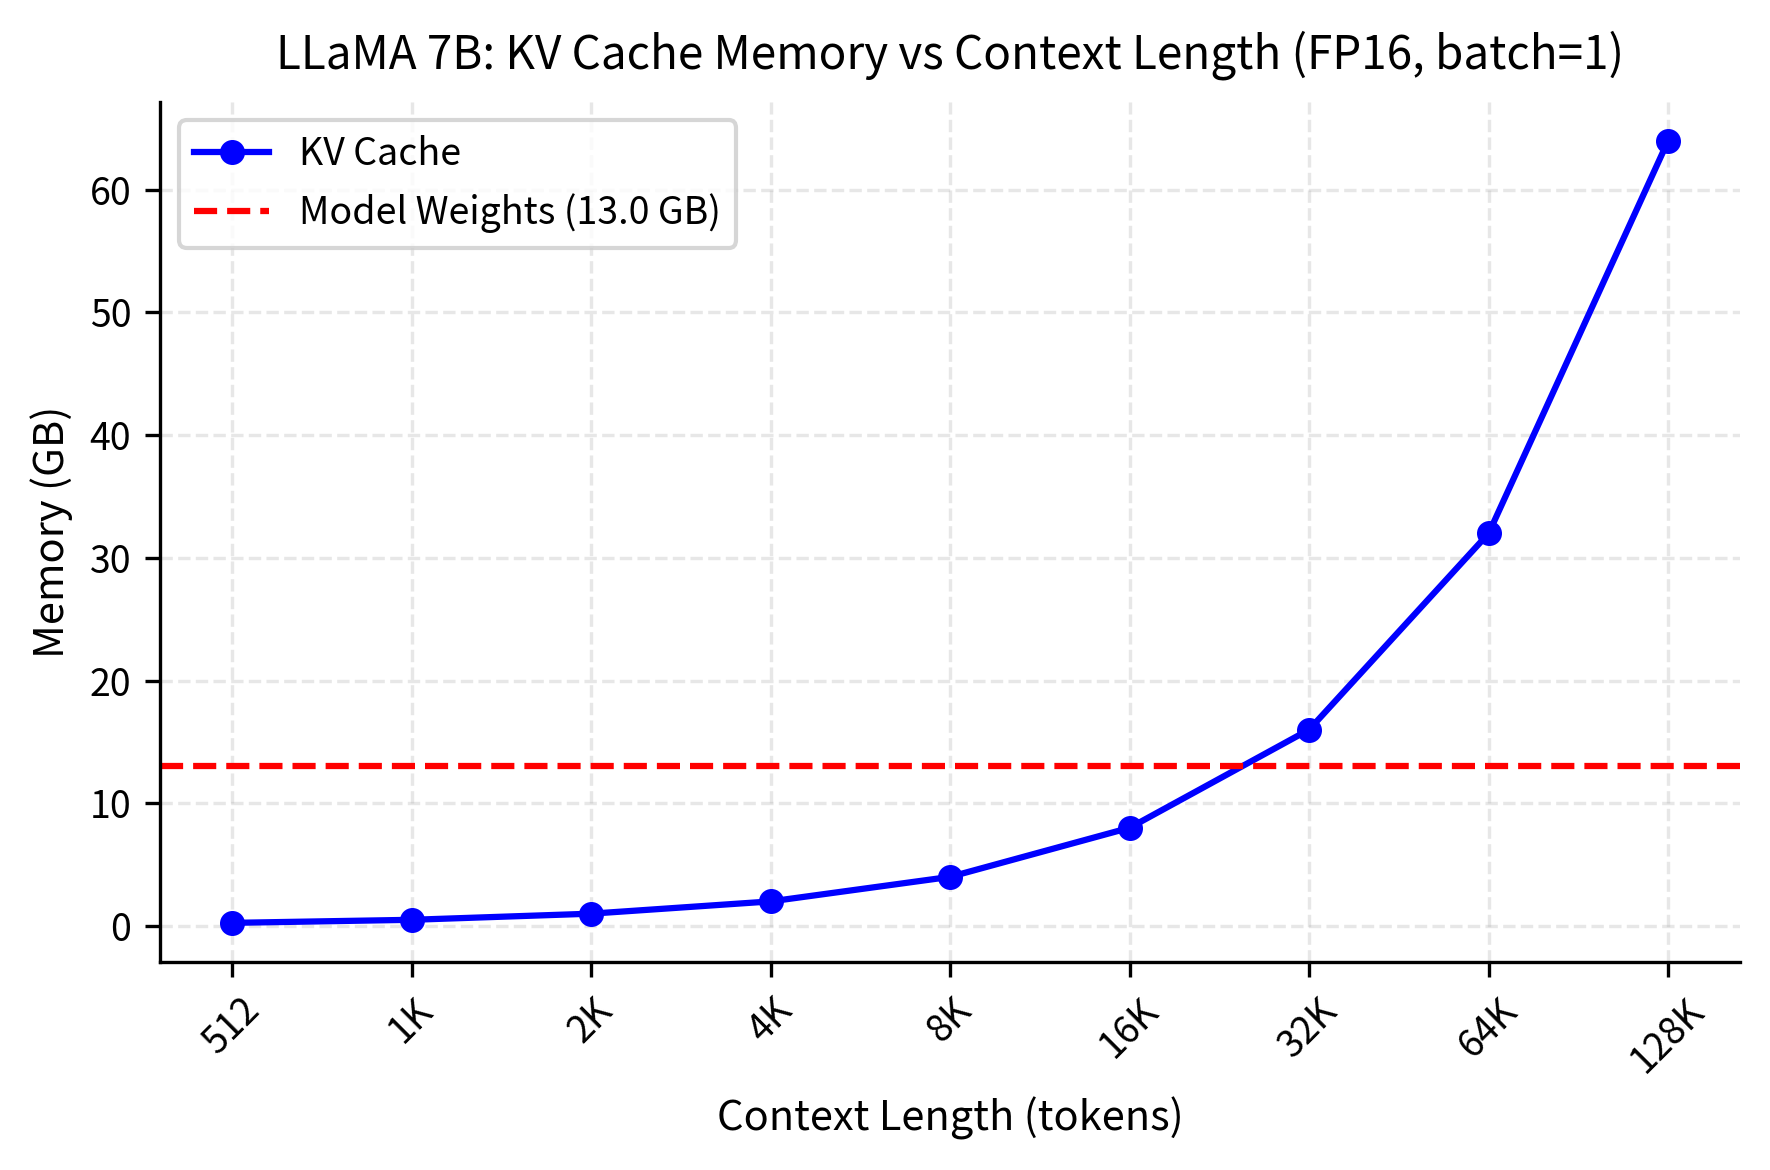
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

KV Cache in Large Language Models: Design, Optimization, and Inference ...
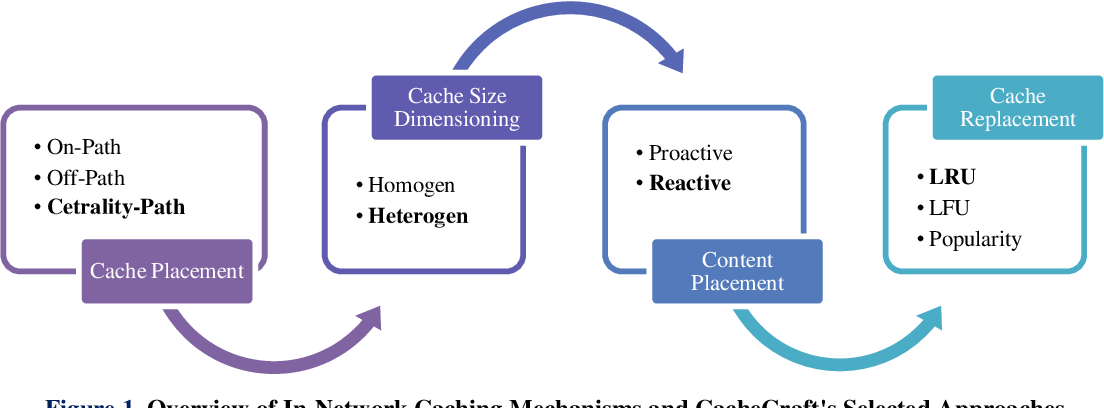
Figure 1 from CacheCraft: A Topology-Aware PageRank Centrality ...
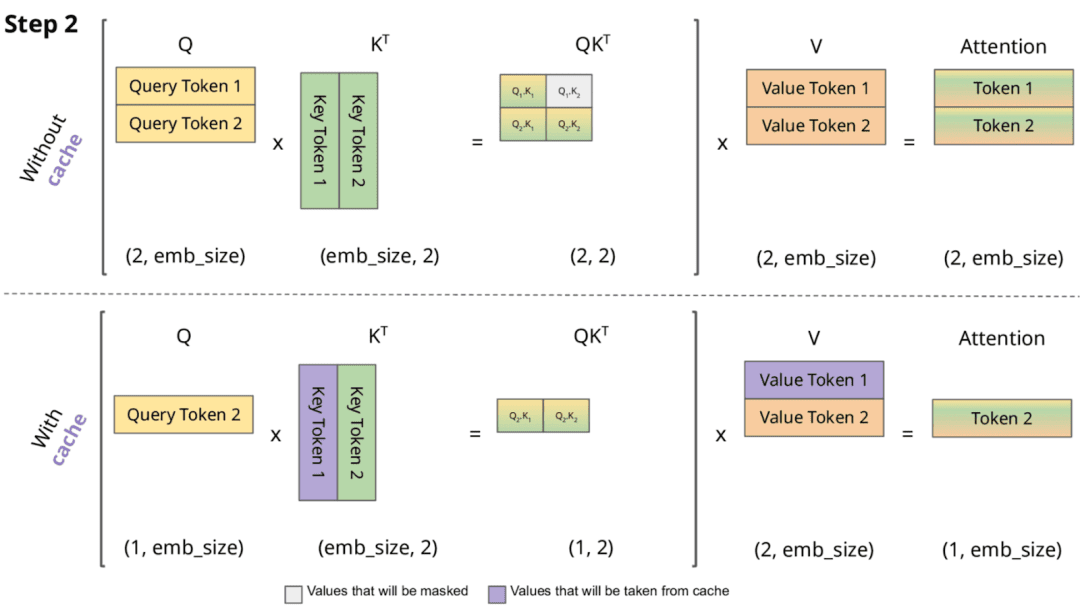
Introduction to KV Cache Optimization Using Grouped Query Attention ...