
Kvpr Efficient Llm Inference With Io Aware Kv Cache Partial

KVPR: Efficient LLM Inference with I/O-Aware KV Cache Partial ...
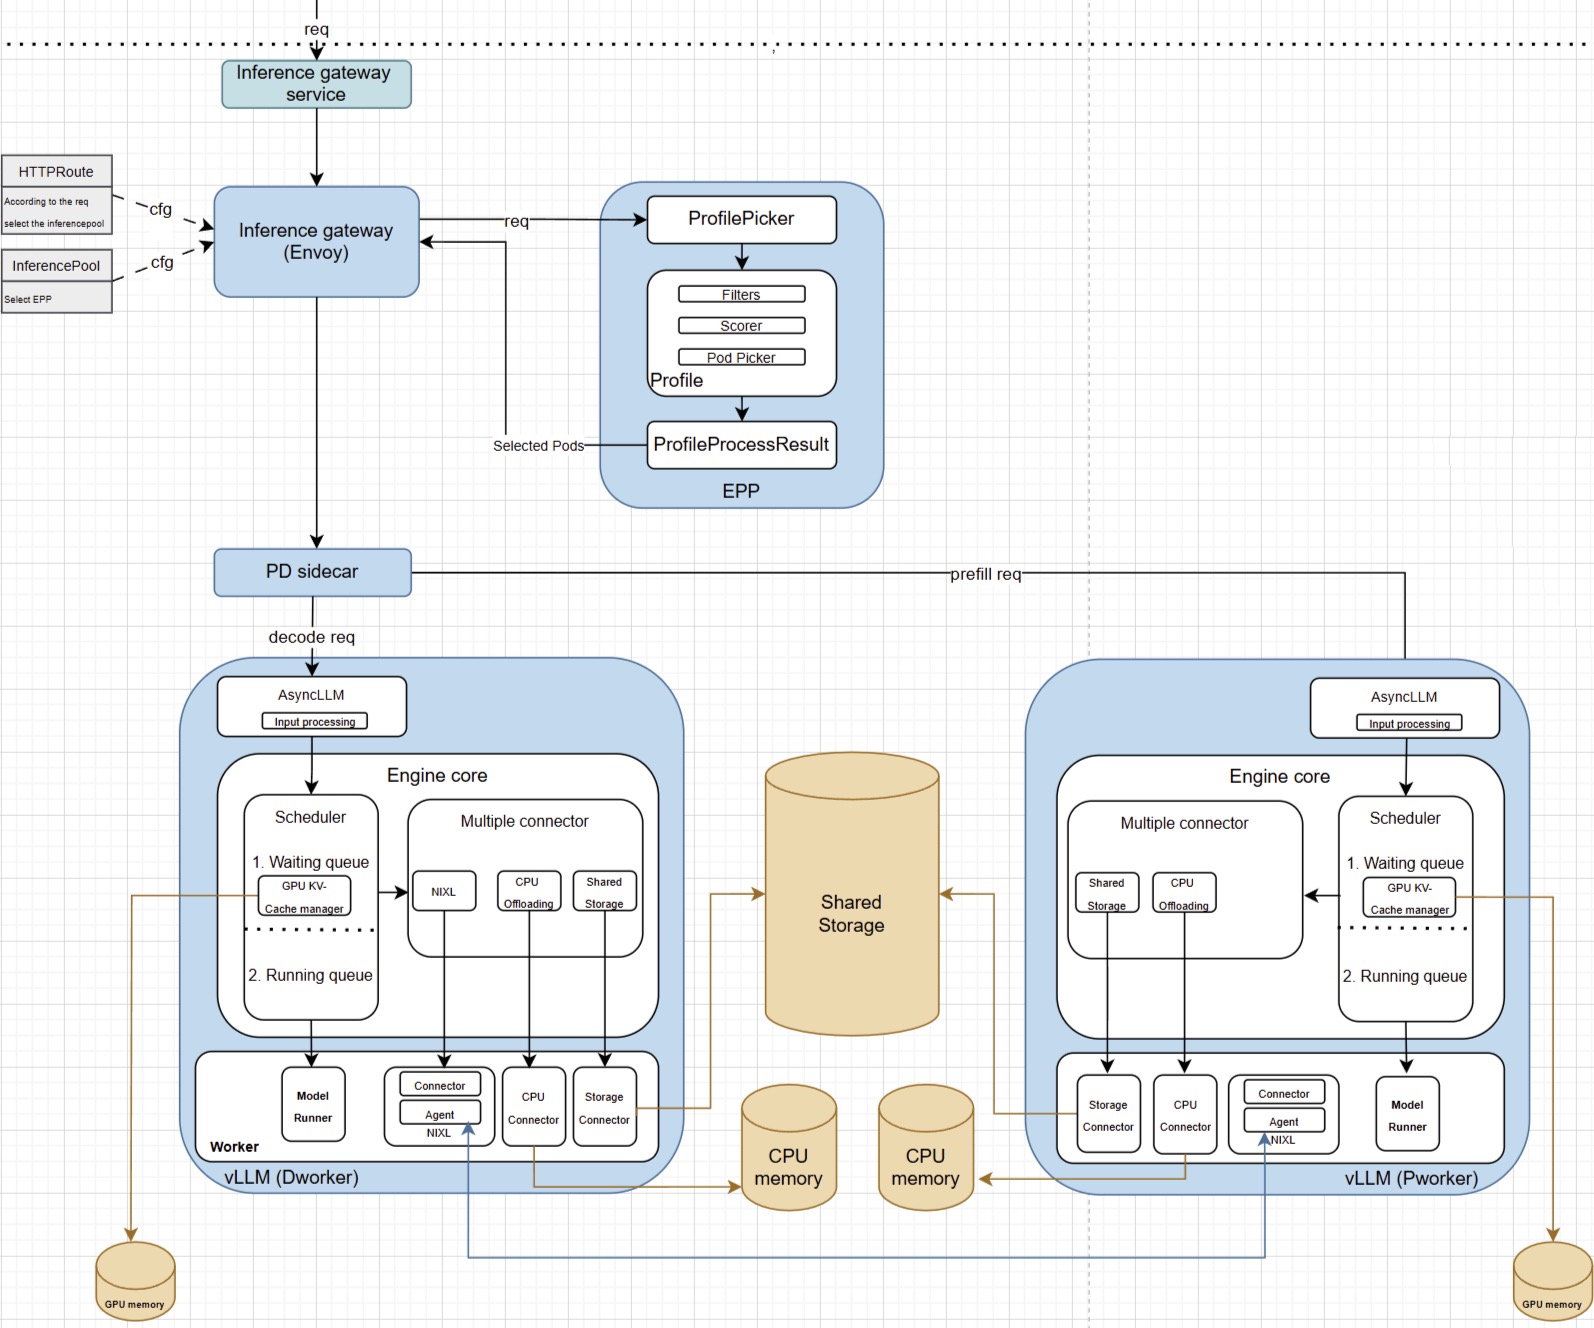
Master KV cache aware routing with llm-d for efficient AI inference ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...

KVSharer: method for efficient LLM inference via dissimilar KV Cache ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
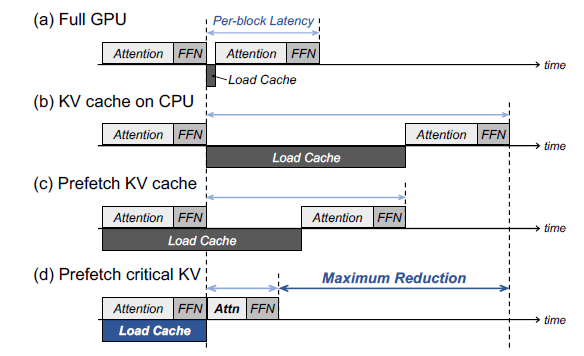
KVSharer: method for efficient LLM inference via dissimilar KV Cache ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference
Advertisement Space (300x250)

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference

FreeKV: Boosting KV Cache Retrieval for Efficient LLM Inference

KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

LLM Inference: Accelerating Long Context Generation with KV Cache ...
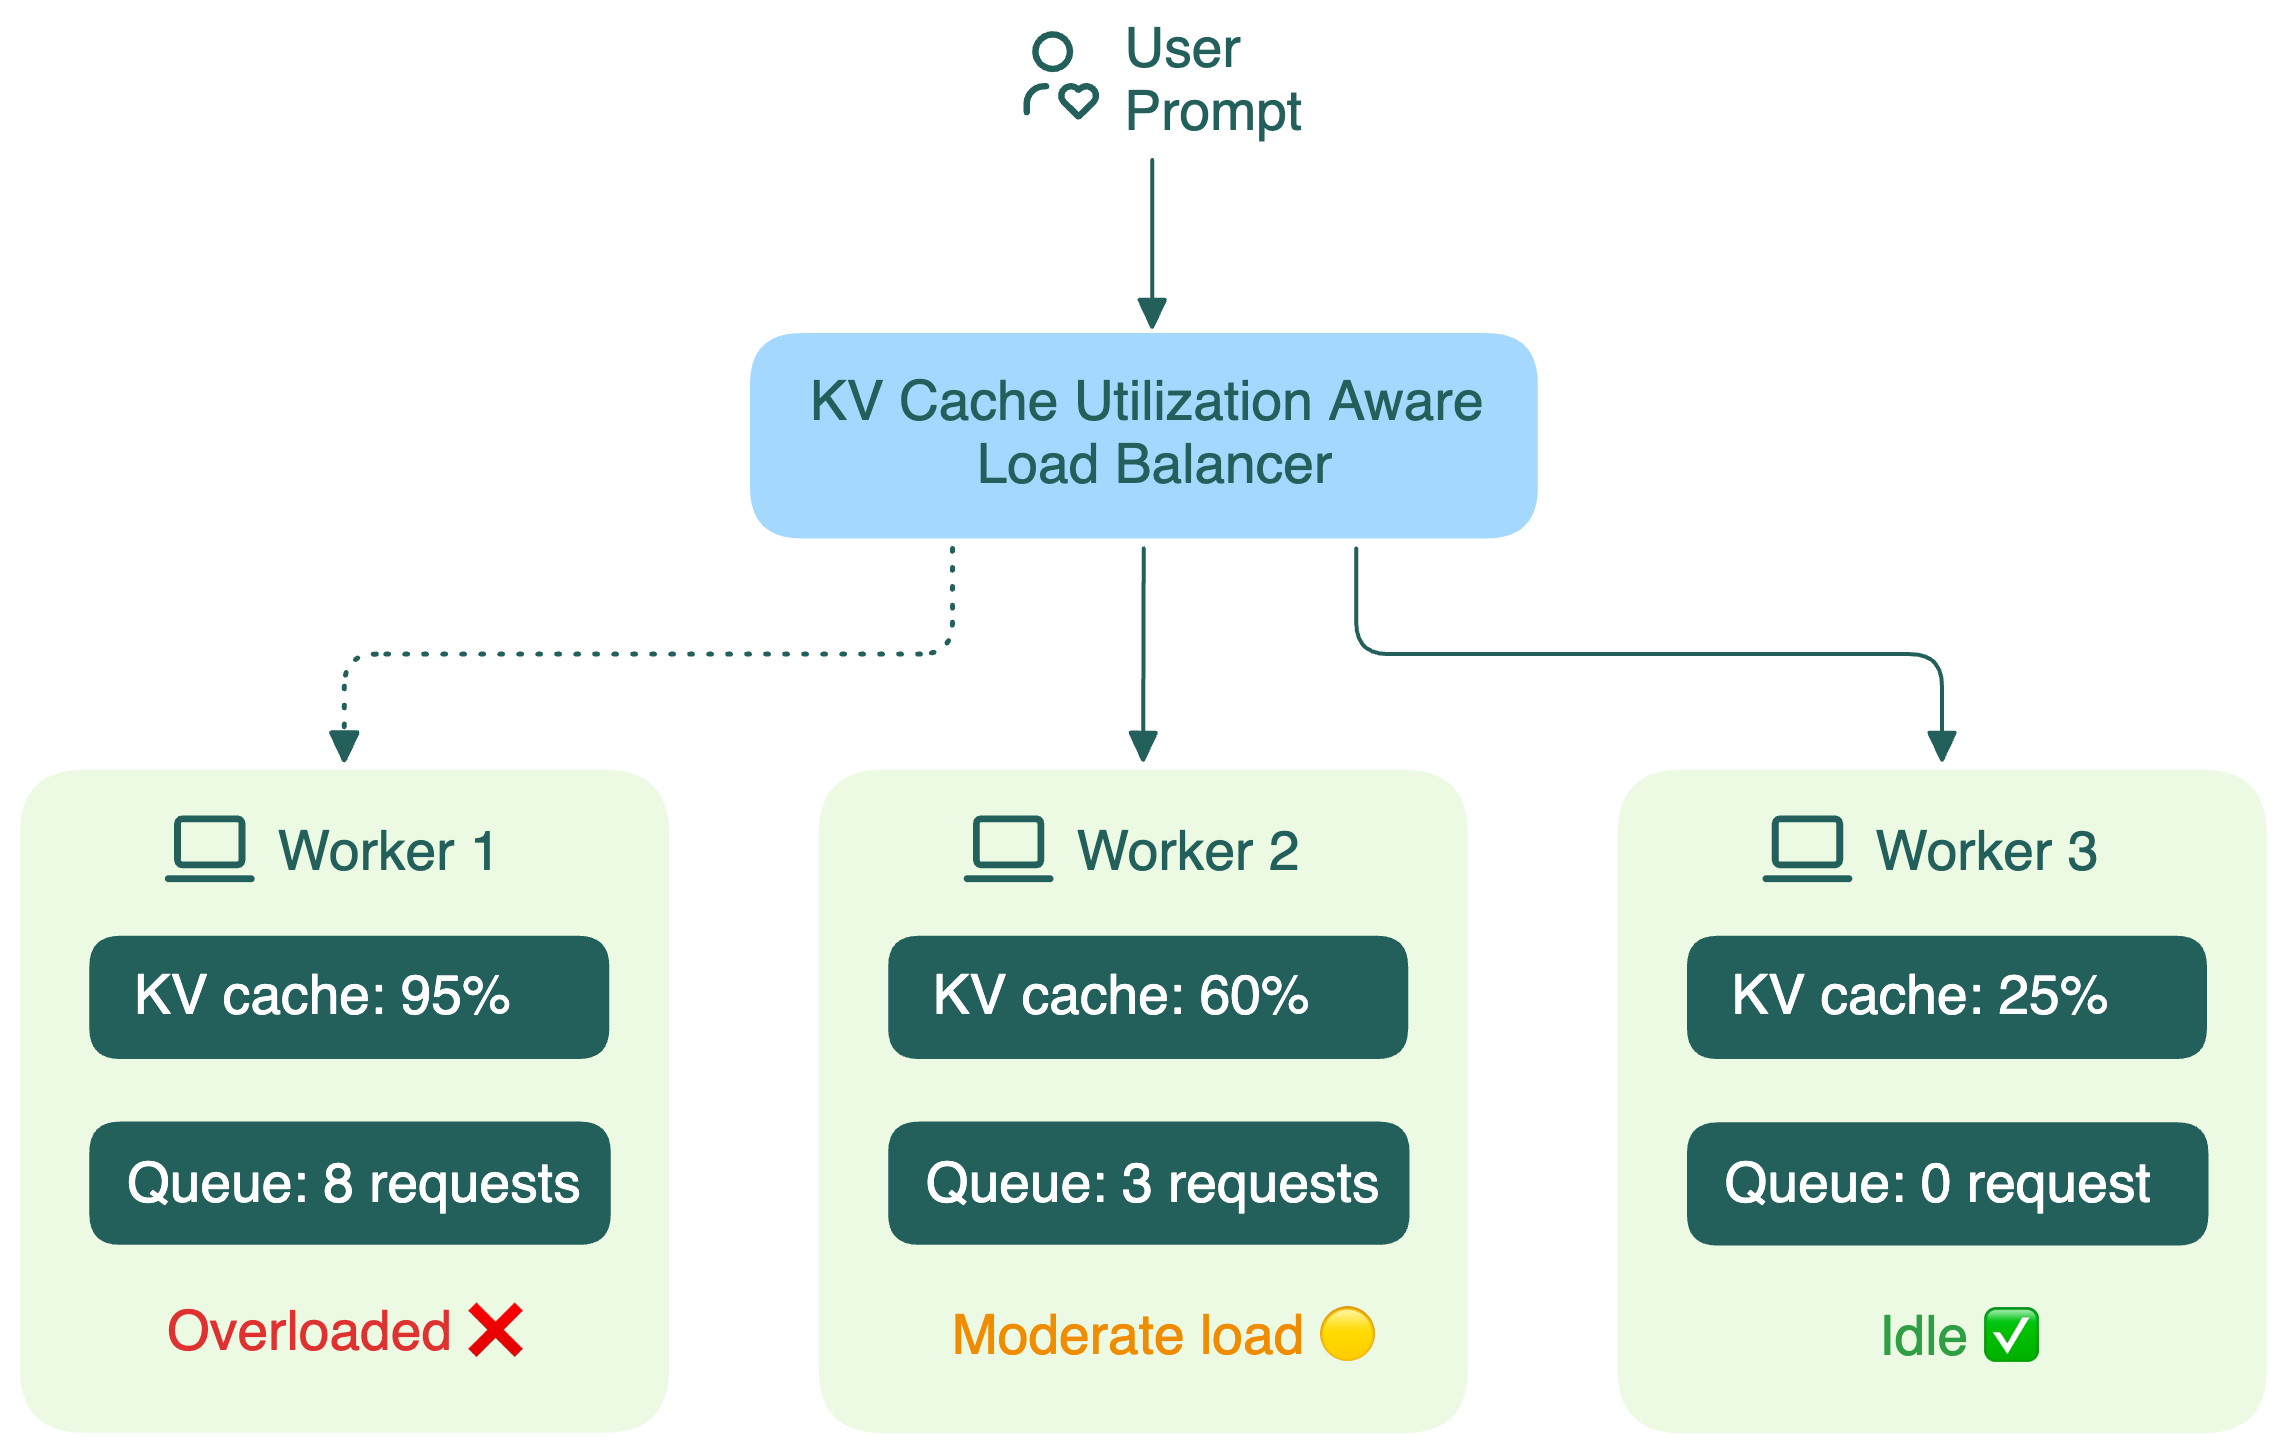
KV cache utilization-aware load balancing | LLM Inference Handbook

[论文评述] KVSharer: Efficient Inference via Layer-Wise Dissimilar KV Cache ...
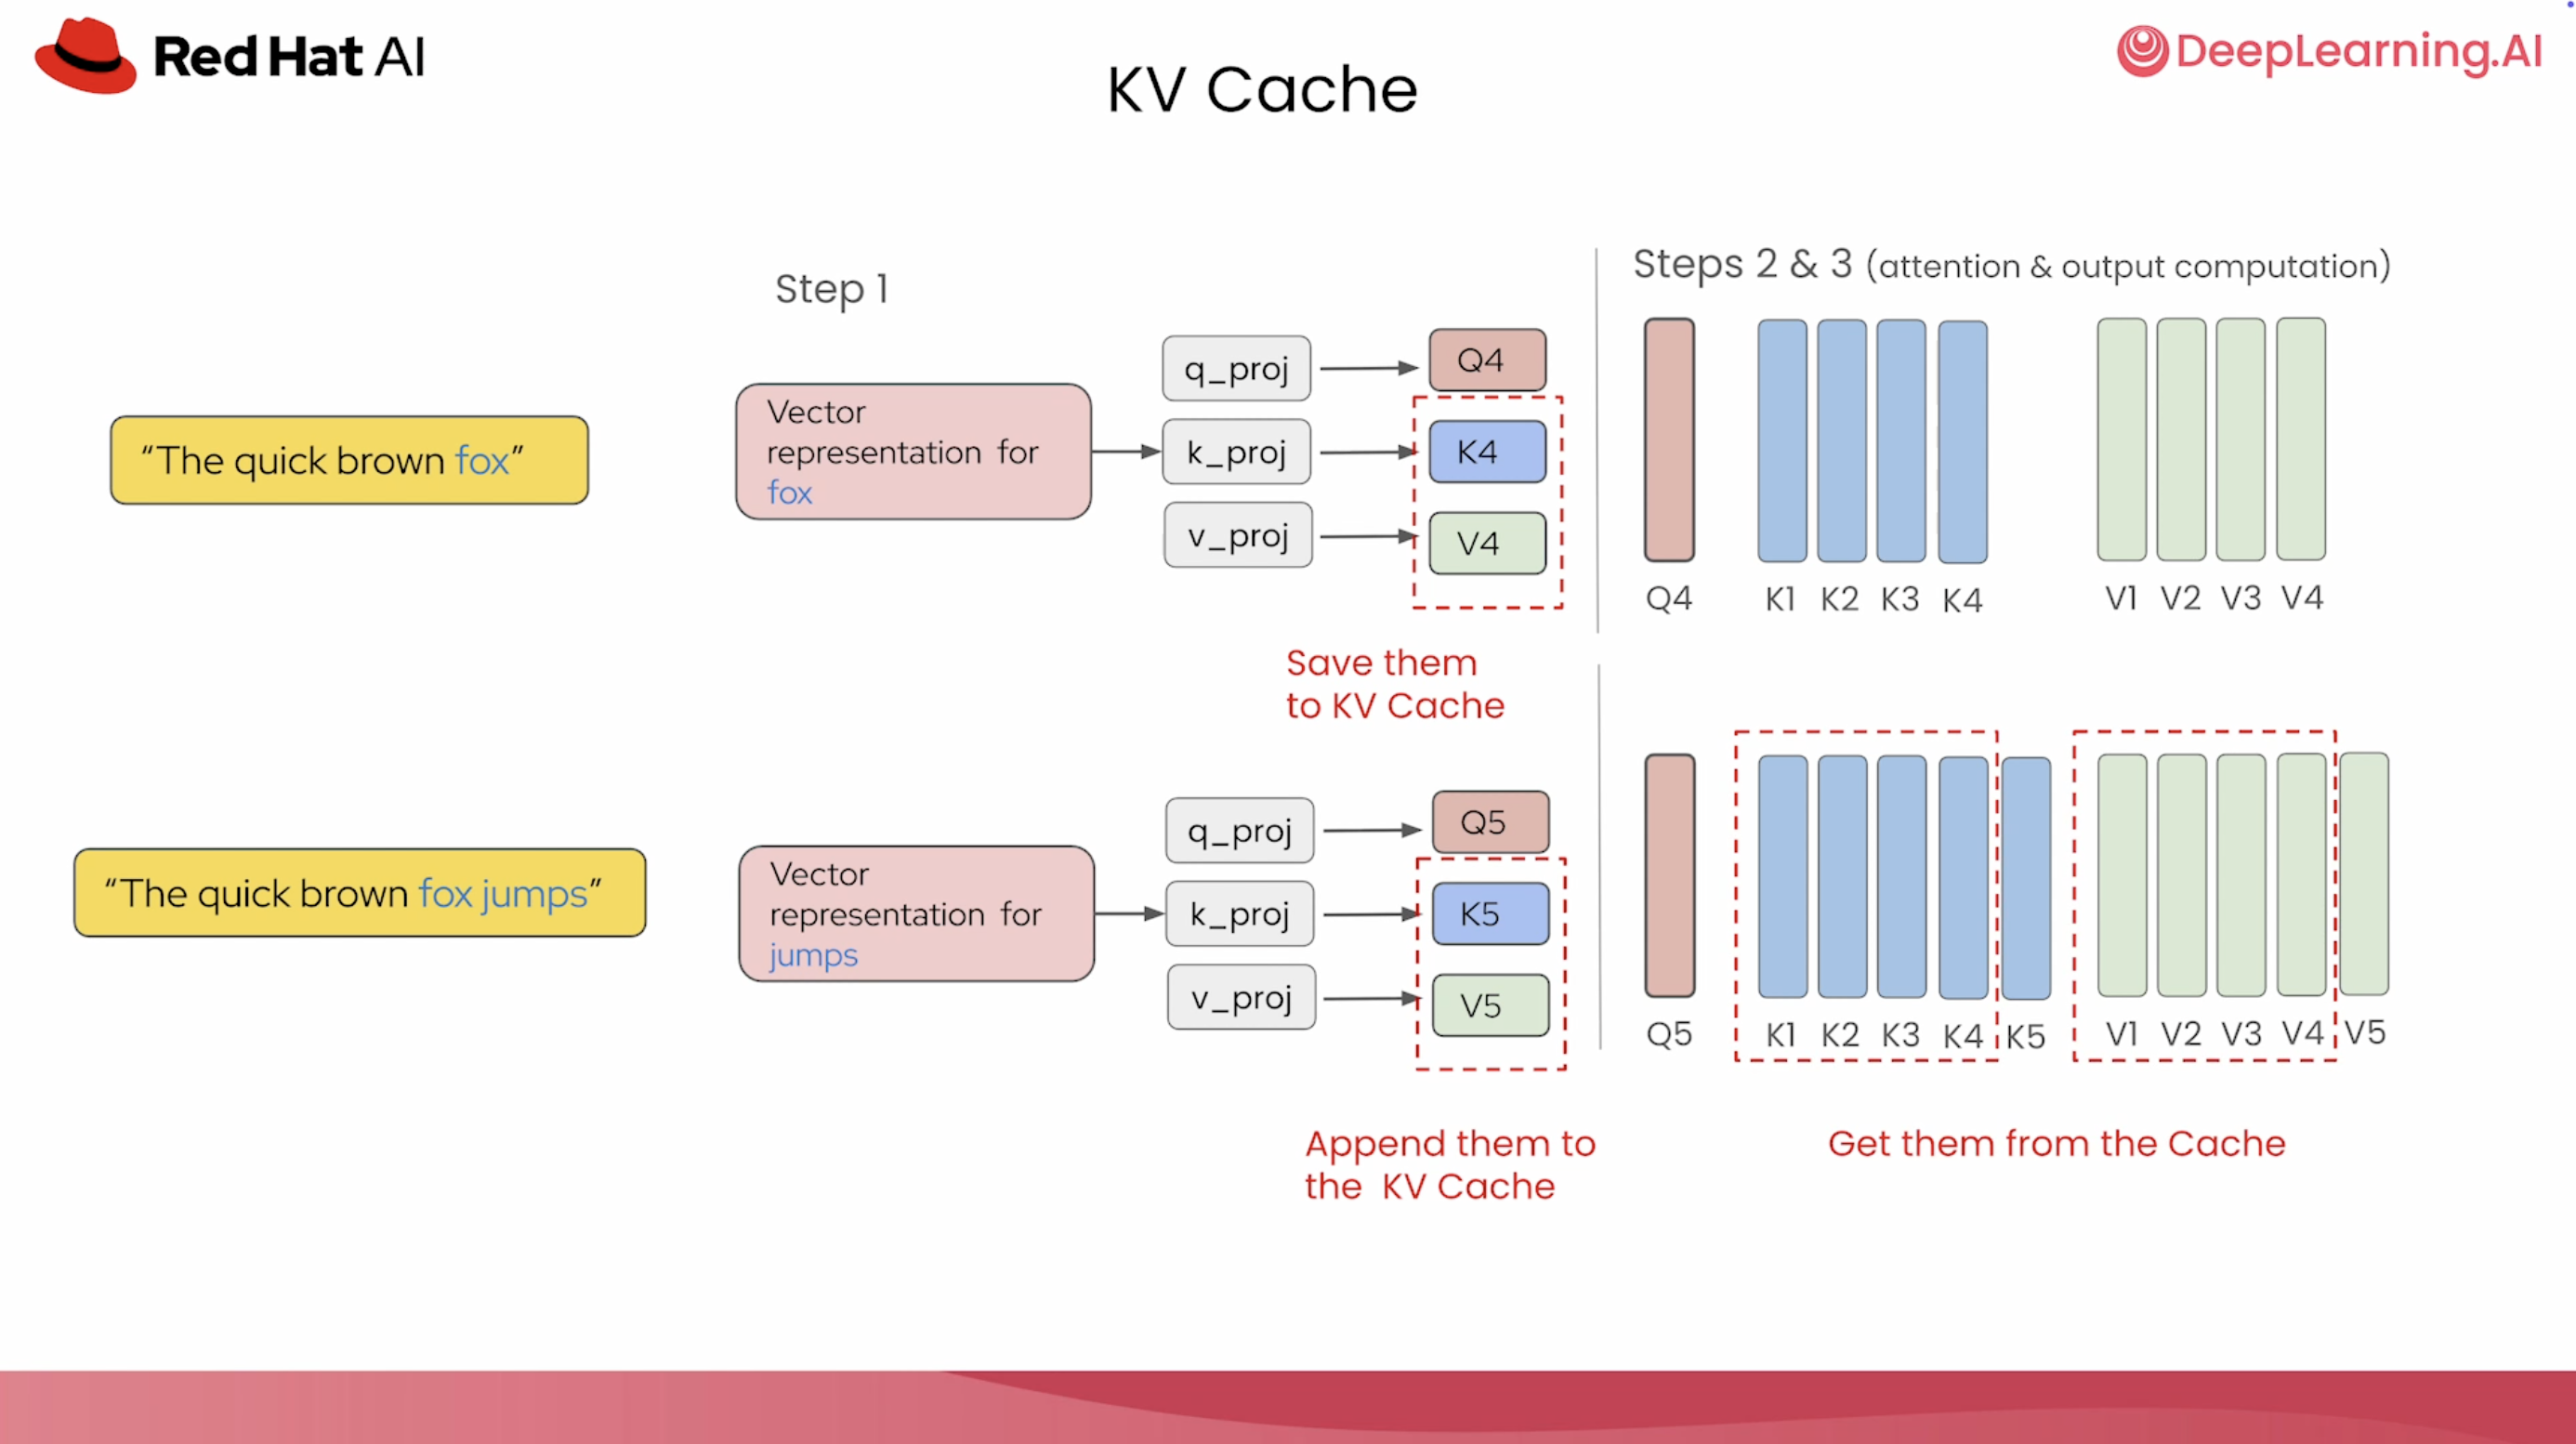
Fast & Efficient LLM Inference with vLLM: A New Course with ...
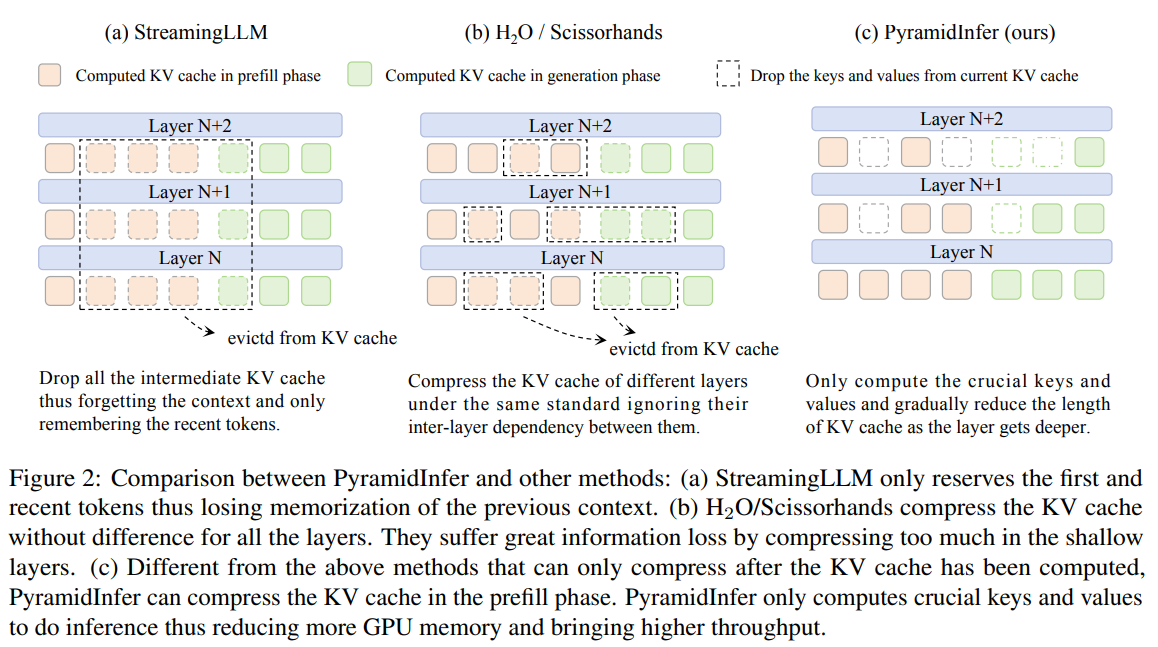
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
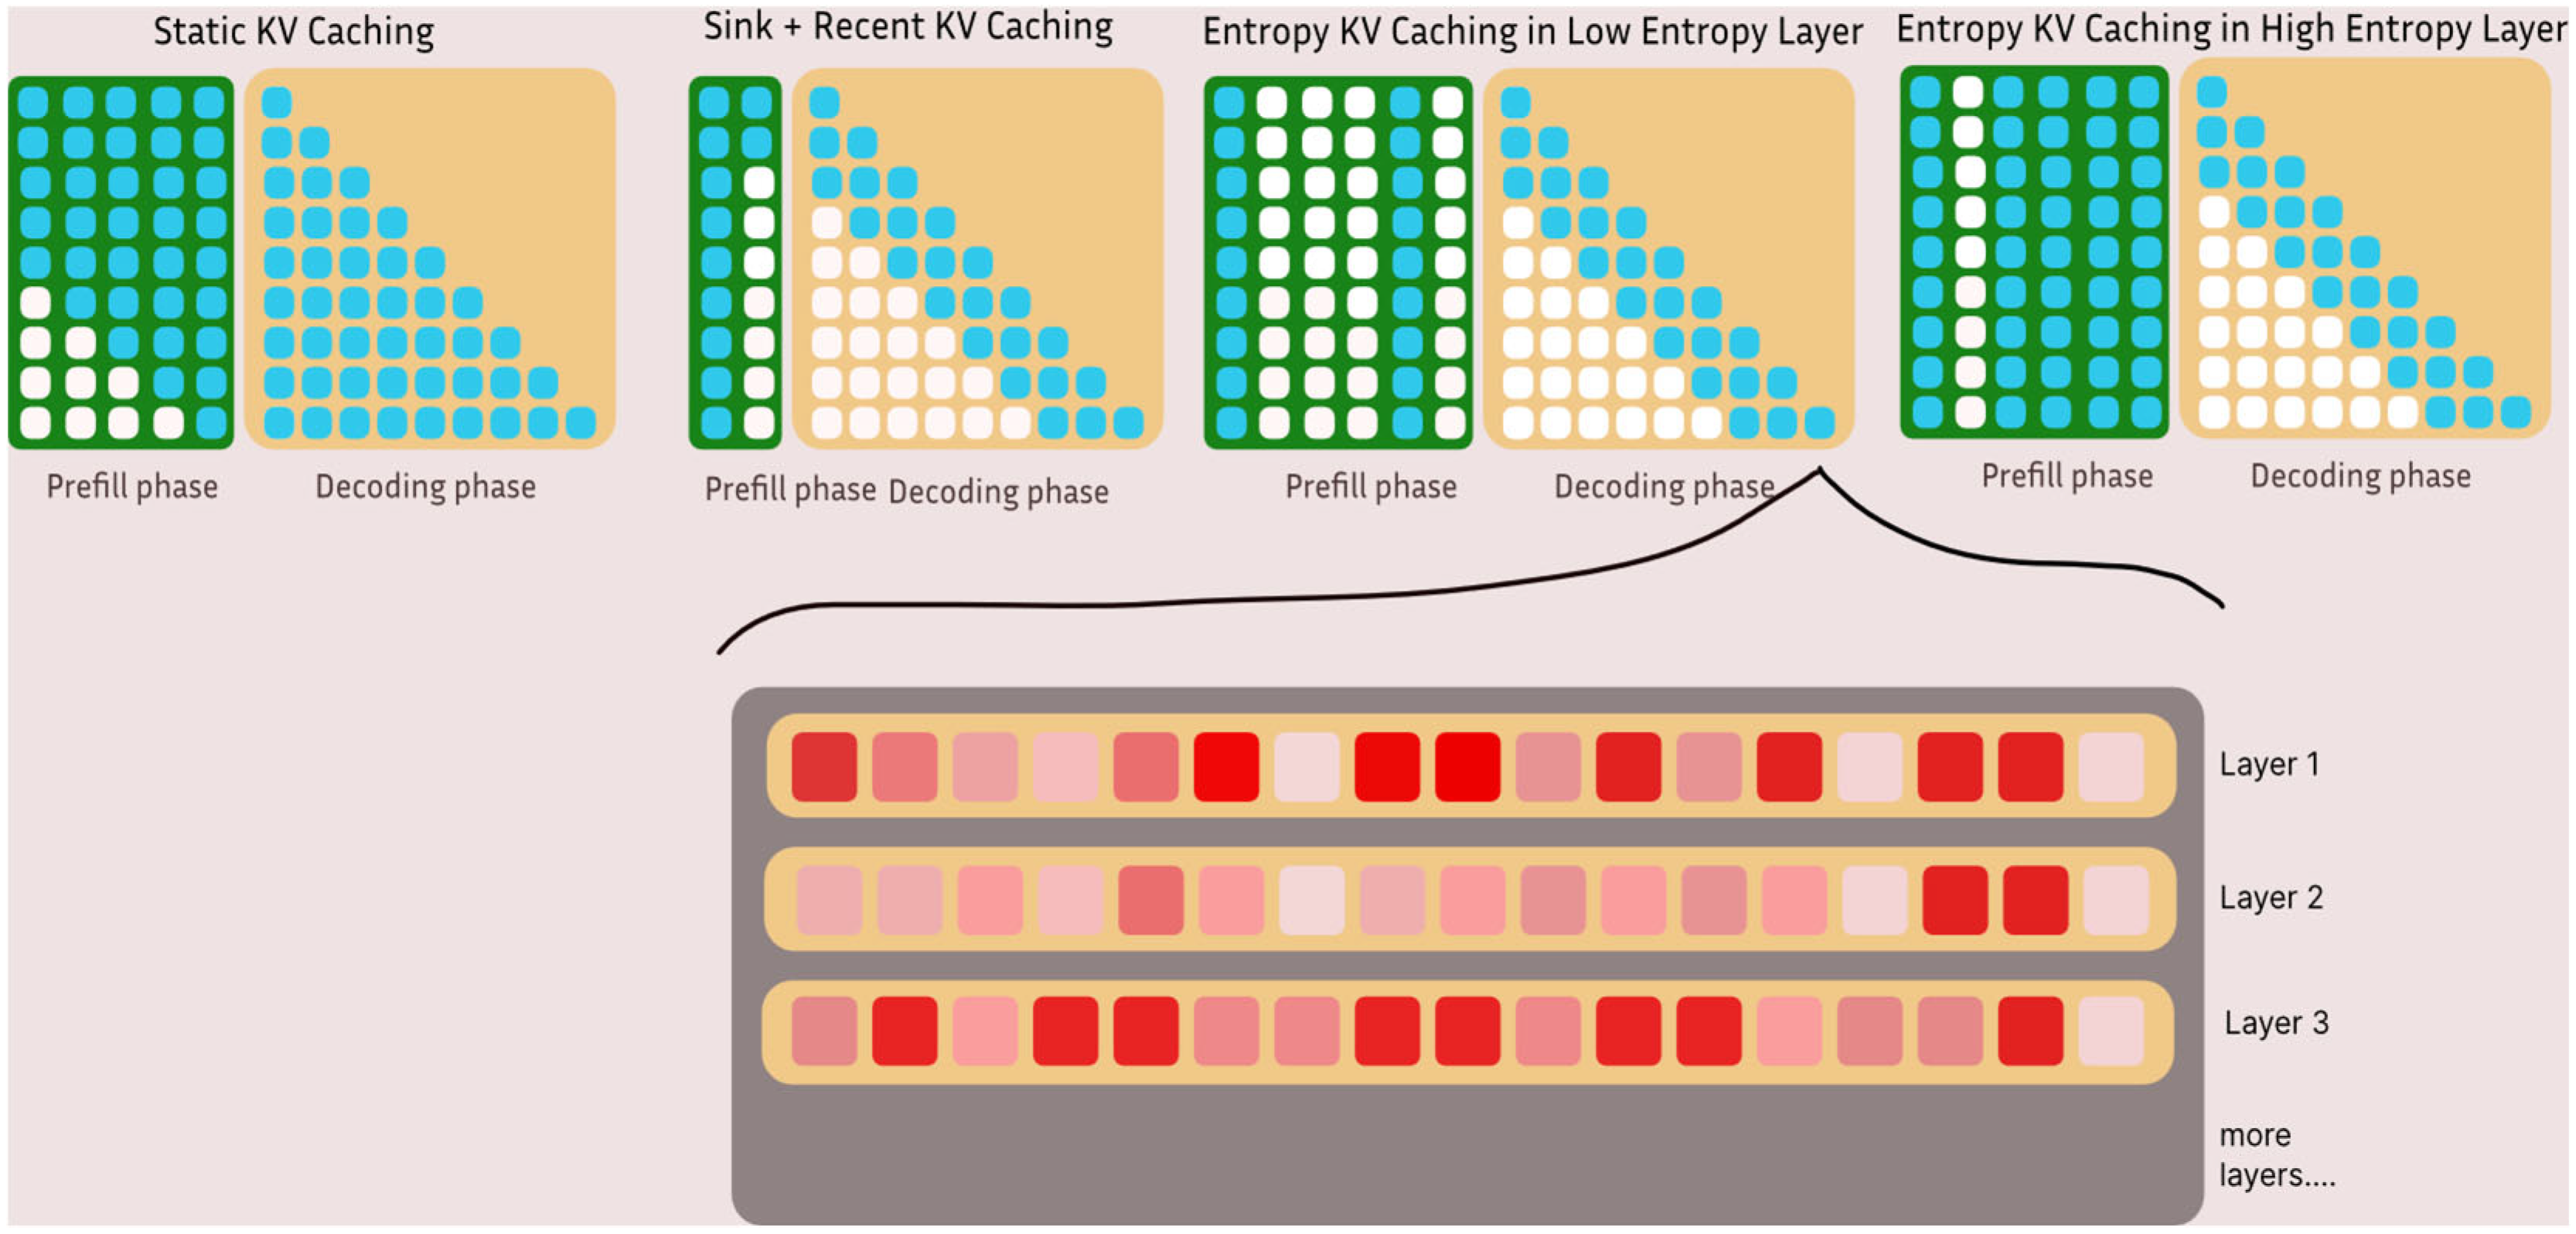
Entropy-Guided KV Caching for Efficient LLM Inference
Advertisement Space (336x280)

KV Cache Offload Accelerates LLM Inference - NADDOD Blog
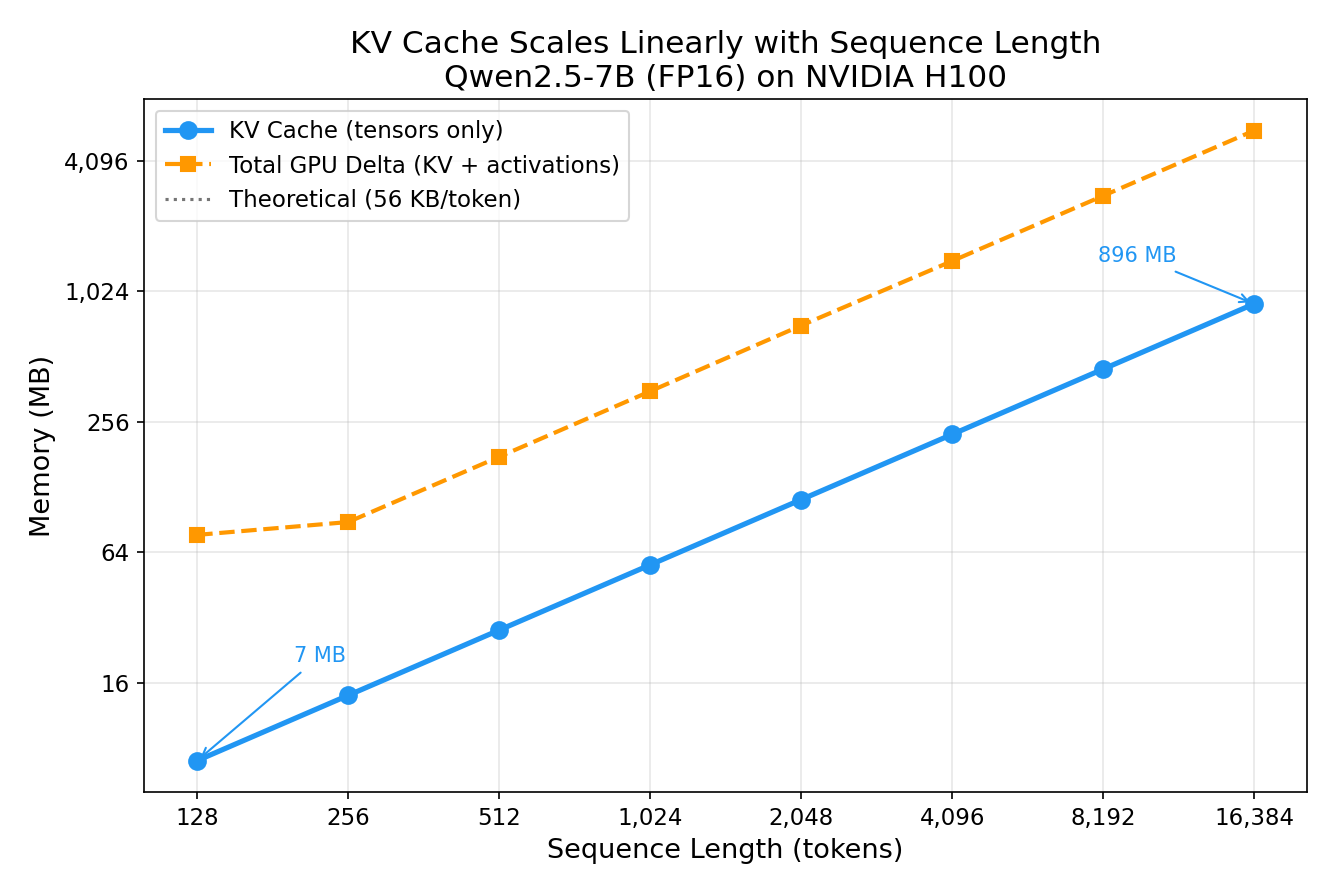
KV Cache Meets NVMe: The Key to Accelerating LLM Inference

KV Cache Reuse Is Quietly Reshaping LLM Inference Architecture | by ...
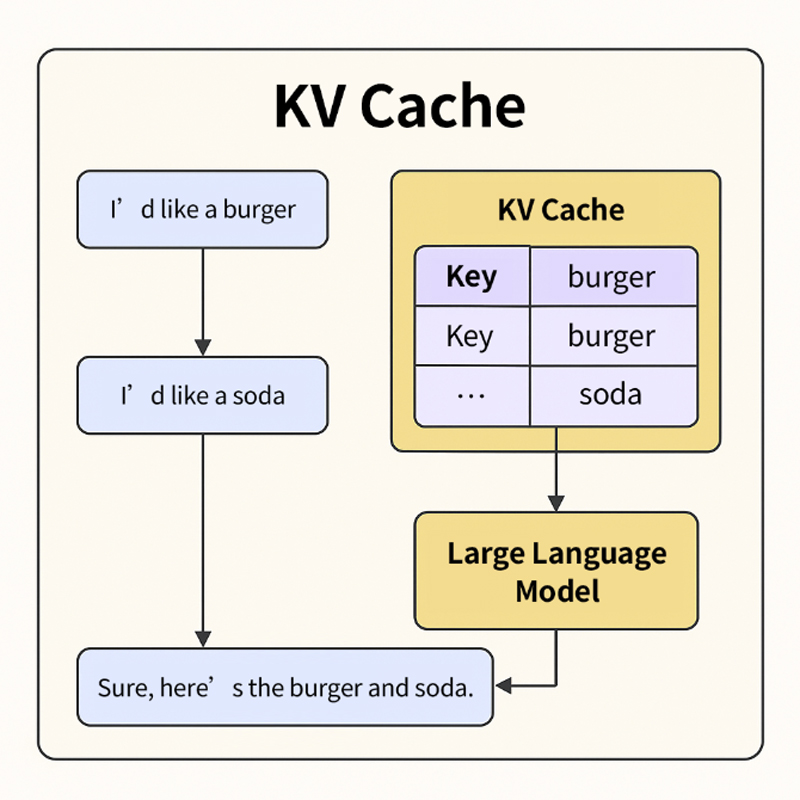
Understanding KV Cache in LLM Inference - Jingchao’s Website

Layer-Condensed KV Cache for Efficient Inference of Large Language ...
KV Cache Explained — Why LLM Inference Is Fast

LLM inference optimization: Architecture, KV cache and Flash attention ...

KV Cache in LLM Inference - Complete Technical Deep Dive - YouTube
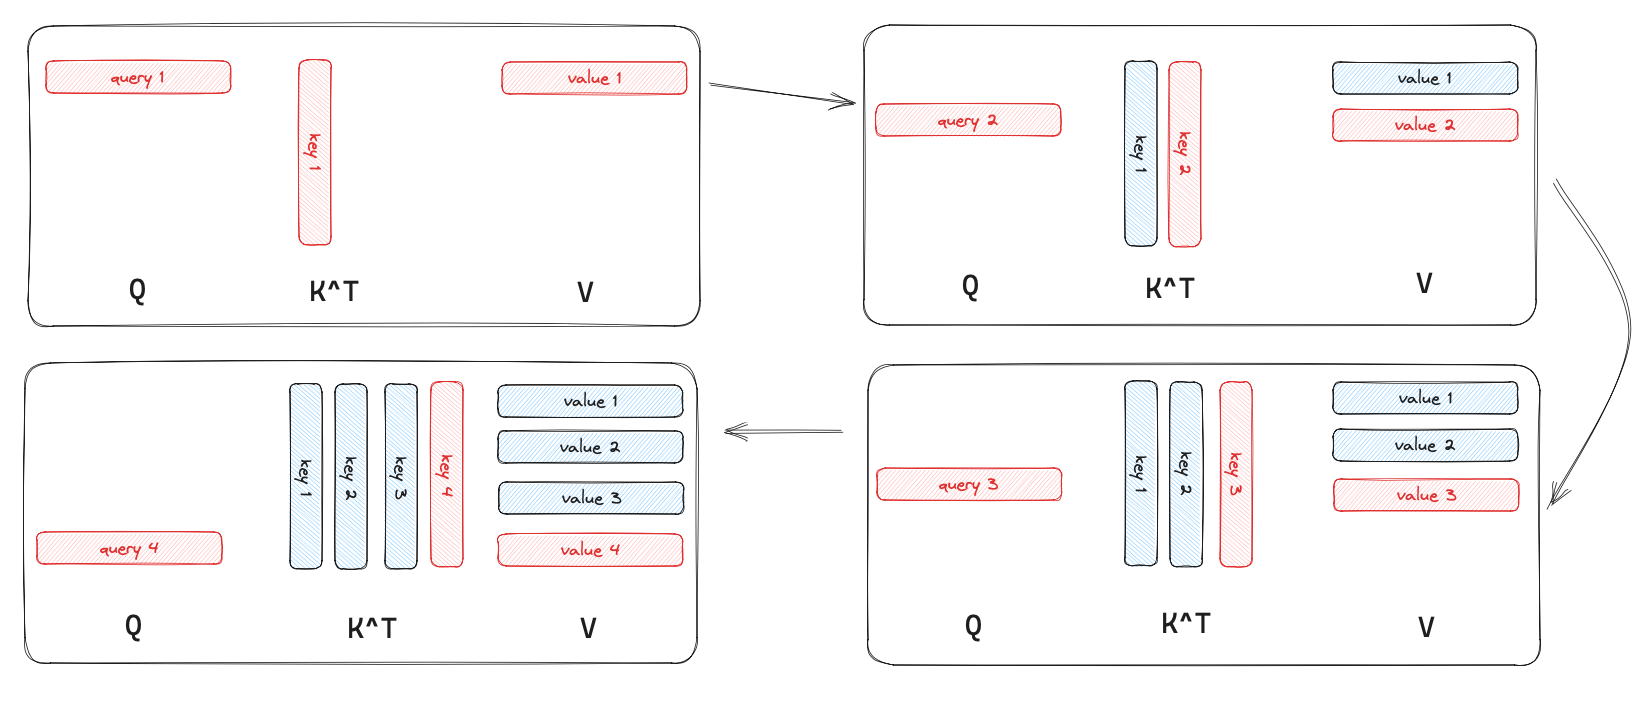
LLM inference optimization (1): KV Cache - MartinLwx's Blog
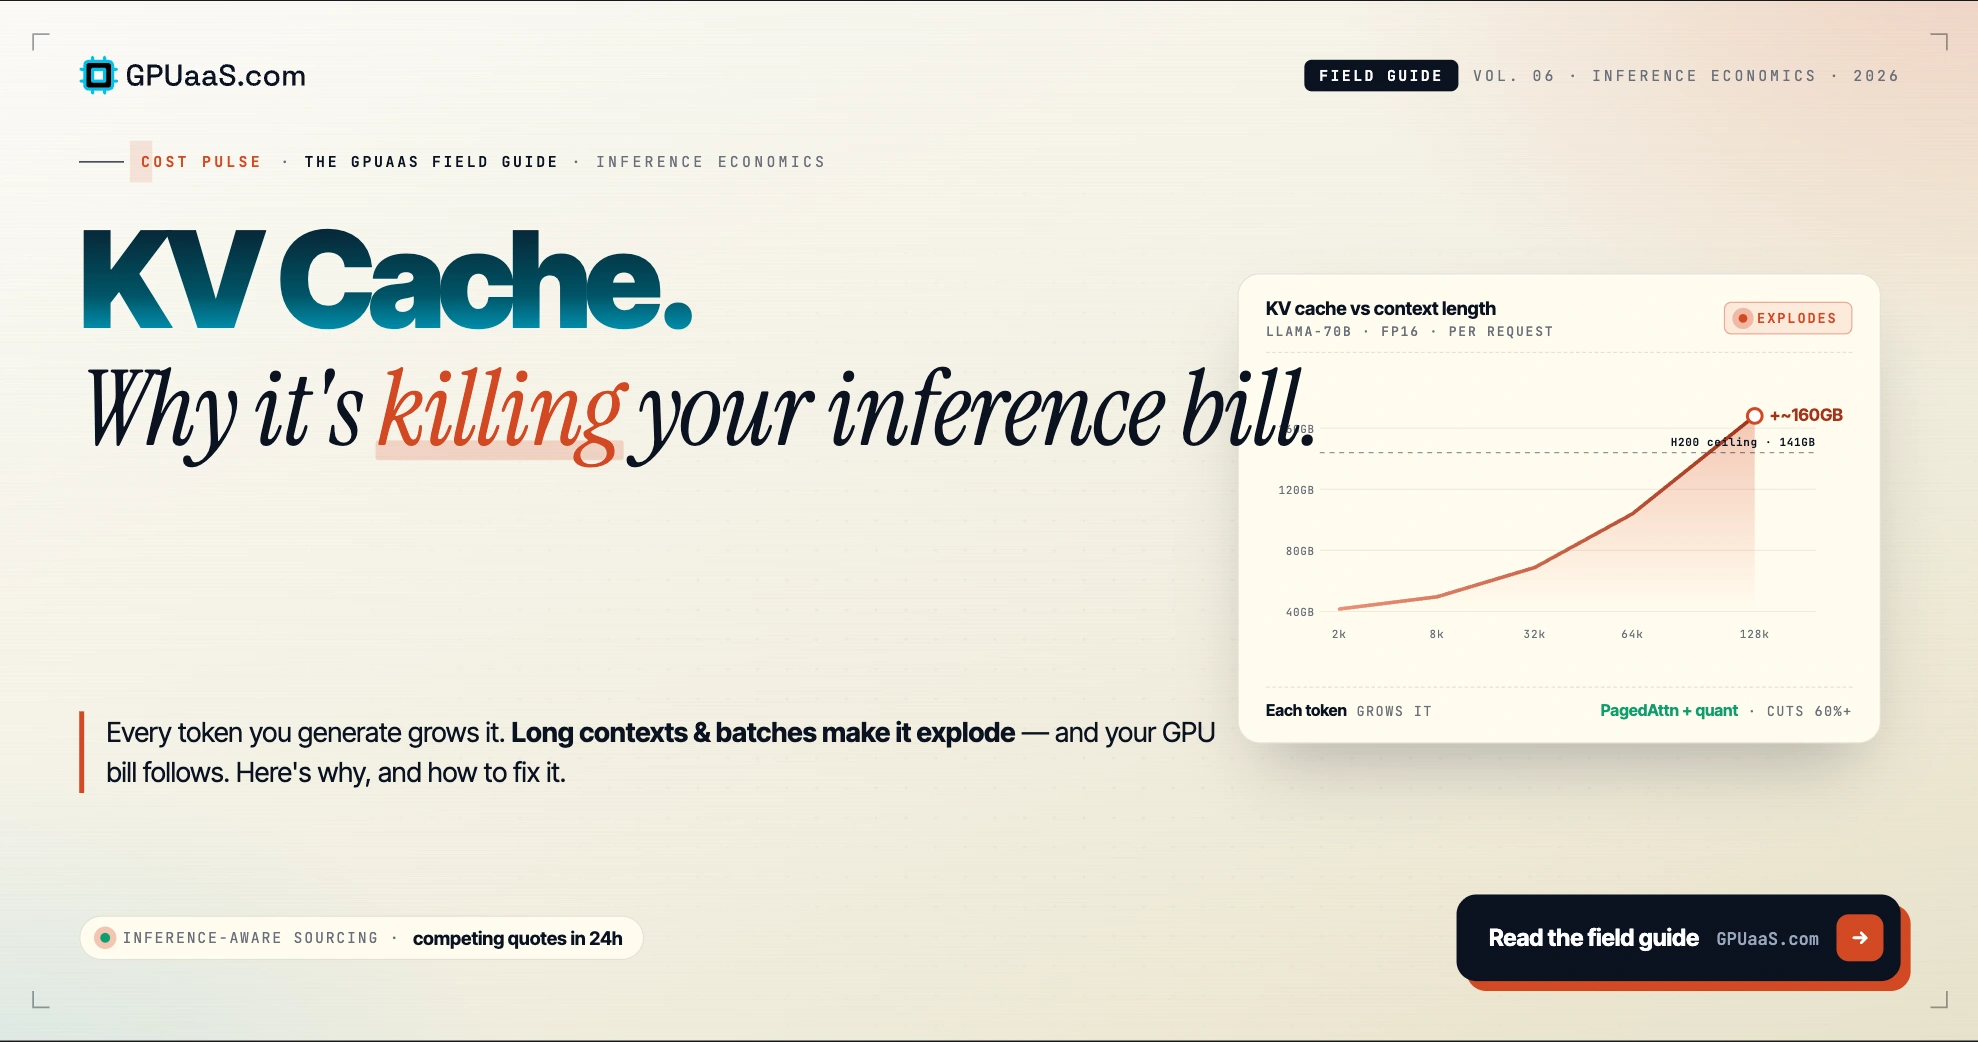
KV Cache Explained: Cut LLM Inference Costs 2026 | GPUaaS.com
Advertisement Space (336x280)

[论文评述] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...

LLM Inference Bottleneck: KV Cache vs Model Weights | Vinjam ...

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
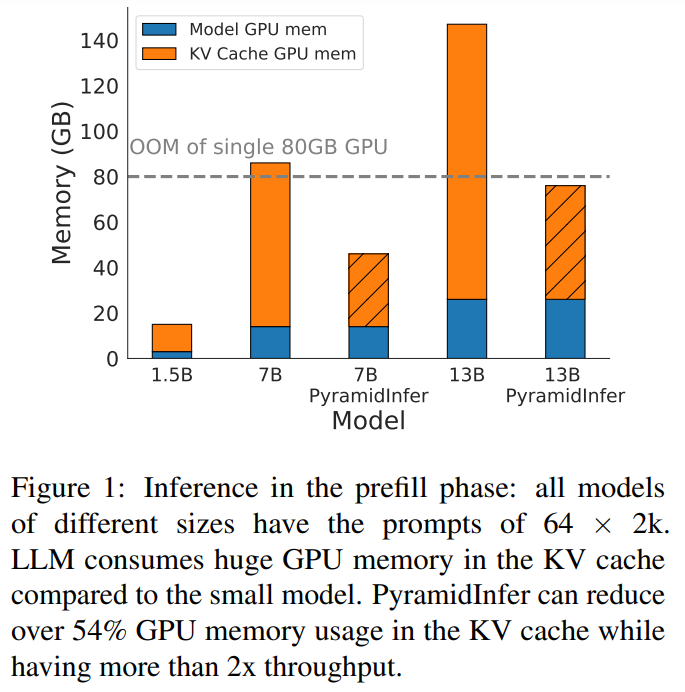
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
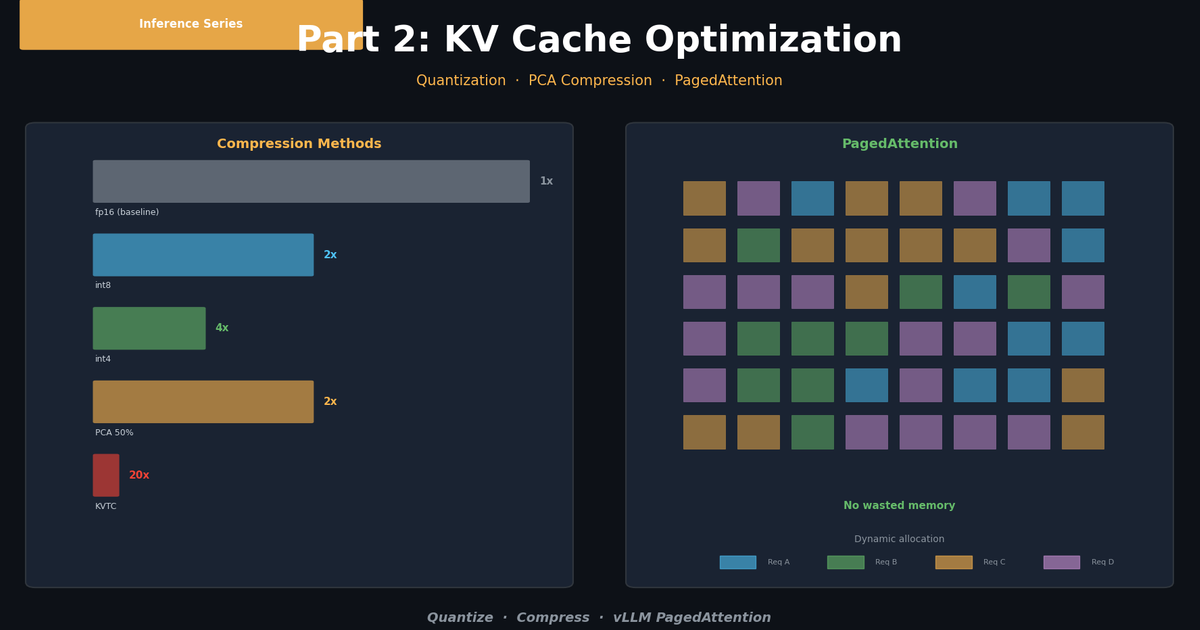
LLM Inference Optimization Part 2 — KV Cache Optimization | SOTAAZ Blog

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...