
Llada Vla Vision Language Diffusion Action Models

LLaDA-VLA: Vision Language Diffusion Action Models | AI Research Paper ...

Paper page - LLaDA-VLA: Vision Language Diffusion Action Models

LLaDA-VLA: Vision Language Diffusion Action Models

LLaDA-VLA: Vision Language Diffusion Action Models

LLaDA-VLA: Vision Language Diffusion Action Models - 智源社区论文

LLaDA-VLA: Vision Language Diffusion Action Models | AI Research Paper ...

LLaDA-VLA: Vision Language Diffusion Action Models | AI Research Paper ...
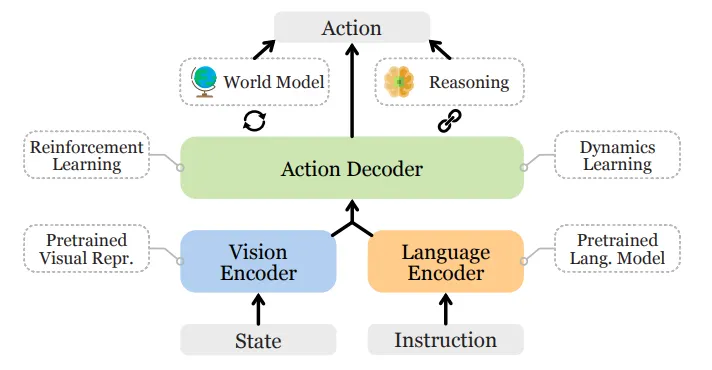
Vision Language Action Models - AI Robots Eidos
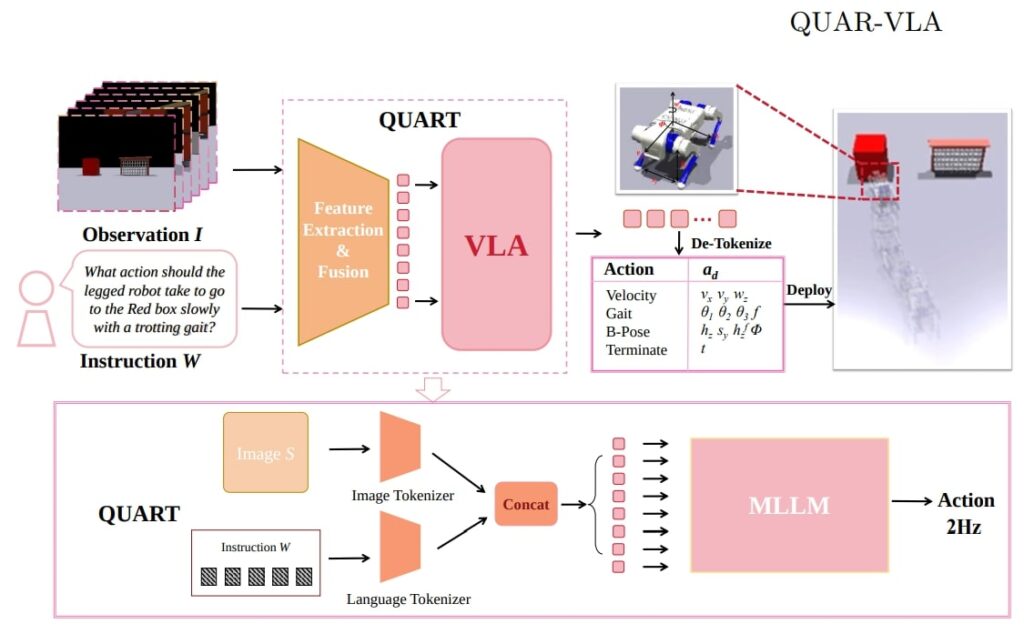
Vision Language Action Models (VLA) & Policies for Robots
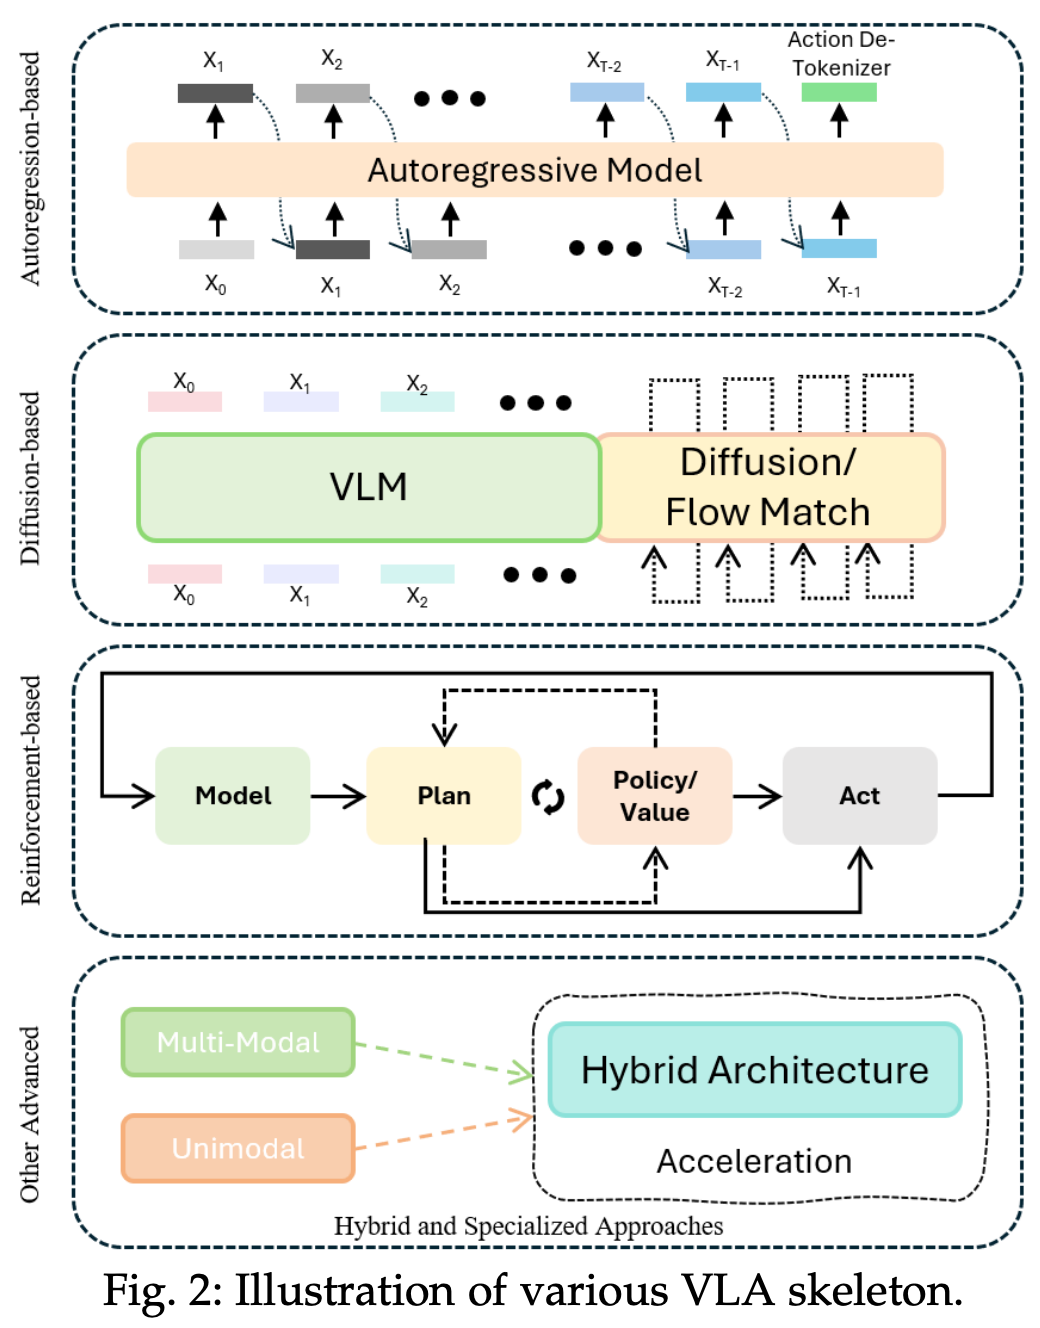
VLA 论文精读(三十四)Pure Vision Language Action (VLA) Models: A Comprehensive ...
Advertisement Space (300x250)
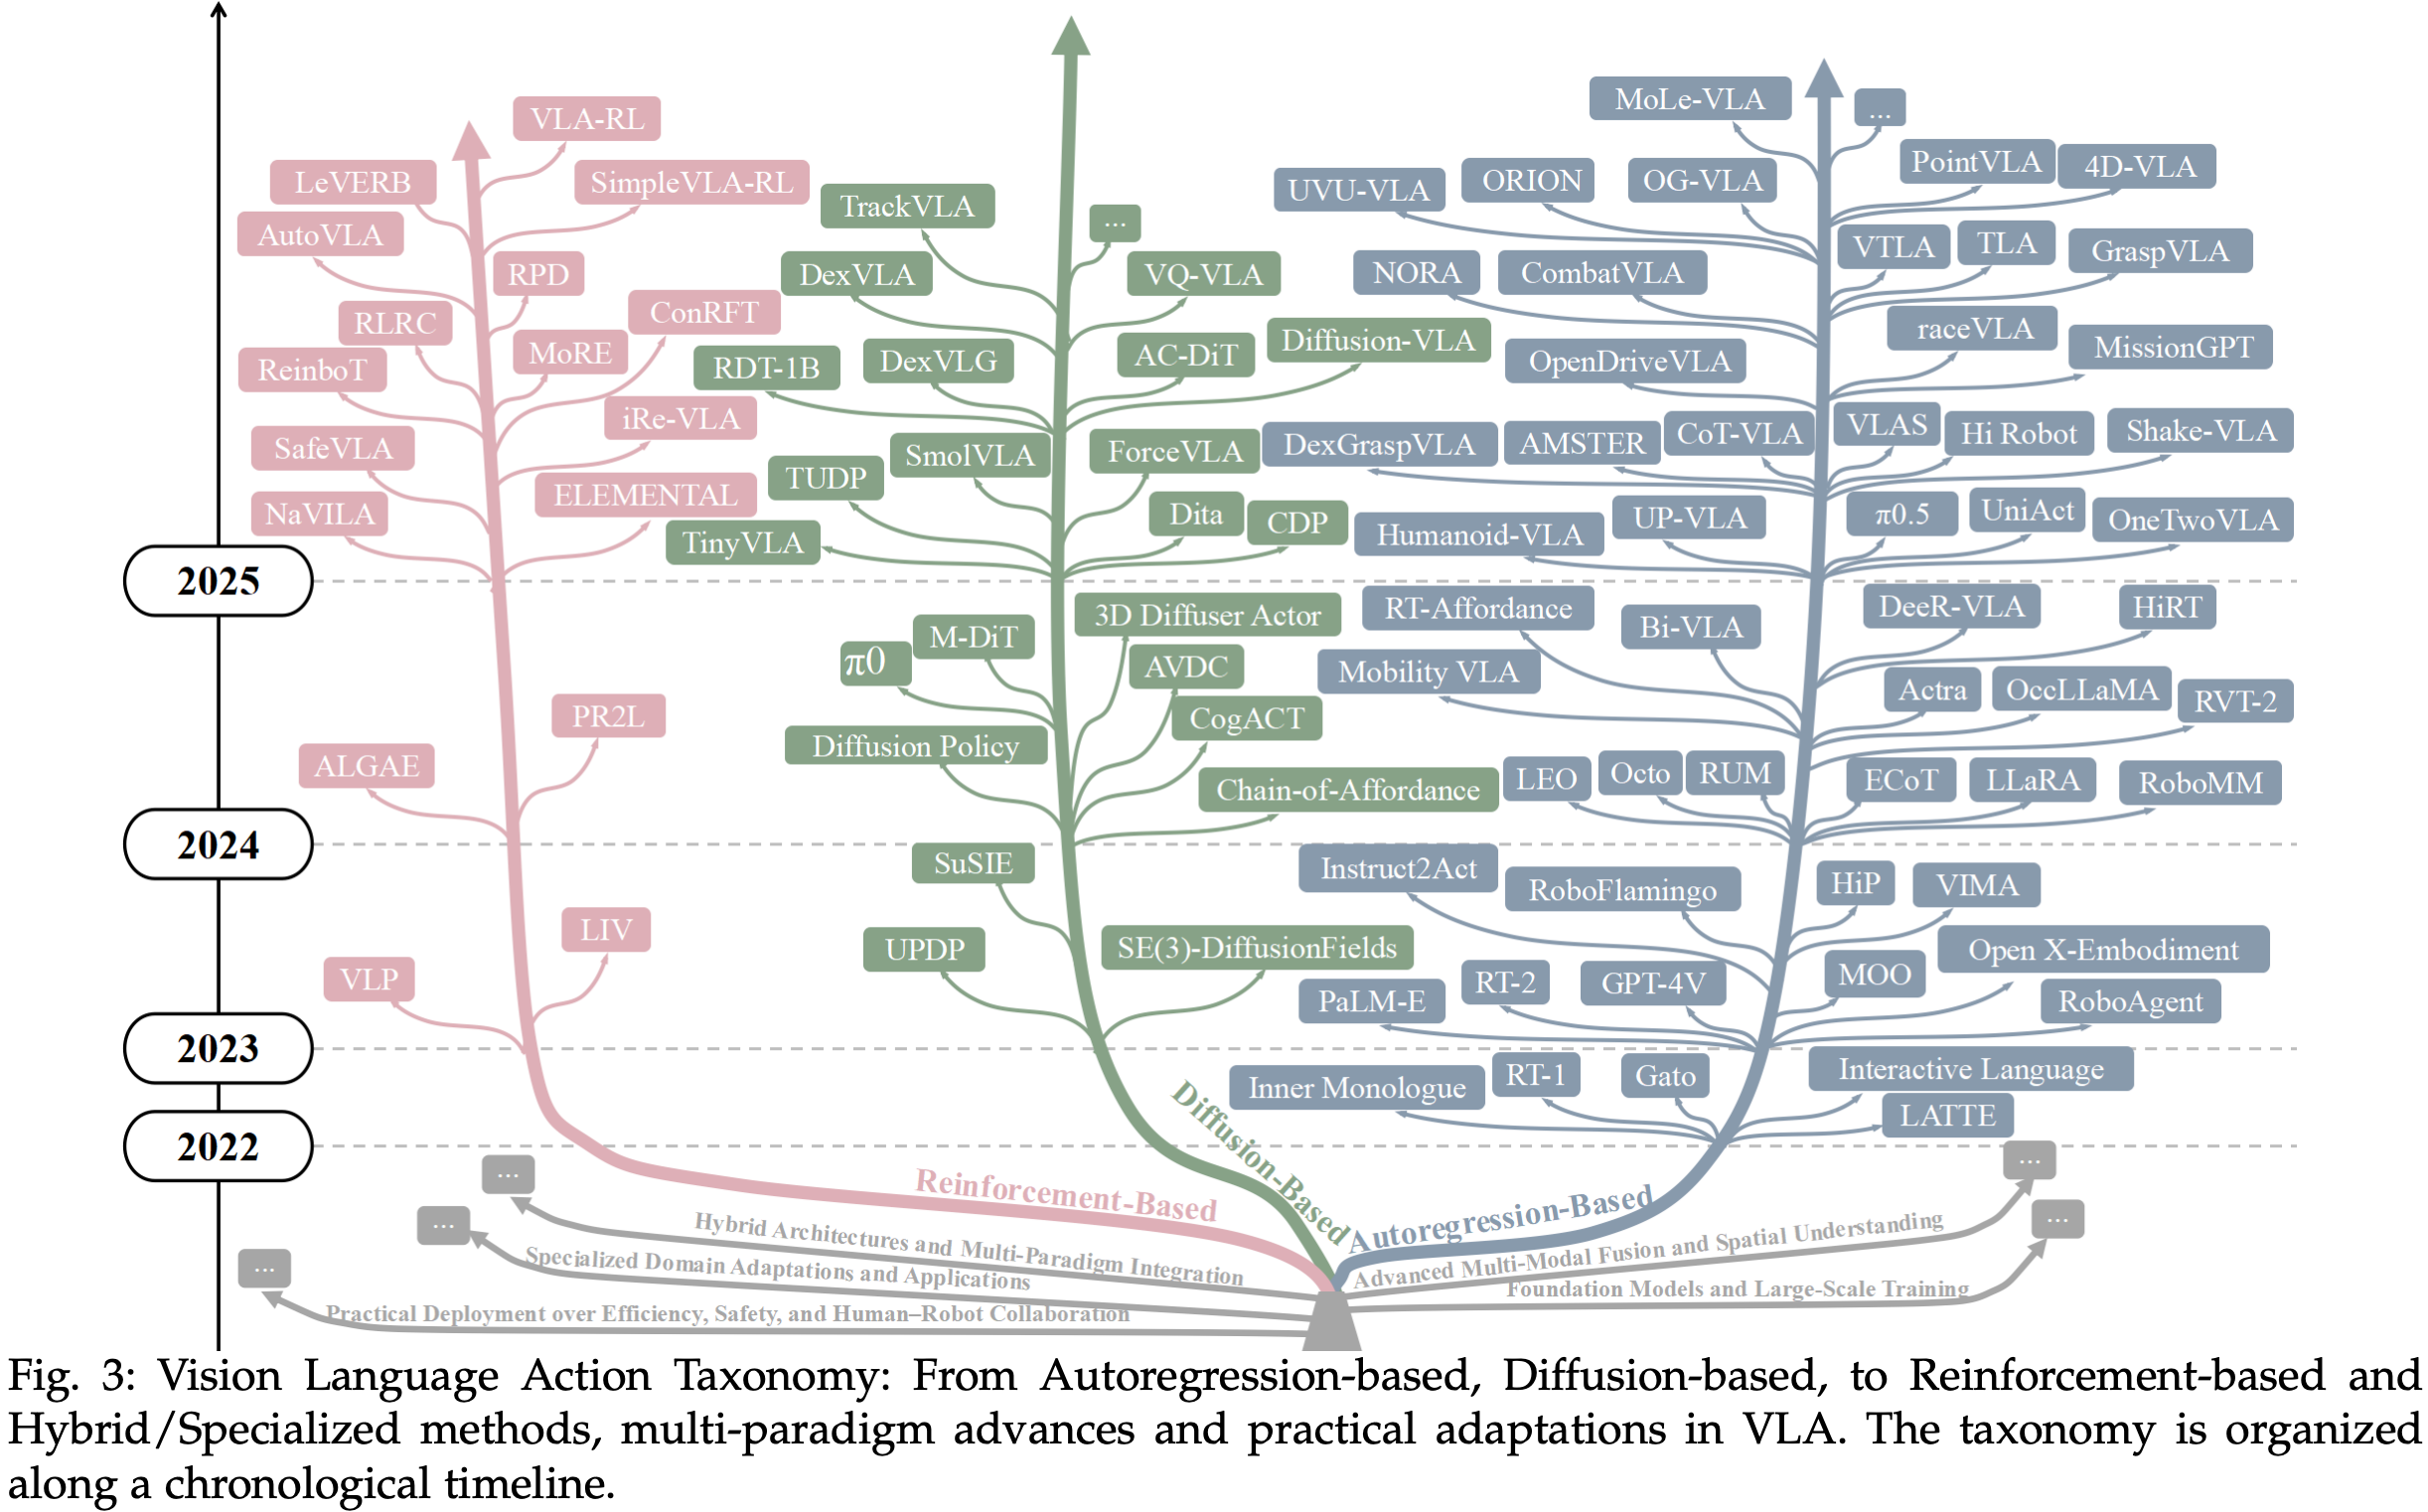
VLA 论文精读(三十四)Pure Vision Language Action (VLA) Models: A Comprehensive ...
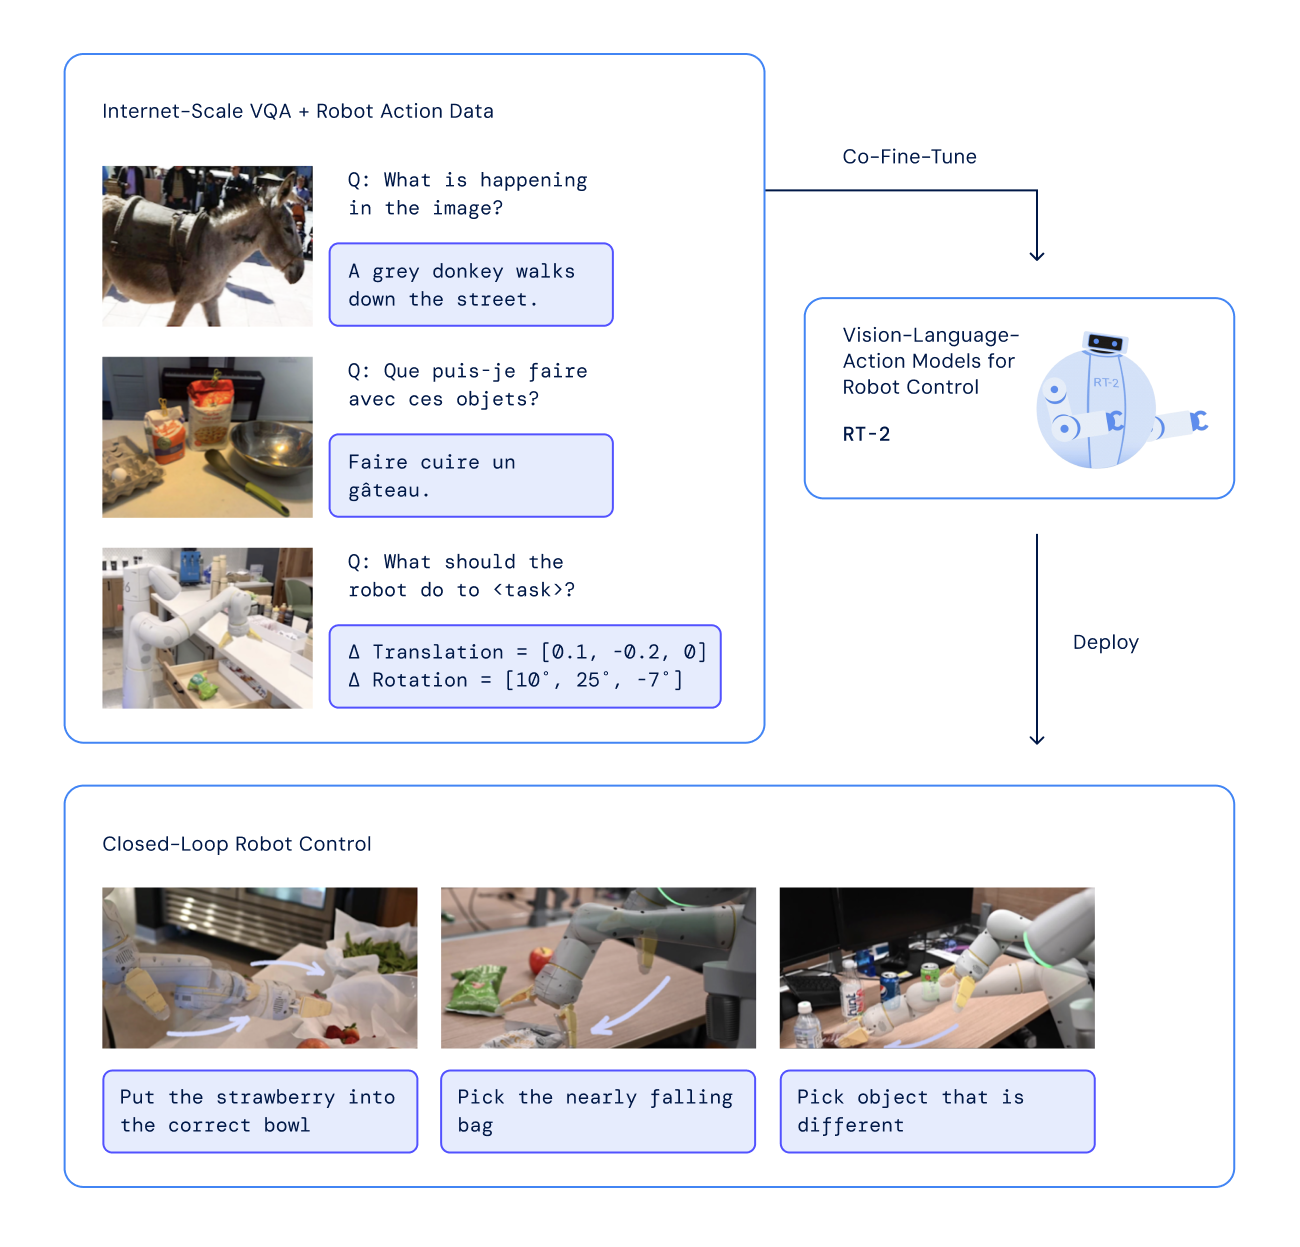
Vision Language Action Models (VLA) & Policies for Robots

Vision Language Action Models | PDF | Cognitive Science
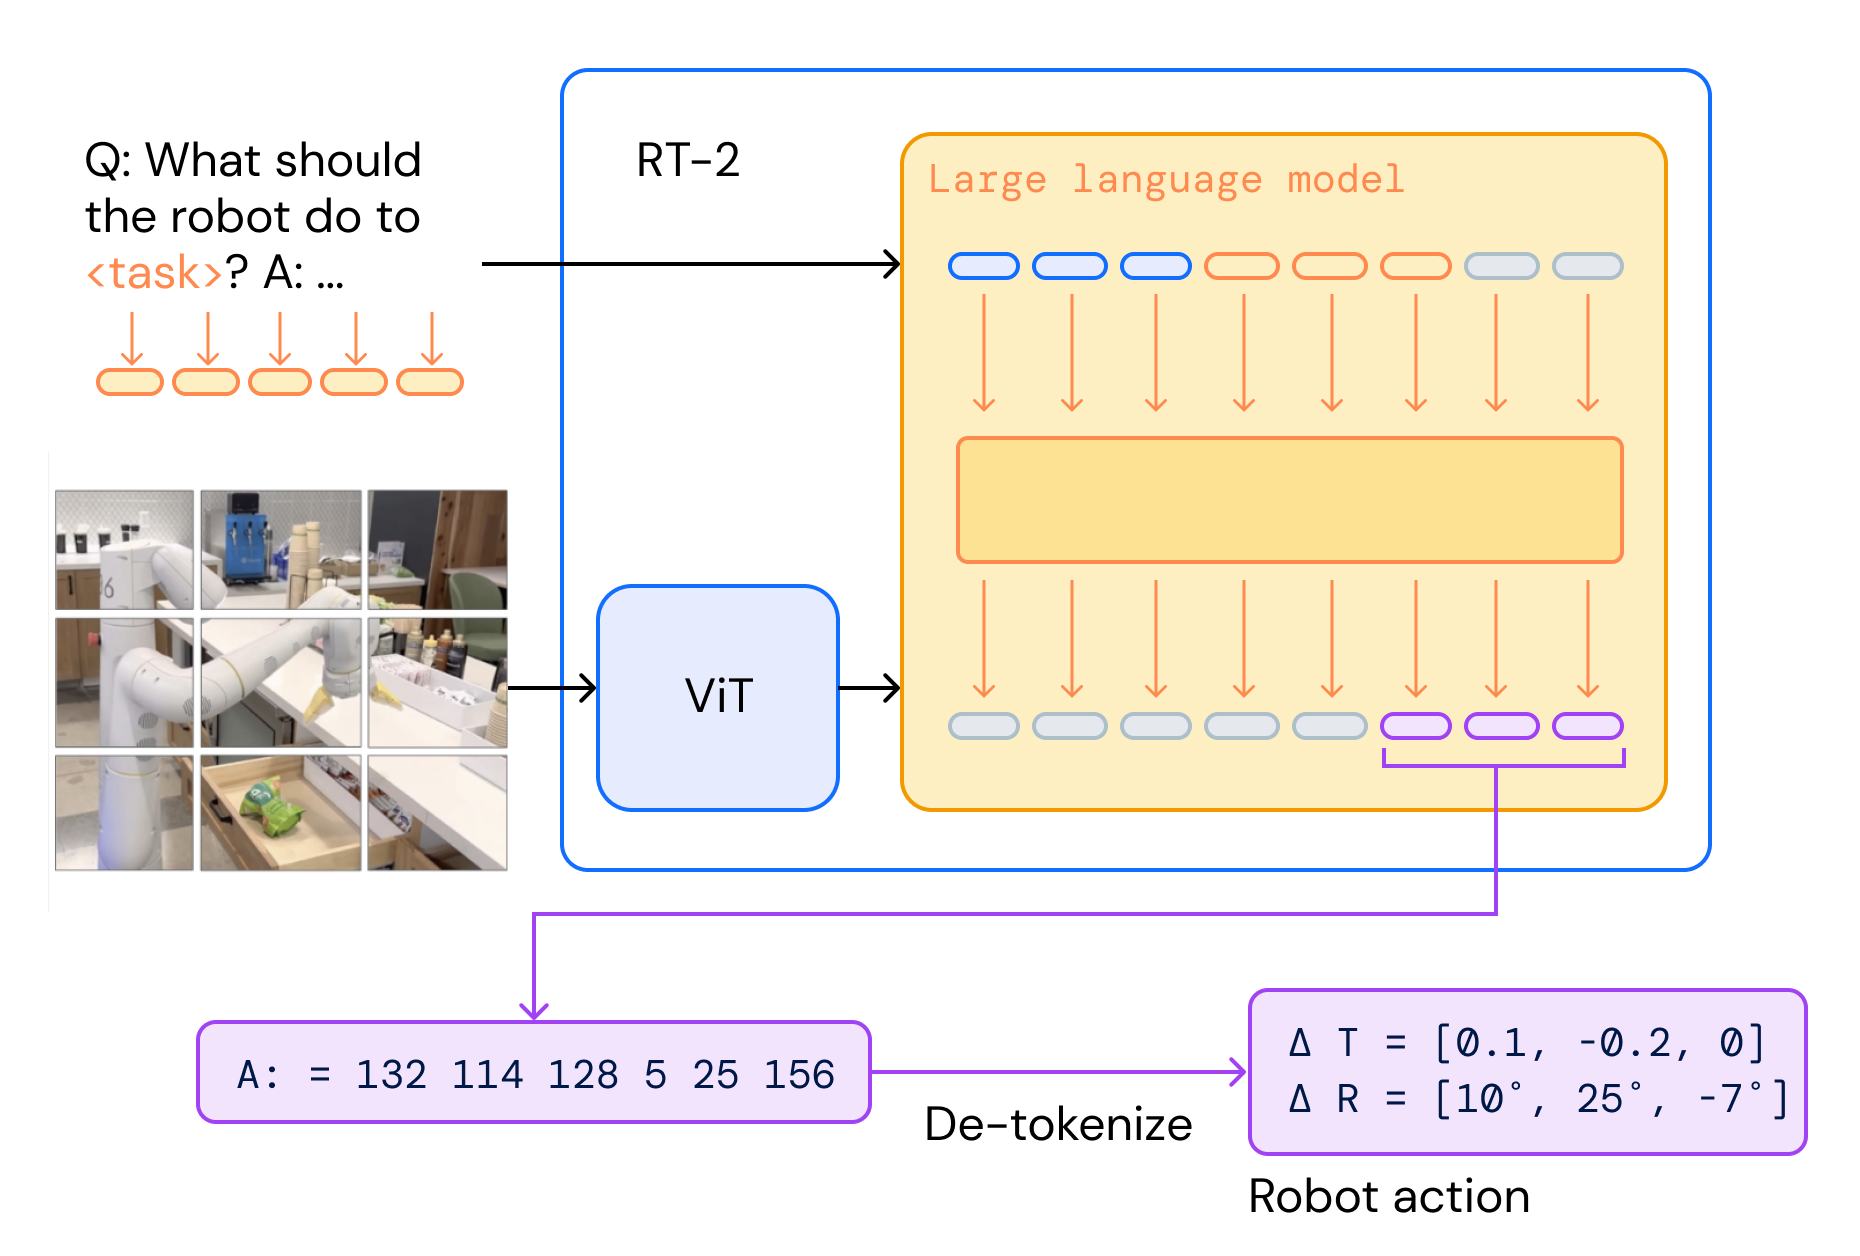
Vision Language Action Models (VLA) & Policies for Robots
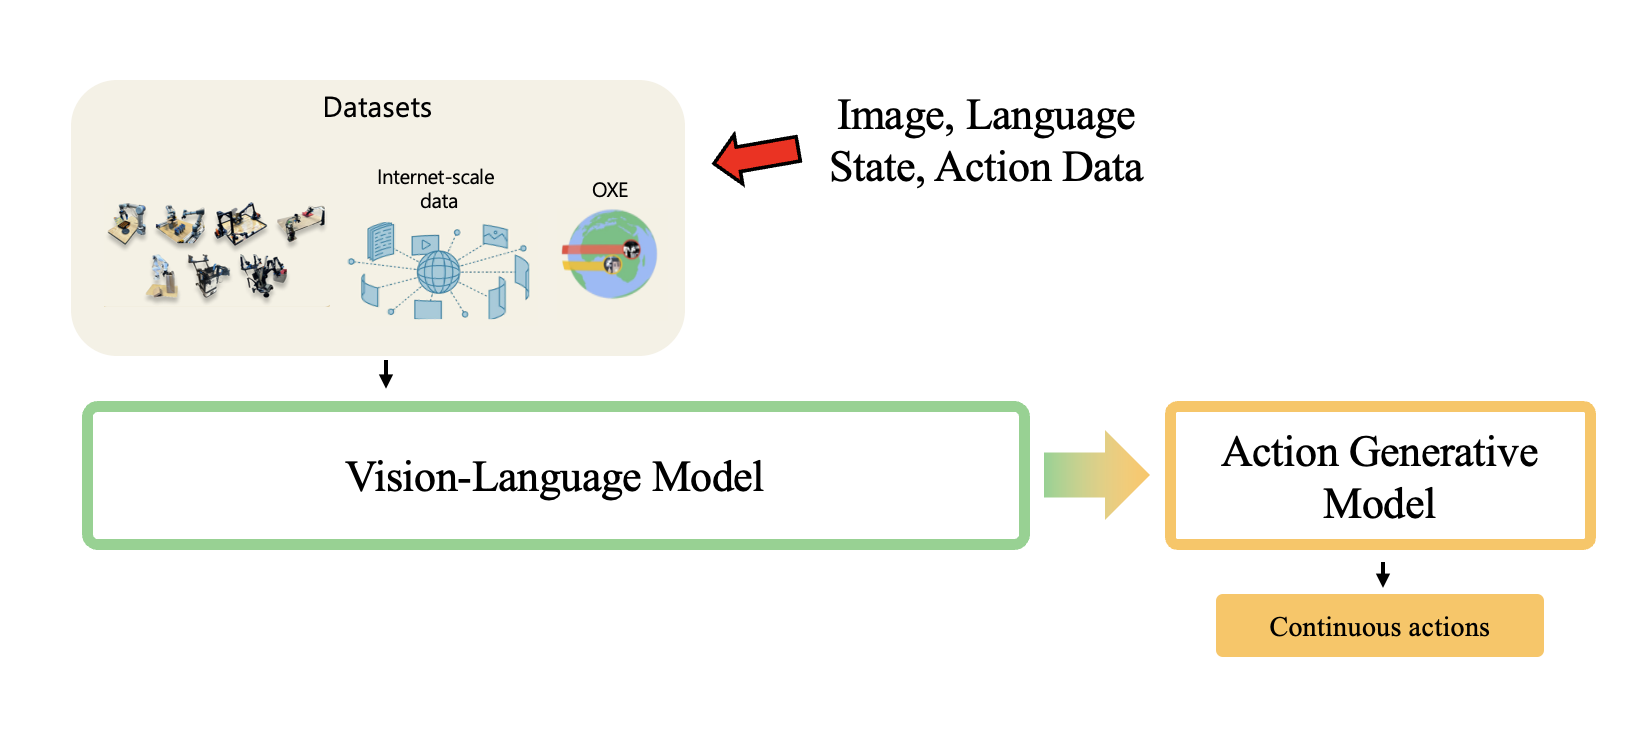
VLA (Vision Language Action model)란?

A Comprehensive Guide to Vision Language Models (VLMs)

VLA最新综述万字解析:Pure Vision Language Action (VLA) Models:A Comprehensive ...

Paper page - LLaDA-V: Large Language Diffusion Models with Visual ...
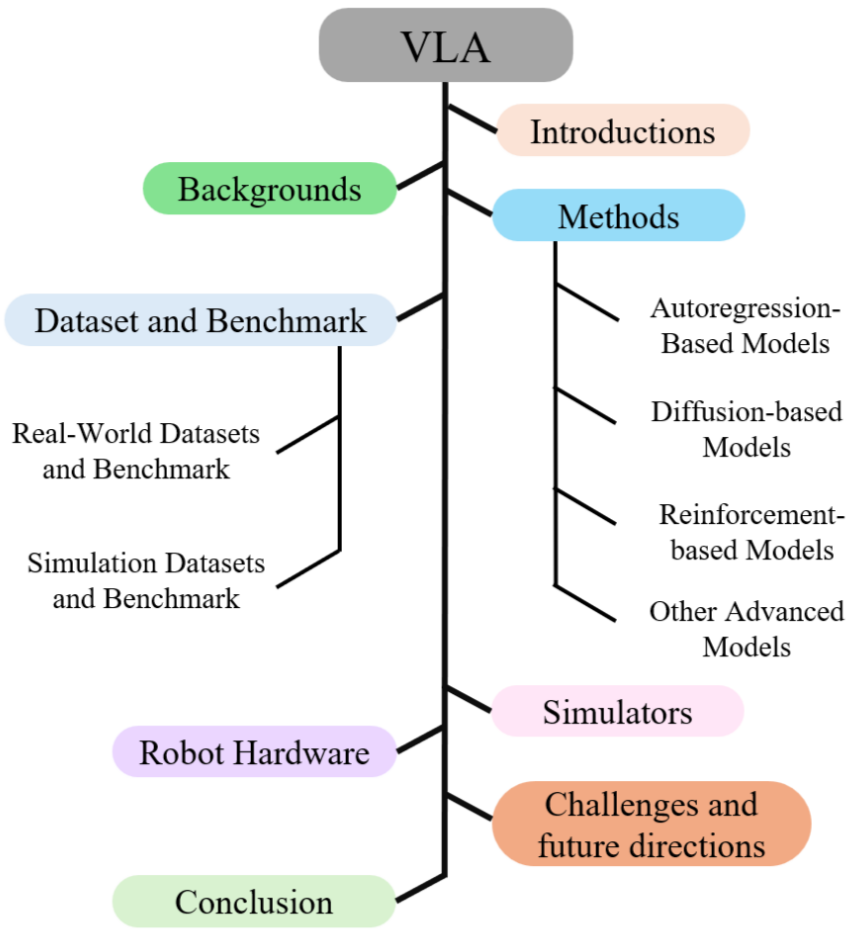
[논문 리뷰] Pure Vision Language Action (VLA) Models: A Comprehensive Survey

(PDF) LLaDA-V: Large Language Diffusion Models with Visual Instruction ...
Advertisement Space (336x280)
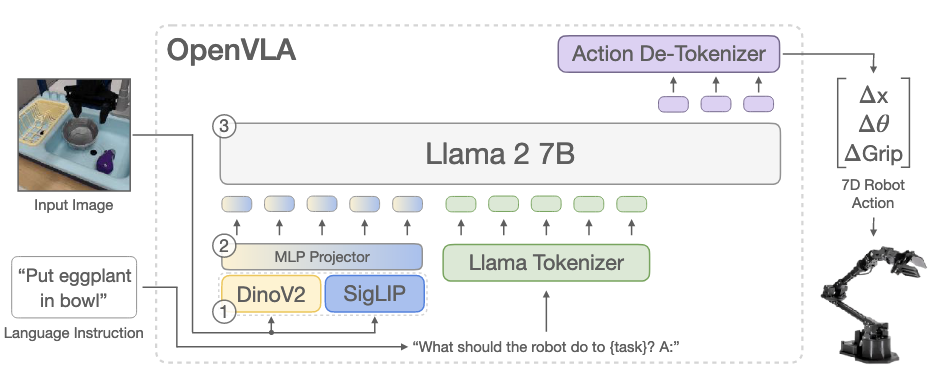
VLA (Vision Language Action model)란?

Language Diffusion

VLA 论文精读(三十六)Efficient Vision-Language-Action Models for Embodied ...

VLA 论文精读(三十六)Efficient Vision-Language-Action Models for Embodied ...
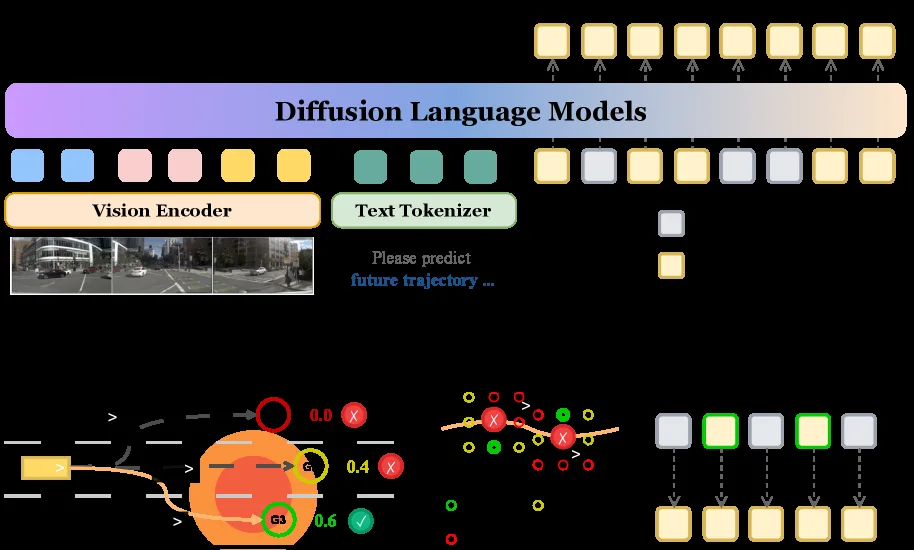
Discrete Diffusion for Reflective Vision-Language-Action Models in ...

Vision Language Modelと完全自動運転AIの最新動向 - Speaker Deck
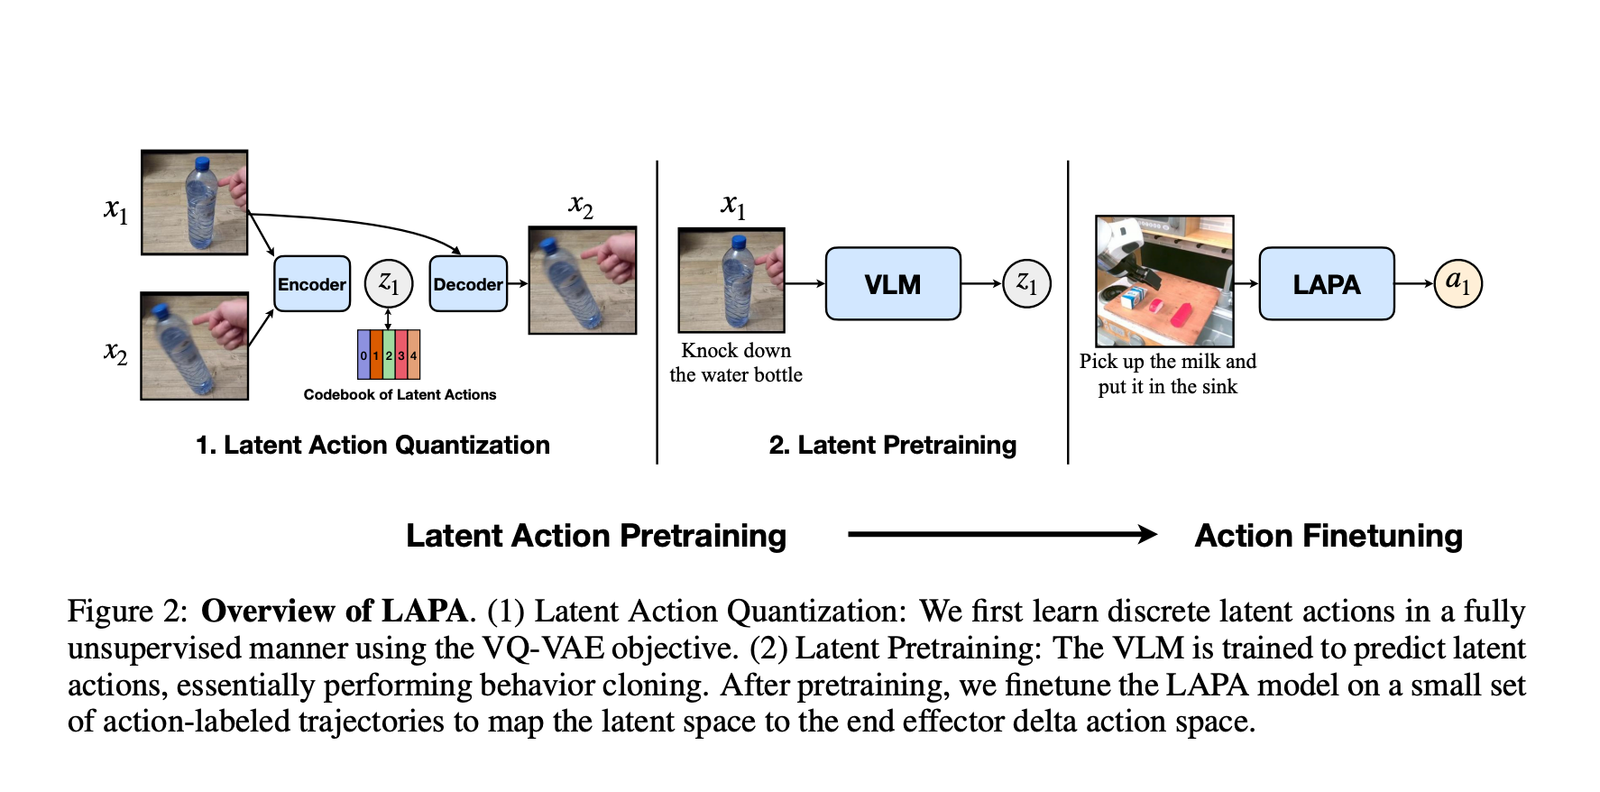
Latent Action Pretraining for General Action models (LAPA): An ...

Revolutionizing Autoregressive Models with LLaDA - Fusion Chat

VLA 论文精读(三十六)Efficient Vision-Language-Action Models for Embodied ...
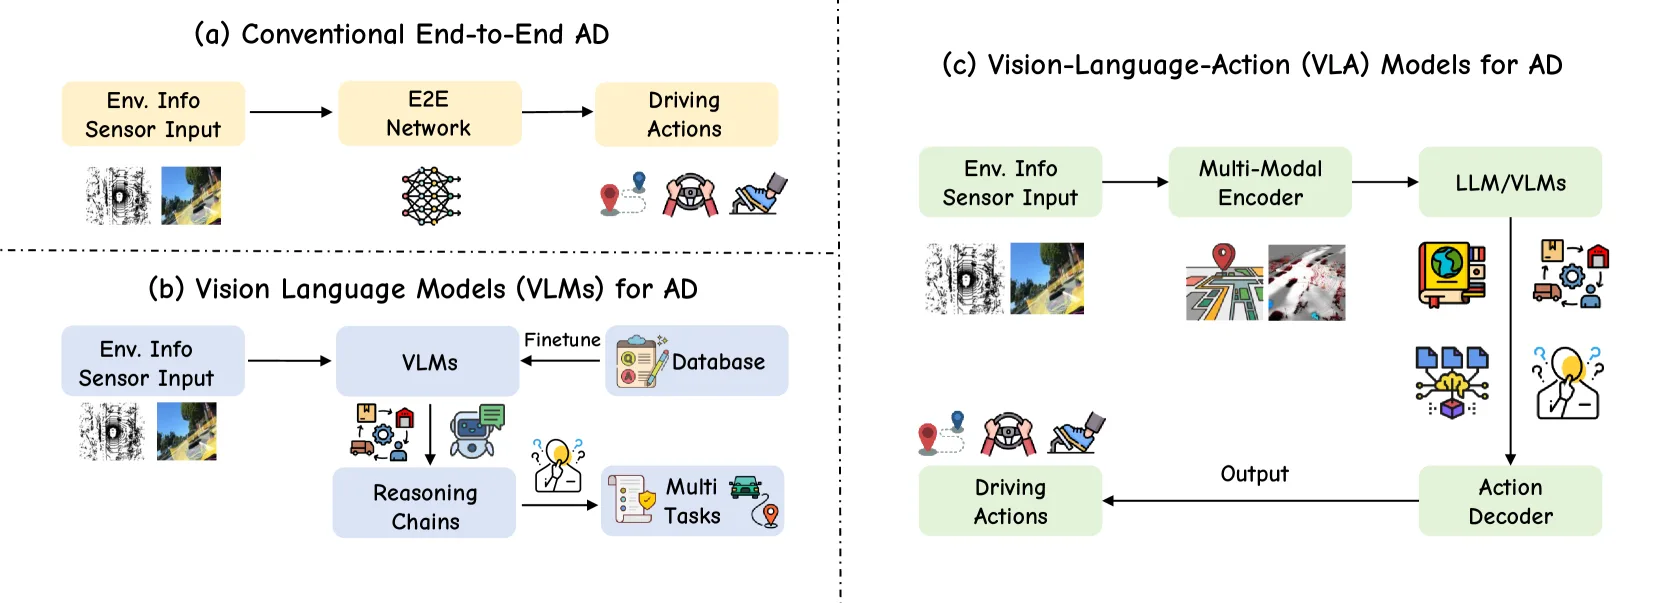
A Survey on Vision-Language-Action Models for Autonomous Driving - VLA ...
Advertisement Space (336x280)
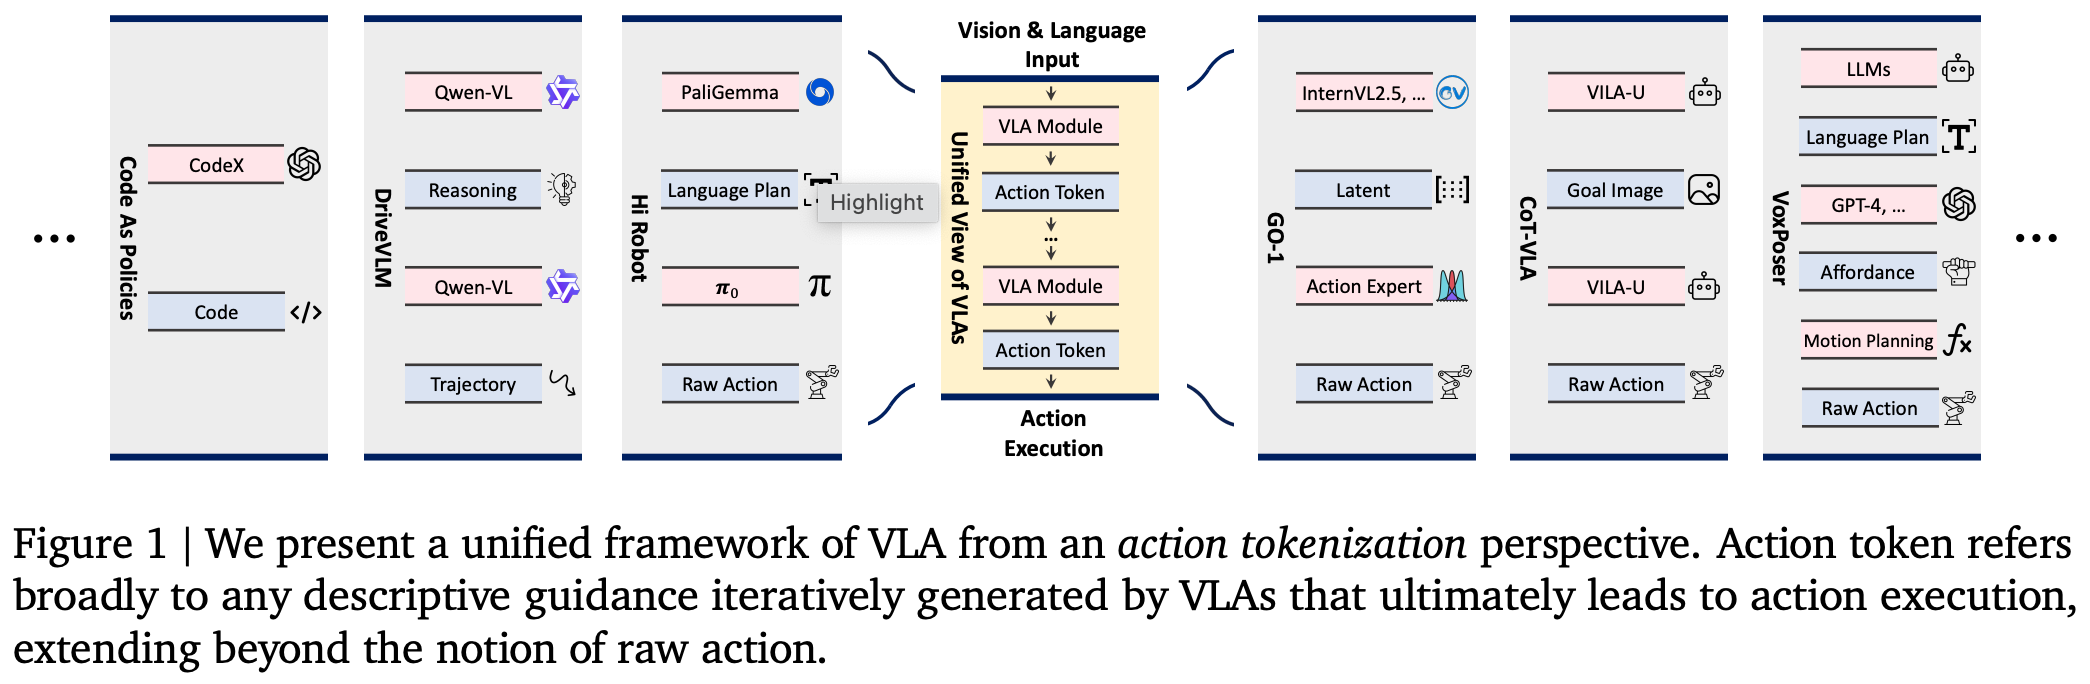
VLA 论文精读(三十三)A Survey on Vision-Language-Action Models: An Action ...

Vizuara VLA Bootcamp | Vision-Language-Action for Autonomous Driving
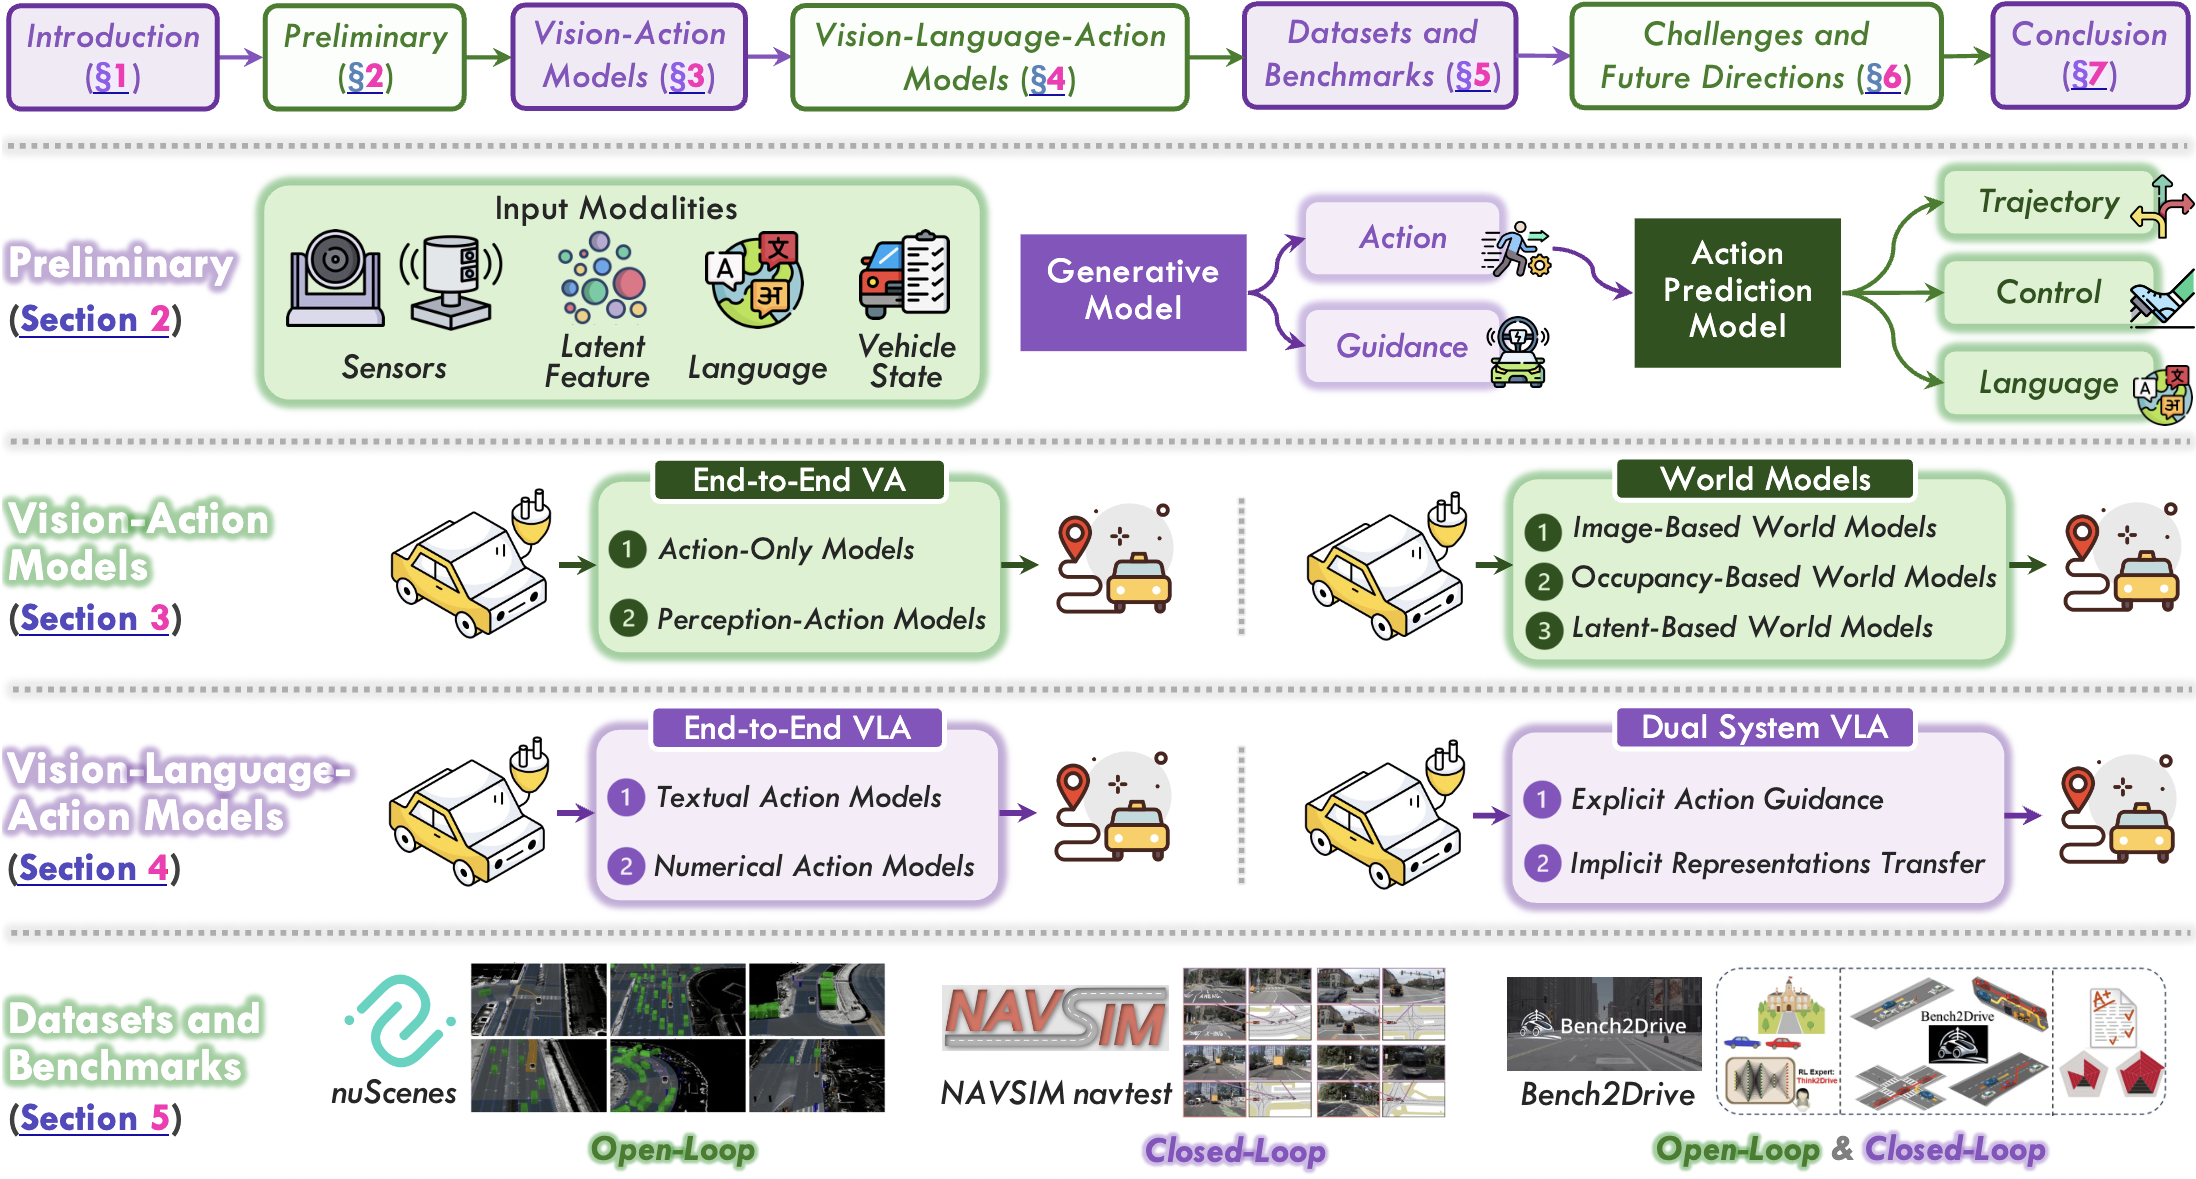
Vision-Language-Action Models for Autonomous Driving: Past, Present ...
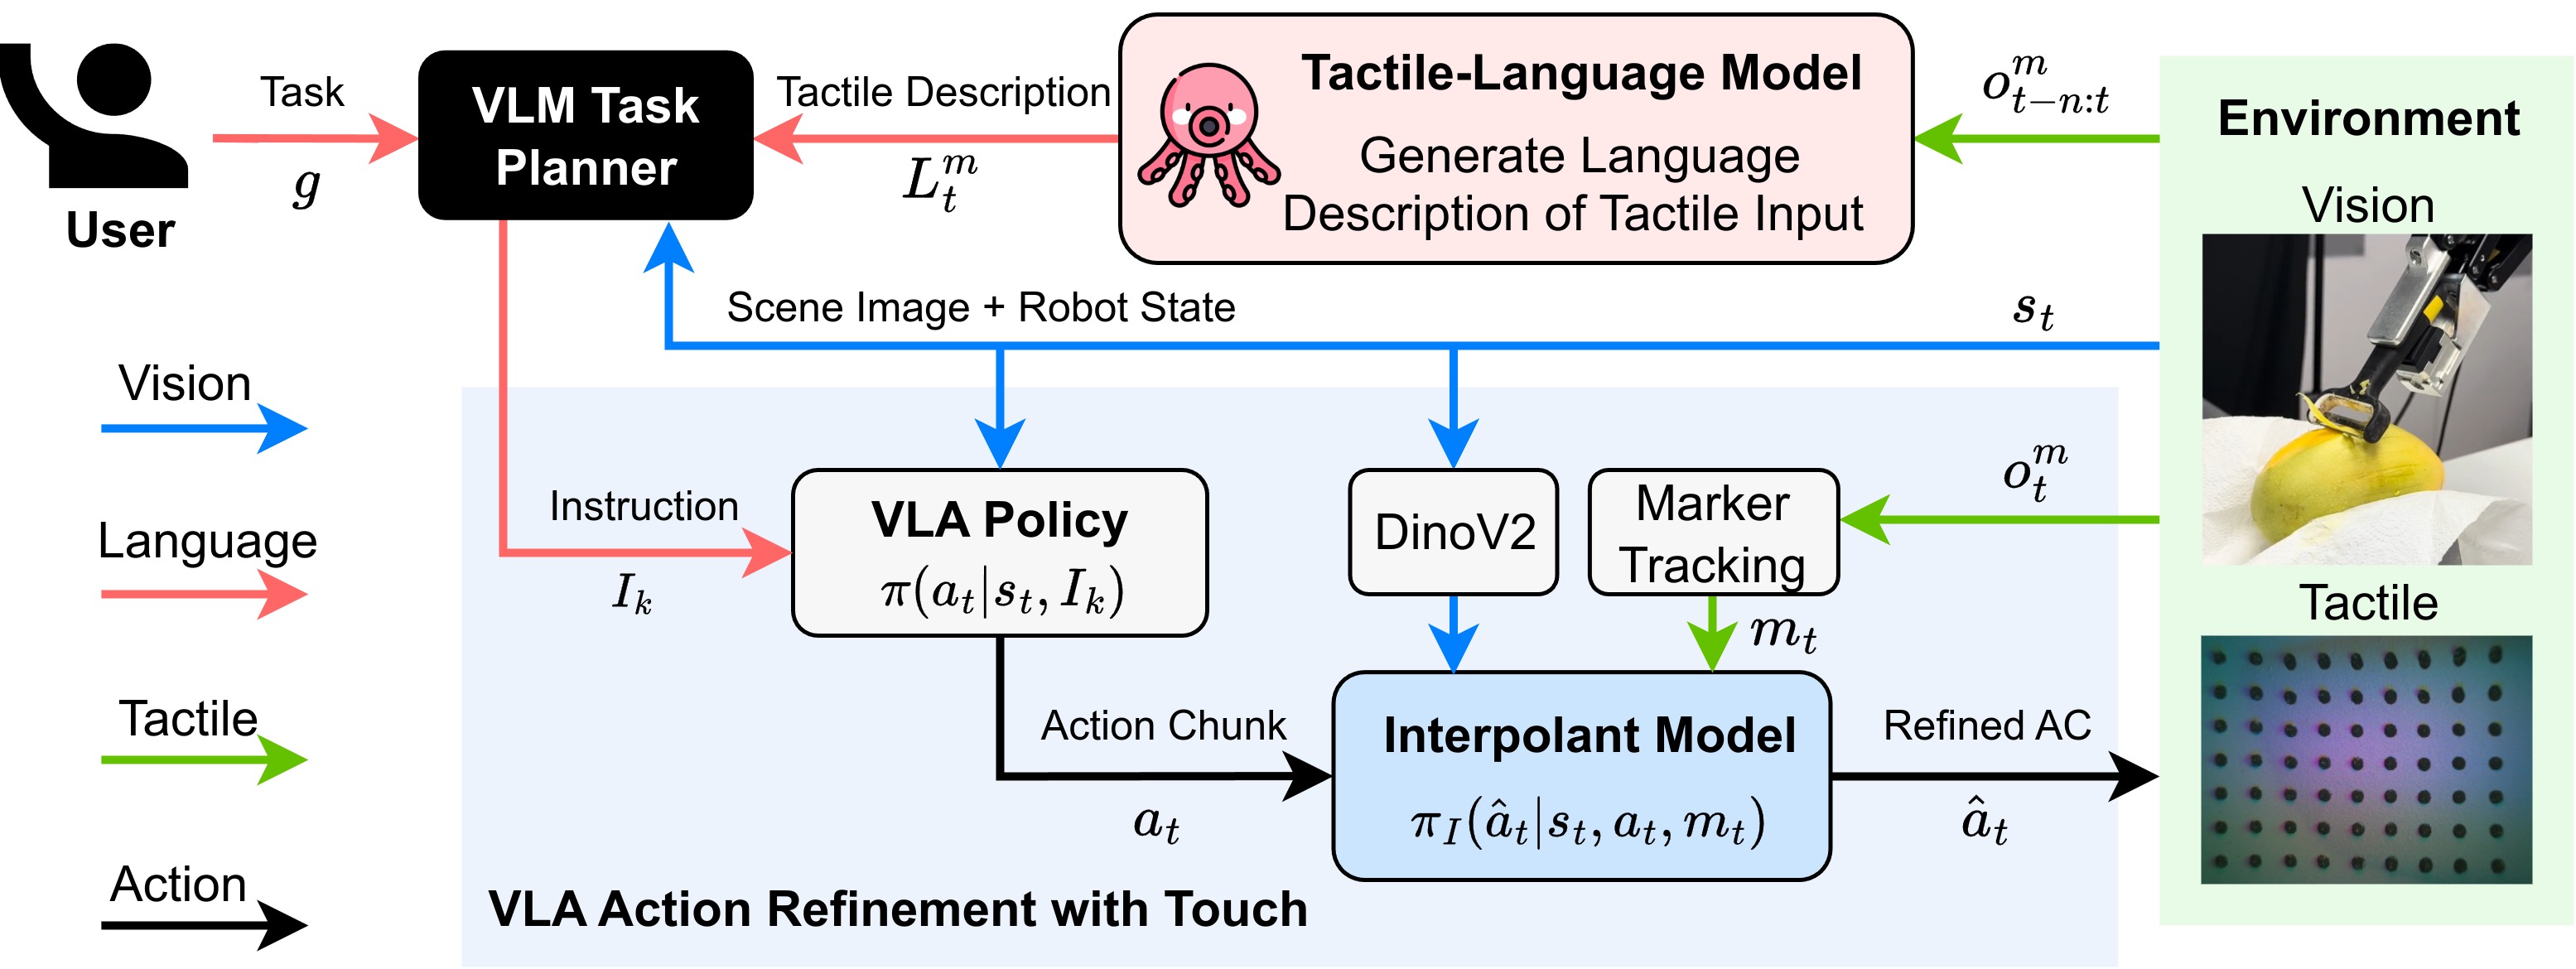
Embedding Symbolic Temporal Knowledge into Deep Sequential Models
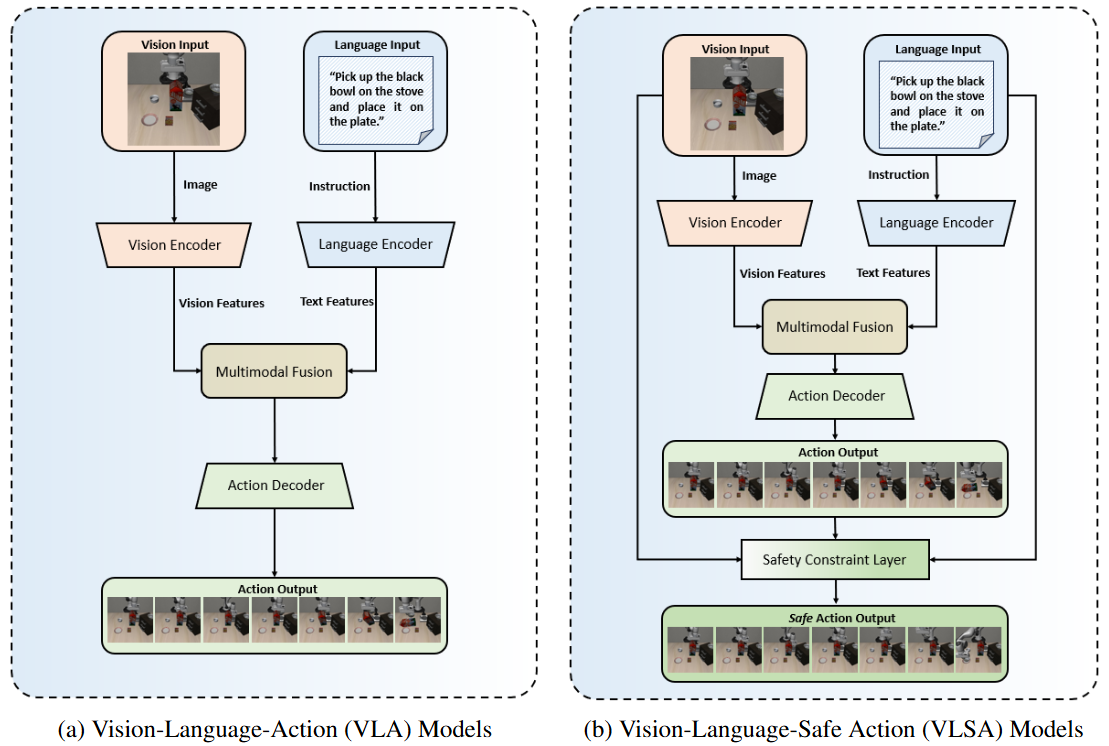
VLSA: Vision-Language-Action Models with Plug-and-Play Safety ...
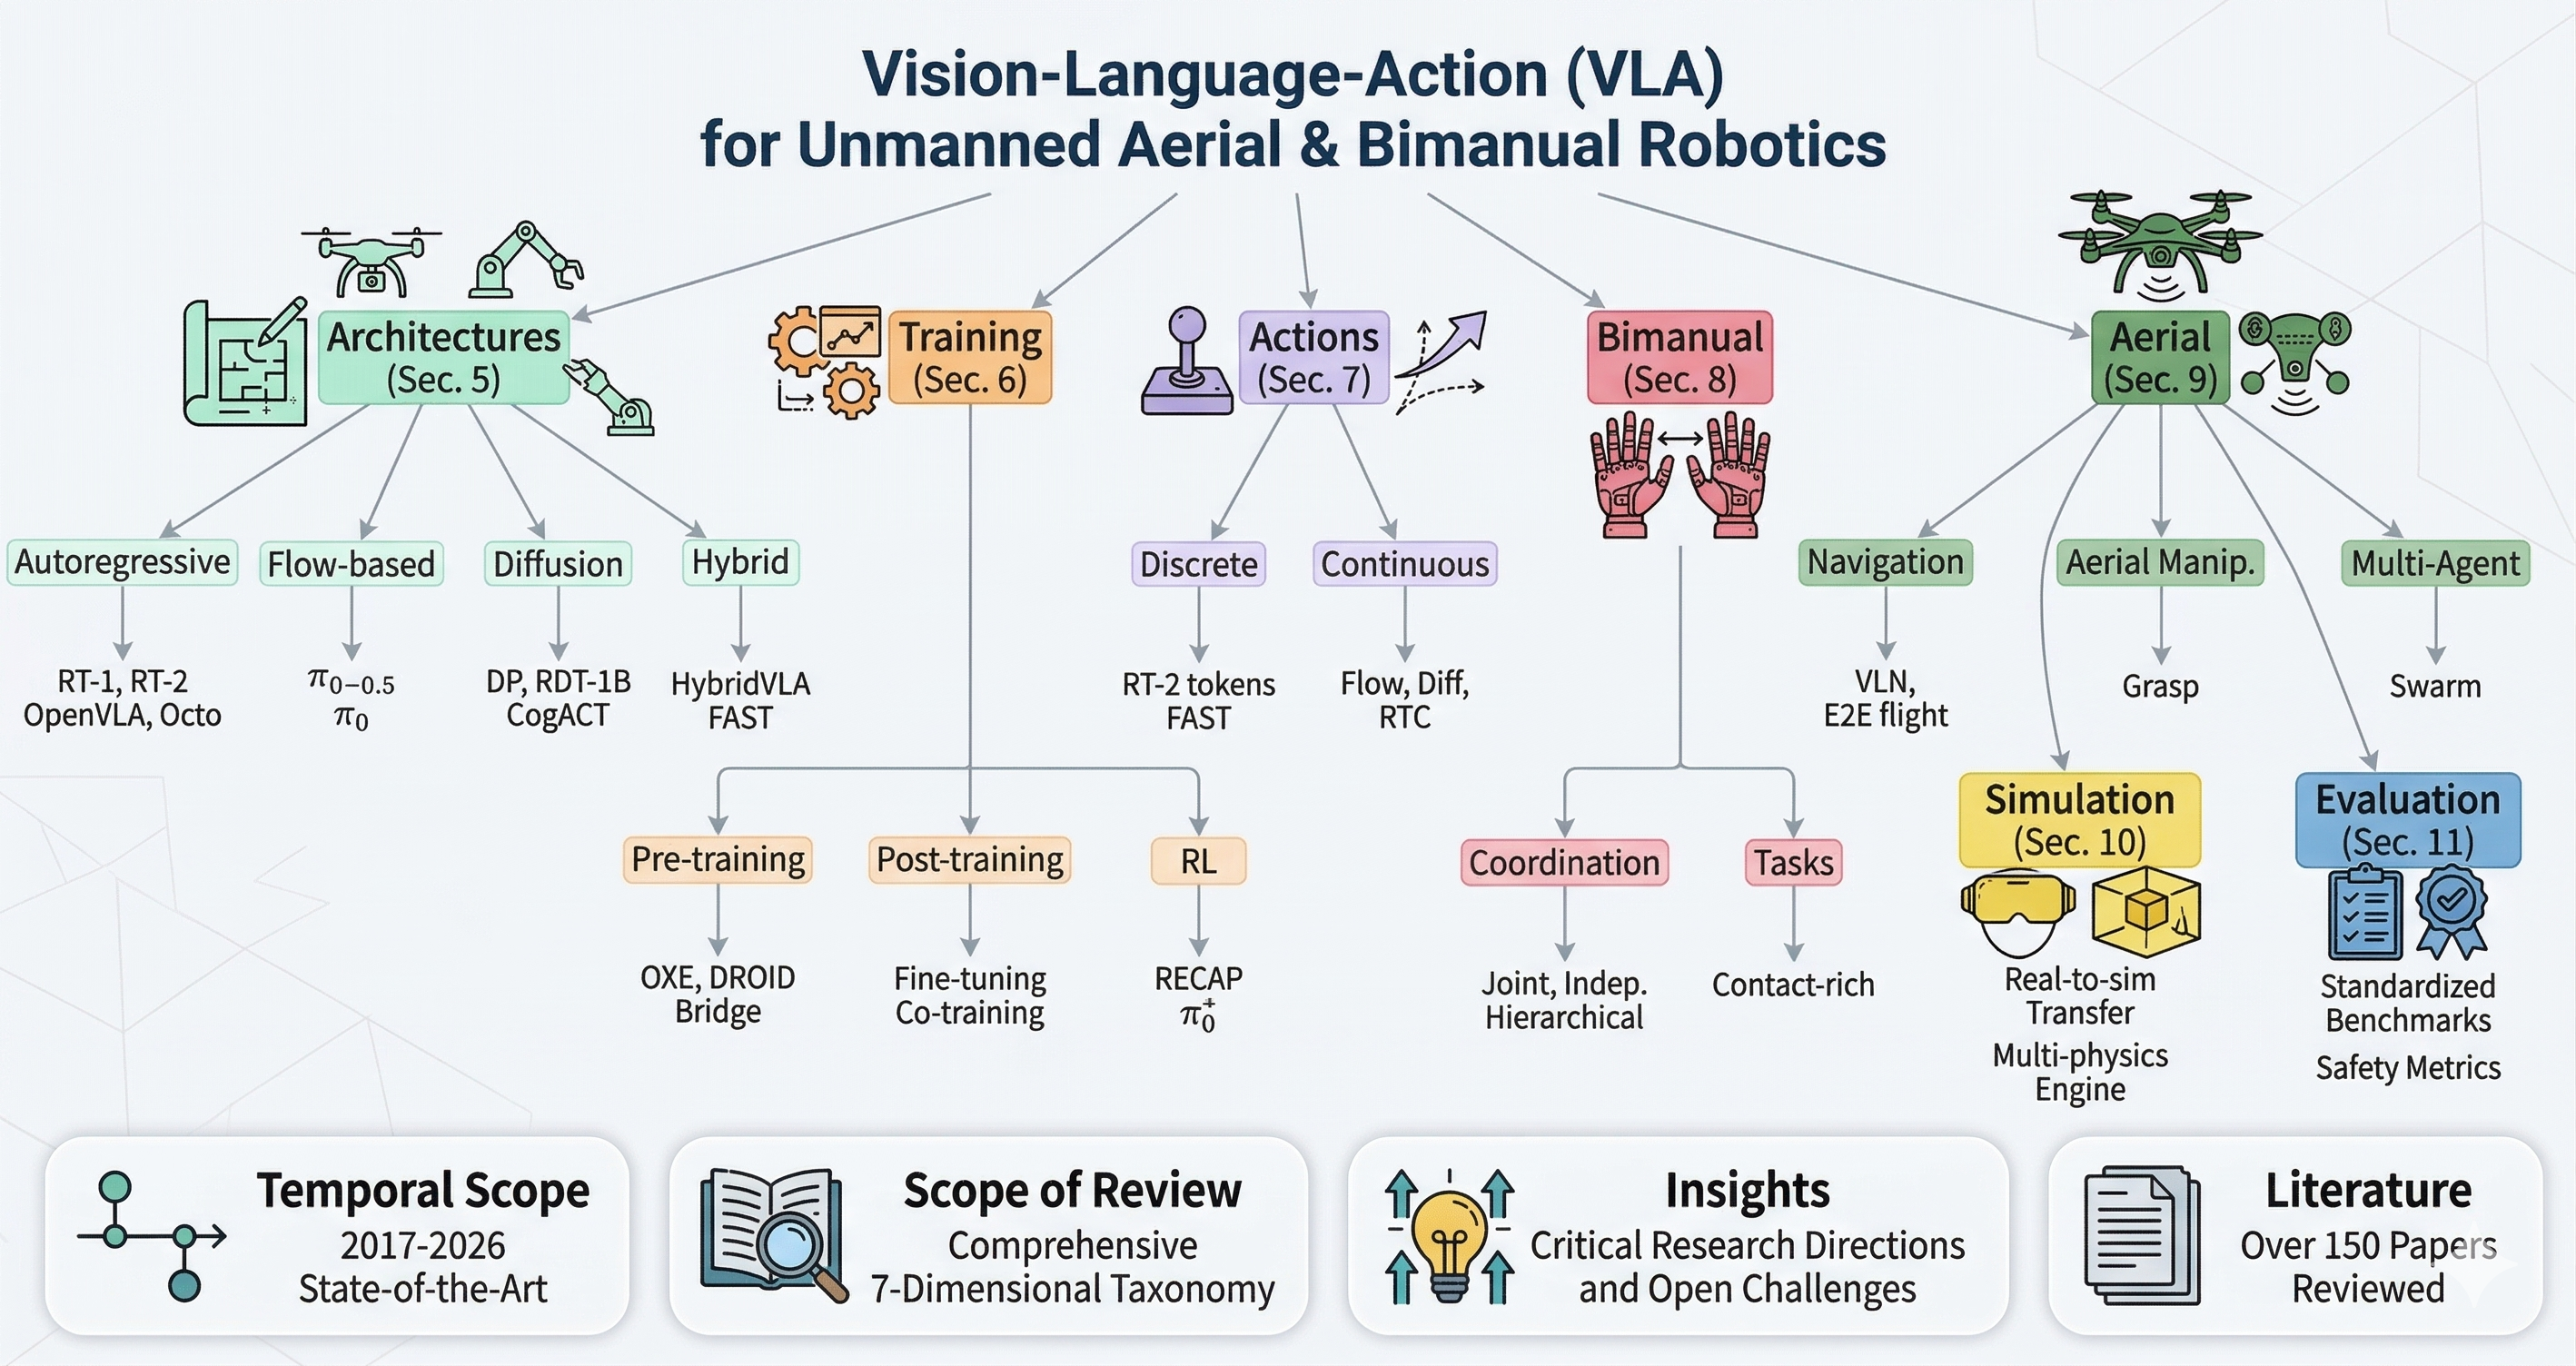
Vision-Language-Action (VLA) Models for Unmanned Aerial Robotics and ...