
Llama 32 Full Stack Optimizations Unlock High Performance On Nvidia

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...
Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama 3.2 Full-Stack Optimizations Unlock High Performance on NVIDIA ...

Llama Ecosystem On NVIDIA GPU-Based AI Servers With High Performance ...
Advertisement Space (300x250)
Unlock Reasoning in Llama 3.1-8B via Full Fine-Tuning on NVIDIA DGX ...
Unlock Reasoning in Llama 3.1-8B via Full Fine-Tuning on NVIDIA DGX ...
Unlock Reasoning in Llama 3.1-8B via Full Fine-Tuning on NVIDIA DGX ...
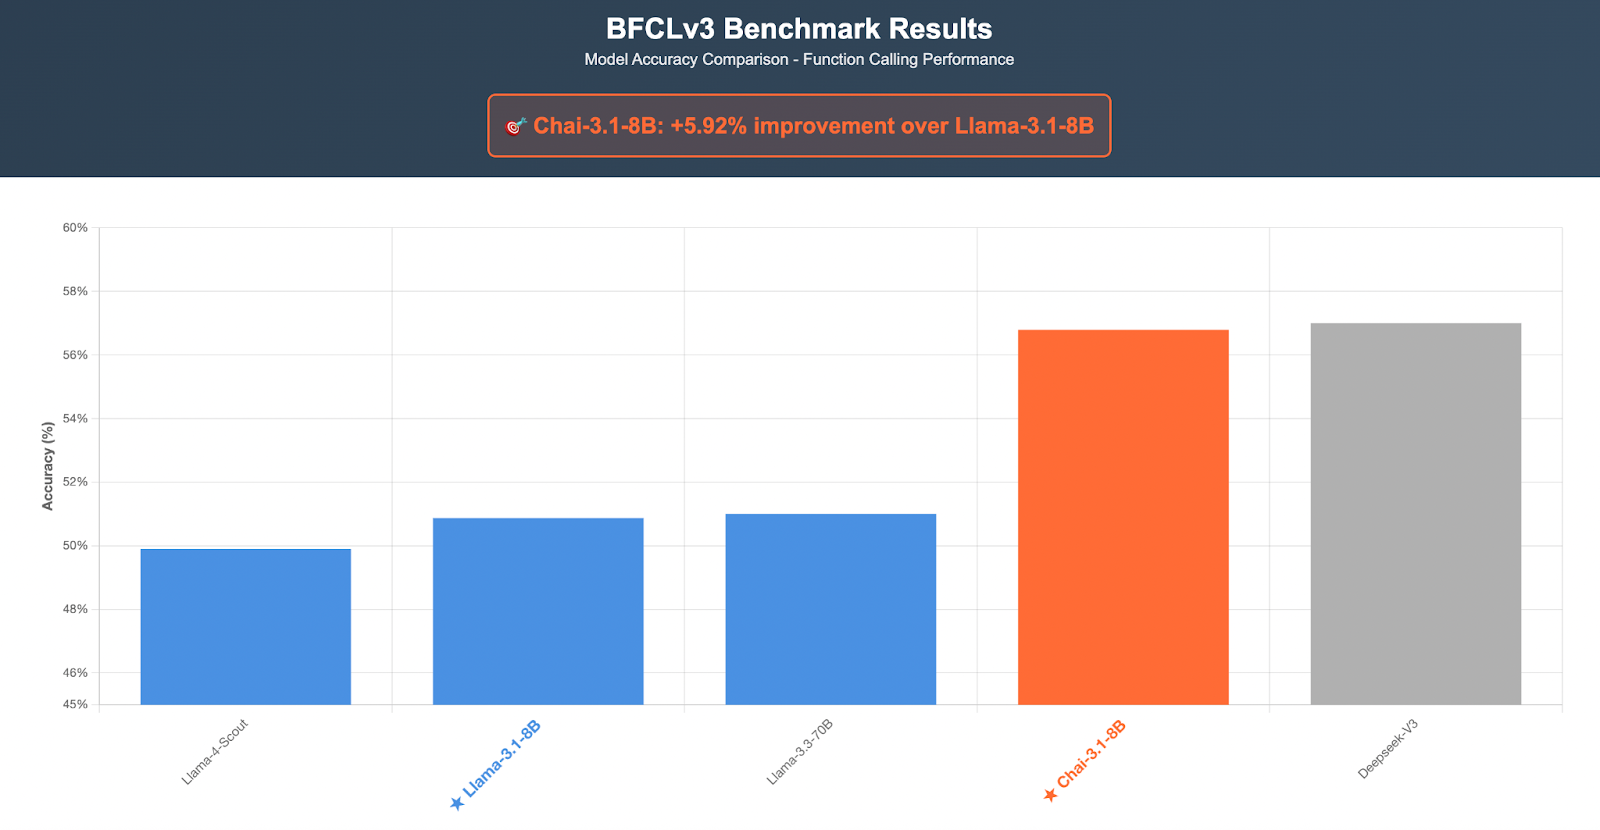
Unlock Reasoning in Llama 3.1-8B via Full Fine-Tuning on NVIDIA DGX ...
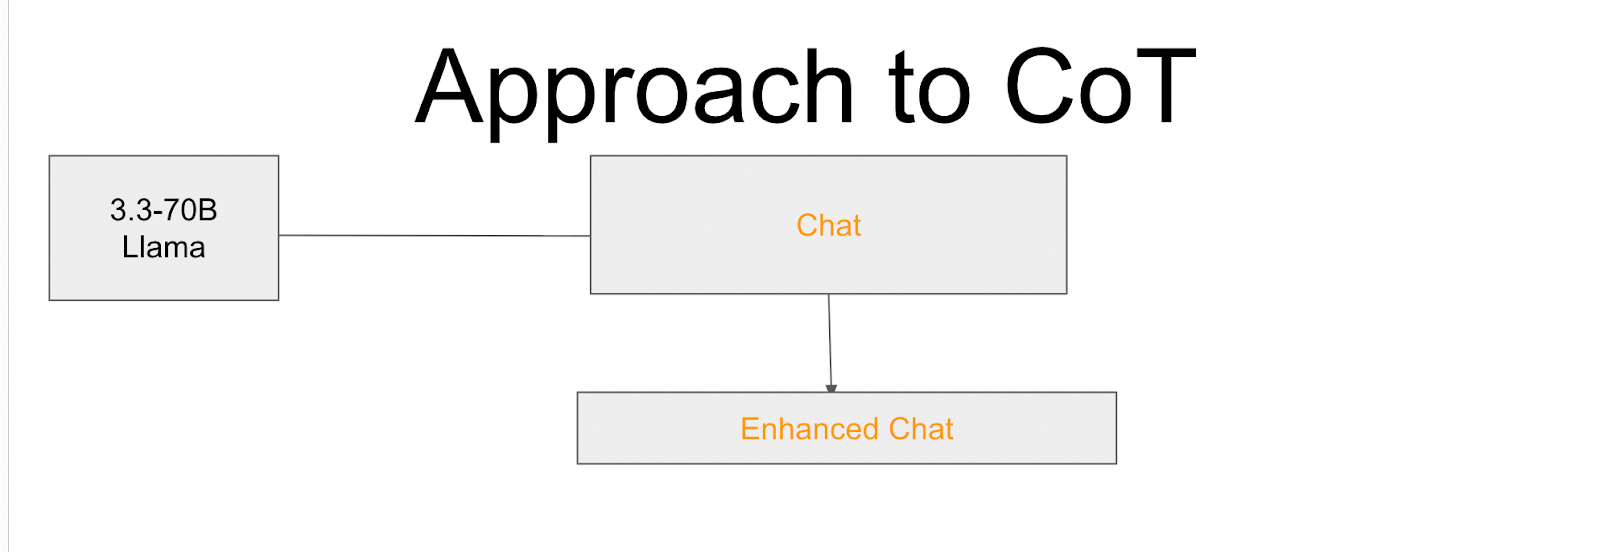
Unlock Reasoning in Llama 3.1-8B via Full Fine-Tuning on NVIDIA DGX ...

Solution architecture | Unlocking the Power of Llama Stack on Dell AI ...
Deploy Llama Stack on GPU Cloud: Meta's Production Framework for Llama ...

🚀 Announcing the launch of Llama 3.2 and Llama Stack on Together AI, in ...

Intel Announces Optimizations For Llama 3.1 To Boost Performance Across ...

Fine-Tune Llama 3.2 for Powerful Performance on Targeted Tasks ...
Advertisement Space (336x280)

Deploying Agentic RAG with Llama Stack on Dell’s AI Factory | Dell ...
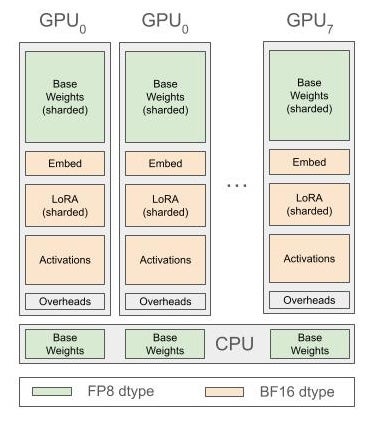
Fine-Tune Llama 3.1 405B on a Single Node using Snowflake’s AI Stack

Intel Announces Optimizations For Llama 3.1 To Boost Performance Across ...

Intel Announces Optimizations For Llama 3.1 To Boost Performance Across ...

Deploying Accelerated Llama 3.2 from the Edge to the Cloud | NVIDIA ...

Deploying Accelerated Llama 3.2 from the Edge to the Cloud | NVIDIA ...

Faster Local AI Agents on RTX PCs and DGX Spark | NVIDIA Blog

Boost Llama 3.3 70B Inference Throughput 3x with NVIDIA TensorRT-LLM ...

Accelerating LLMs with llama.cpp on NVIDIA RTX Systems | NVIDIA ...

Full-Stack Optimizations for Agentic Inference with NVIDIA Dynamo ...
Advertisement Space (336x280)

Stacking Up AMD Versus Nvidia For Llama 3.1 GPU Inference
Fine-tuning Llama 3.1 405B on AMD GPUs – Moreh

Deploying Accelerated Llama 3.2 from the Edge to the Cloud | NVIDIA ...

Supercharging Llama 3.1 across NVIDIA Platforms | NVIDIA Technical Blog

How to Use Ollama, Llama Stack & AgentOps for AI Development - Geeky ...
Accelerating LLMs with llama.cpp on NVIDIA RTX Systems | NVIDIA ...