
Llama Cpp Problem Gpu Support Issue 509 Abetlenllama Cpp
LLama cpp problem ( gpu support) · Issue #509 · abetlen/llama-cpp ...
[Bug]: Not able to use GPU with LLama CPP · Issue #8105 · run-llama ...

How to install with GPU support via cuBLAS and CUDA · Issue #250 ...
llama : support reranking API endpoint and models · Issue #8555 · ggml ...

How To Run Llama Cpp On Windows - Dibujos Cute Para Imprimir
How to Install llama cpp python bindings in windows using w64devkit or ...
Build from Source Llama.cpp with CUDA GPU Support and Run LLM Models ...
n_gpu_layers Not Offloading to GPU · Issue #1953 · abetlen/llama-cpp ...
Models loading on CPU instead of GPU after updating version · Issue ...
llama.cpp is slow on GPU · Issue #9881 · ggml-org/llama.cpp · GitHub
Advertisement Space (300x250)
Please bump llama.cpp version to b3472 to have llama 3.1 support ...
Can't get GPU offloading to work · Issue #1112 · abetlen/llama-cpp ...
Support llama.cpp's Control Vector Functionality · Issue #8110 · ollama ...
GPU not being utilized on Windows · Issue #3806 · ggml-org/llama.cpp ...
Finetuning Llama 2 "failed to allocate CPU buffer" · Issue #5483 · ggml ...
add support for llama.cpp · Issue #8004 · open-webui/open-webui · GitHub
Error when loading Llama model from file · Issue #3183 · ggml-org/llama ...
Feature request : NPU Support · Issue #1702 · abetlen/llama-cpp-python ...
Commit `7c898d5` breaks generation on GPU · Issue #1089 · abetlen/llama ...
Support for arm64 wheels and CPU Features · Issue #1342 · abetlen/llama ...
Advertisement Space (336x280)
Quantized Llama 7B not working · Issue #216 · abetlen/llama-cpp-python ...
Problem with the CMake installation, aborting build. · Issue #698 ...
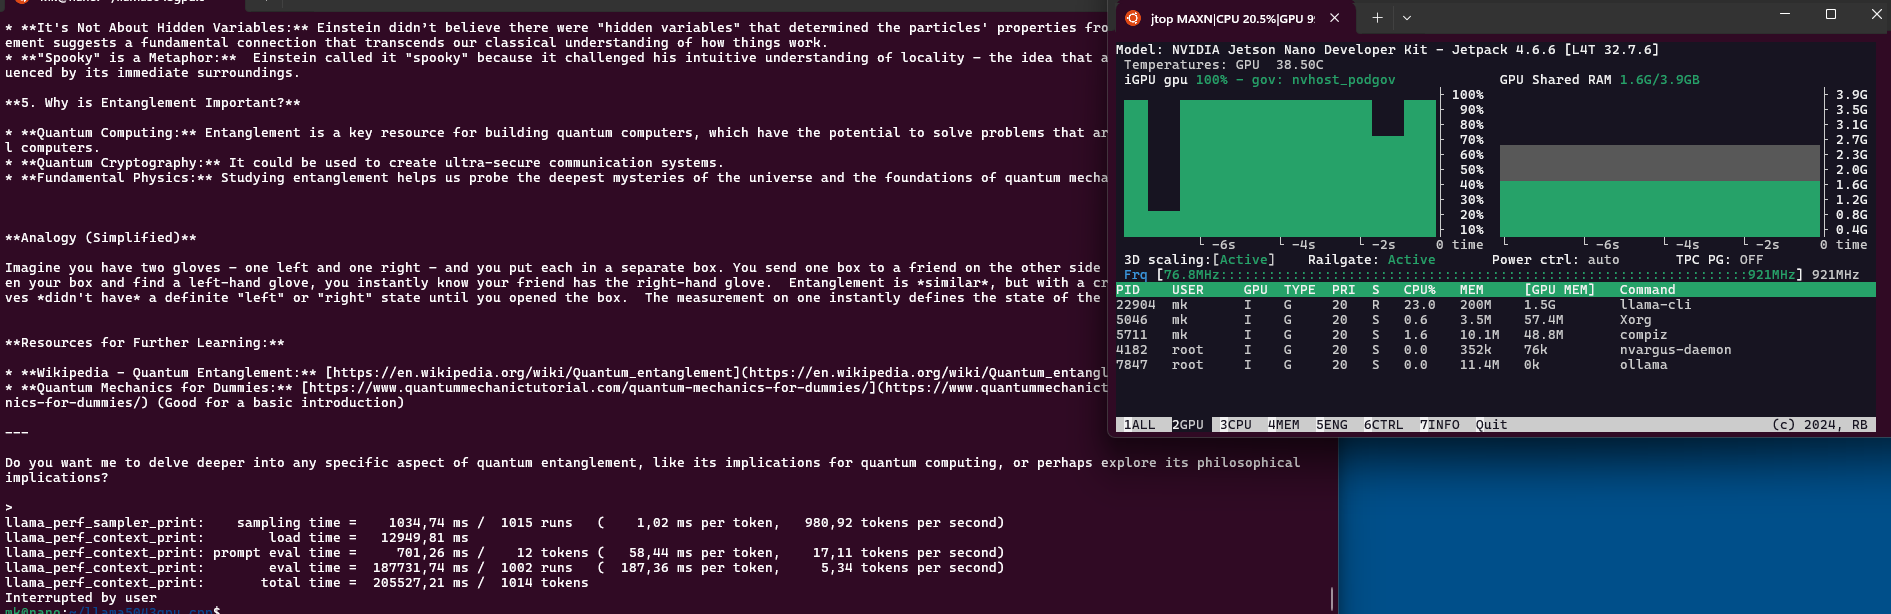
Llama.cpp with CUDA support on a Jetson Nano | llama.cpp-jetson
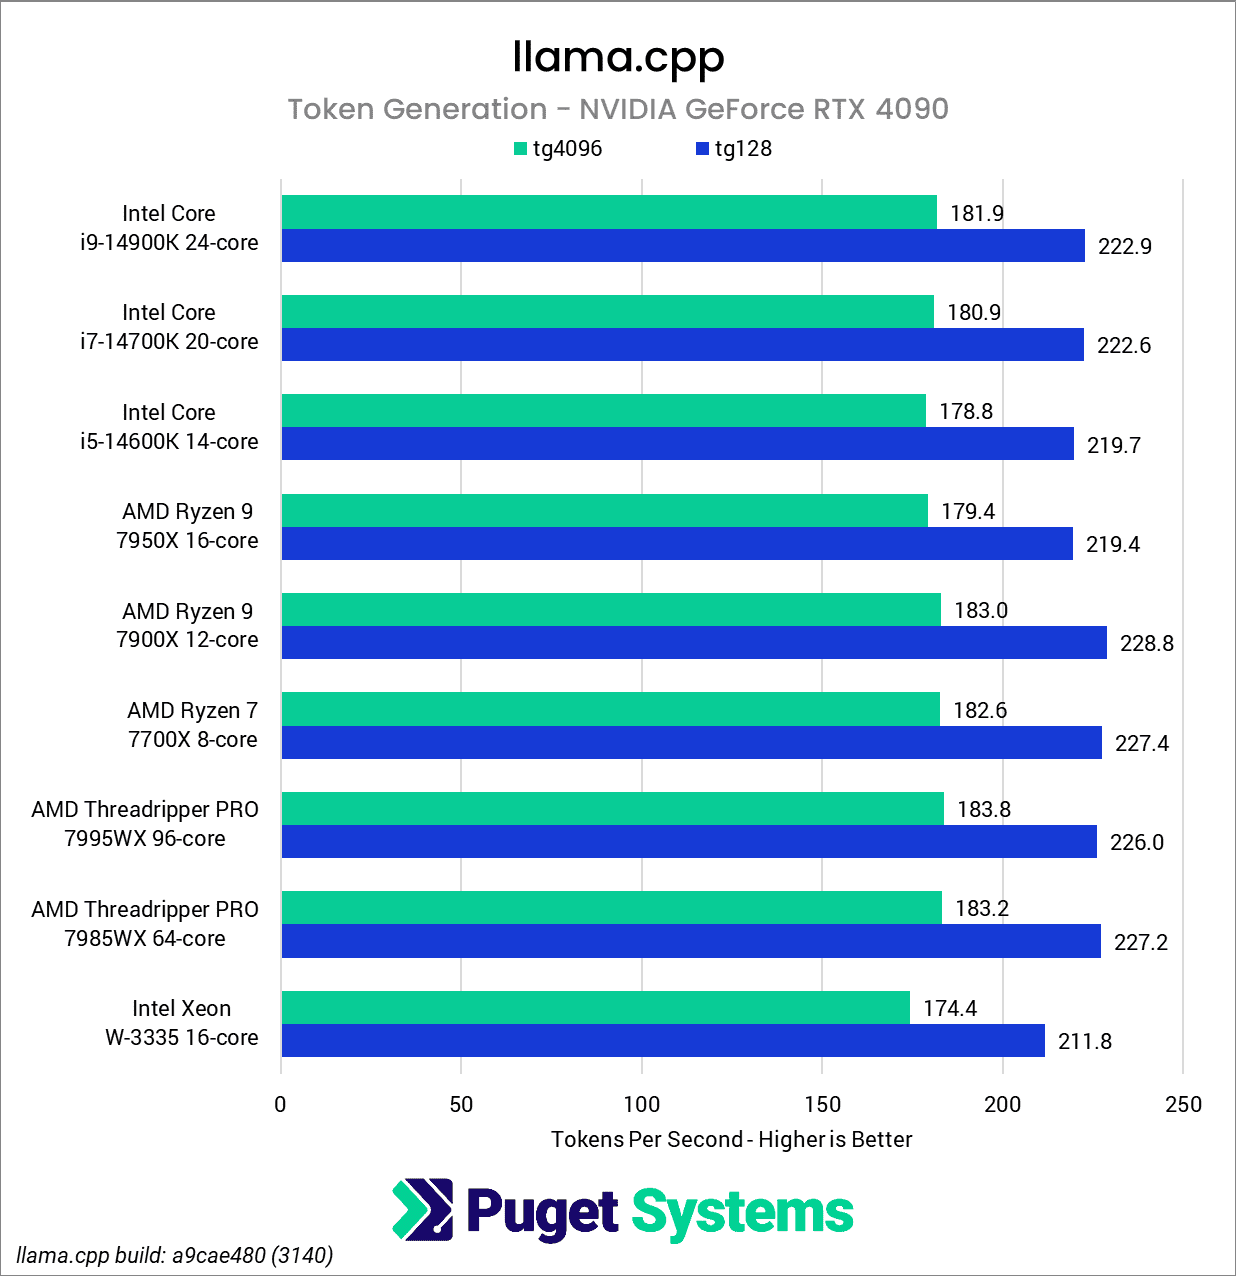
Effects of CPU speed on GPU inference in llama.cpp | Puget Systems
function_call support for LLMs/llama_cpp_python · abetlen llama-cpp ...
Issue with Installing llama-cpp-python 0.3.7: Dependency Problems with ...
llama.cpp Windows/ROCm builds are broken? Using shared GPU memory ...
LlamaCPP Usage · Issue #1035 · abetlen/llama-cpp-python · GitHub

LLAMA-CPP-PYTHON on RTX4060 GPU
KV_cache not offloading to GPU. Slows down the process a lot! · Issue ...
Advertisement Space (336x280)
GPU memory not cleaned up after off-loading layers to GPU using `n_gpu ...
llama-cpp-python now supports GPU, privateGPT a lot faster now · Issue ...
The last working build of llama.cpp for Windows10 21H2 is 4179 · Issue ...
Llama crashes instead of raising an Exception when loading a model too ...
what commit of llama.cpp does v0.1.57 of llama-cpp-python use? · Issue ...
Trying to Install GPU Version - Getting CMake Error With _CMAKE_CUDA ...