
Llm Deployment A Guide To Nvidia Triton Inference Server And Tensorrt

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
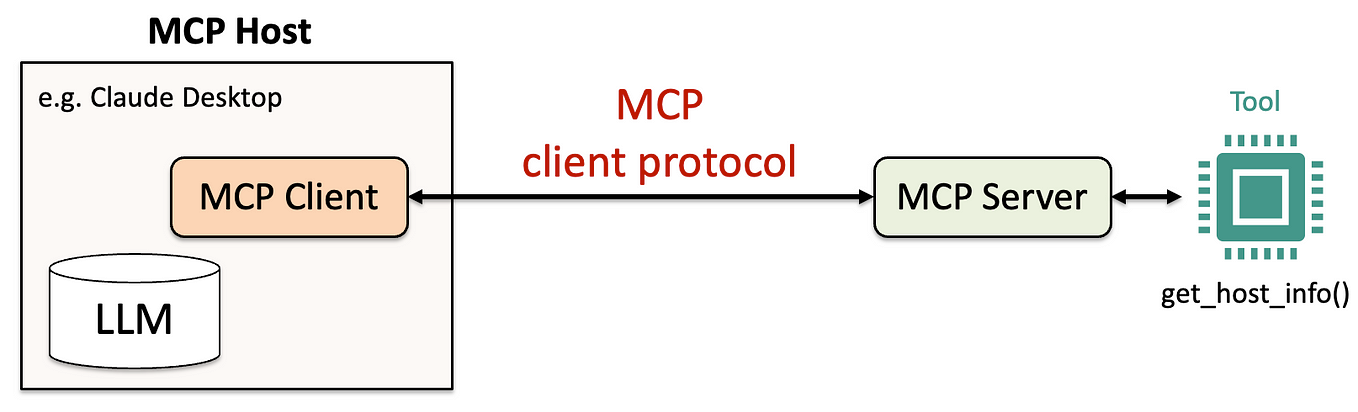
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

One-click Deployment of NVIDIA Triton Inference Server to Simplify AI ...
Advertisement Space (300x250)
Simplify LLM Deployment and AI Inference with a Unified NVIDIA NIM ...

Simplify LLM Deployment and AI Inference with a Unified NVIDIA NIM ...

One-click Deployment of NVIDIA Triton Inference Server to Simplify AI ...
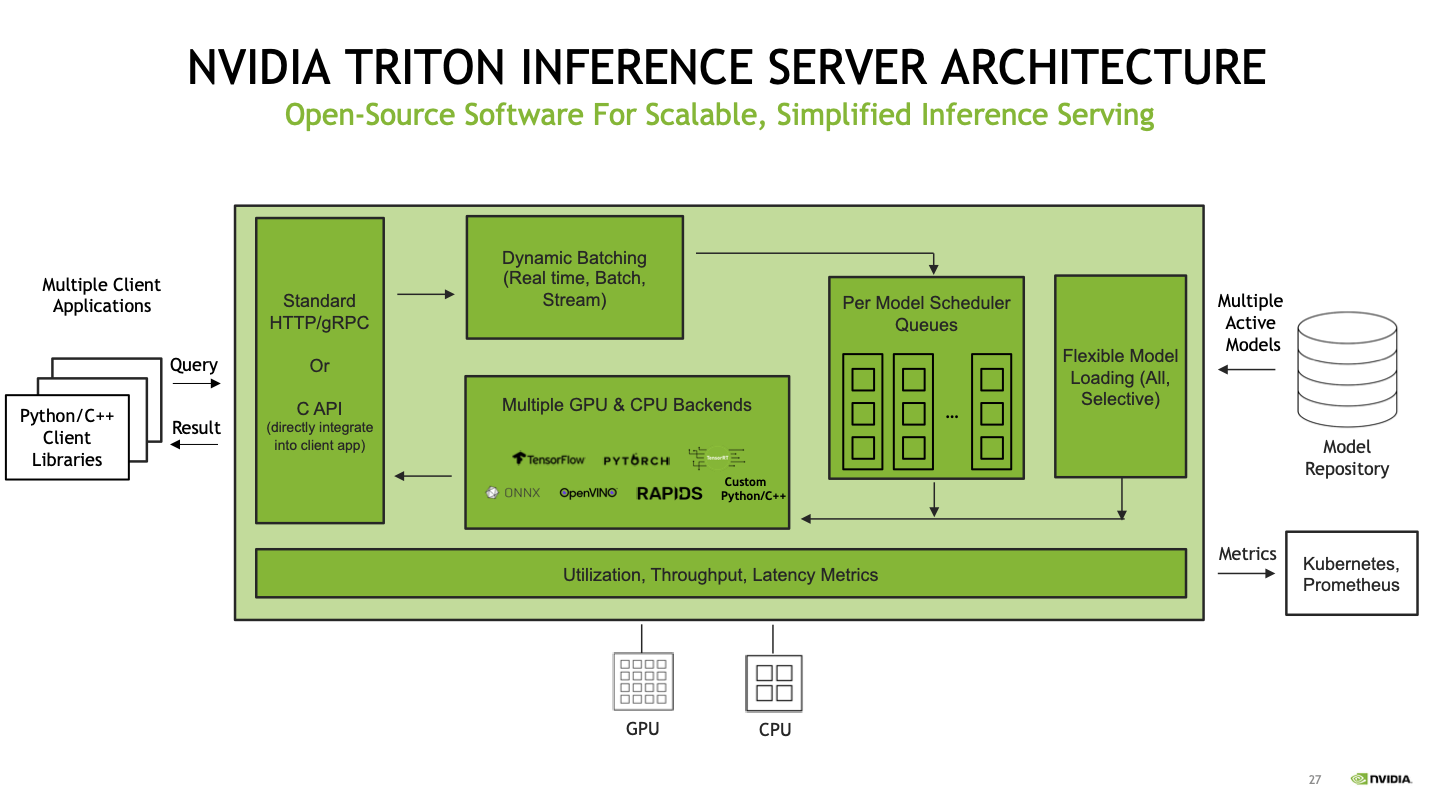
Deploy fast and scalable AI with NVIDIA Triton Inference Server in ...

Scaling Llms with Nvidia Triton and Tensorrt-LLM: The Complete Guide to ...
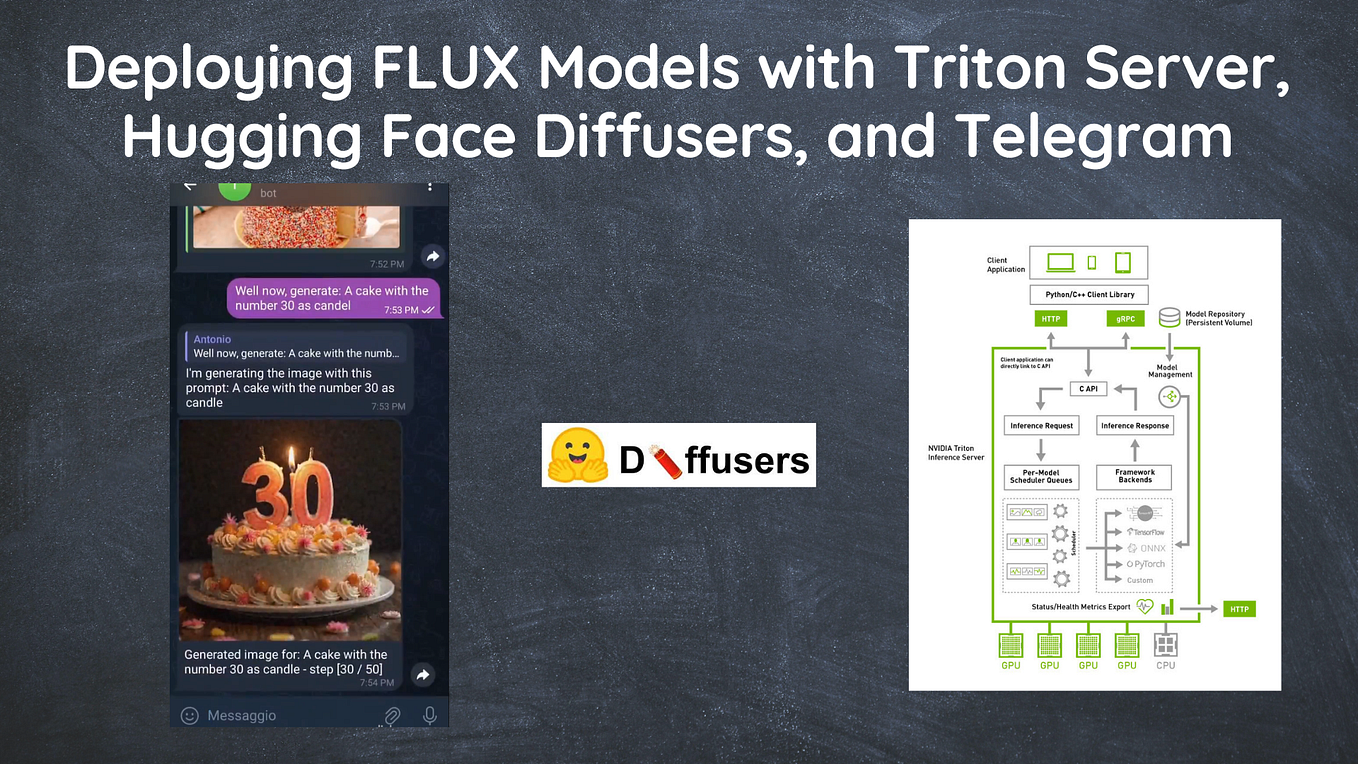
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

Fast and Scalable AI Model Deployment with NVIDIA Triton Inference ...
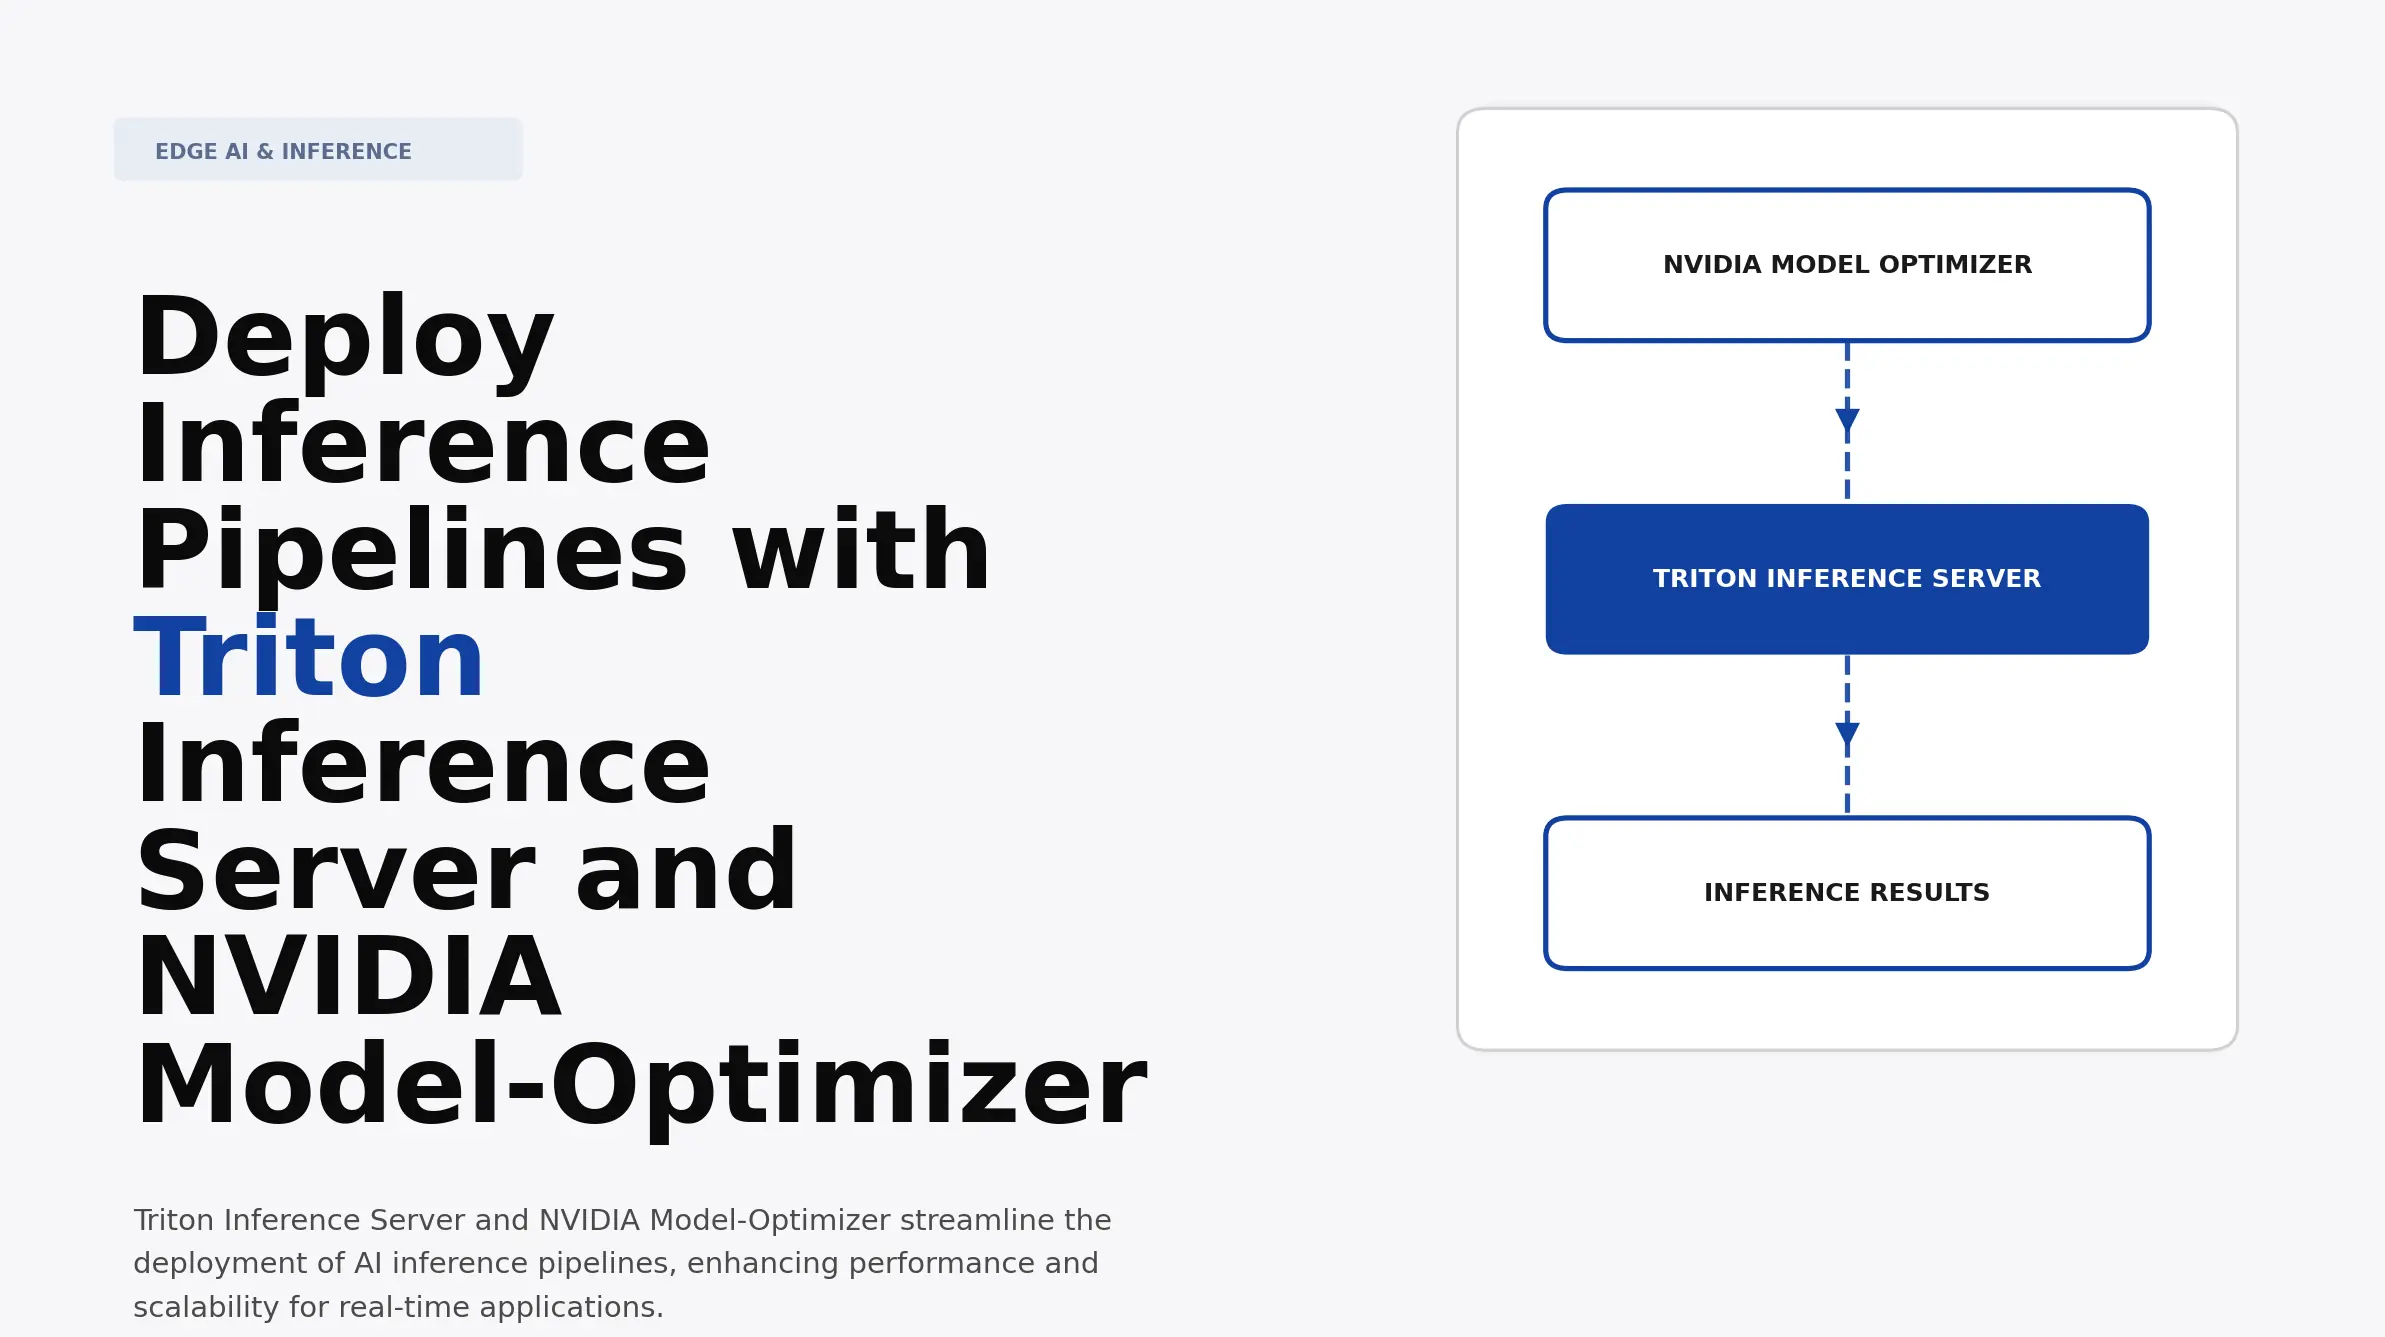
Deploy Inference Pipelines with Triton Inference Server and NVIDIA ...
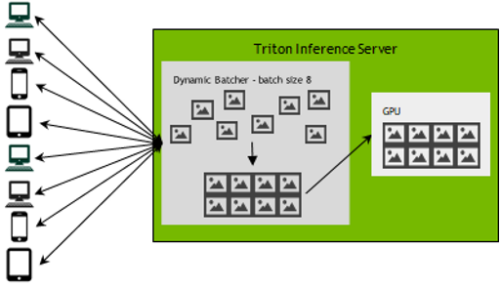
Fast and Scalable AI Model Deployment with NVIDIA Triton Inference ...
How to Deploy NVIDIA Triton Inference Server via Portainer
Advertisement Space (336x280)

Serving TensorRT Models with NVIDIA Triton Inference Server | by Tan ...
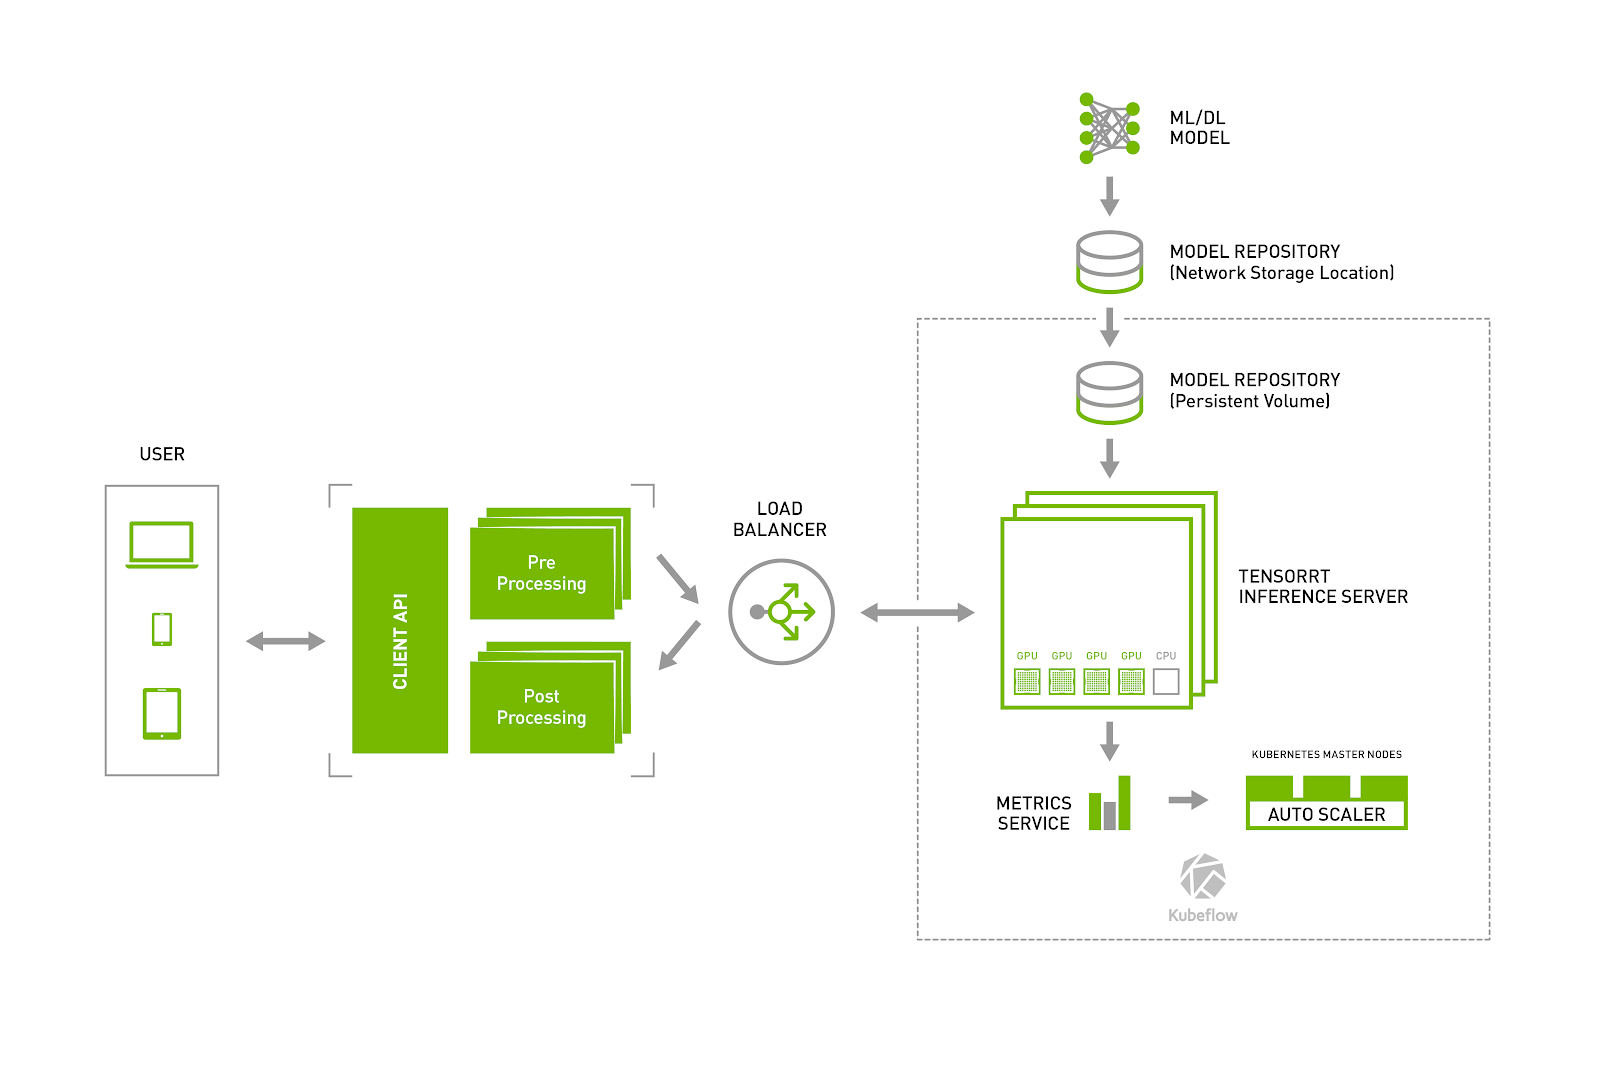
NVIDIA TensorRT Inference Server and Kubeflow Make Deploying Data ...
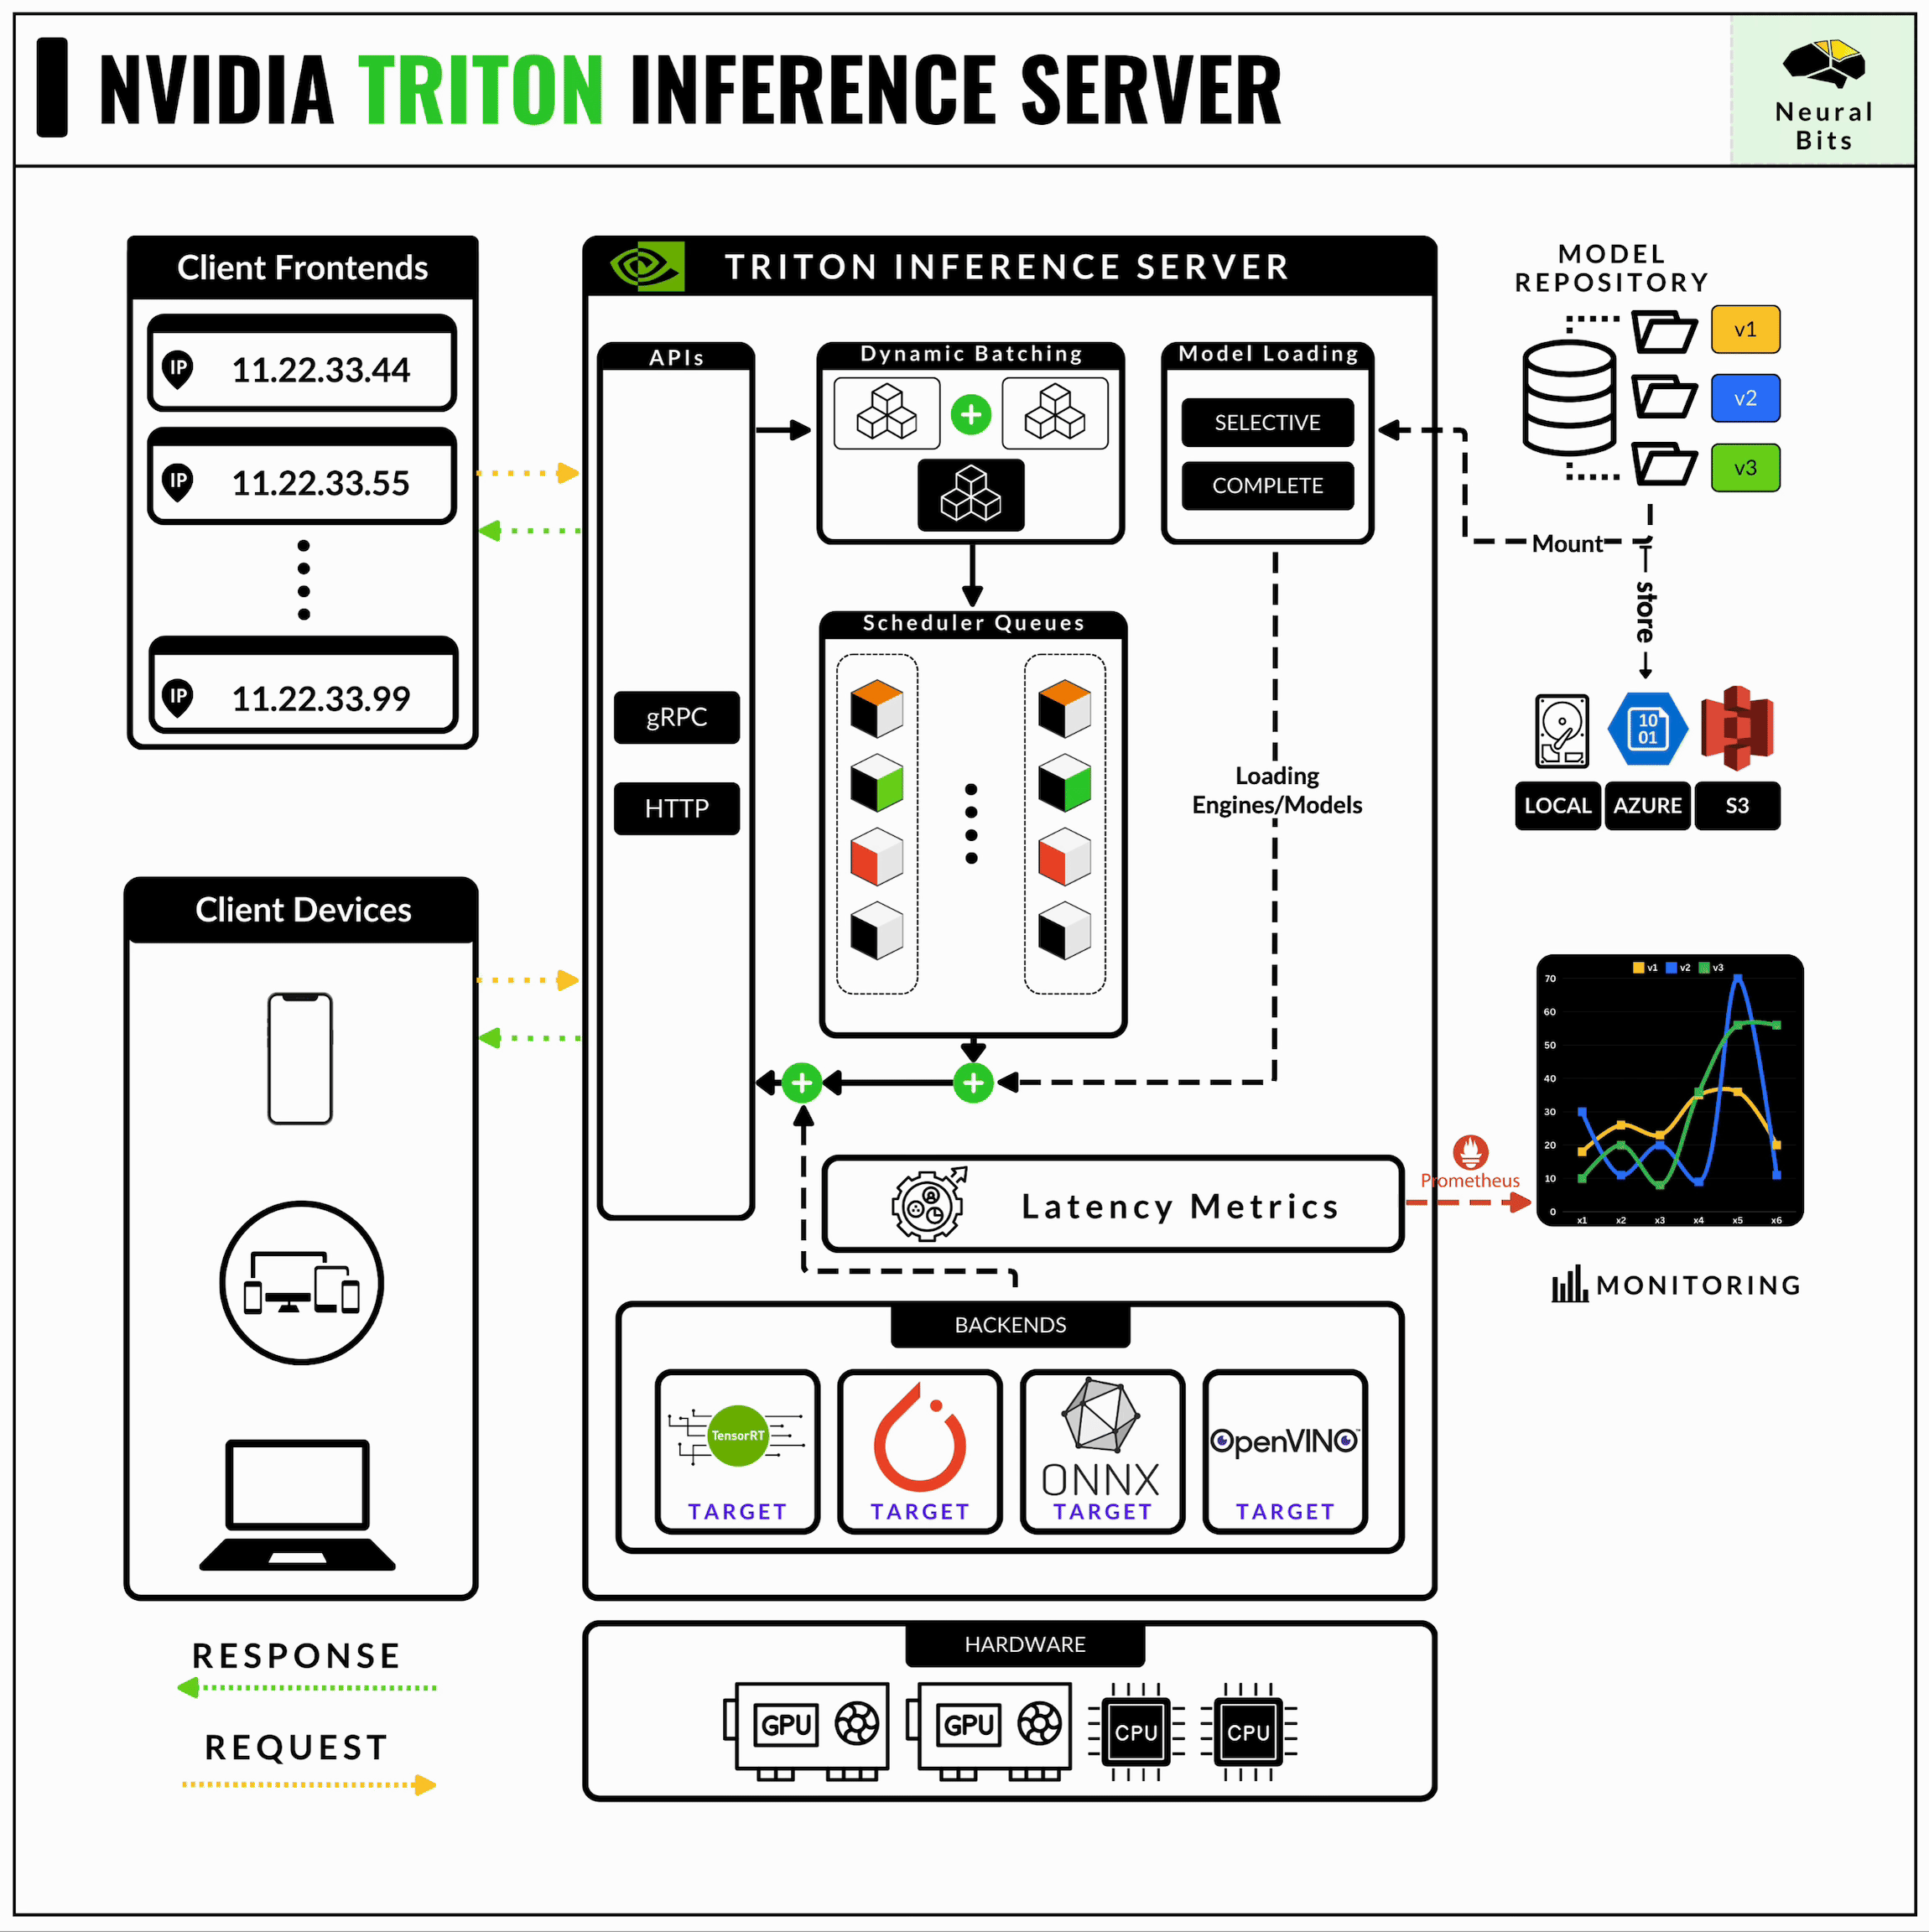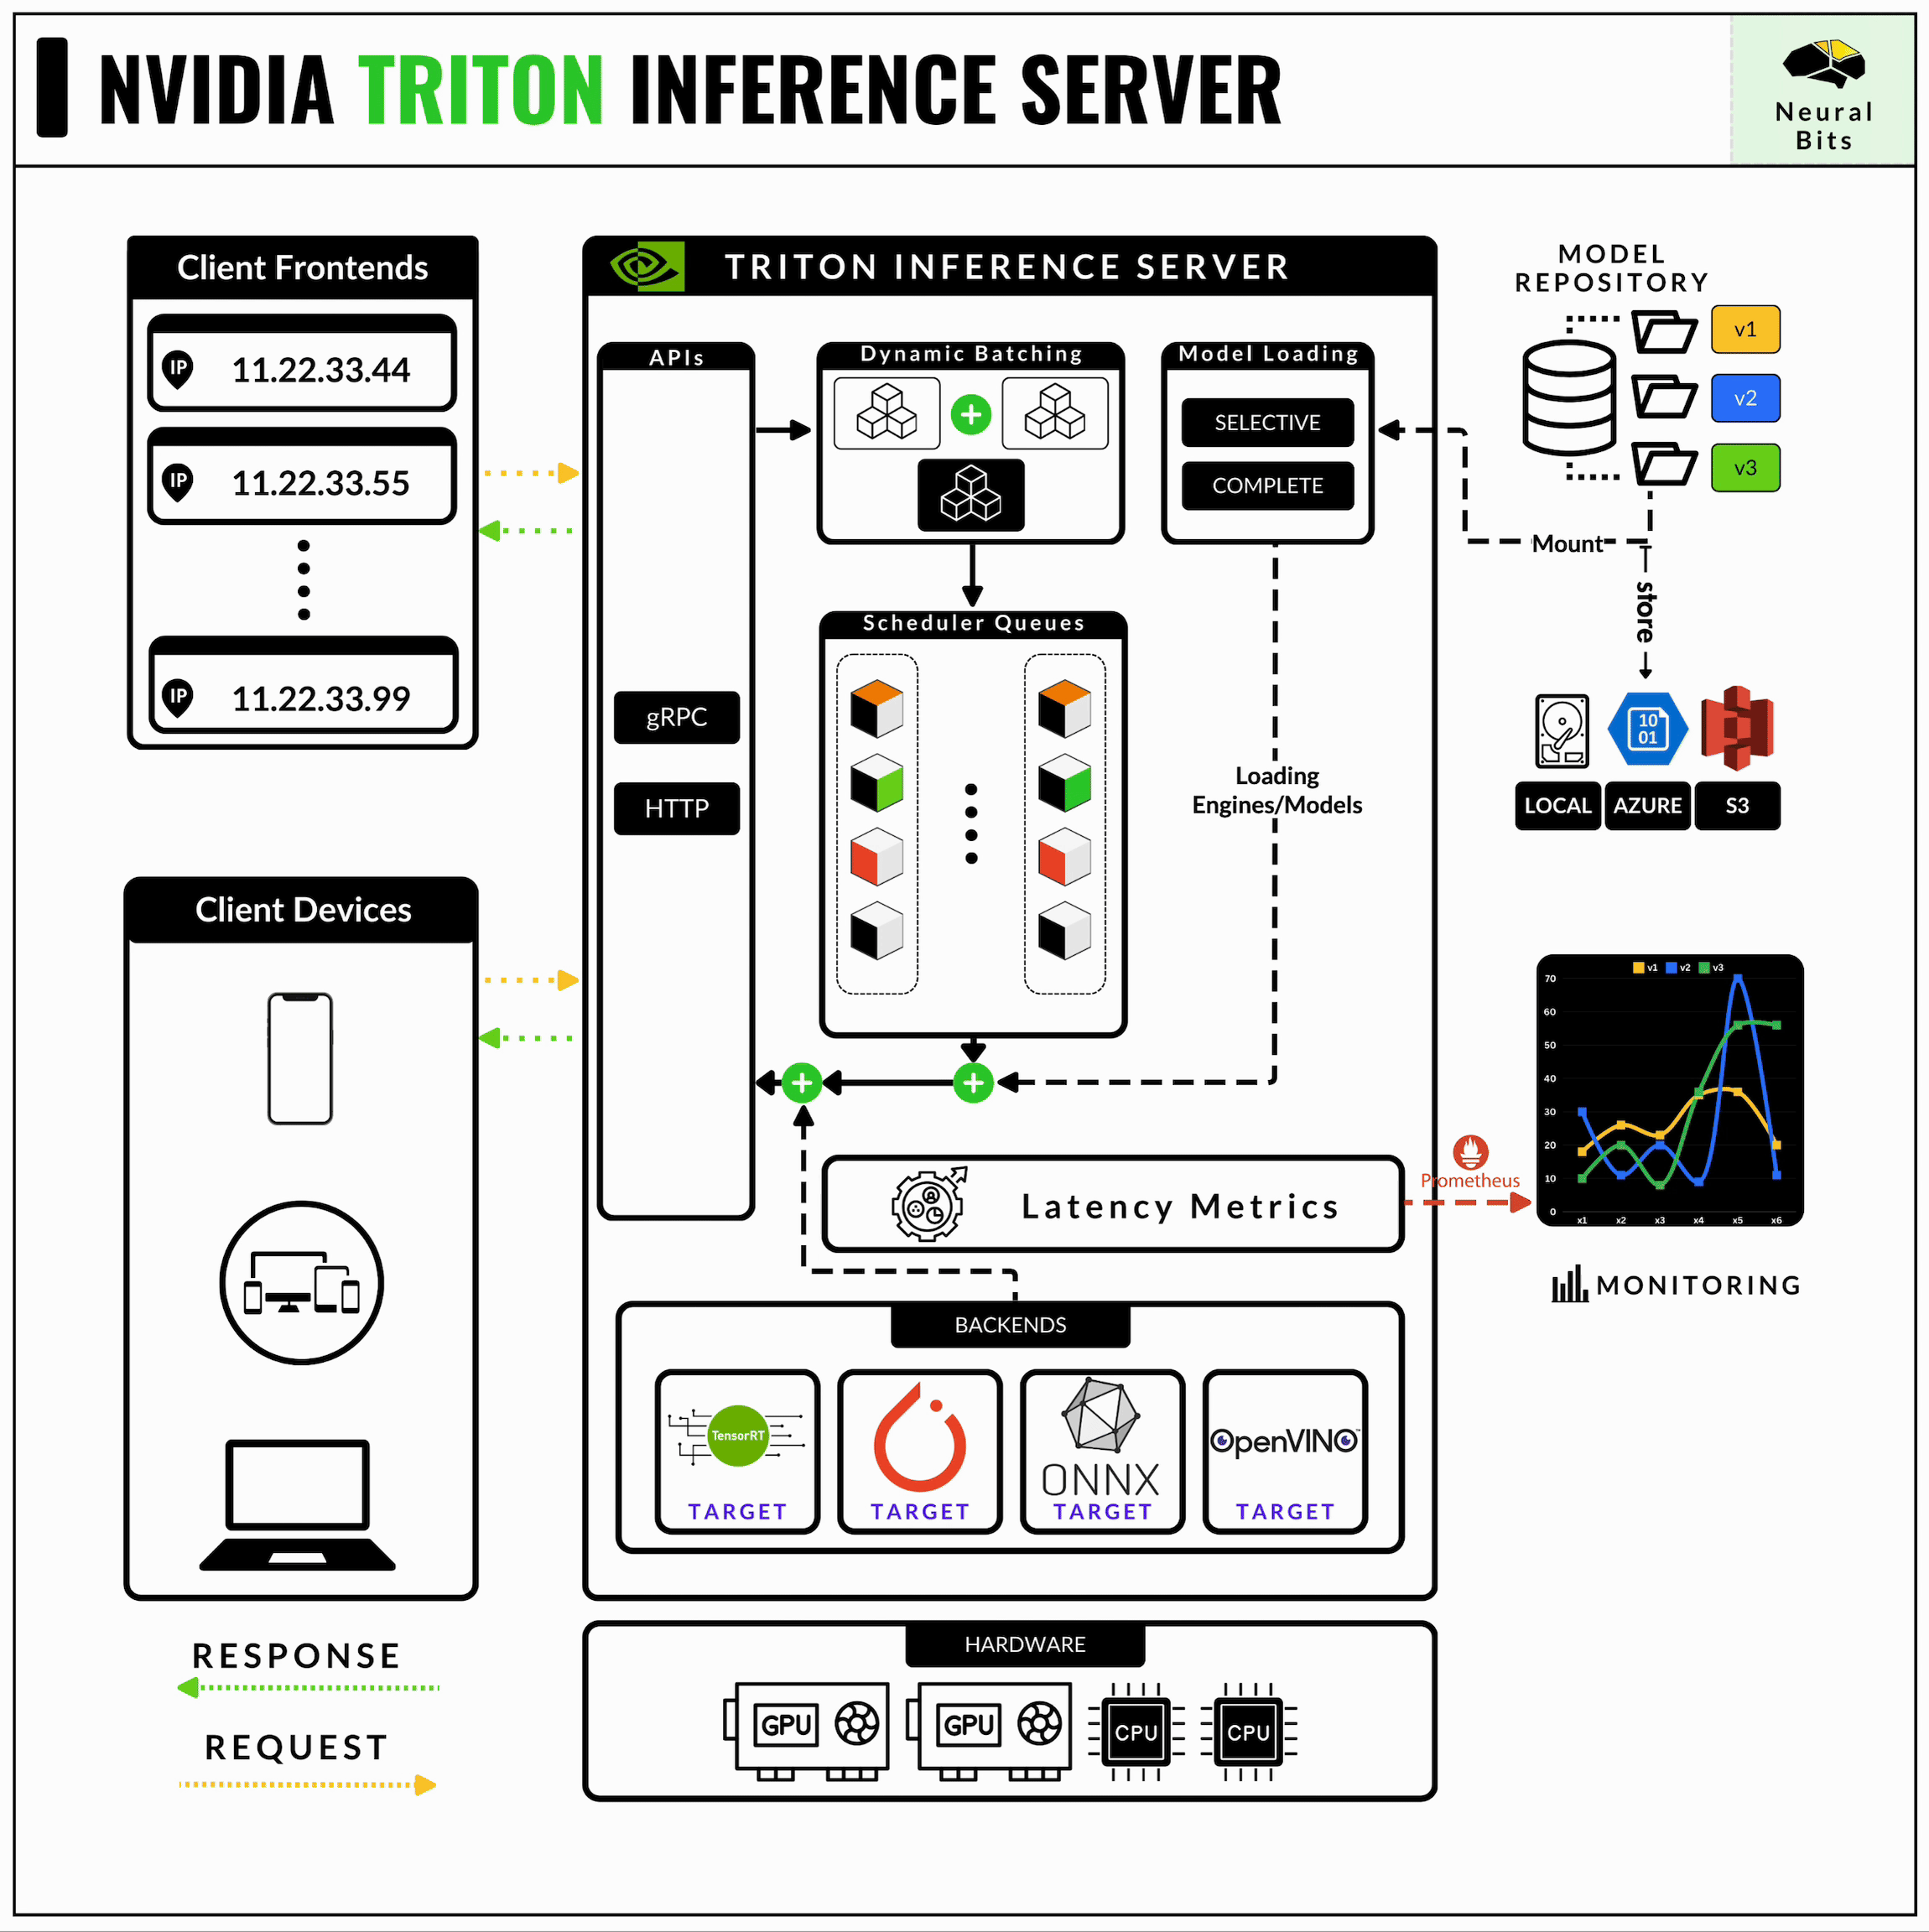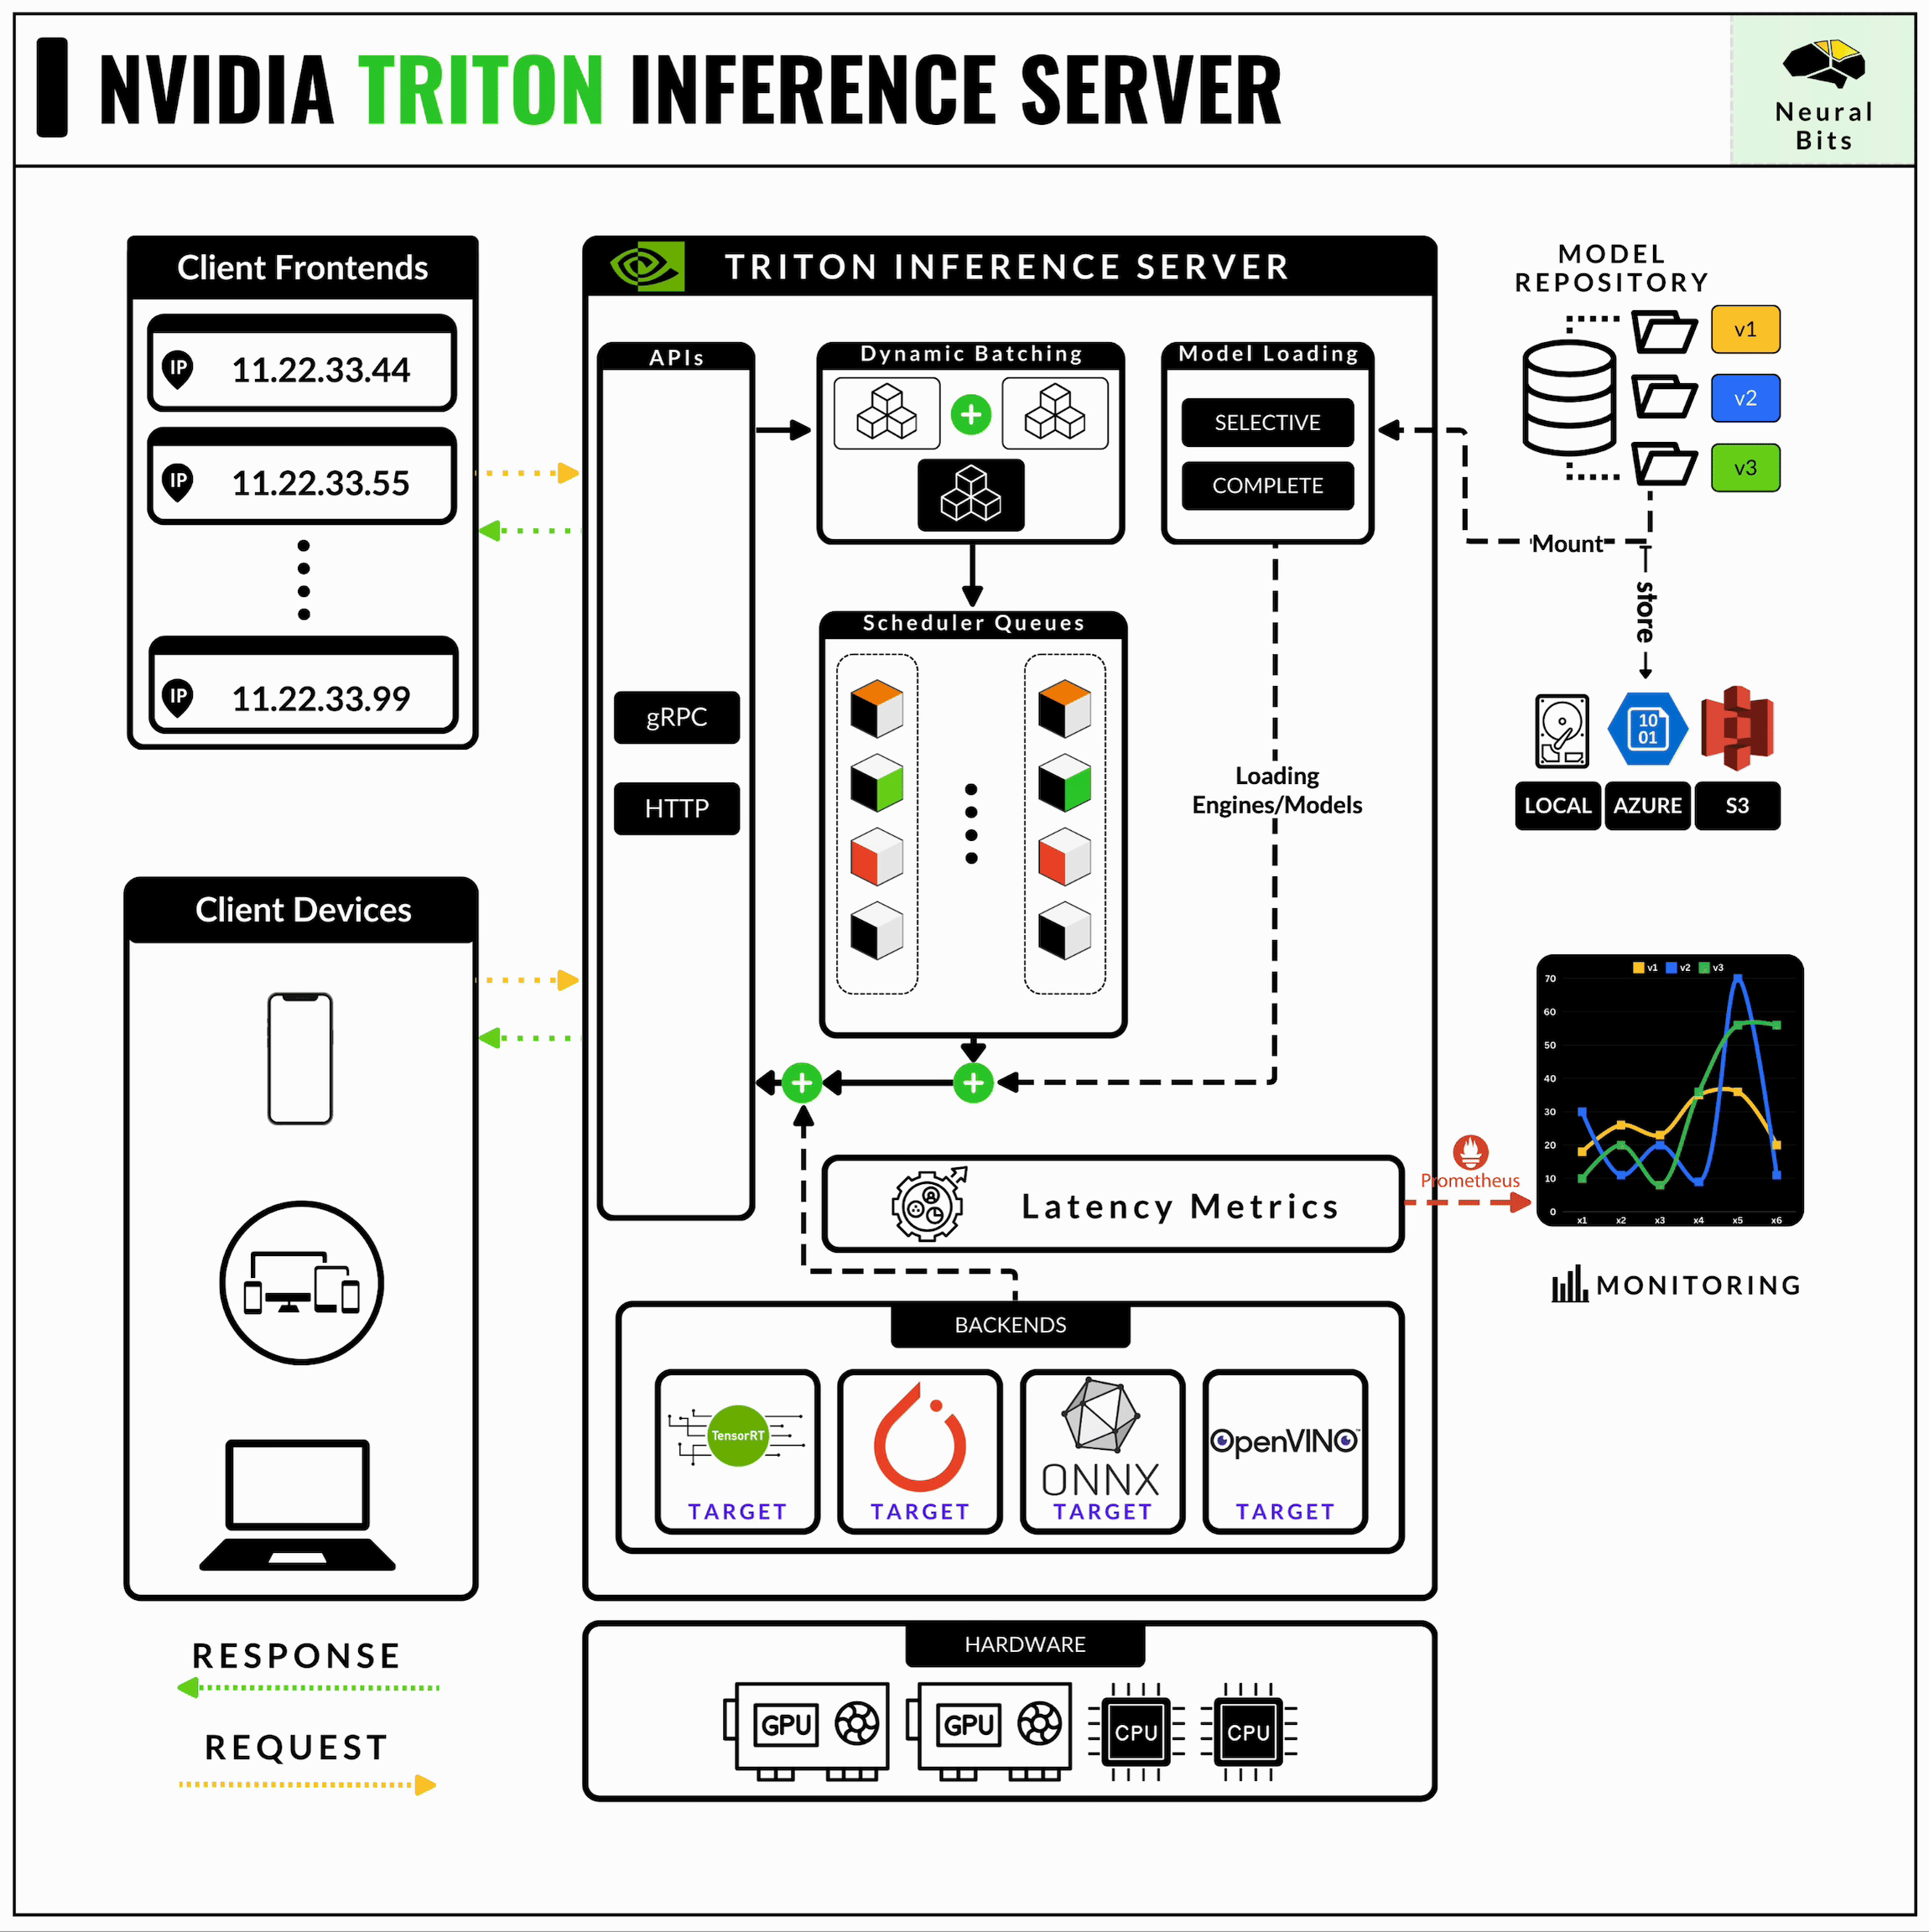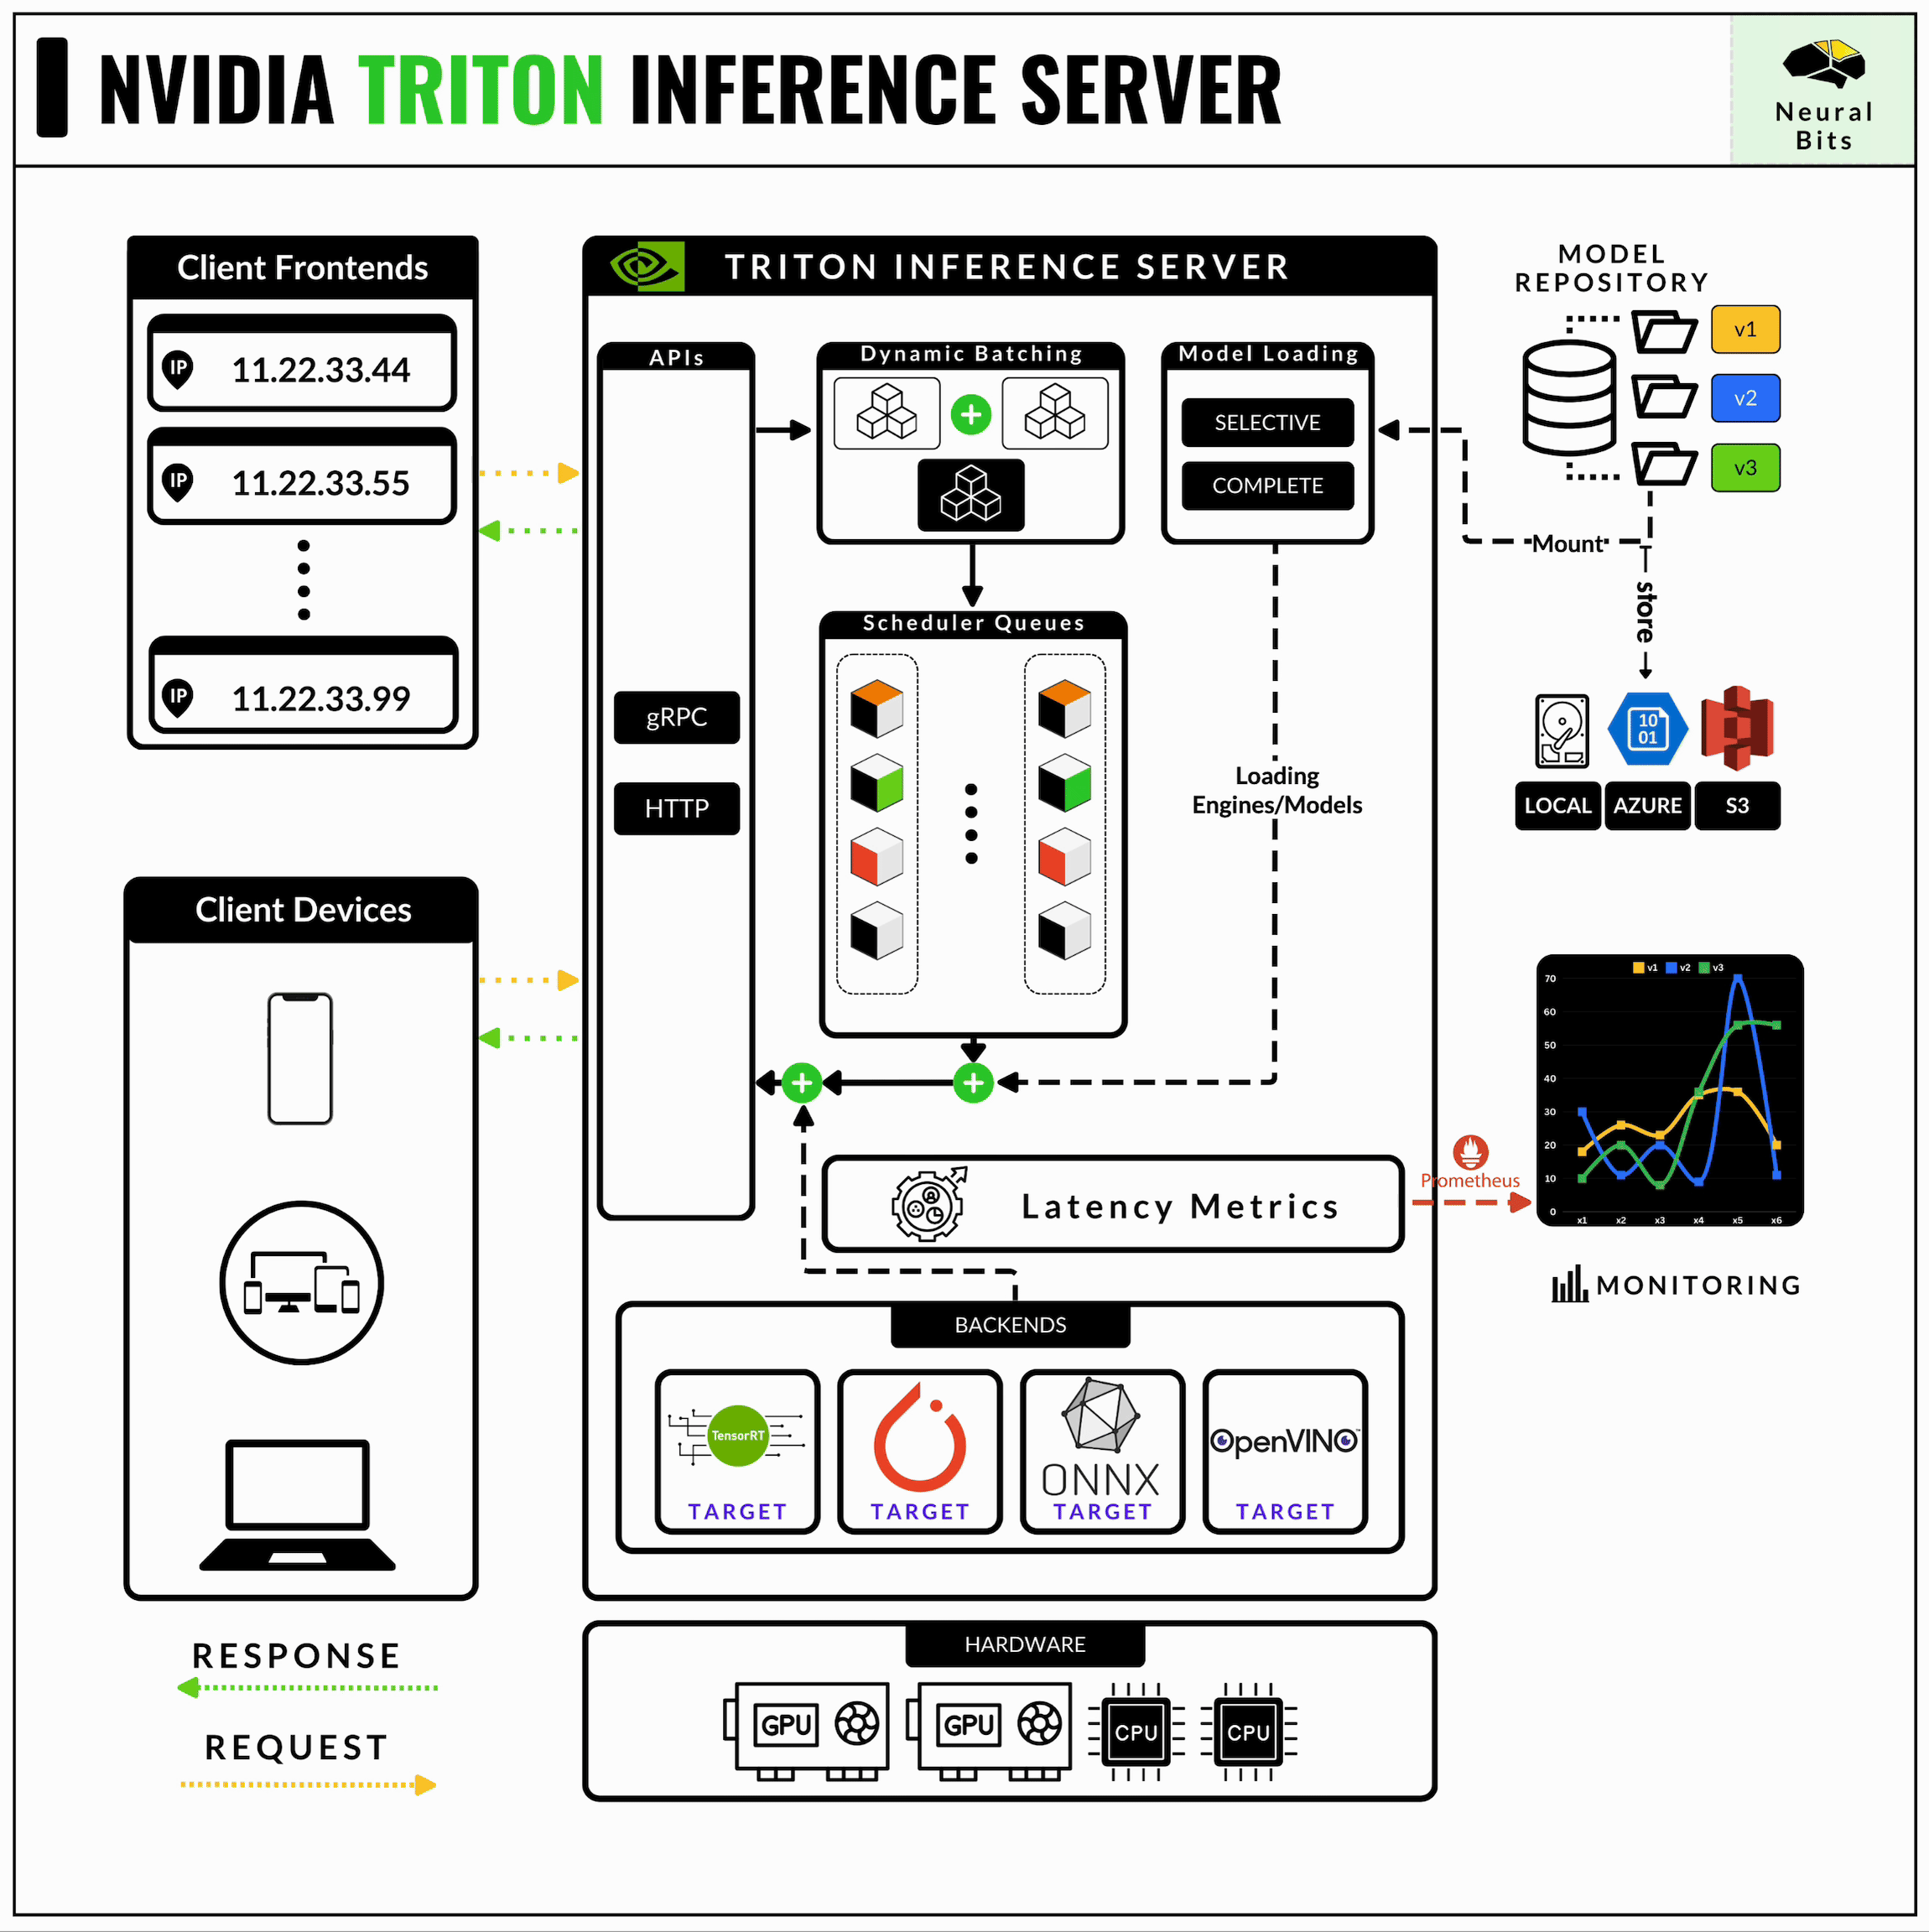
Deploy Triton Inference server and TensorRT-LLM - Cerebrium

TensorRT LLM vs. Triton Inference Server: Optimizing Large Language ...

Architecture — NVIDIA Triton Inference Server 2.0.0 documentation

TensorRT LLM vs. Triton Inference Server: Optimizing Large Language ...

🤖 LLM Inferencing with TensorRT-LLM + Triton Inference Server | by ...

TensorRT LLM vs. Triton Inference Server: Optimizing Large Language ...

Optimizing and Serving Models with NVIDIA TensorRT and NVIDIA Triton ...
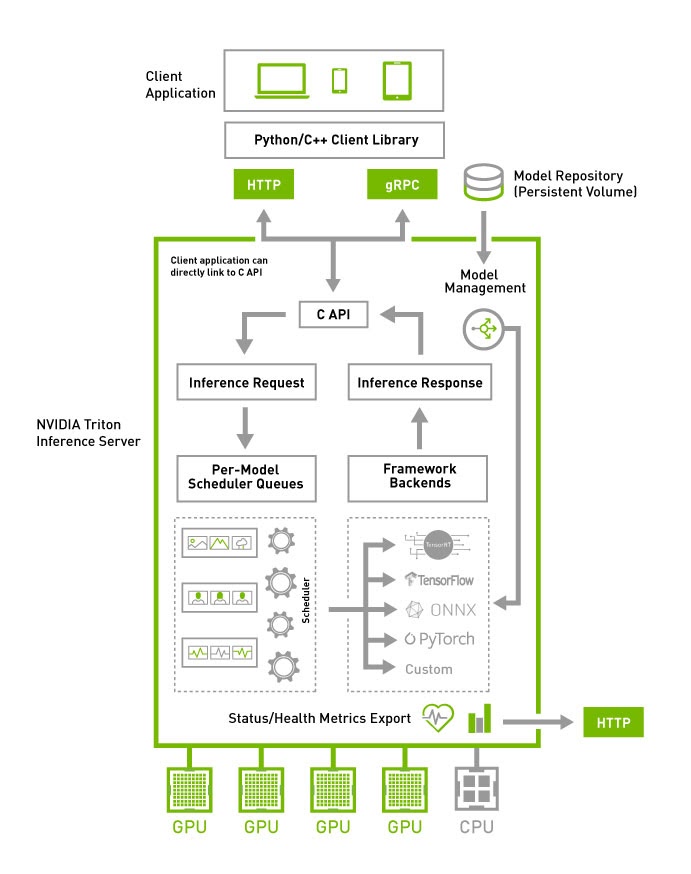
NVIDIA Triton Inference Server | NVIDIA Developer
Advertisement Space (336x280)

TensorRT-LLM Backend — NVIDIA Triton Inference Server
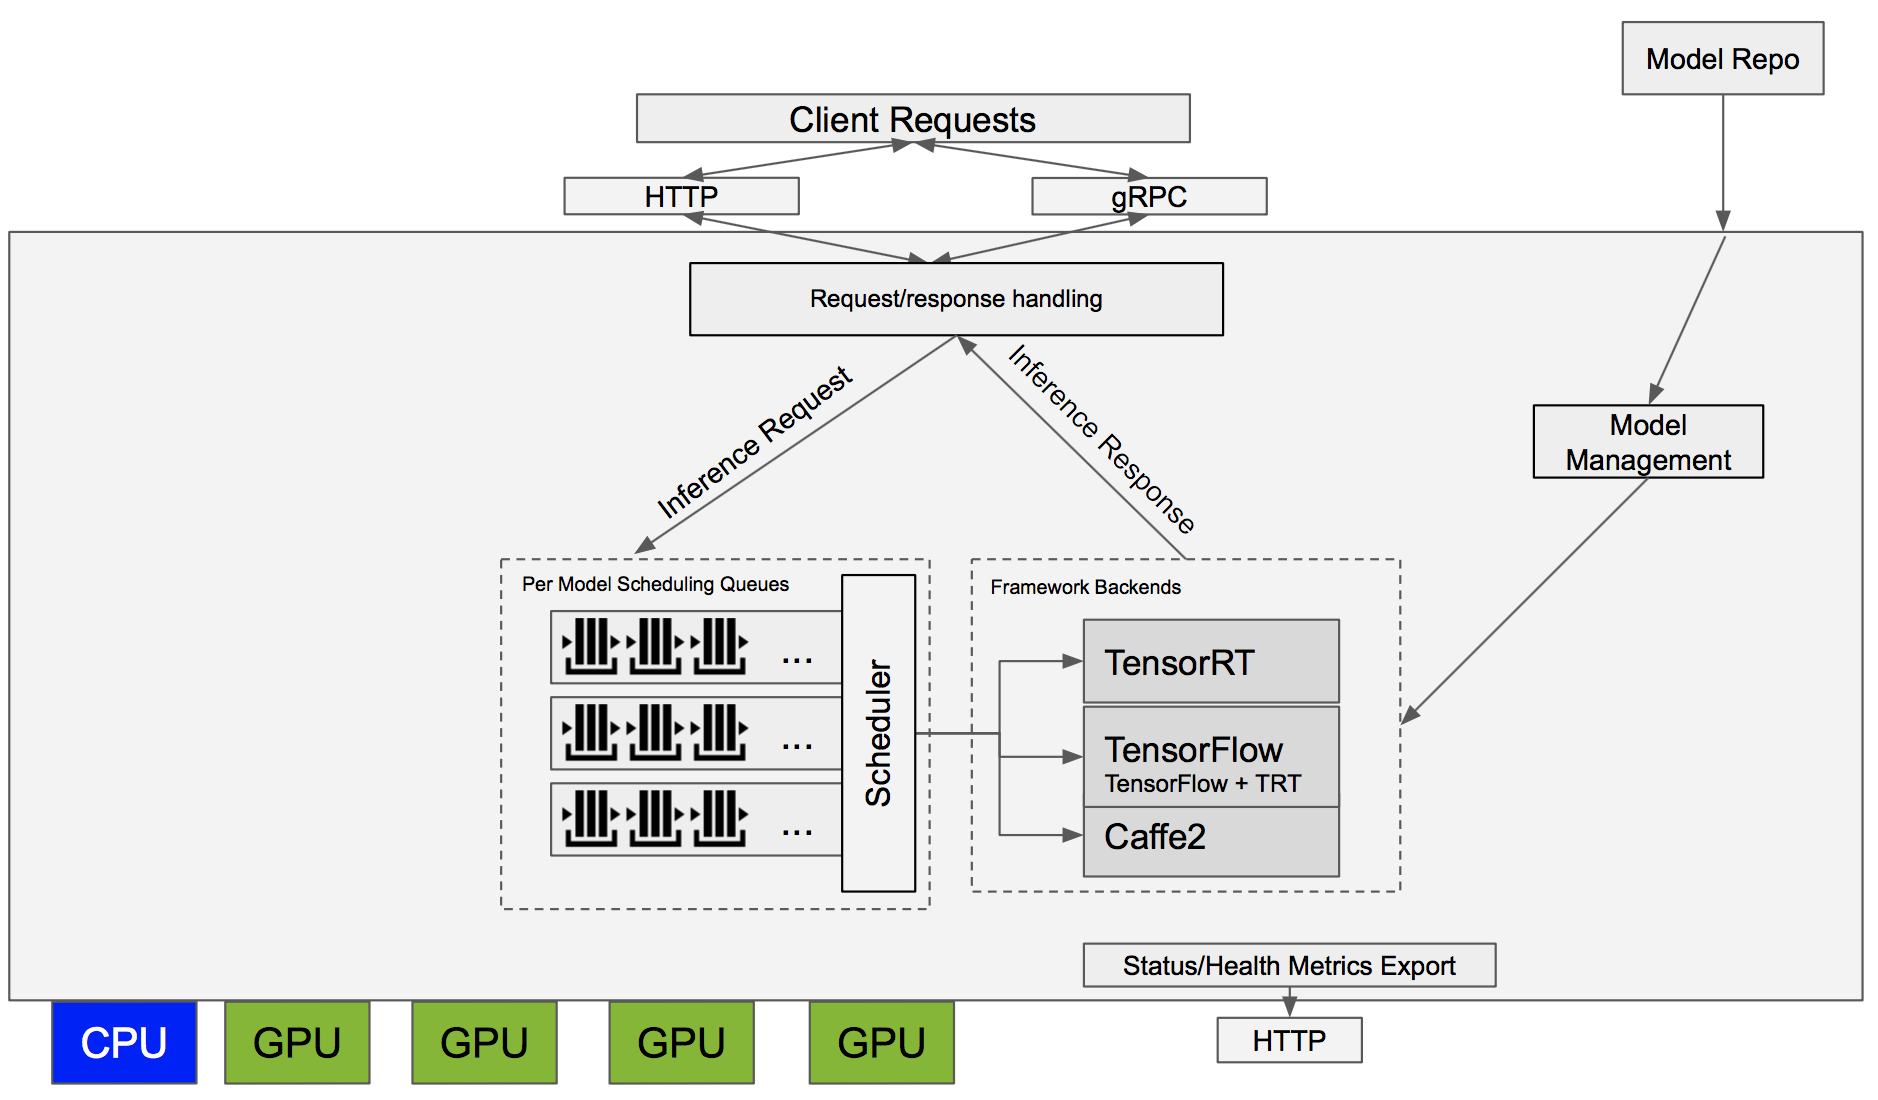
NVIDIA Triton Inference Server Boosts Deep Learning Inference | NVIDIA ...

How to Deploy Inference Using NVIDIA Dynamo and TensorRT-LLM | Vultr Docs
Deploy NVIDIA Triton Inference Server on GPU Cloud: Production Multi ...
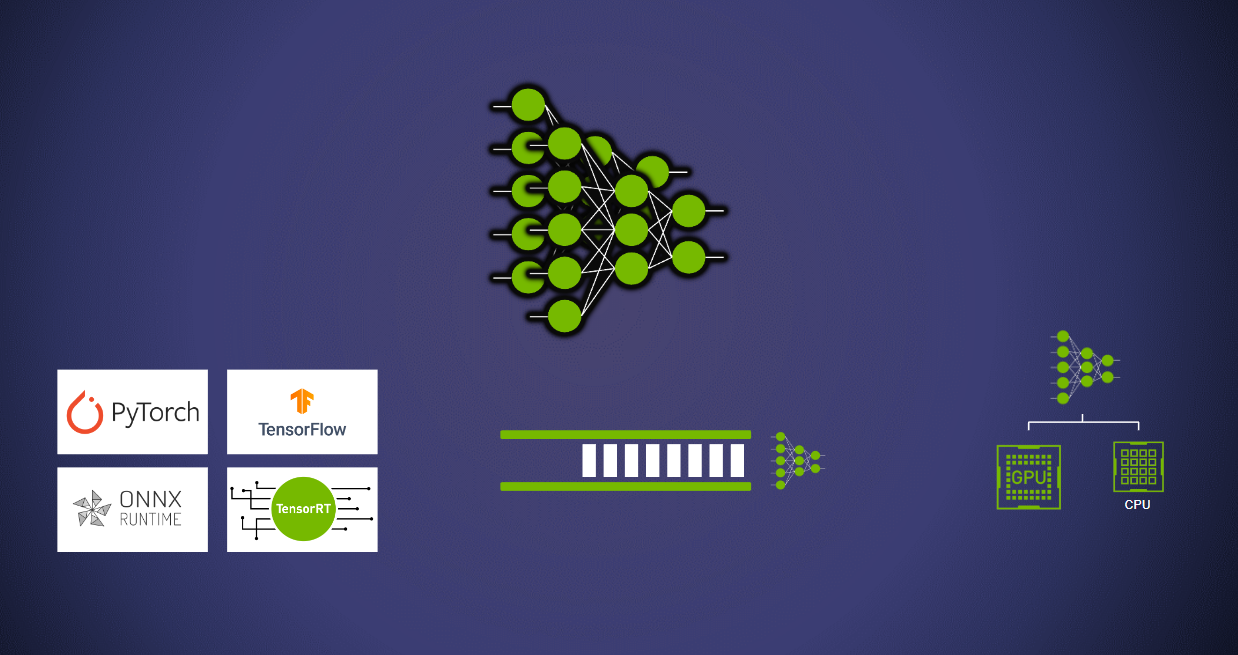
Deploy models using Triton — NVIDIA Triton Inference Server

Optimizing and Serving Models with NVIDIA TensorRT and NVIDIA Triton ...