
Llm Gpu Lmdeploy
LLM 低成本 GPU 部署方案 lmdeploy 开源 - 知乎
LLM 低成本 GPU 部署方案 lmdeploy 开源 - 知乎
LLM 低成本 GPU 部署方案 lmdeploy 开源 - 知乎
LLM 低成本 GPU 部署方案 lmdeploy 开源 - 知乎

LMDeploy Accelerates Mixed-Precision LLM Inference with TurboMind
Deploy LMDeploy on GPU Cloud: TurboMind Inference for InternLM, Qwen3 ...

LMDeploy 量化部署 LLM 实践 | shmaur - shmaur
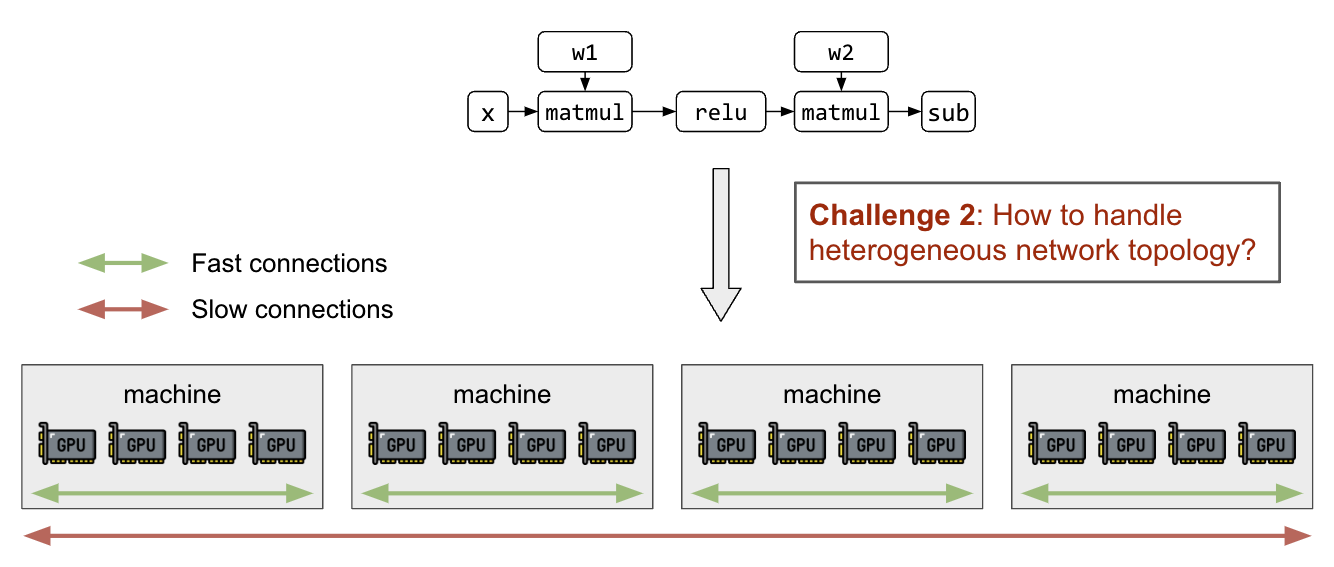
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray

How To Serve LLM on Multiple GPUs Locally with LMDeploy - YouTube

The LLM GPU Buying Guide - August 2023 : r/LocalLLaMA
Advertisement Space (300x250)
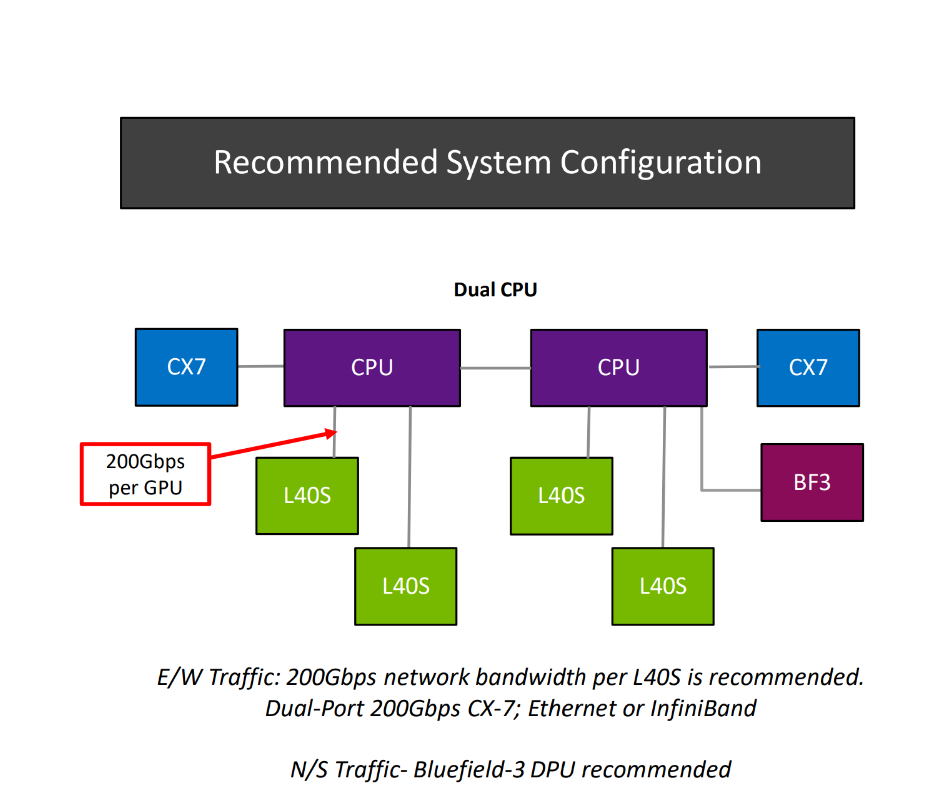
Choosing the Right GPU for LLM Inference and Training
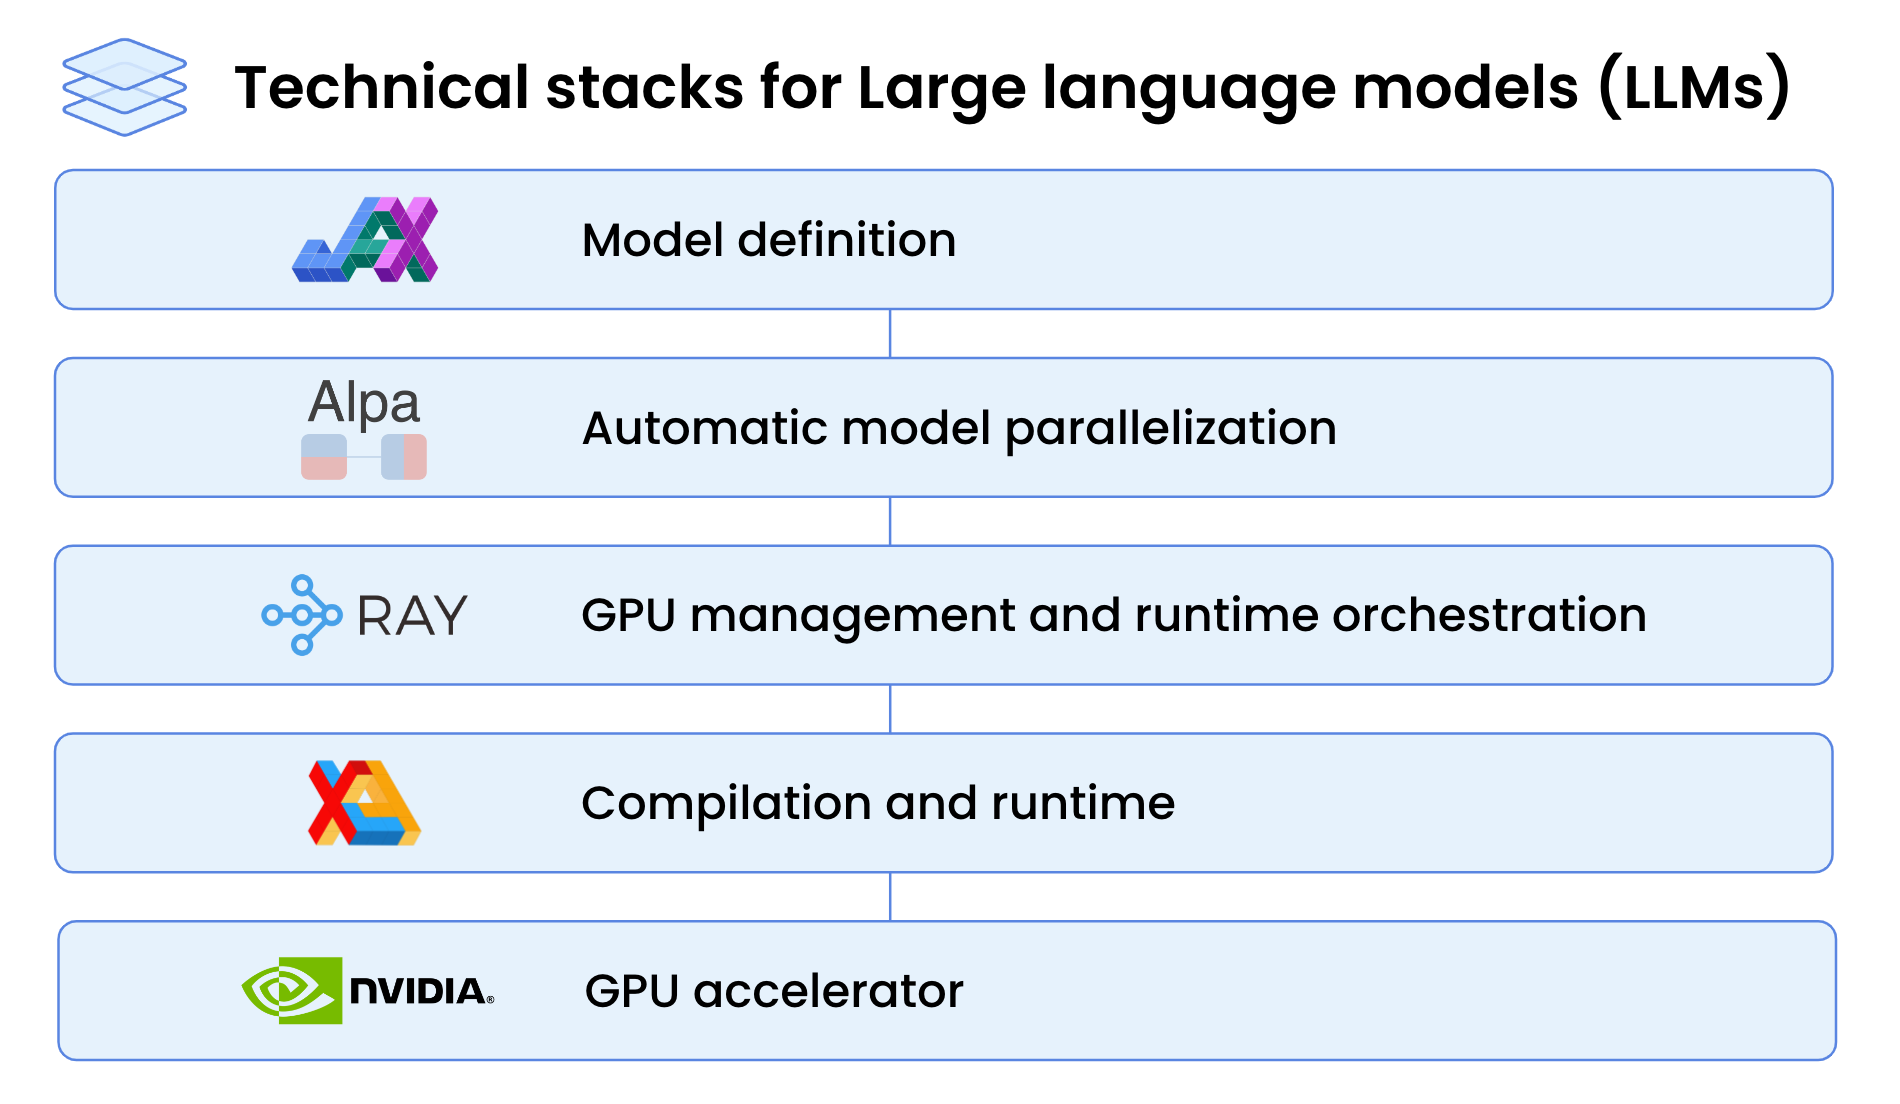
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray

Best GPU for LLM in 2026: 7 Local & Cloud Picks
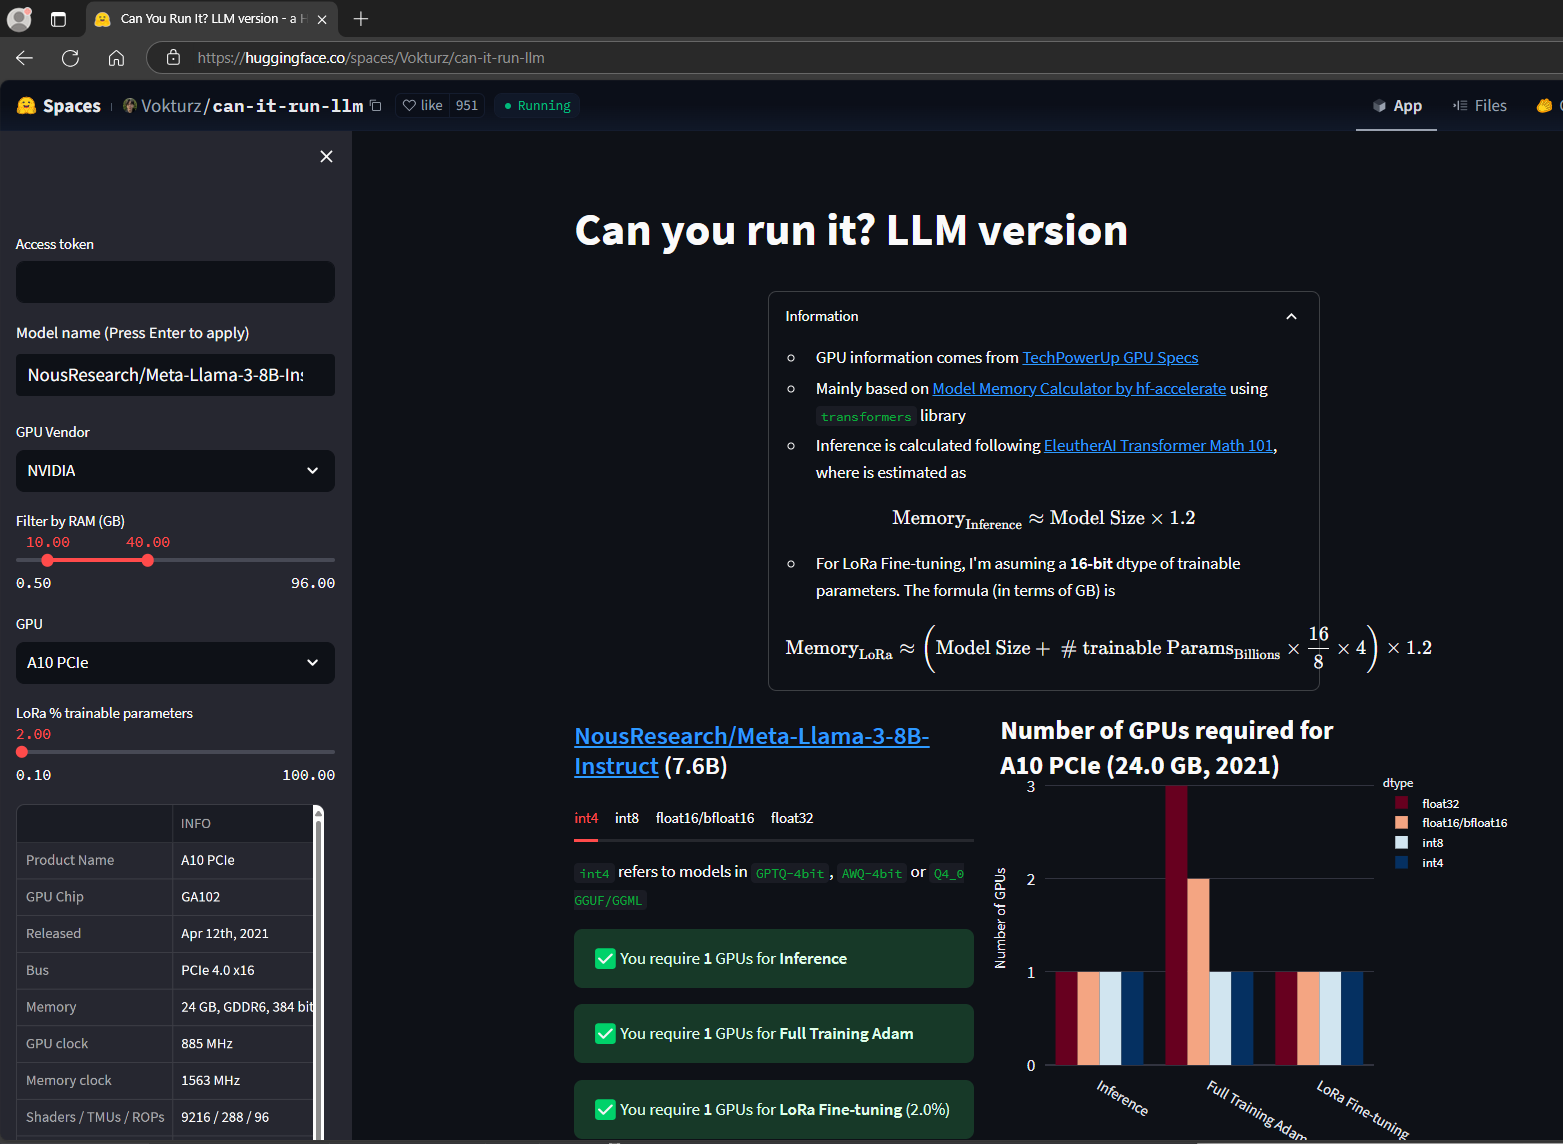
LLM 구동을 위한 GPU 메모리 계산 완벽 가이드 (Can it Run LLM? 도구 포함) - Huni TechNote

LMDeploy 量化部署 LLM 实践_how to train llm and deploy-CSDN博客
Production LLM API with GPU Auto Scaling in Under an Hour
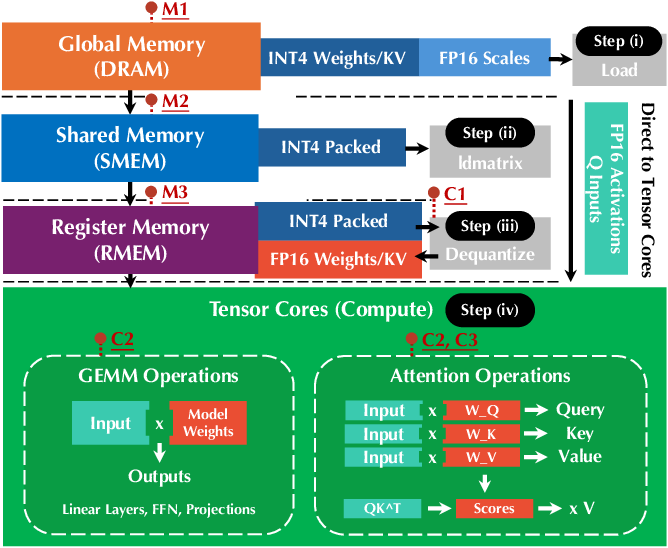
Figure 1 from LMDeploy Accelerates Mixed-Precision LLM Inference with ...
Embedded LLM Launches TokenVisor to Monetize AMD AI GPU

Predictable LLM Serving on GPU Clusters | AI Research Paper Details
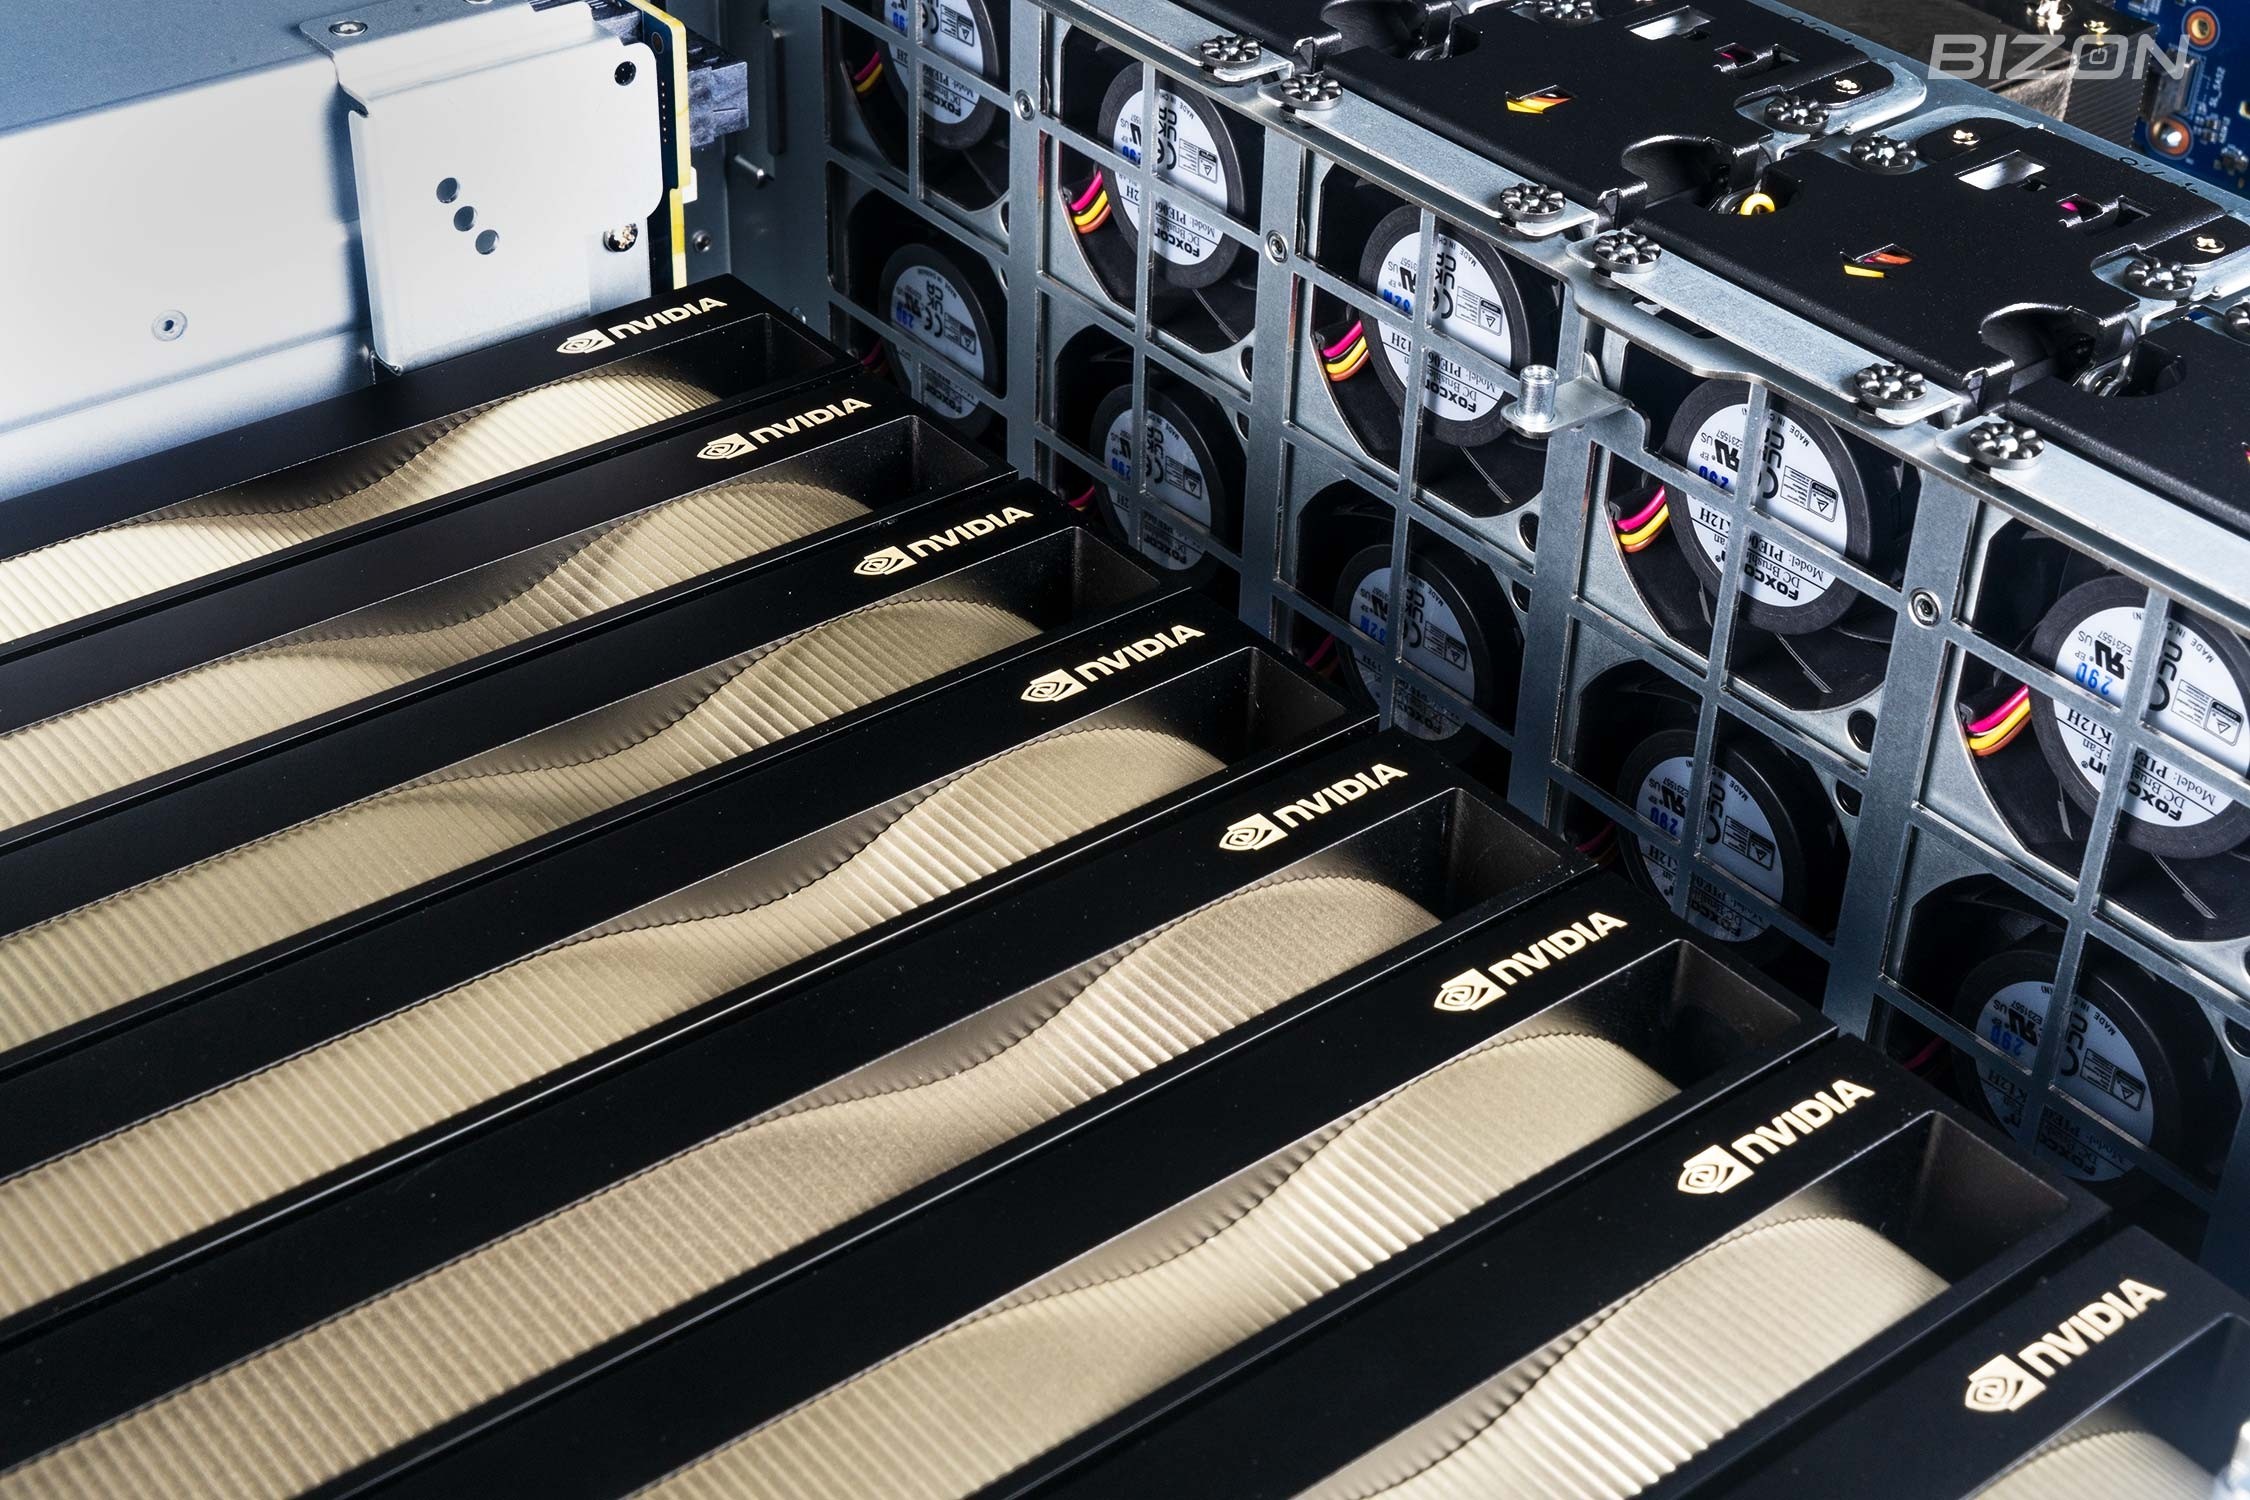
Best GPU for LLM Inference and Training – March 2024 [Updated] | BIZON
Advertisement Space (336x280)
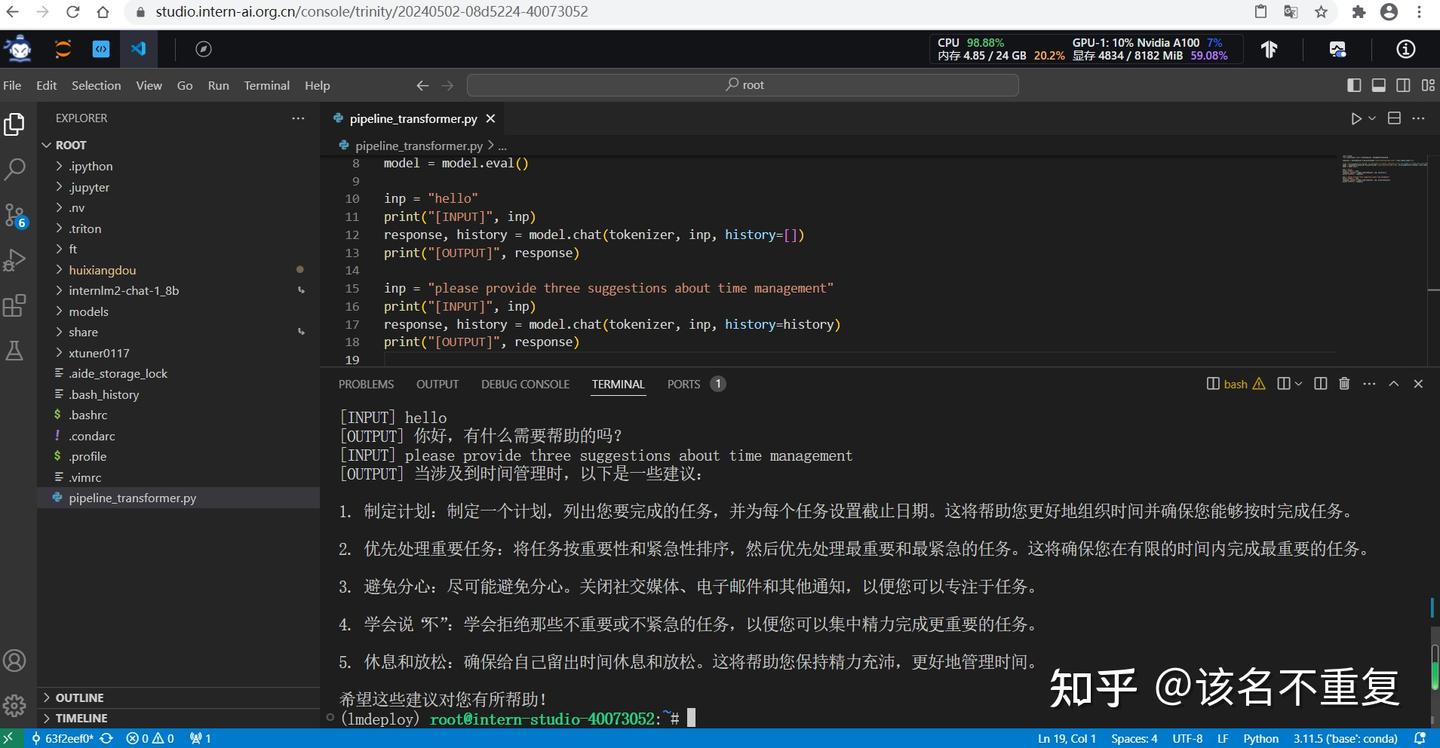
LMDeploy 部署 LLM 实践 - 知乎
Deploy easily your LLM with Serverless GPU - avec @jlandure - YouTube
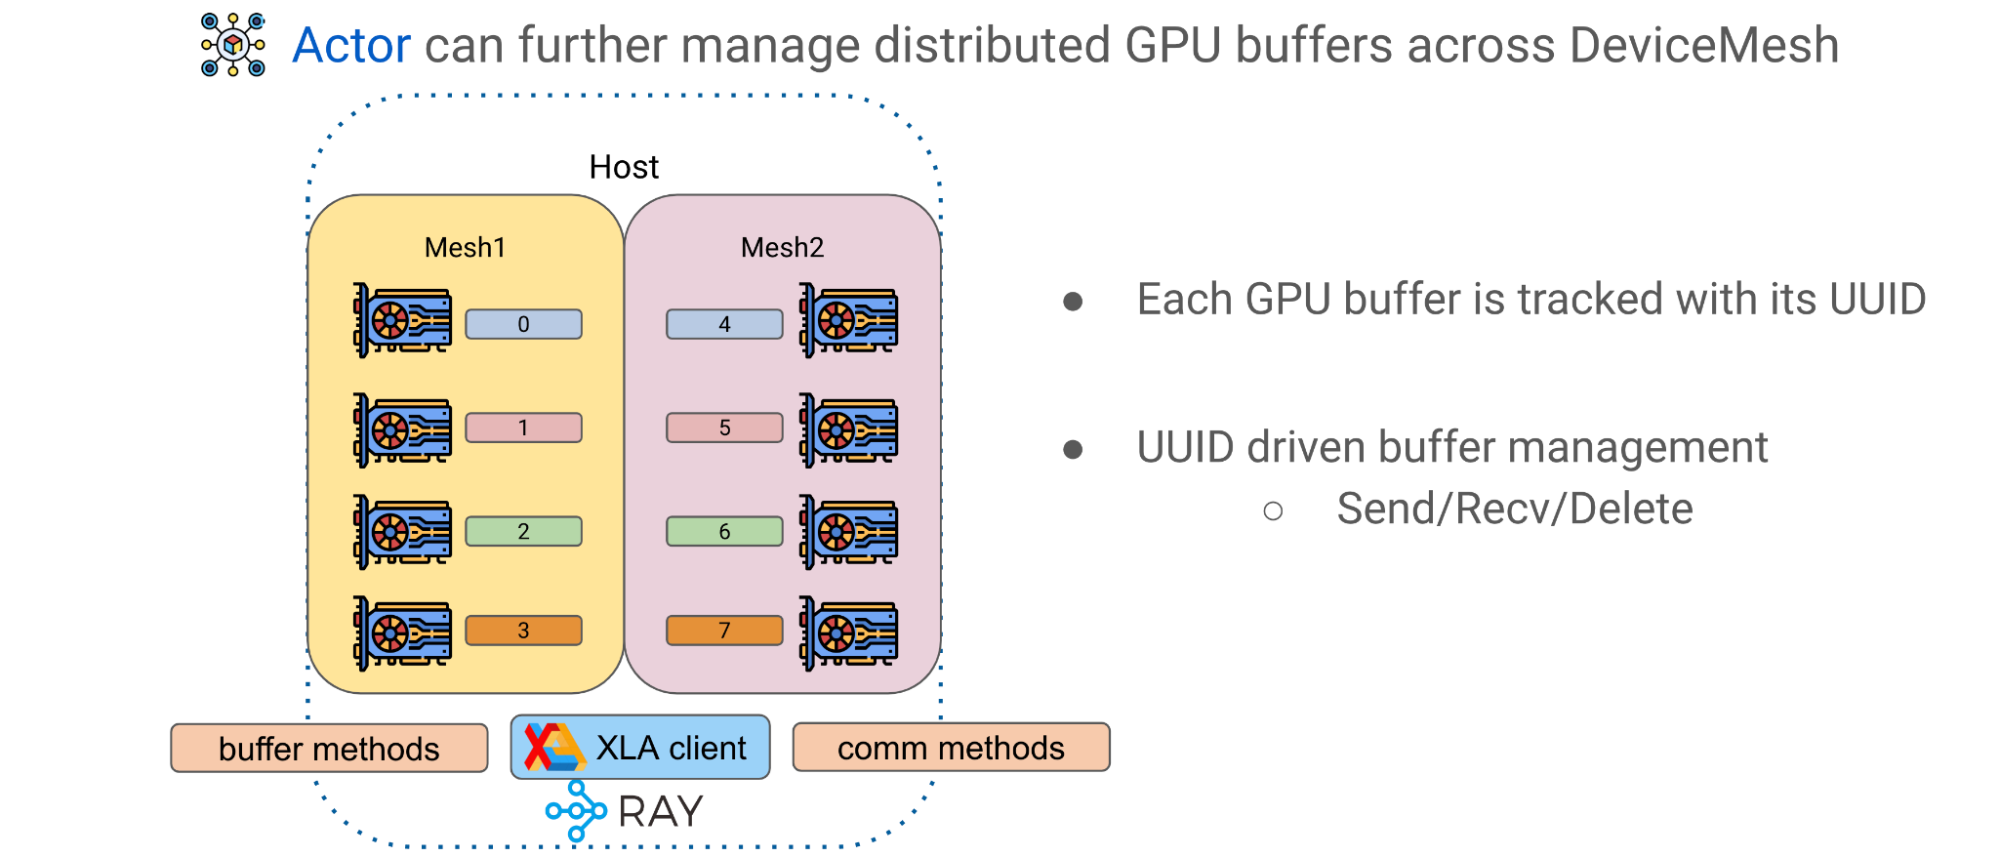
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray

GPU Kernel Optimization Beyond Full Builds: An LLM Framework with ...
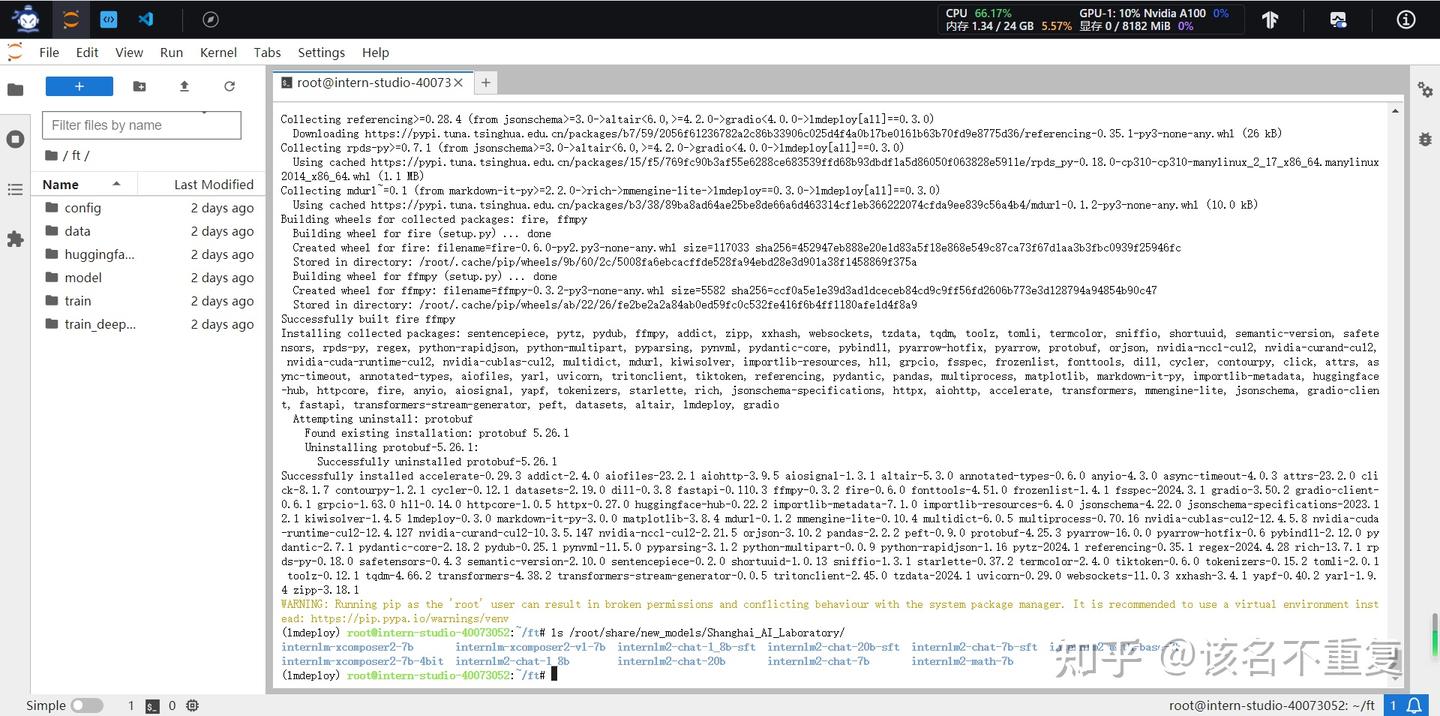
LMDeploy 部署 LLM 实践 - 知乎

Install, setup llm locally or on gpu cloud by Nocodedeveloper | Fiverr

LMDeploy 量化部署 LLM 实践 | shmaur - shmaur
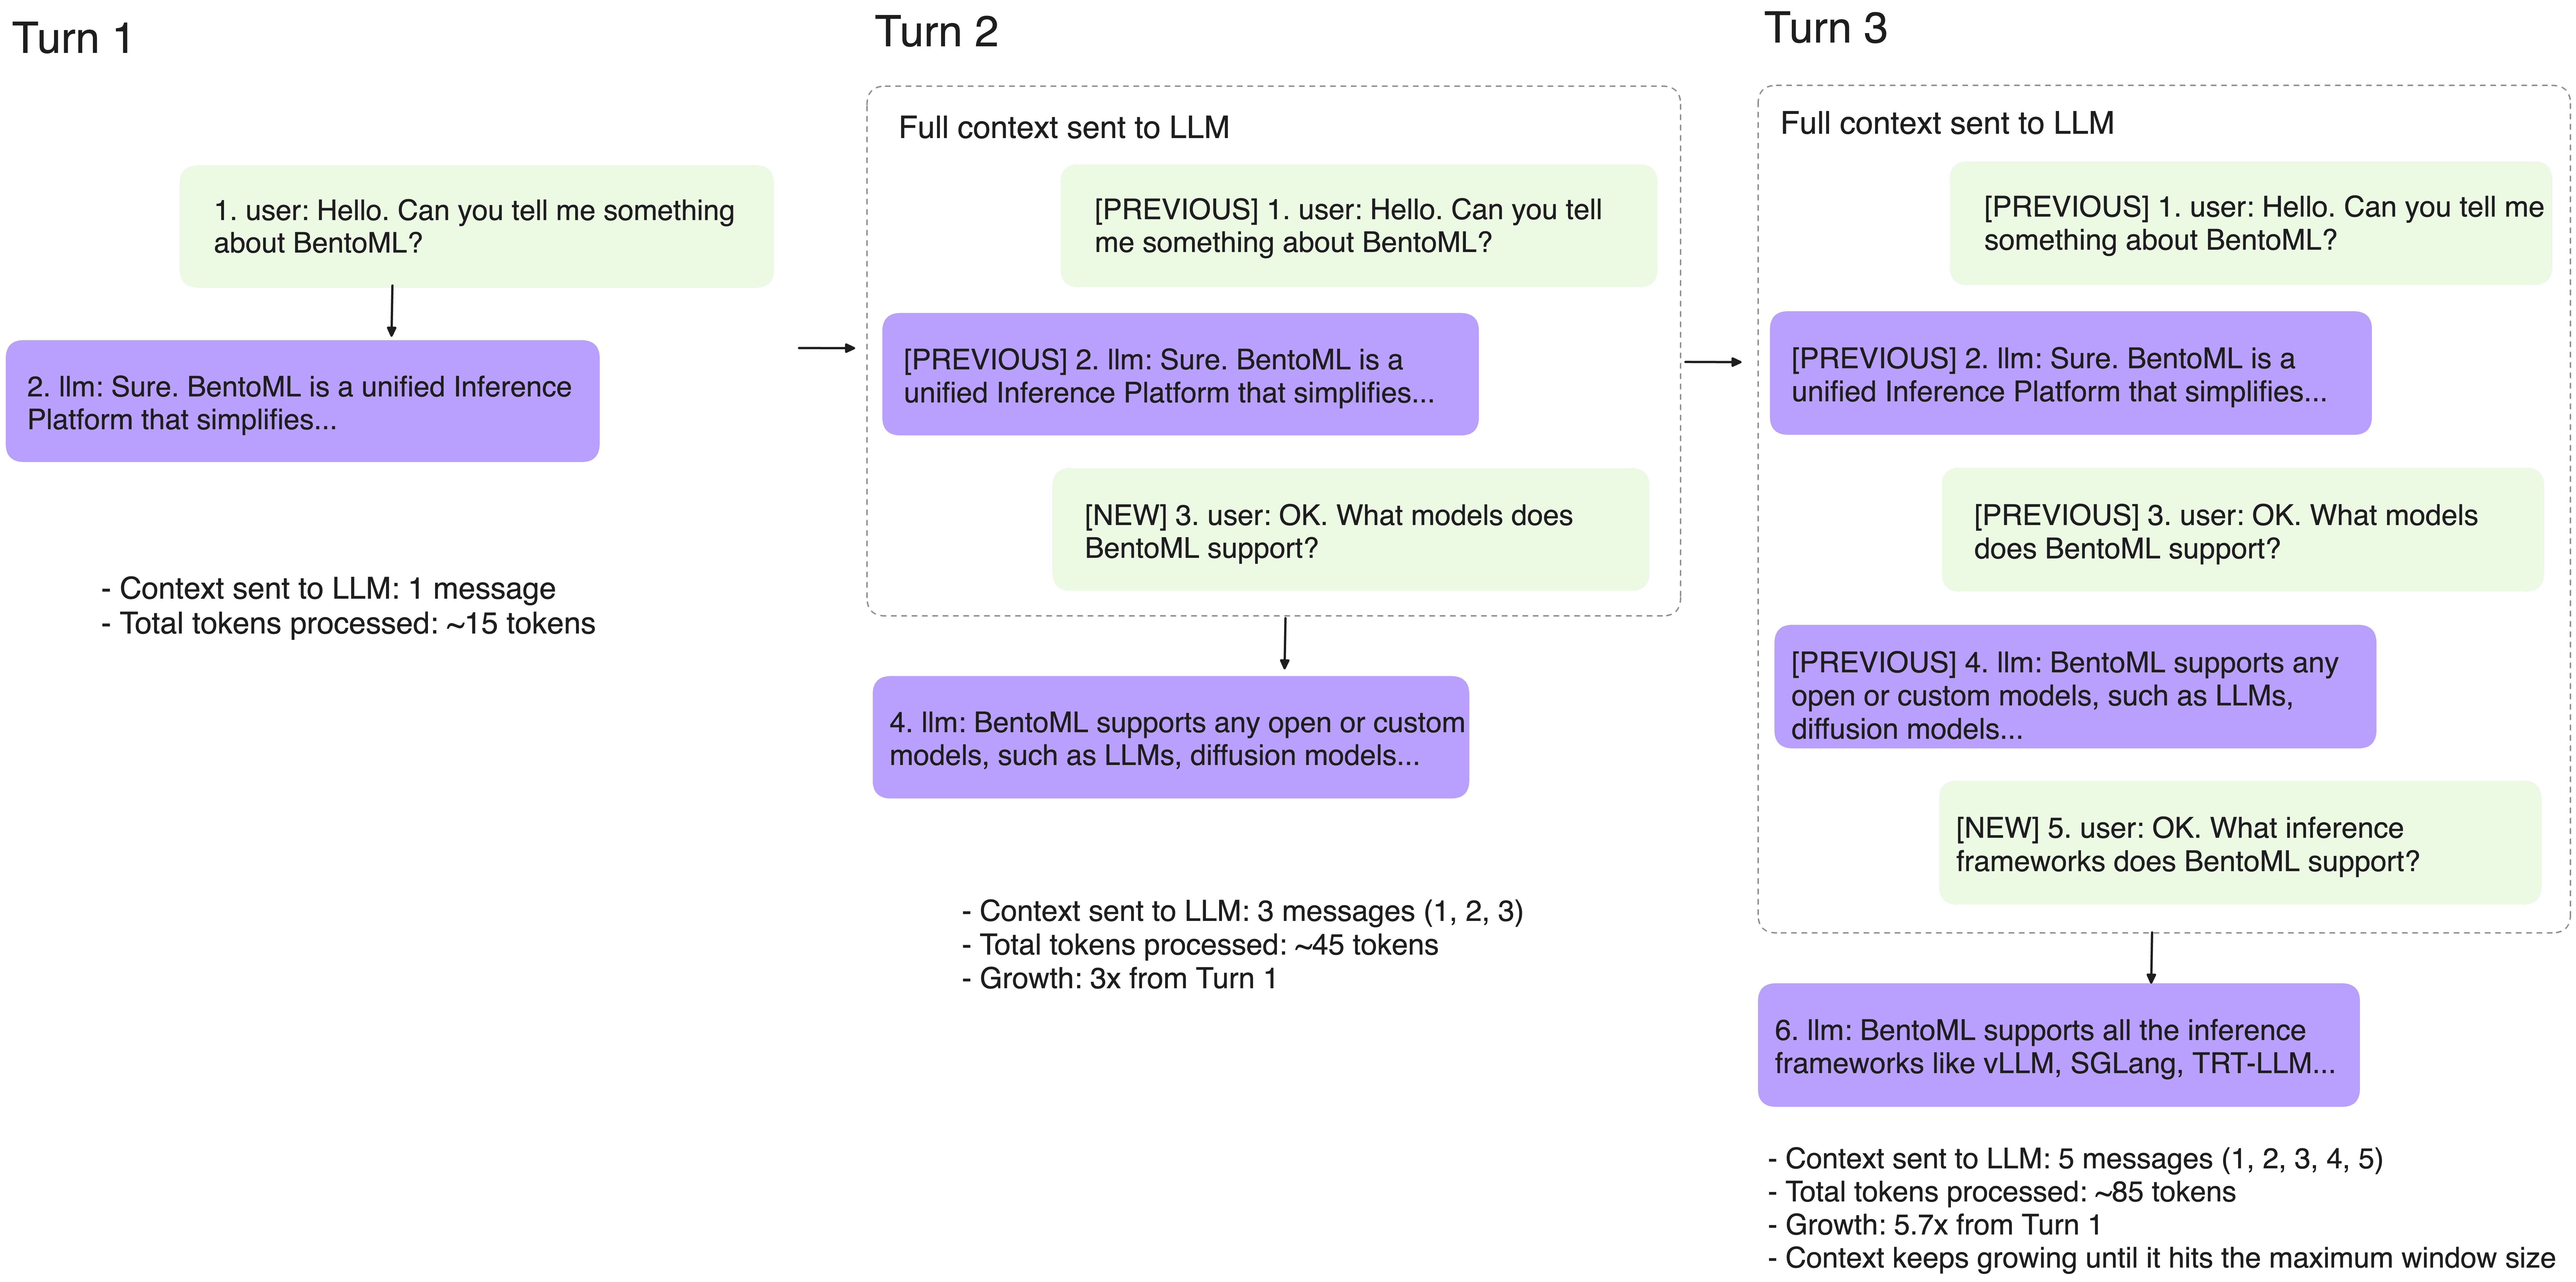
What is GPU Memory and Why it Matters for LLM Inference
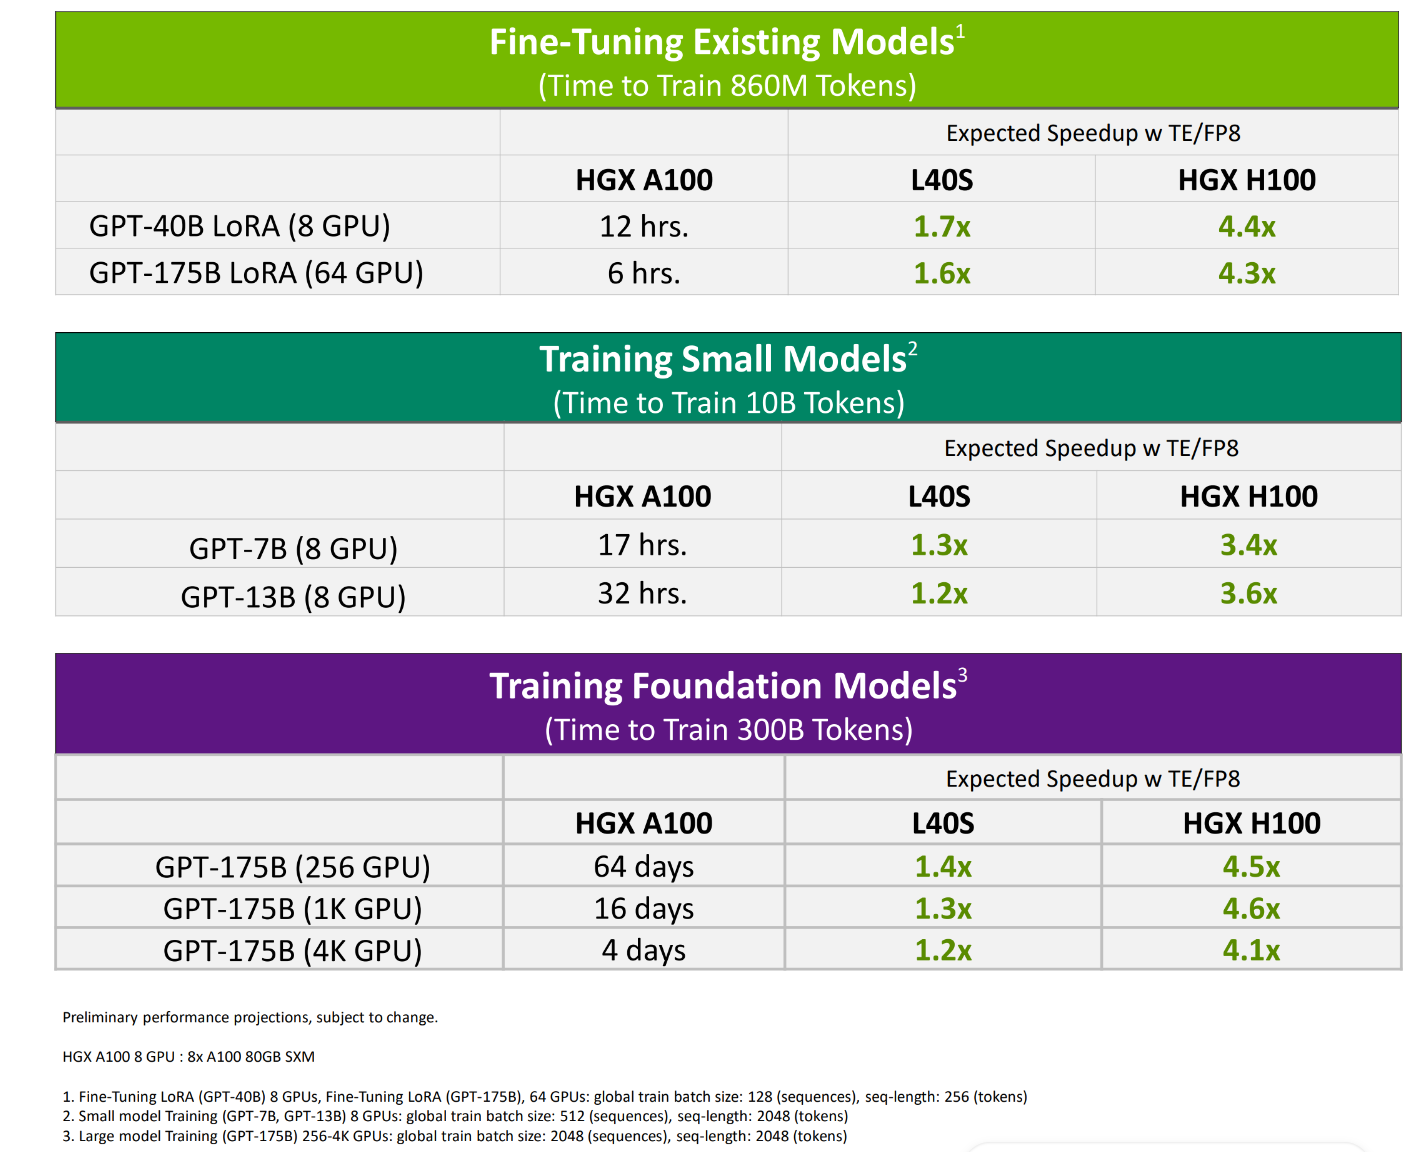
Choosing the Right GPU for LLM Inference and Training
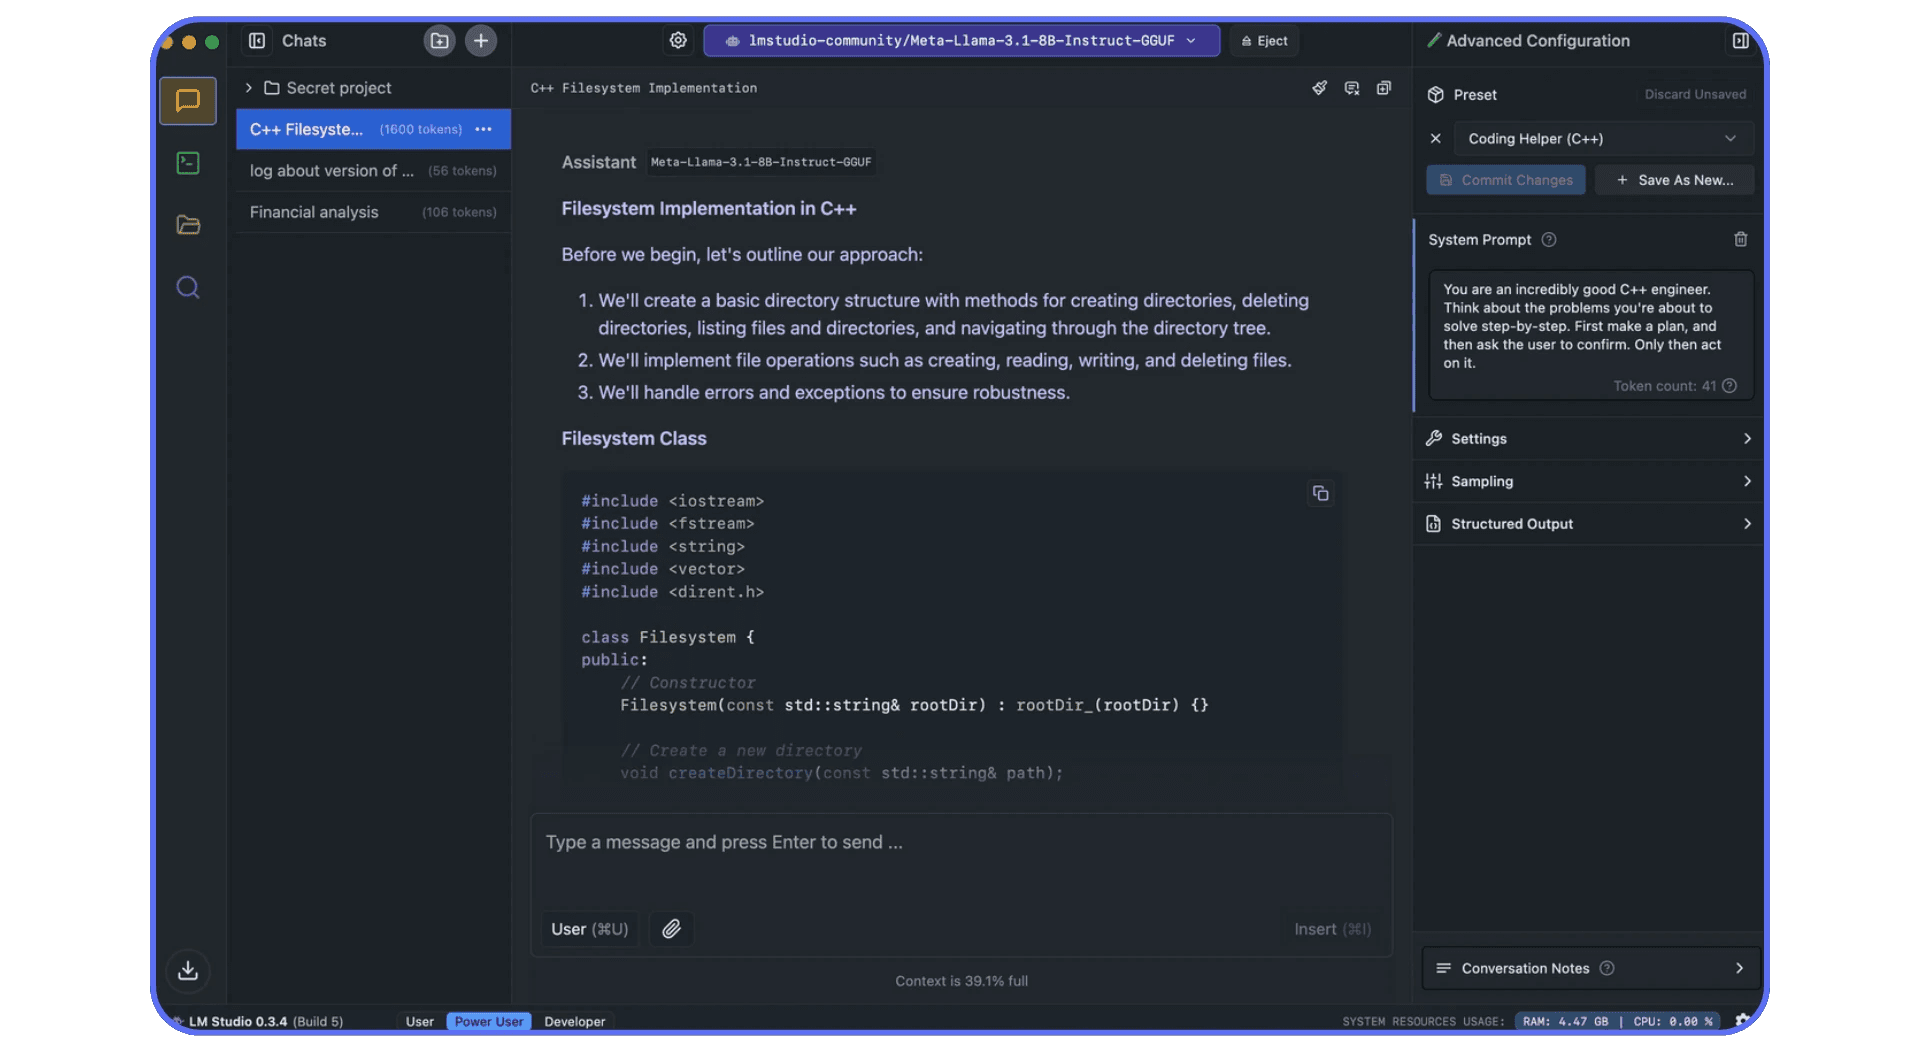
How to Use GPU on LLM Studio | GPU Acceleration Guide
Advertisement Space (336x280)

How to Launch a Production Ready LLM API with GPU Auto Scaling in Under ...
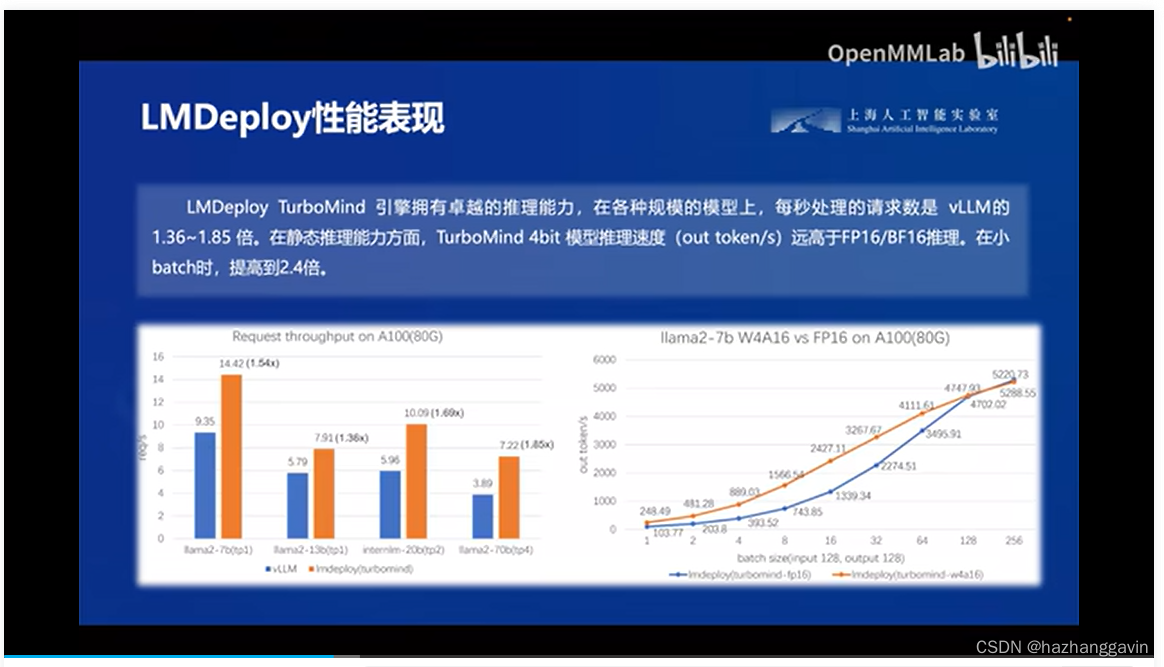
LMDeploy 量化部署 LLM&VLM实战——学习笔记_lmdeploy multi gpu-CSDN博客
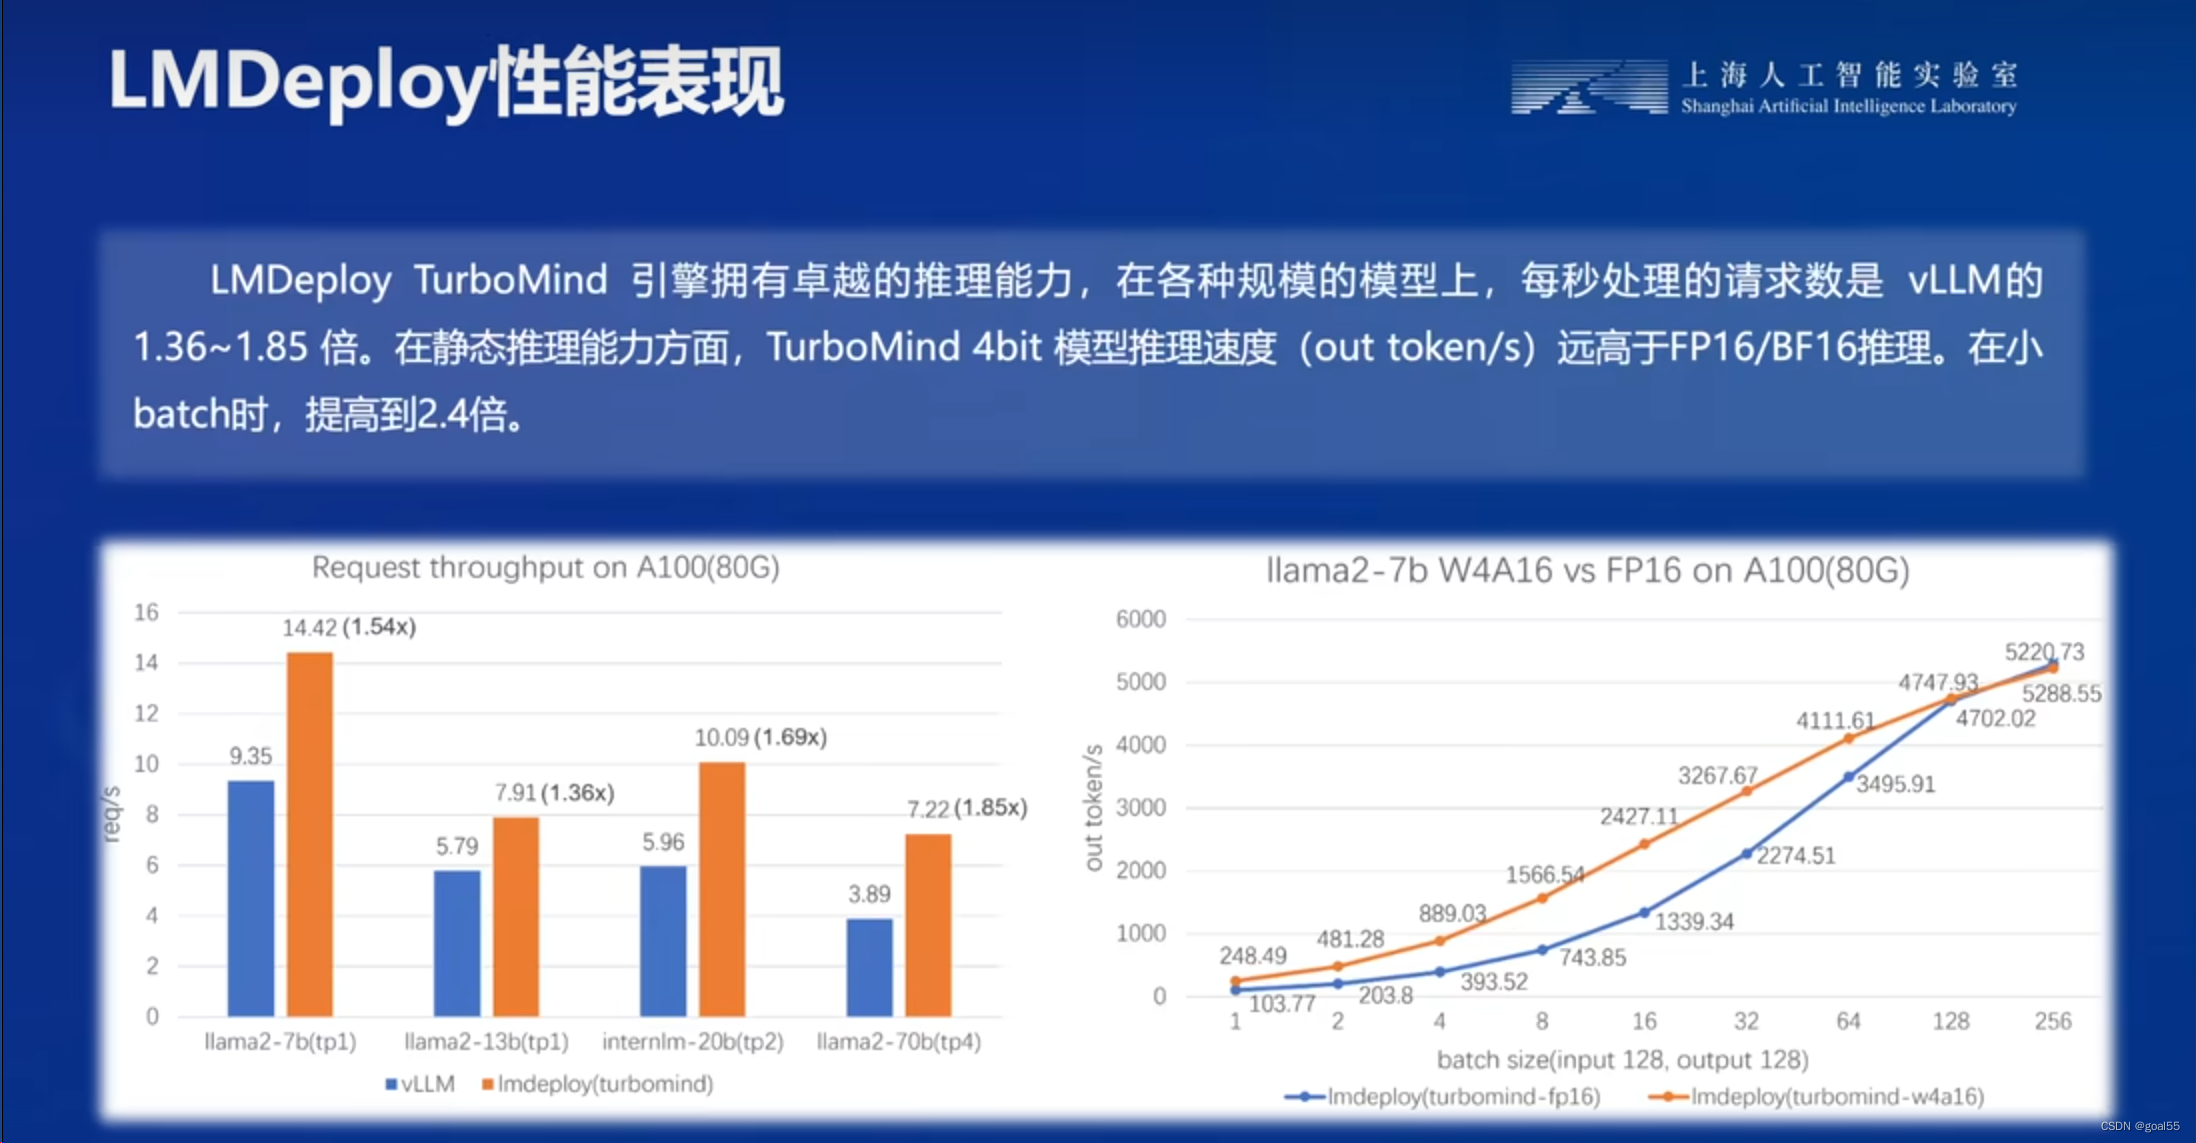
第五课 LMDeploy 量化部署 LLM-VLM 实践_lmdeploy 安装-CSDN博客
Streamline LLM Deployment for Autonomous Vehicle Applications with ...

05【LMDeploy 量化部署 LLM 实践】笔记+作业 - 知乎

[论文评述] Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...