
Llm Inference Optimizing The Kv Cache For High Throughput Long

LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
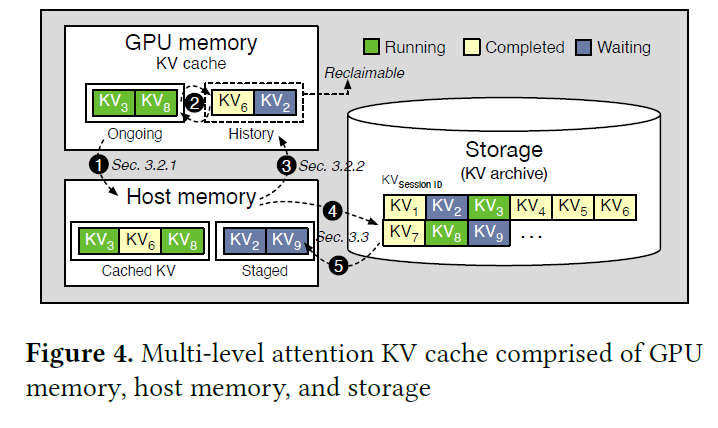
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
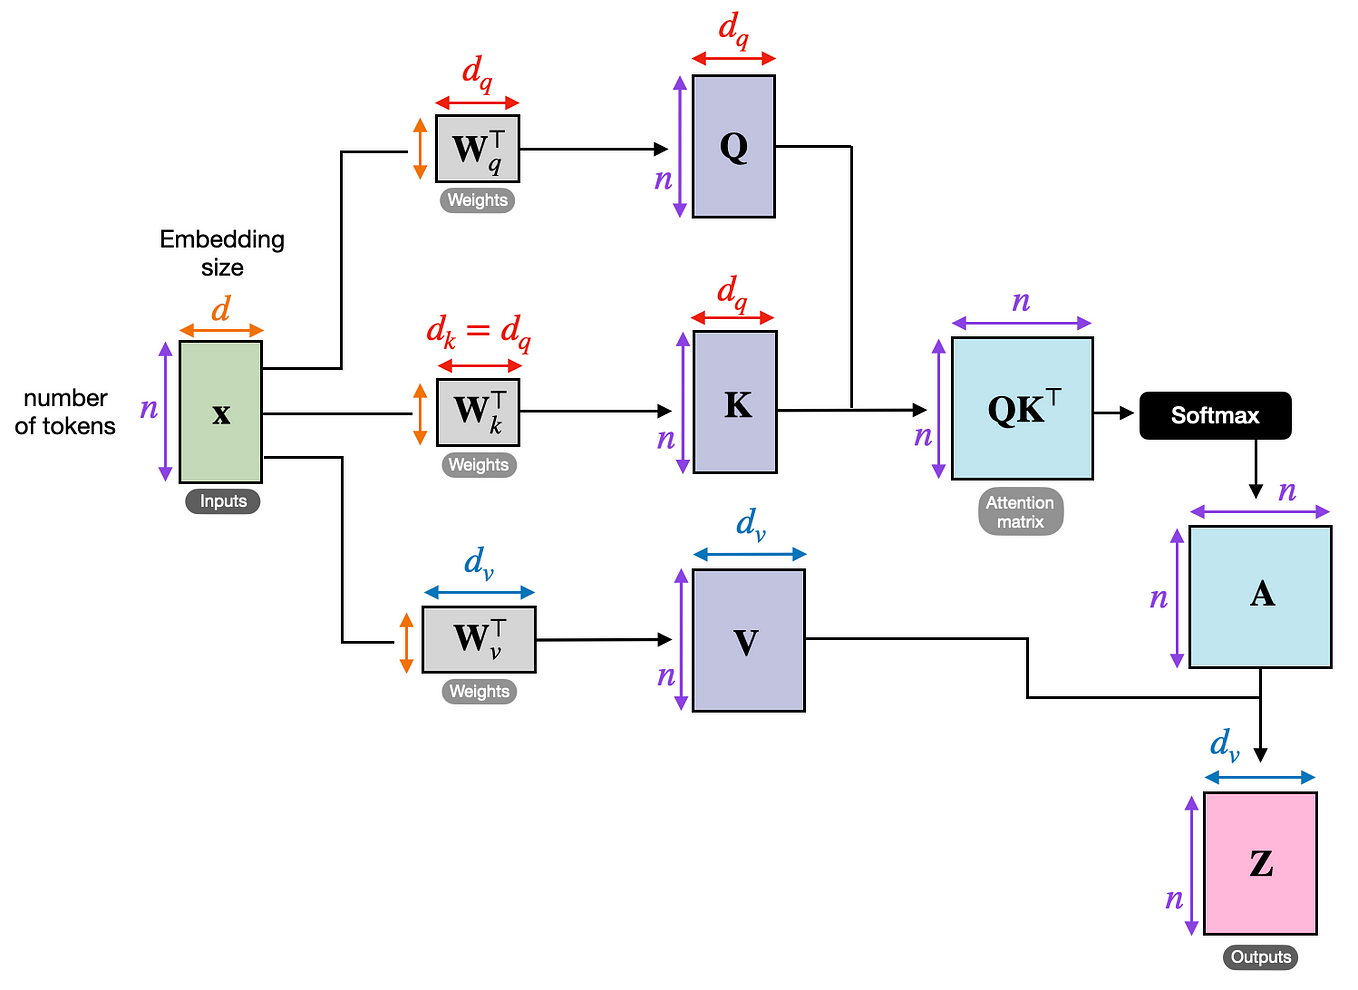
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
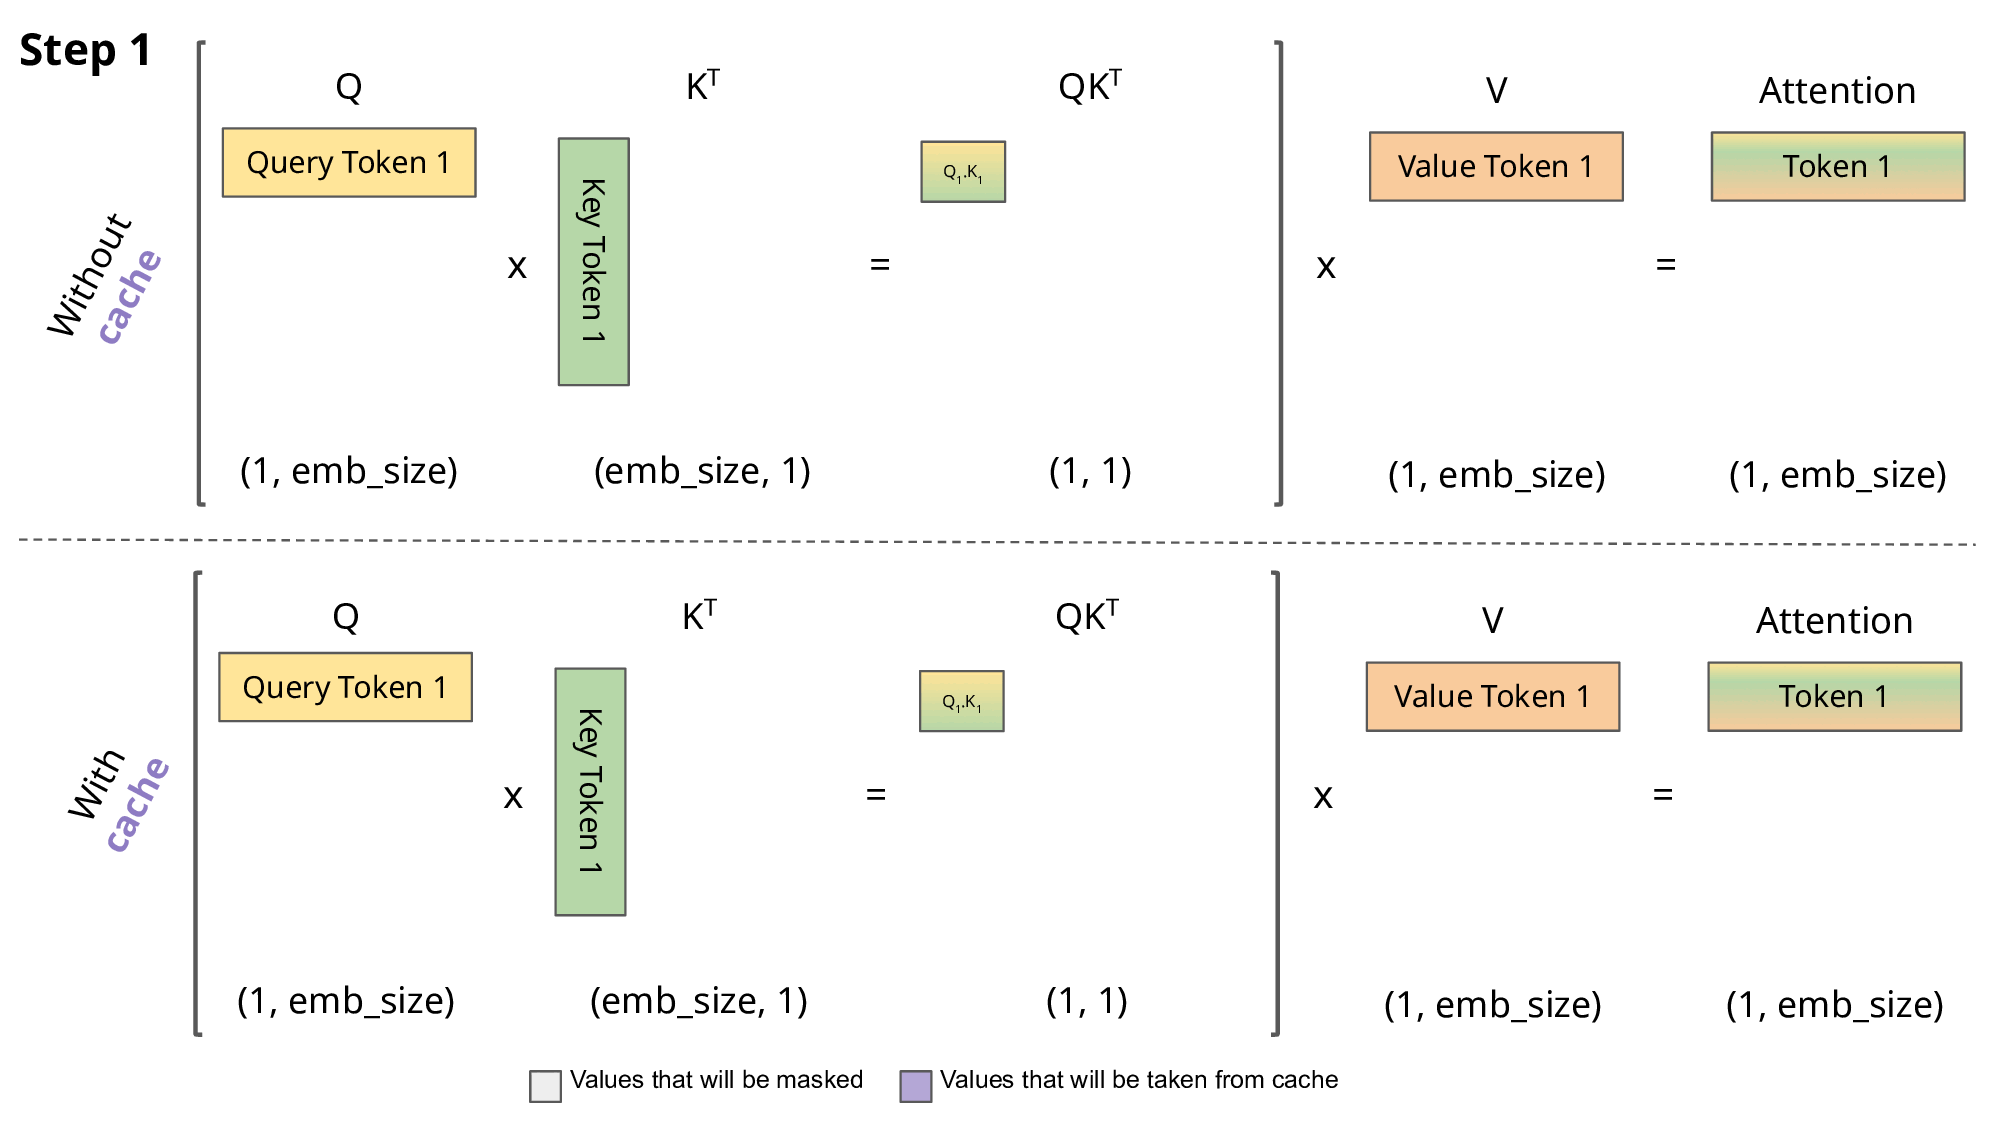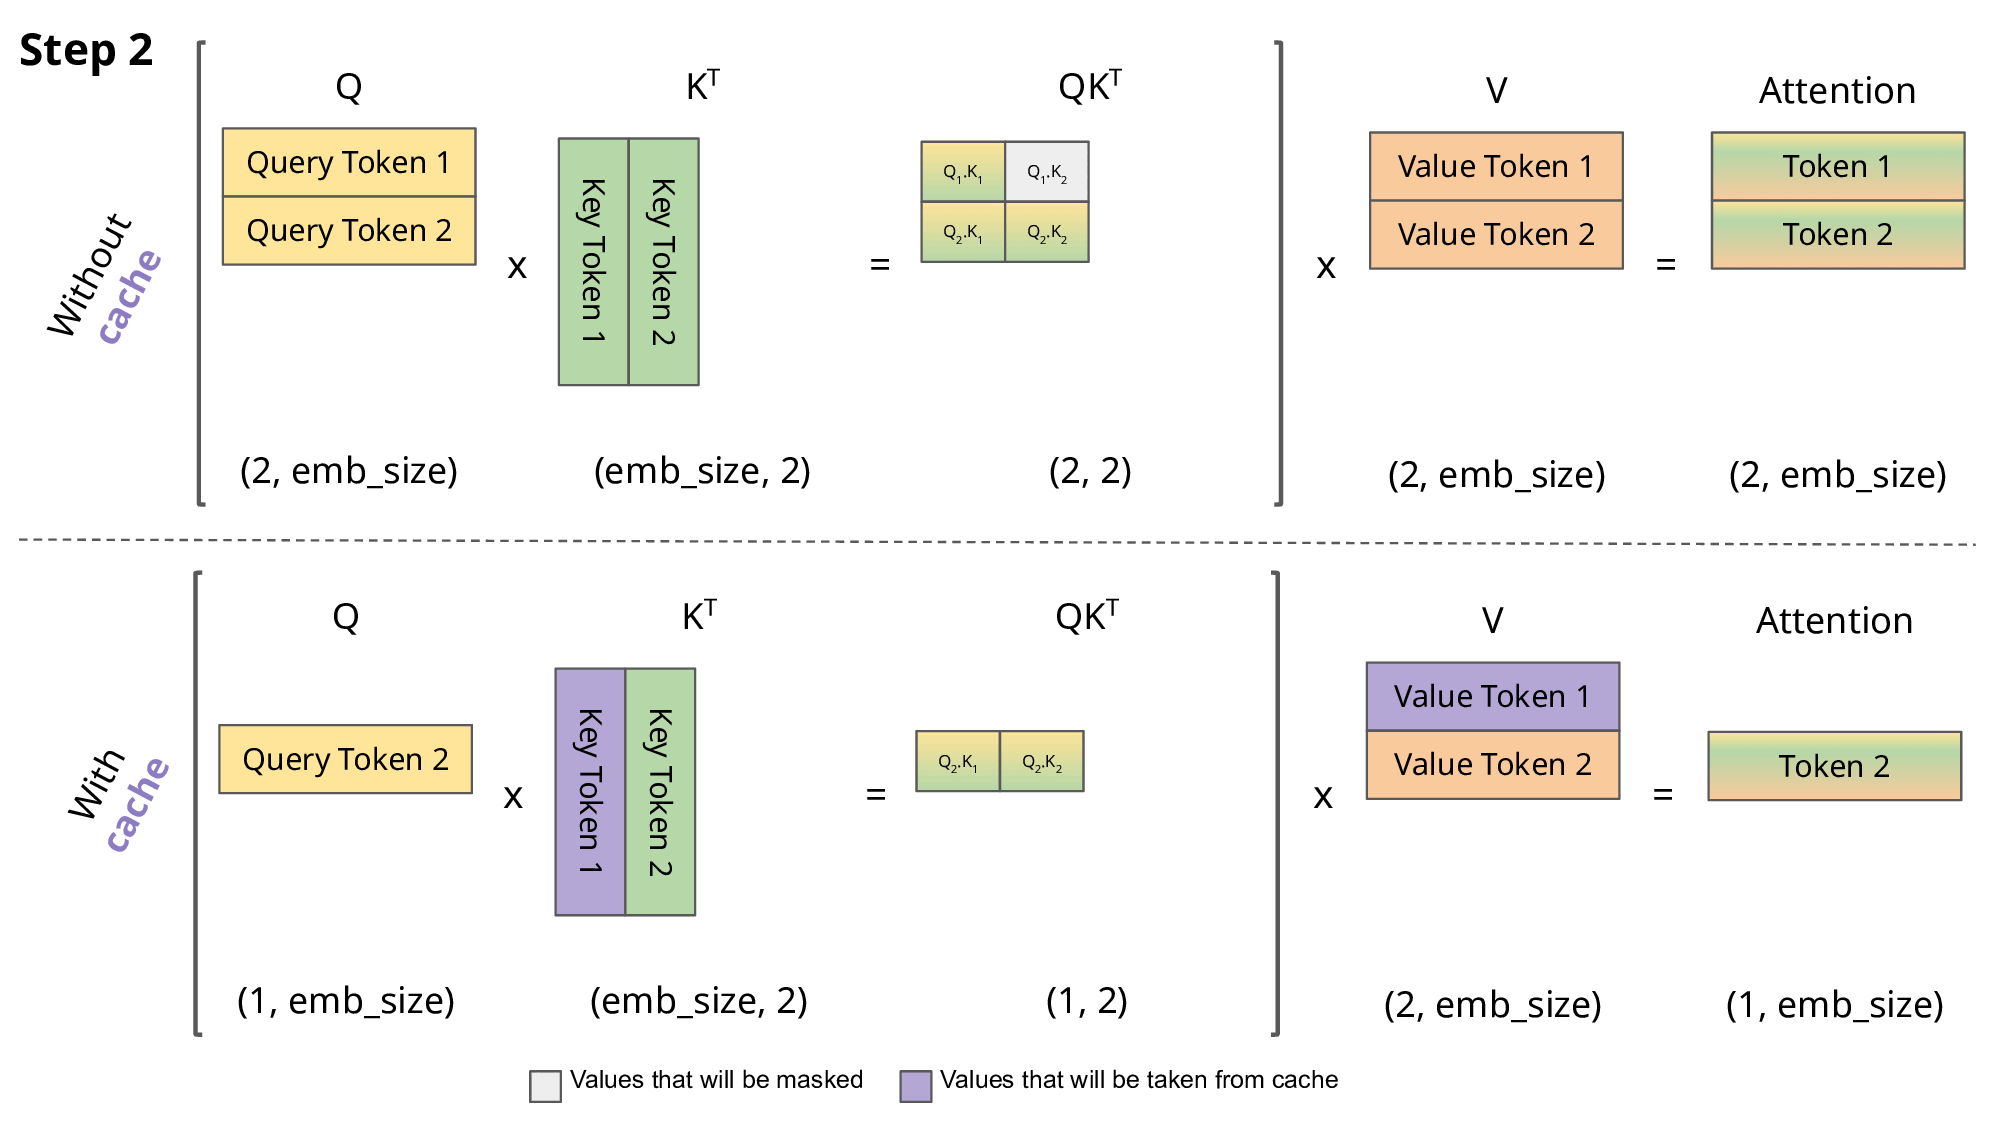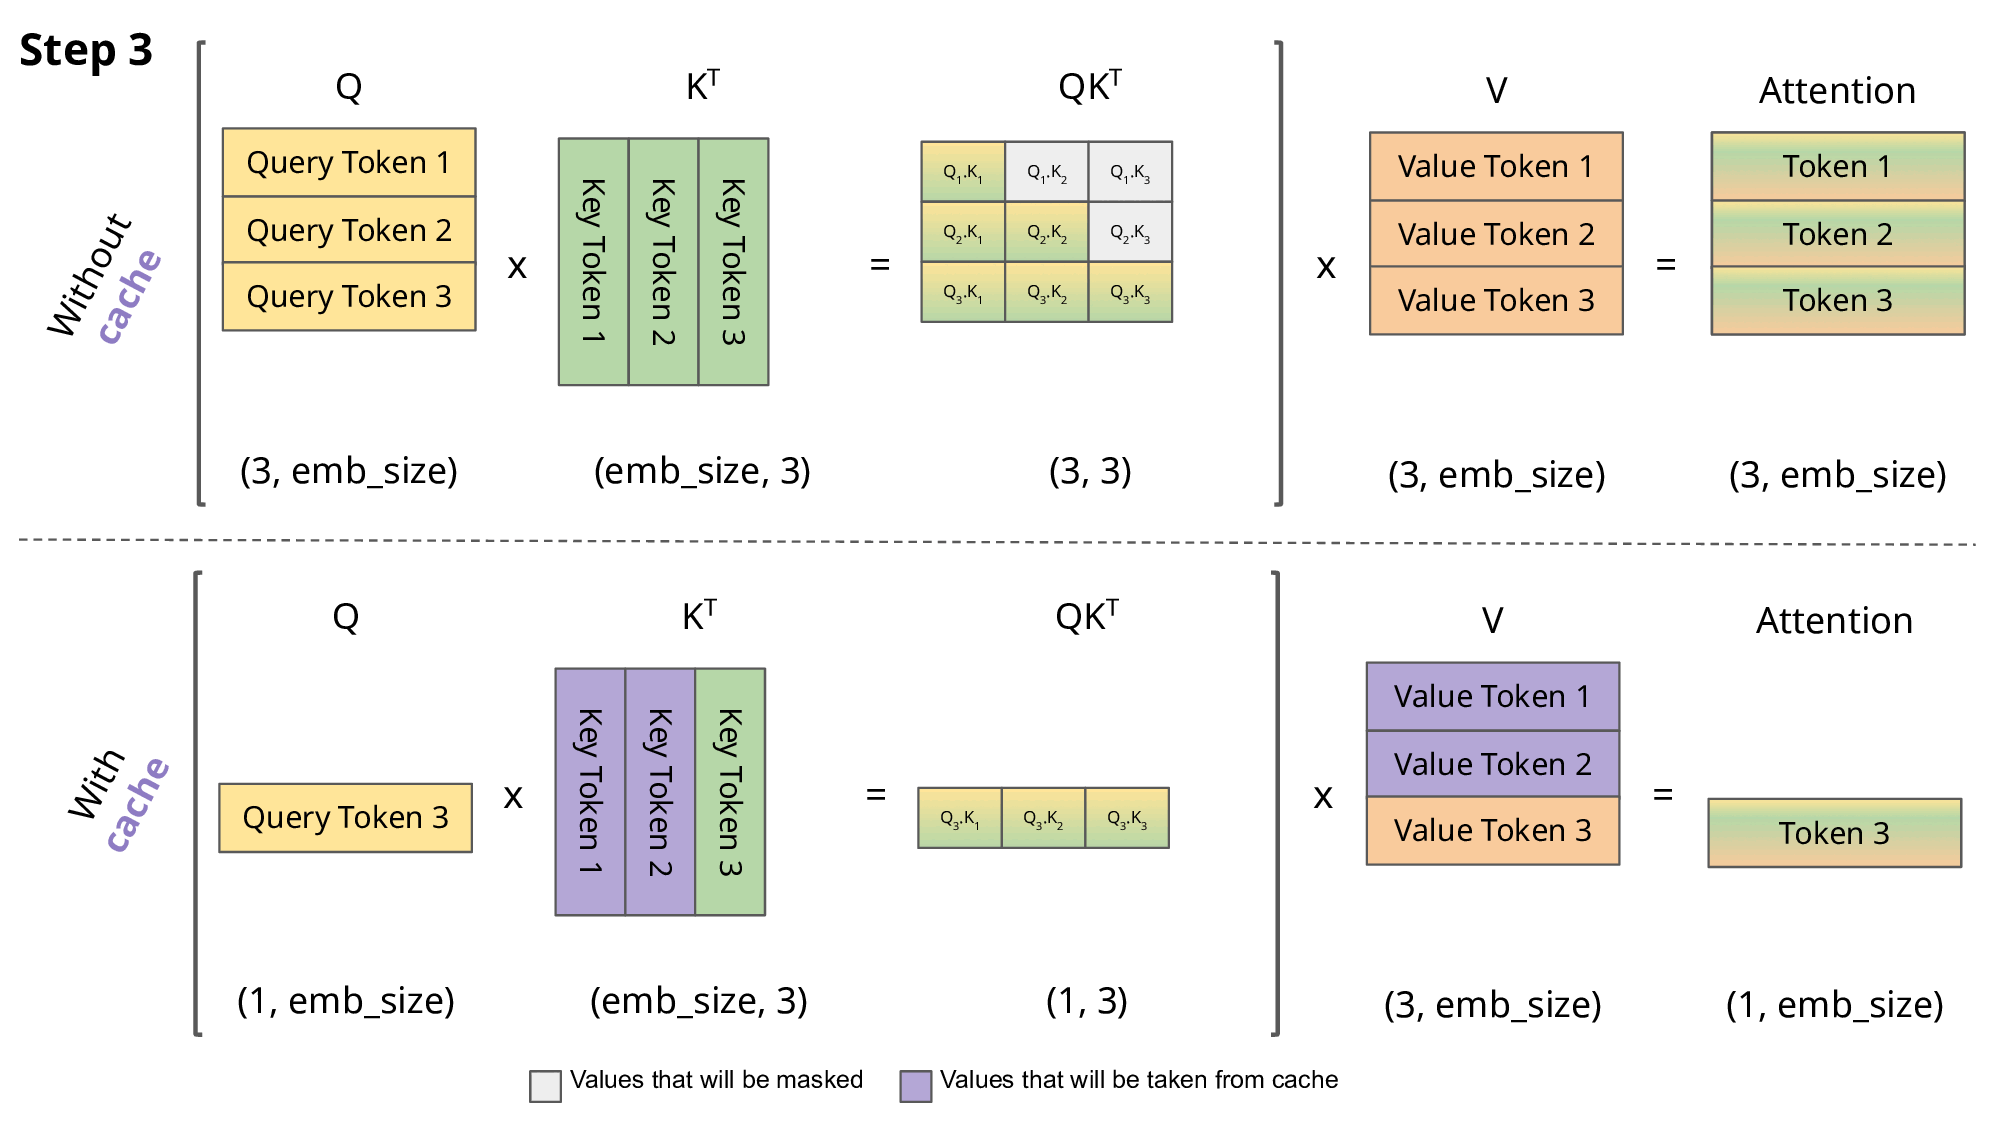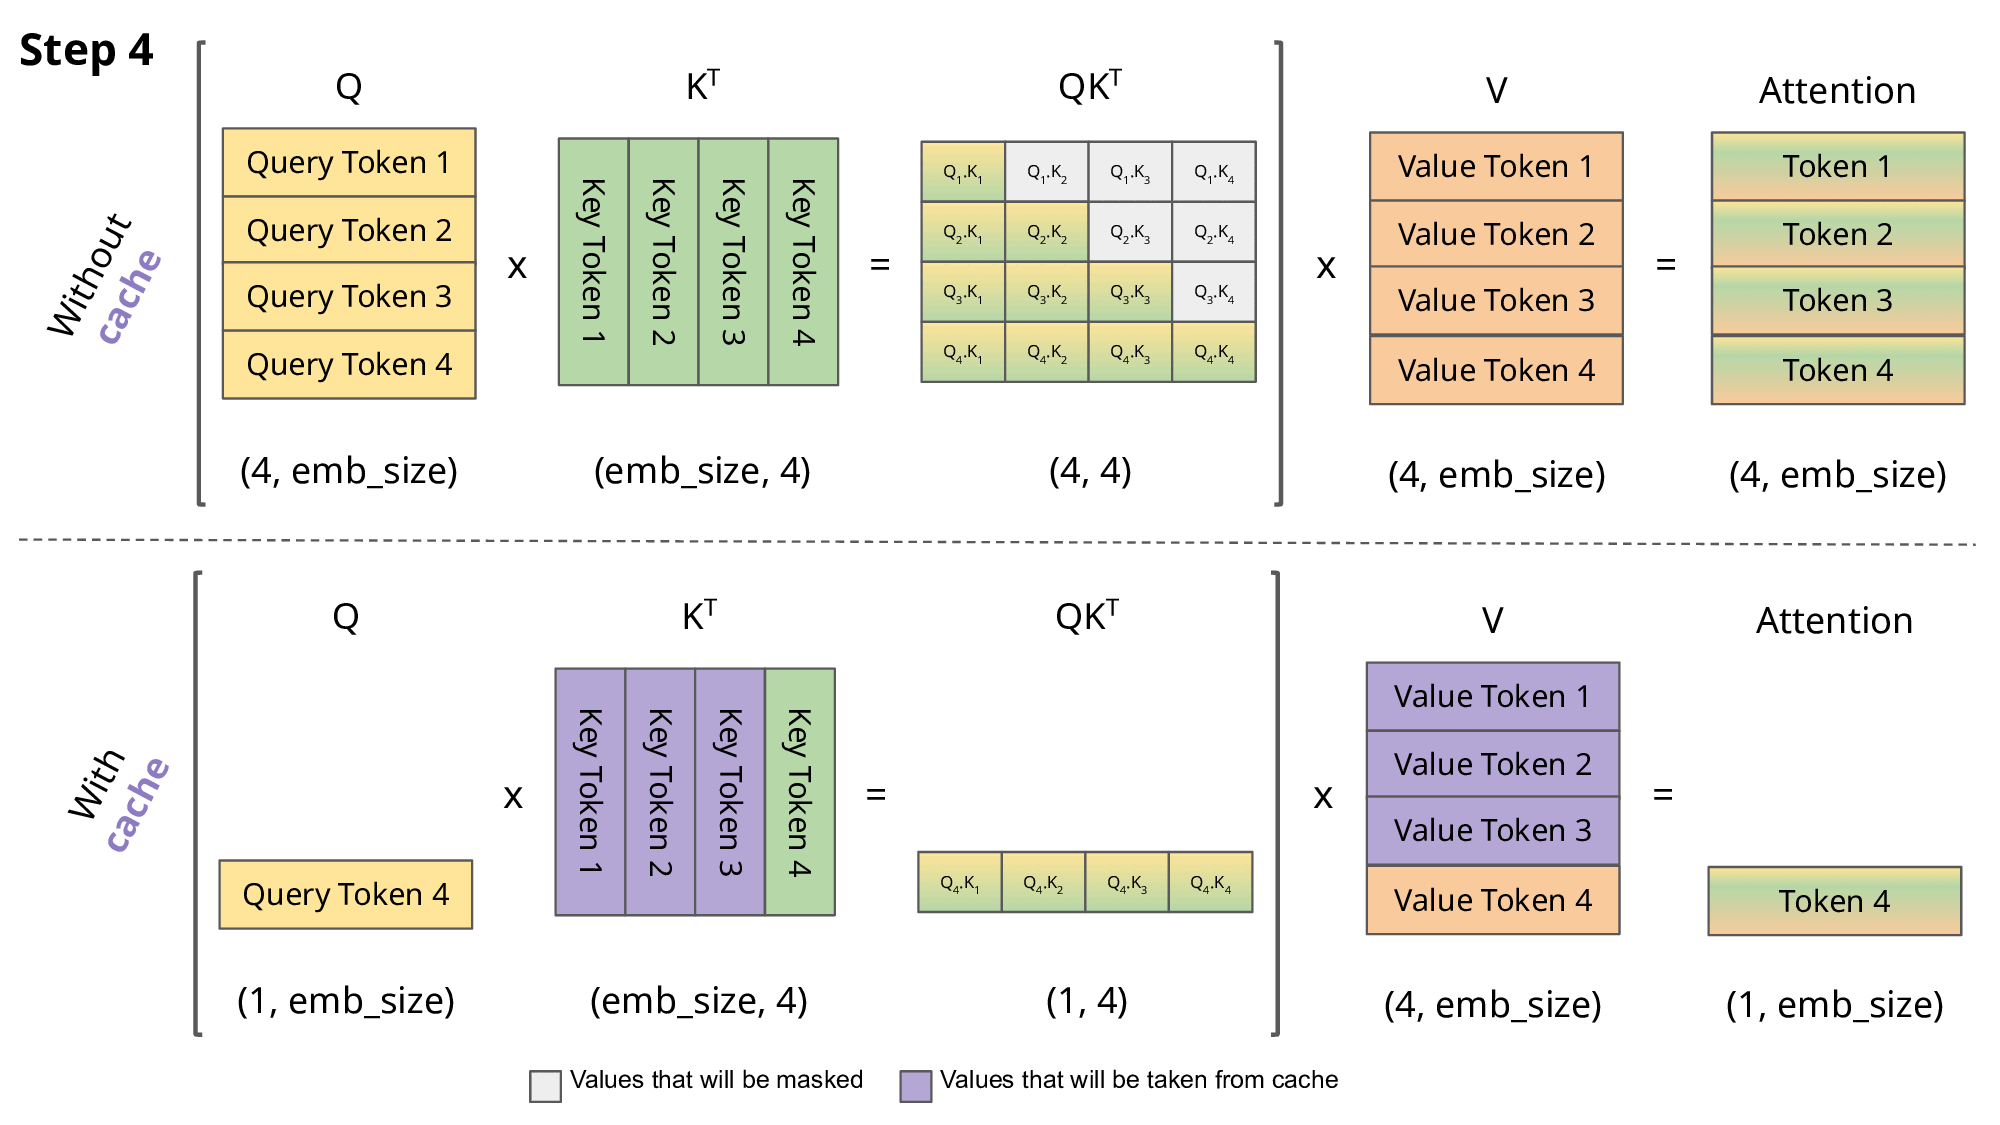
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
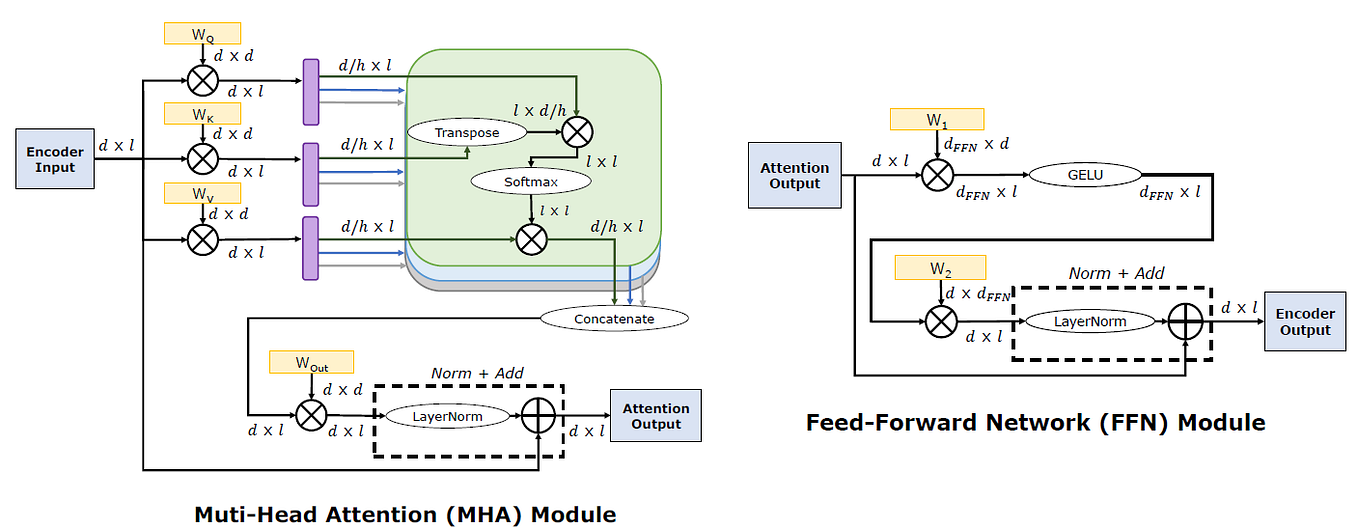
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
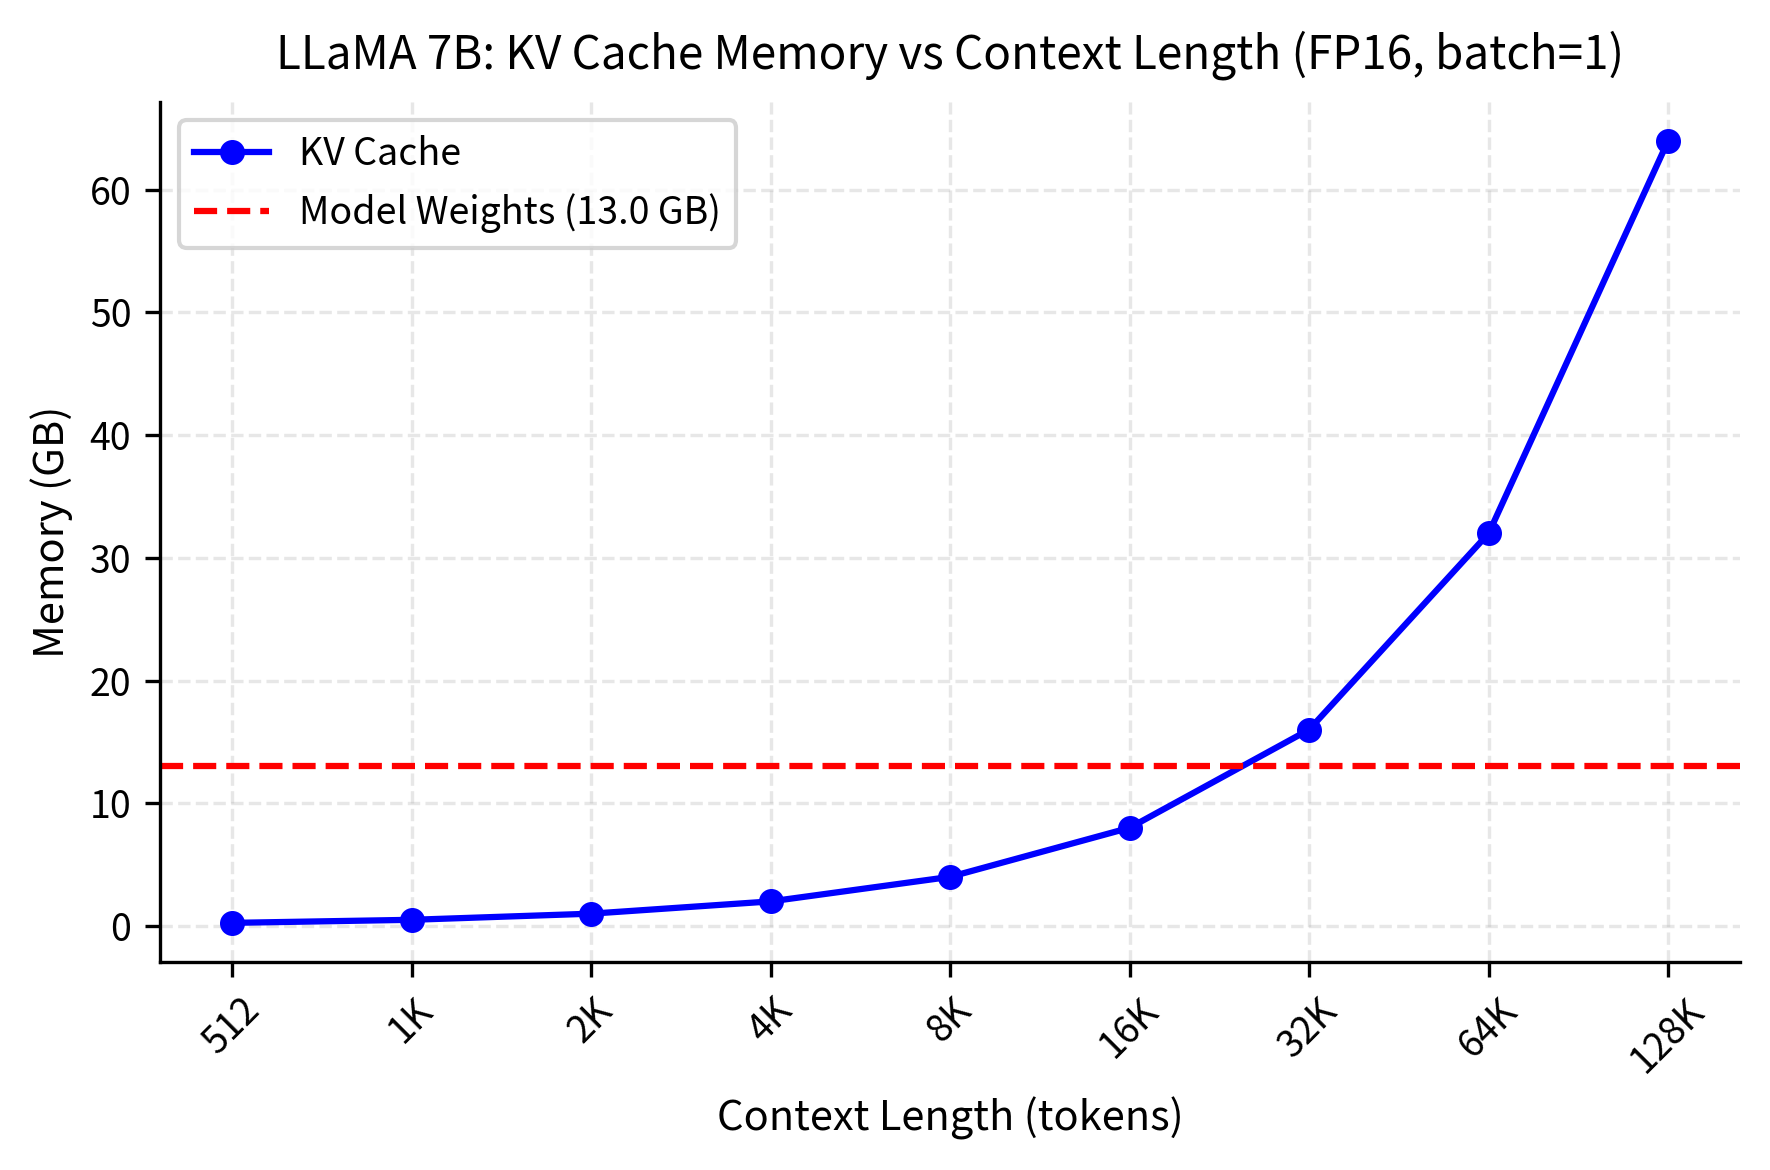
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

Accelerating LLM Inference Throughput via Asynchronous KV Cache Prefetching

KVSharer: method for efficient LLM inference via dissimilar KV Cache ...
Advertisement Space (300x250)

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...

Accelerating LLM Inference Throughput via Asynchronous KV Cache Prefetching

KV Cache Transform Coding for Compact Storage in LLM Inference

Caching Strategies for LLM Systems (Part 2): KV Cache and the ...

Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium
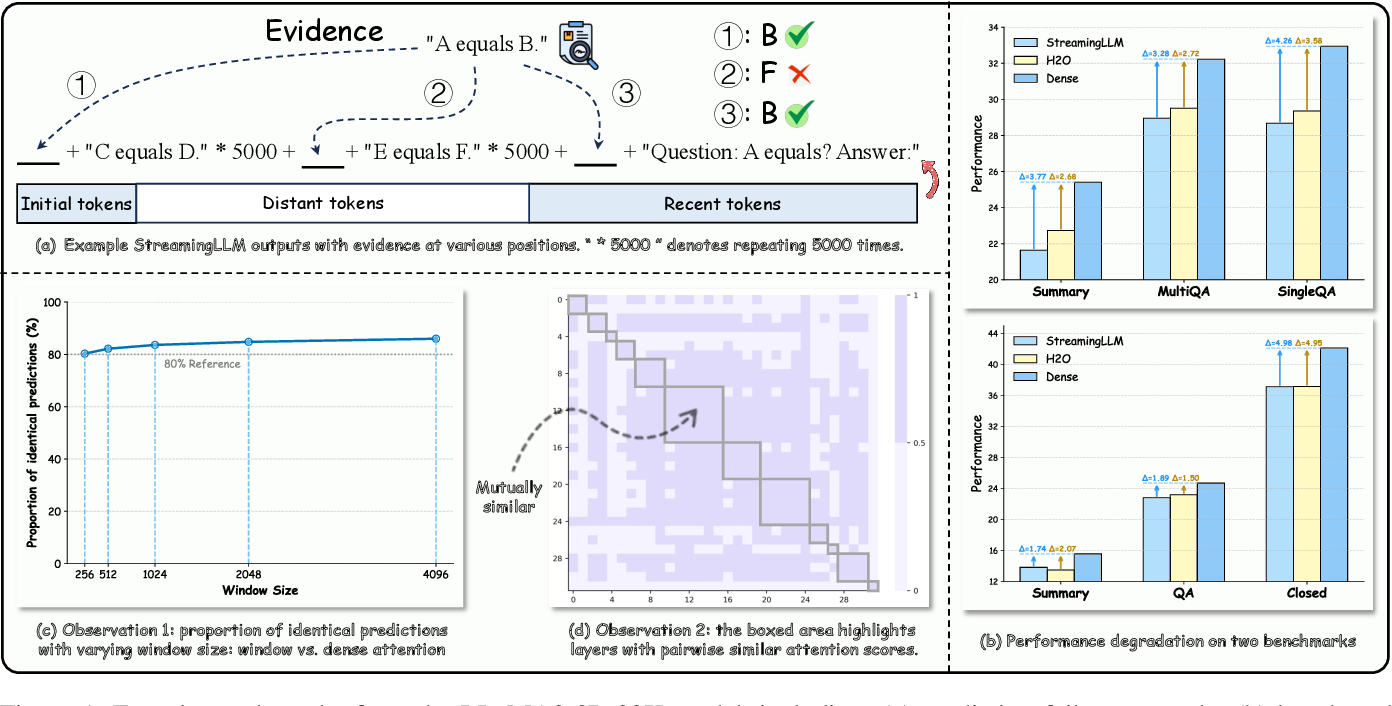
Figure 1 from Compressing KV Cache for Long-Context LLM Inference with ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
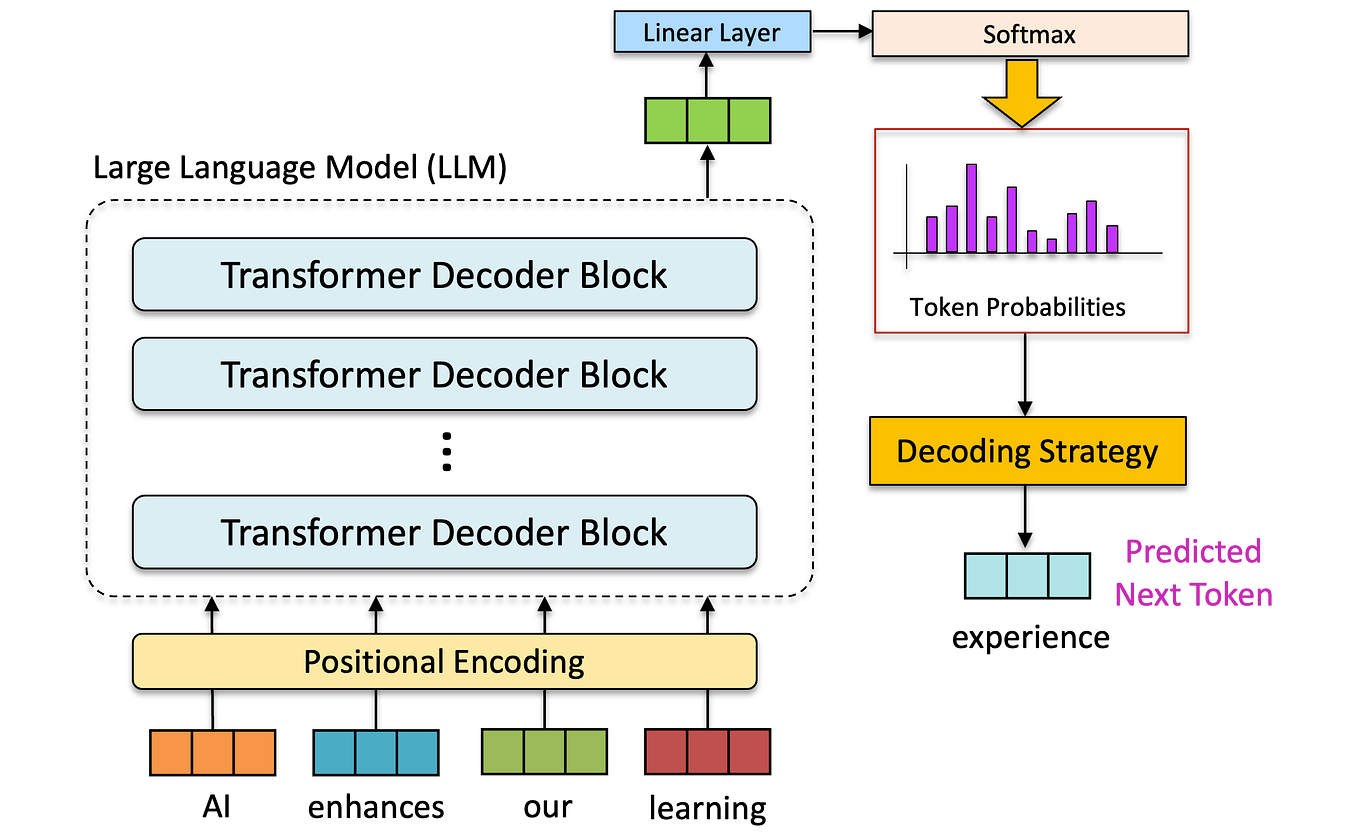
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium
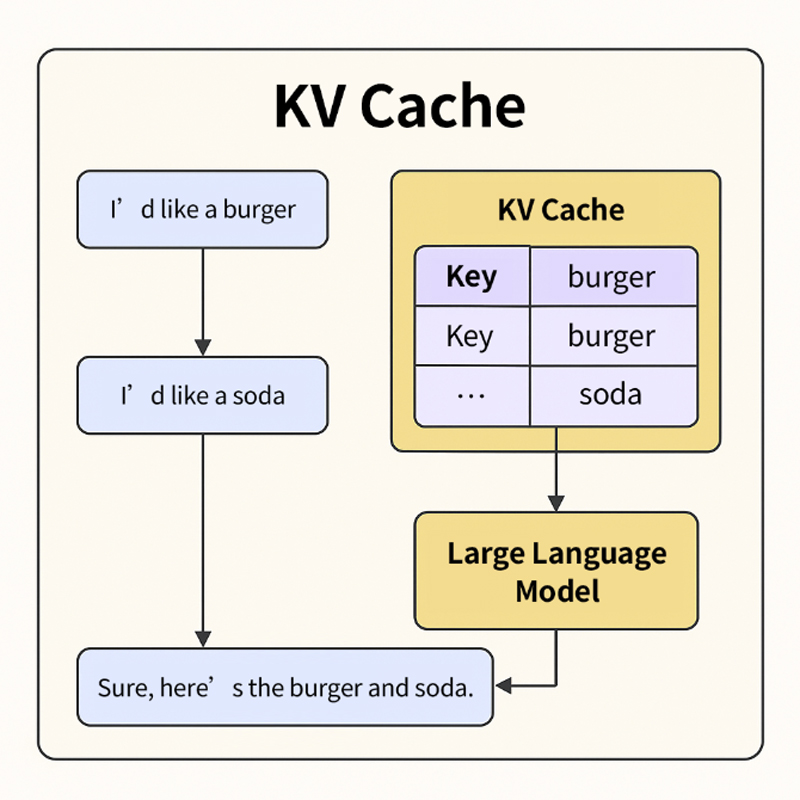
KV Cache Meets NVMe: The Key to Accelerating LLM Inference
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
Advertisement Space (336x280)

[论文评述] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...
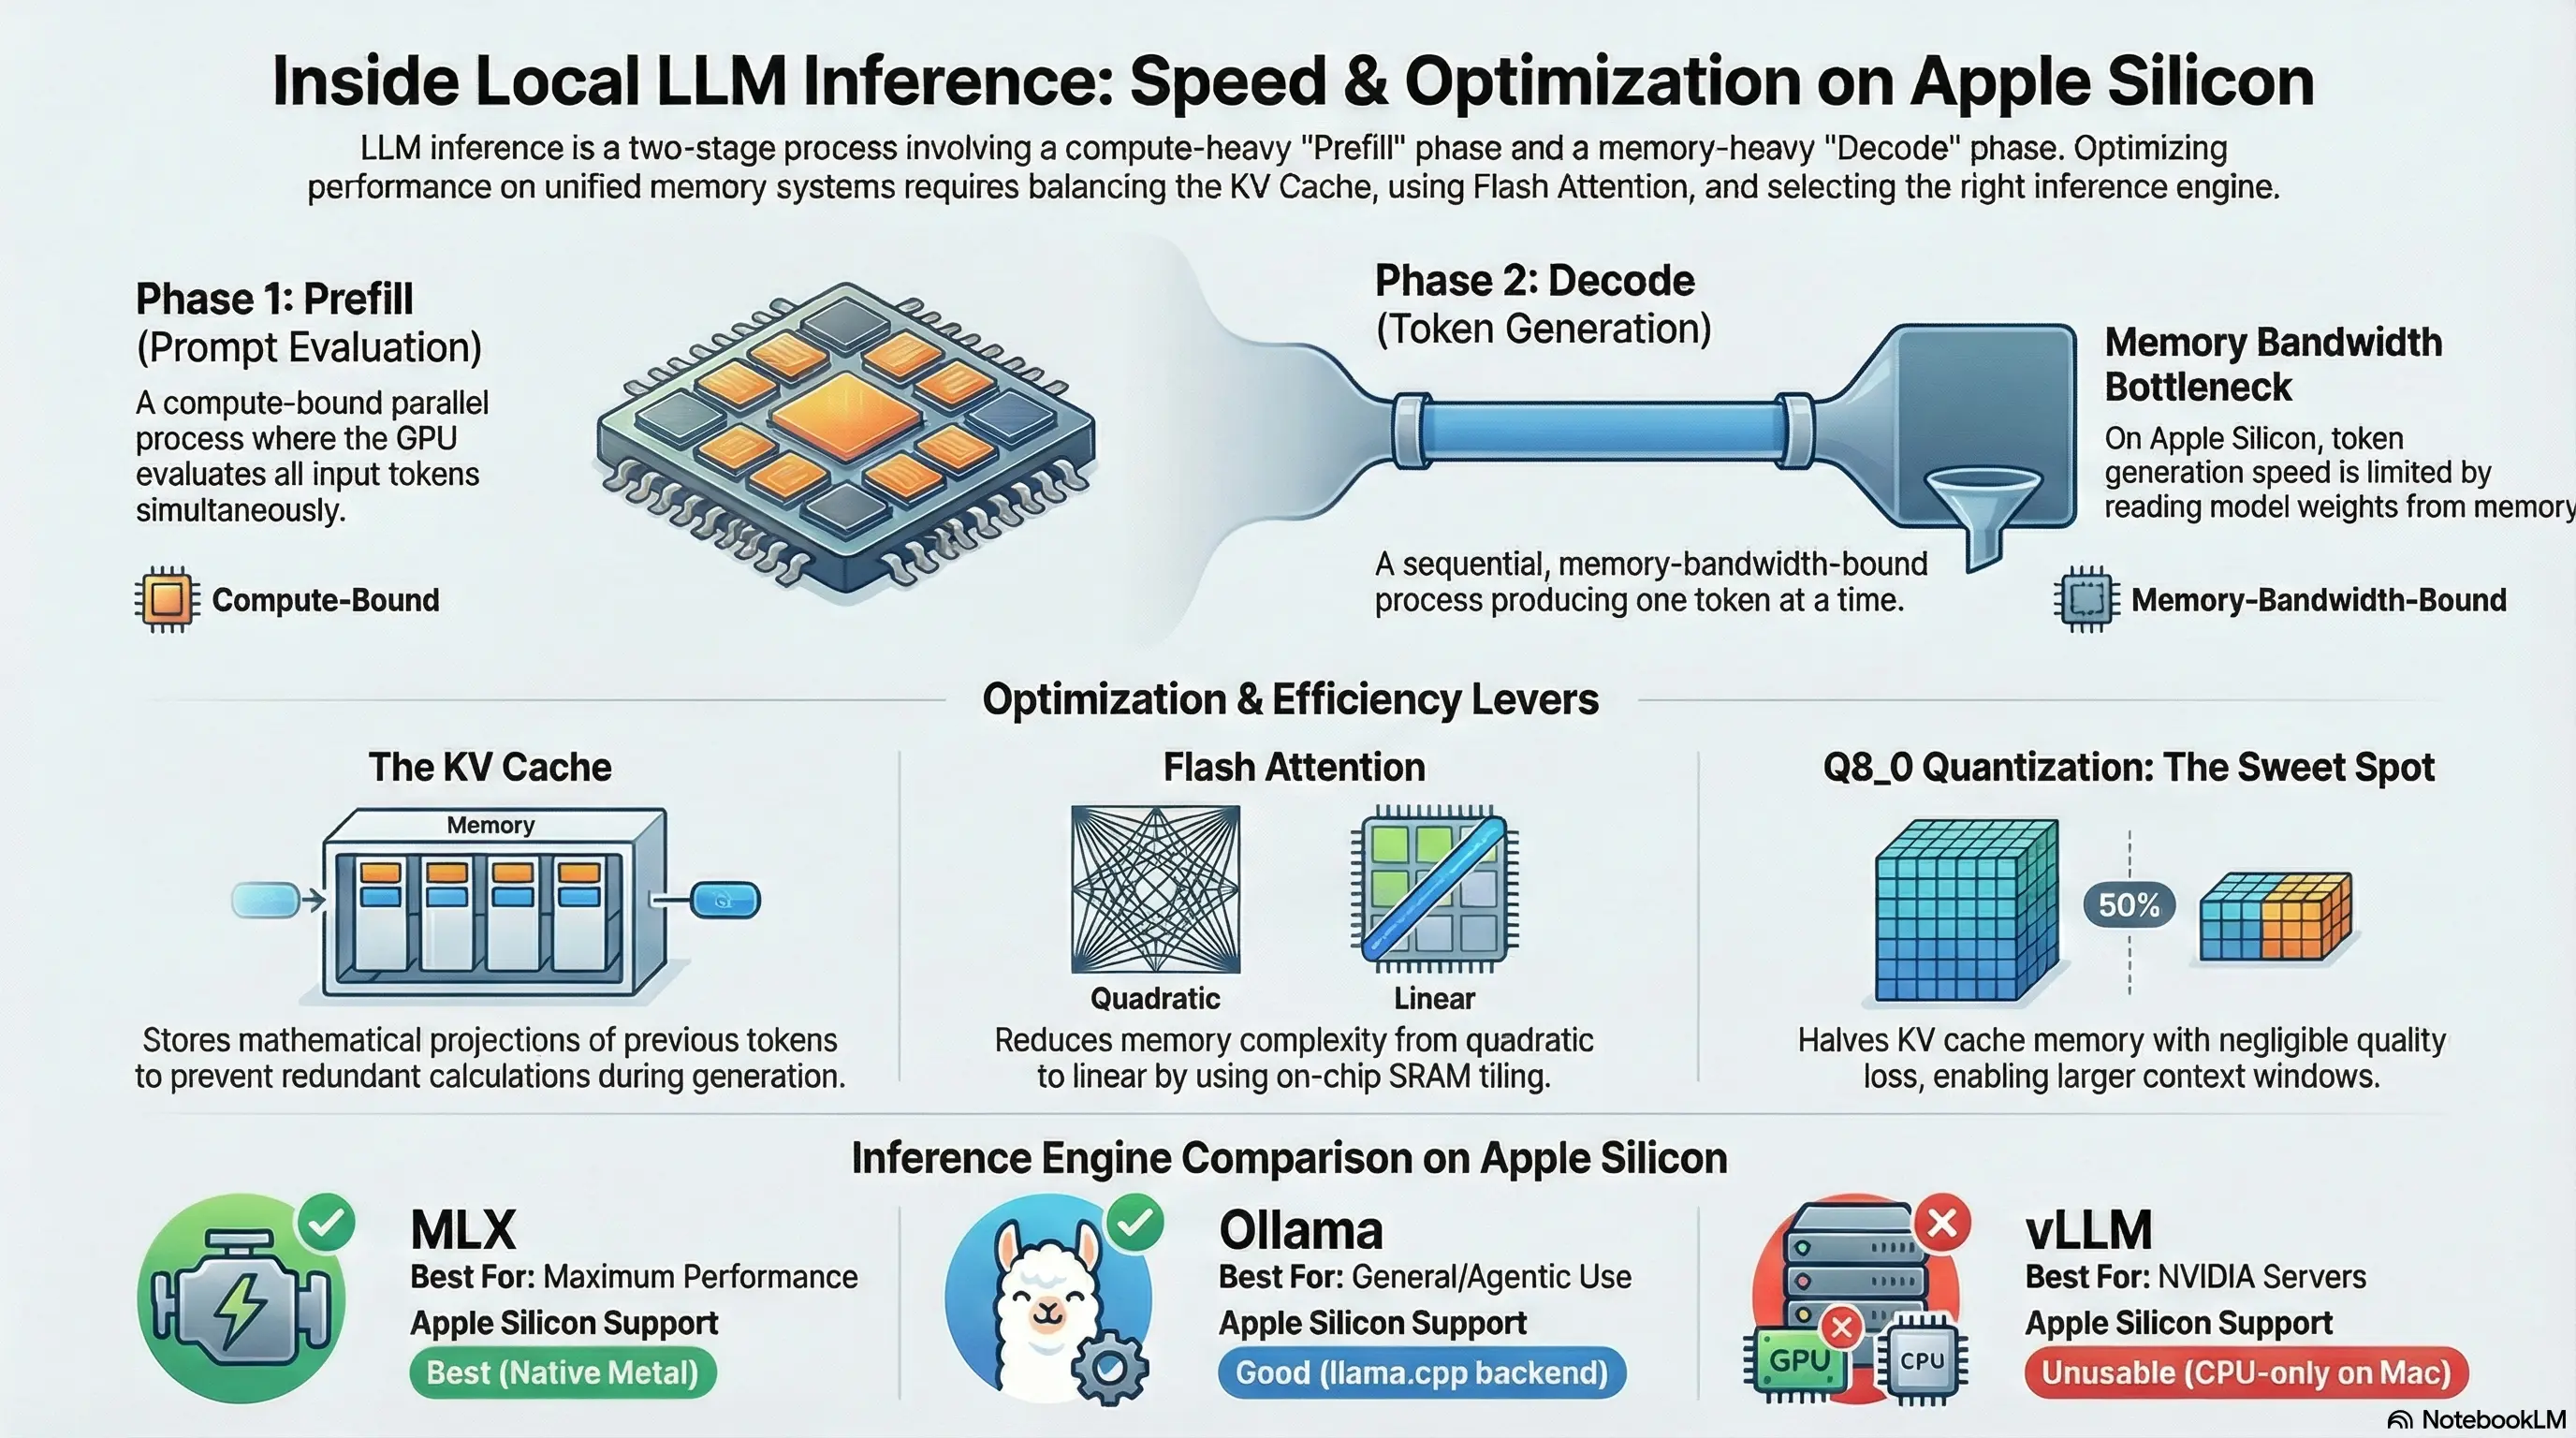
LLM Inference Internals: KV Cache, Flash Attention, and Optimizing for ...

Figure 2 from ShadowKV: KV Cache in Shadows for High-Throughput Long ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
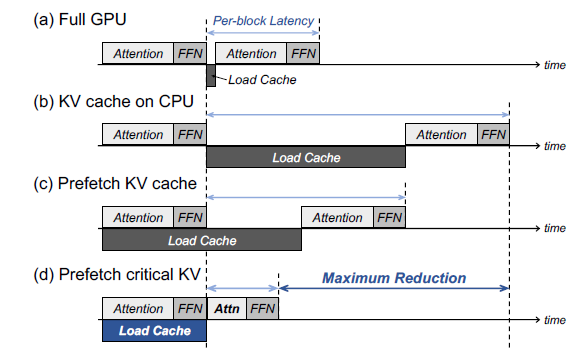
LLM Inference: Accelerating Long Context Generation with KV Cache ...

Optimizing Inference for Long Context and Large Batch Sizes with NVFP4 ...

Comparative Characterization of KV Cache Management Strategies for LLM ...
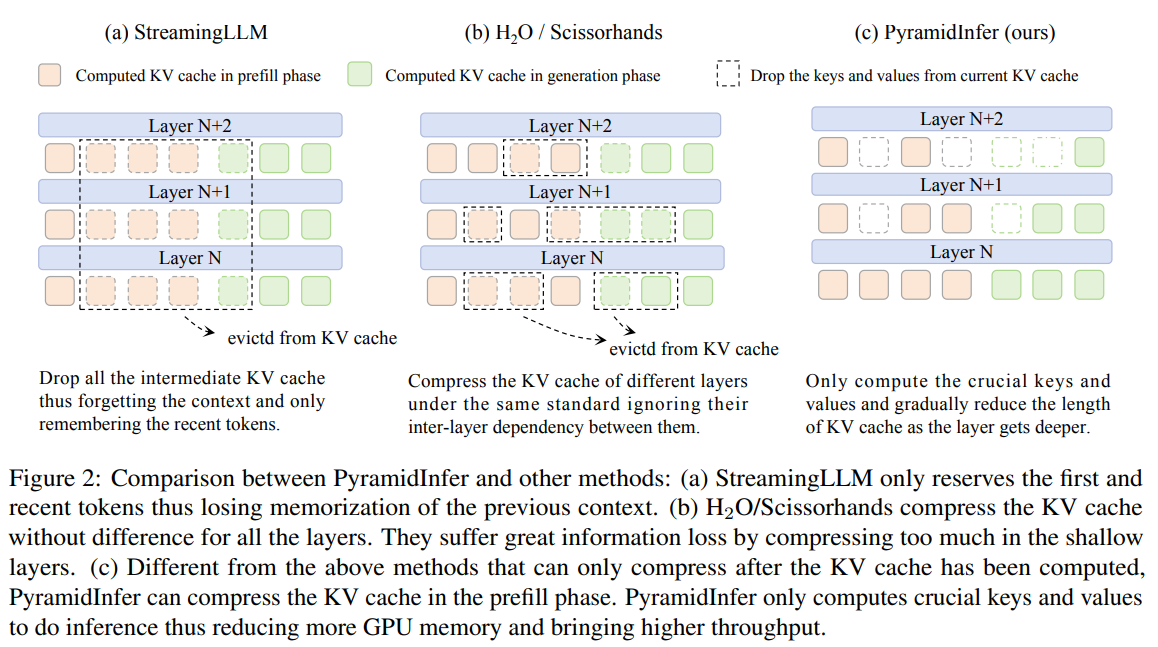
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...

KV Cache Offload Accelerates LLM Inference - NADDOD Blog
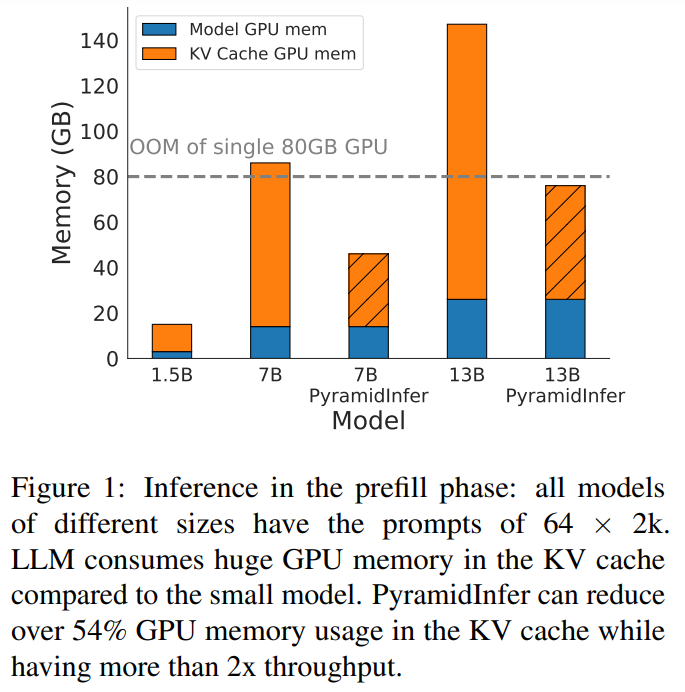
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
Advertisement Space (336x280)

Entropy-Guided KV Caching for Efficient LLM Inference

Understanding High Throughput LLM Inference Systems - AER LABS

ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM ...
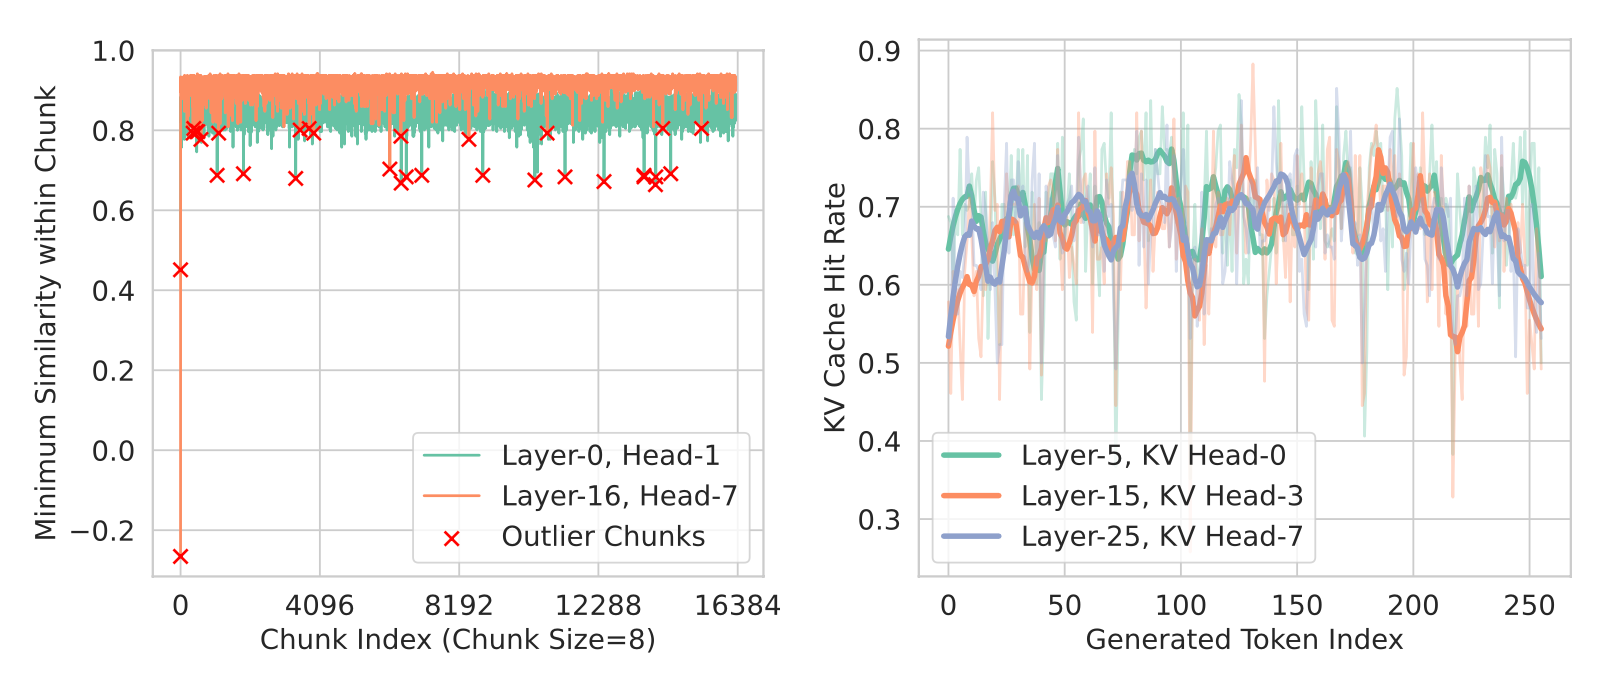
ShadowKV: KV Cache in Shadows for High-Throughput Long-Context LLM ...

KV Cache Reuse Is Quietly Reshaping LLM Inference Architecture | by ...

Paper page - PyramidInfer: Pyramid KV Cache Compression for High ...