
Llm Inference Quantization And Model Compression

LLM inference optimization: Model Quantization and Distillation - YouTube

On-Device Qwen2.5: Efficient LLM Inference with Model Compression and ...

On-Device Qwen2.5: Efficient LLM Inference with Model Compression and ...

On-Device Qwen2.5: Efficient LLM Inference with Model Compression and ...

On-Device Qwen2.5: Efficient LLM Inference with Model Compression and ...

LLM Inference, Quantization, and Model Compression
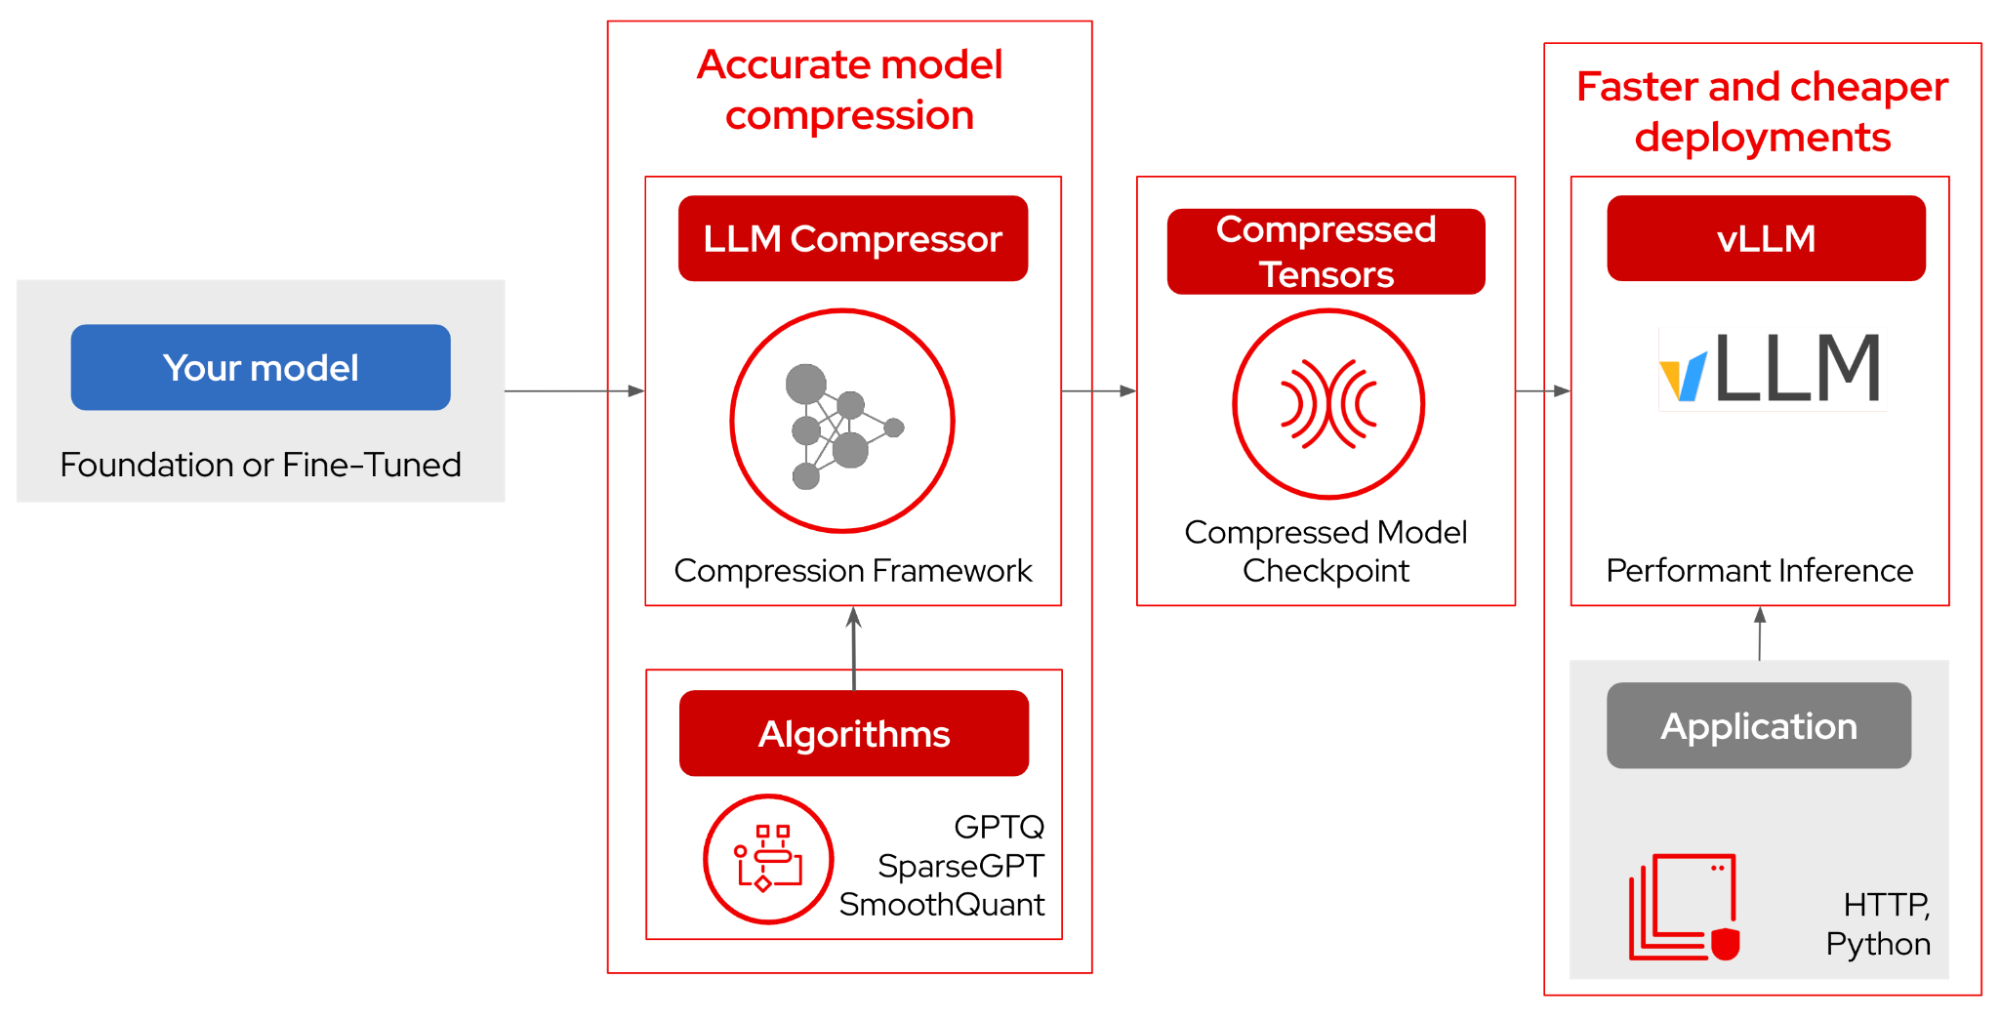
LLM compression and optimization: Cheaper inference with fewer hardware ...
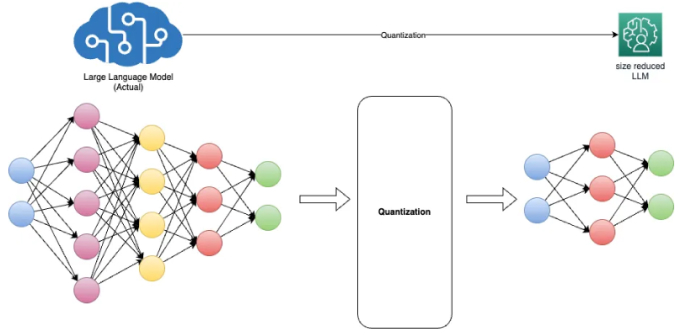
Top LLM Quantization Methods and Their Impact on Model Quality

LLM compression and optimization: Cheaper inference with fewer hardware ...

Optimizing LLM size and inference : - Lossless compression for AI ...
Advertisement Space (300x250)

Improving LLM Inference Latency on CPUs with Model Quantization ...
How to Optimize LLM Inference with Quantization and Pruning

AWQ: Activation-aware Weight Quantization for LLM Compression and ...
Model Quantization Guide: Reduce LLM Size and Cost | DevOpsNess

Top LLM Quantization Methods and Their Impact on Model Quality
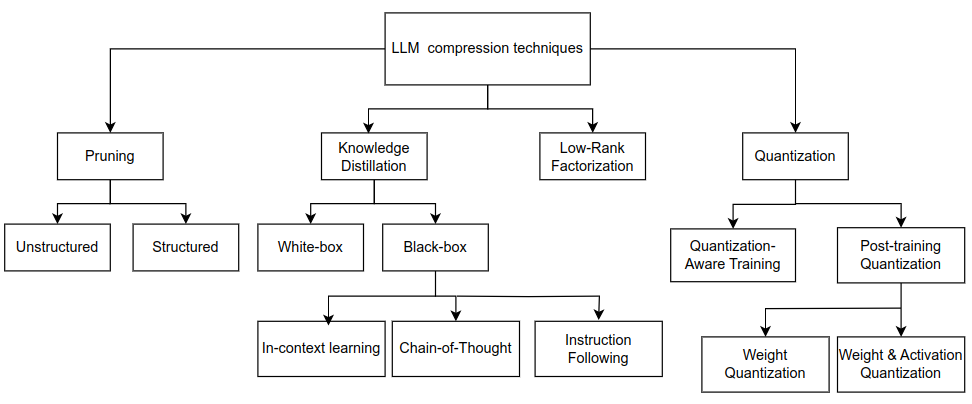
LLM Compression Techniques to Build Faster and Cheaper LLMs
Quantization: AI Model Compression for Faster Inference | Inference Systems
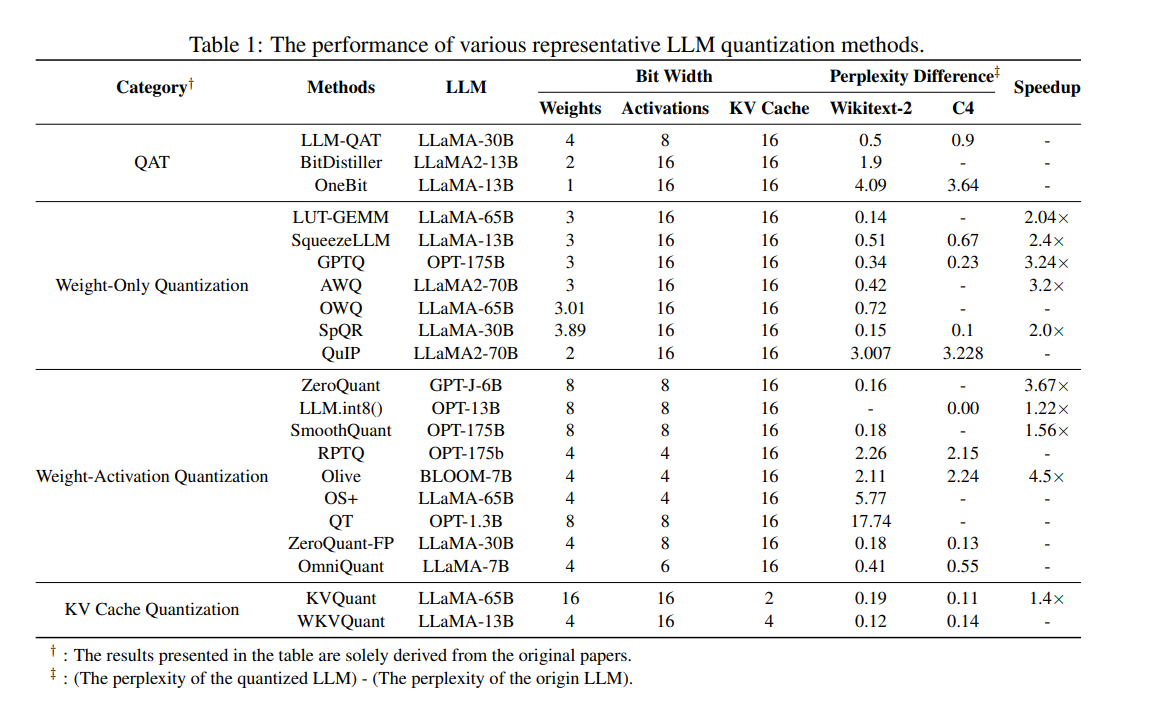
LLM Compression Techniques to Build Faster and Cheaper LLMs

Communication Compression for Tensor Parallel LLM Inference | AI ...

KLLM: Fast LLM Inference with K-Means Quantization | AI Research Paper ...
Advertisement Space (336x280)
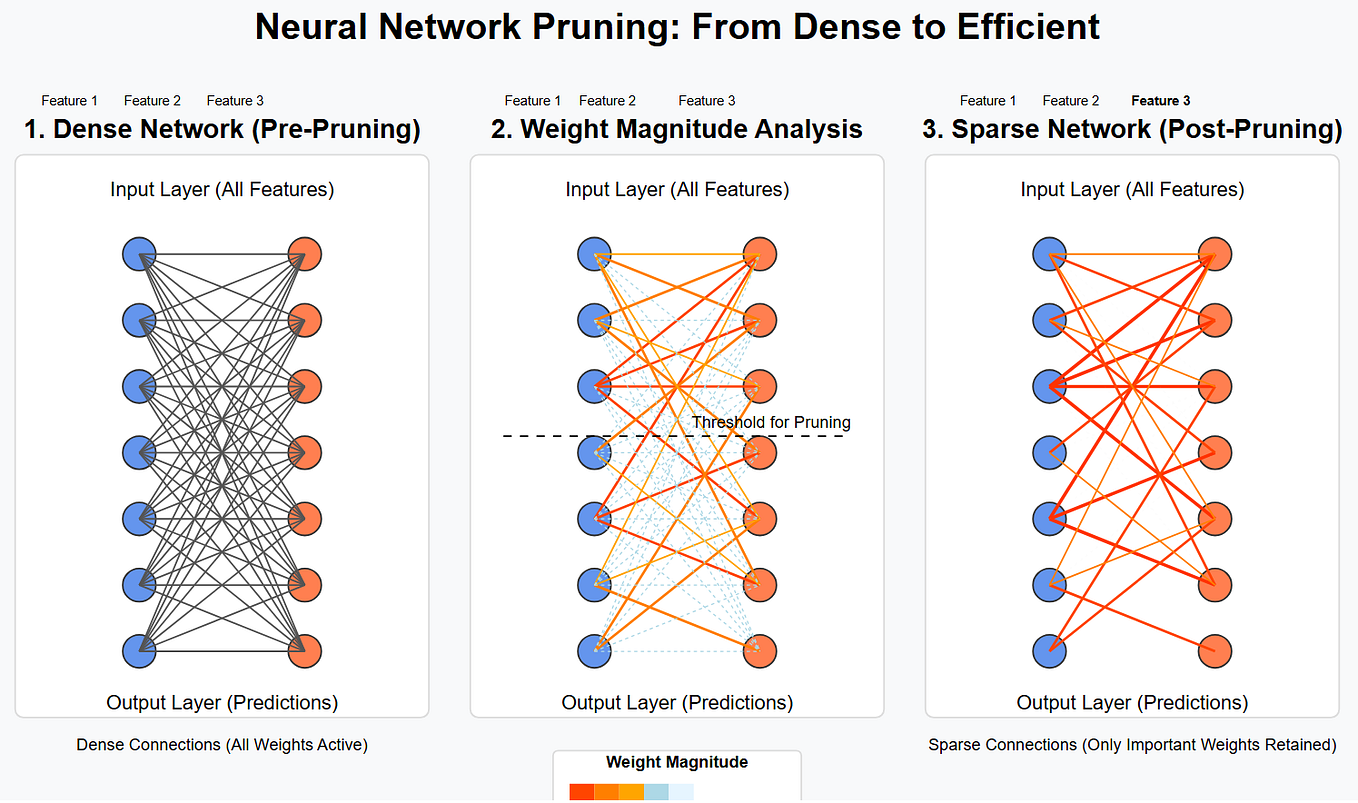
Offloading the optimal number of model layers for a given LLM and GPU ...

[논문 리뷰] On-Device Qwen2.5: Efficient LLM Inference with Model ...
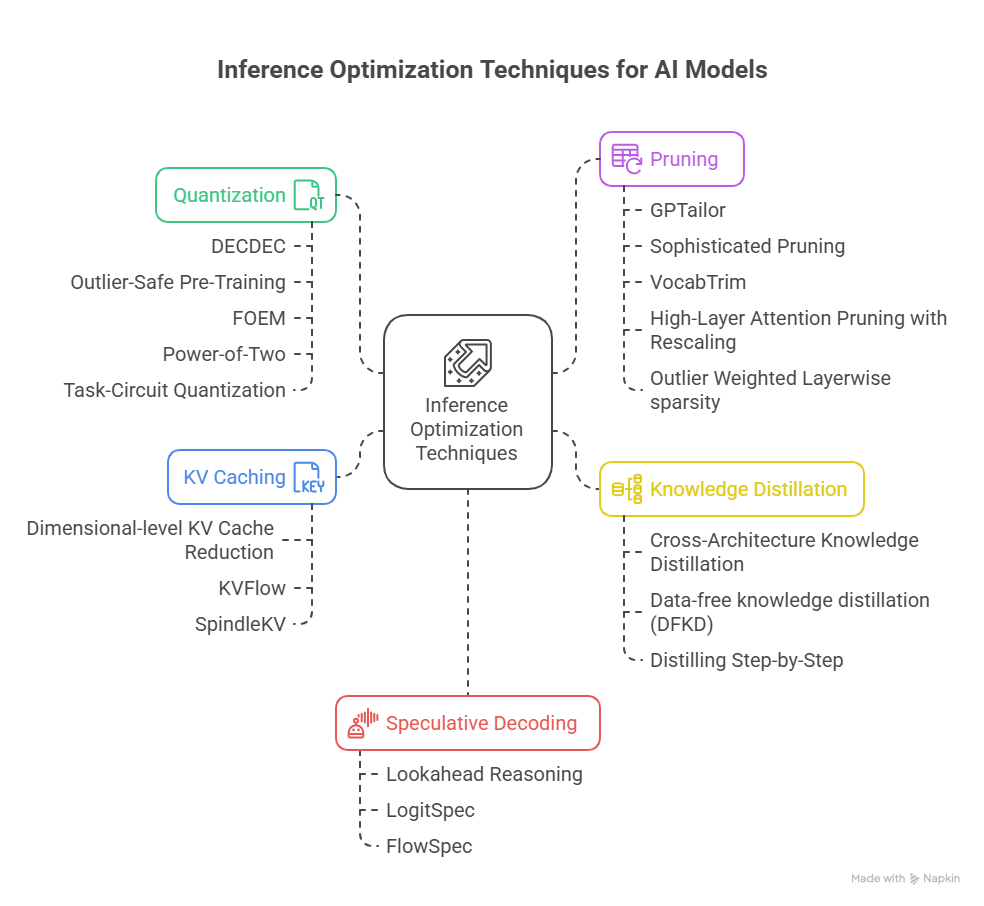
What’s New in LLM Inference Optimization: Recent Advances and ...
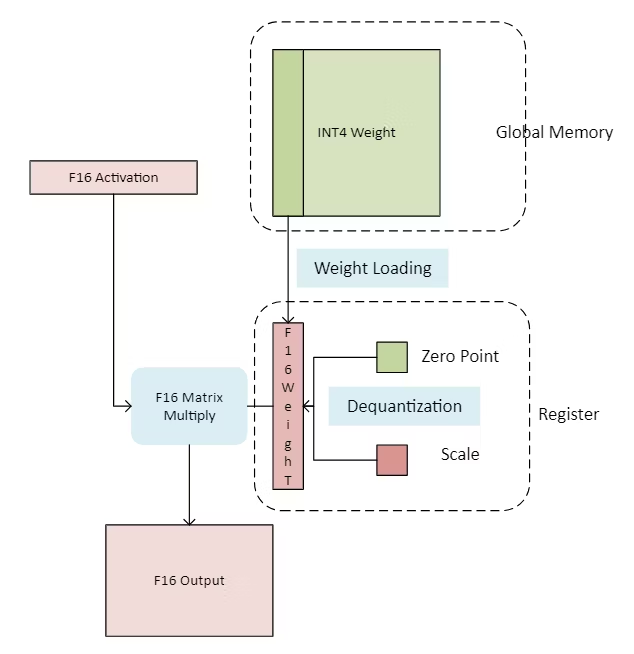
Weight-only Quantization to Improve LLM Inference

SDQ: Sparse Decomposed Quantization for LLM Inference | AI Research ...
LLM Quantization: A Comprehensive Guide to Model Compression for ...

Visualizing LLM Inference Flow with Turboquant KV Compression Following ...
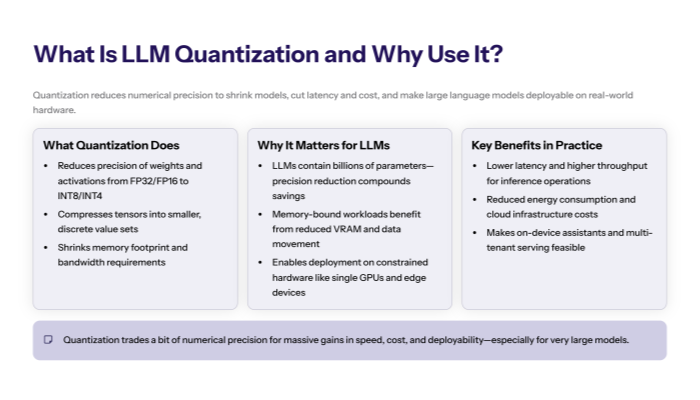
What is LLM Quantization Understanding Its Importance and Techniques
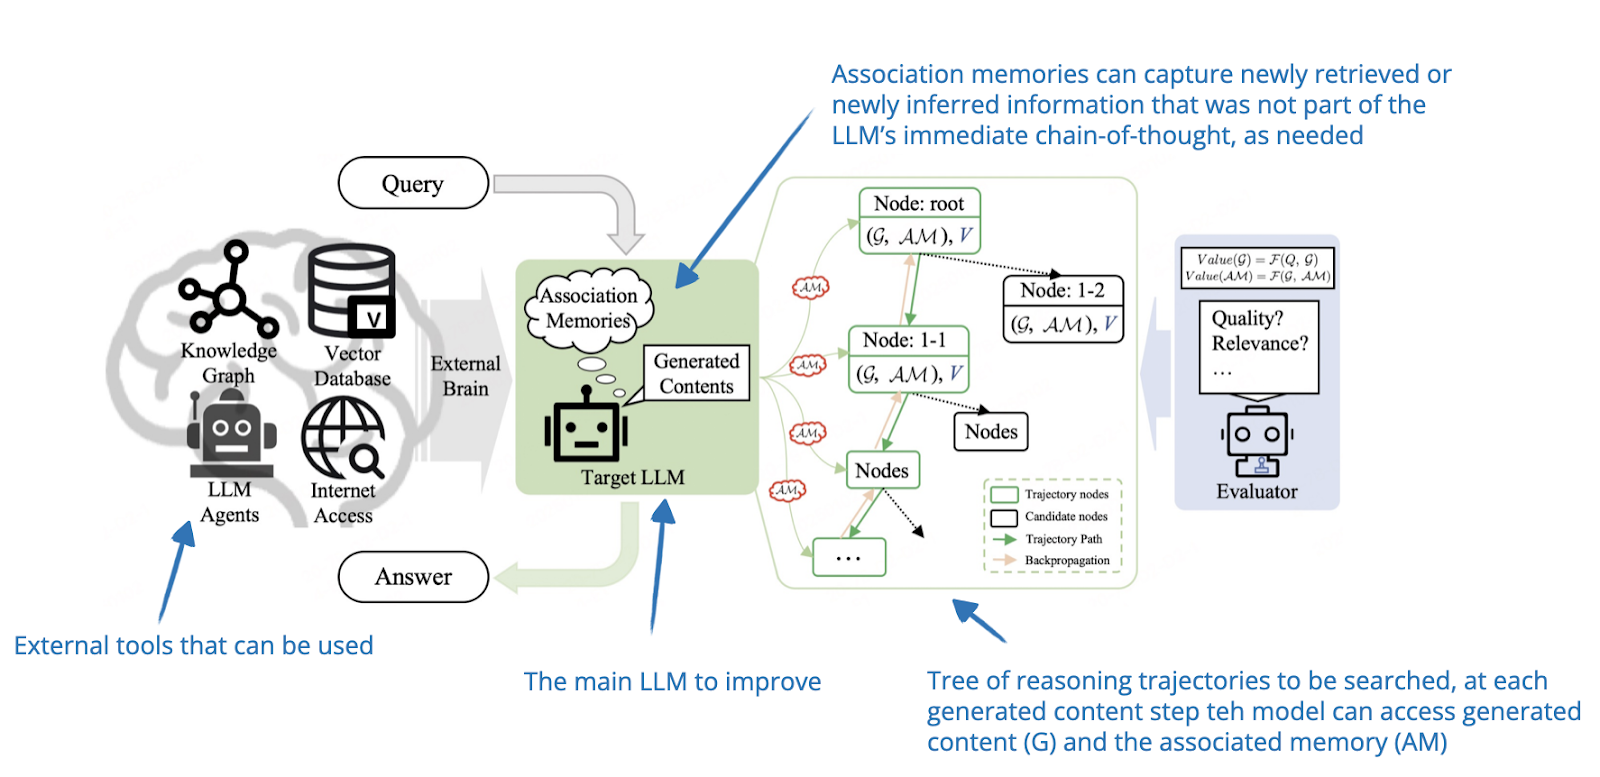
The State of LLM Reasoning Model Inference

Energy-Efficient Inference on RNN and LLM networks: A Quantized ...
Advertisement Space (336x280)

LLM Quantization: Quantize Model with GPTQ, AWQ, and Bitsandbytes ...
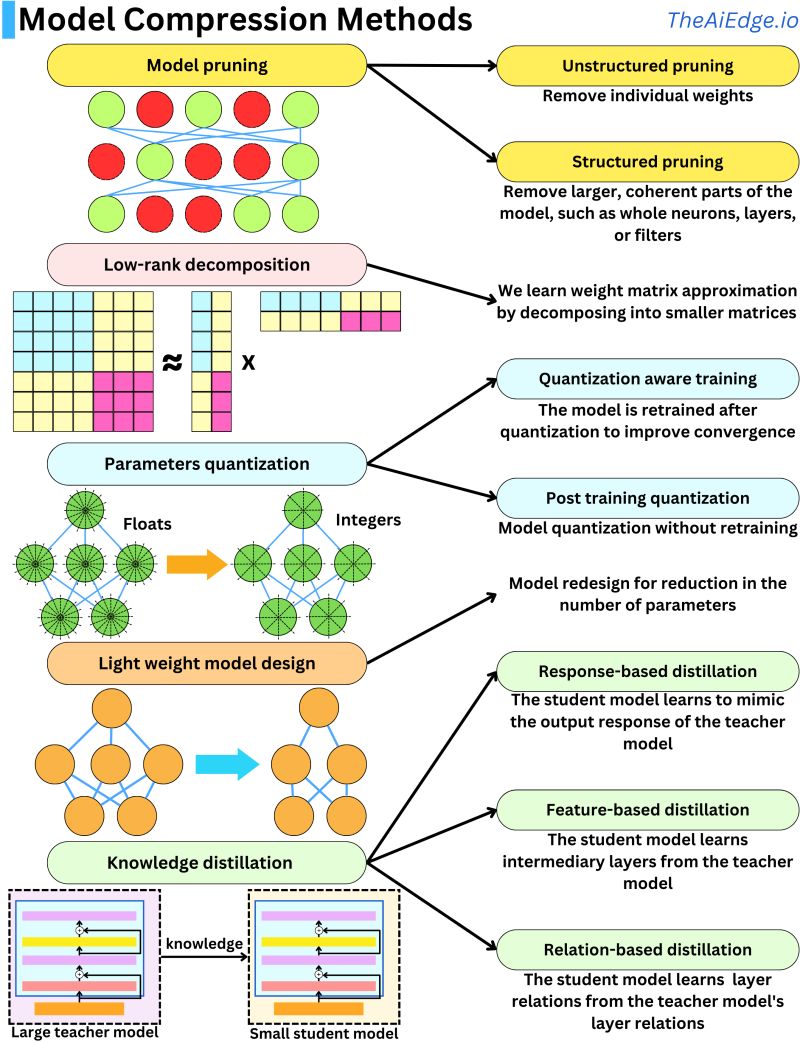
Vinija's Notes • Primers • Model Compression using Inference/Training ...
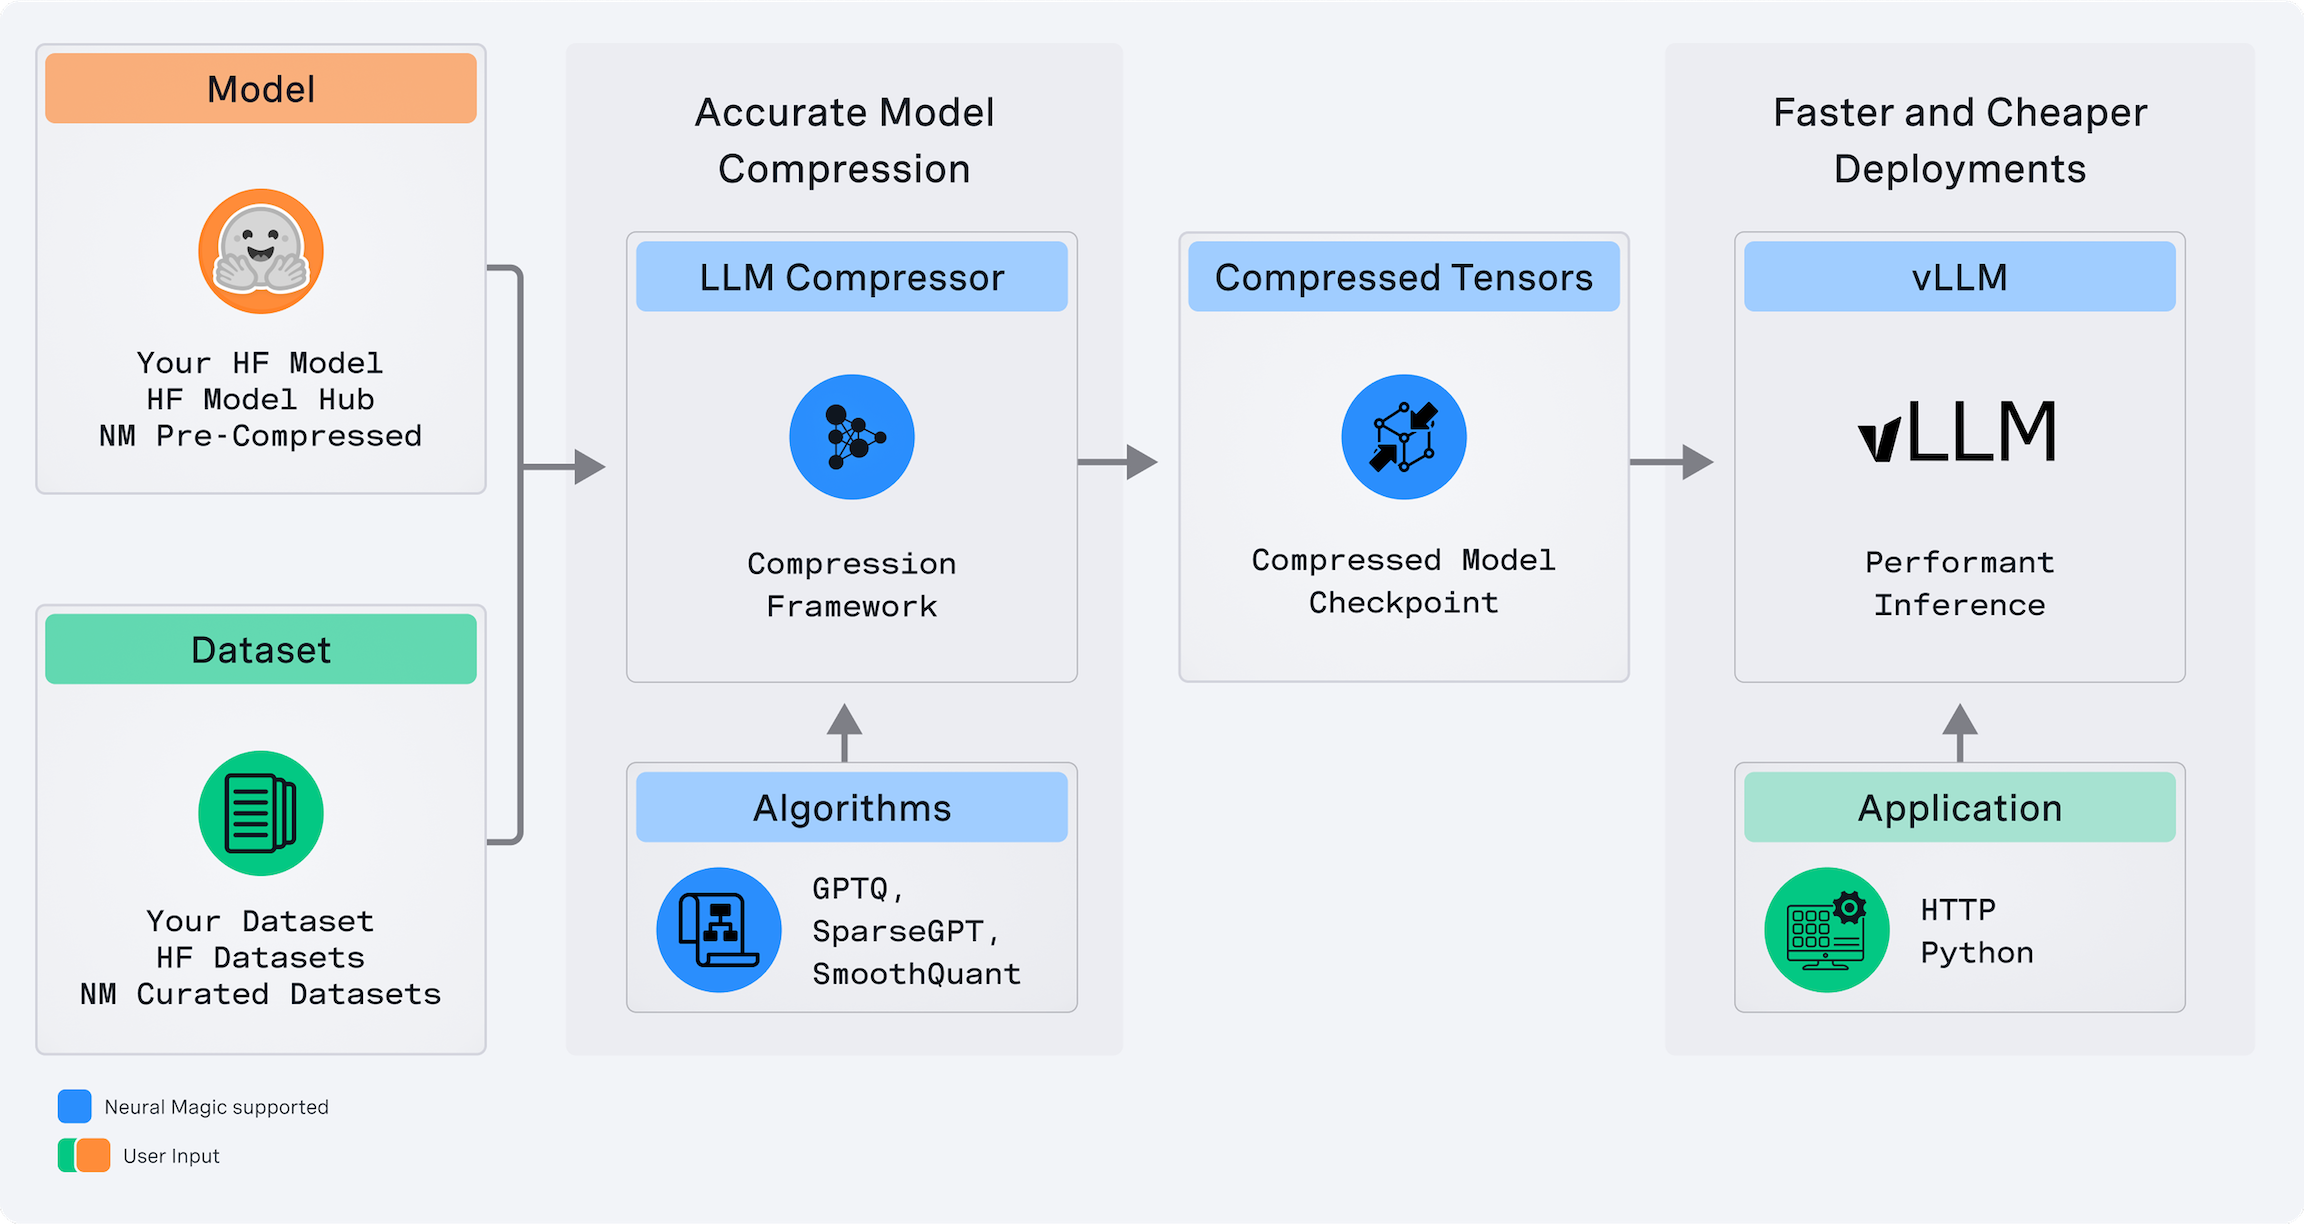
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

GitHub - HuangOwen/Awesome-LLM-Compression: Awesome LLM compression ...
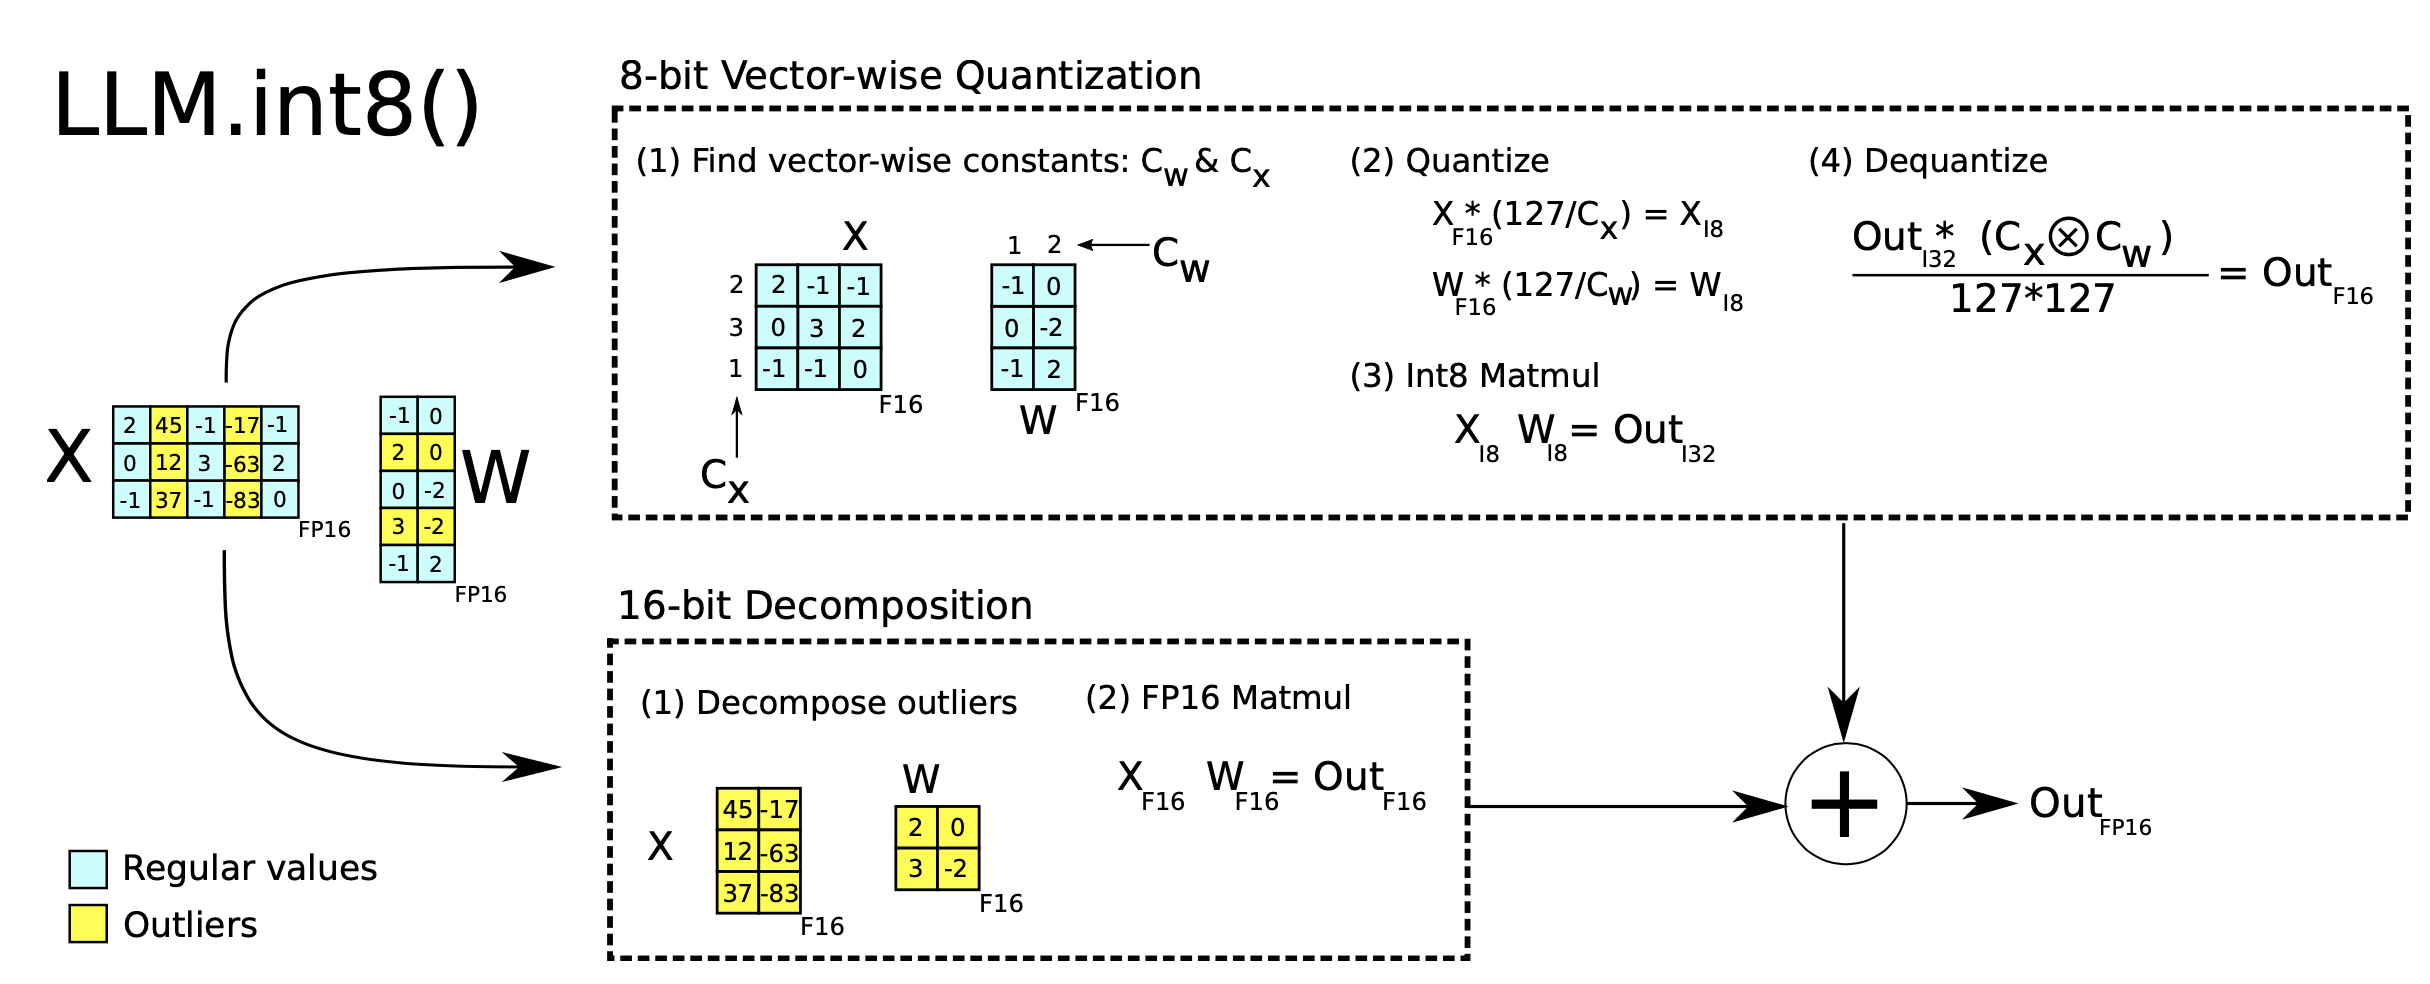
Large Transformer Model Inference Optimization | Lil'Log

The Great AI Compression: How LLM Quantization Solves the VRAM Bottleneck