
Llm Serving Nvidia Ccluster
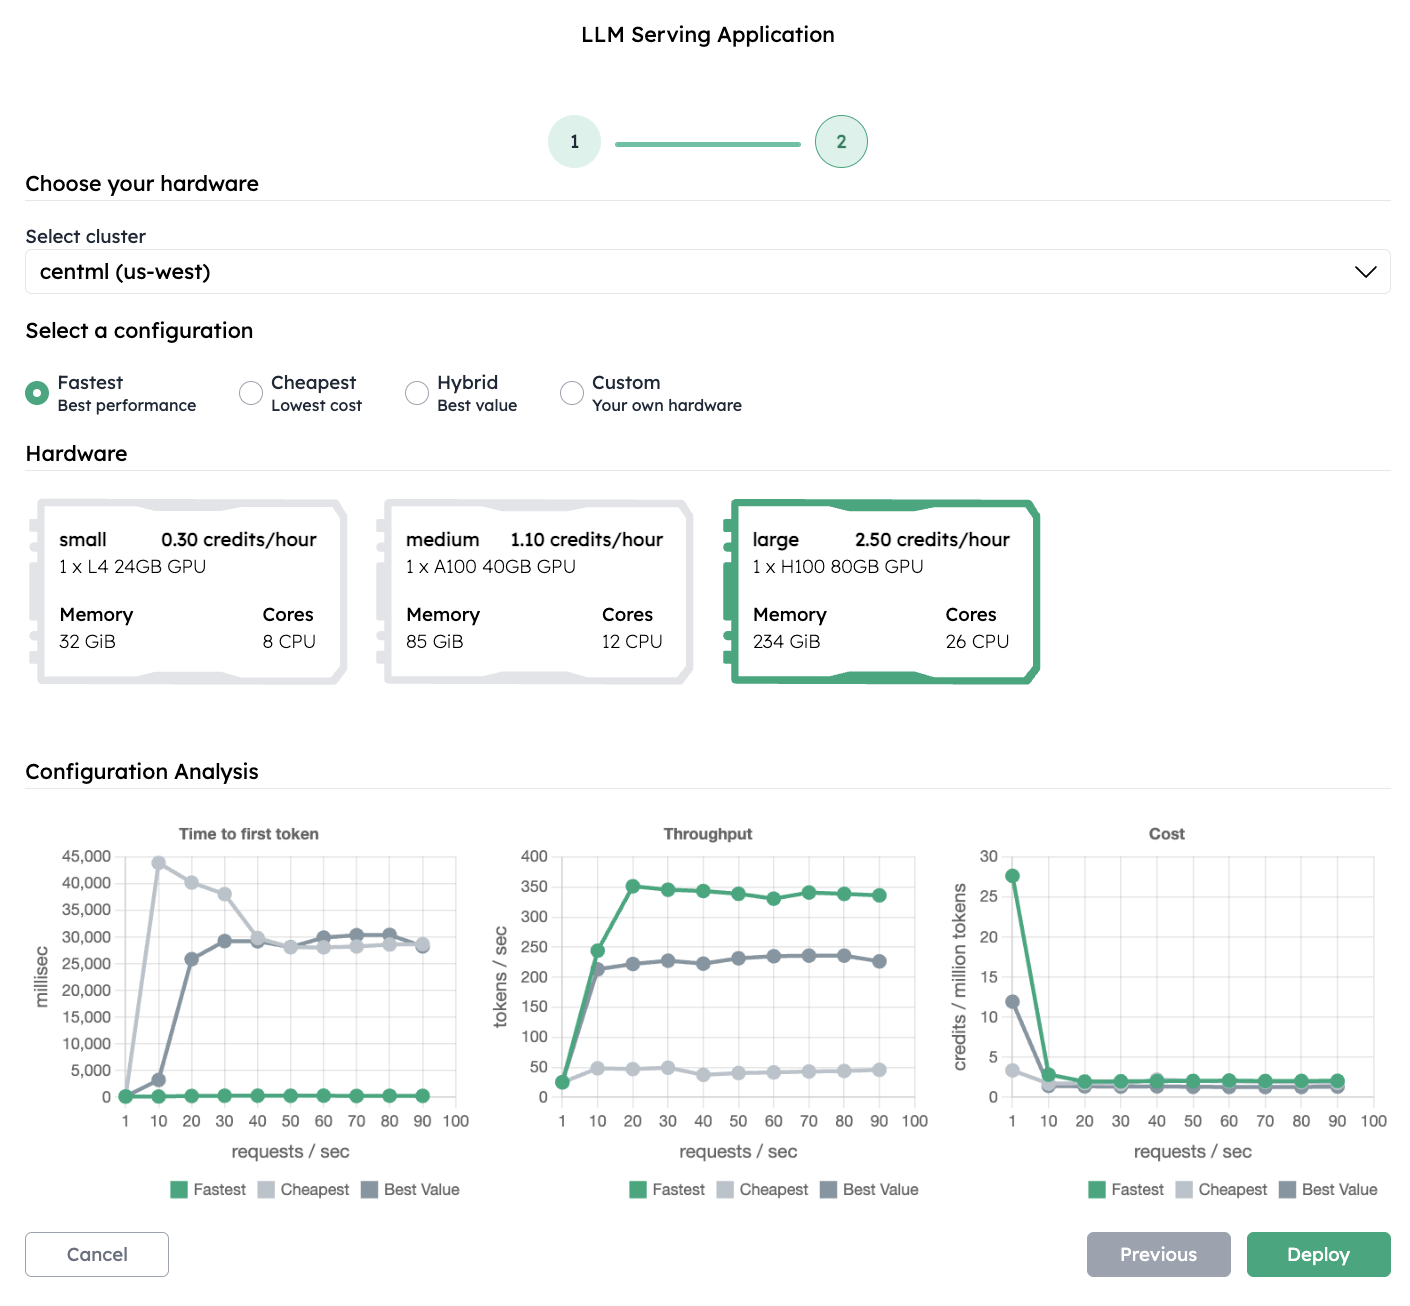
LLM Serving | NVIDIA CCluster
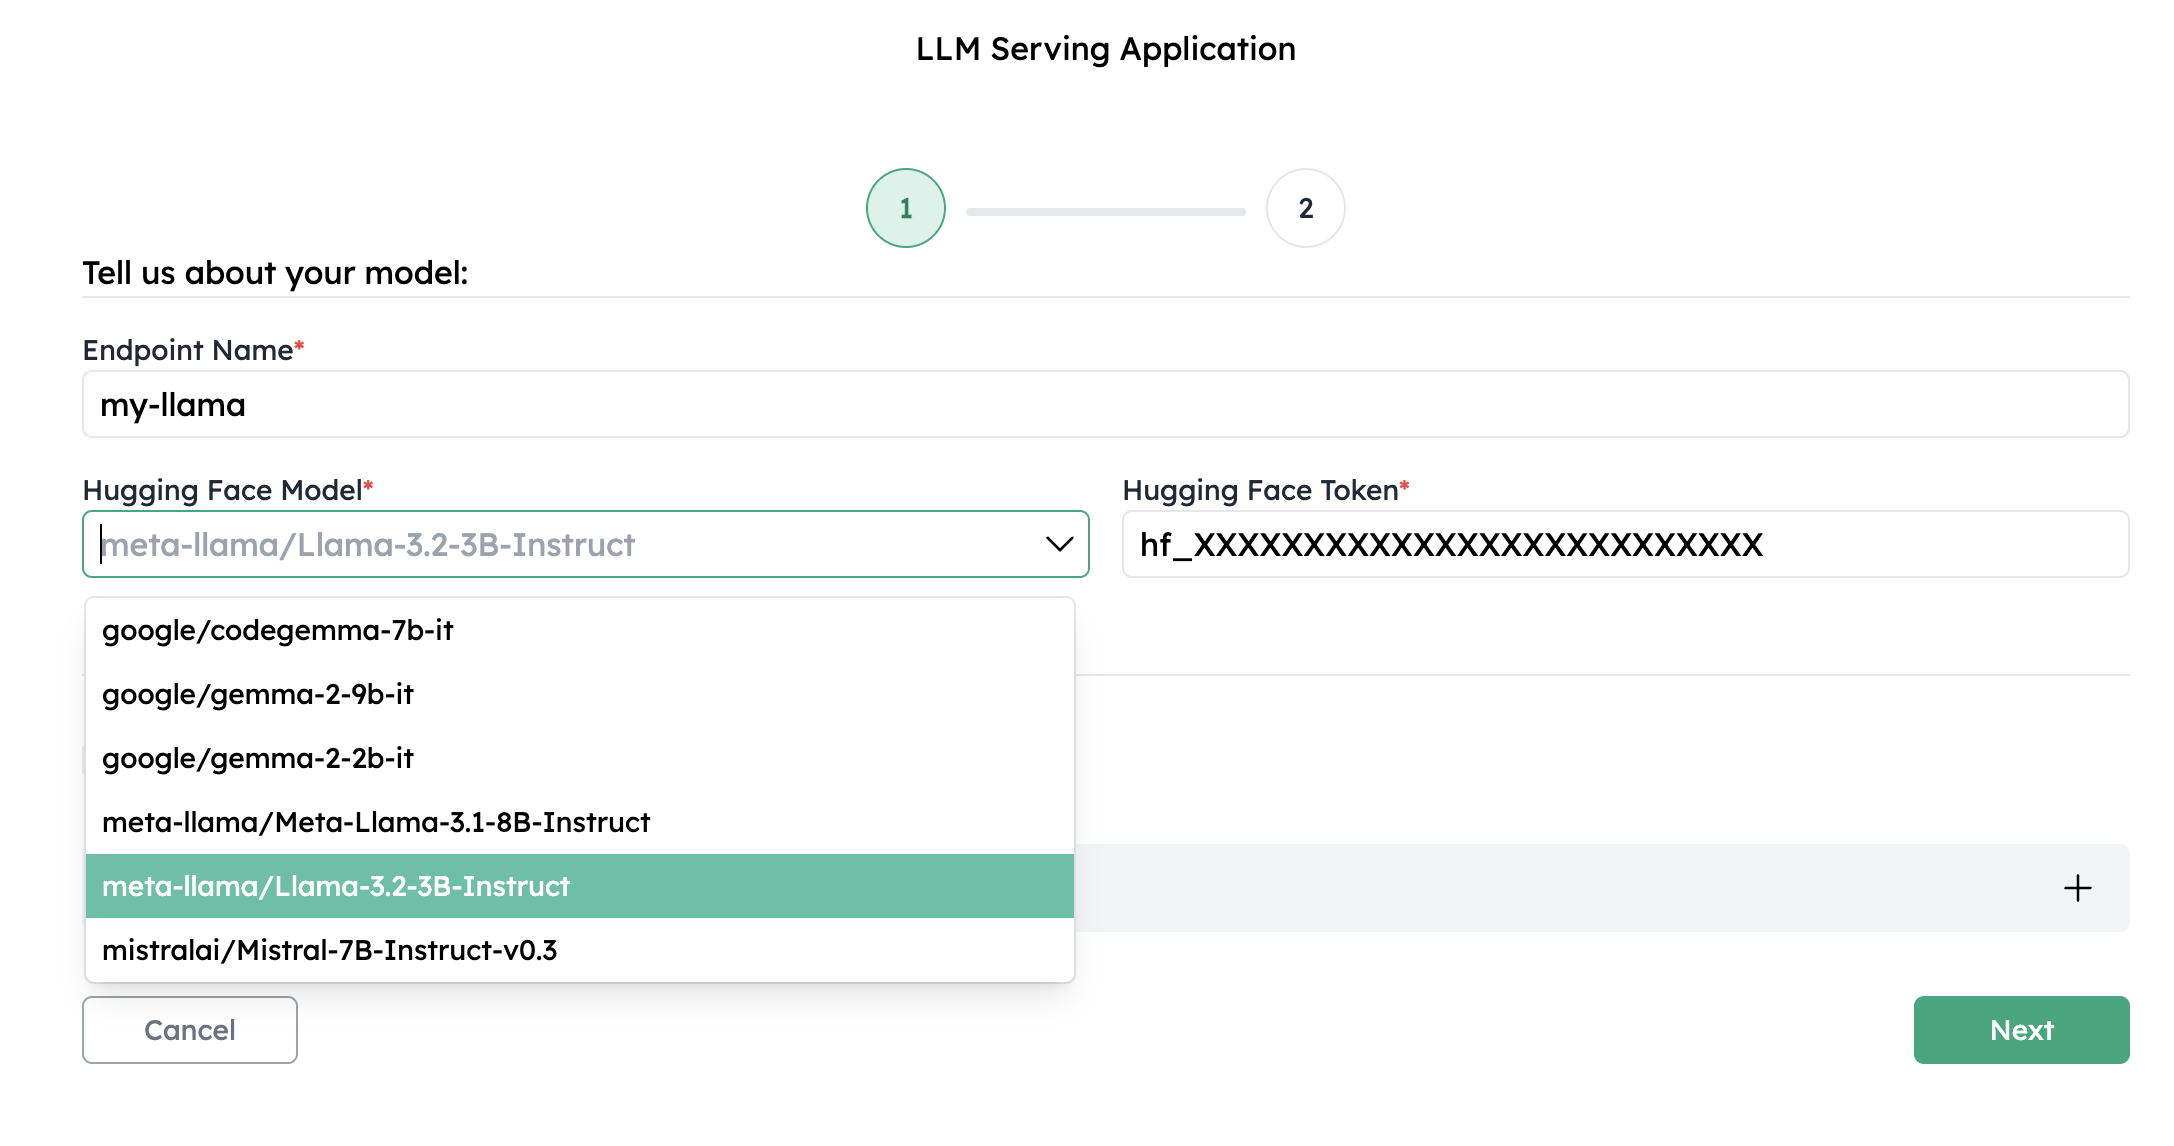
LLM Serving | NVIDIA CCluster

Deploying the NVIDIA AI Blueprint for Cost-Efficient LLM Routing ...
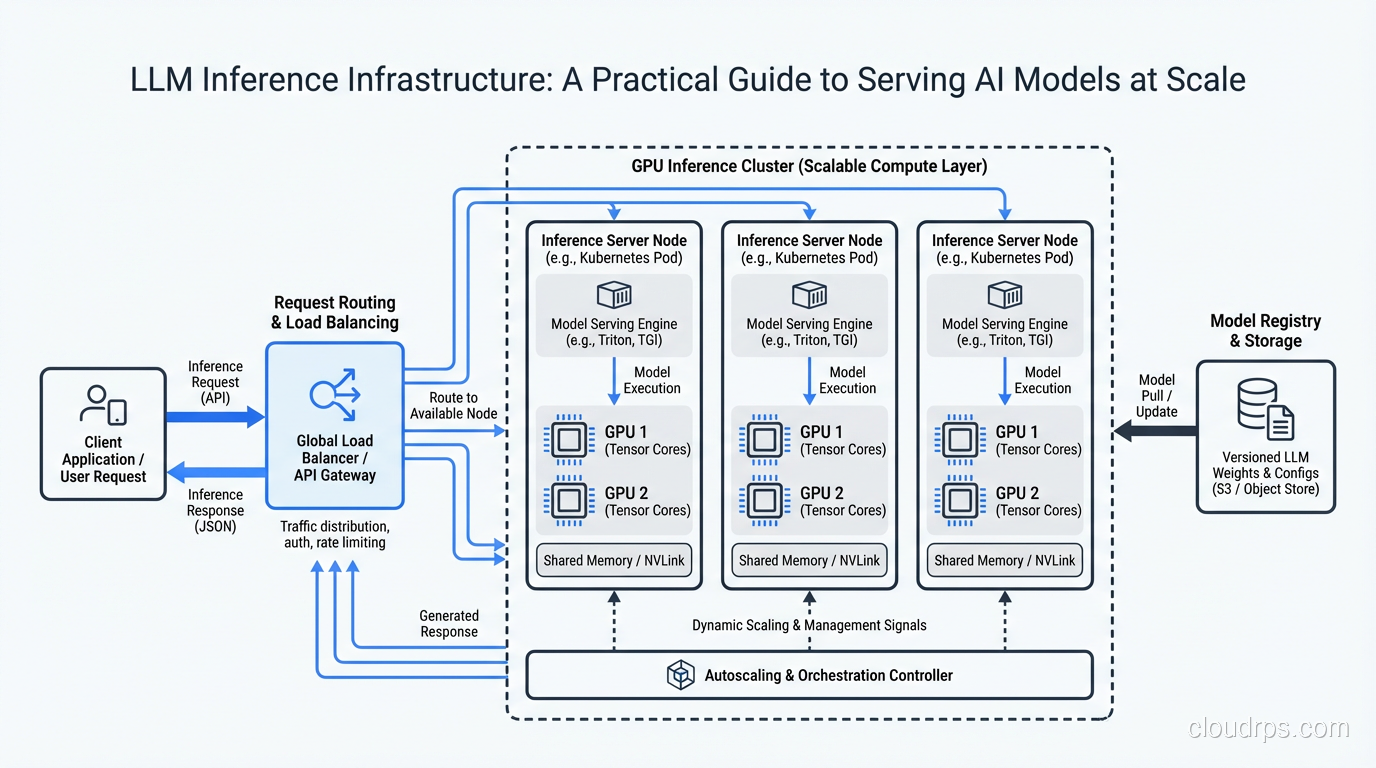
LLM Inference Infrastructure: Serving AI at Scale

Predictable LLM Serving on GPU Clusters | AI Research Paper Details
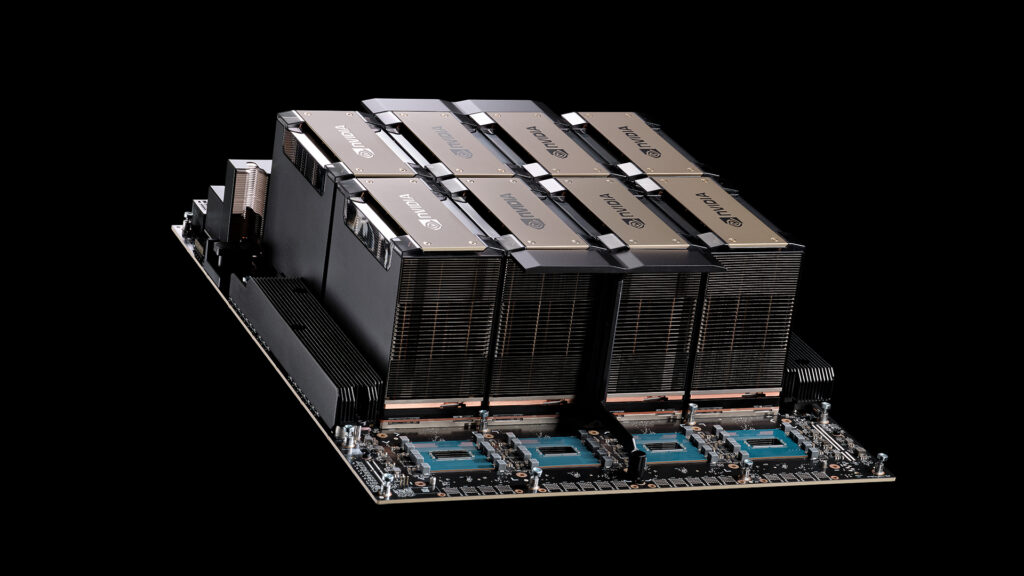
Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...

Securing LLM Systems Against Prompt Injection | NVIDIA Technical Blog
Mastering LLM Techniques: Training | NVIDIA Technical Blog

How NVIDIA improves GPU Cluster Utilization with LLM Agents - YouTube

TensorRT-LLM in Practice: A Field Guide to NVIDIA-Optimized LLM Serving ...
Advertisement Space (300x250)
Curating Custom Datasets for LLM Training with NVIDIA NeMo Curator ...
LLM Inference Benchmarking Guide: NVIDIA GenAI-Perf and NIM | NVIDIA ...
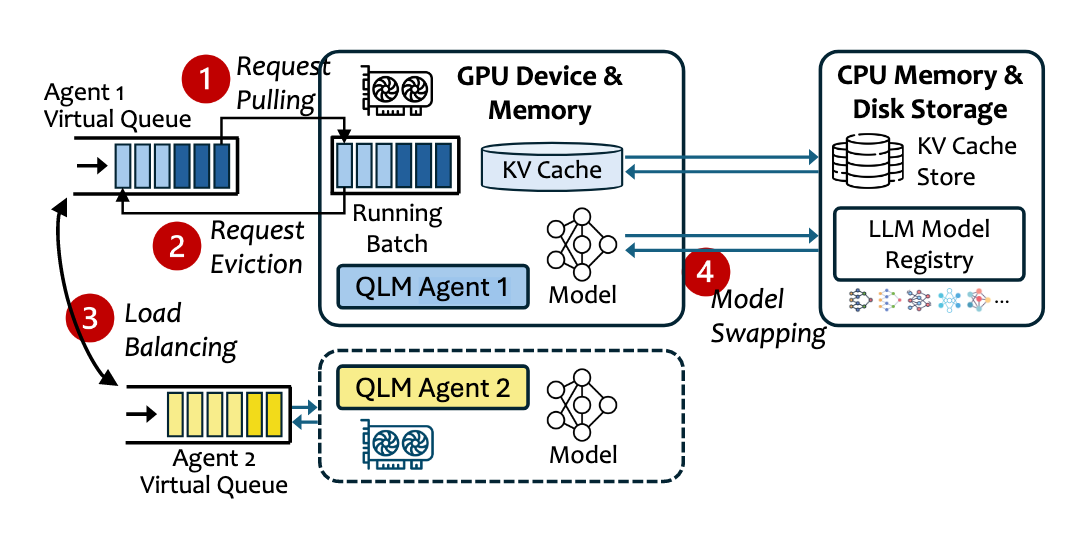
LLM Serving | l1l
NVIDIA RTX 시스템으로 Windows PC에서 LLM 애플리케이션 강화하기 - NVIDIA Technical Blog

Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
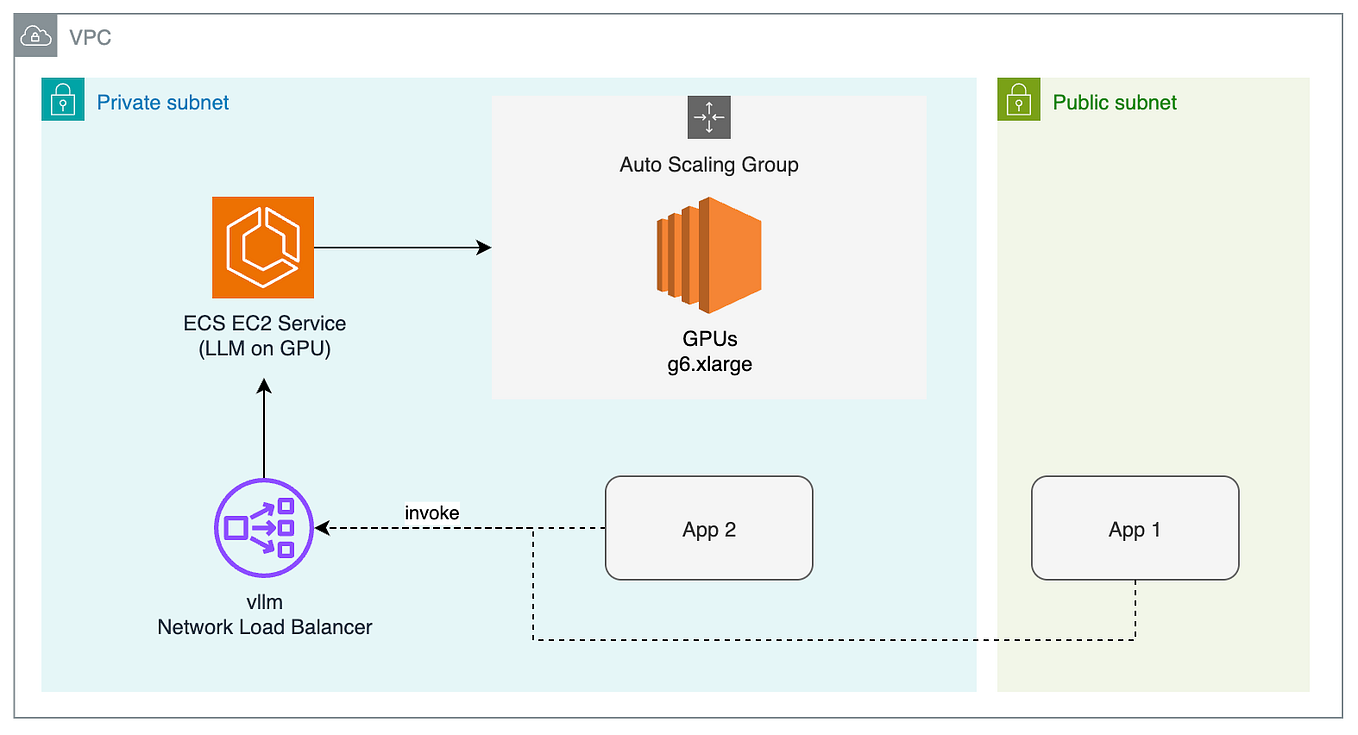
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

NVIDIA's TensorRT-LLM: Fast LLM Inference on NVIDIA GPUs | Mridhul Jose ...

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
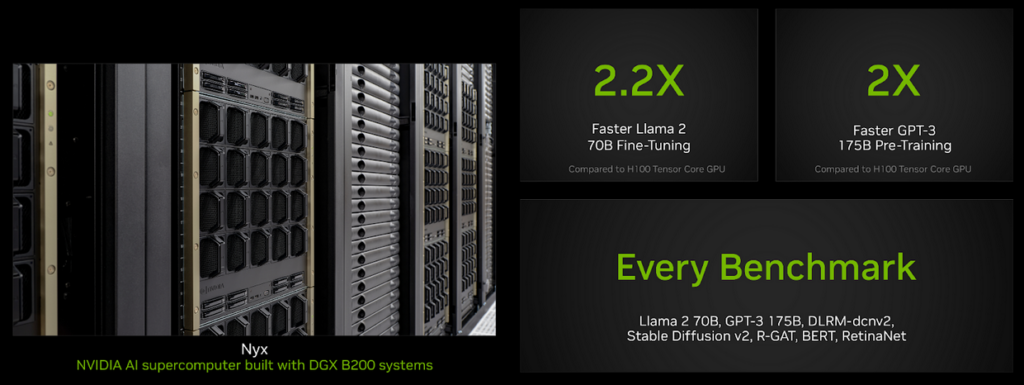
NVIDIA Blackwell Doubles LLM Training Performance in MLPerf Training v4 ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
Advertisement Space (336x280)
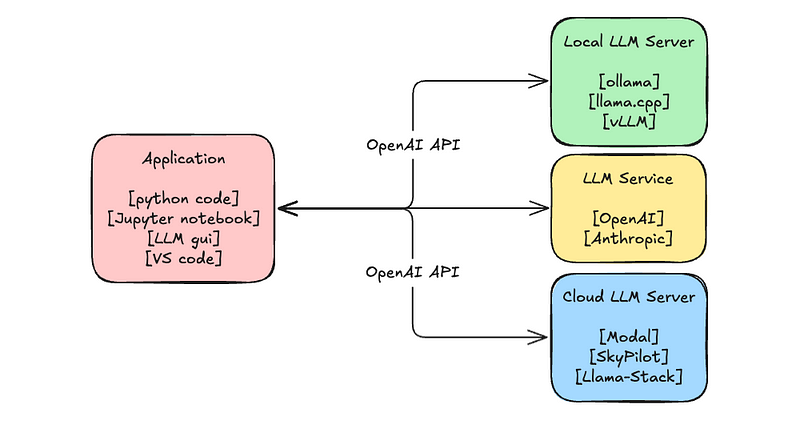
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

Serving Inference for LLMs: A Case Study with NVIDIA Triton Inference ...

Applying Mixture of Experts in LLM Architectures | NVIDIA Technical Blog

Tailoring LLM Inference with NVIDIA NIM using Key Features of TensorRT ...

NVIDIA TensorRT-LLM による、LoRA LLM のチューニングとデプロイ - NVIDIA 技術ブログ
Supercharging LLM Applications on Windows PCs with NVIDIA RTX Systems ...
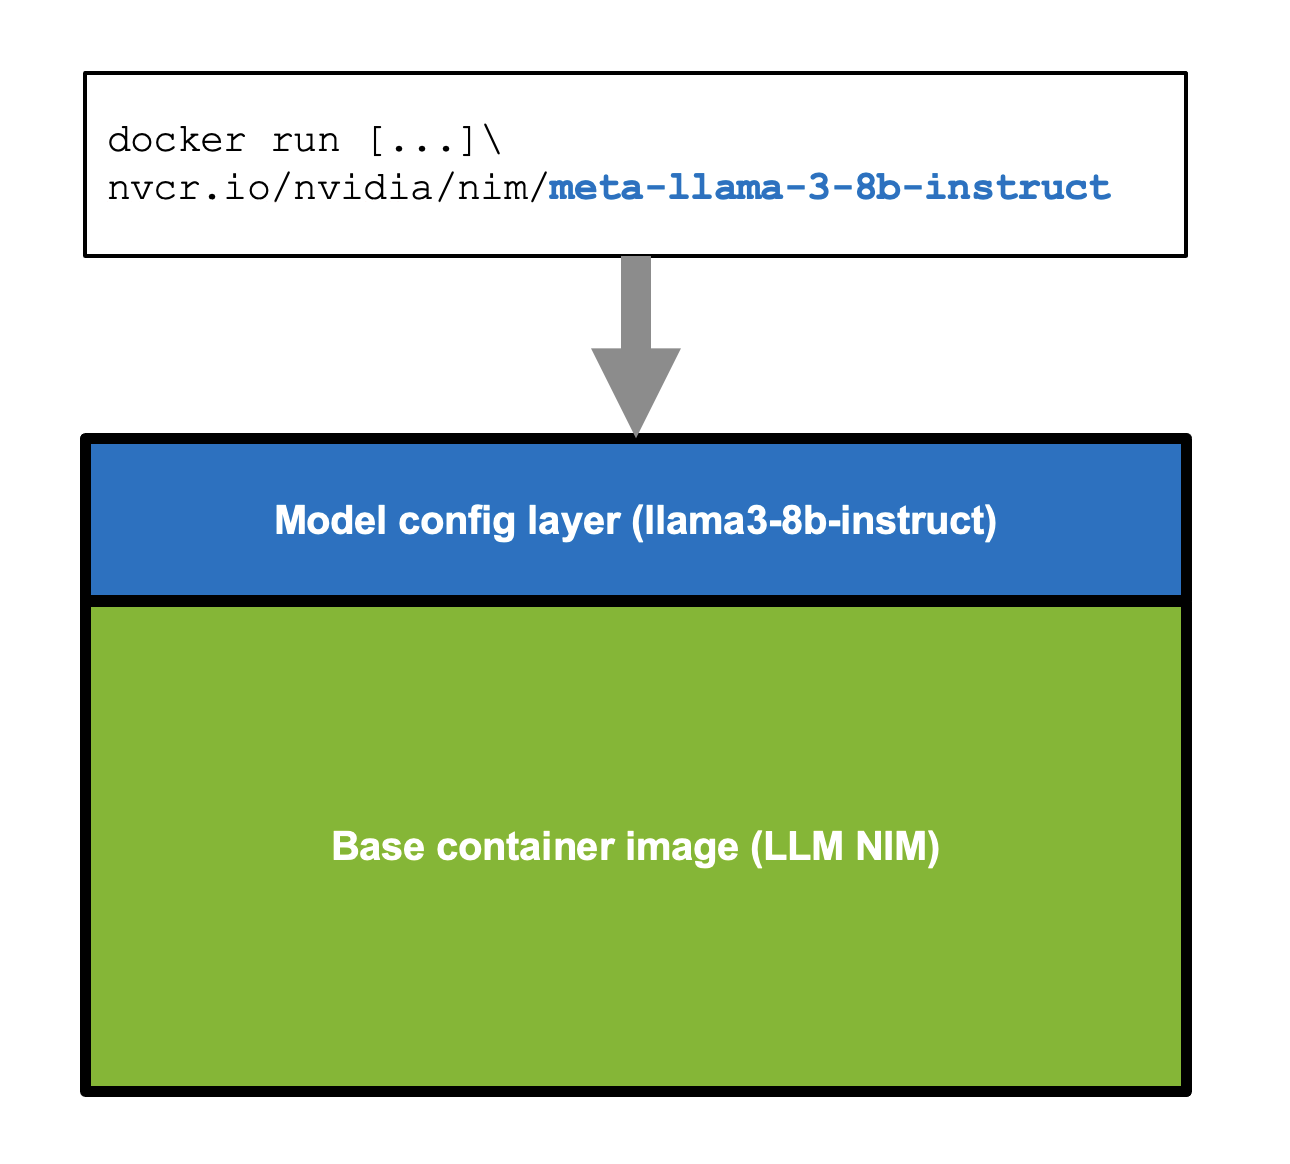
NVIDIA NIM을 사용한 다국어 LLM 배포 - NVIDIA Technical Blog

NVIDIA Blackwell Sets STAC-AI Record for LLM Inference in Finance ...
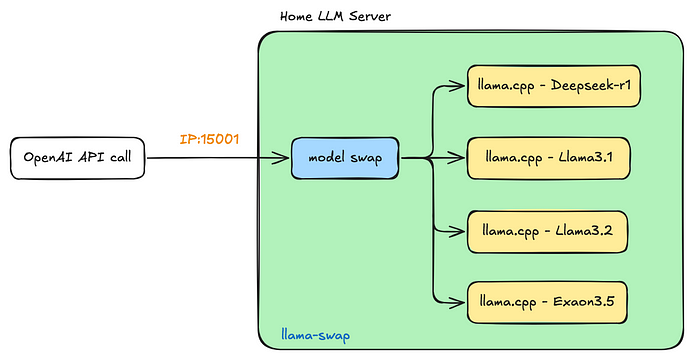
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
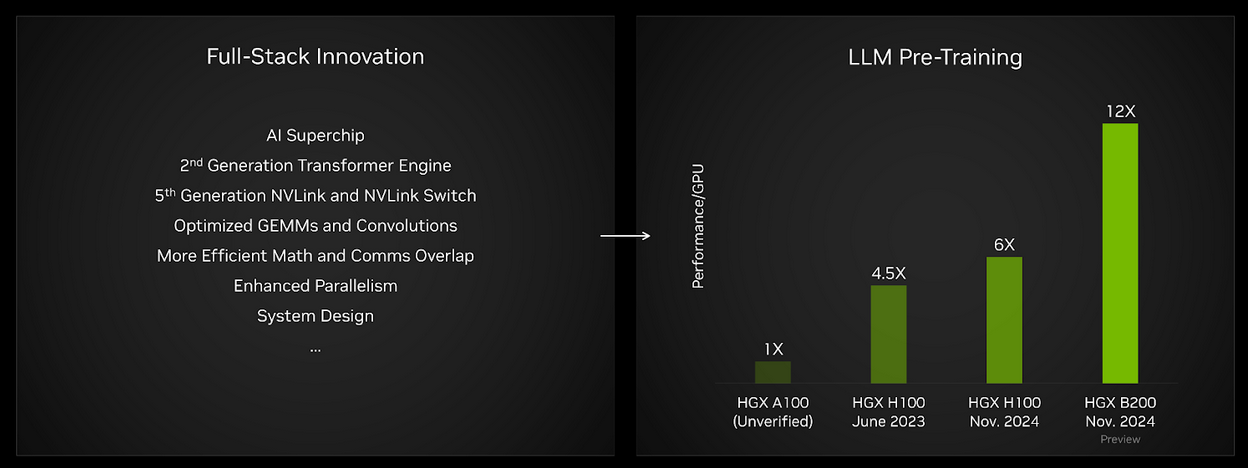
MLPerf Training v4.1에서 LLM 트레이닝 성능을 두 배로 향상시킨 NVIDIA Blackwell - NVIDIA ...
Advertisement Space (336x280)

NVIDIA H200 Tensor Core GPUs and NVIDIA TensorRT-LLM Set MLPerf LLM ...

$NVDA NVIDIA Dynamo: Datacenter-Scale LLM Disaggregated Orchestration ...
Multi-Tenant LLM Serving on GPU Cloud: Per-Customer Isolation, Token ...
NVIDIA TensorRT-LLM Now Supports Recurrent Drafting for Optimizing LLM ...

Efficient Distributed LLM serving | by Sergii Ivakhno | Medium
NVIDIA TensorRT-LLM による、LoRA LLM のチューニングとデプロイ - NVIDIA 技術ブログ