
Llmcompressorutils Llm Compressor Docs

What is LLM Compressor? - LLM Compressor Docs

pytorch - LLM Compressor Docs

modeling - LLM Compressor Docs
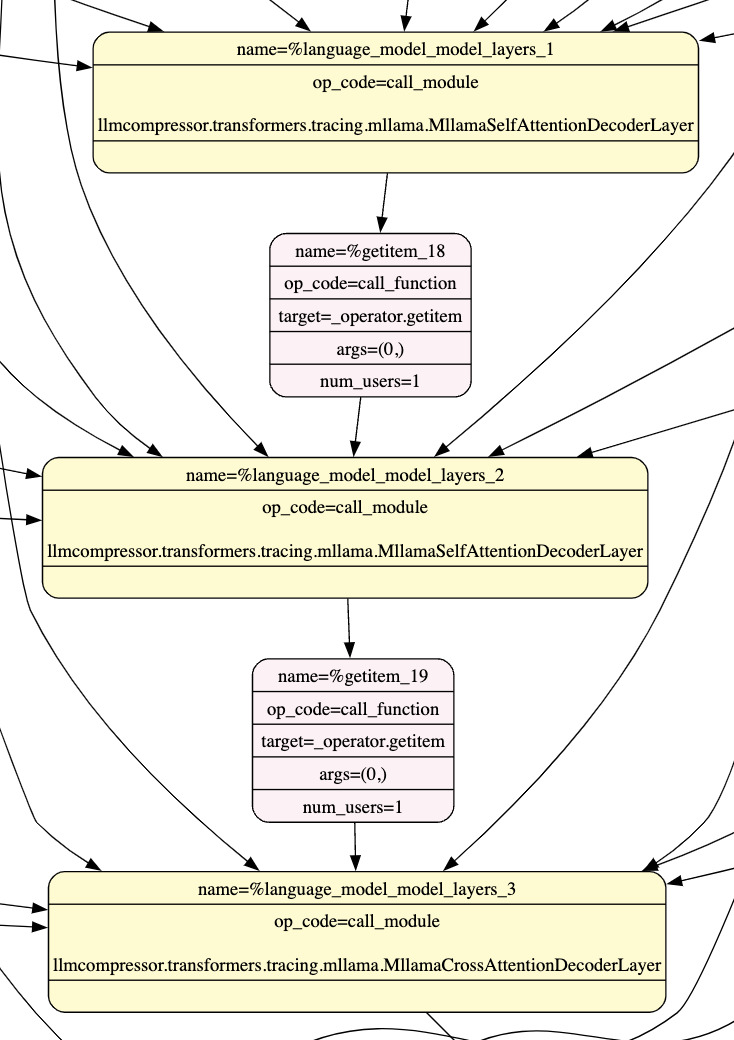
Sequential Onloading - LLM Compressor Docs
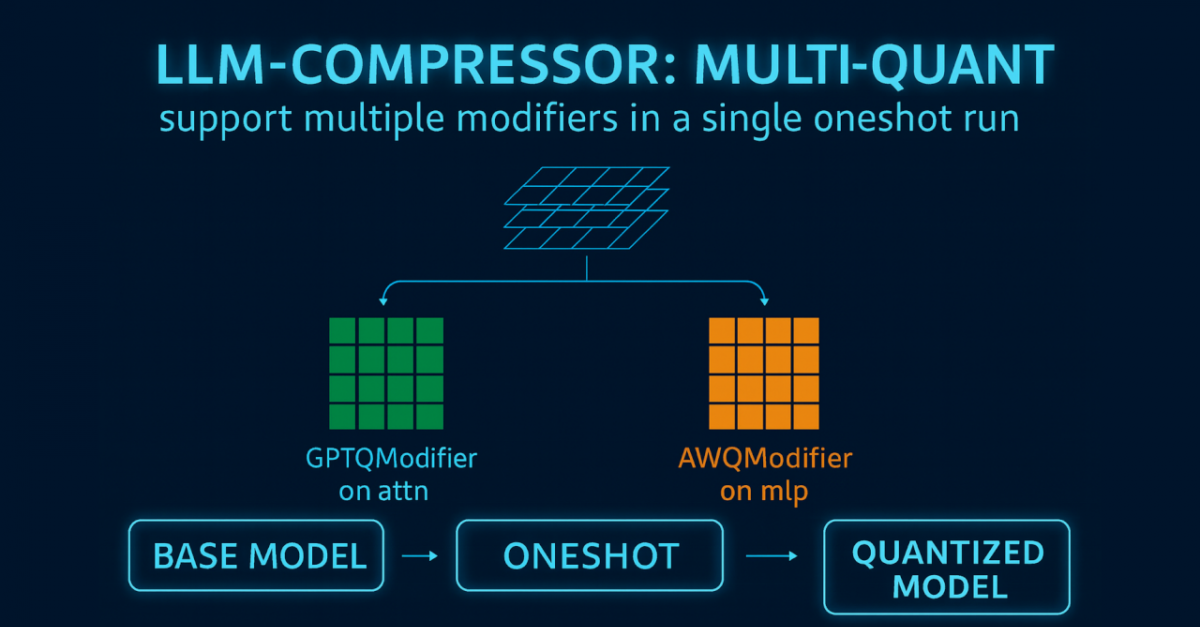
LLM Compressor 0.8.0: Extended support for Qwen3 and more | Red Hat ...
LLM Compressor v0.10: Faster compression with distributed GPTQ | Red ...
Advancing Low‑Bit Quantization for LLMs: AutoRound x LLM Compressor ...

LLM Compressor deep dive + walkthrough - YouTube

LLM Compressor testing - a nm-testing Collection

分散式 oneshot - LLM Compressor 文件 - vLLM 文件
Advertisement Space (300x250)

LLM Compressor 0.7.0 release recap | Red Hat Developer
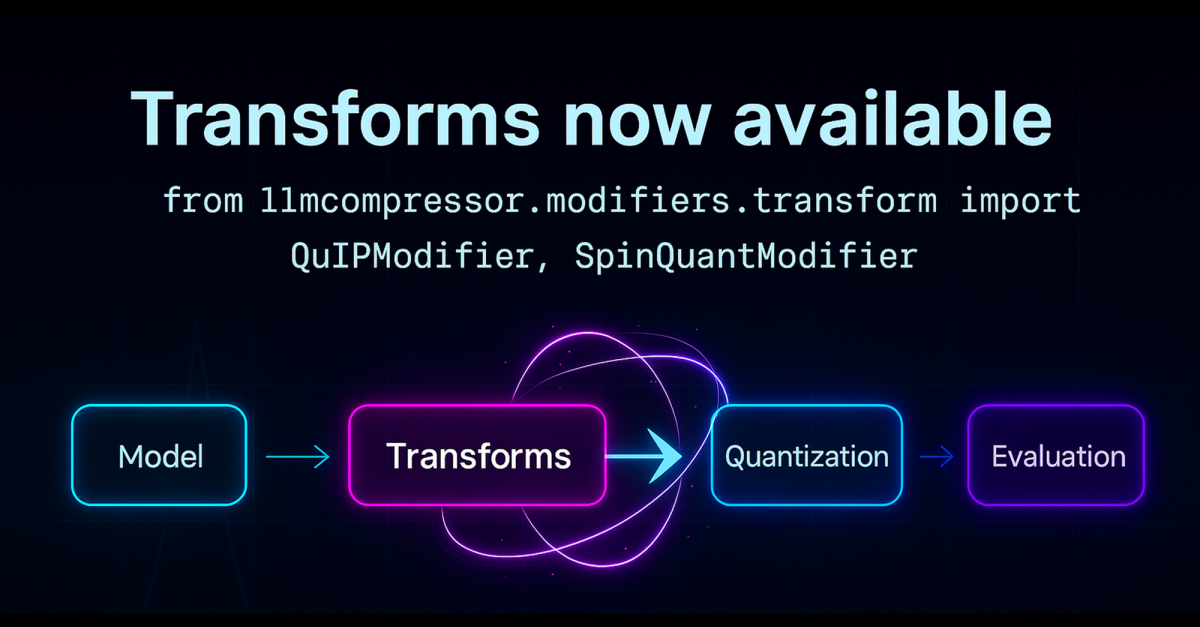
LLM Compressor 0.7.0 release recap | Red Hat Developer

Optimize LLMs for inference with LLM Compressor - YouTube
Latest LLM Compressor version slowdown · Issue #1610 · vllm-project/llm ...
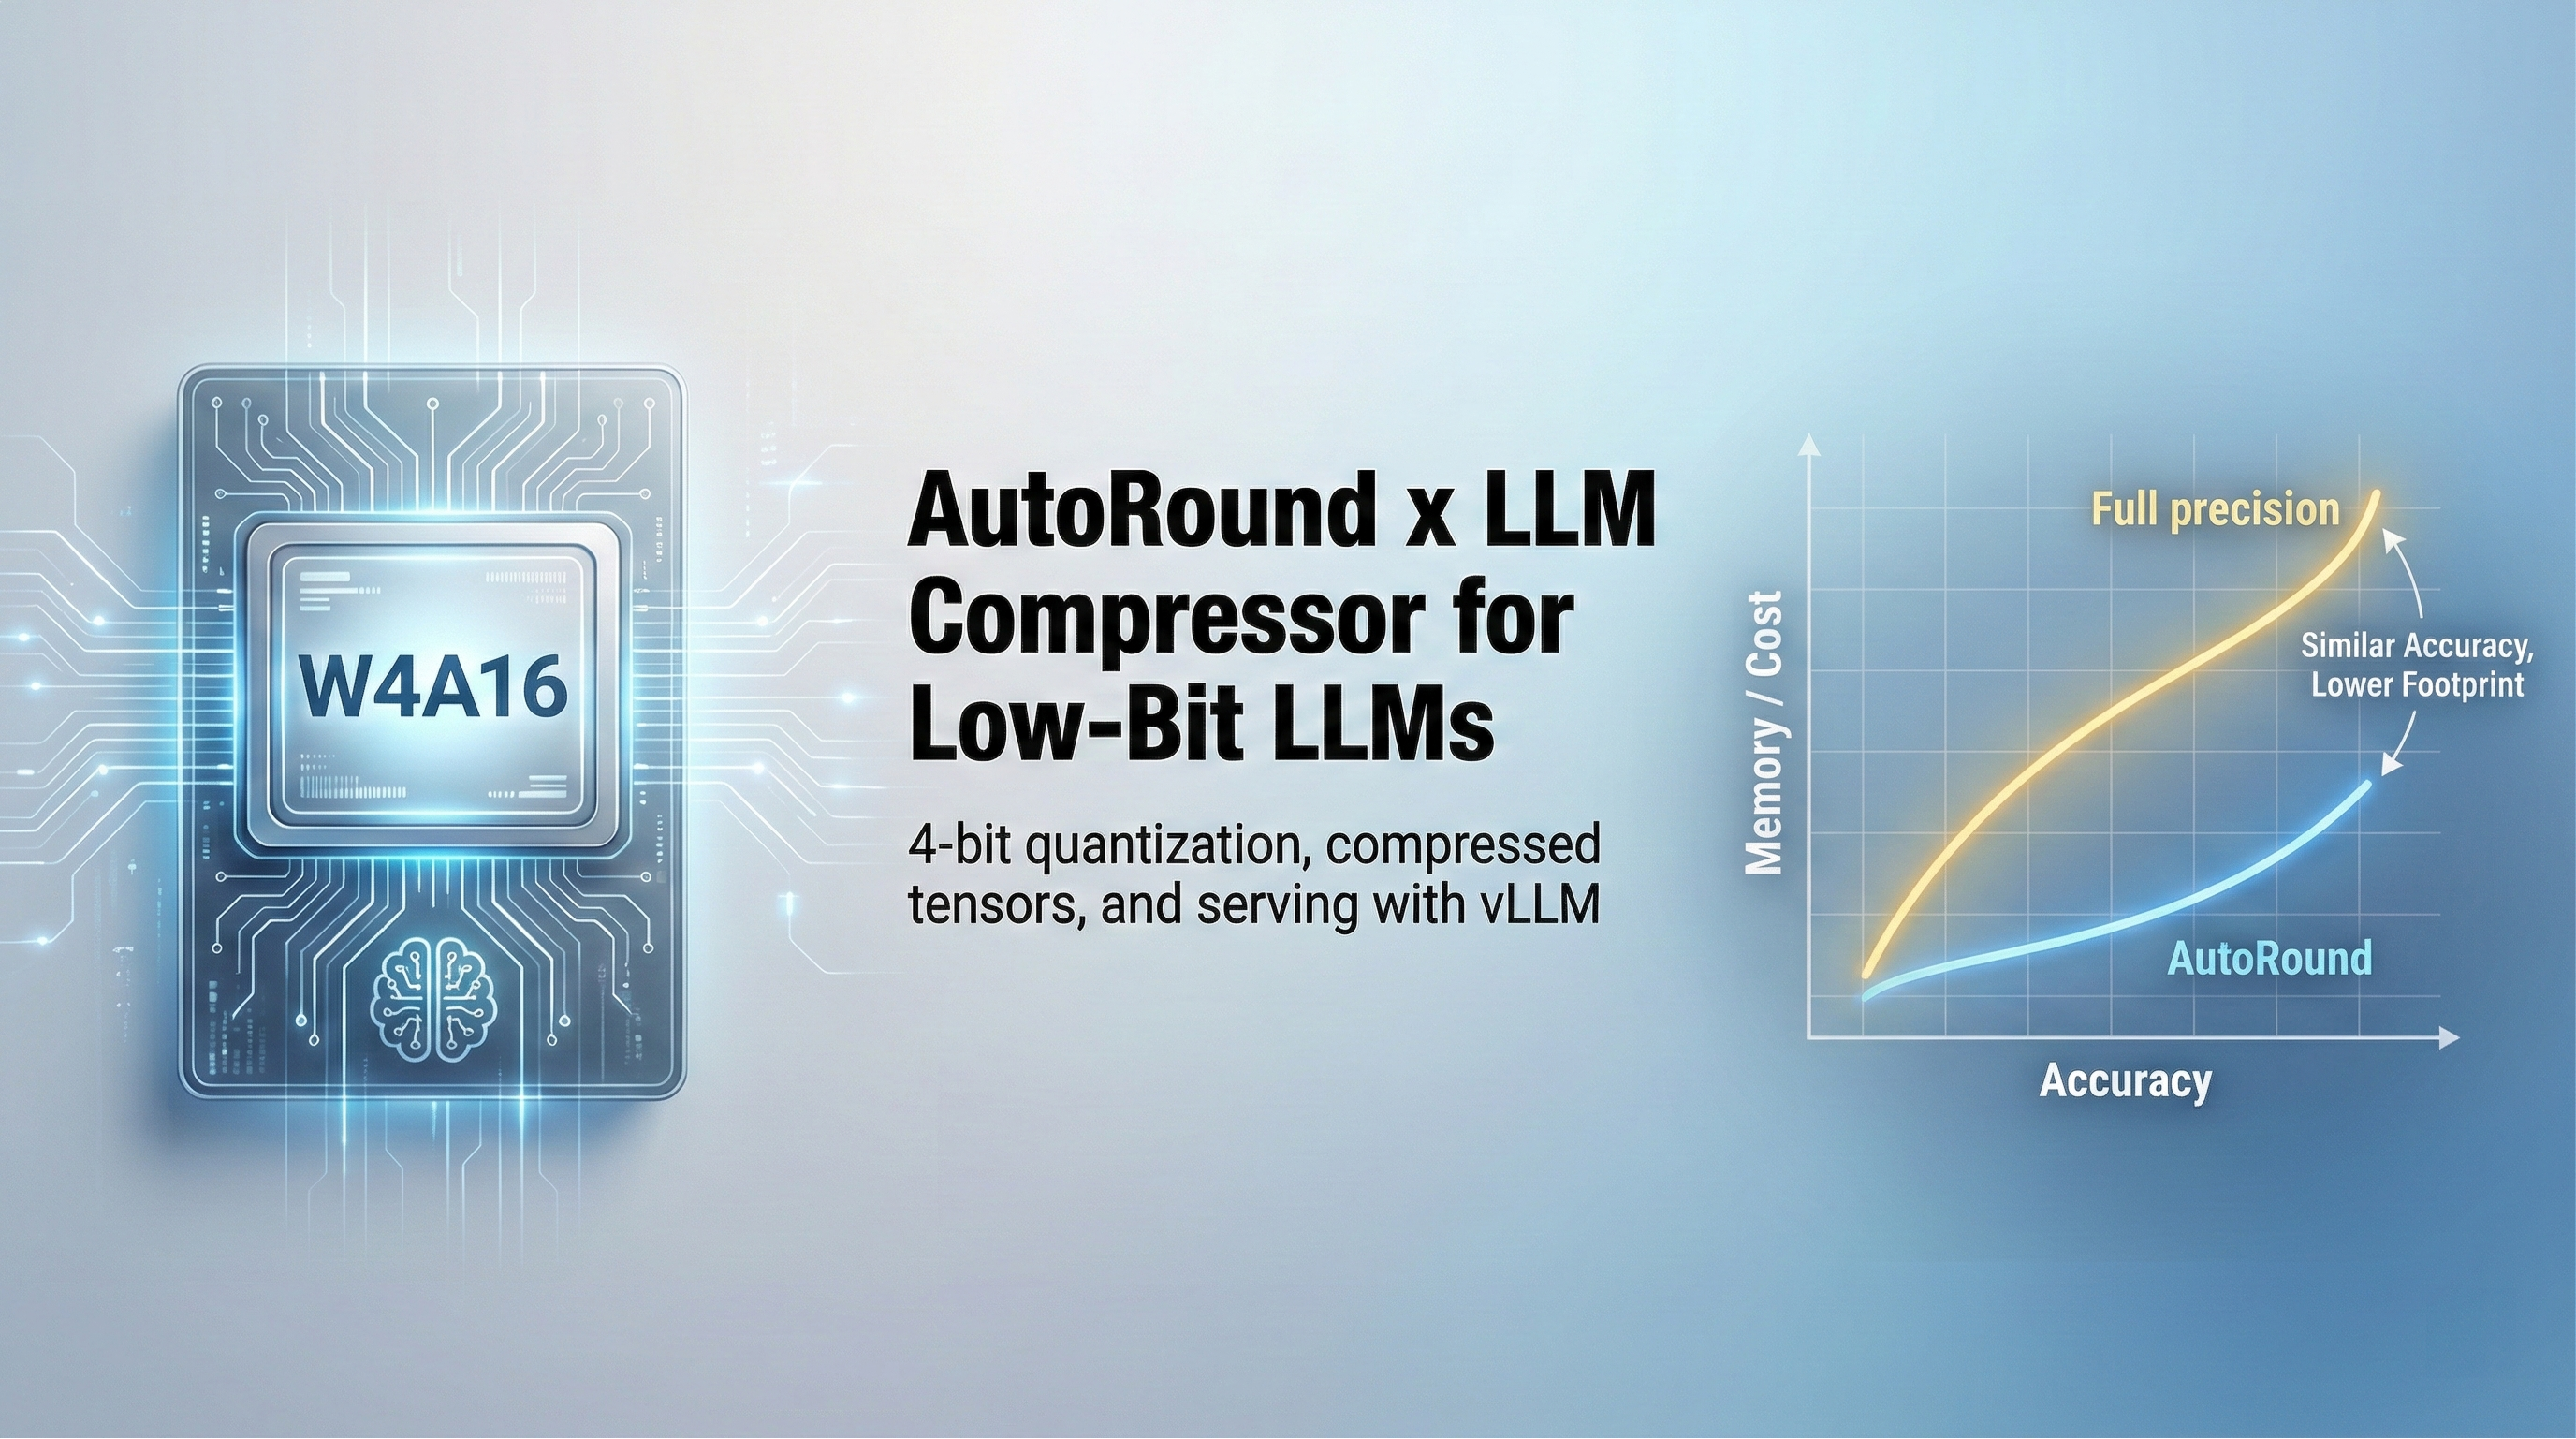
Advancing Low‑Bit Quantization for LLMs: AutoRound x LLM Compressor ...

什麼是 LLM Compressor? - LLM Compressor 文件 - vLLM 文件

Neural Magic Introduces the LLM Compressor Library | ml-news – Weights ...
Advancing low‑bit quantization for LLMs: AutoRound x LLM Compressor ...
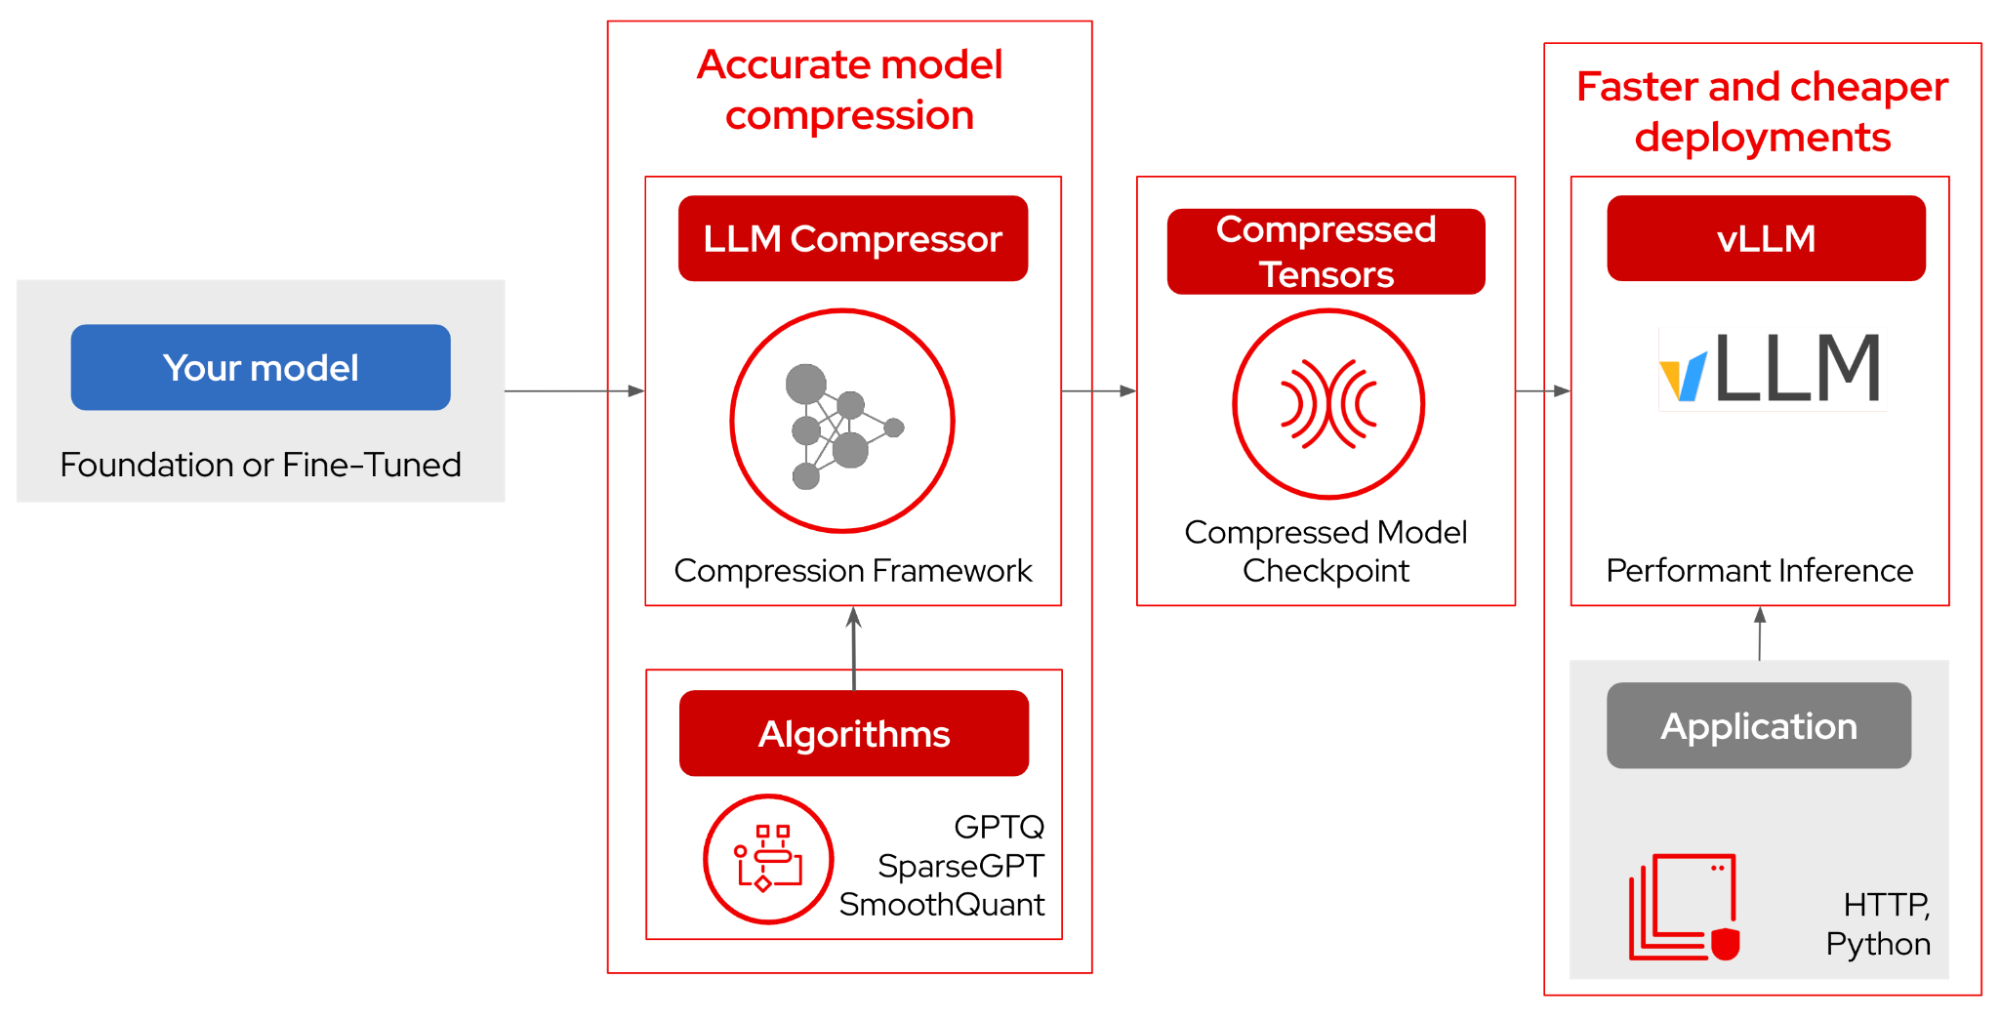
LLM compression and optimization: Cheaper inference with fewer hardware ...
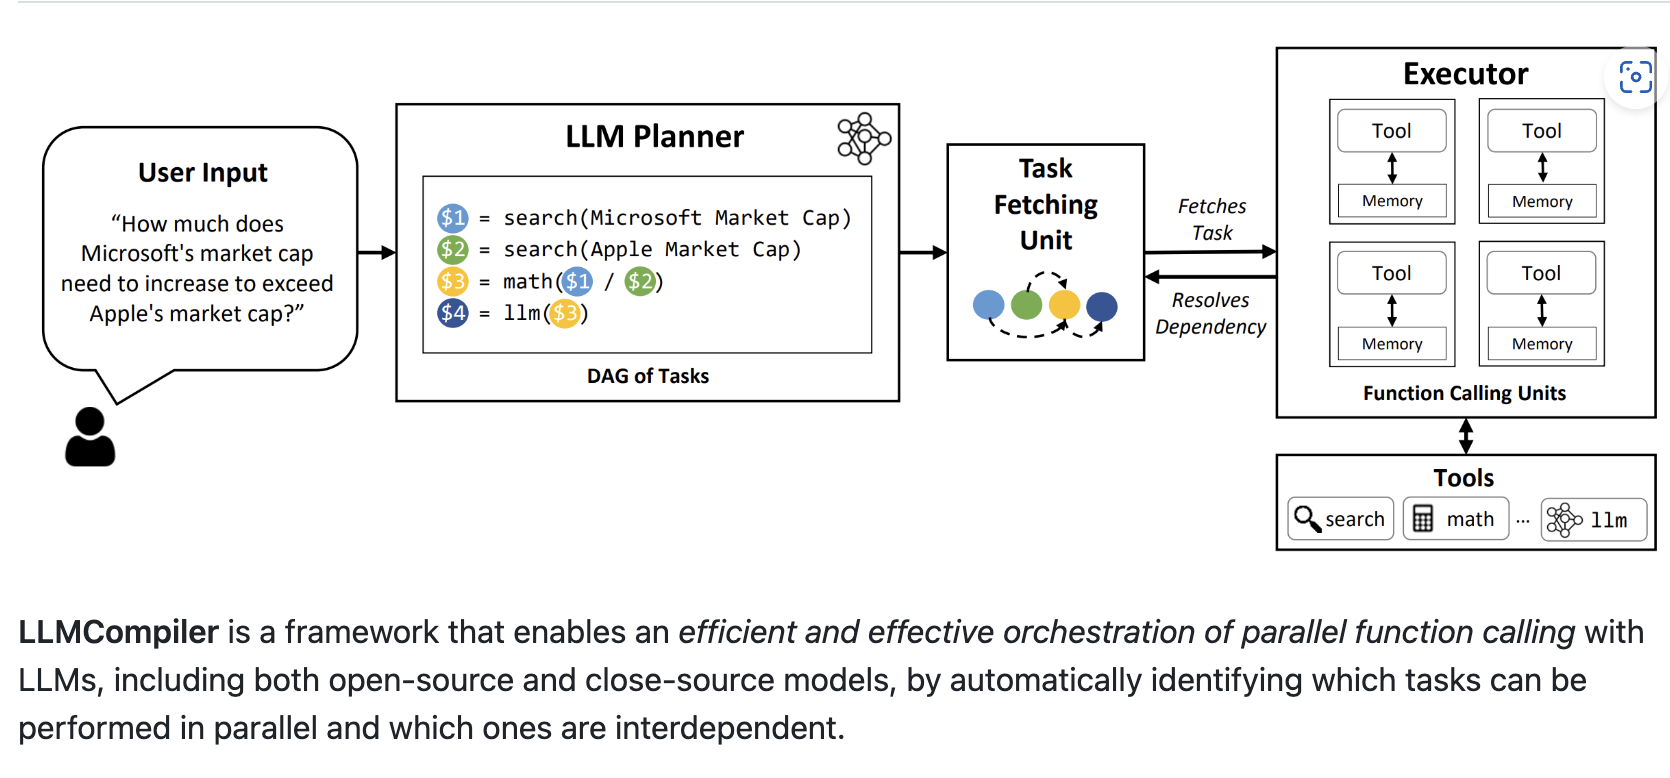
Exploring The Dynamics Of Llm Based Agent Frameworks – Monir ...
Advertisement Space (336x280)
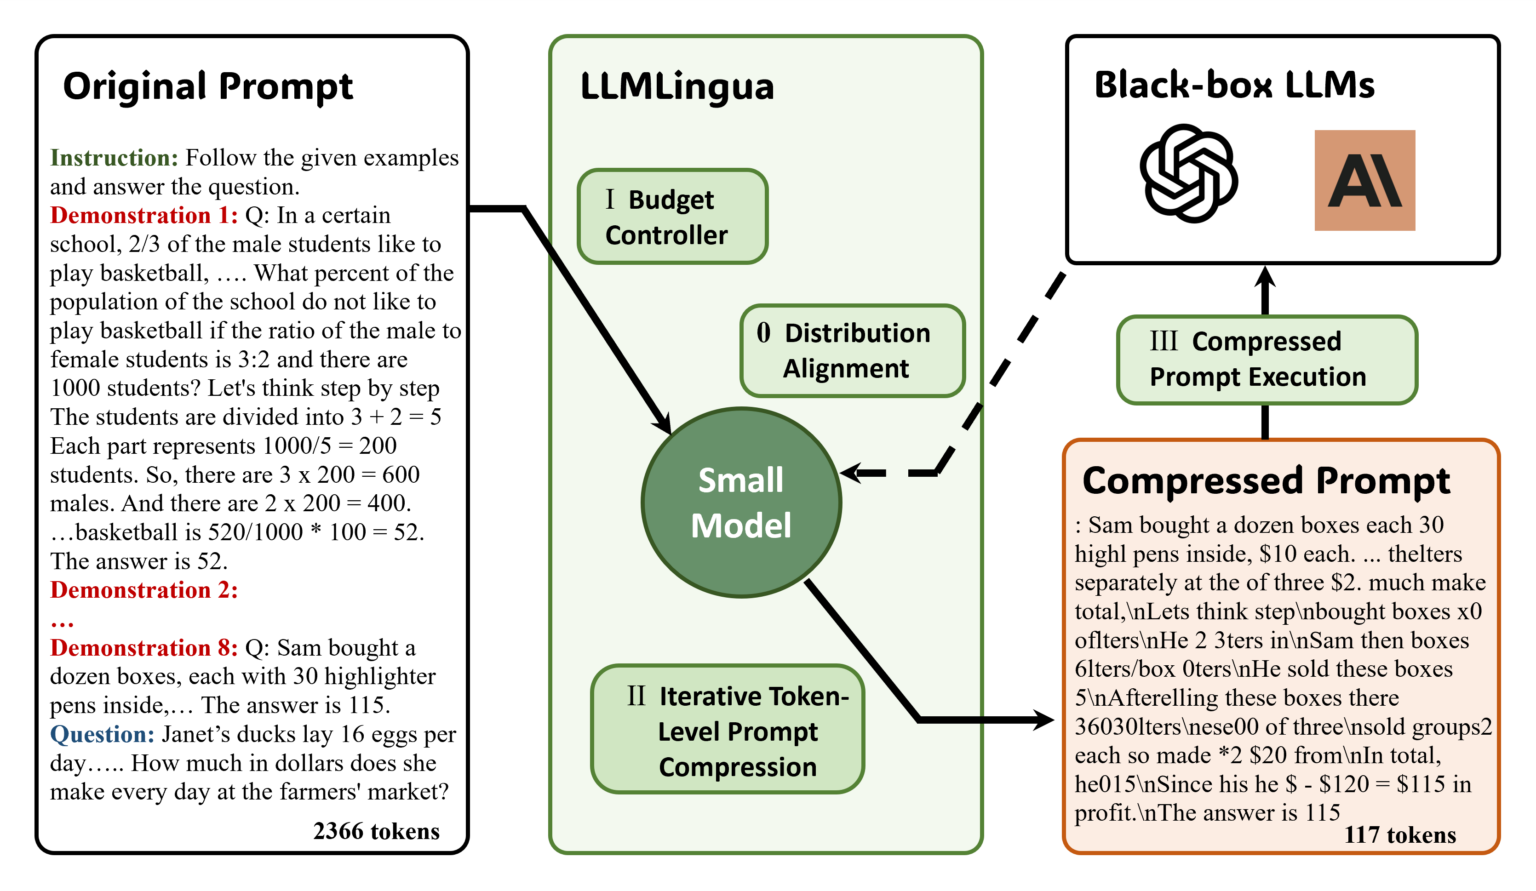
LLMLingua: Innovating LLM efficiency with prompt compression ...
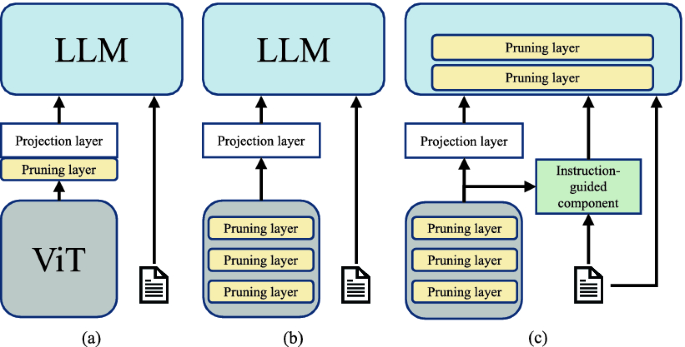
4 LLM Compression Techniques That You Can't Miss

LLM Compressor: Optimize LLMs for low-latency deployments | Red Hat ...
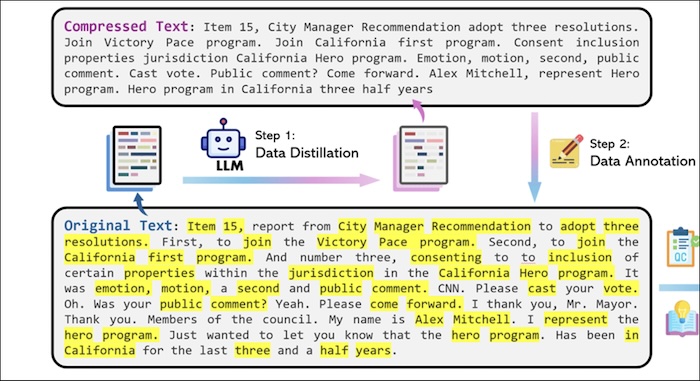
Lean AI - How to Reduce LLM Cost? | Benny's Mind Hack

Evaluating LLM Compression: Balancing Efficiency, Trustworthiness, and ...

Prompt Compression Benchmarker: Cut LLM Input Costs by 35–63% With ...

LLM Compressor: Optimize LLMs for low-latency deployments | Red Hat ...
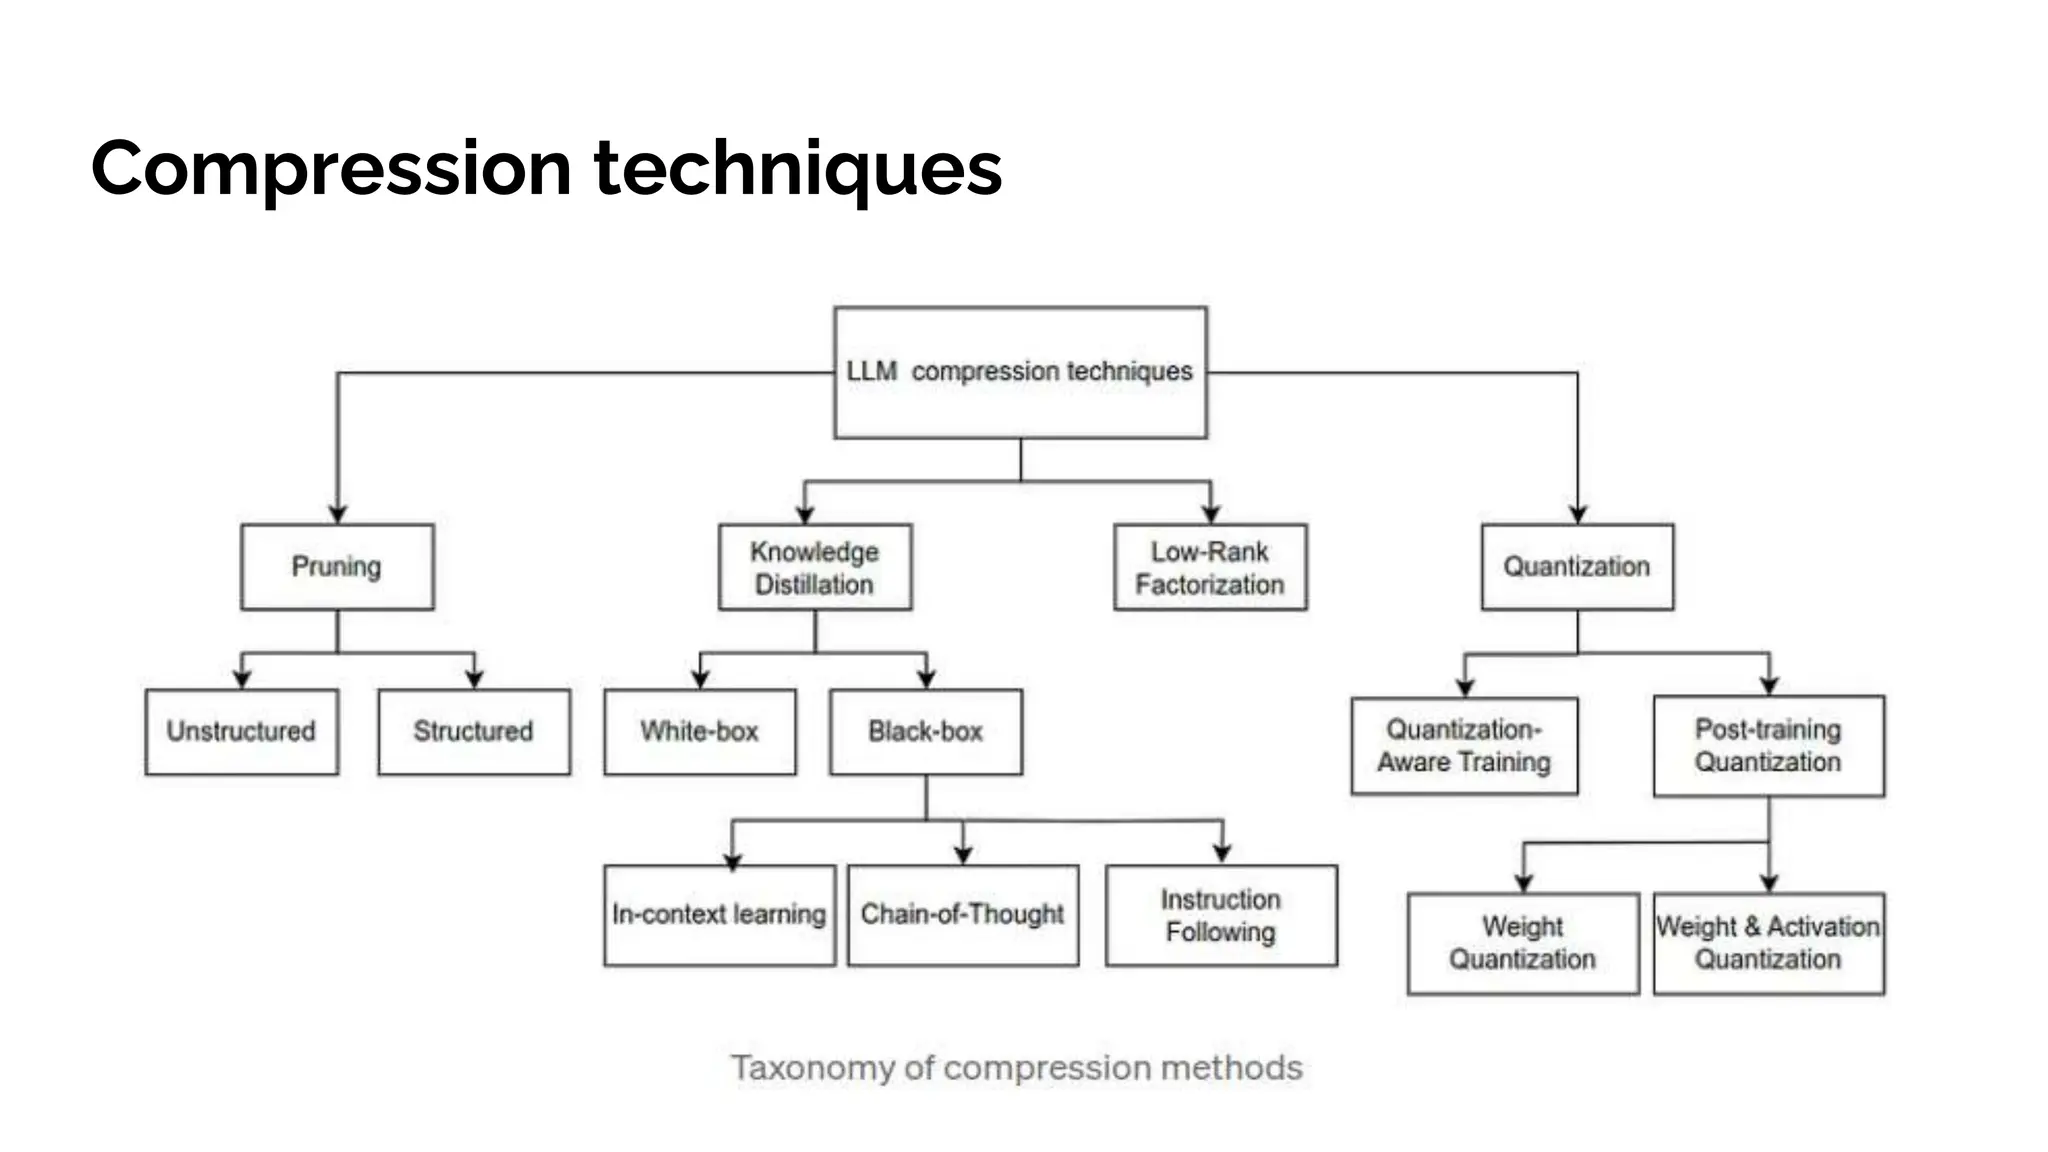
Paper presentation on LLM compression | PPTX
LLM Compression Techniques to Build Faster and Cheaper LLMs
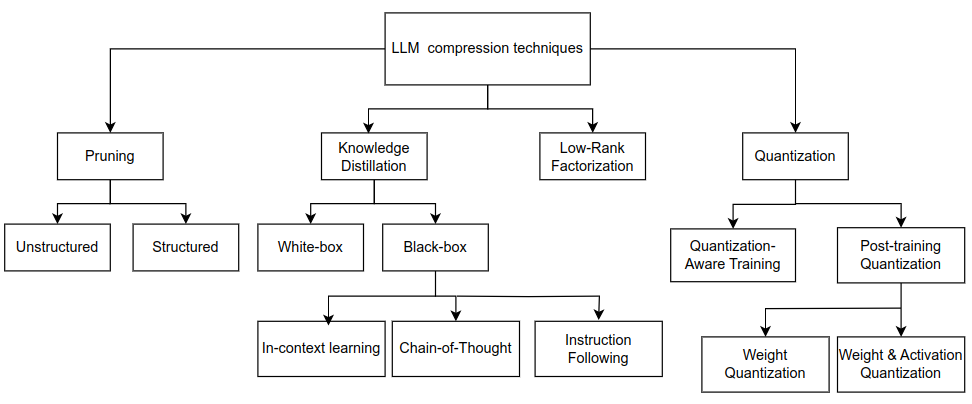
LLM Compression Techniques to Build Faster and Cheaper LLMs
Advertisement Space (336x280)
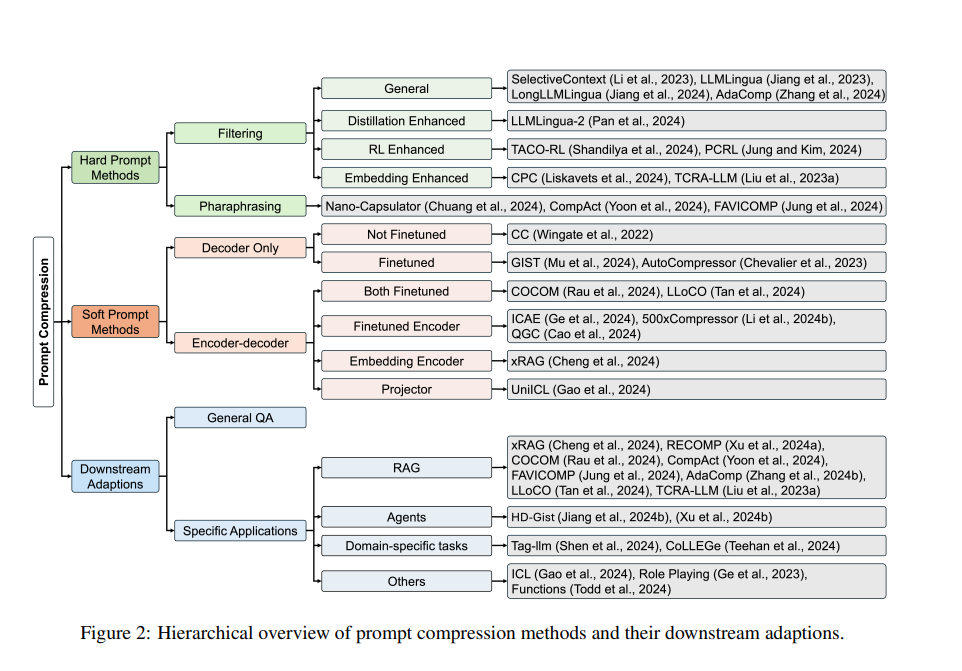
LLM Compression Techniques to Build Faster and Cheaper LLMs
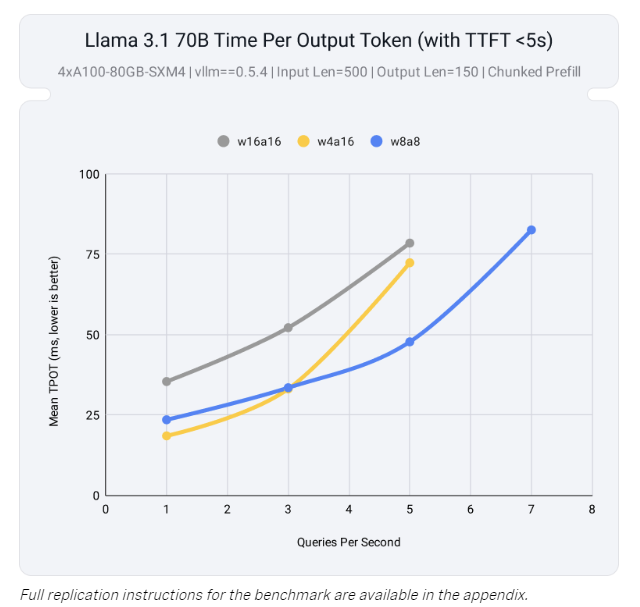
Neural Magic Releases LLM Compressor: A Novel Library to Compress LLMs ...
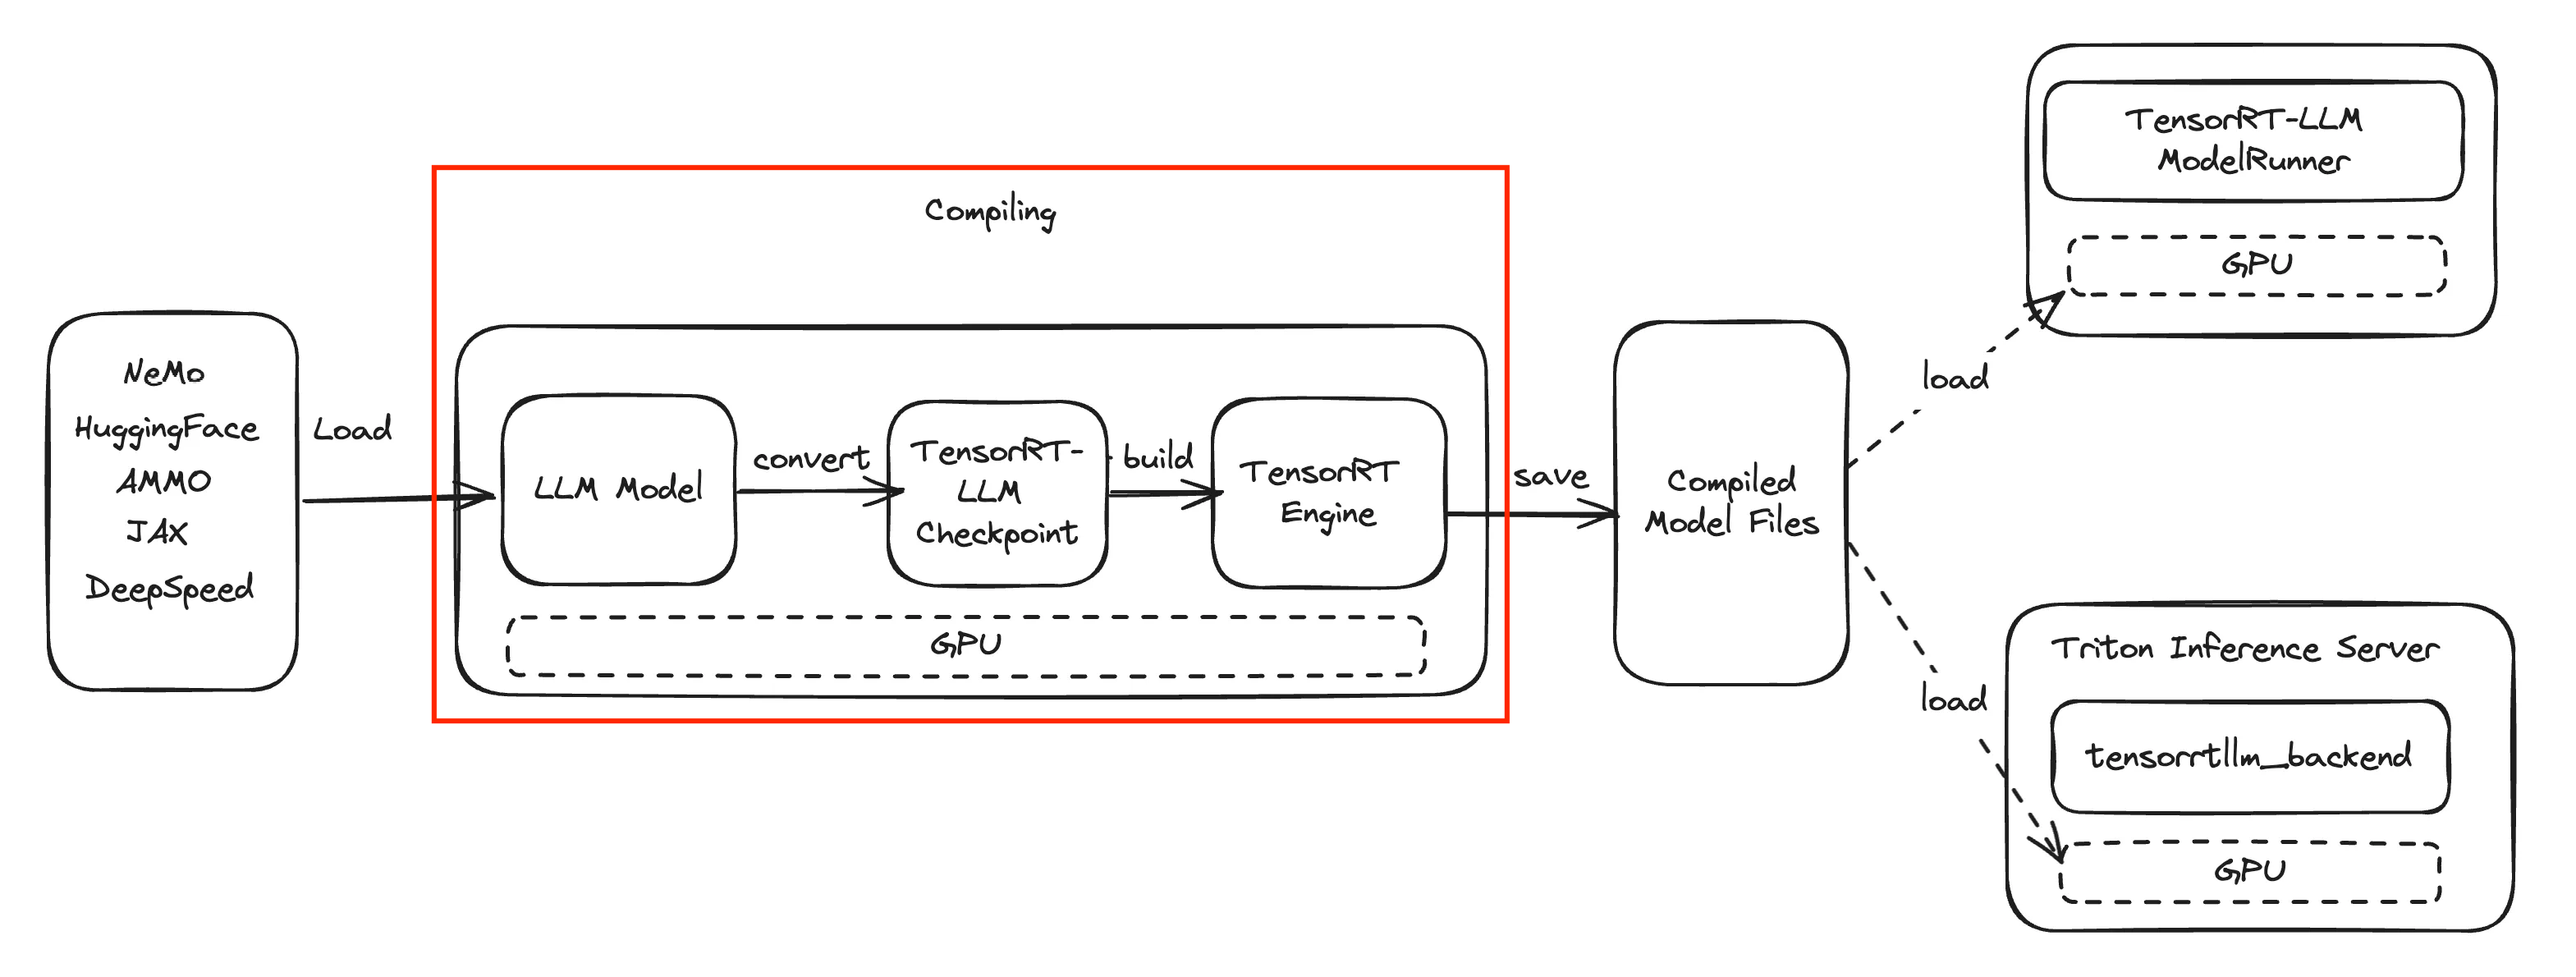
Compiling a LLM for High Performance Inference - Rafay Product ...
LLM Model Abstractions | nunchaku-ai/deepcompressor | DeepWiki
LLM Extractor (Preferred) - AIForged Documentation
Paper presentation on LLM compression | PPTX