
Pytorch Llm Compressor Docs

pytorch - LLM Compressor Docs

llmcompressor.pytorch - LLM Compressor Docs
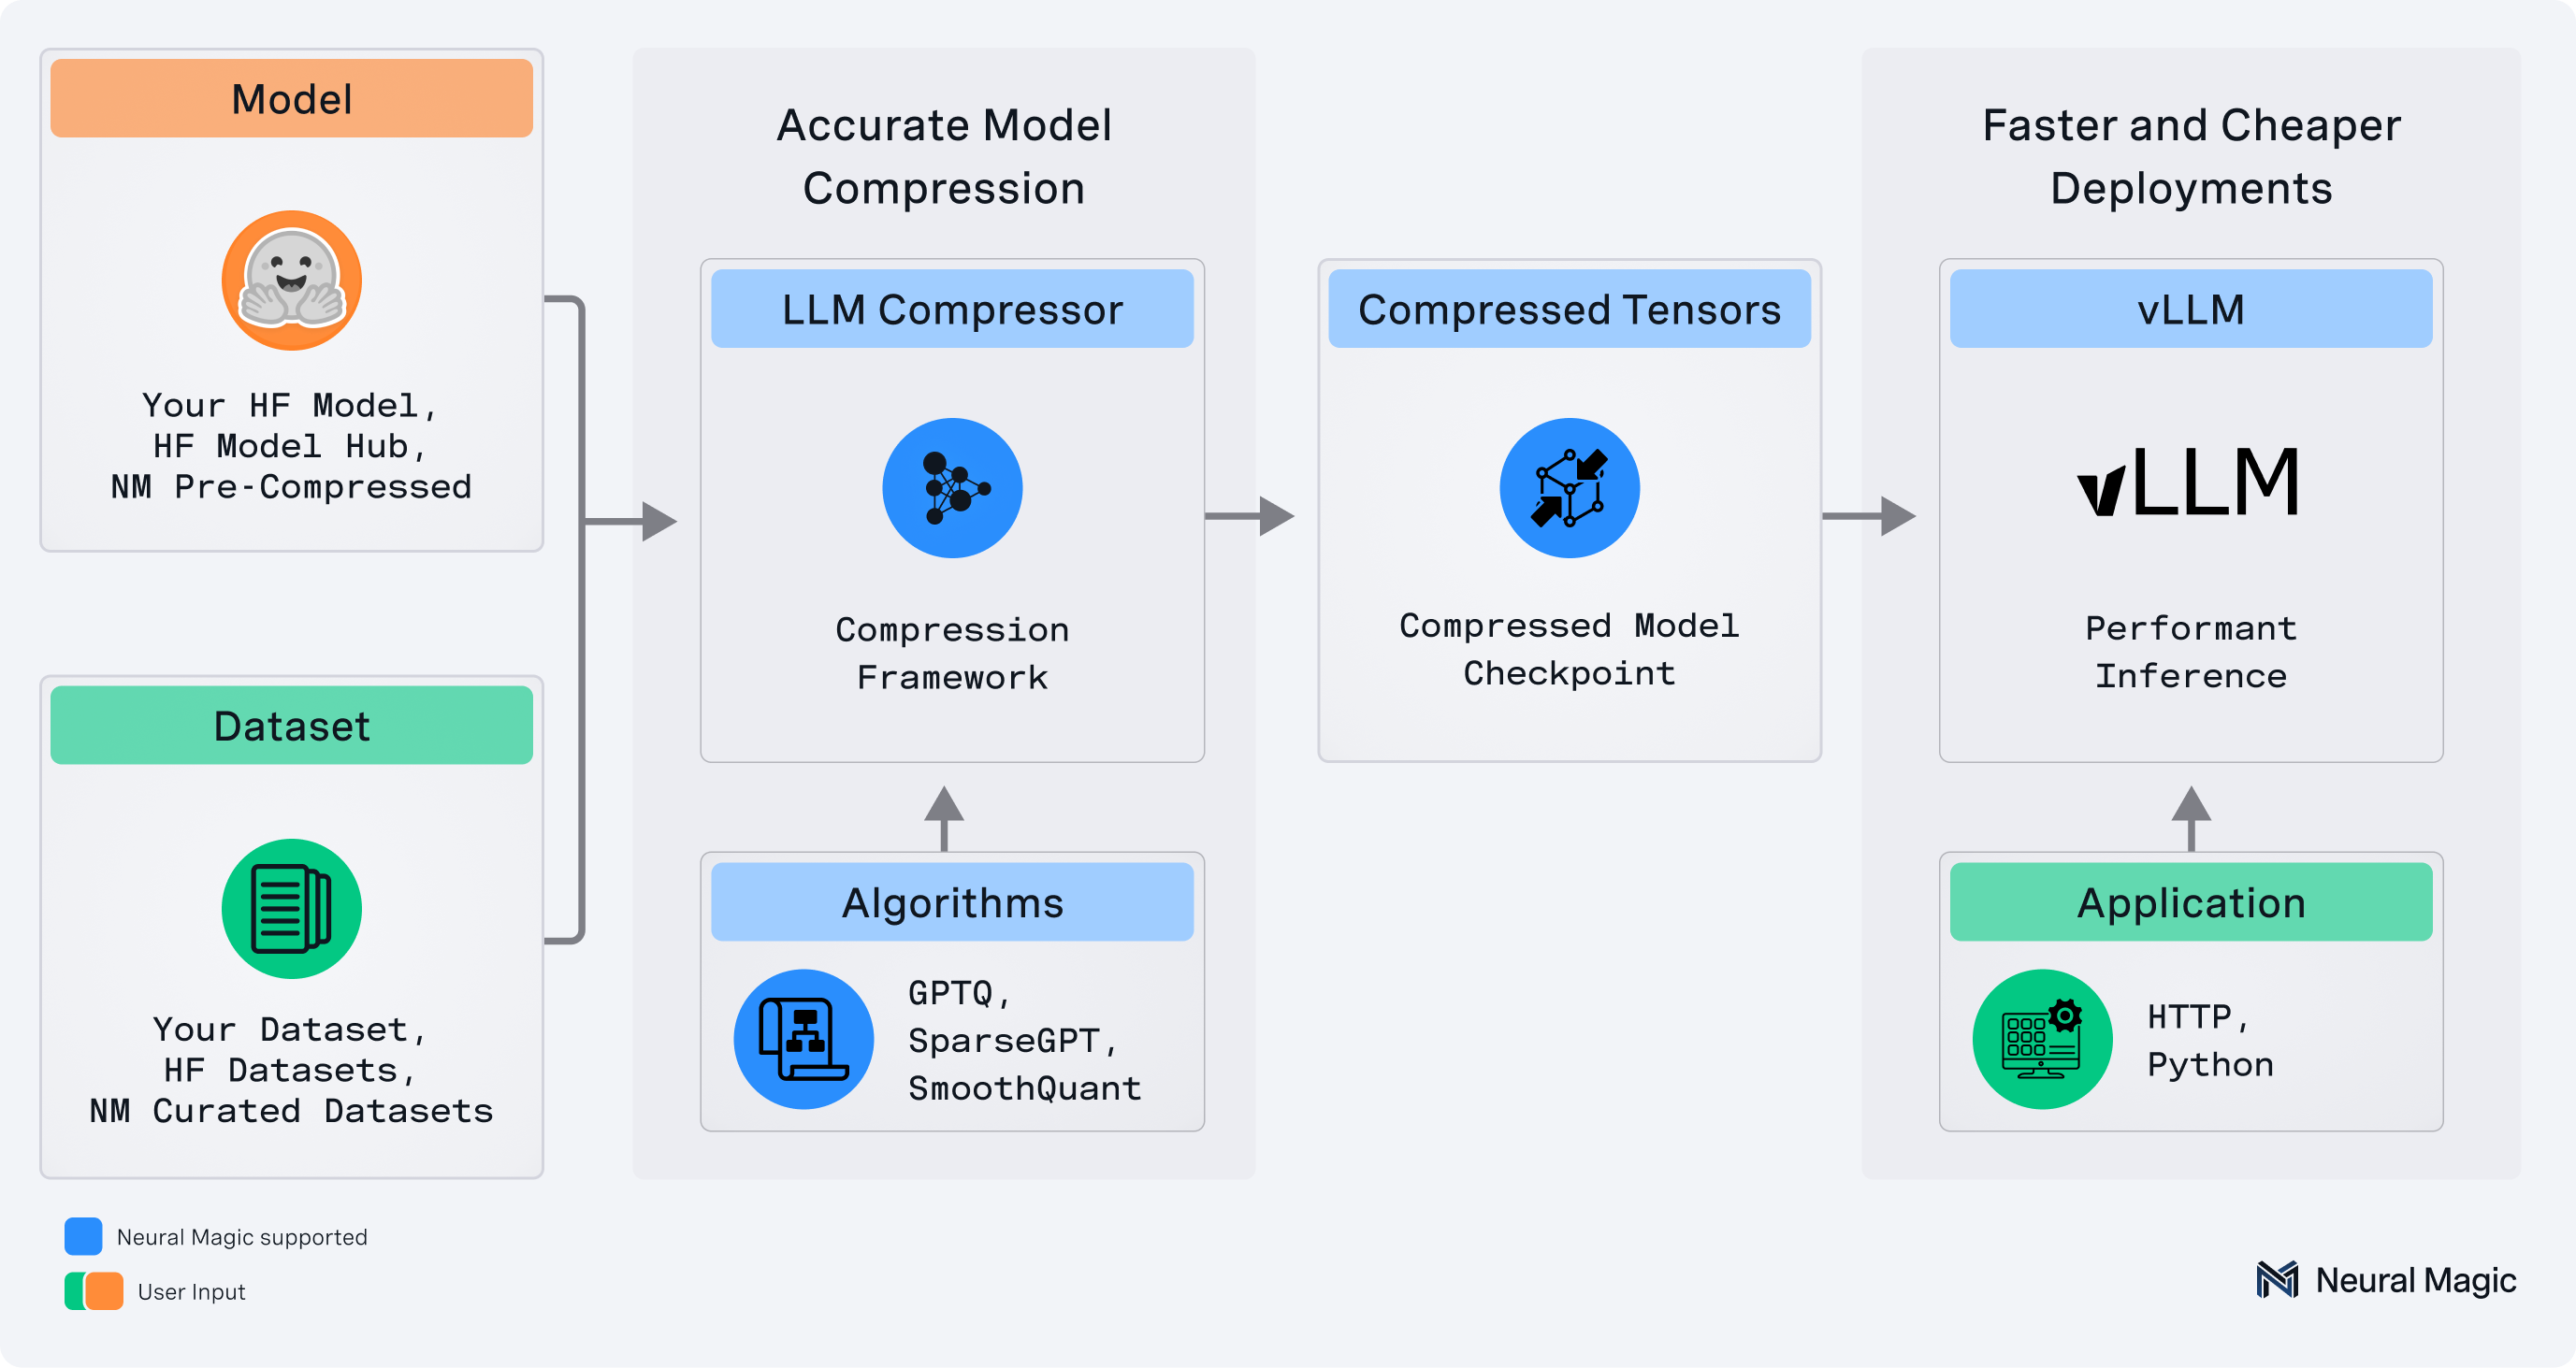
LLM Compressor Docs
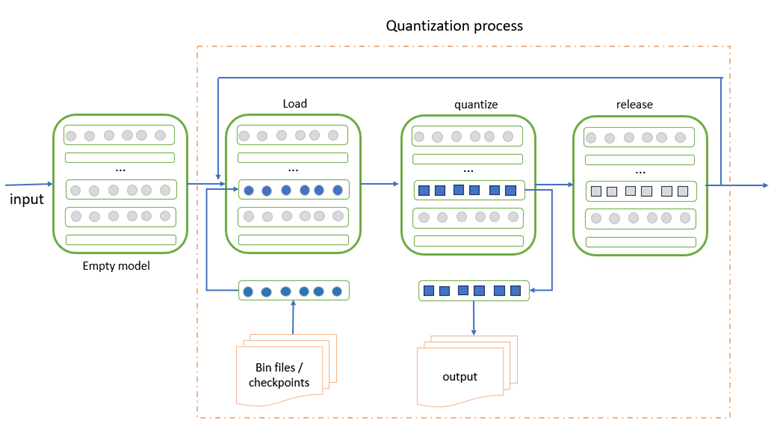
PyTorch Weight Only Quantization — Intel® Neural Compressor 3.0 ...
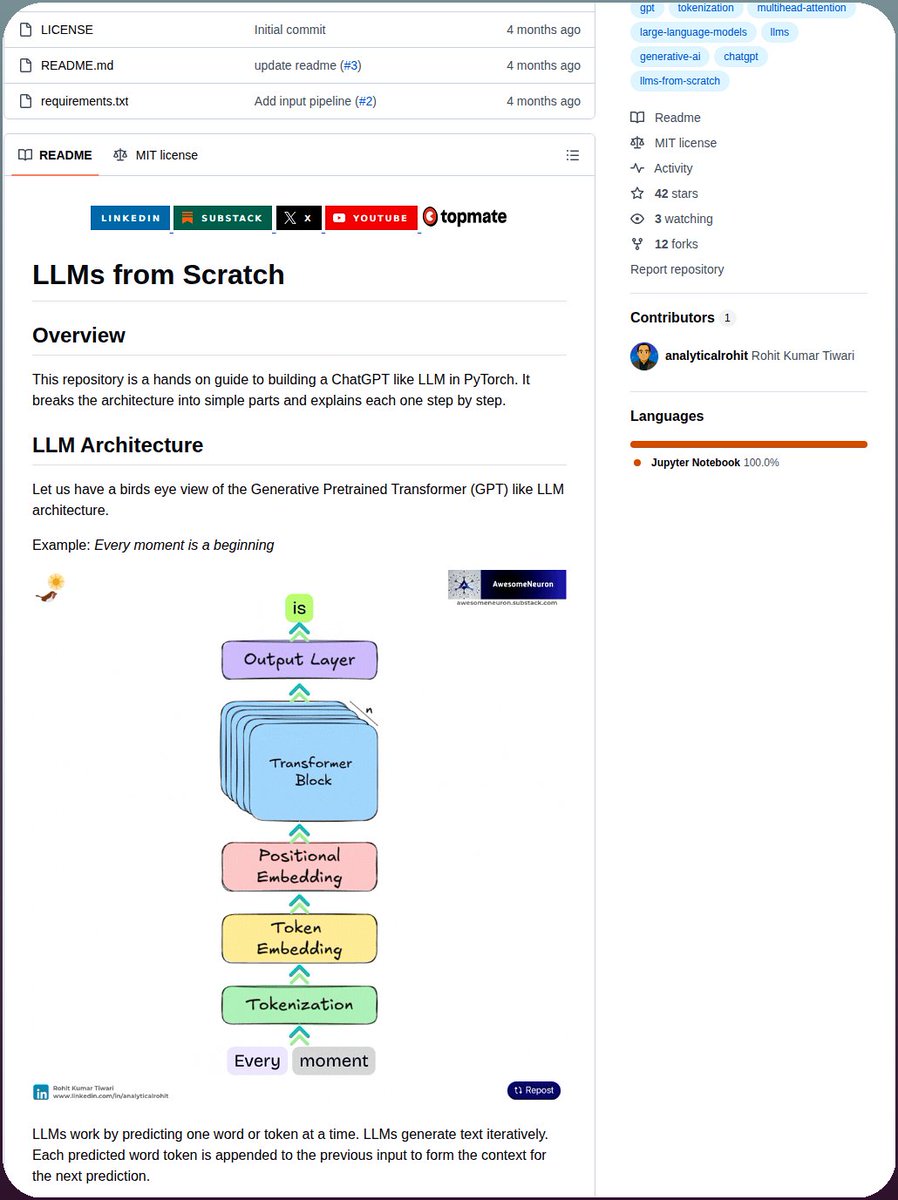
Builds GPT-like LLMs from scratch in PyTorch > Breaks the LLM ...
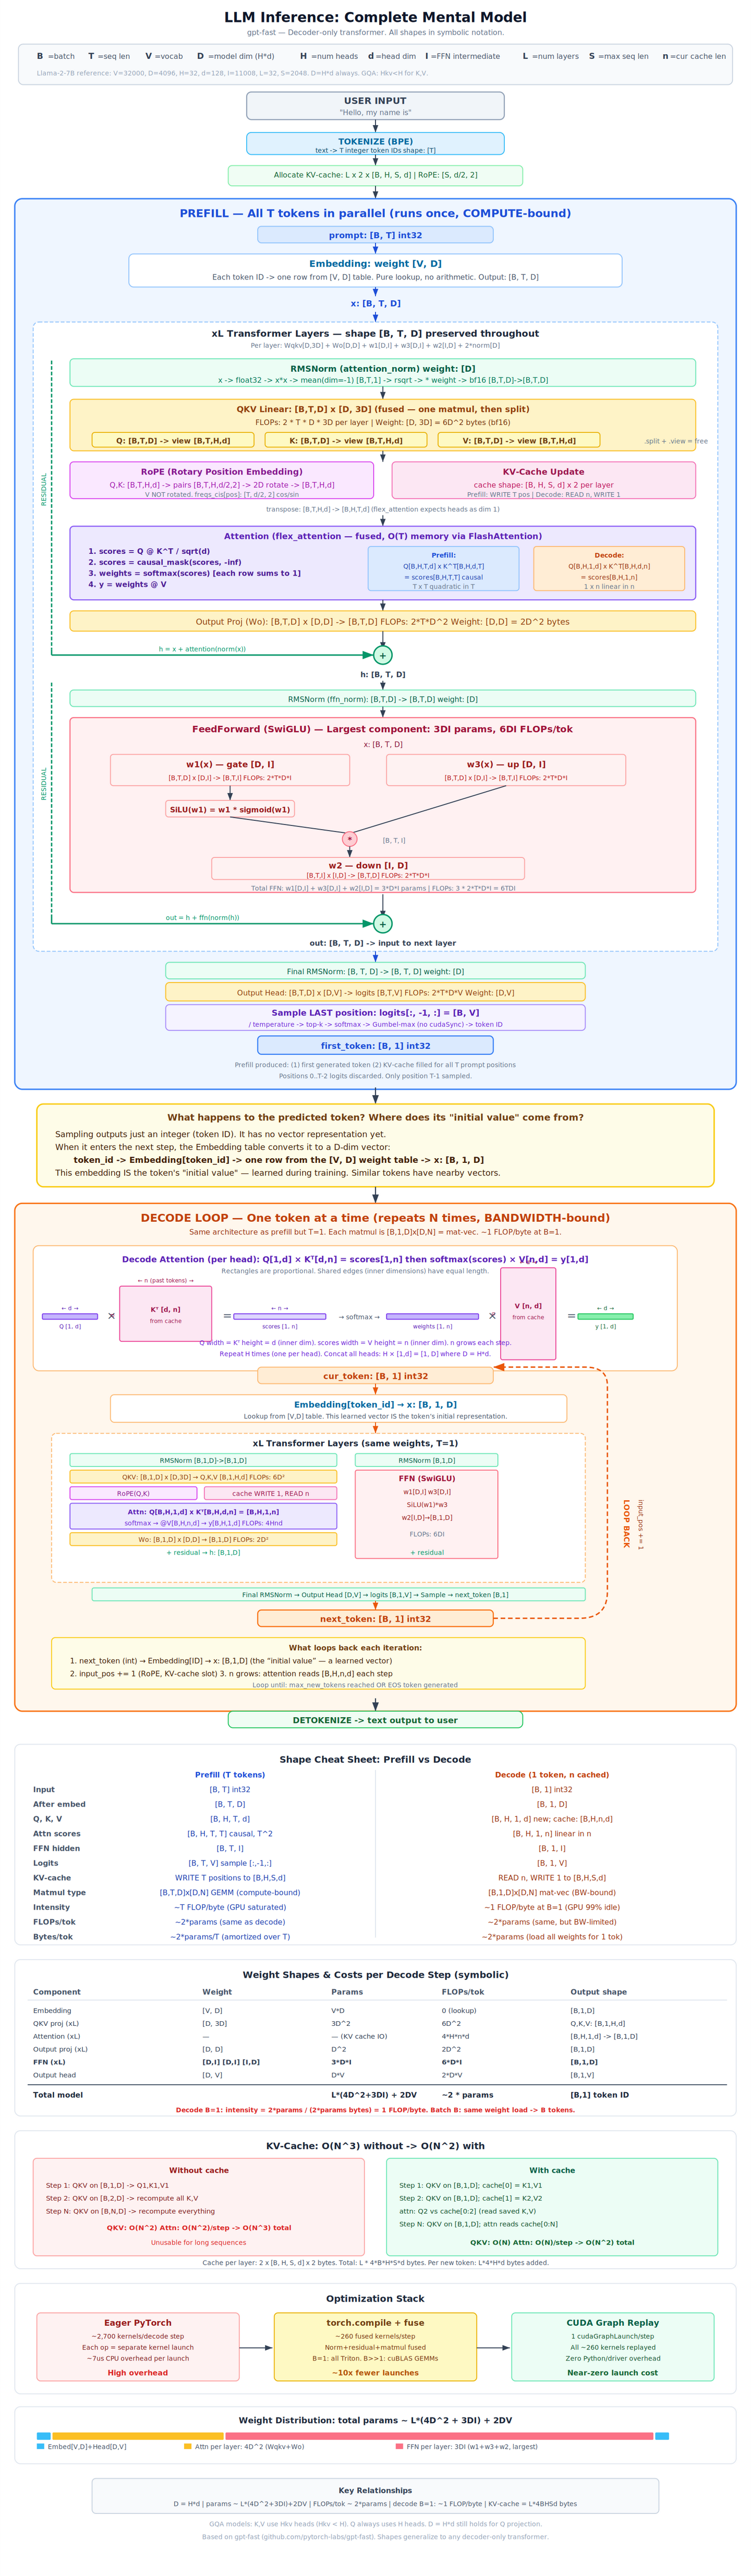
LLM Inference: PyTorch gpt-fast code walkthrough - 知乎

EP1 : LLM from scratch : Pytorch Essentials - YouTube

Excellent guide to using Pytorch for llm computes with accompanying ...
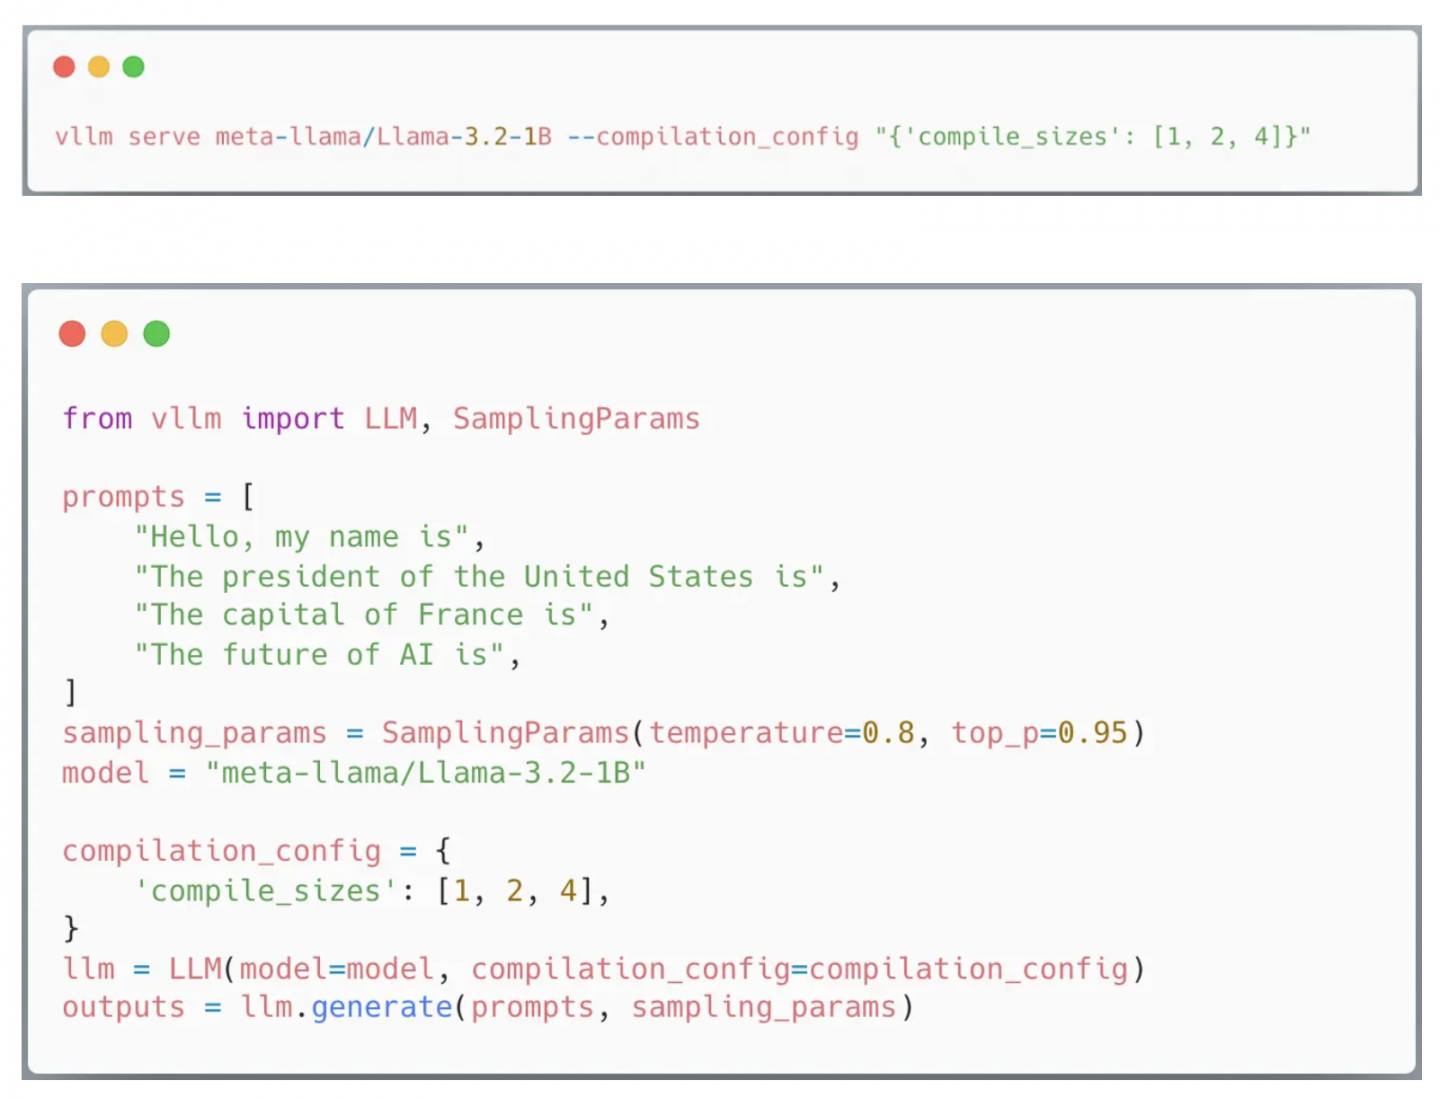
vLLM with torch.compile: Efficient LLM inference on PyTorch | Red Hat ...
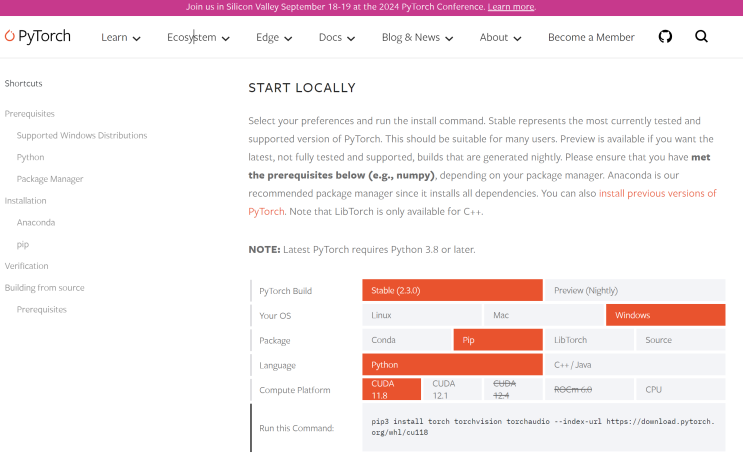
[알아봅시다] [Pytorch] Pytorch & LLM Training Pipeline (pytorch로 chatgpt만들기 ...
Advertisement Space (300x250)
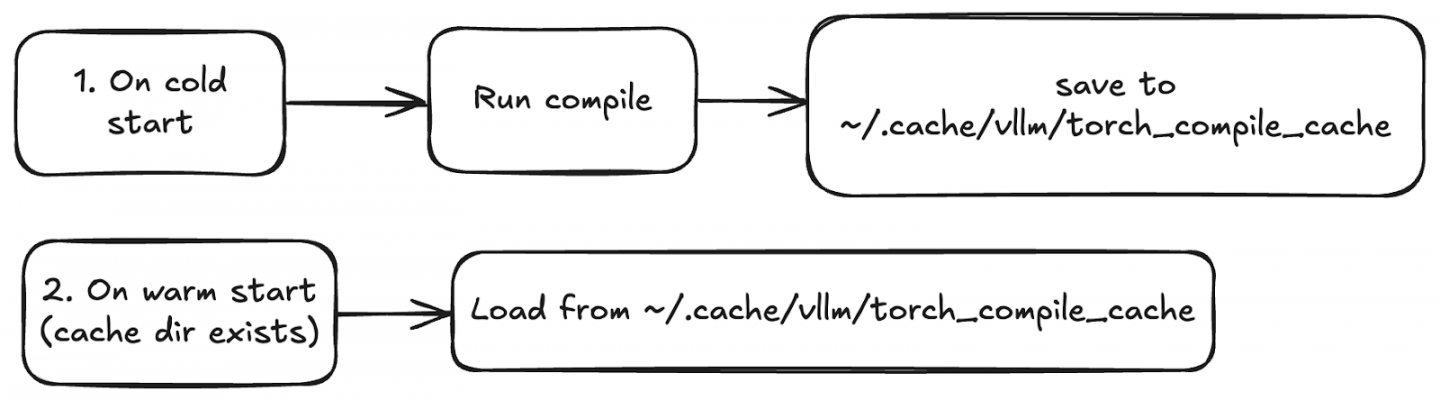
vLLM with torch.compile: Efficient LLM inference on PyTorch | Red Hat ...
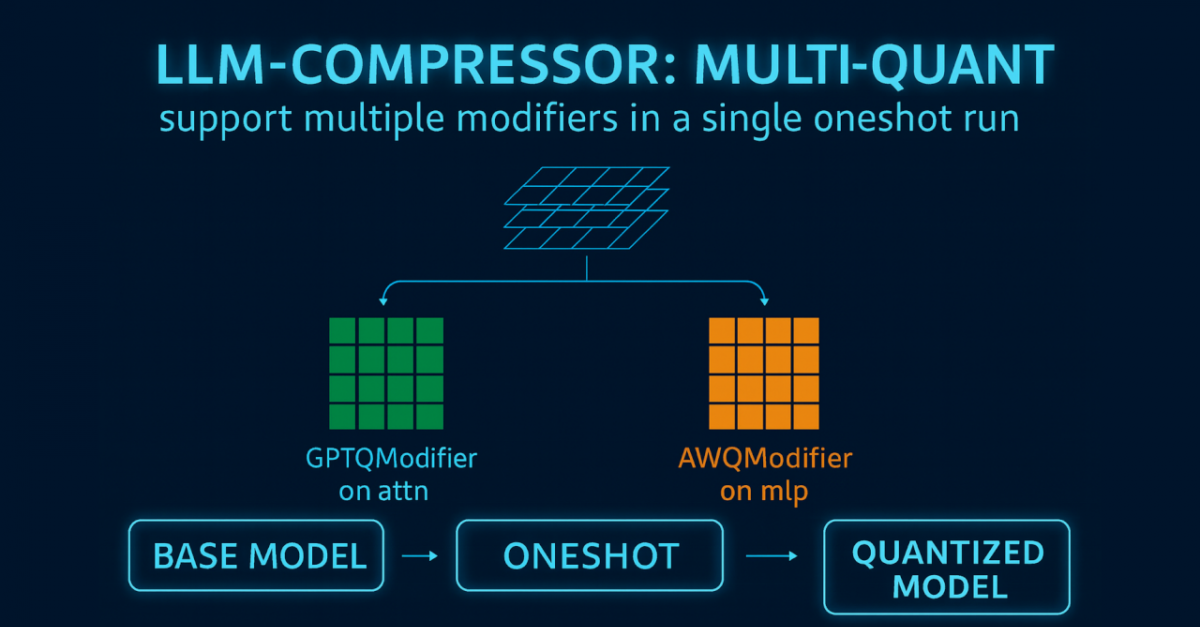
LLM Compressor 0.8.0: Extended support for Qwen3 and more | Red Hat ...

Great to see PyTorch extend into LLM fine-tuning and create more value ...
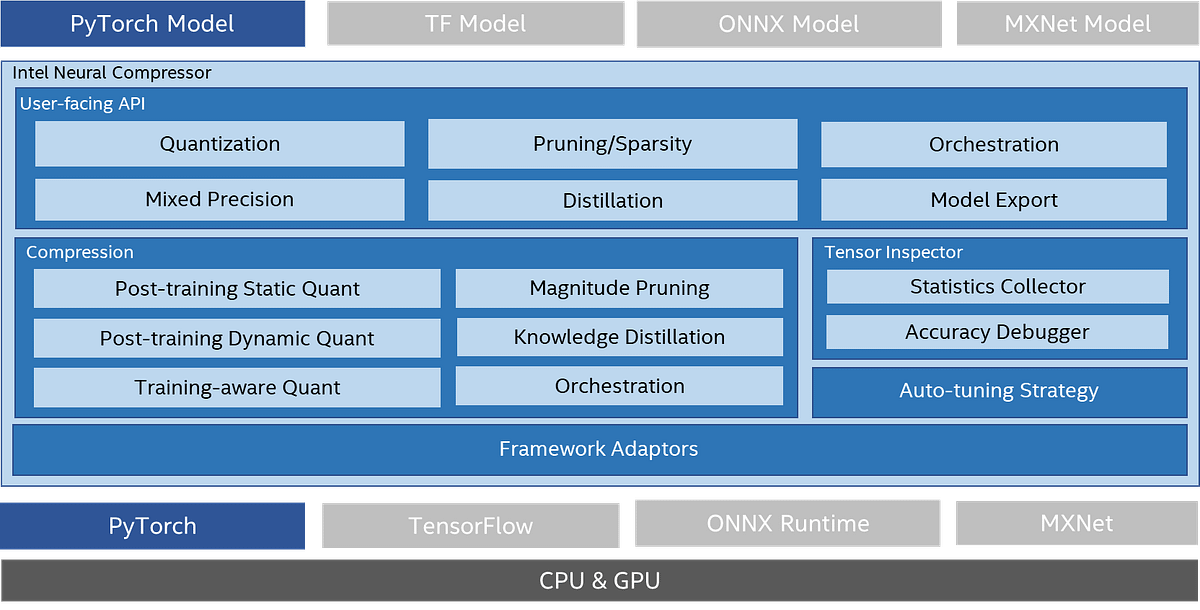
PyTorch Inference Acceleration with Intel® Neural Compressor | by Feng ...
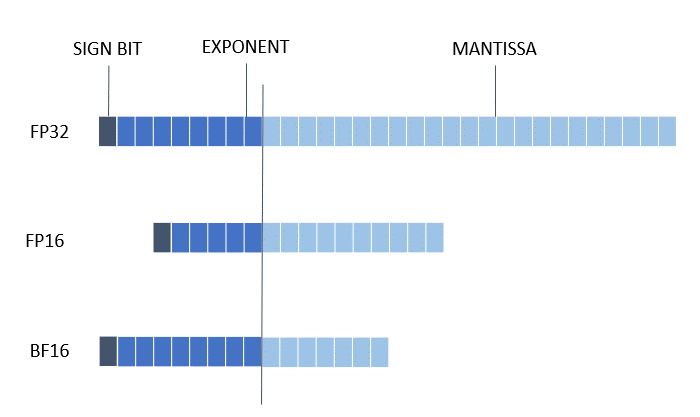
PyTorch Mixed Precision — Intel® Neural Compressor 3.1 documentation

How to accelerate LLM inference on Intel GPUs with PyTorch | PyTorch ...

Build MalayGPT: LLM with PyTorch | PDF | Computational Neuroscience ...
LLM Compressor v0.10: Faster compression with distributed GPTQ | Red ...

LLM Optimization and Deployment on SiFive RISC-V Intelligence Products
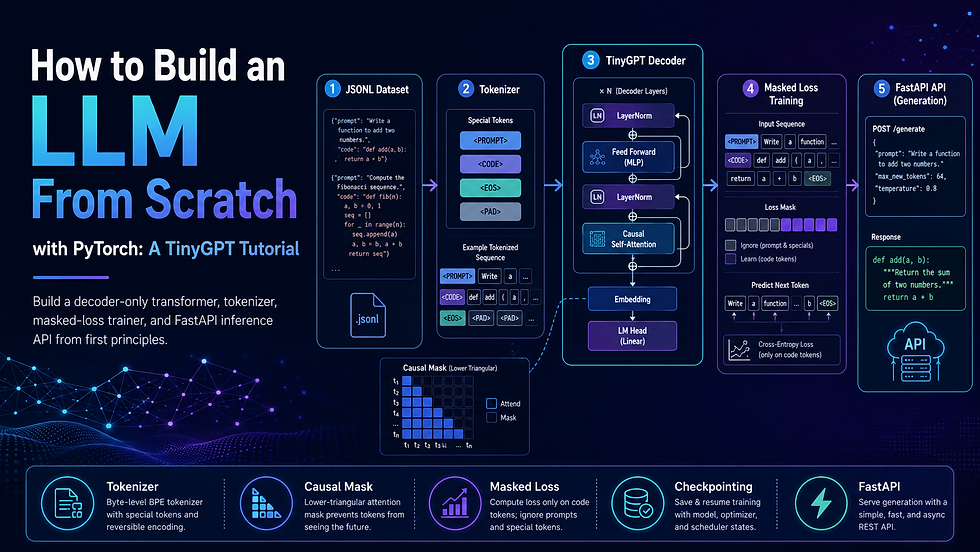
How to Build an LLM from Scratch with PyTorch: A TinyGPT Tutorial
Advertisement Space (336x280)
LLM Environments and Tools | pytorch/rl | DeepWiki

Build your own Large Language Model (LLM) From Scratch Using PyTorch ...
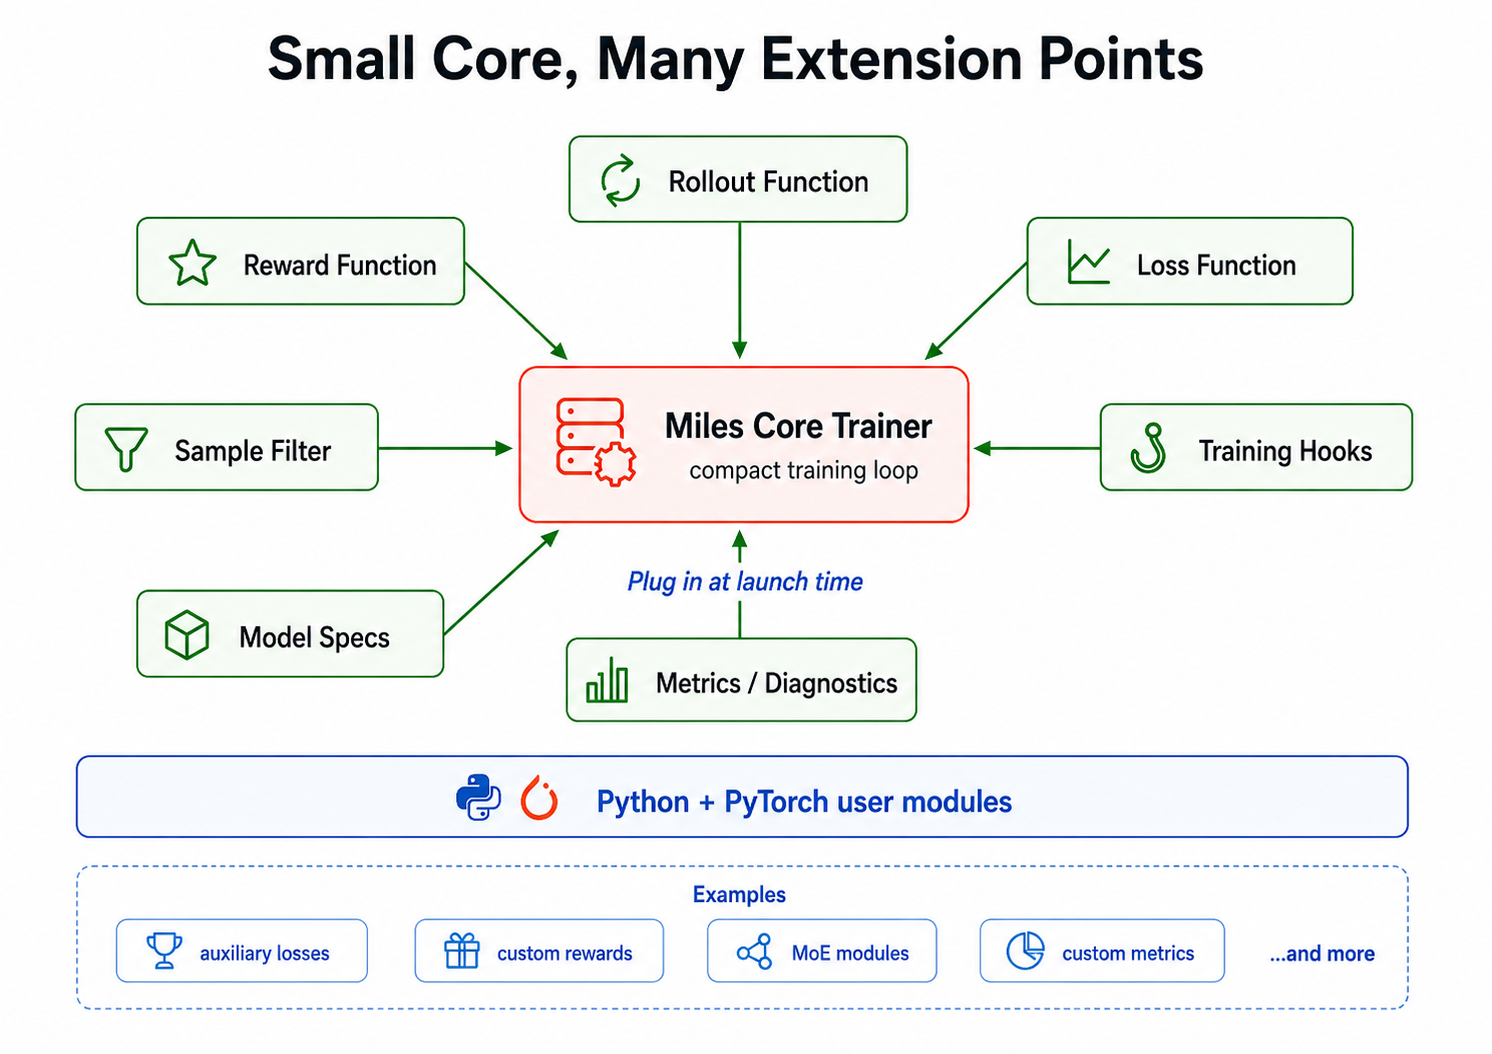
Miles: A PyTorch-Native Stack for Large-Scale LLM RL Post-Training ...

PyTorch LLM: Train, Fine-Tune, and Deploy Large Language Models for ...
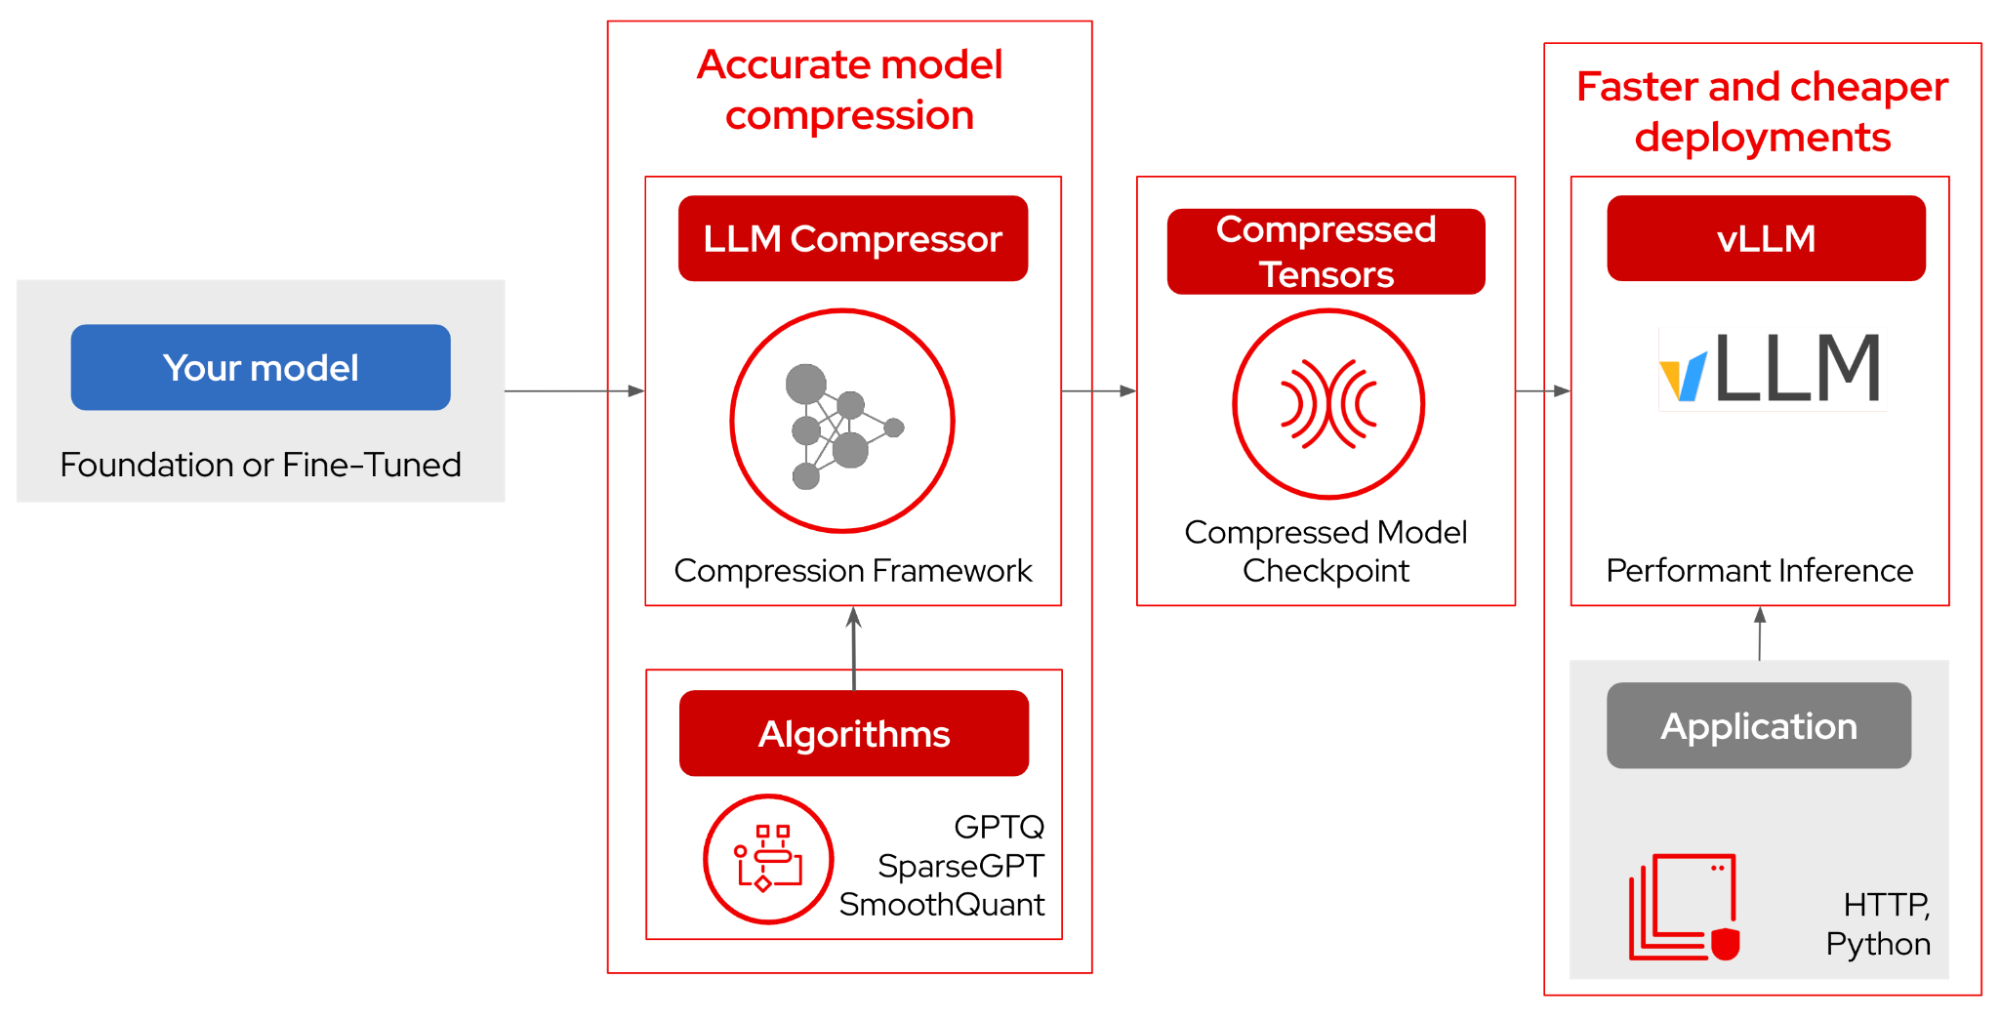
LLM compression and optimization: Cheaper inference with fewer hardware ...
verl: Flexible and Scalable Reinforcement Learning Library for LLM ...
Model Export and LLM Support | pytorch/executorch | DeepWiki
How to evaluate quantised model in Pytorch · Issue #1208 · intel/neural ...

High-performance quantized LLM inference on Intel CPUs with native ...
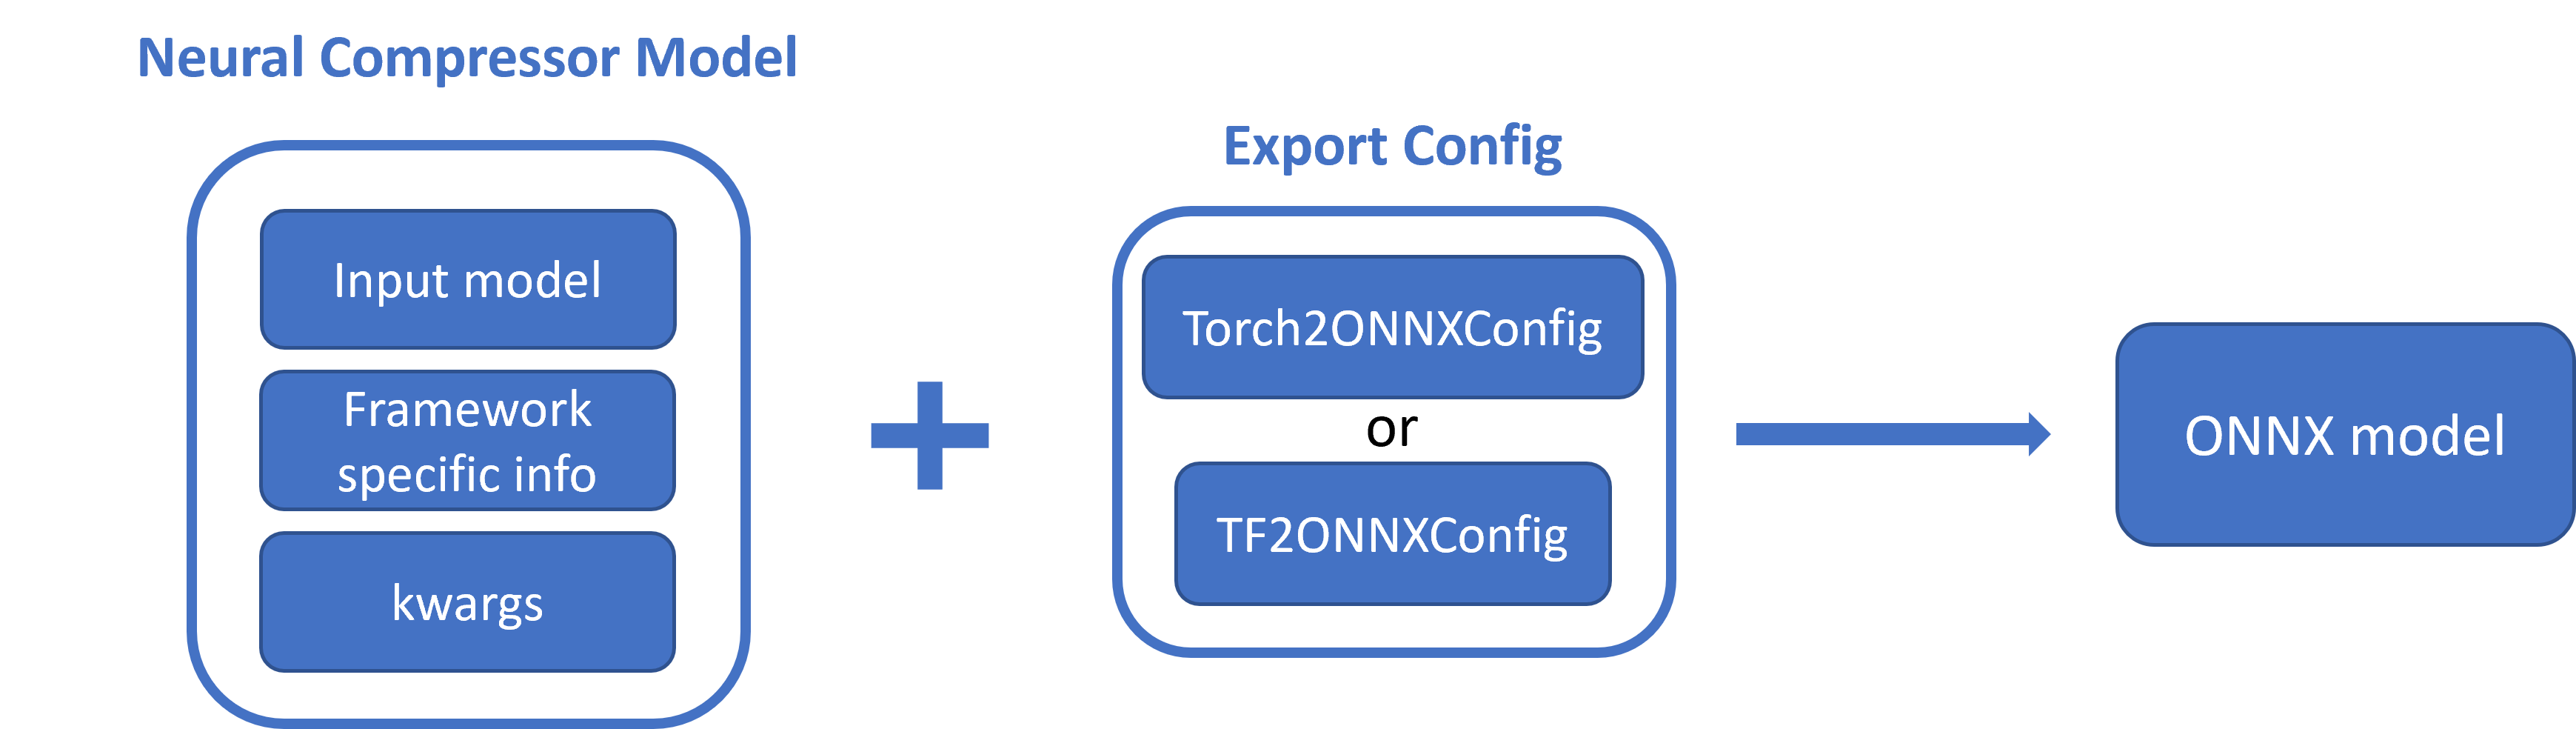
Export — Intel® Neural Compressor 3.2 documentation
Advertisement Space (336x280)
GitHub - intel/neural-compressor: SOTA low-bit LLM quantization (INT8 ...

GitHub - JianyangQin/S2TS-LLM: A pytorch implementation of S2TS-LLM ...
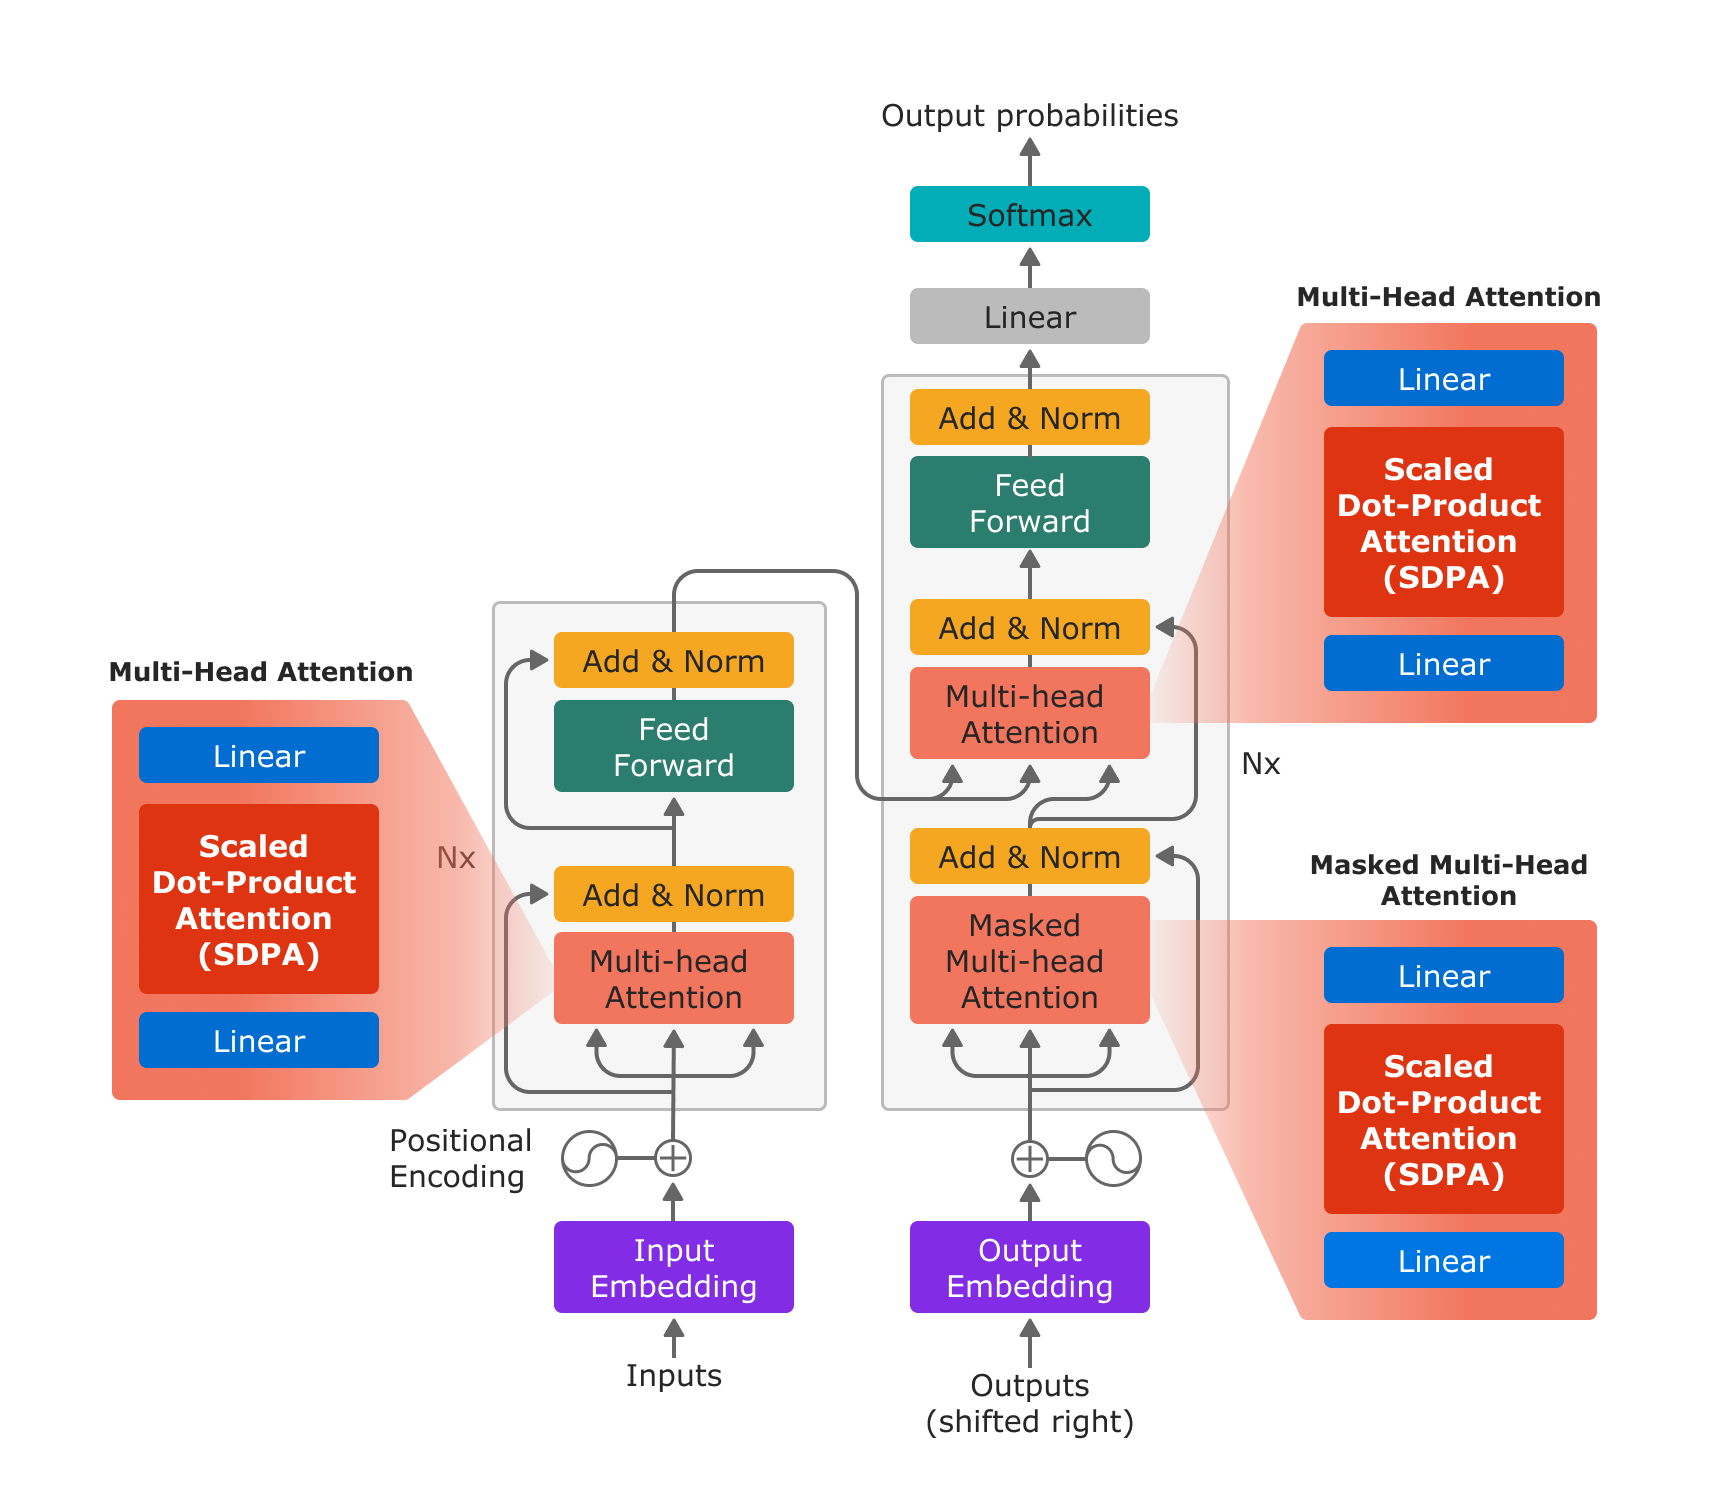
Accelerating Large Language Models with Accelerated Transformers – PyTorch
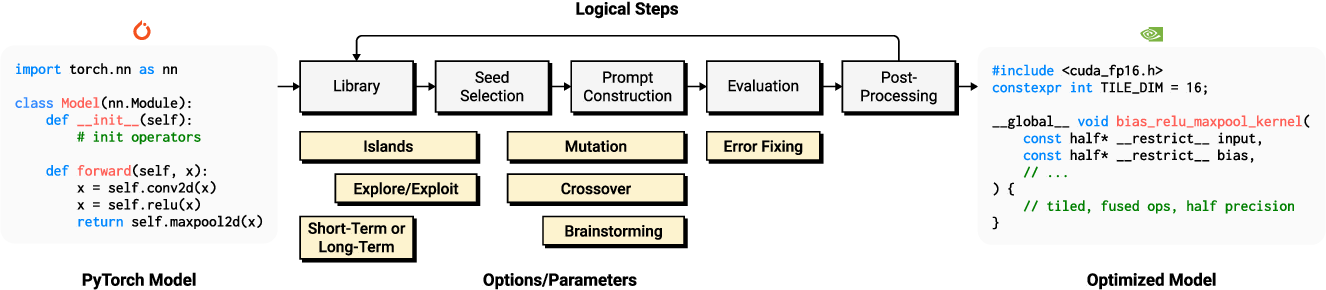
Figure 1 from Optimizing PyTorch Inference with LLM-Based Multi-Agent ...

Export — Intel® Neural Compressor 2.1 documentation
GitHub - syedabersabil/pytorch-llm-from-scratch: Complete PyTorch ...