
Llmops Quantization Models Inference Onnx Generative Runtime

LLMOps: Quantization models & Inference ONNX Generative Runtime # ...

Free Video: LLMOps: Quantization Models and Inference with ONNX ...

Python Quantization-Aware Inference with ONNX Runtime | by Nikulsinh ...

Free Video: LLMOPs - Inference in CPU with Phi3 4k Instruct ONNX 4-bit ...

Accelerate NLP inference with ONNX Runtime on AWS Graviton processors ...
GitHub - leimao/ONNX-Runtime-Inference: ONNX Runtime Inference C++ Example
Deploy AI/ML Inference Pipeline with ONNX Runtime and FastAPI on Rocky ...

Accelerate NLP inference with ONNX Runtime on AWS Graviton processors ...

Inference Optimization with ONNX Runtime - YouTube

Accelerate NLP inference with ONNX Runtime on AWS Graviton processors ...
Advertisement Space (300x250)

Accelerate NLP inference with ONNX Runtime on AWS Graviton processors ...
ONNX Runtime inference extensions (Wenbing Li) - YouTube
How to inference image segmentation application on ONNX runtime using ...
Where are the live inference results stored in Onnx runtime model for ...

LLMOPs: Inference in CPU Phi3 4k Intruct ONNX 4bits in C# #datascience ...

Quantize ONNX models | onnxruntime

LLMOPs: Inference in CPU Model Microsoft Florence2 ONNX in C# # ...
LLMOPs: Inference en CPU Phi3 Vision 128k Intruct ONNX 4bits in C# # ...

LLMOps: Convertir Fine Tuned ViT classifier a ONNX e inference en CPU # ...
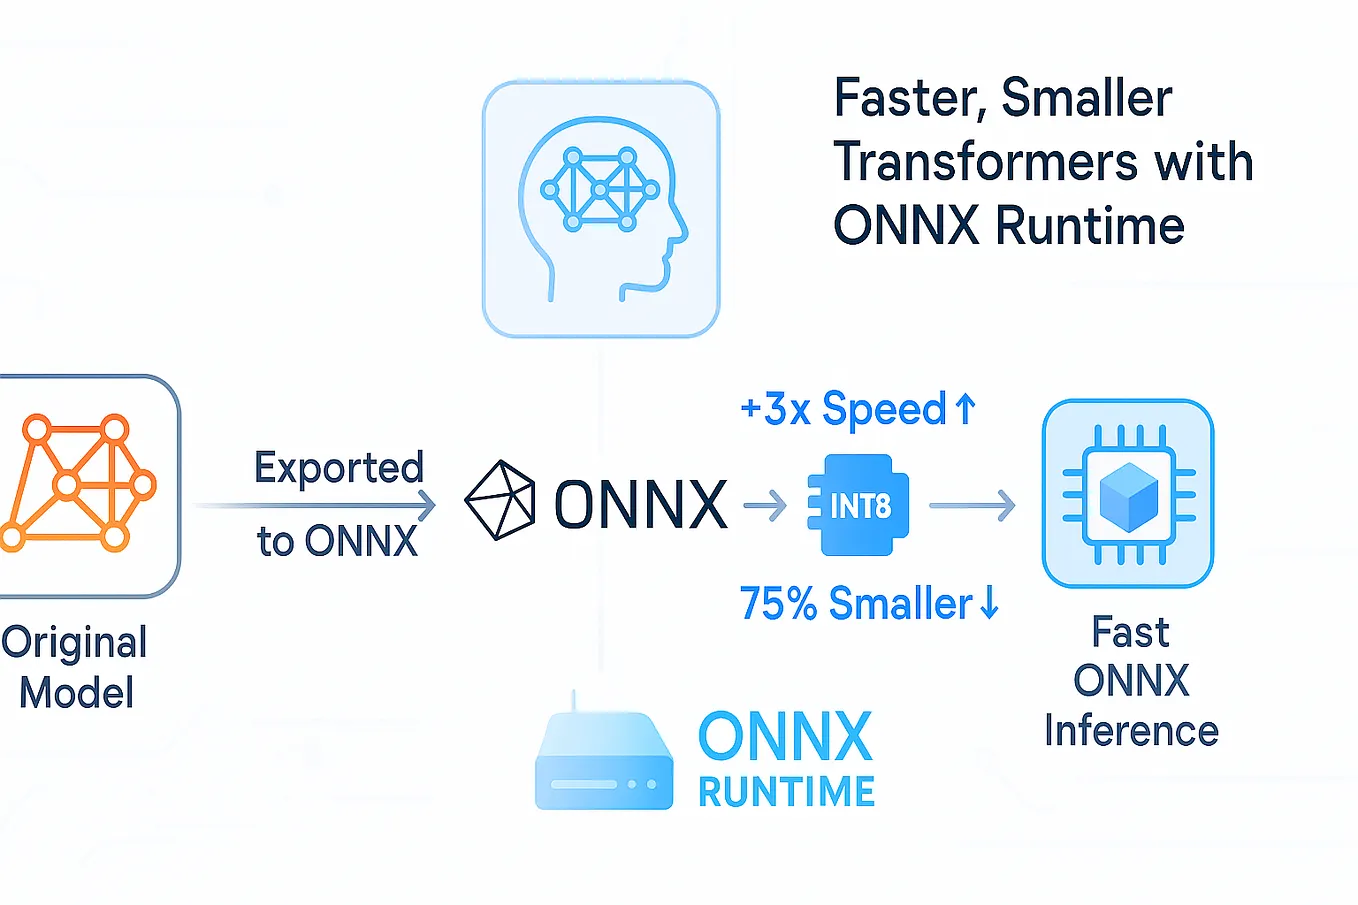
The Beginner’s Guide: CPU Inference Optimization with ONNX (99.8% TF ...
Advertisement Space (336x280)

Free Video: LLMOPs: Inference in CPU with Microsoft Florence 2 ONNX ...
Deploying Quantized LLMs with ONNX Runtime
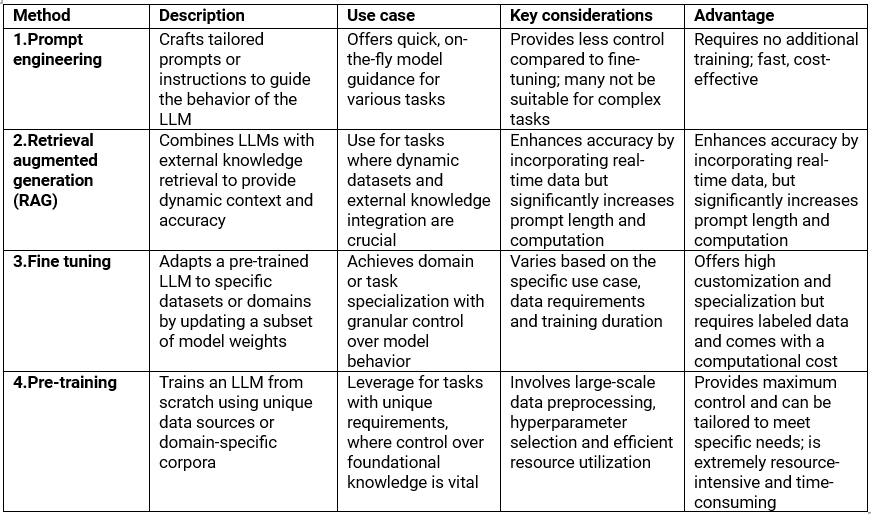
The LLMOps Guide to Generative AI Success: From Concept to Deployment ...
ONNX Model Quantization | NVIDIA/Model-Optimizer | DeepWiki
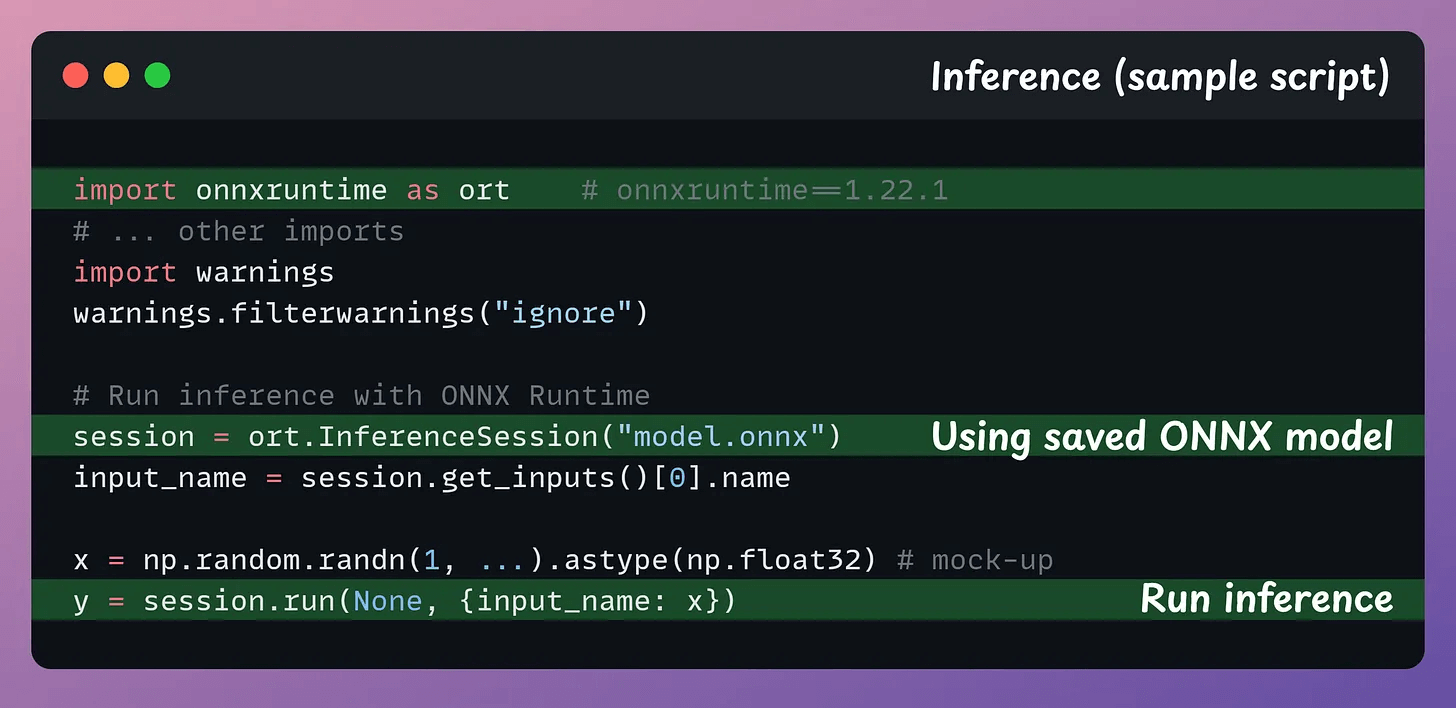
Build Portable ML Models with ONNX - by Avi Chawla

LLMOps: OpenVino Toolkit quantization 4int LLama3.2 3B, Inference CPU # ...
How to save inference onnx model? · Issue #14185 · microsoft ...
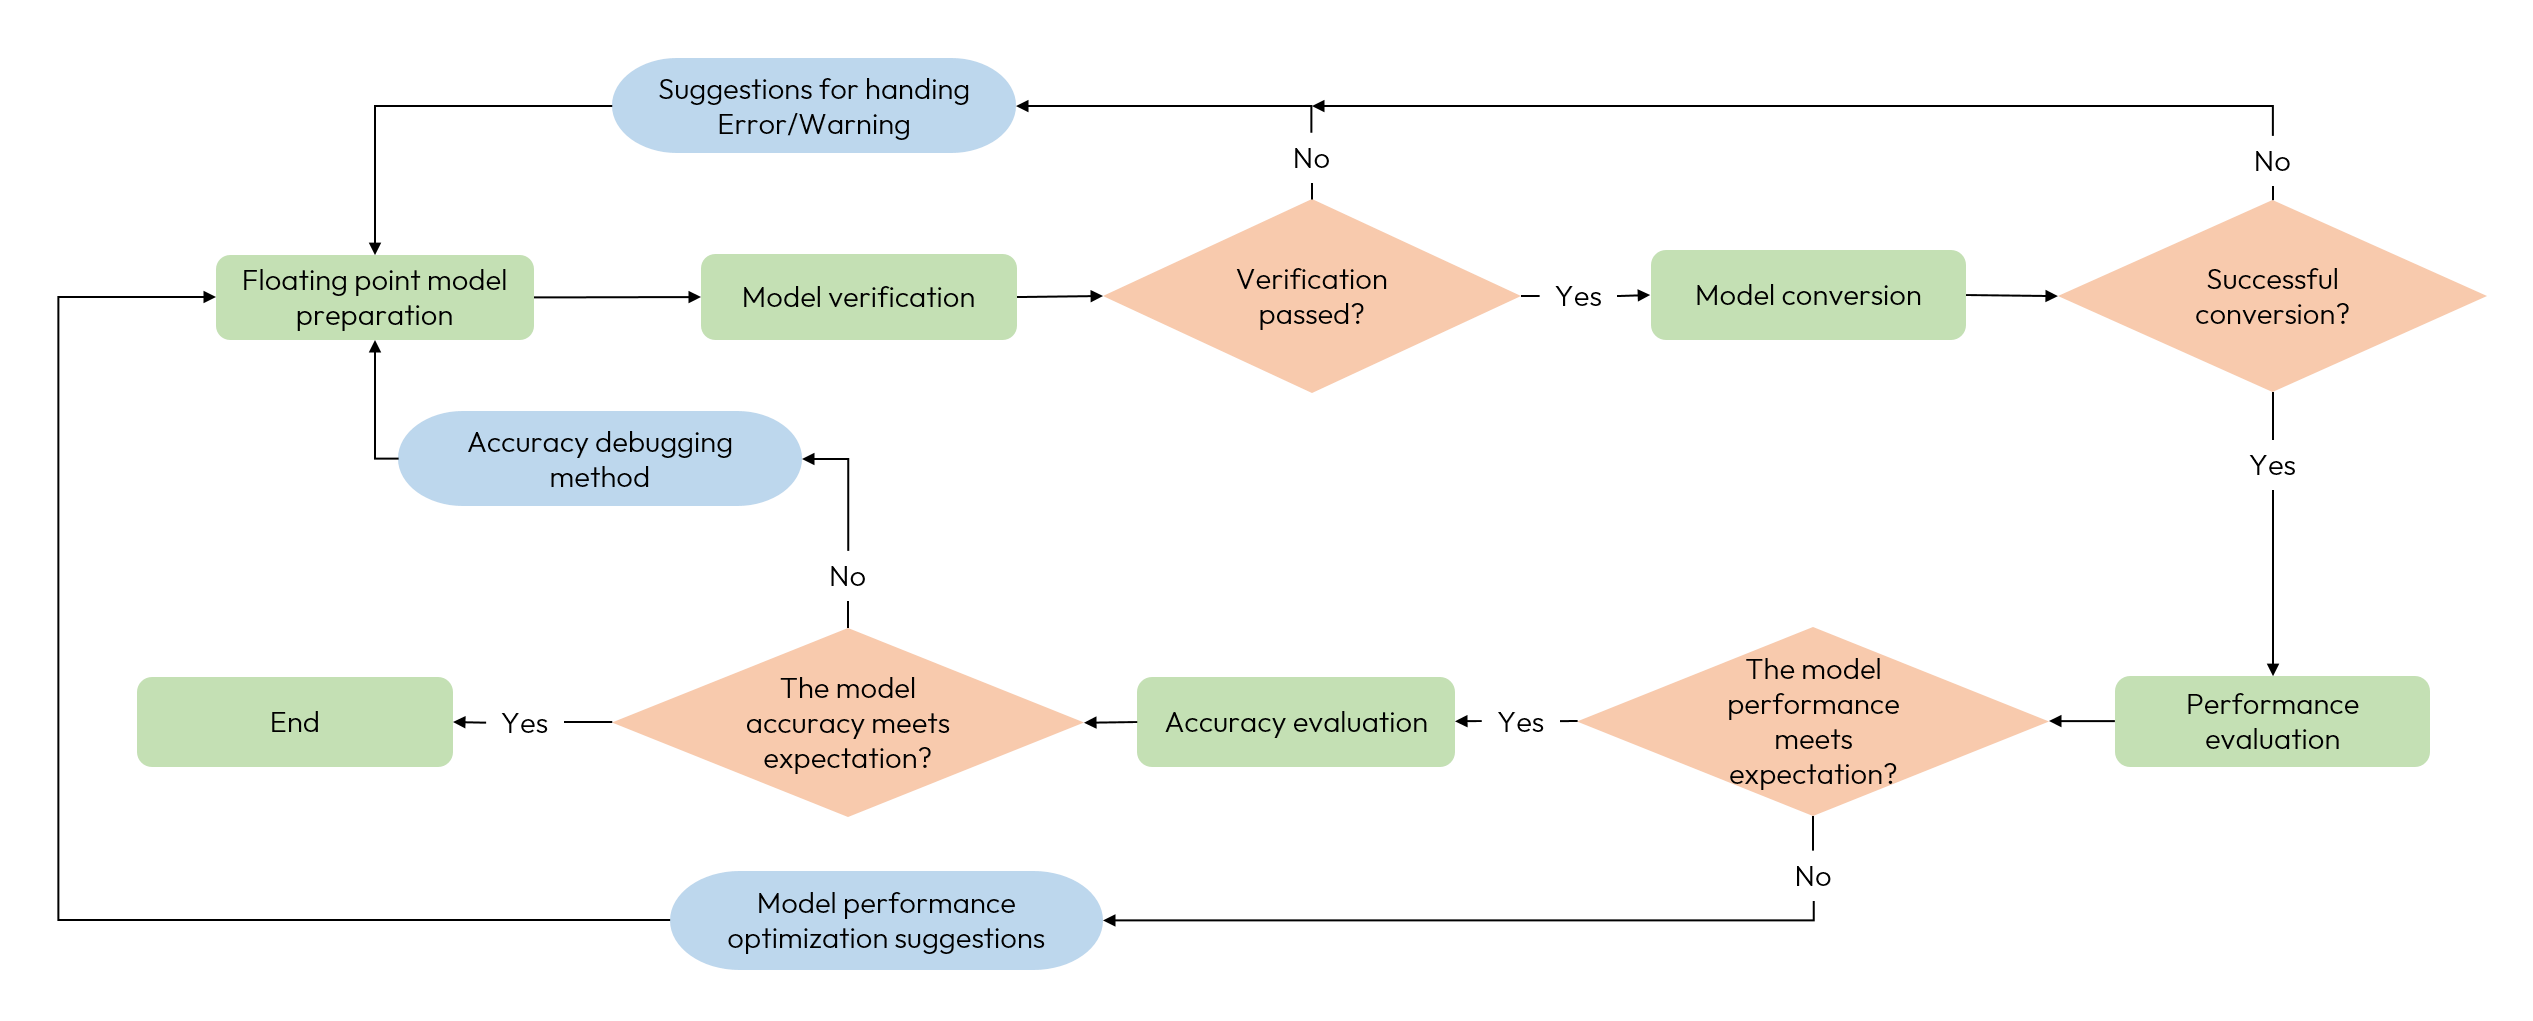
ONNX Model Quantization Principle and Process - Horizon OpenExplorer ...

Your questions answered: How to succeed in generative AI using LLMOps ...

How to save inference onnx model? · Issue #14185 · microsoft ...
Advertisement Space (336x280)

How to save inference onnx model? · Issue #14185 · microsoft ...

How to save inference onnx model? · Issue #14185 · microsoft ...
Quantization Onnx - AssertionError · Issue #377 · microsoft/onnxruntime ...
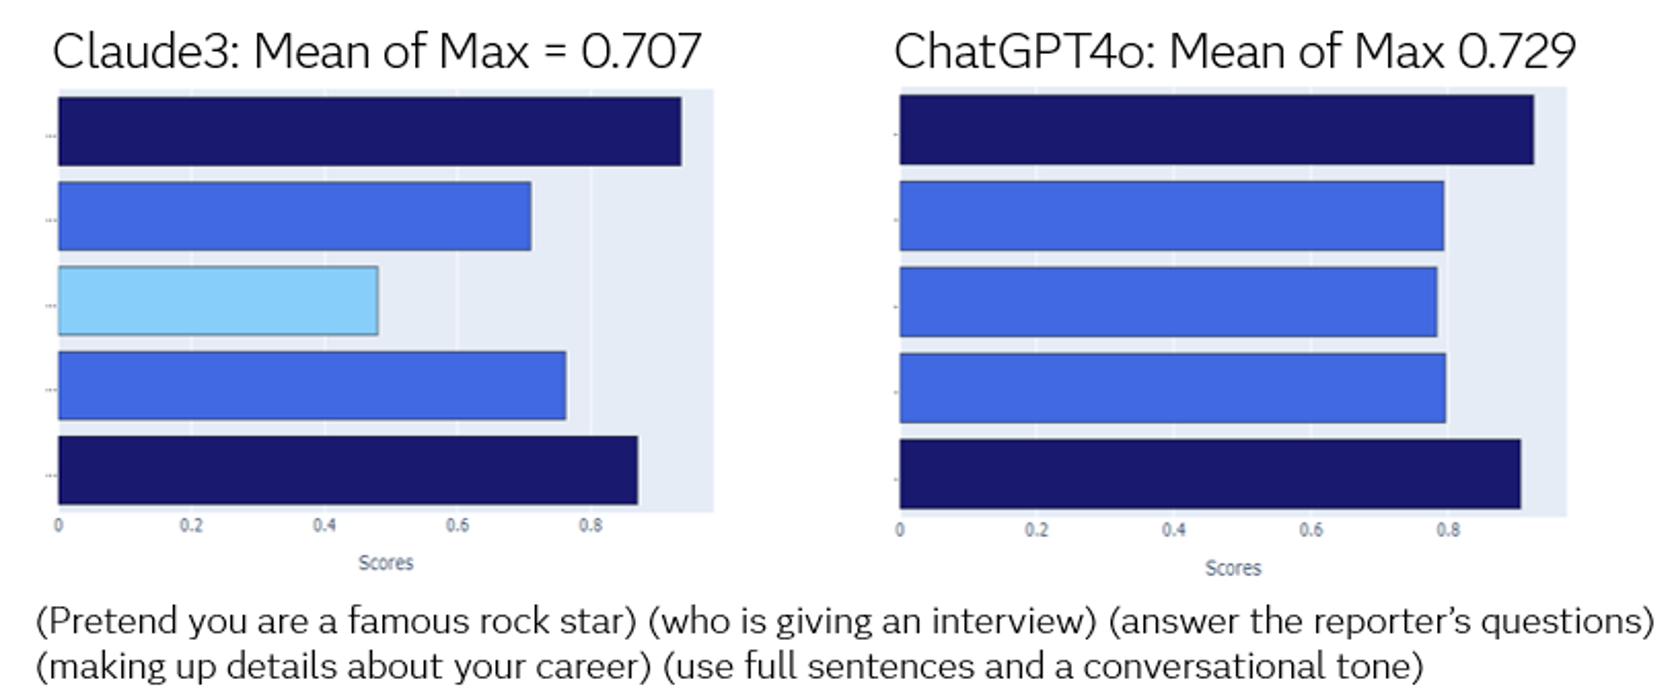
Your questions answered: How to succeed in generative AI using LLMOps ...
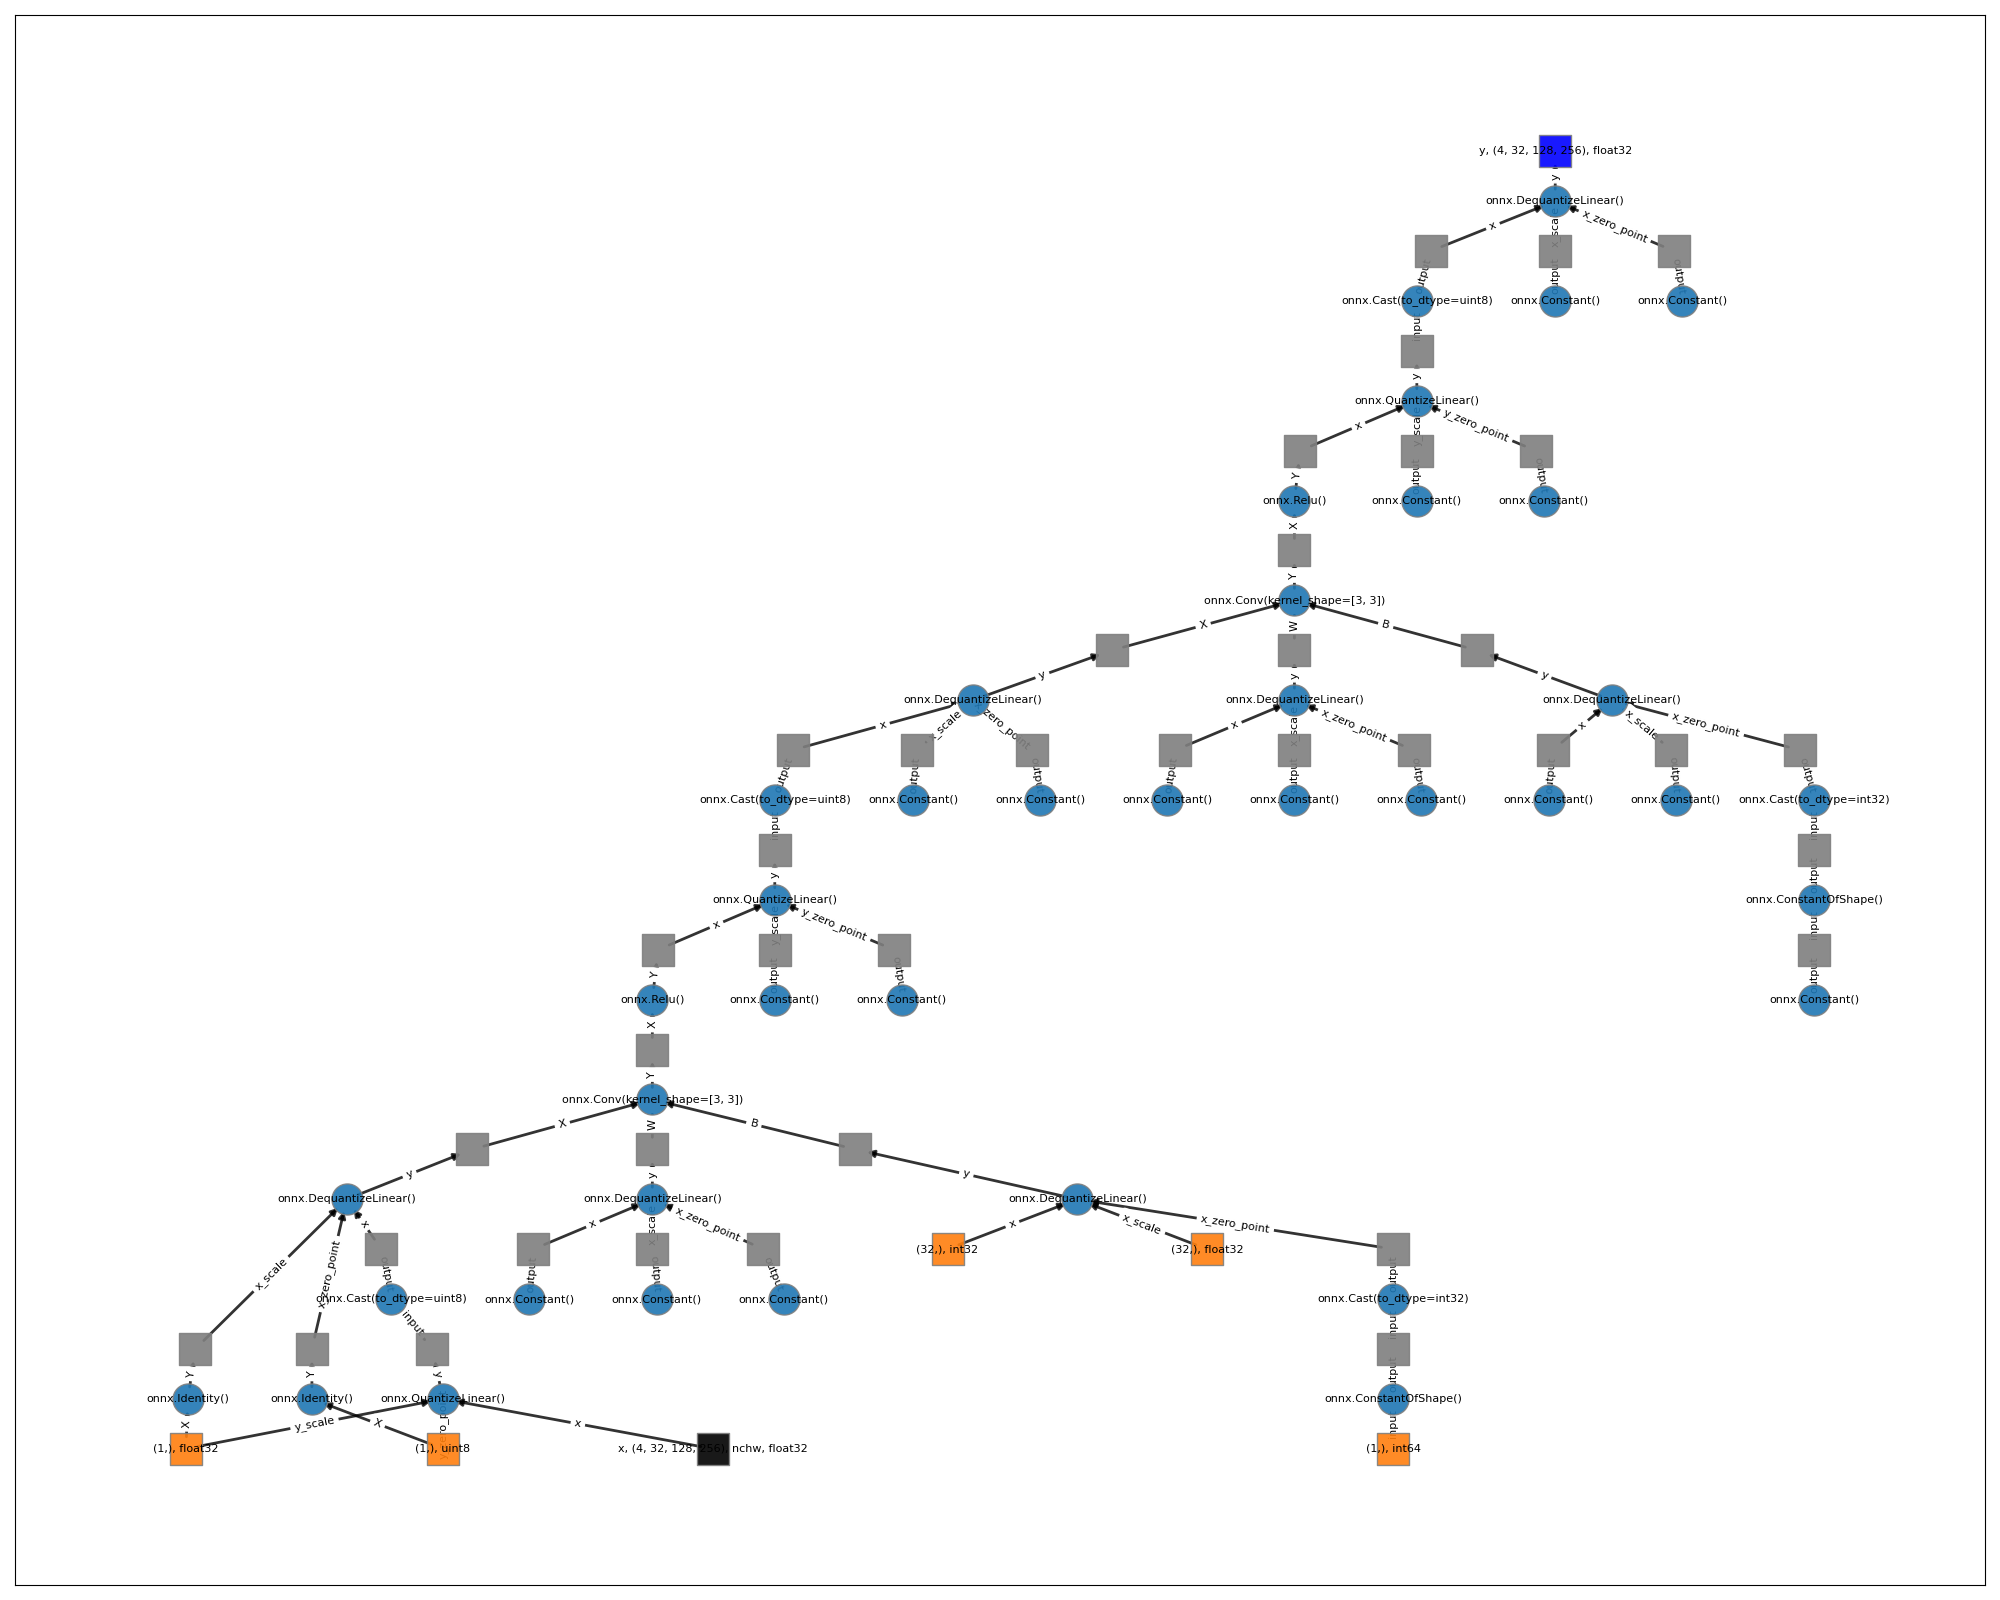
ONNX export of simple quantized model fails - quantization - PyTorch Forums

Optimizing Inference on Large Language Models with NVIDIA TensorRT-LLM ...