
Llms Weight Quantization Explained Youtube

LLM's Weight Quantization Explained - YouTube

LLM Quantization Explained - YouTube
How to Achieve Extreme Low-bit Quantization for LLMs - YouTube

LLMs Quantization Crash Course for Beginners - YouTube

Understanding Model Quantization and Distillation in LLMs - YouTube

Does Quantization Make LLMs Dumb? - YouTube

EfficientQAT - New LLMs Quantization Algorithm - YouTube

LLM Marathon series : Quantization in LLMs: Future in LLMs - YouTube

Simple quantization of LLMs - a hands-on - YouTube

QuIP: 2-Bit Quantization for LLMs - YouTube
Advertisement Space (300x250)

Quantization Explained: The Secret Behind Fast and Efficient LLMs - YouTube
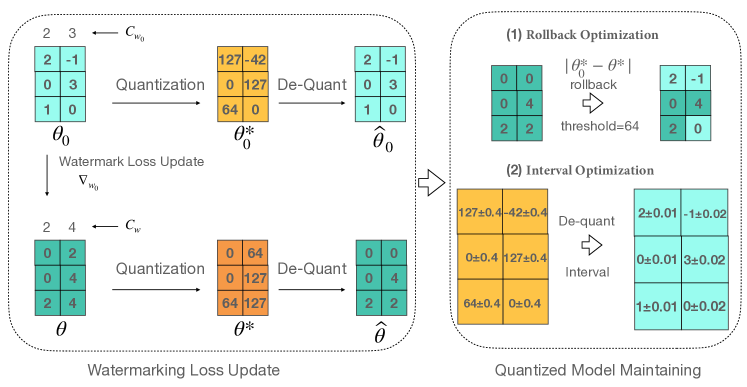
[2310.11237] Watermarking LLMs with Weight Quantization

GGUF quantization of LLMs with llama cpp - YouTube

NVIDIA GPU Quantization Support for LLMs - YouTube

AI-Powered Insights: Quantization | Making LLMs Lighter & Faster - YouTube
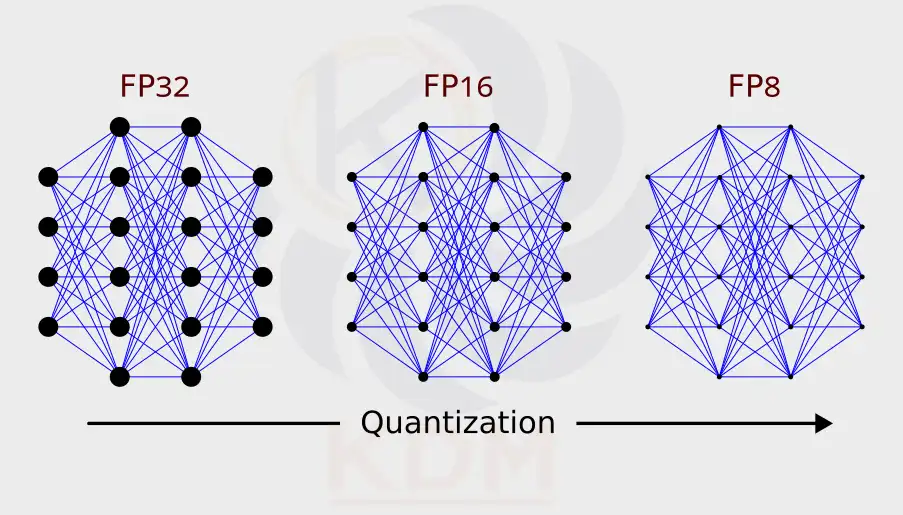
The Size of LLMs Explained and the Key Role of Quantization | Khaldevmedia
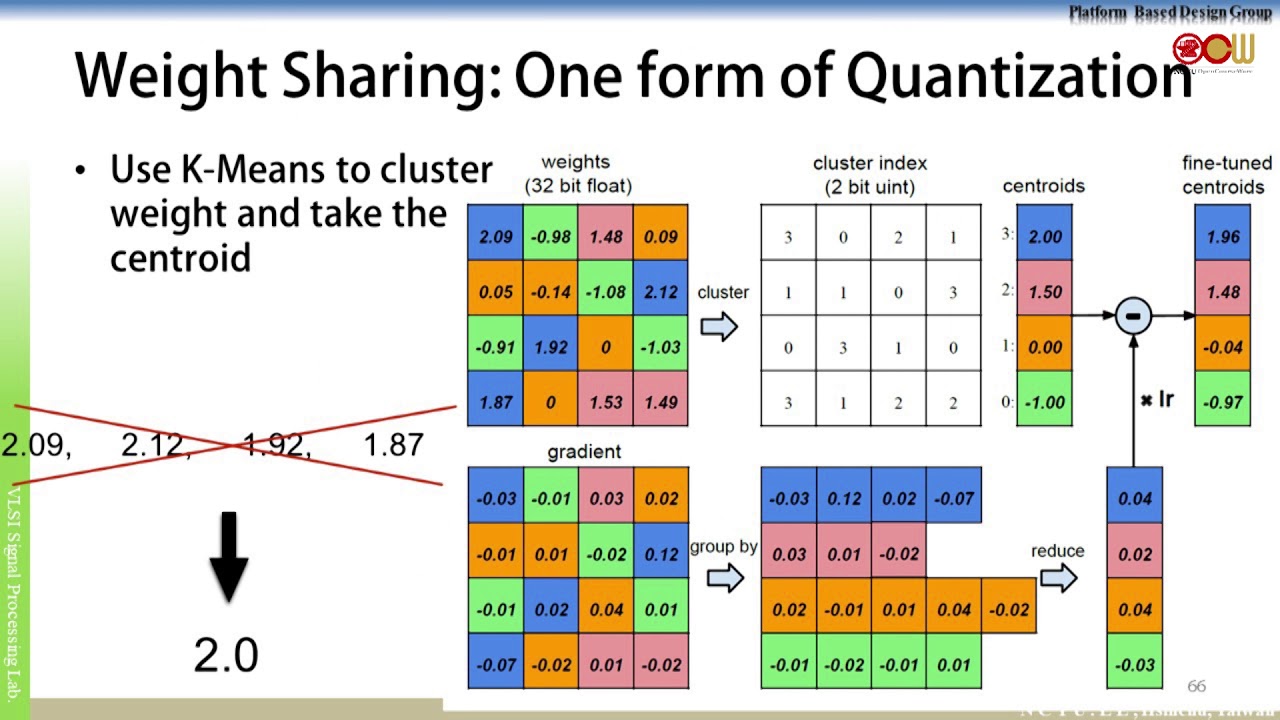
Lec04 深度學習的模型壓縮與加速 Weight Quantization (4/9) - YouTube

How LLMs survive in low precision | Quantization Fundamentals - YouTube
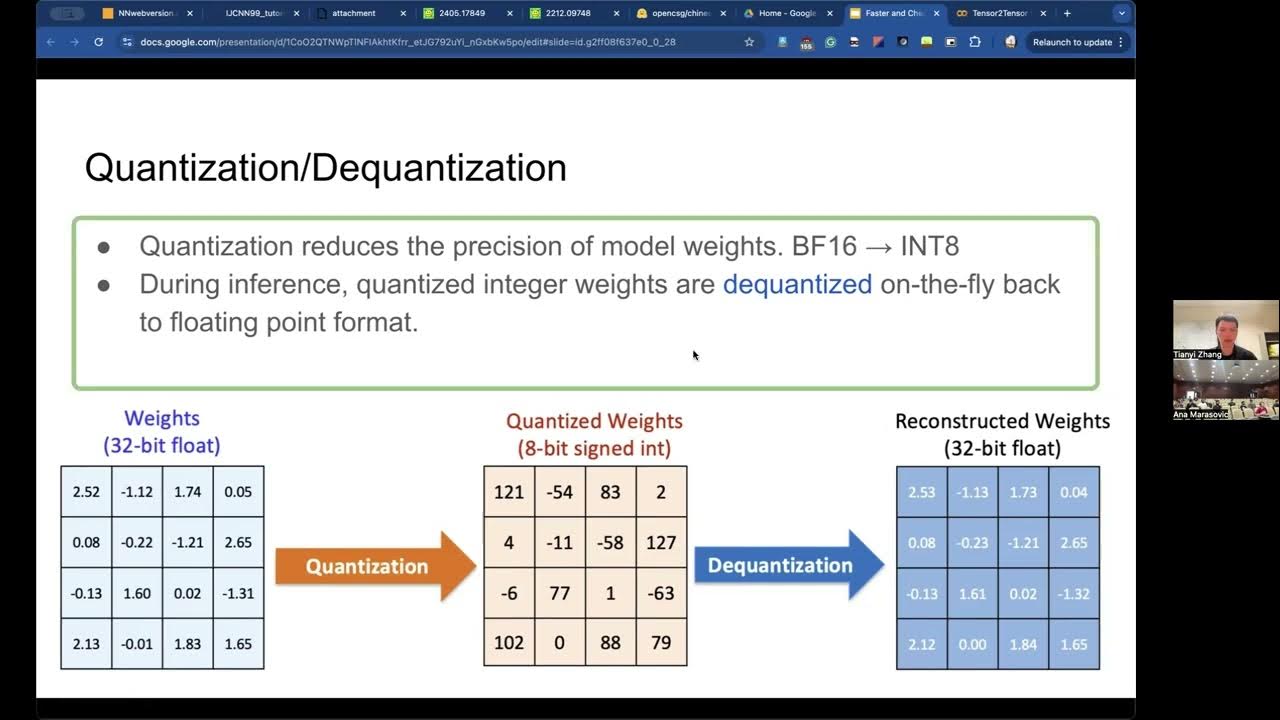
Guest Lecture by Tianyi Zhang: Faster & Cheaper LLMs with Weight and ...

AWQ: Activation-aware Weight Quantization for LLM Compression and ...
Advertisement Space (336x280)

LLM Quantization why size matters - YouTube

This AI Paper Boldly Quantizes the Weight Matrices of LLMs to 1-Bit ...

Deciphering LLMs: From Transformers to Quantization - YouTube

This AI Paper Boldly Quantizes the Weight Matrices of LLMs to 1-Bit ...
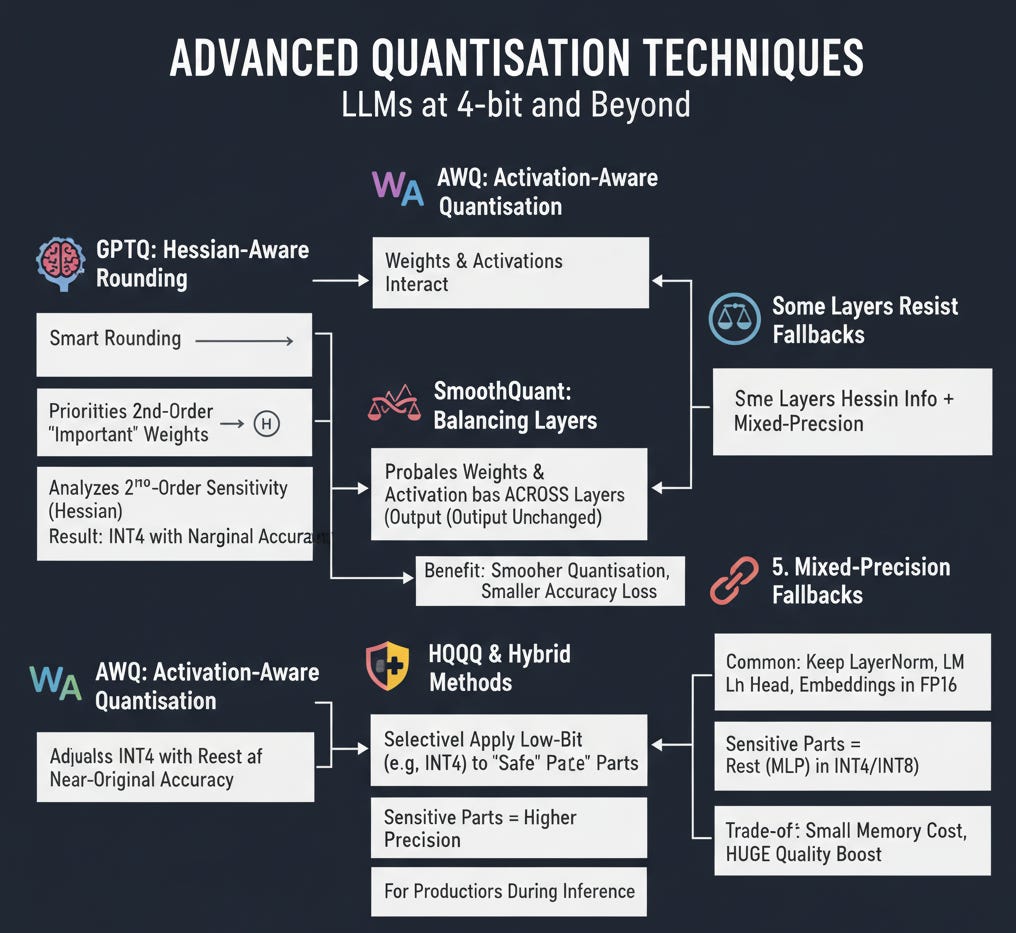
Deep Dive into Quantization of LLMs - by Bhavishya Pandit

AWQ: Activation-aware Weight Quantization for LLM Compression and ...

AWQ for LLM Quantization - YouTube

LLM inference optimization: Model Quantization and Distillation - YouTube

What is LLM Quantization ? - YouTube

LLM Quantization Explained in simple language: How to Reduce Memory ...
Advertisement Space (336x280)

The Magic Behind QLORA: Efficient Finetuning of Quantized LLMs - YouTube

Introduction to LLM Quantization - YouTube
LLM Fine-Tuning 13: LLM Quantization Explained (PART 2) | PTQ, QAT ...
LLM Quantization Explained — How 4-Bit Models Run on Consumer GPUs ...

AWQ: Activation-aware Weight Quantization for LLM Compression and ...

How to load Large LLMs in lesser memory using Quantization? - YouTube