
Meet Vllm For Faster More Efficient Llm Inference And Serving

Meet vLLM: For faster, more efficient LLM inference and serving
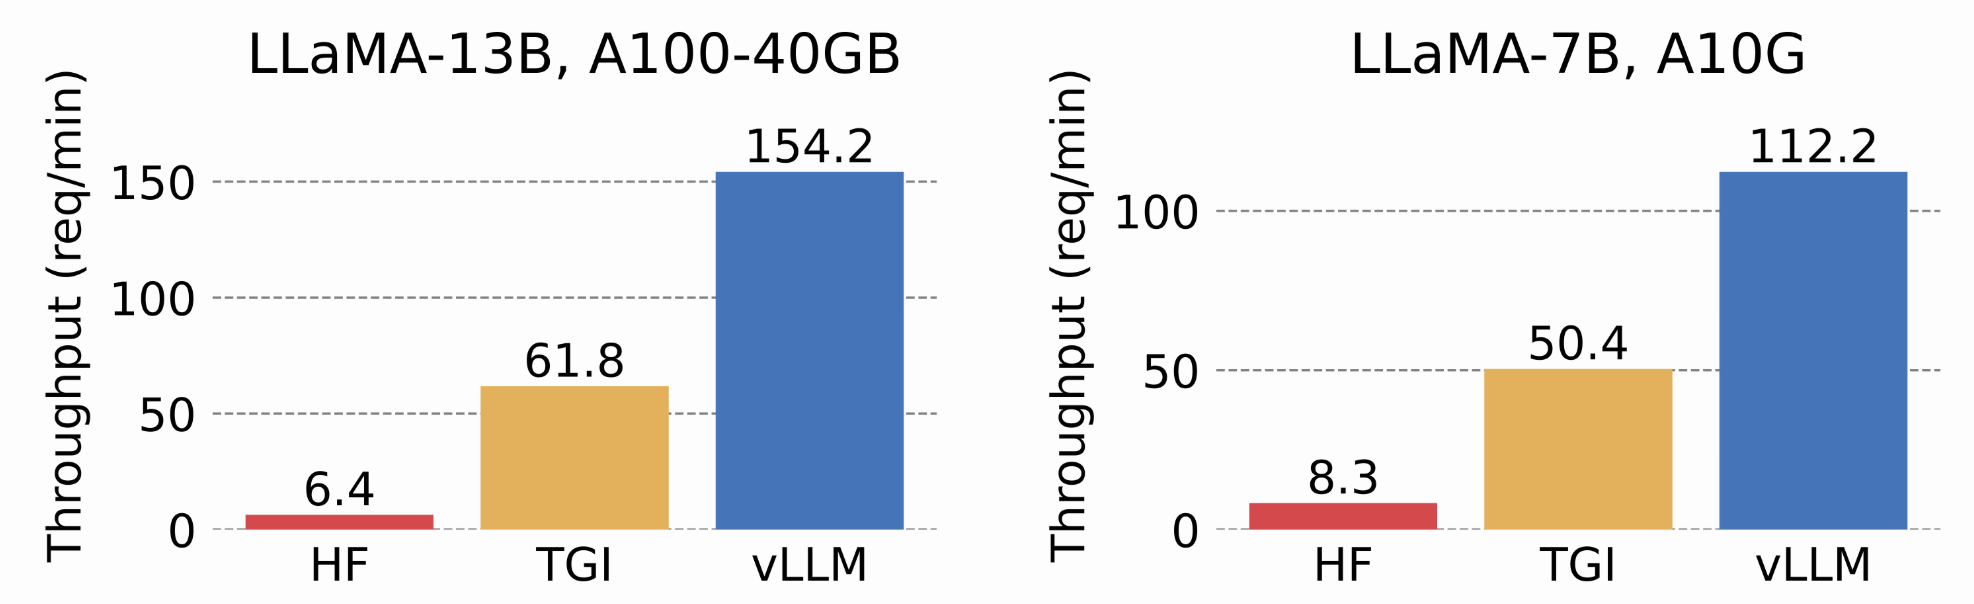
Meet vLLM: For faster, more efficient LLM inference and serving

Meet vLLM: For faster, more efficient LLM inference and serving
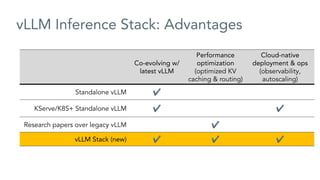
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
Efficient LLM Inference and Serving with vLLM
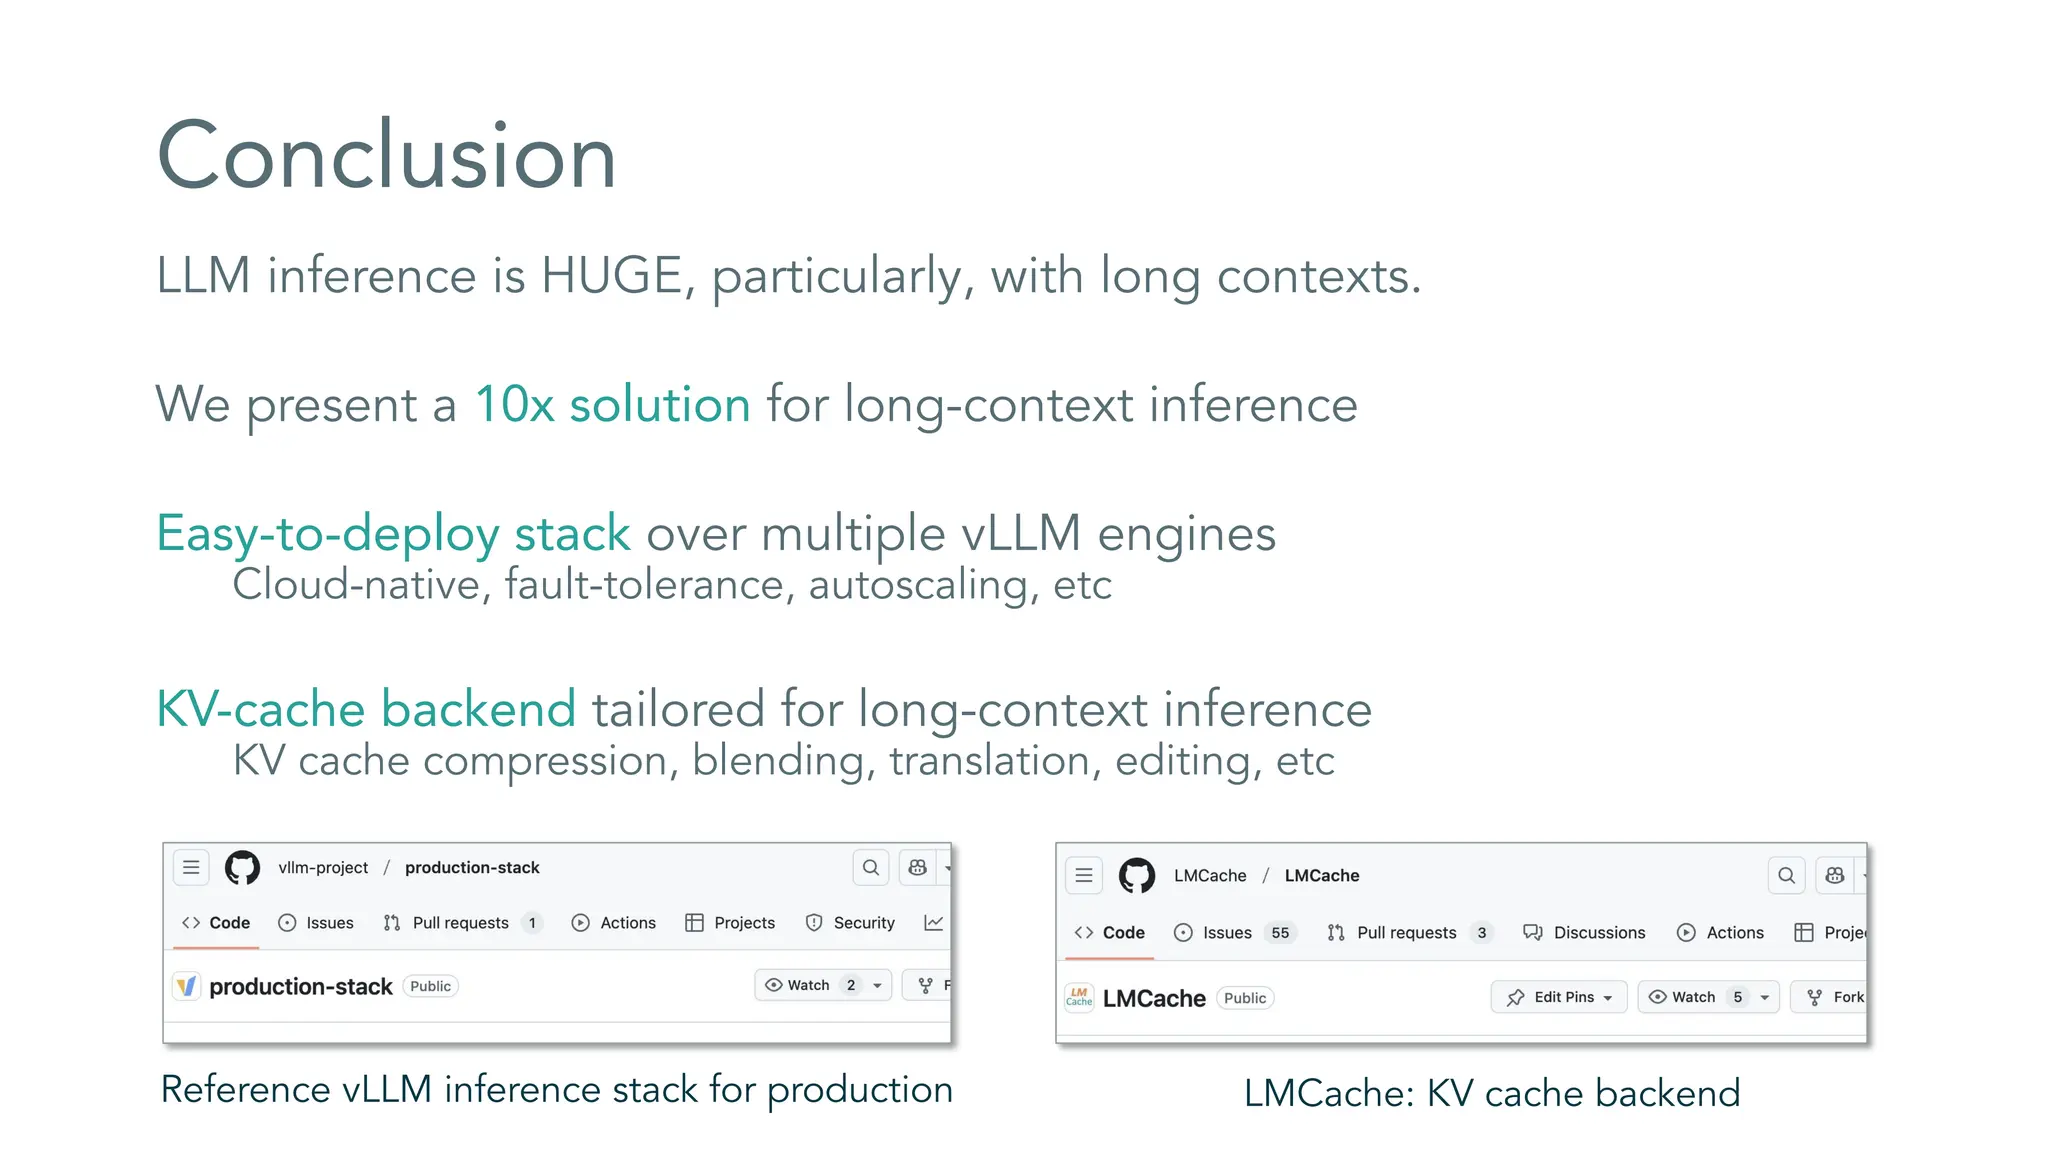
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...
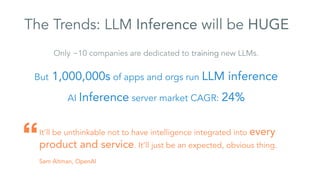
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
Advertisement Space (300x250)
12 vLLM Alternatives for Efficient and Scalable LLM Inference ...

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...

AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

Free Video: vLLM Inference and LLM Server Engine for Machine Learning ...

UC Berkeley Researchers Introduce vLLM for Efficient LLM Inference ...
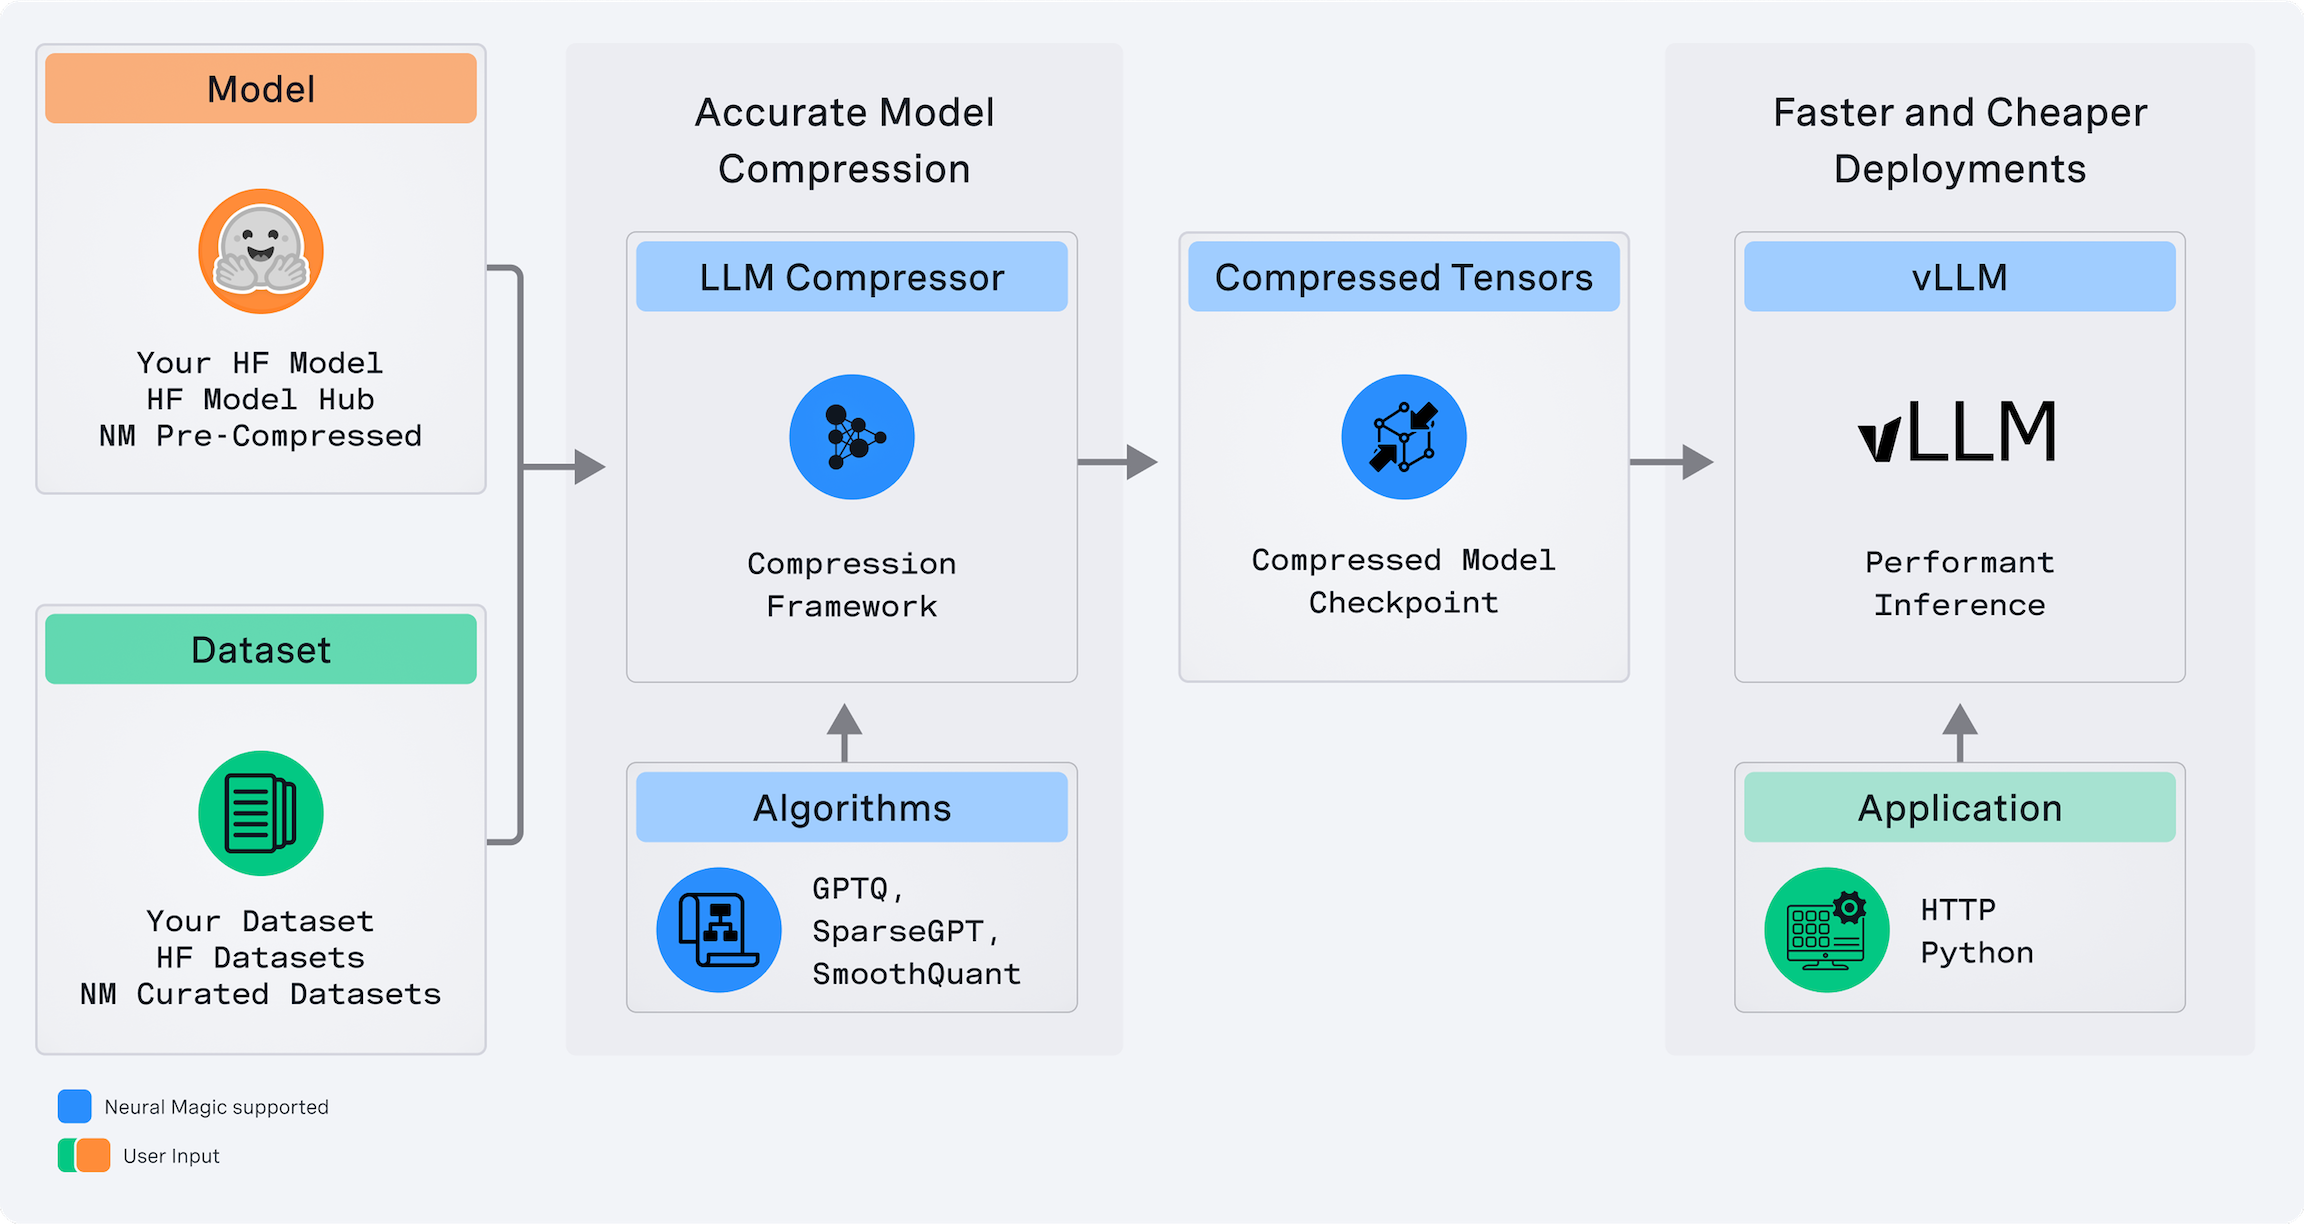
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer

vLLM Review: High-Performance LLM Inference Engine for GPU ...
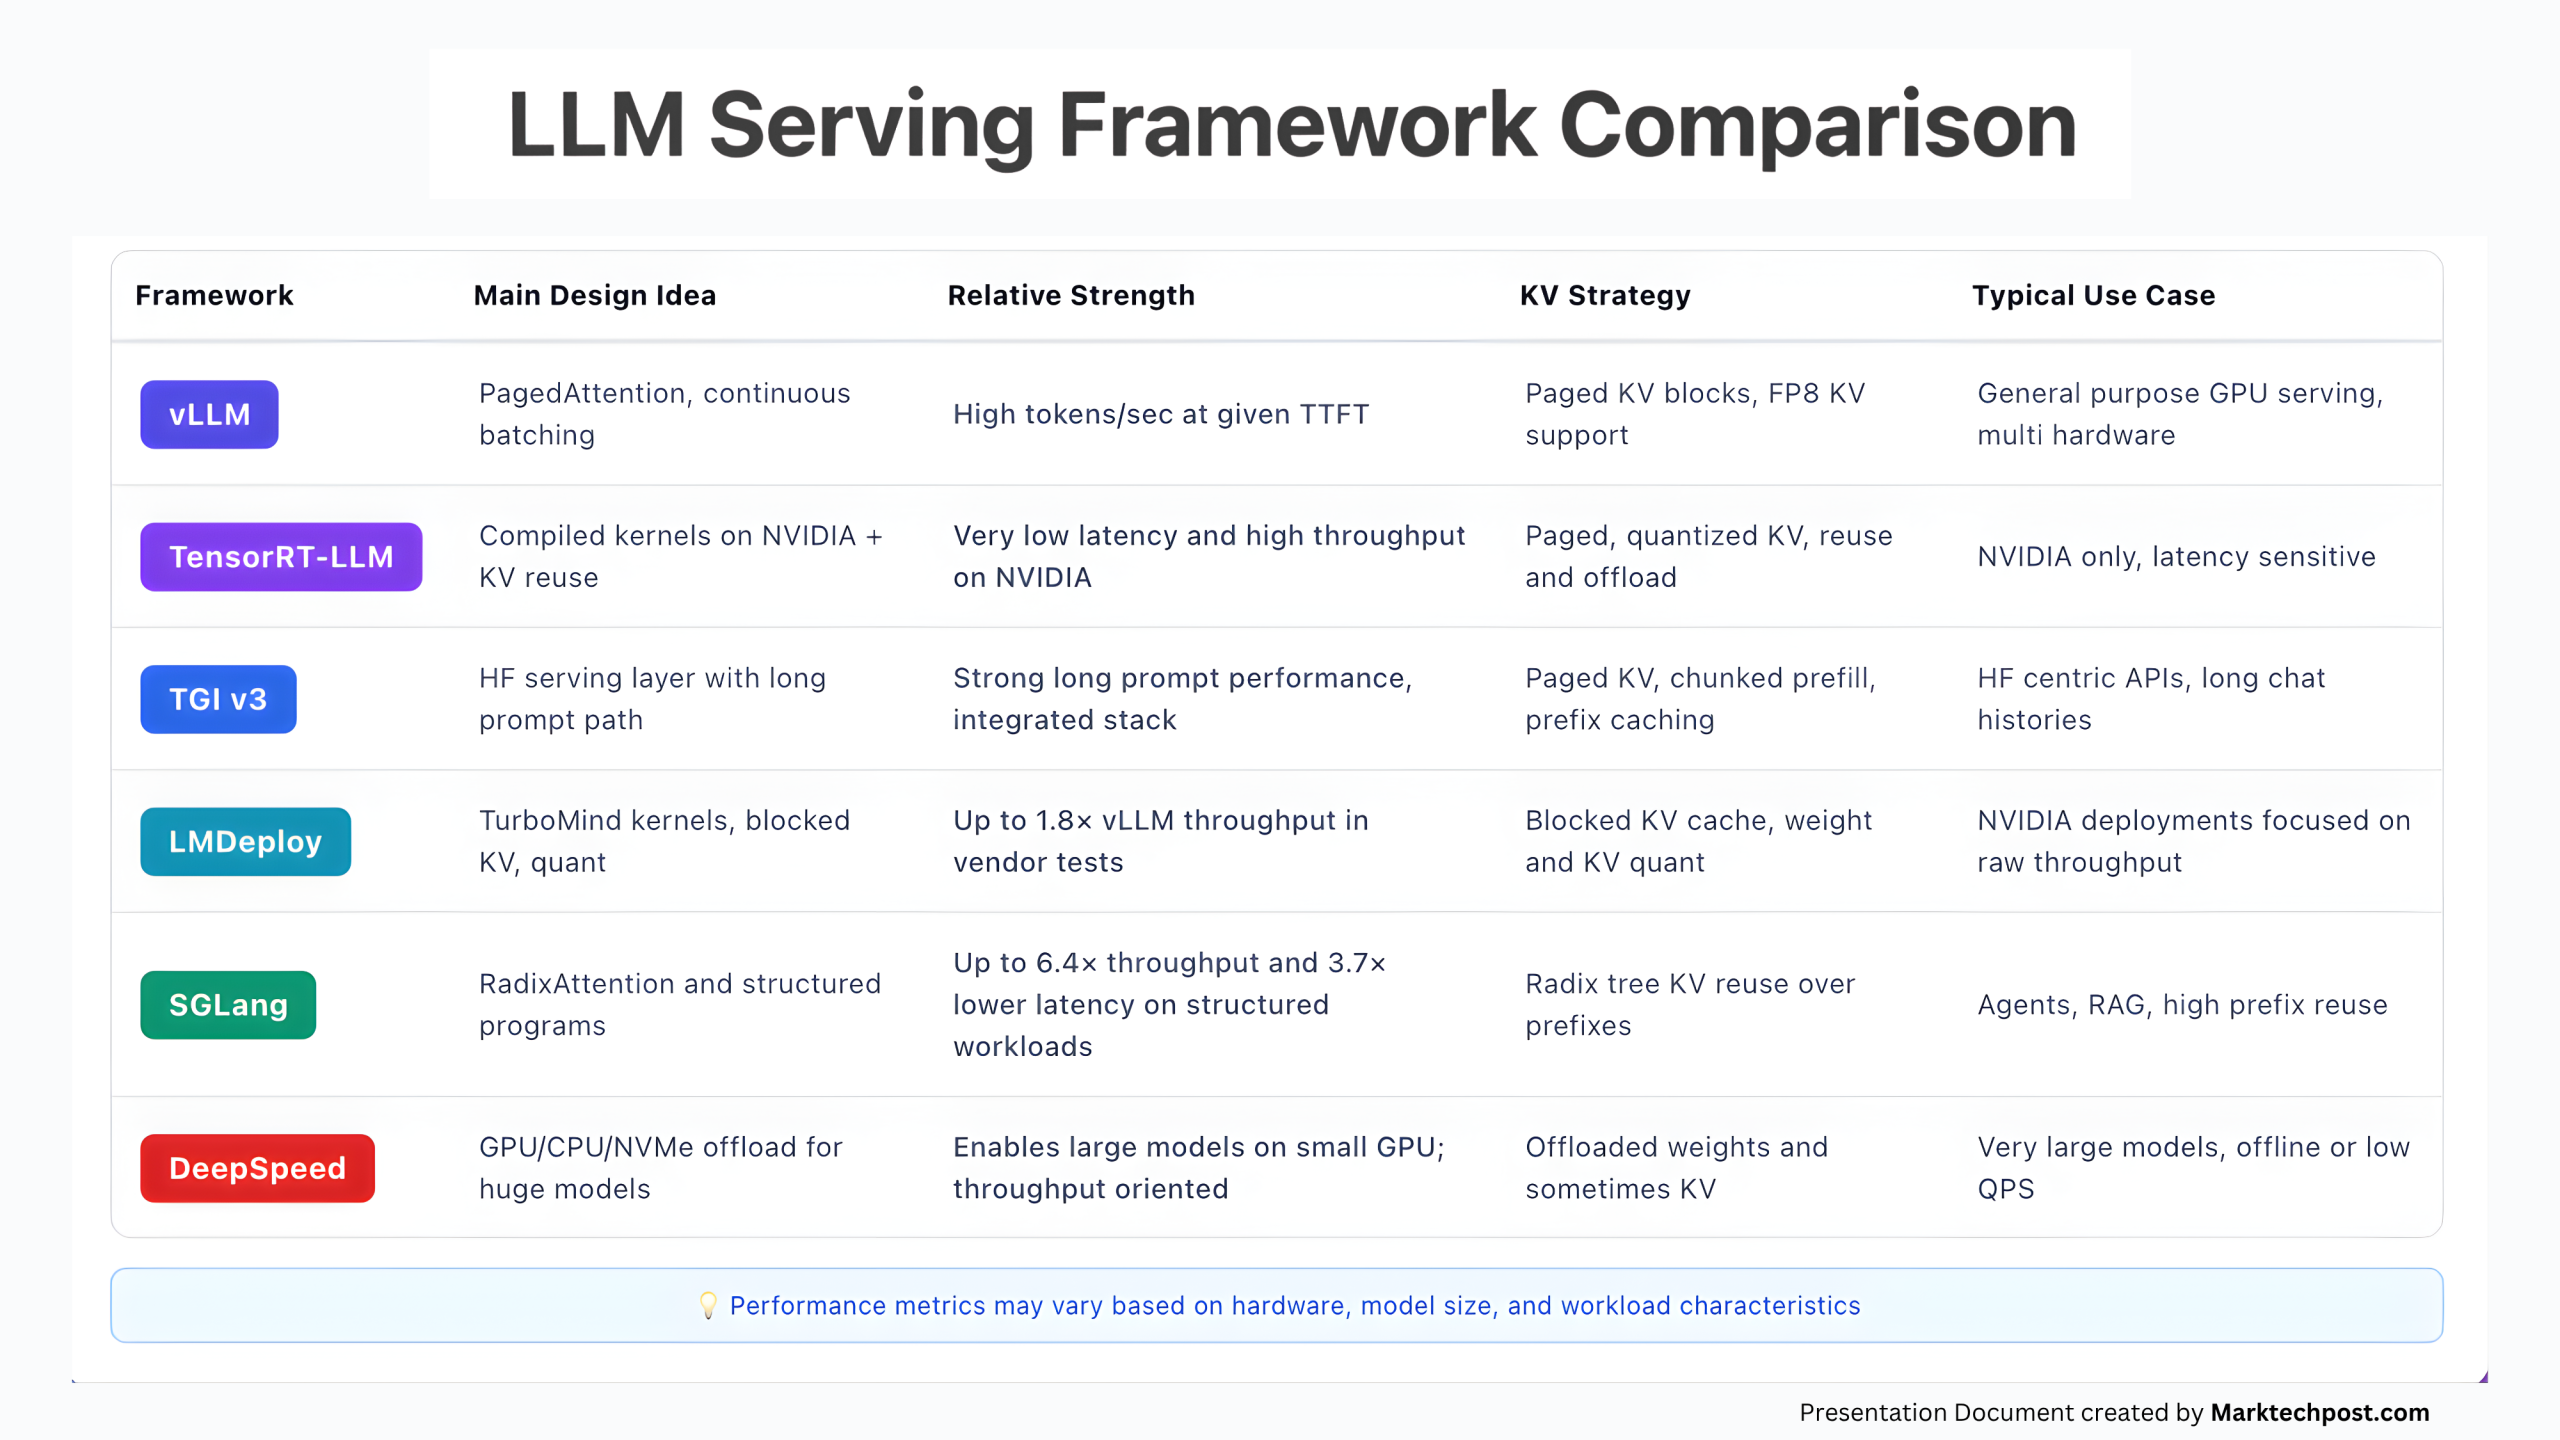
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...

Getting Started with vLLM: Fast and Efficient LLM Inference | by Wenyi ...
Advertisement Space (336x280)
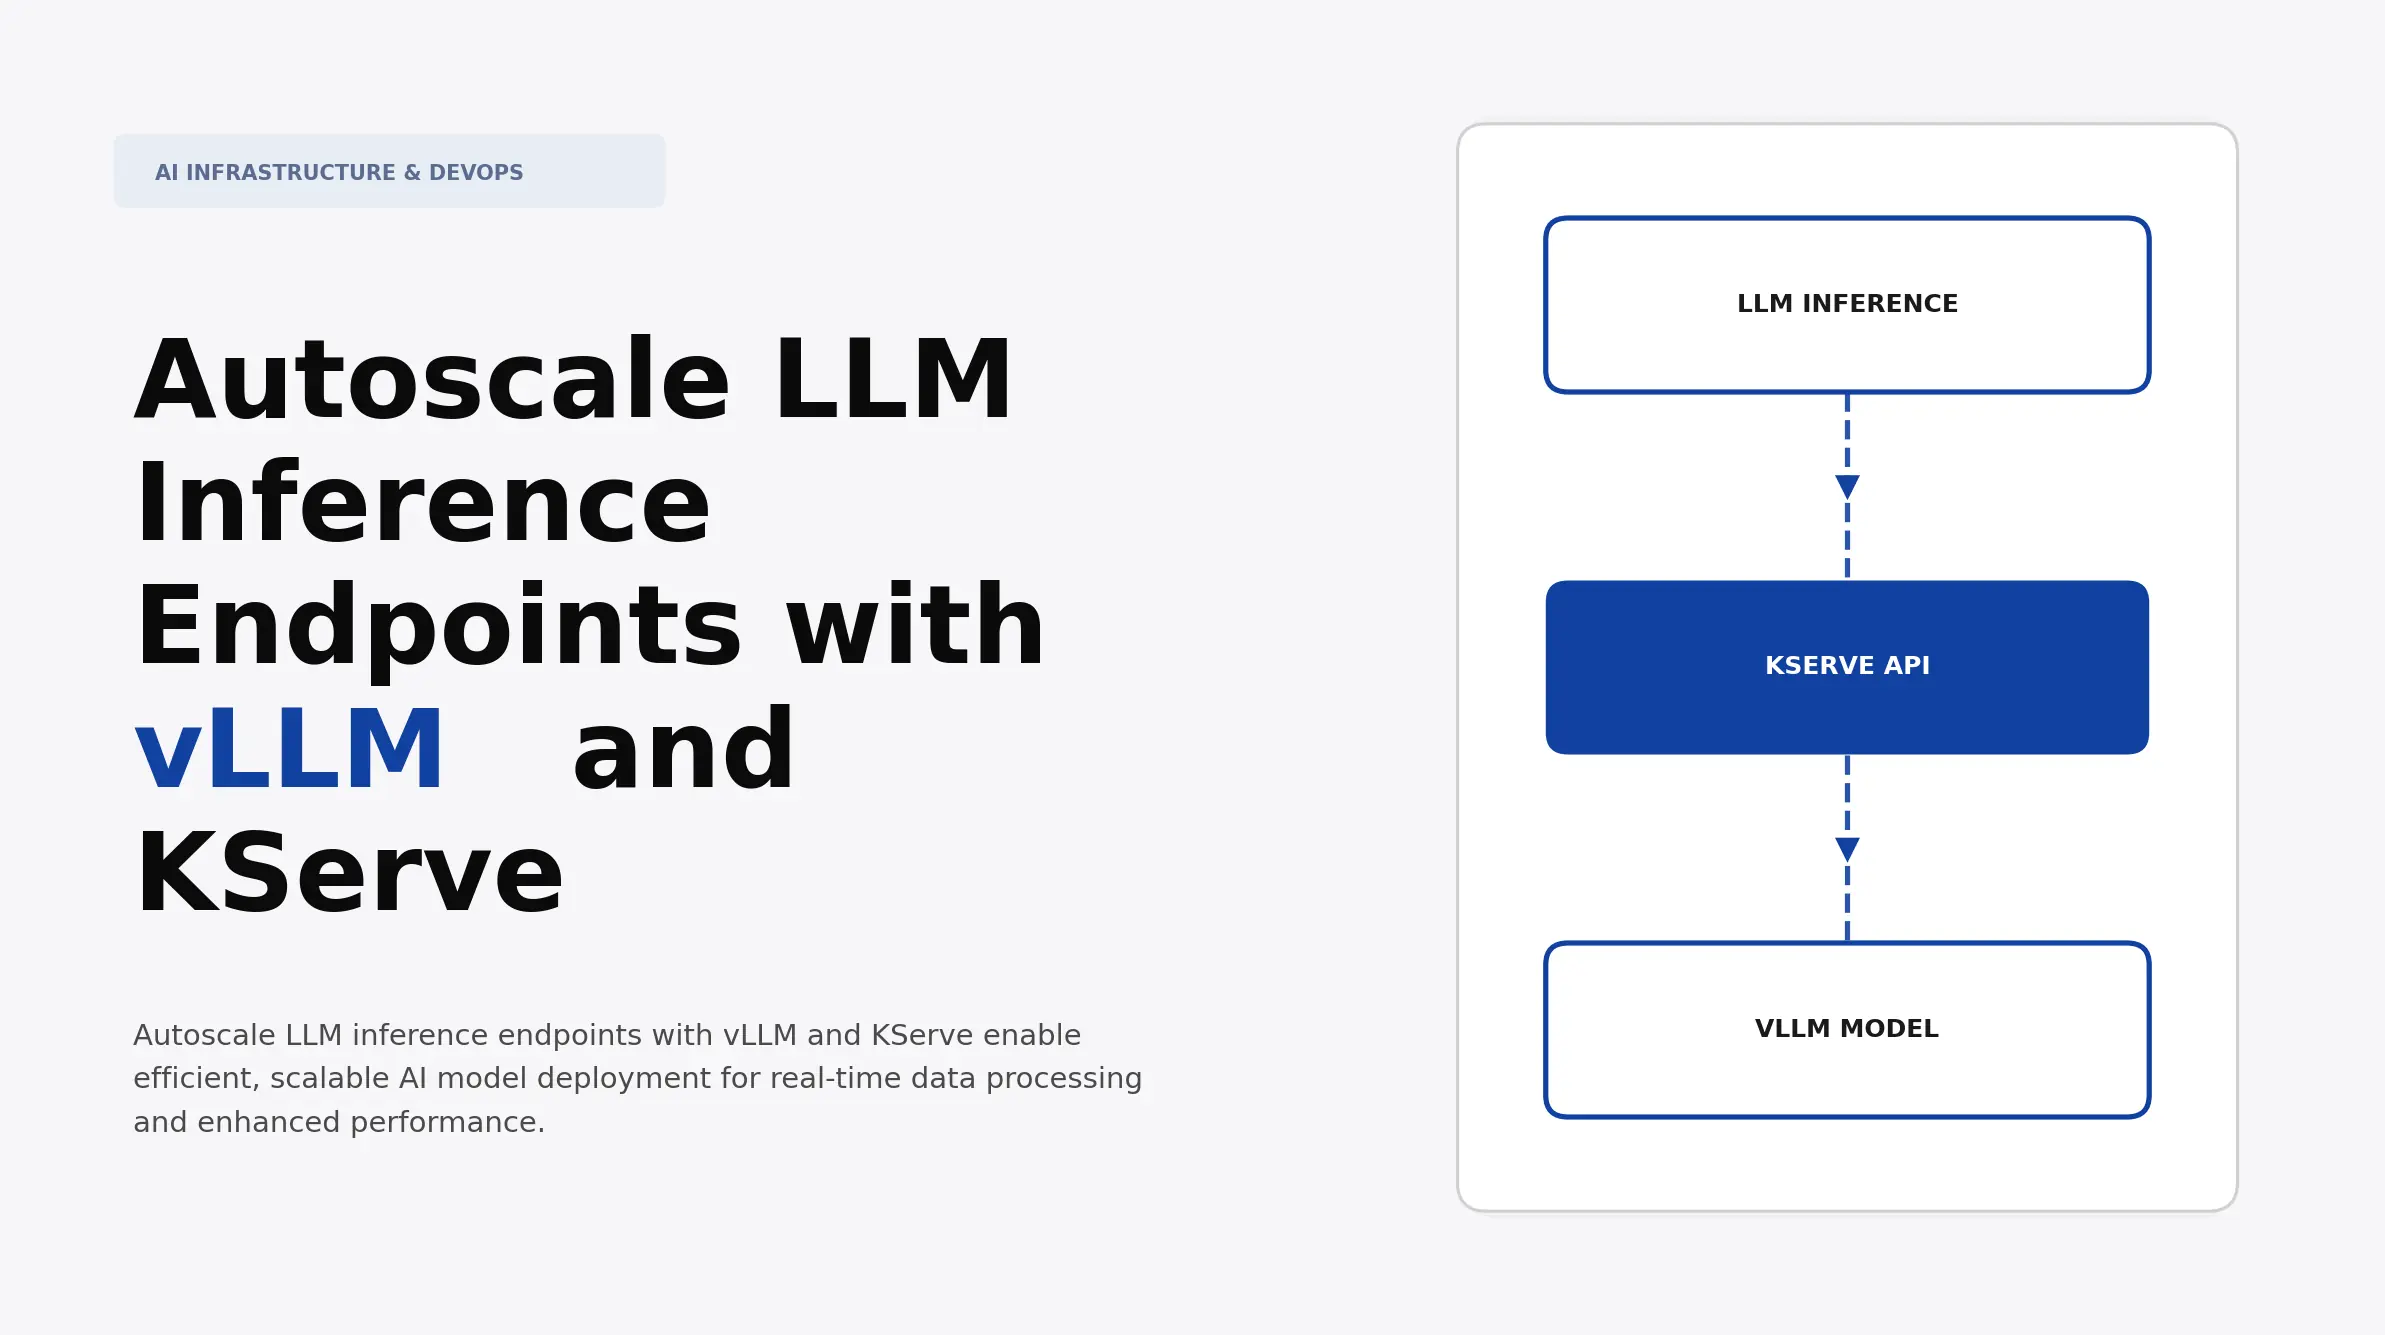
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops

Free Video: Fast LLM Serving with vLLM and PagedAttention from Anyscale ...

New Course! Enroll in Fast & Efficient LLM Inference with vLLM - News ...

LLM vs vLLM: A Complete Comparison for Efficient AI Inference
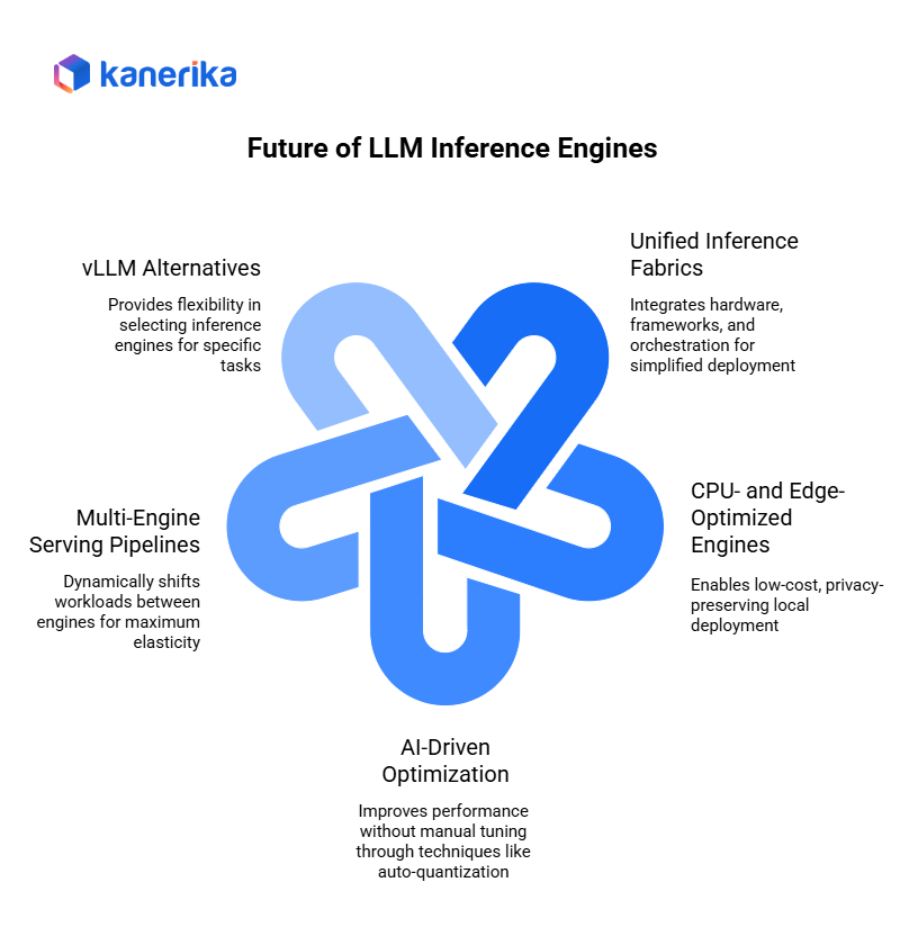
Top 10 vLLM Alternatives for Faster AI Inference in 2026
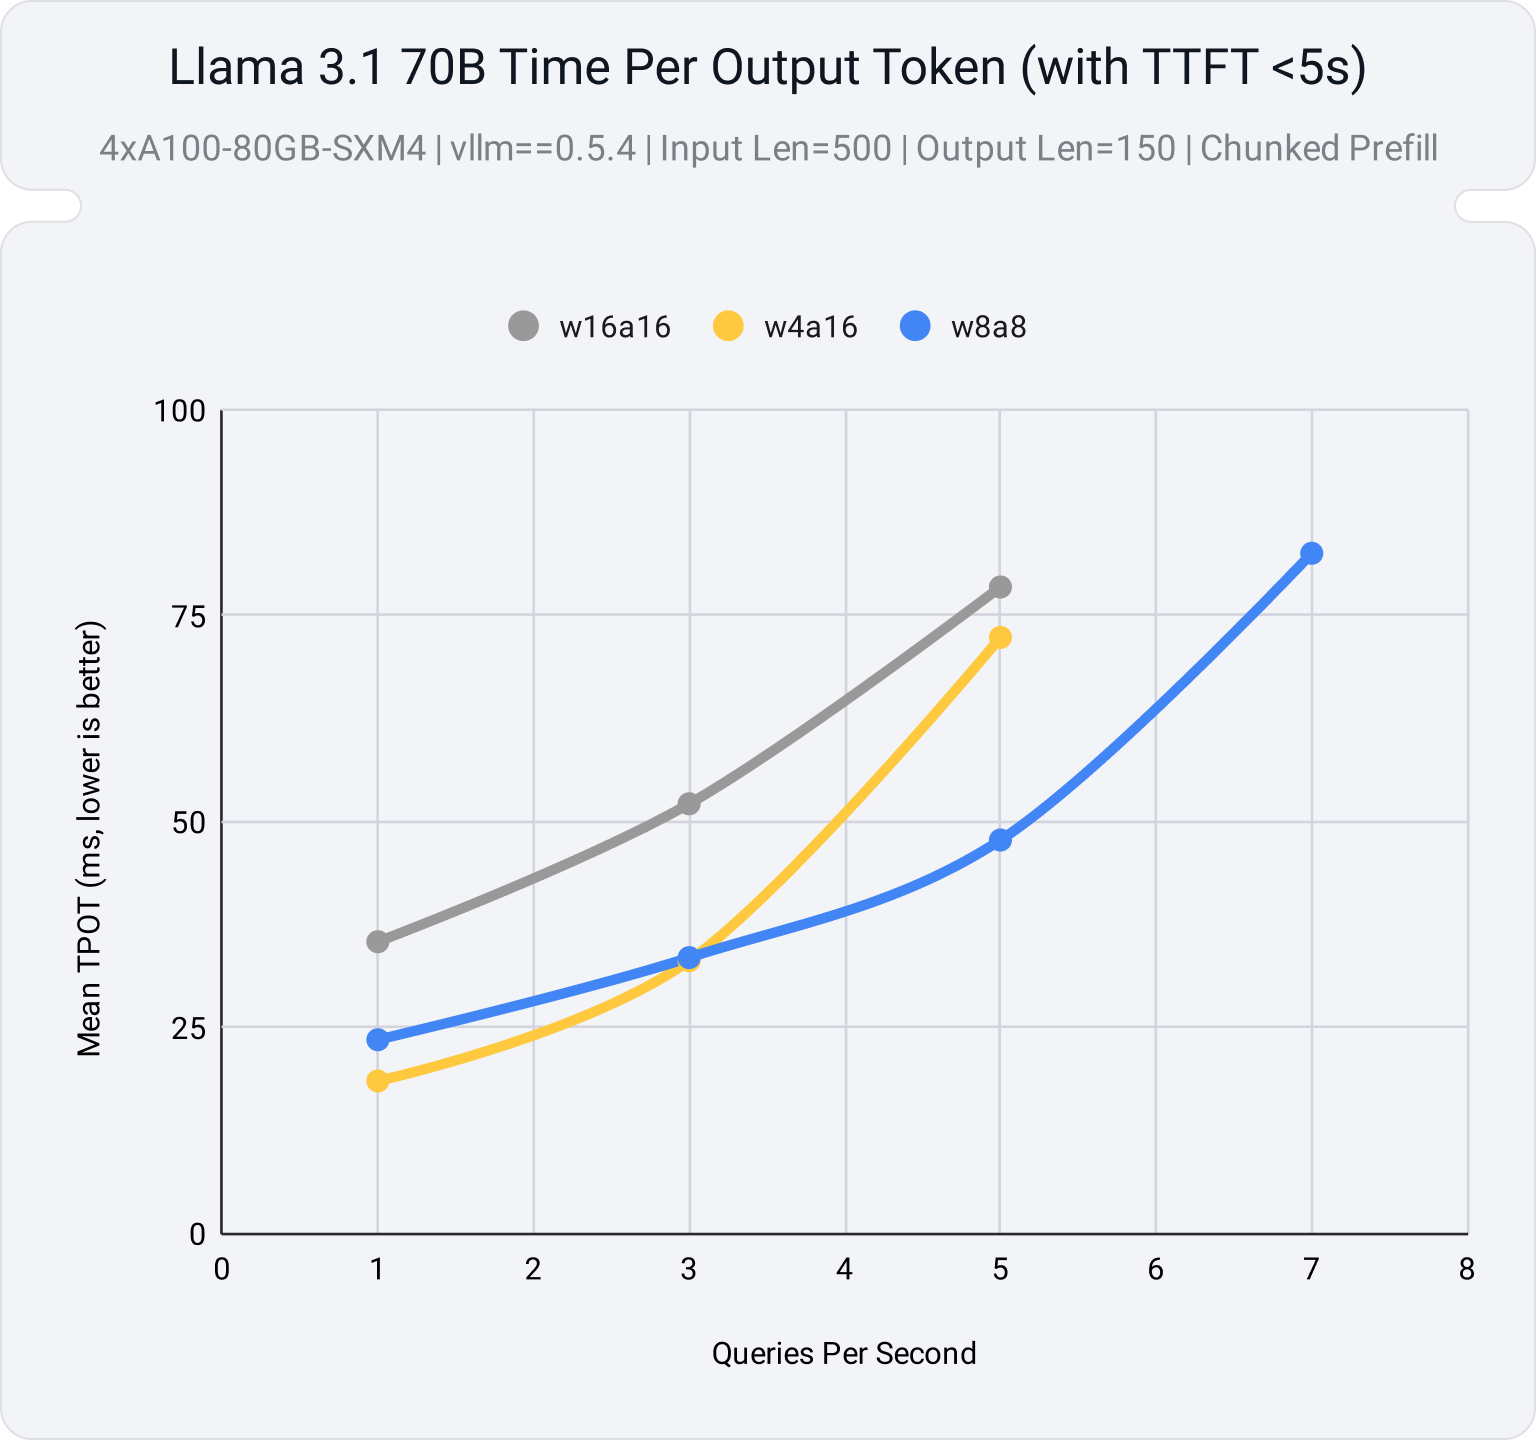
LLM Compressor is here: Faster inference with vLLM | Red Hat Developer
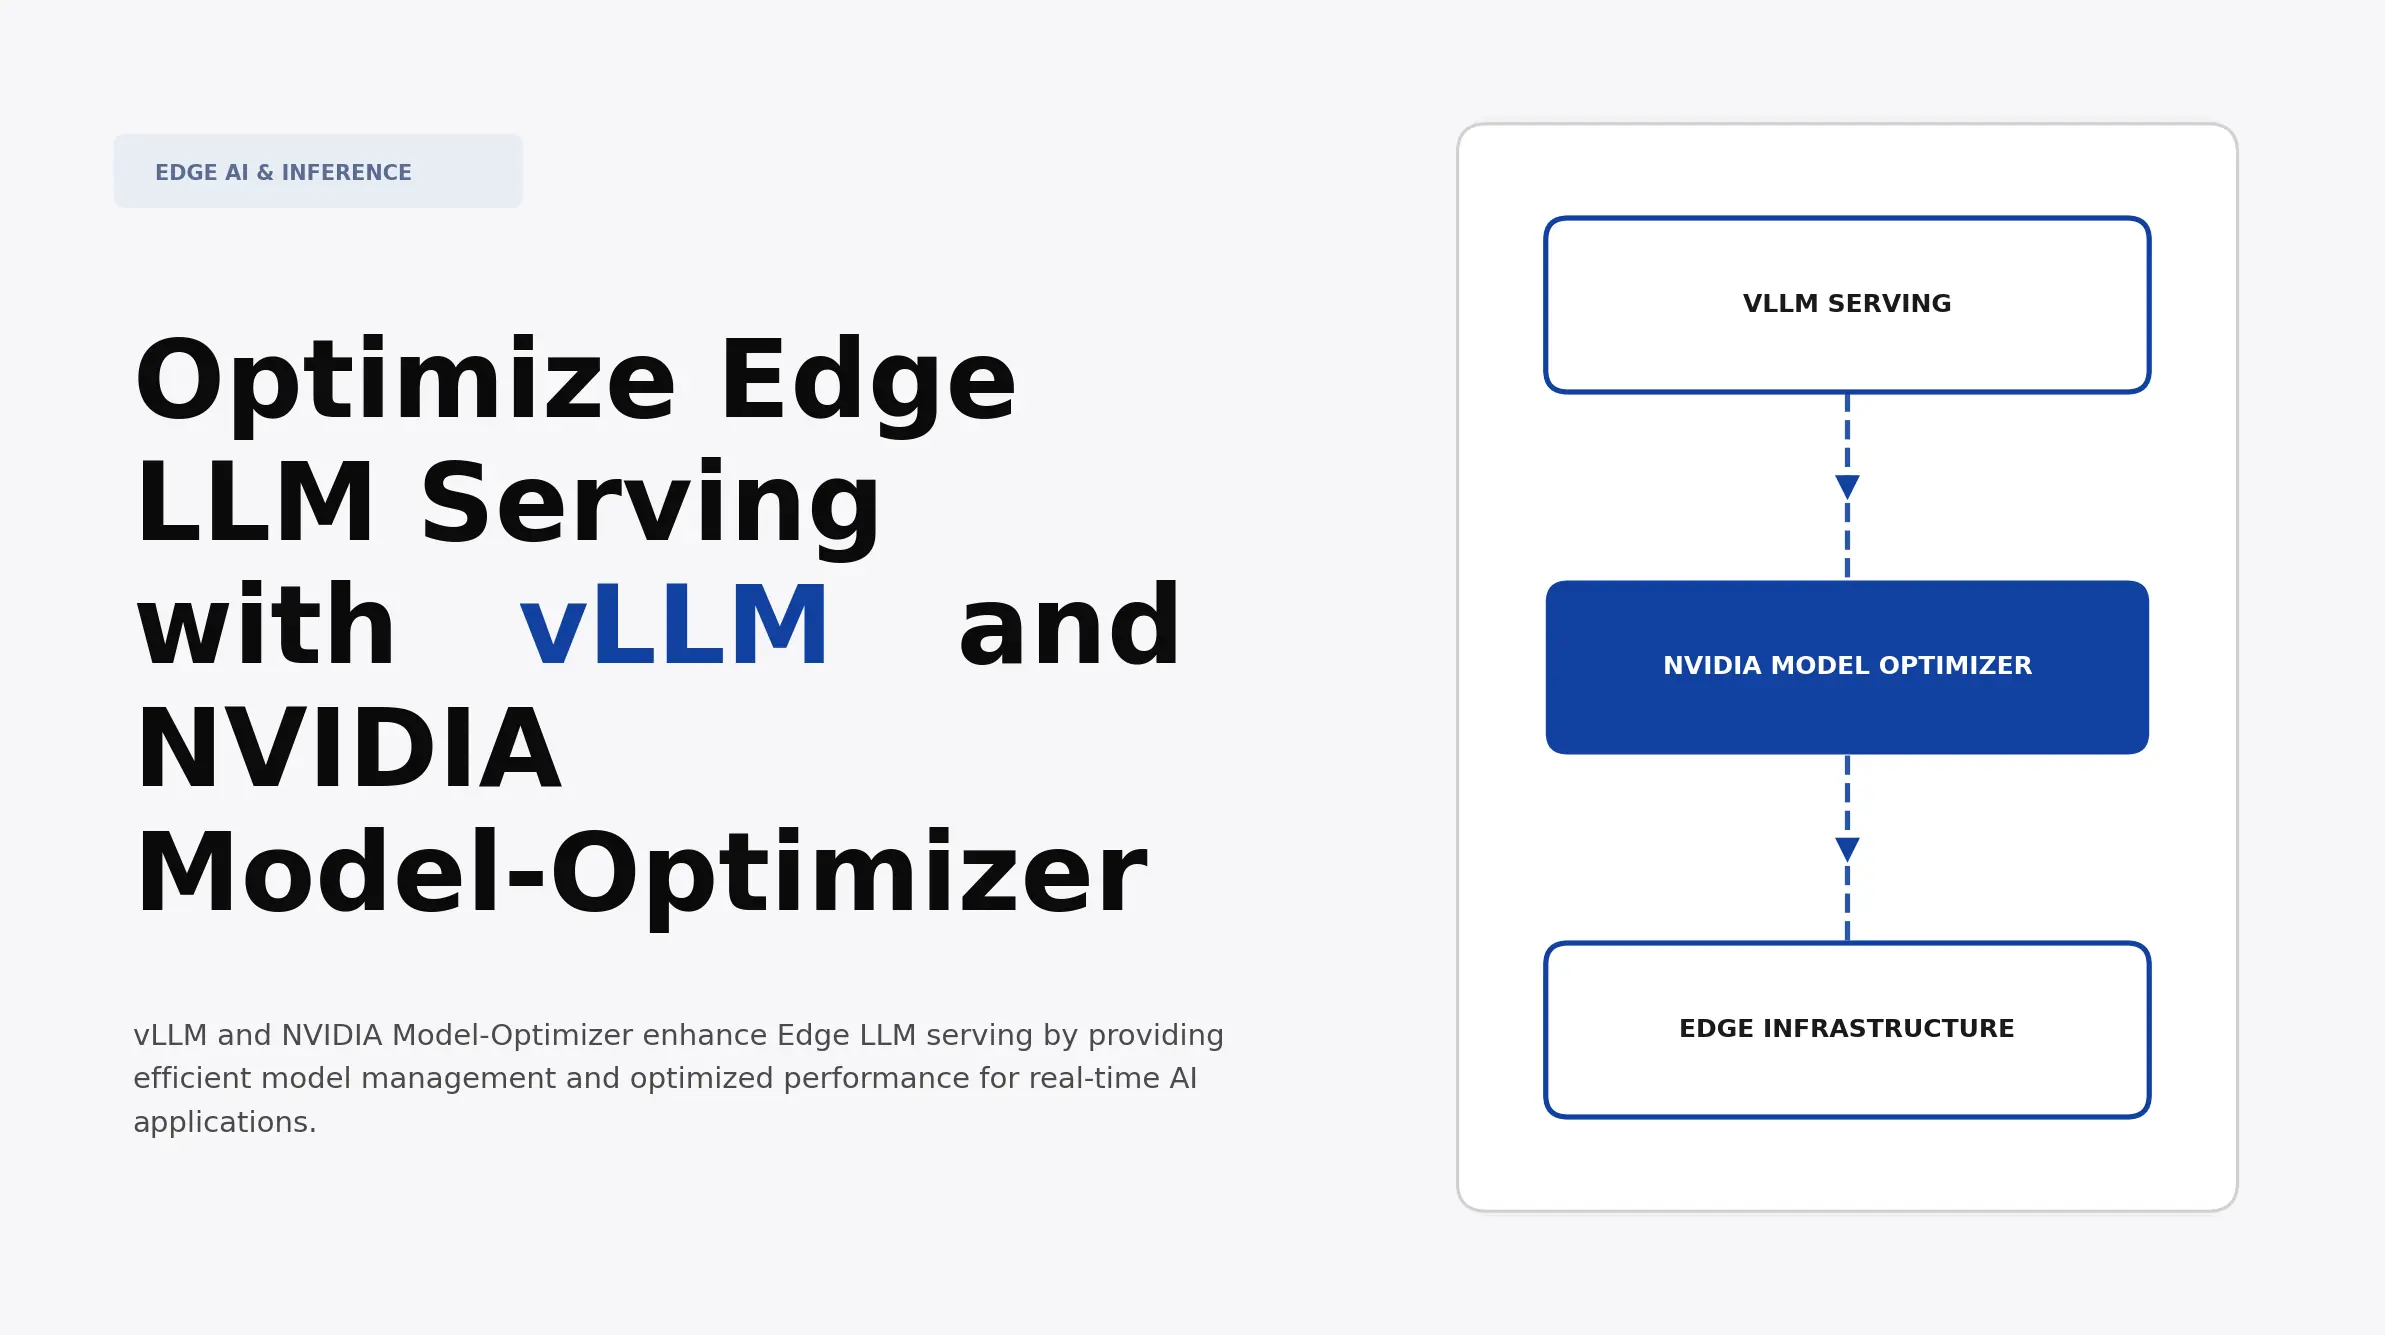
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving ...
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...

Introducing vLLM: Fast and Efficient LLM Inference Engine | Sneha Rudra ...
Advertisement Space (336x280)

Comparing two LLM serving frameworks: Friendli Inference vs. vLLM

VLLM: High-Throughput LLM Inference and Serving by Rapid Synthesis ...

vLLM is a super fast and efficient LLMs serving library, which is ...

How to easily migrate LLM inference serving from vLLM to Friendli ...

vLLM Explained in 10 Minutes: Faster LLM Serving - YouTube

Scaling LLM inference with Ray and vLLM