
Moba Native Sparse Attention
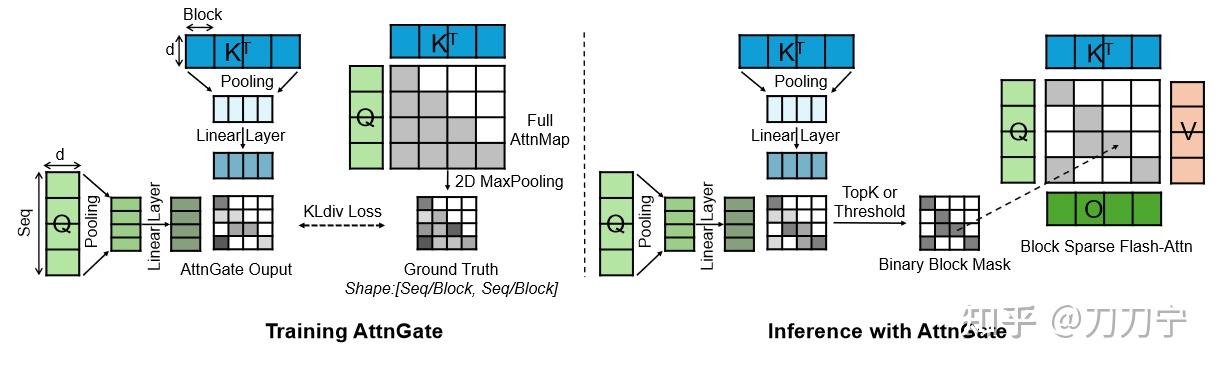
笔记:MoBA 与 Native Sparse Attention - 知乎
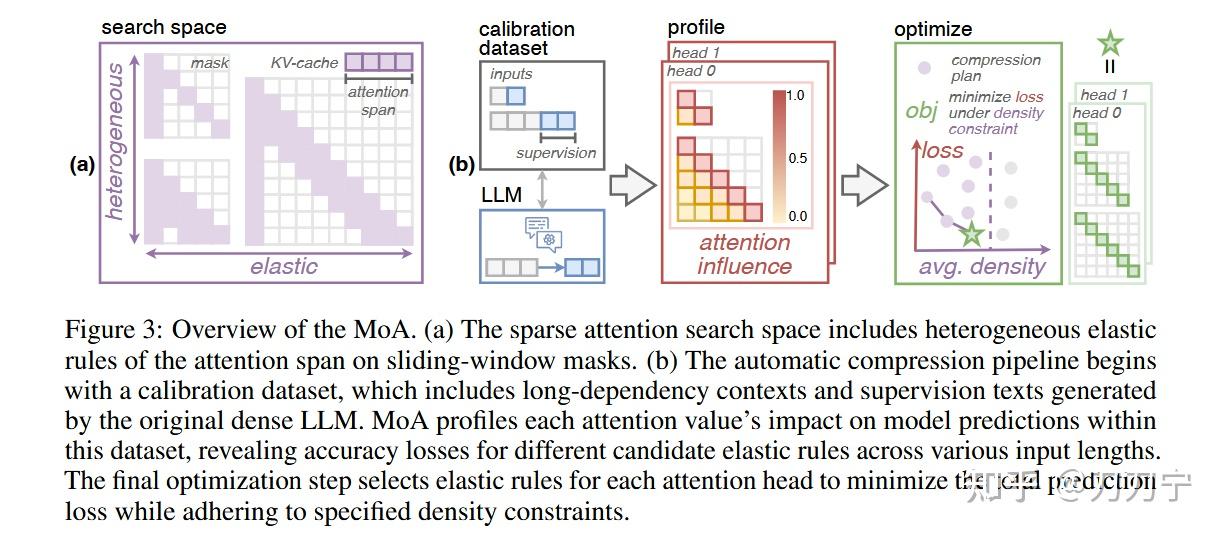
笔记:MoBA 与 Native Sparse Attention - 知乎
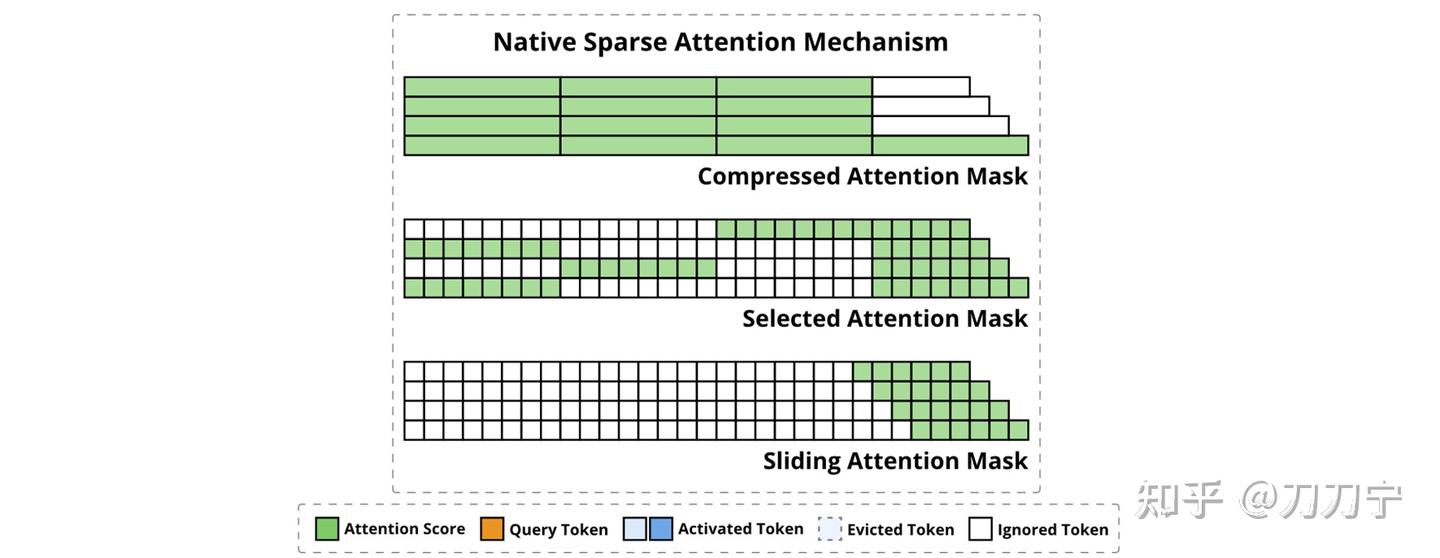
笔记:MoBA 与 Native Sparse Attention - 知乎
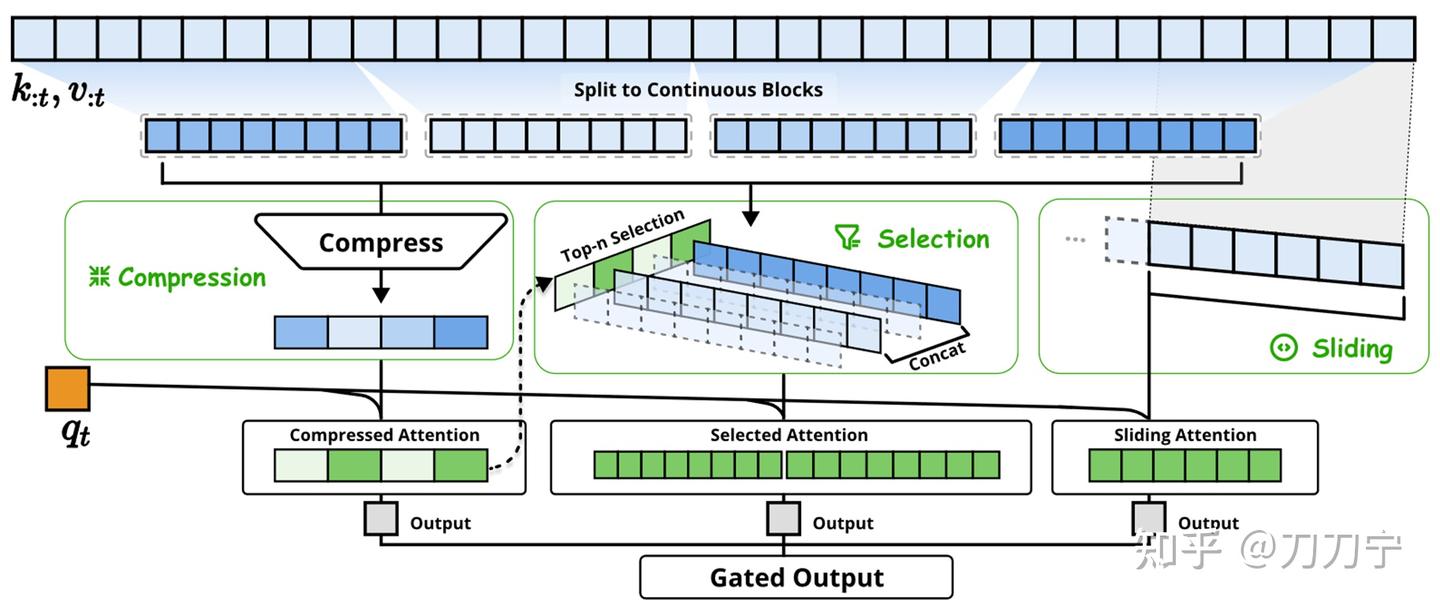
笔记:MoBA 与 Native Sparse Attention - 知乎
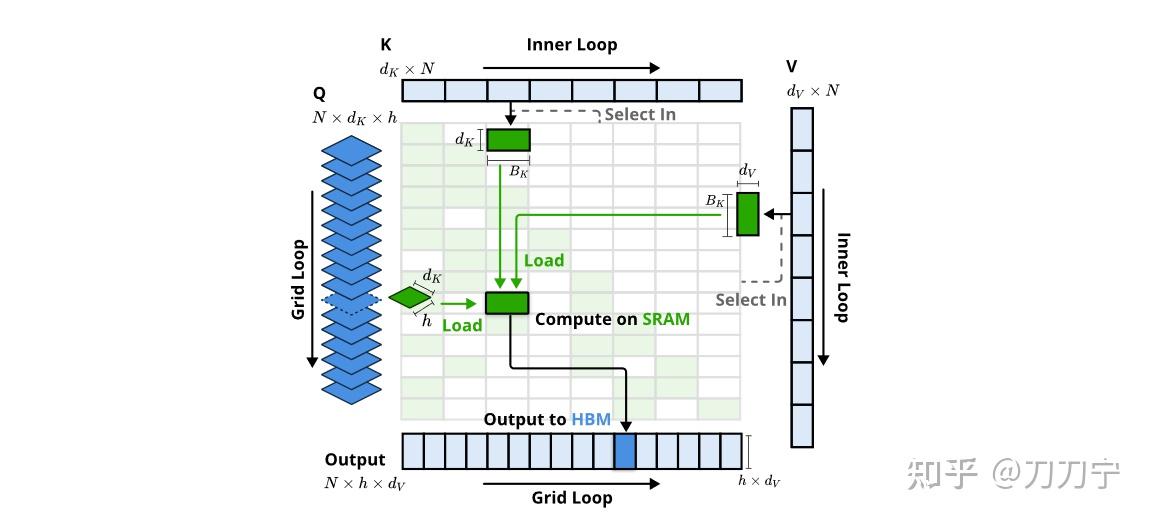
笔记:MoBA 与 Native Sparse Attention - 知乎

Optimizing Native Sparse Attention with Latent Attention and Local ...
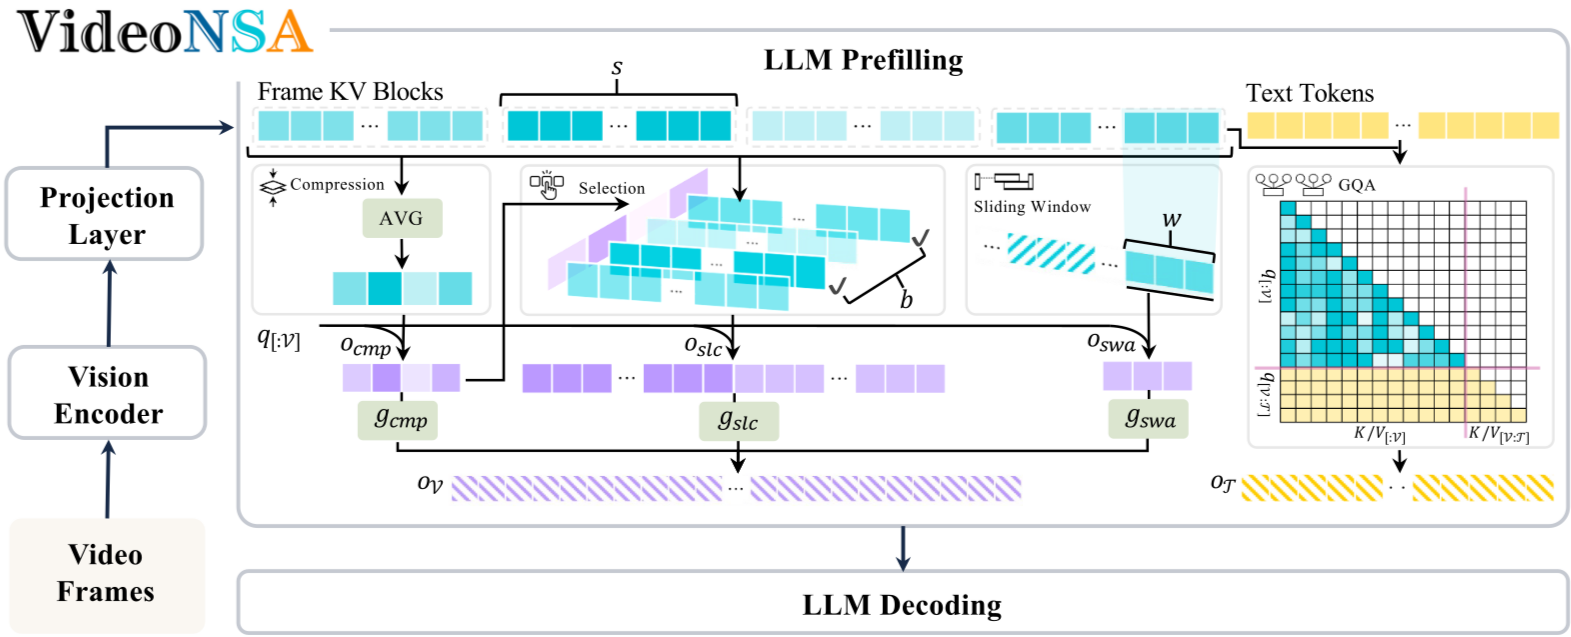
[논문 리뷰] VideoNSA: Native Sparse Attention Scales Video Understanding
Native Sparse Attention Mechanism | fla-org/native-sparse-attention ...

[Sparse Attention] Native Sparse Attention (NSA) Explained: Efficient ...
TabNSA: Native Sparse Attention for Efficient Tabular Data Learning ...
Advertisement Space (300x250)
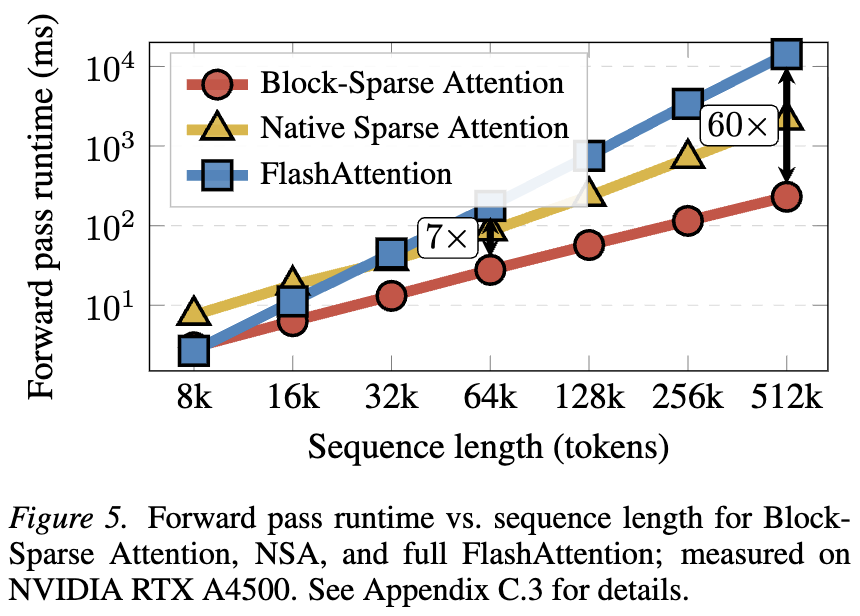
I am not surprised by the numbers, Native Sparse Attention alone gets ...

Paper page - Native Sparse Attention: Hardware-Aligned and Natively ...

Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
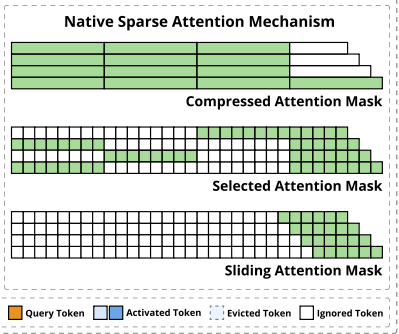
LLM大模型:deepseek浅度解析(四):Native Sparse Attention NSA原理 - 第七子007 - 博客园
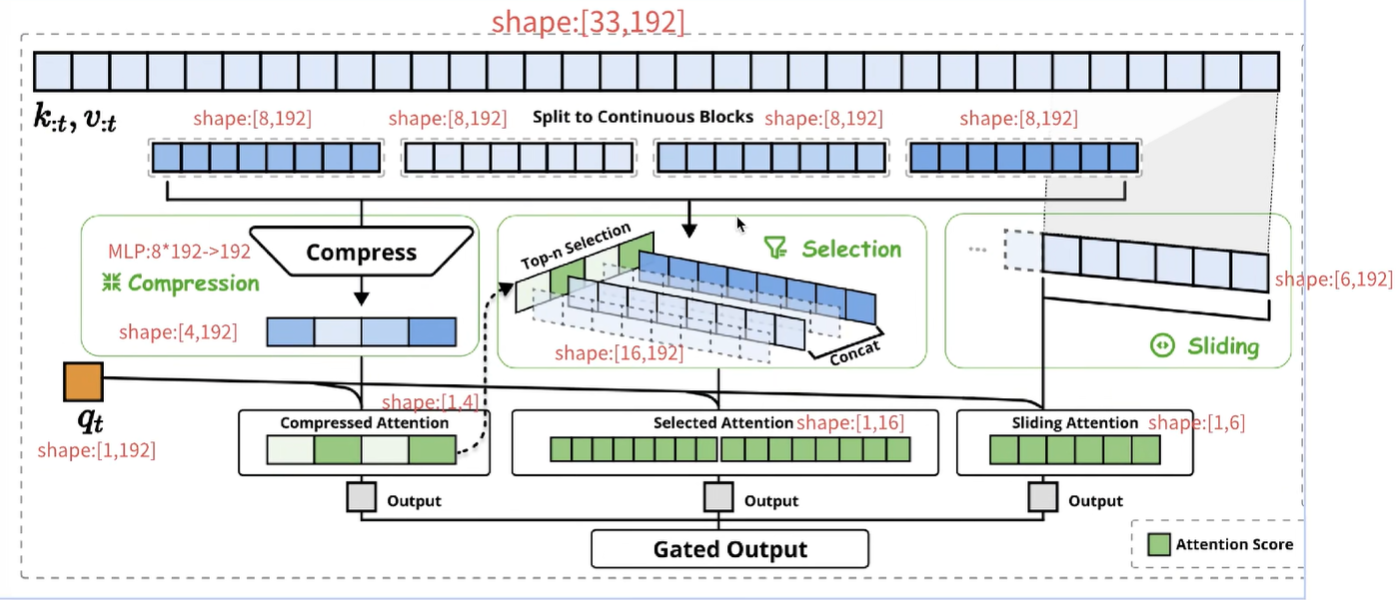
LLM大模型:deepseek浅度解析(四):Native Sparse Attention NSA原理 - 第七子007 - 博客园
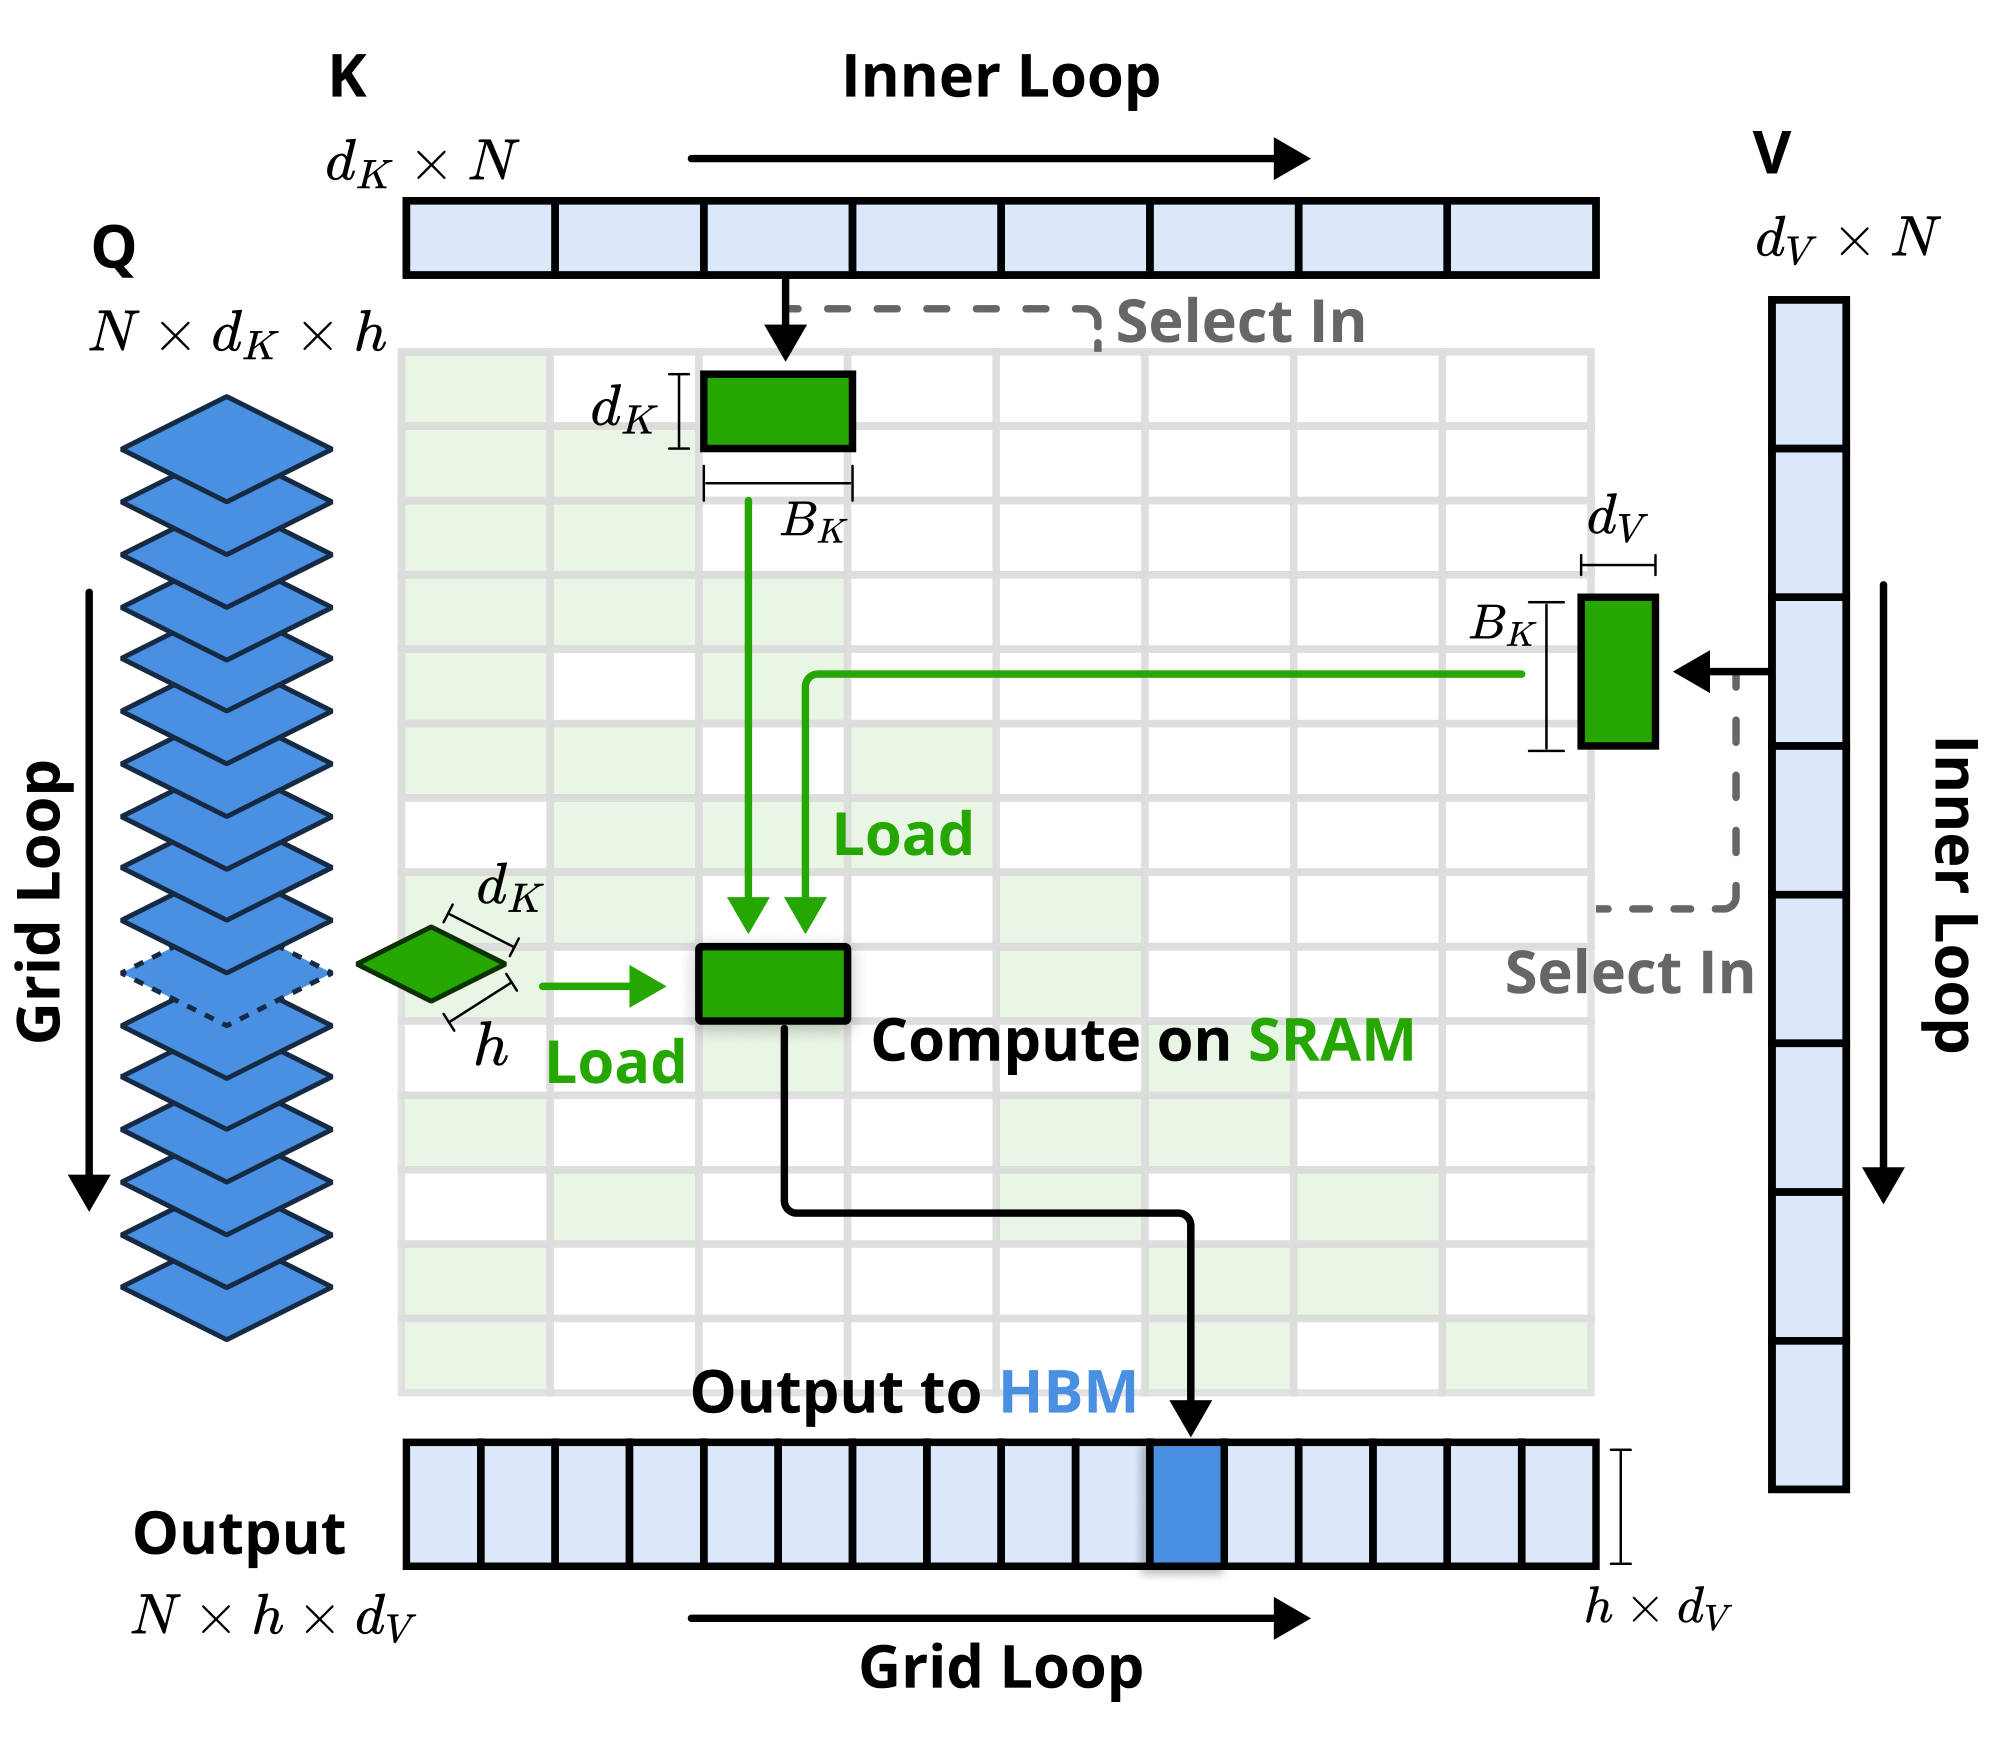
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
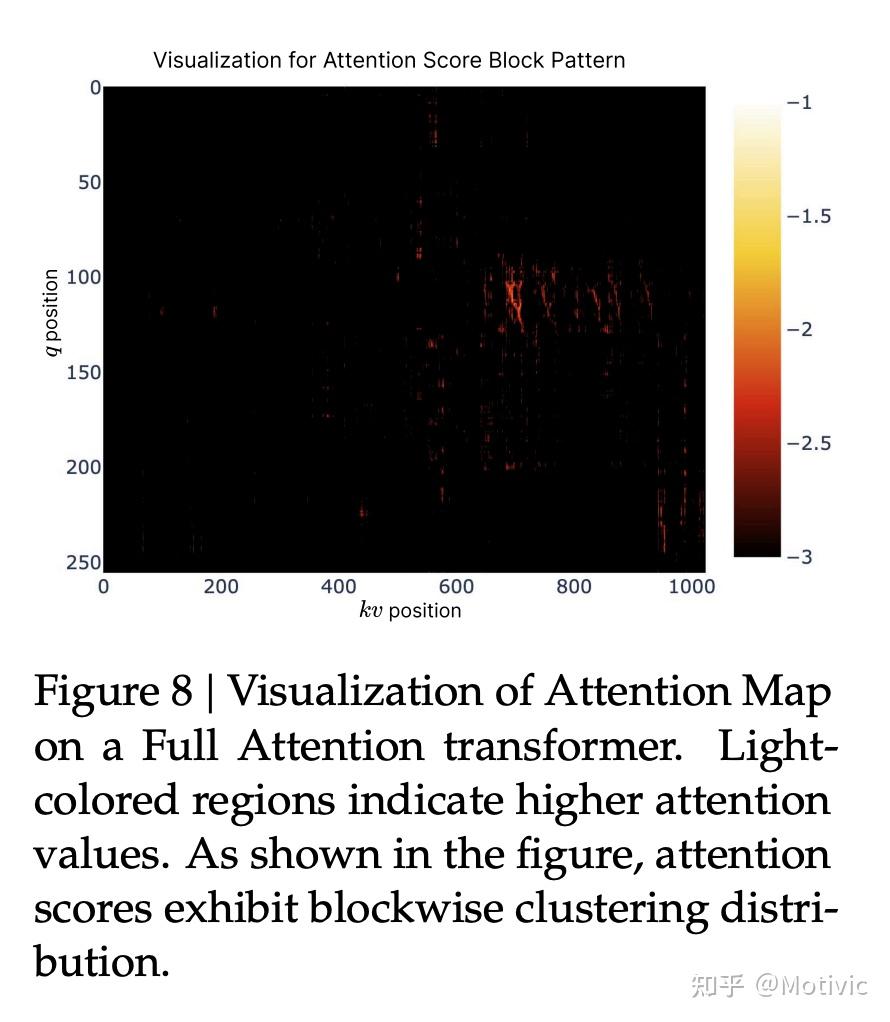
解读 | Native Sparse Attention:硬件对齐的稀疏注意力机制 - 知乎
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...

DeepSeek最新论文精读:【Native Sparse Attention 一种硬件对齐且可训练的稀疏注意力机制】-CSDN博客
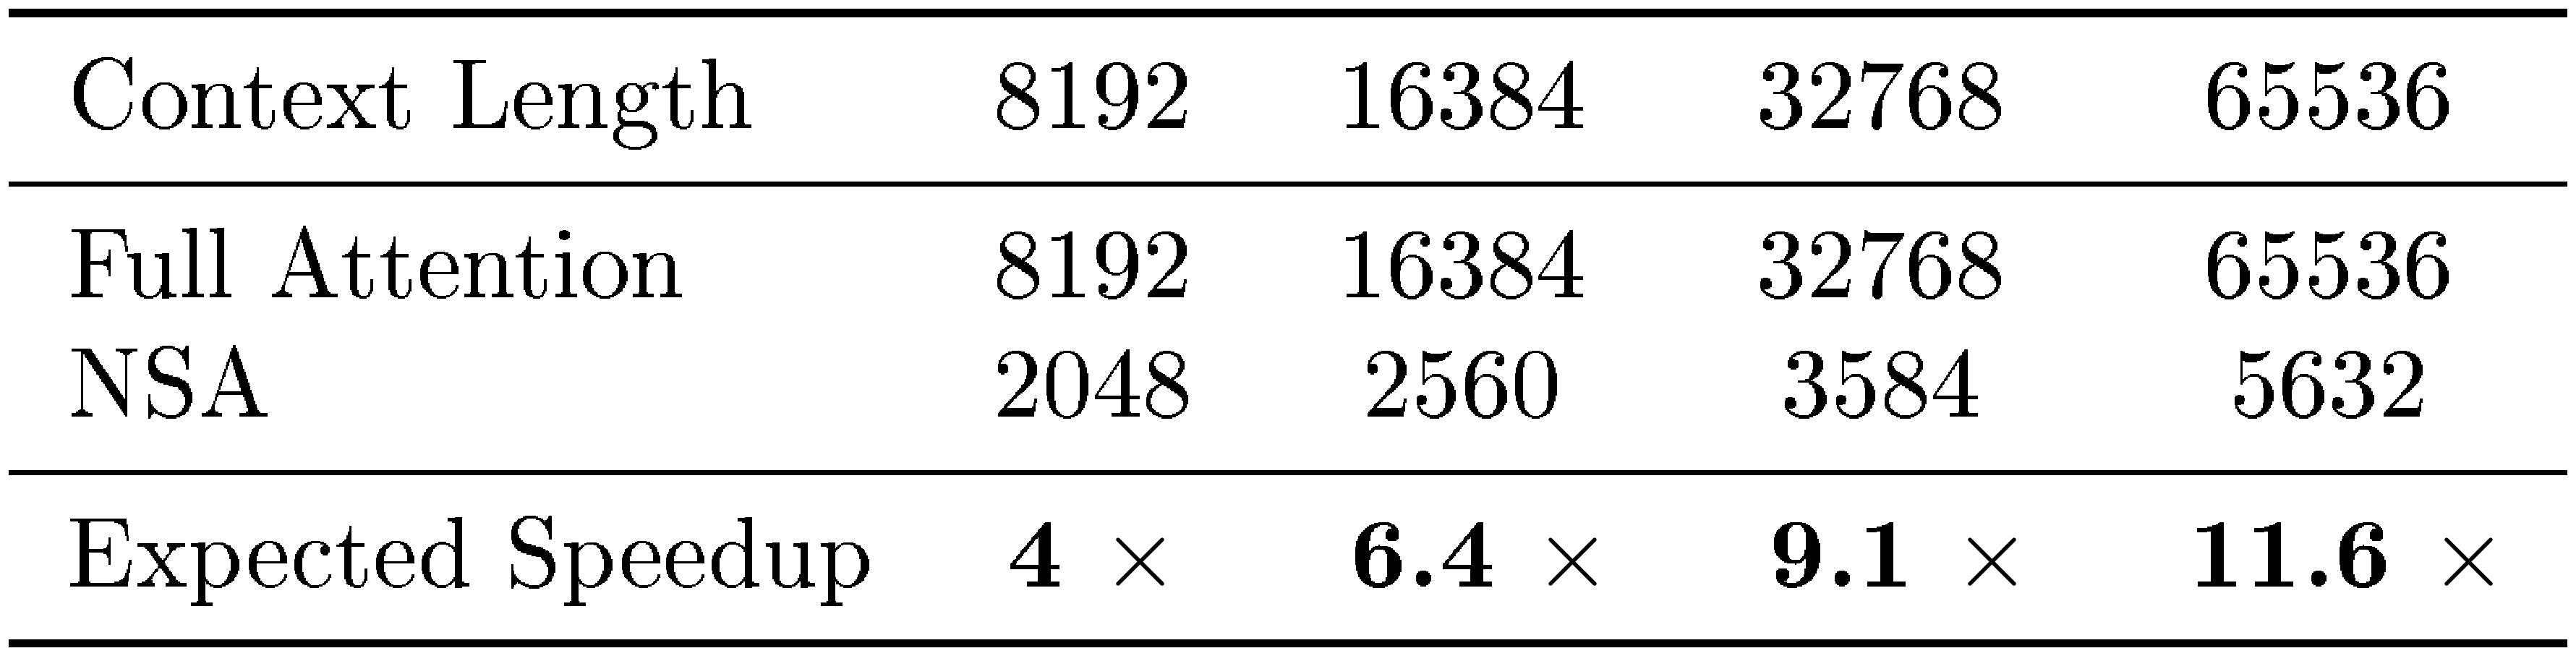
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
Advertisement Space (336x280)
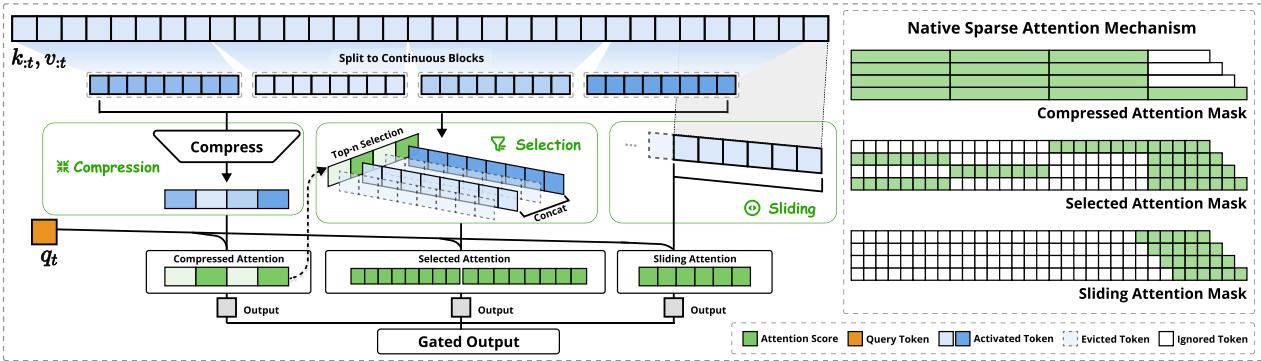
📄 Native Sparse Attention: Hardware-Aligned and Natively Trainable ...
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
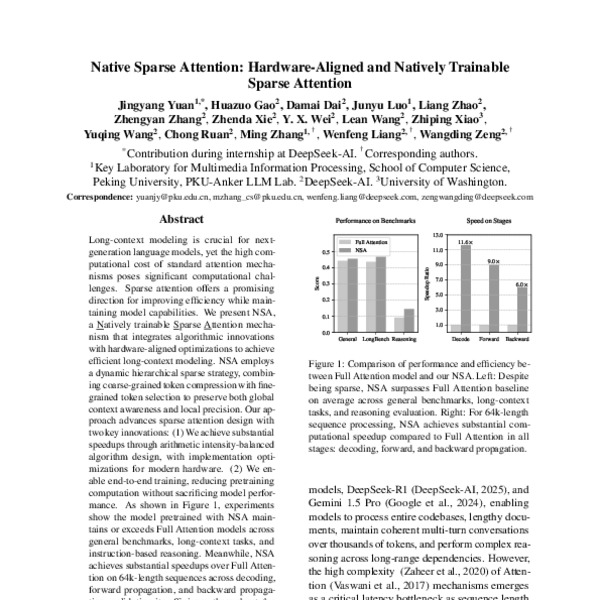
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
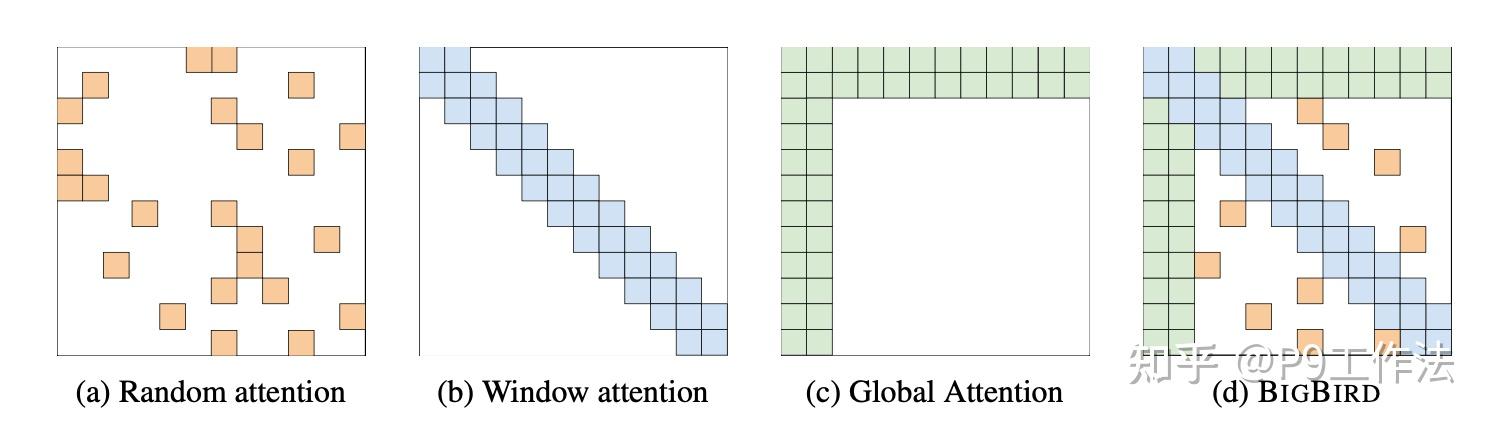
一文搞懂Native Sparse Attention - 知乎

[논문 리뷰] Native Sparse Attention: Hardware-Aligned and Natively ...
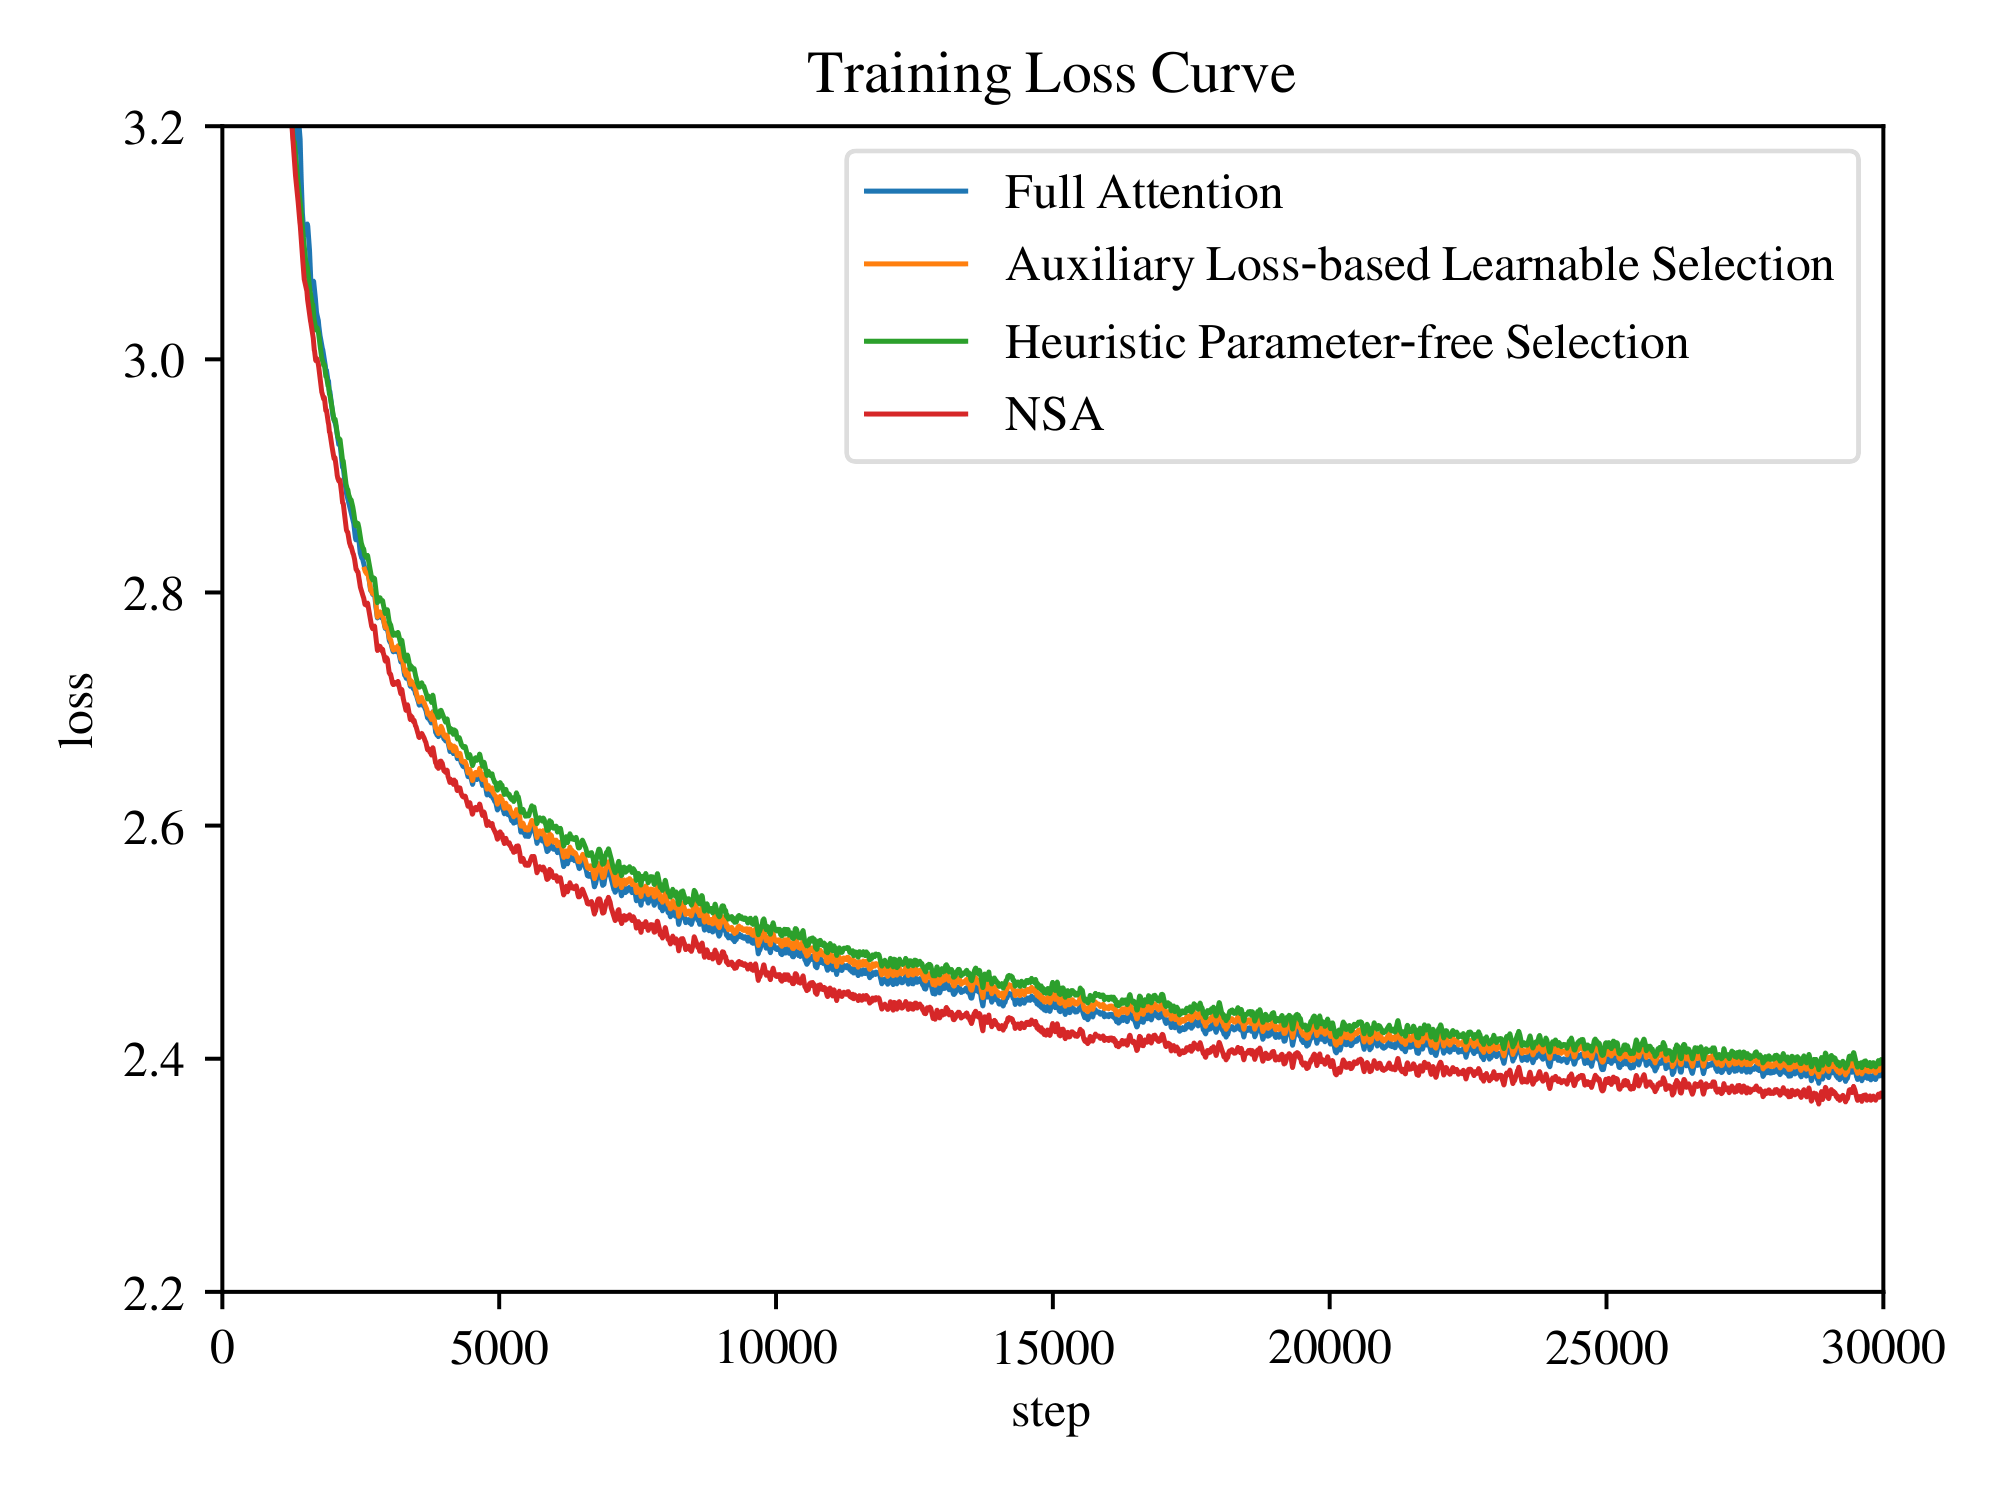
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...

DeepSeek最新论文精读:【Native Sparse Attention 一种硬件对齐且可训练的稀疏注意力机制】-CSDN博客

大语言模型处理长文本的新思路 - Native Sparse Attention让推理速度提升6倍 - YouTube
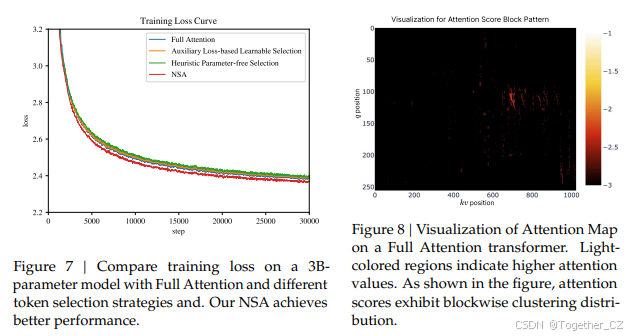
Native Sparse Attention: Hardware-Aligned and NativelyTrainable Sparse ...
Advertisement Space (336x280)

Sparse Attention — 왜 일부 토큰만 계산해도 문맥을 유지하는가 - Zero Math AI
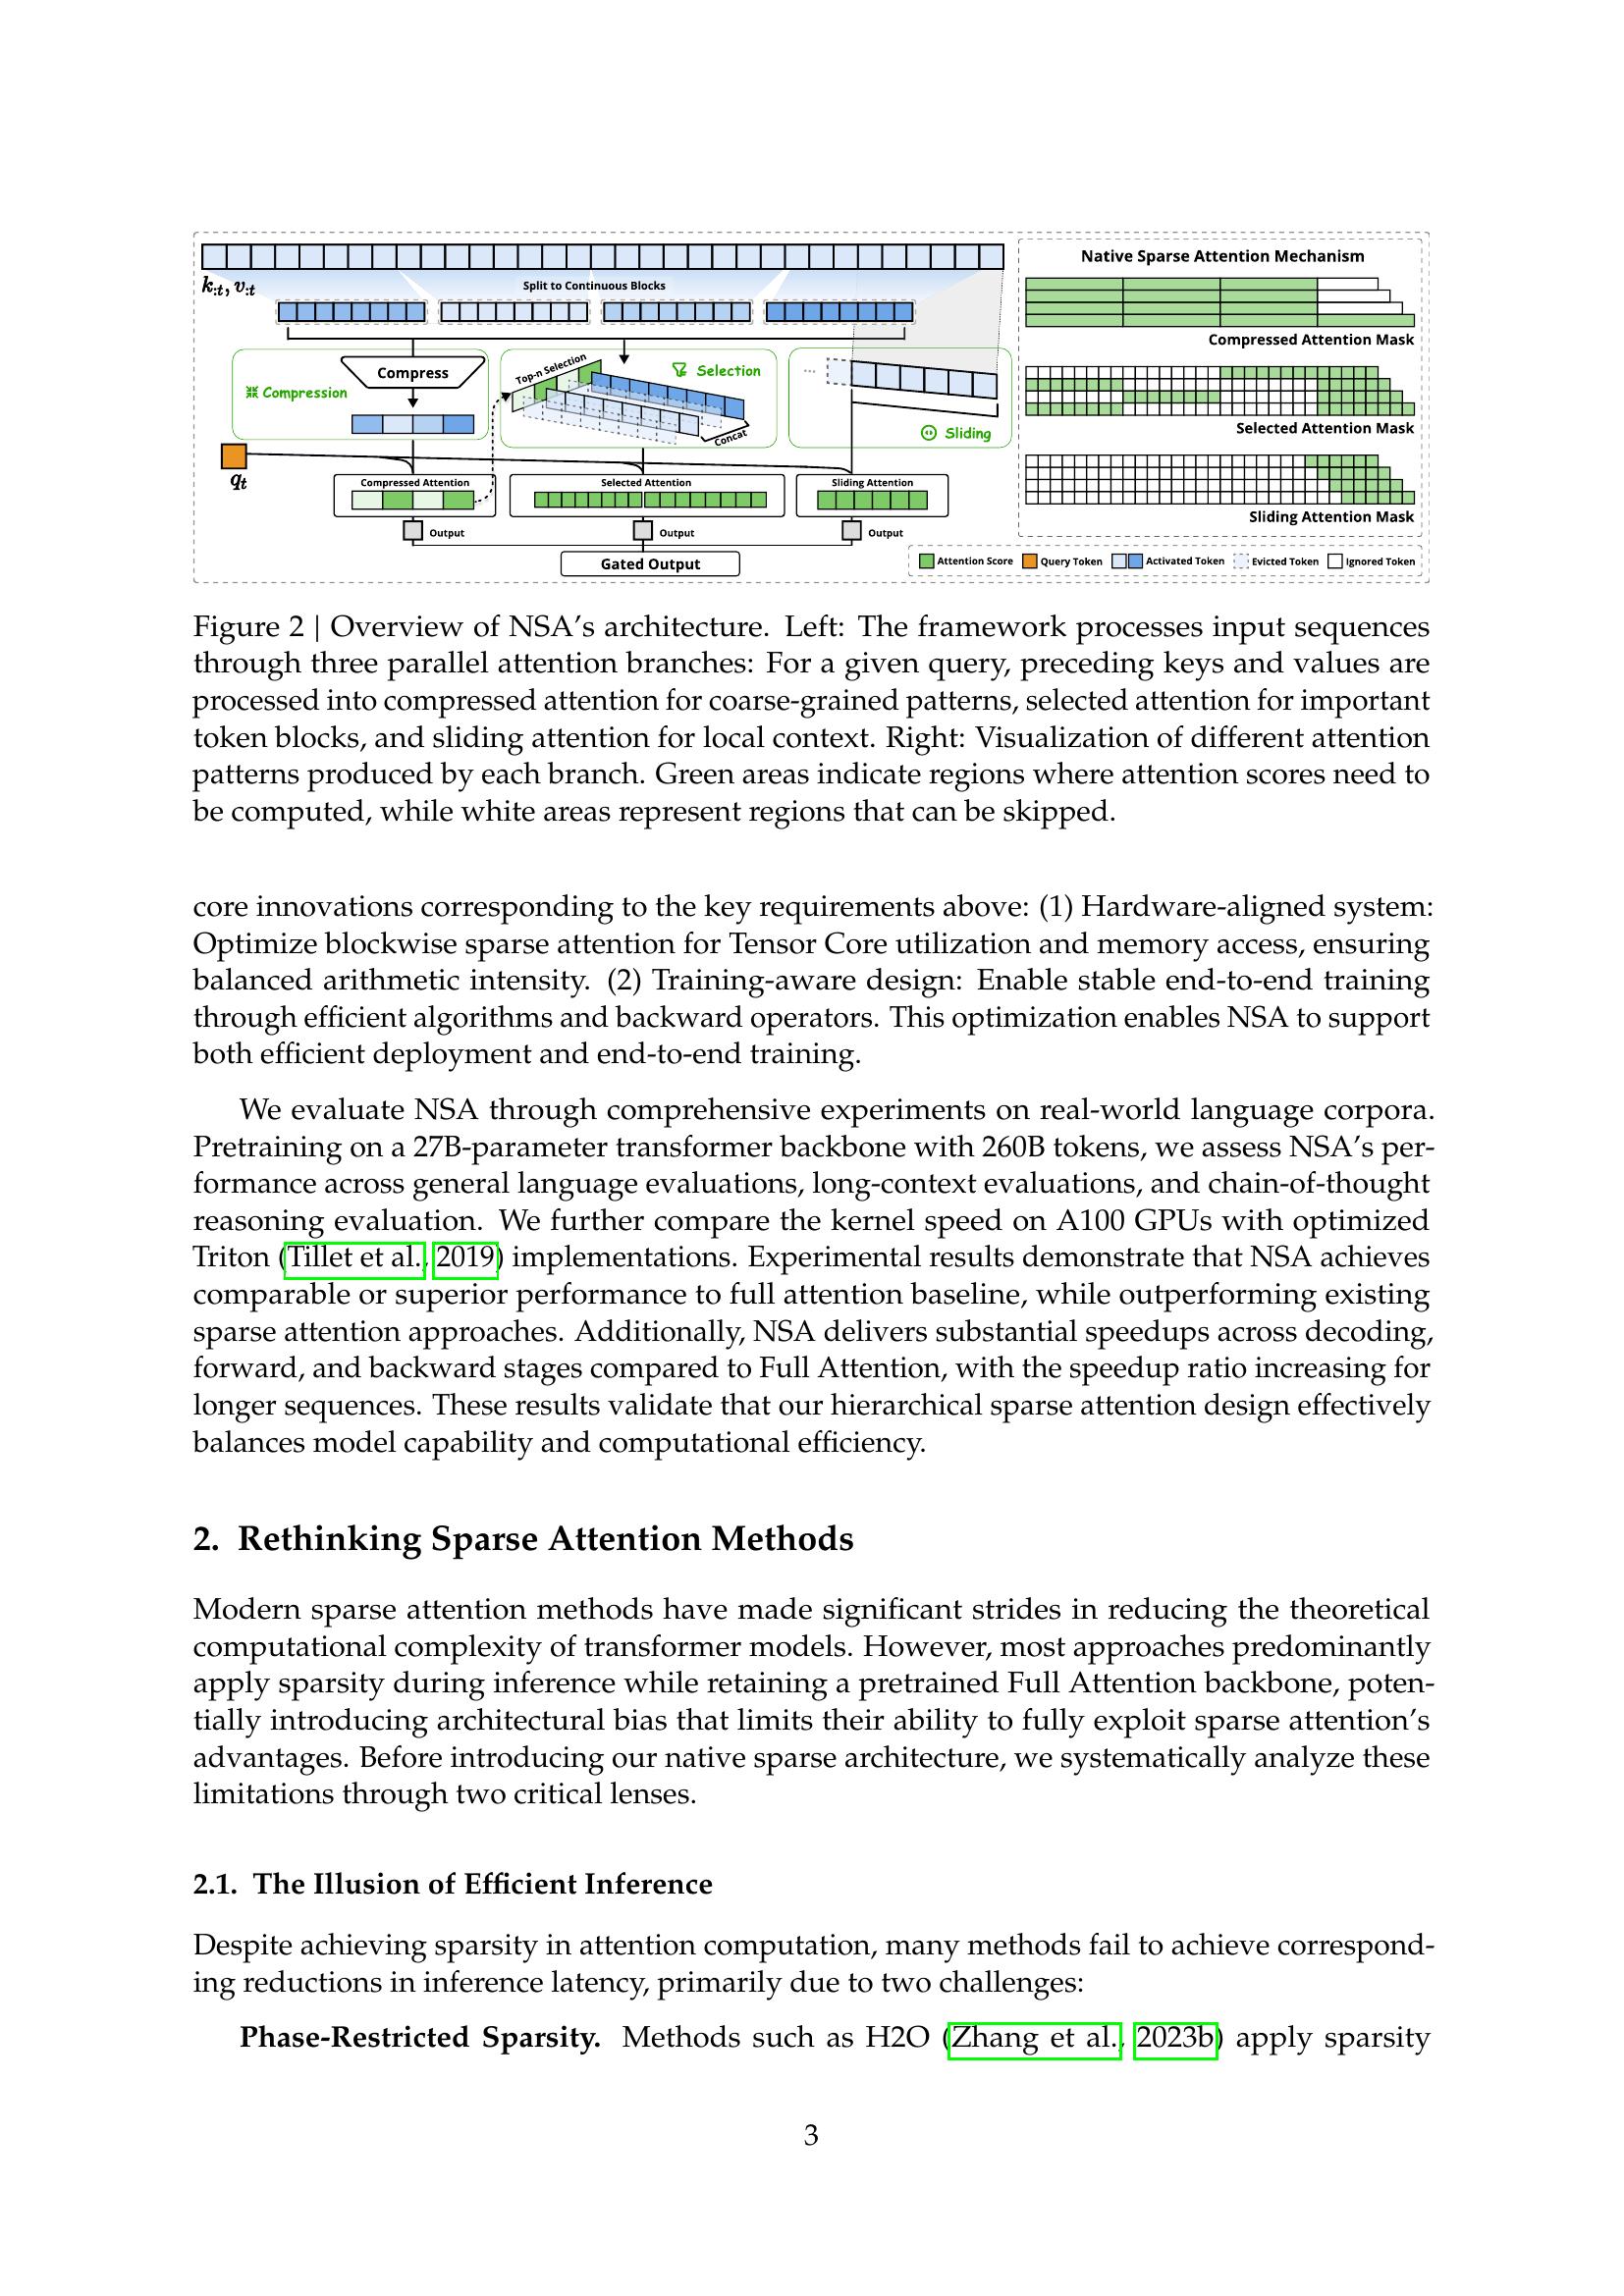
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
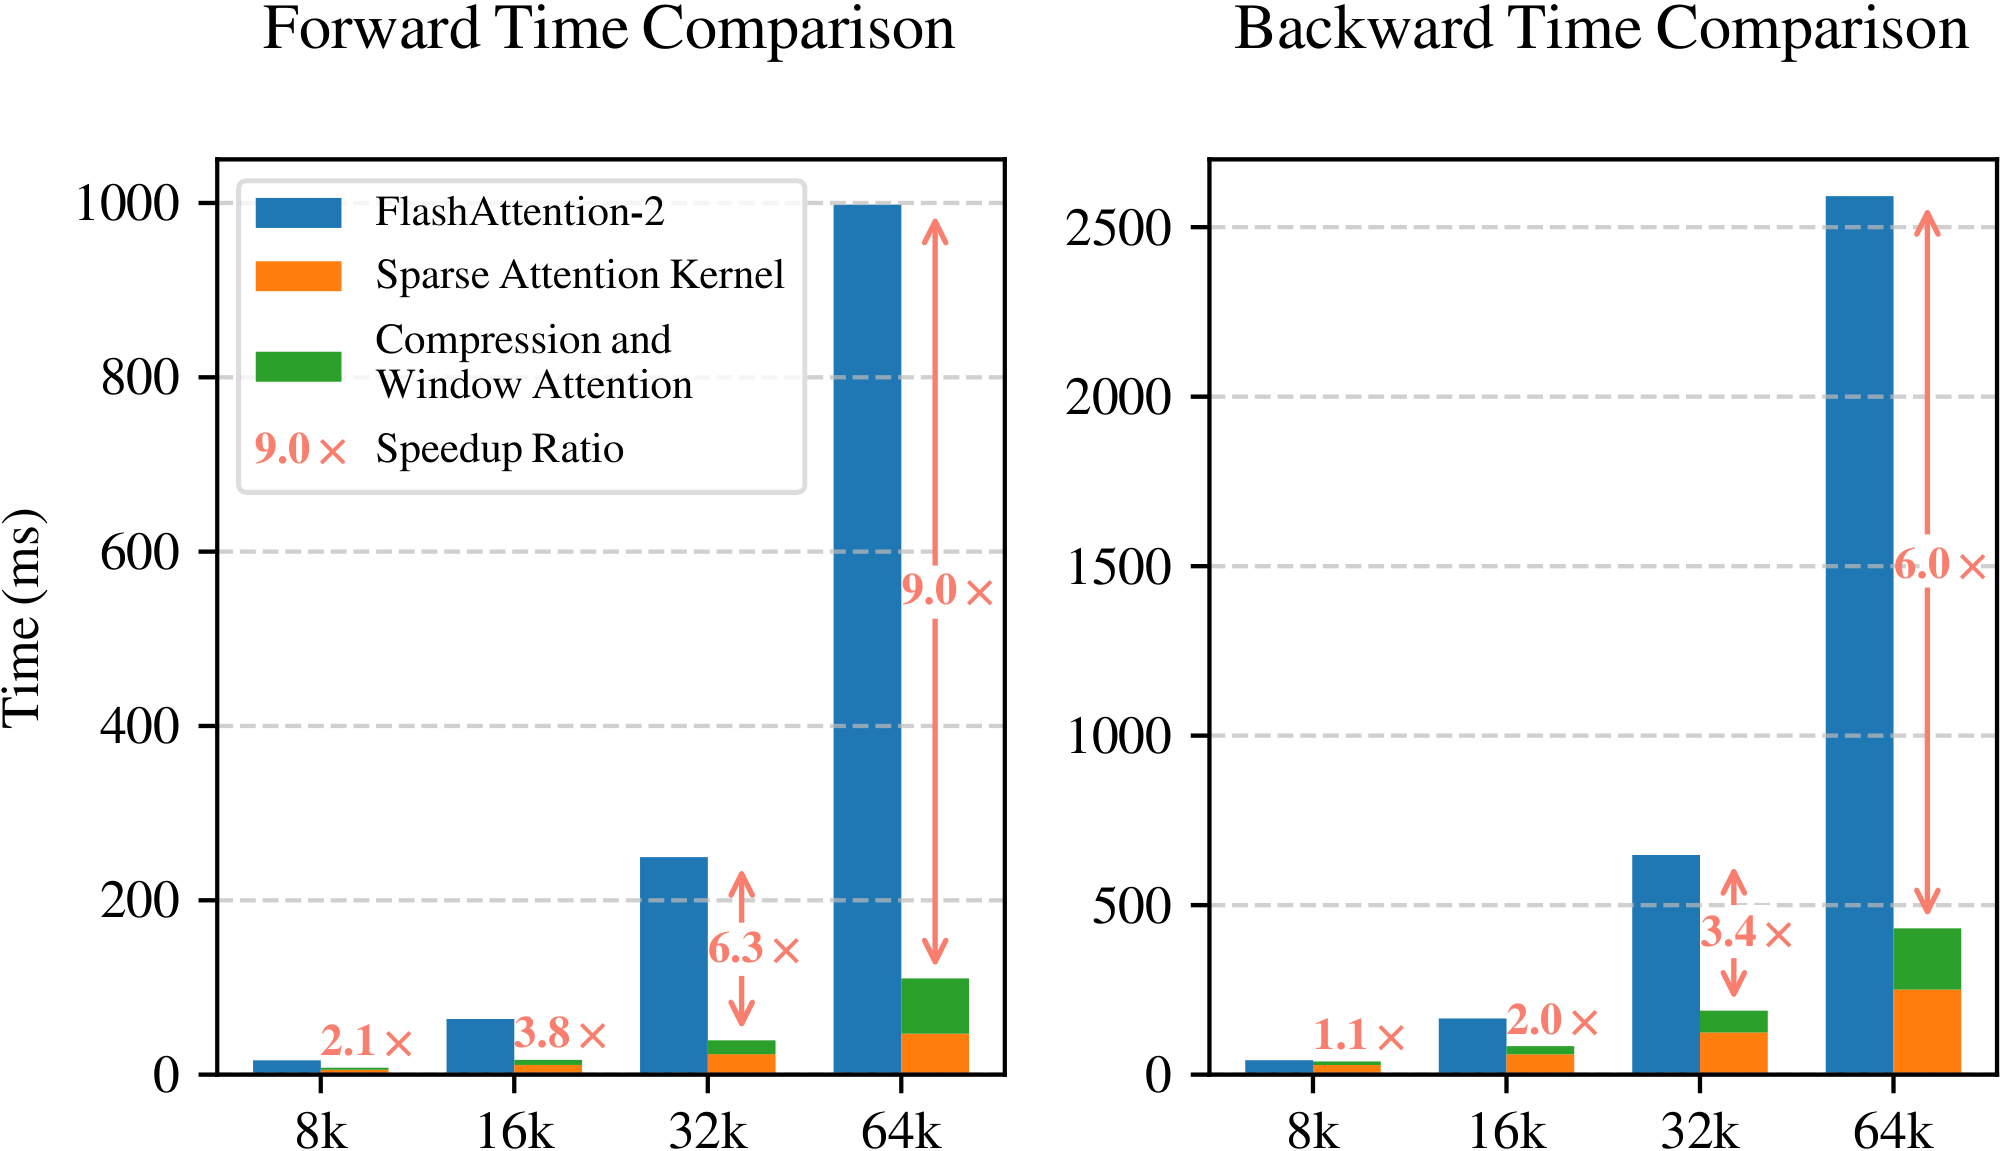
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse ...
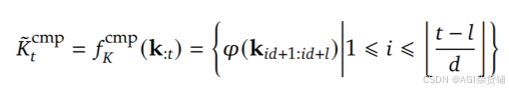
梁文峰署名的NSA 与 Kimi杨植麟署名的MoBA撞车,新注意力架构比拼_native sparse attention 实现-CSDN博客
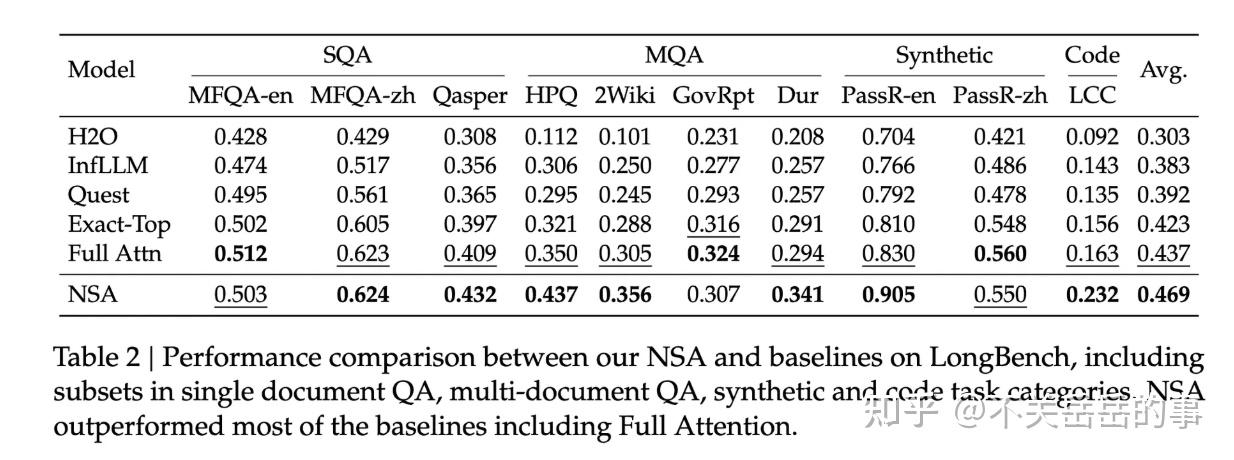
Native Sparse Attention的算法原理和Triton Kernel实现解读(一) - 知乎
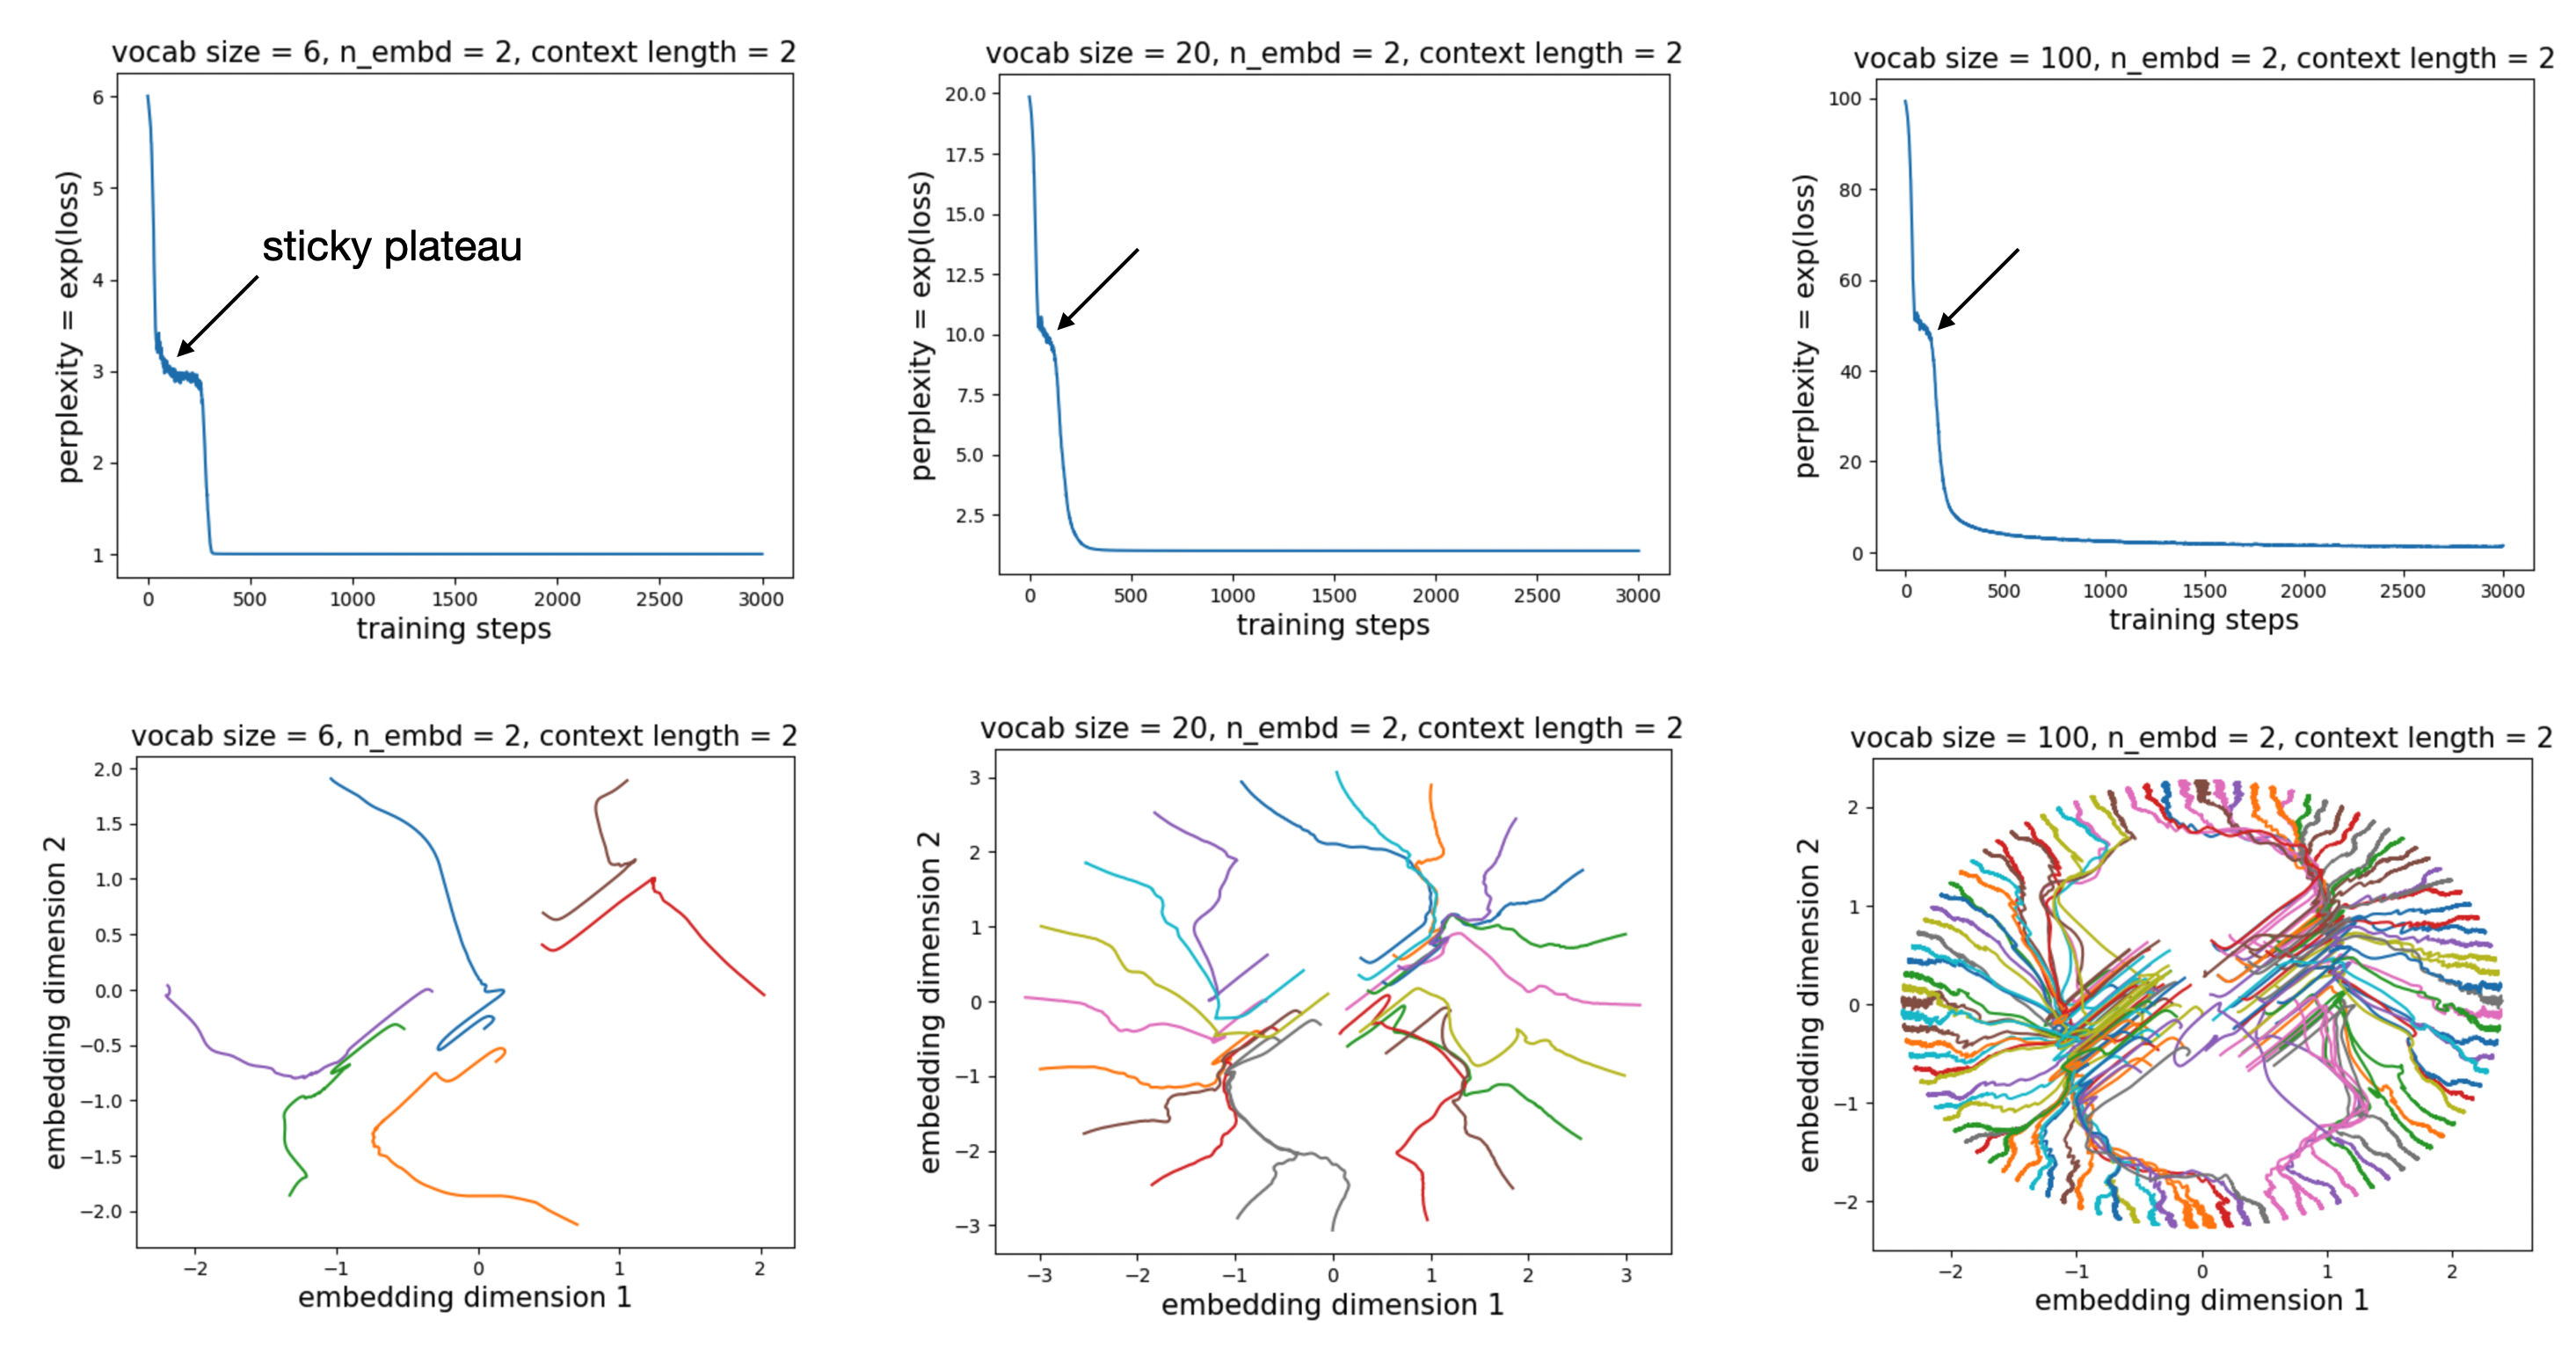
Sparse attention 2 -- Unattention head, branching dynamics | Ziming Liu