
Modular Max And Mojo On Gpu Cloud Deploy An Llm Inference Engine That
Modular MAX and Mojo on GPU Cloud: Deploy an LLM Inference Engine That ...
Deploy DeepSeek V4 on GPU Cloud: MoE Inference with vLLM and Expert ...
LLM Inference Router on GPU Cloud: Smart Model Routing for Cost and ...

Deploy MAX on GPU with self-hosted endpoints | Modular

Next-Gen GPU Programming: Hands-On with Mojo & MAX @ Modular HQ ...
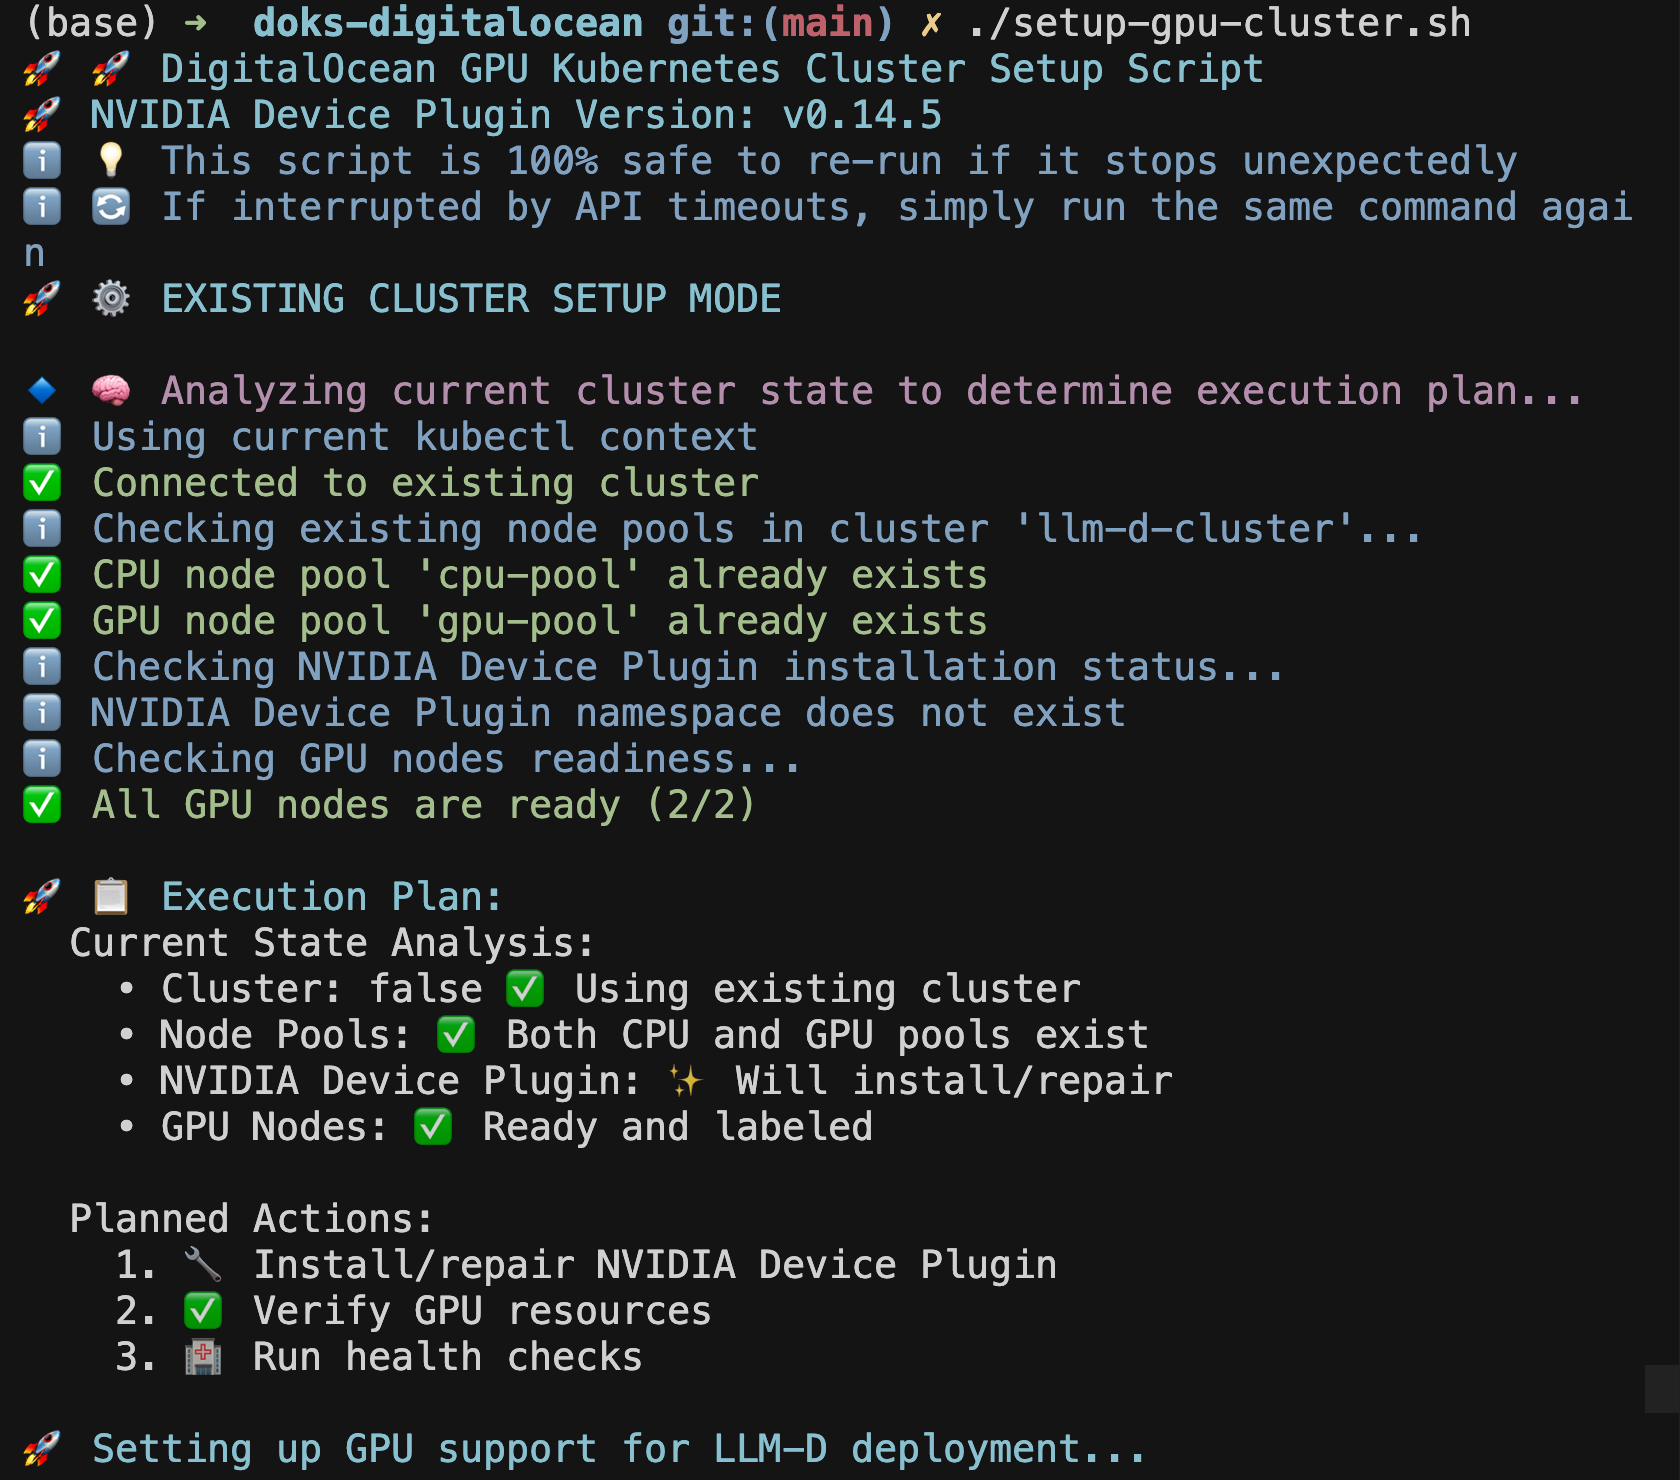
Deploy llm-d for Distributed LLM Inference on DigitalOcean Kubernetes ...

What is GPU Memory and Why it Matters for LLM Inference
Best LLM Inference Engines and Servers to Deploy LLMs in Production - Koyeb

Low-Latency LLM Inference on Multi-GPU Cloud Systems

vLLM Review: High-Performance LLM Inference Engine for GPU ...
Advertisement Space (300x250)
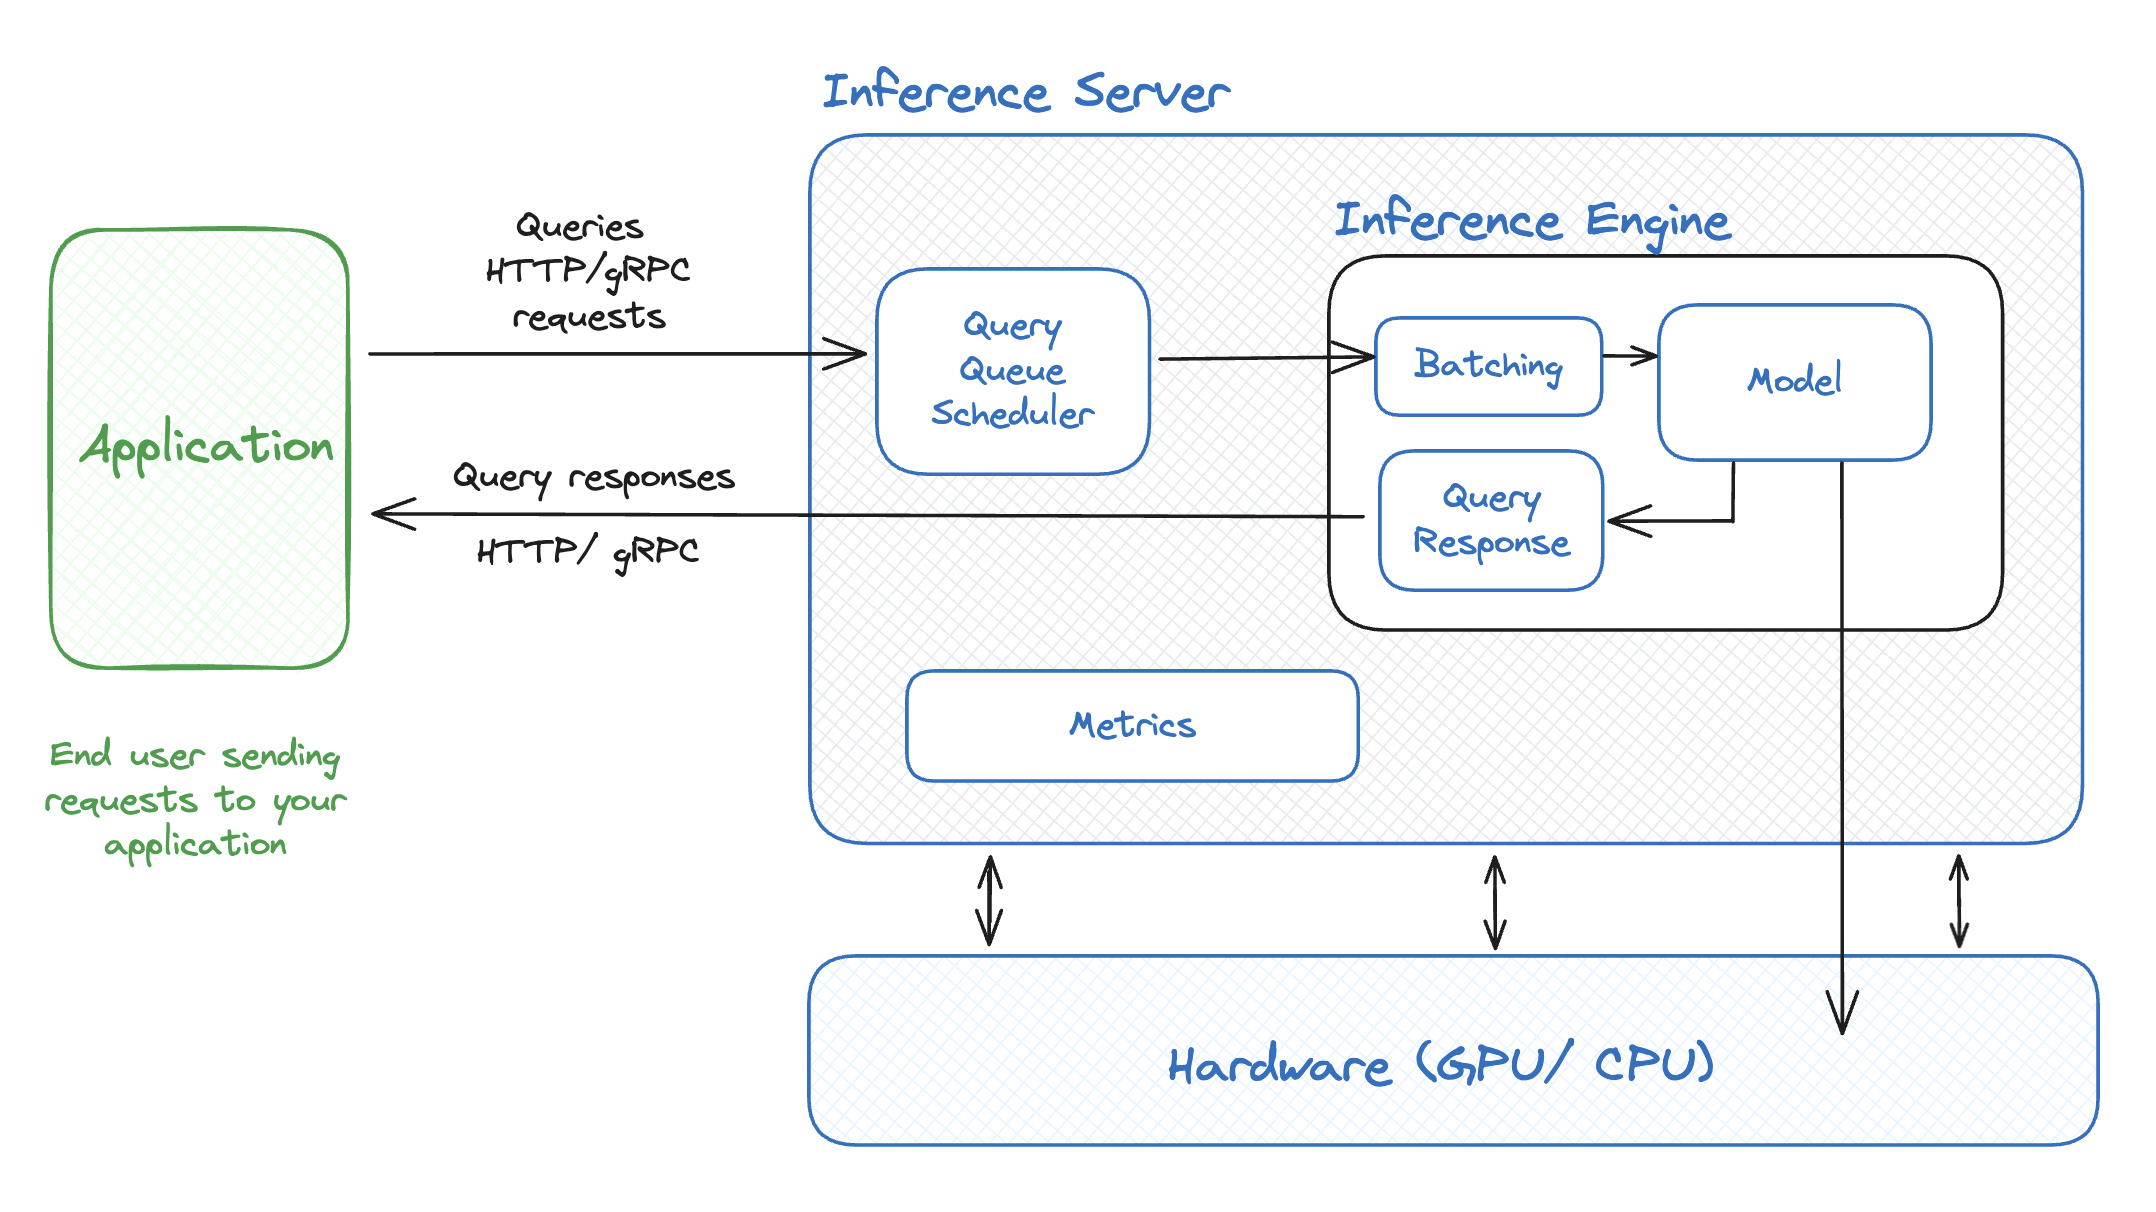
Best LLM Inference Engines and Servers to Deploy LLMs in Production - Koyeb
Deploy LMDeploy on GPU Cloud: TurboMind Inference for InternLM, Qwen3 ...

How to Deploy GPU-Powered AI Model LLM on Google Cloud Run - Geeky Gadgets
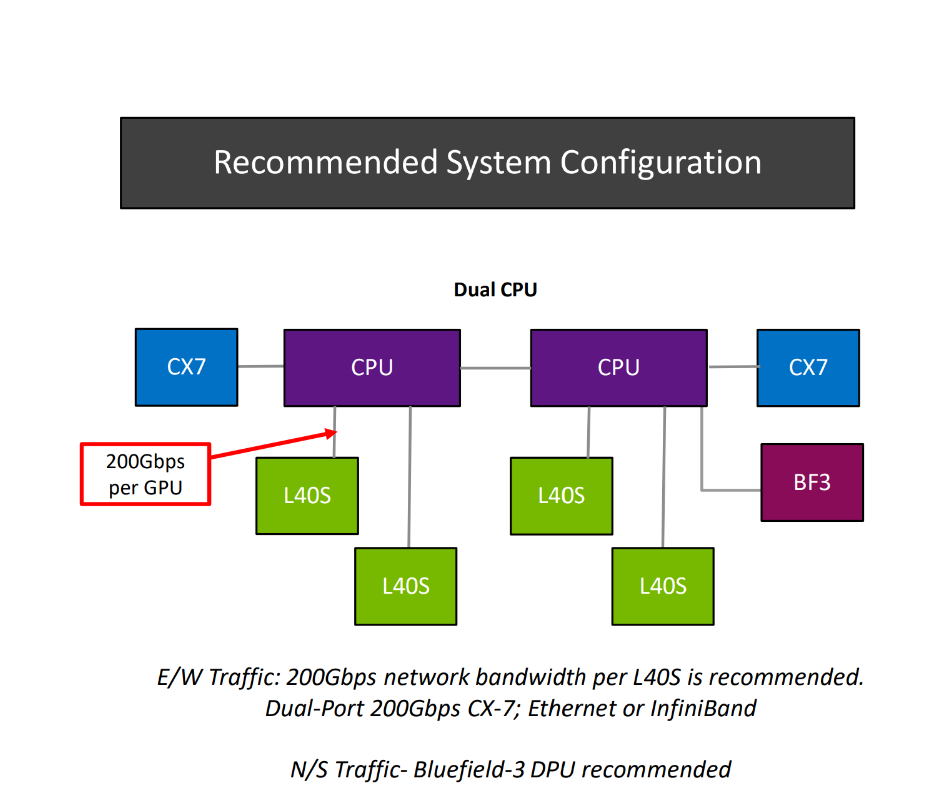
Choosing the Right GPU for LLM Inference and Training

AMD Developer Cloud Tutorial: Host Your First LLM on AMD GPU for AI ...

[论文评述] Characterizing and Optimizing LLM Inference Workloads on CPU-GPU ...
Deploy NVIDIA Dynamo for High-Performance LLM Inference on DigitalOcean ...

Next-Gen GPU Programming: Hands-On with Mojo & MAX @ Modular HQ · Luma ...
LLM Inference On-Premise vs GPU Cloud: 2026 Cost and Break-Even ...

GitHub - modular/modular: The Modular Platform (includes MAX & Mojo ...
Advertisement Space (336x280)
Deploy GLM-5.1 on GPU Cloud: Self-Host the 754B MoE Model (2026 Guide ...

Free Video: LLMOps: Accelerate LLM Inference in GPU Using TensorRT-LLM ...
LLM Inference - NVIDIA RTX GPU Performance | Puget Systems

LLM Inference - Consumer GPU performance | Puget Systems
Does GPU Cloud is suitable for deploying LLM or only for training? - Runpod
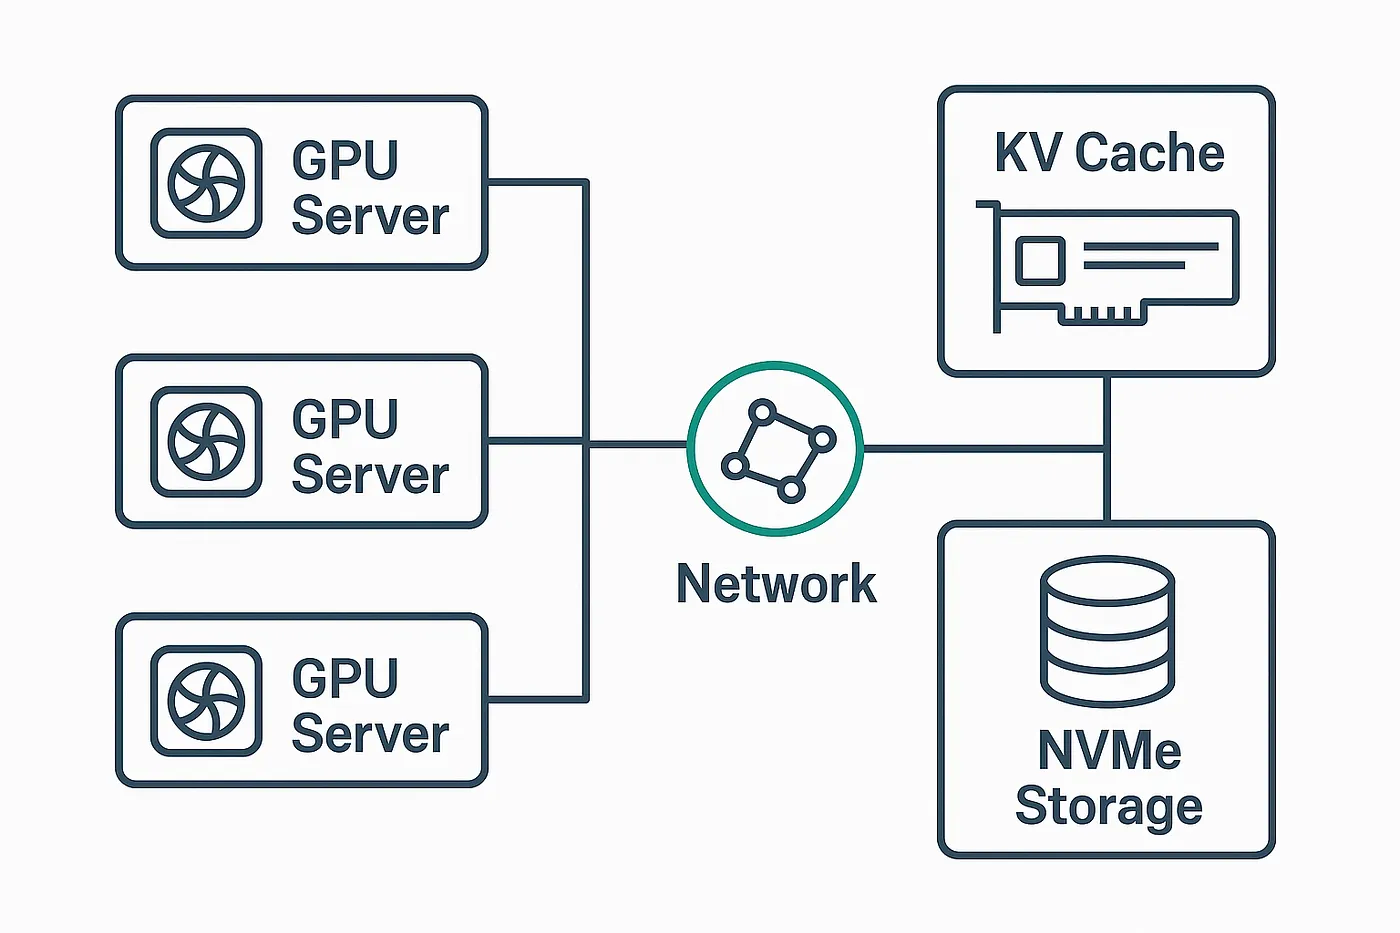
How to Give Your RTX GPU Nearly Infinite Memory for LLM Inference
Ray Serve on GPU Cloud: Production LLM Serving Guide (2026) | Spheron Blog
Deploy easily your LLM with Serverless GPU - avec @jlandure - YouTube
Deploy MiMo-V2-Flash on GPU Cloud: Xiaomi's 309B MoE Model Setup Guide ...
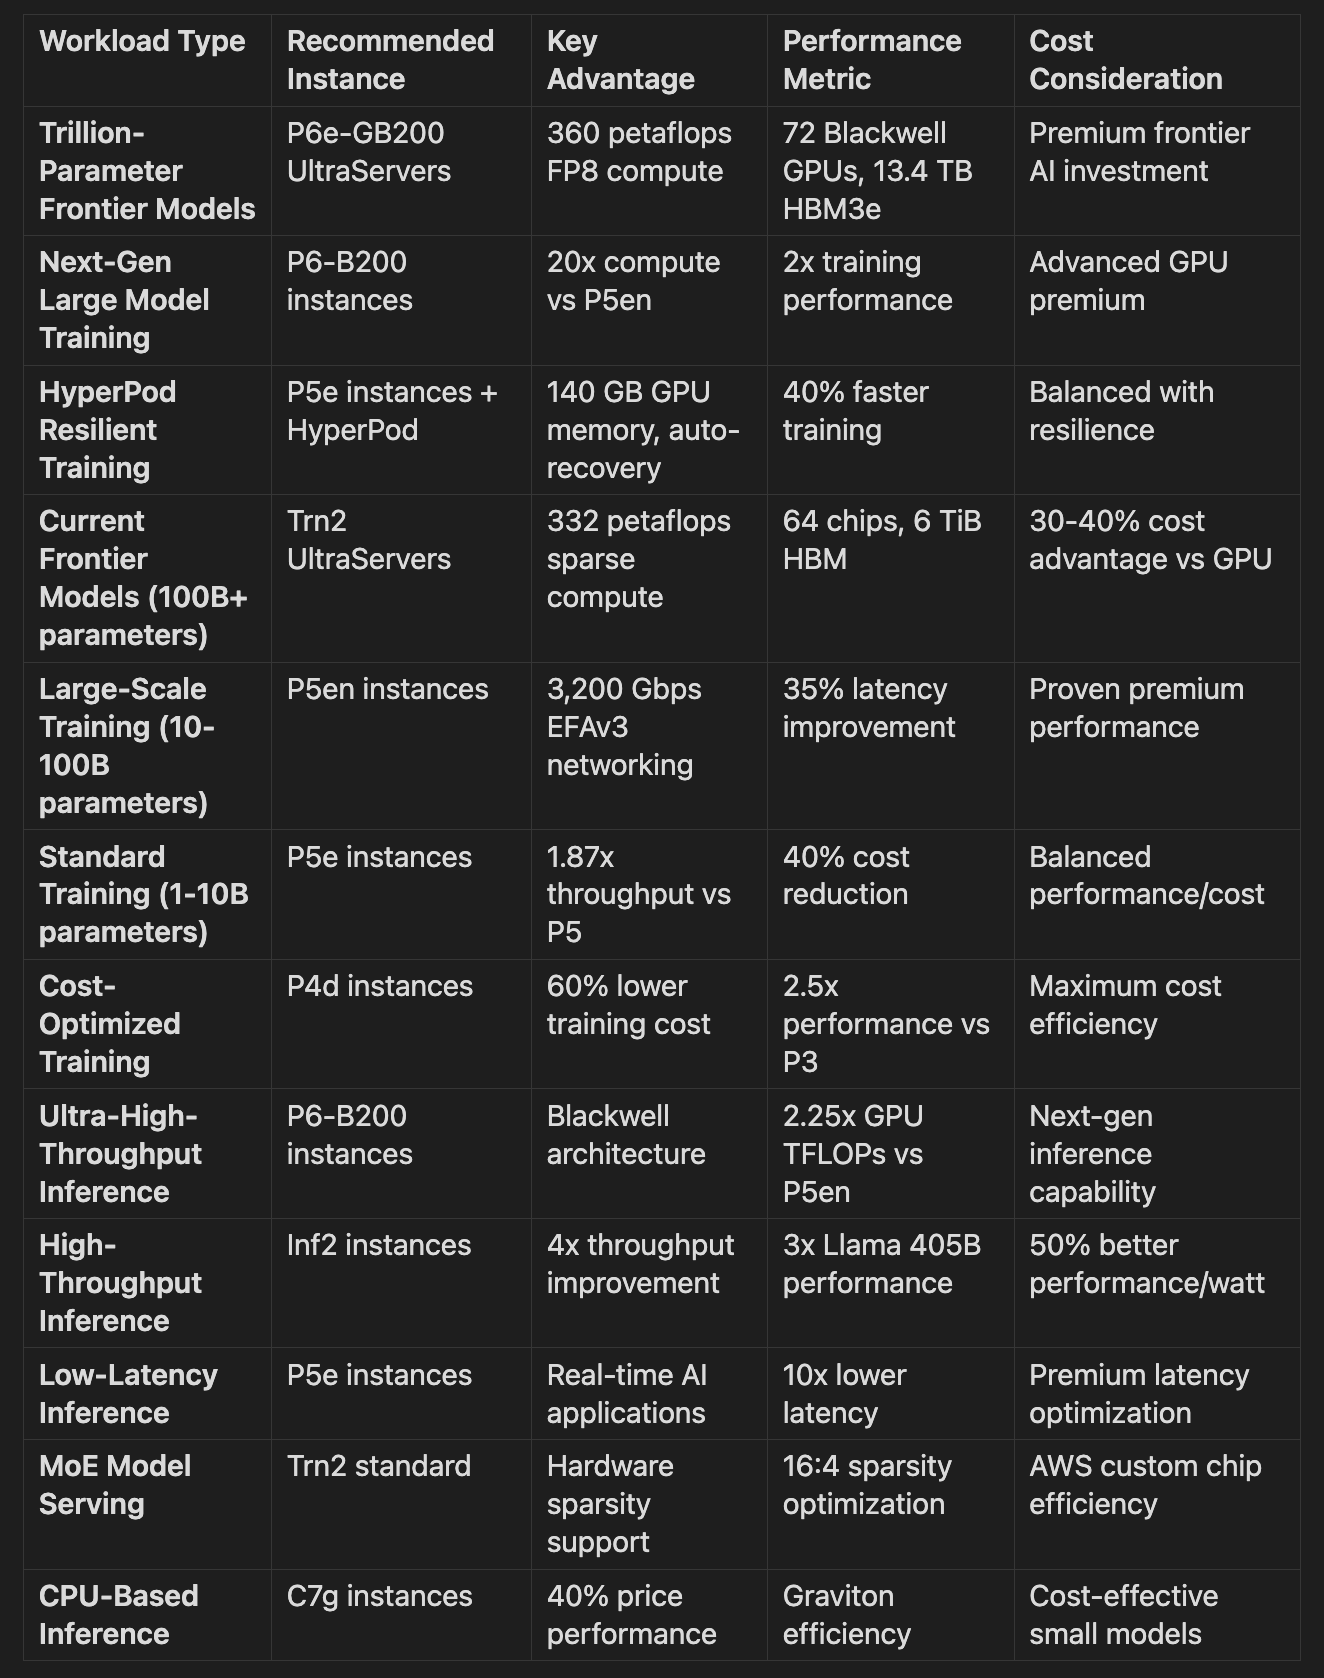
Analysis of LLM Architectures and AWS for Training and Inference Pipelines
Advertisement Space (336x280)
High-Performance LLM Infrastructure with Kubernetes and vLLM on Private ...
Why LLM Inference Wastes So Much GPU Power | Yotta Labs

Efficiently Scale LLM Training Across a Large GPU Cluster with Alpa and ...
Top Benefits of Using GPU Cloud for Training LLM Models
Deploy Large Language Models on GPU - Float16 Learn

Modular MAX vs vLLM Performance Comparison on Vast.ai