
Near Lossless Acceleration Of Long Context Llm Inference With Adaptive

Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...
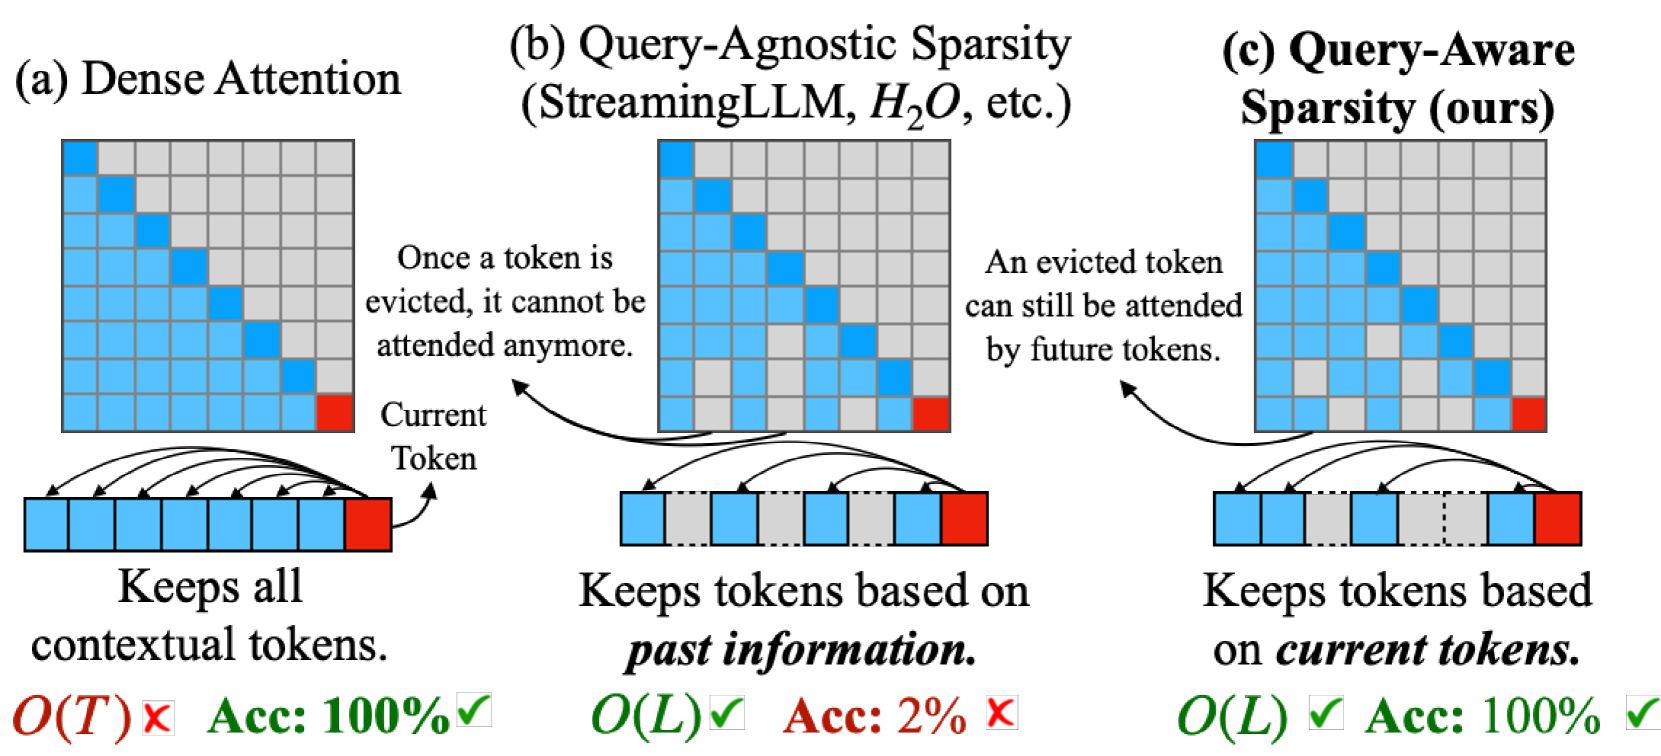
Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...
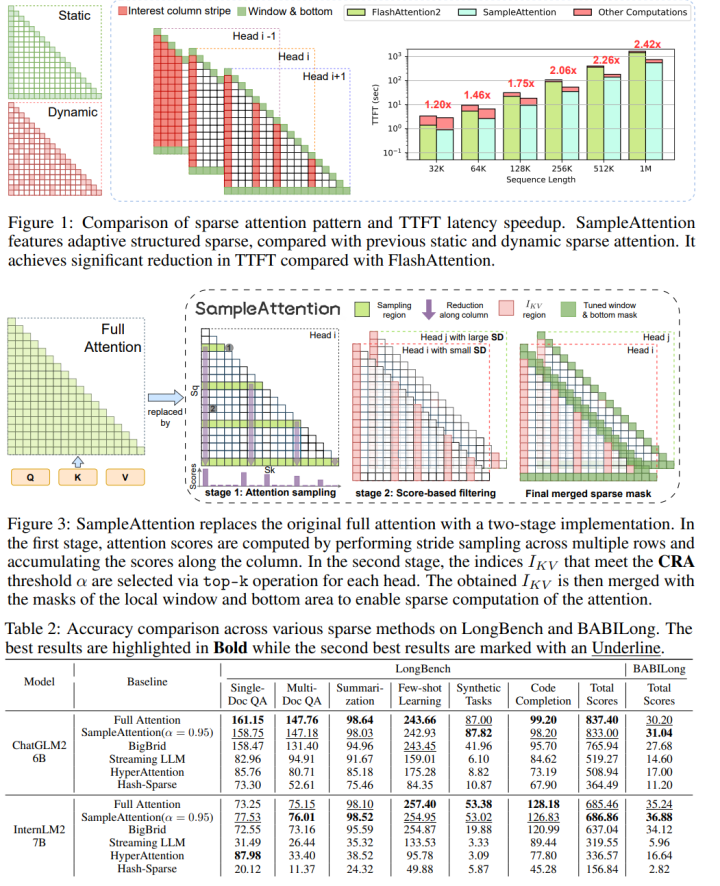
Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...

Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...

Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...

SampleAttention: Near-Lossless Acceleration of Long Context LLM ...
Lossless LLM inference acceleration with Speculators | Sebae Videos

Inference with Reference: Lossless Acceleration of Large Language Models

(PDF) Inference with Reference: Lossless Acceleration of Large Language ...

Inference with Reference: Lossless Acceleration of Large Language Models
Advertisement Space (300x250)

Squeezed Attention: Accelerating Long Context Length LLM Inference ...

EAGLE: Lossless Acceleration of LLM Decoding by Feature Extrapolation ...
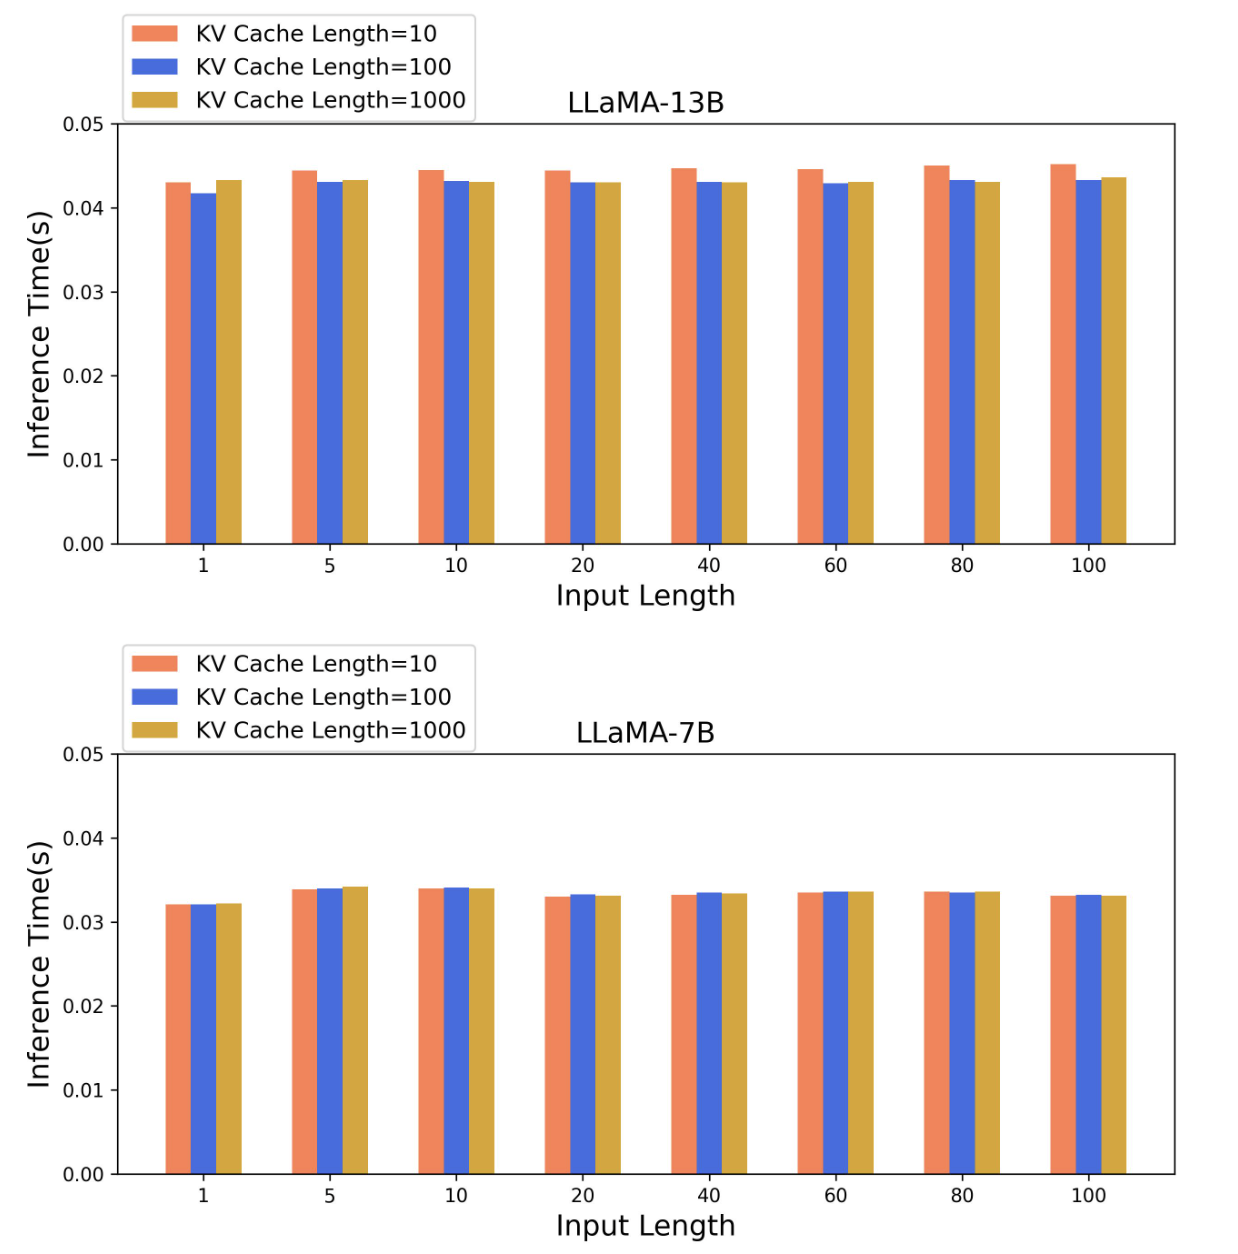
Lossless Acceleration of Large Language Model via Adaptive N-gram ...

Paper page - Medusa: Simple LLM Inference Acceleration Framework with ...

LoopServe: An Adaptive Dual-phase LLM Inference Acceleration System for ...

(PDF) Accelerating LLM Inference with Lossless Speculative Decoding ...

Figure 1 from Medusa: Simple LLM Inference Acceleration Framework with ...
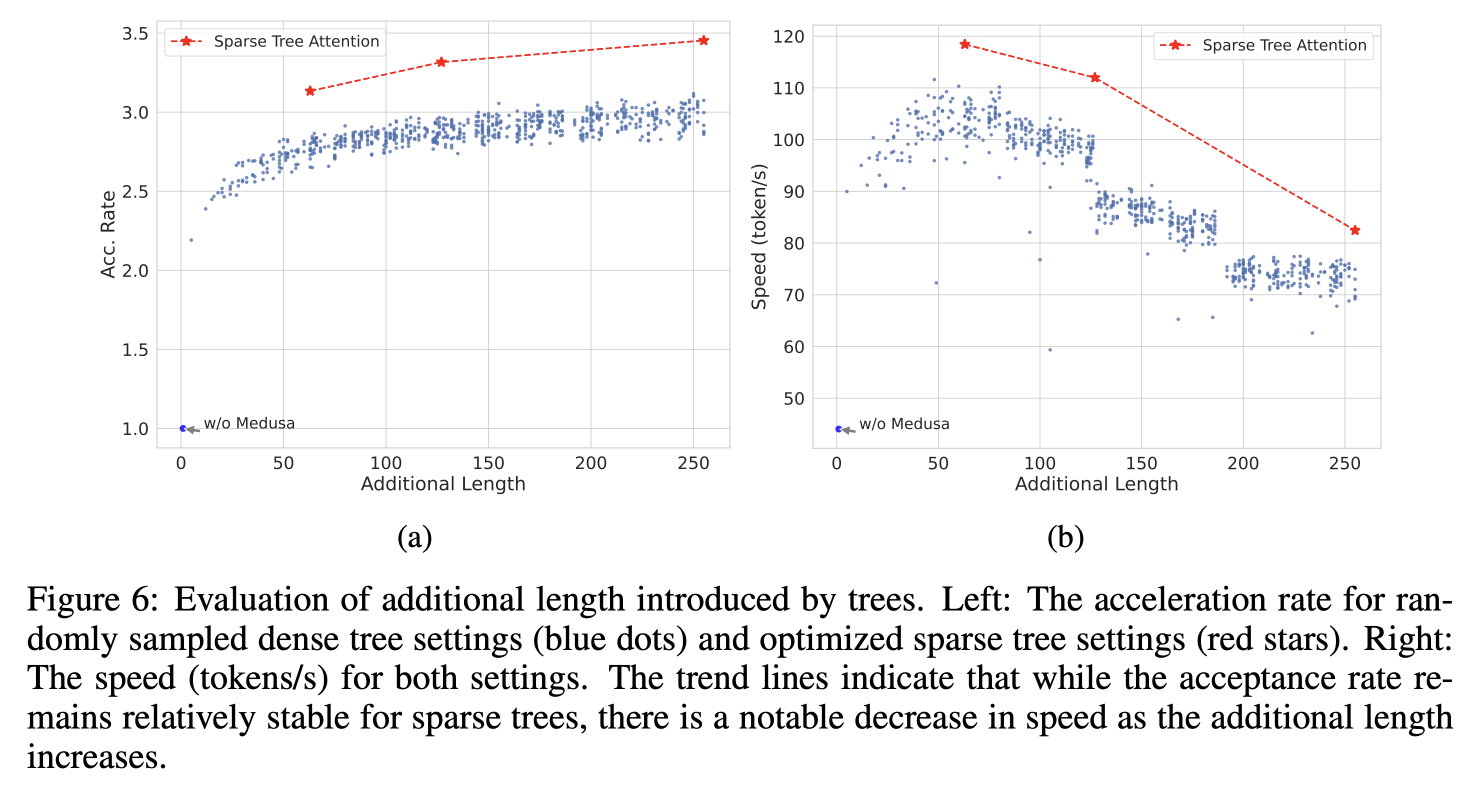
[paper review] MEDUSA: Simple LLM Inference Acceleration Framework with ...

LLM Inference: Accelerating Long Context Generation with KV Cache ...
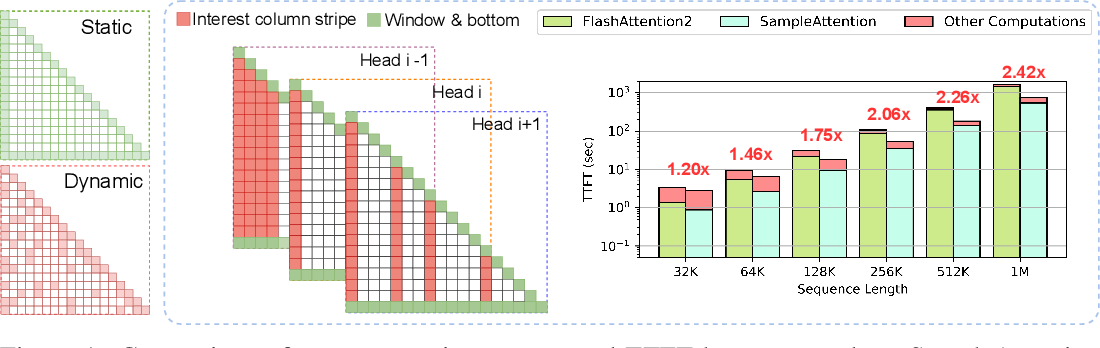
Figure 1 from SampleAttention: Near-Lossless Acceleration of Long ...
Advertisement Space (336x280)

[Literature Review] SampleAttention: Near-Lossless Acceleration of Long ...

Paper page - SampleAttention: Near-Lossless Acceleration of Long ...

[论文评述] Breaking the Boundaries of Long-Context LLM Inference: Adaptive ...

Figure 1 from QoS-Aware Inference Acceleration Using Adaptive Depth ...

Table 1 from SampleAttention: Near-Lossless Acceleration of Long ...

LLM Inference Acceleration via Efficient Operation Fusion | AI Research ...

Star Attention: Efficient LLM Inference over Long Sequences | AI ...

Wider or Deeper? Scaling LLM Inference-Time Compute with Adaptive ...
LLM Inference Acceleration | Inference Engineering

Paper page - Accelerating LLM Inference with Staged Speculative Decoding
Advertisement Space (336x280)

(PDF) Context Adaptive Lossless and Near-Lossless Coding for Digital ...
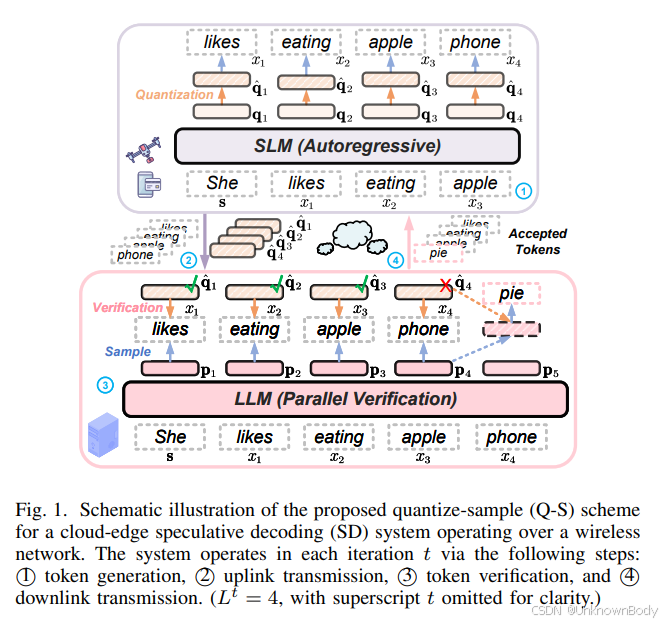
Quantize-Sample-and-Verify: LLM Acceleration via Adaptive Edge-Cloud ...
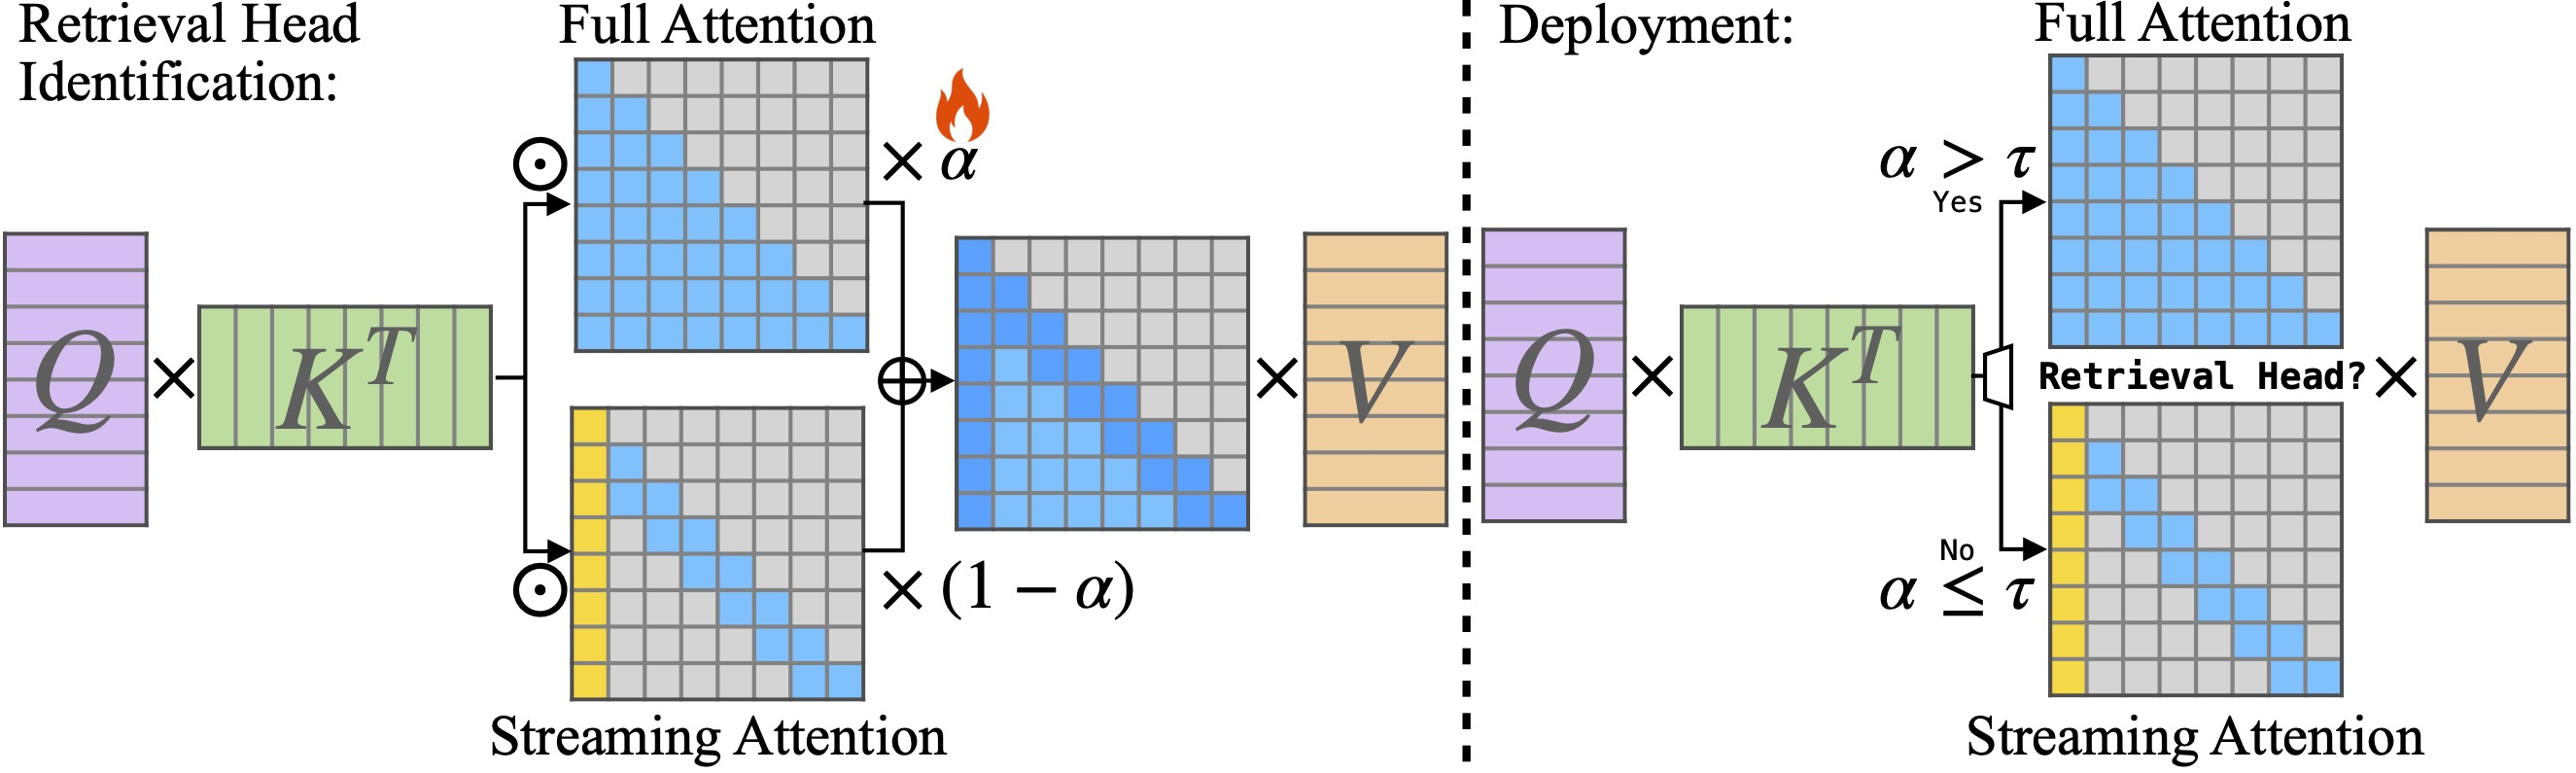
DuoAttention: Efficient Long-Context LLM Inference with Retrieval and ...

Accelerating Long-Context LLM Inference Eightfold with FlashAttention ...
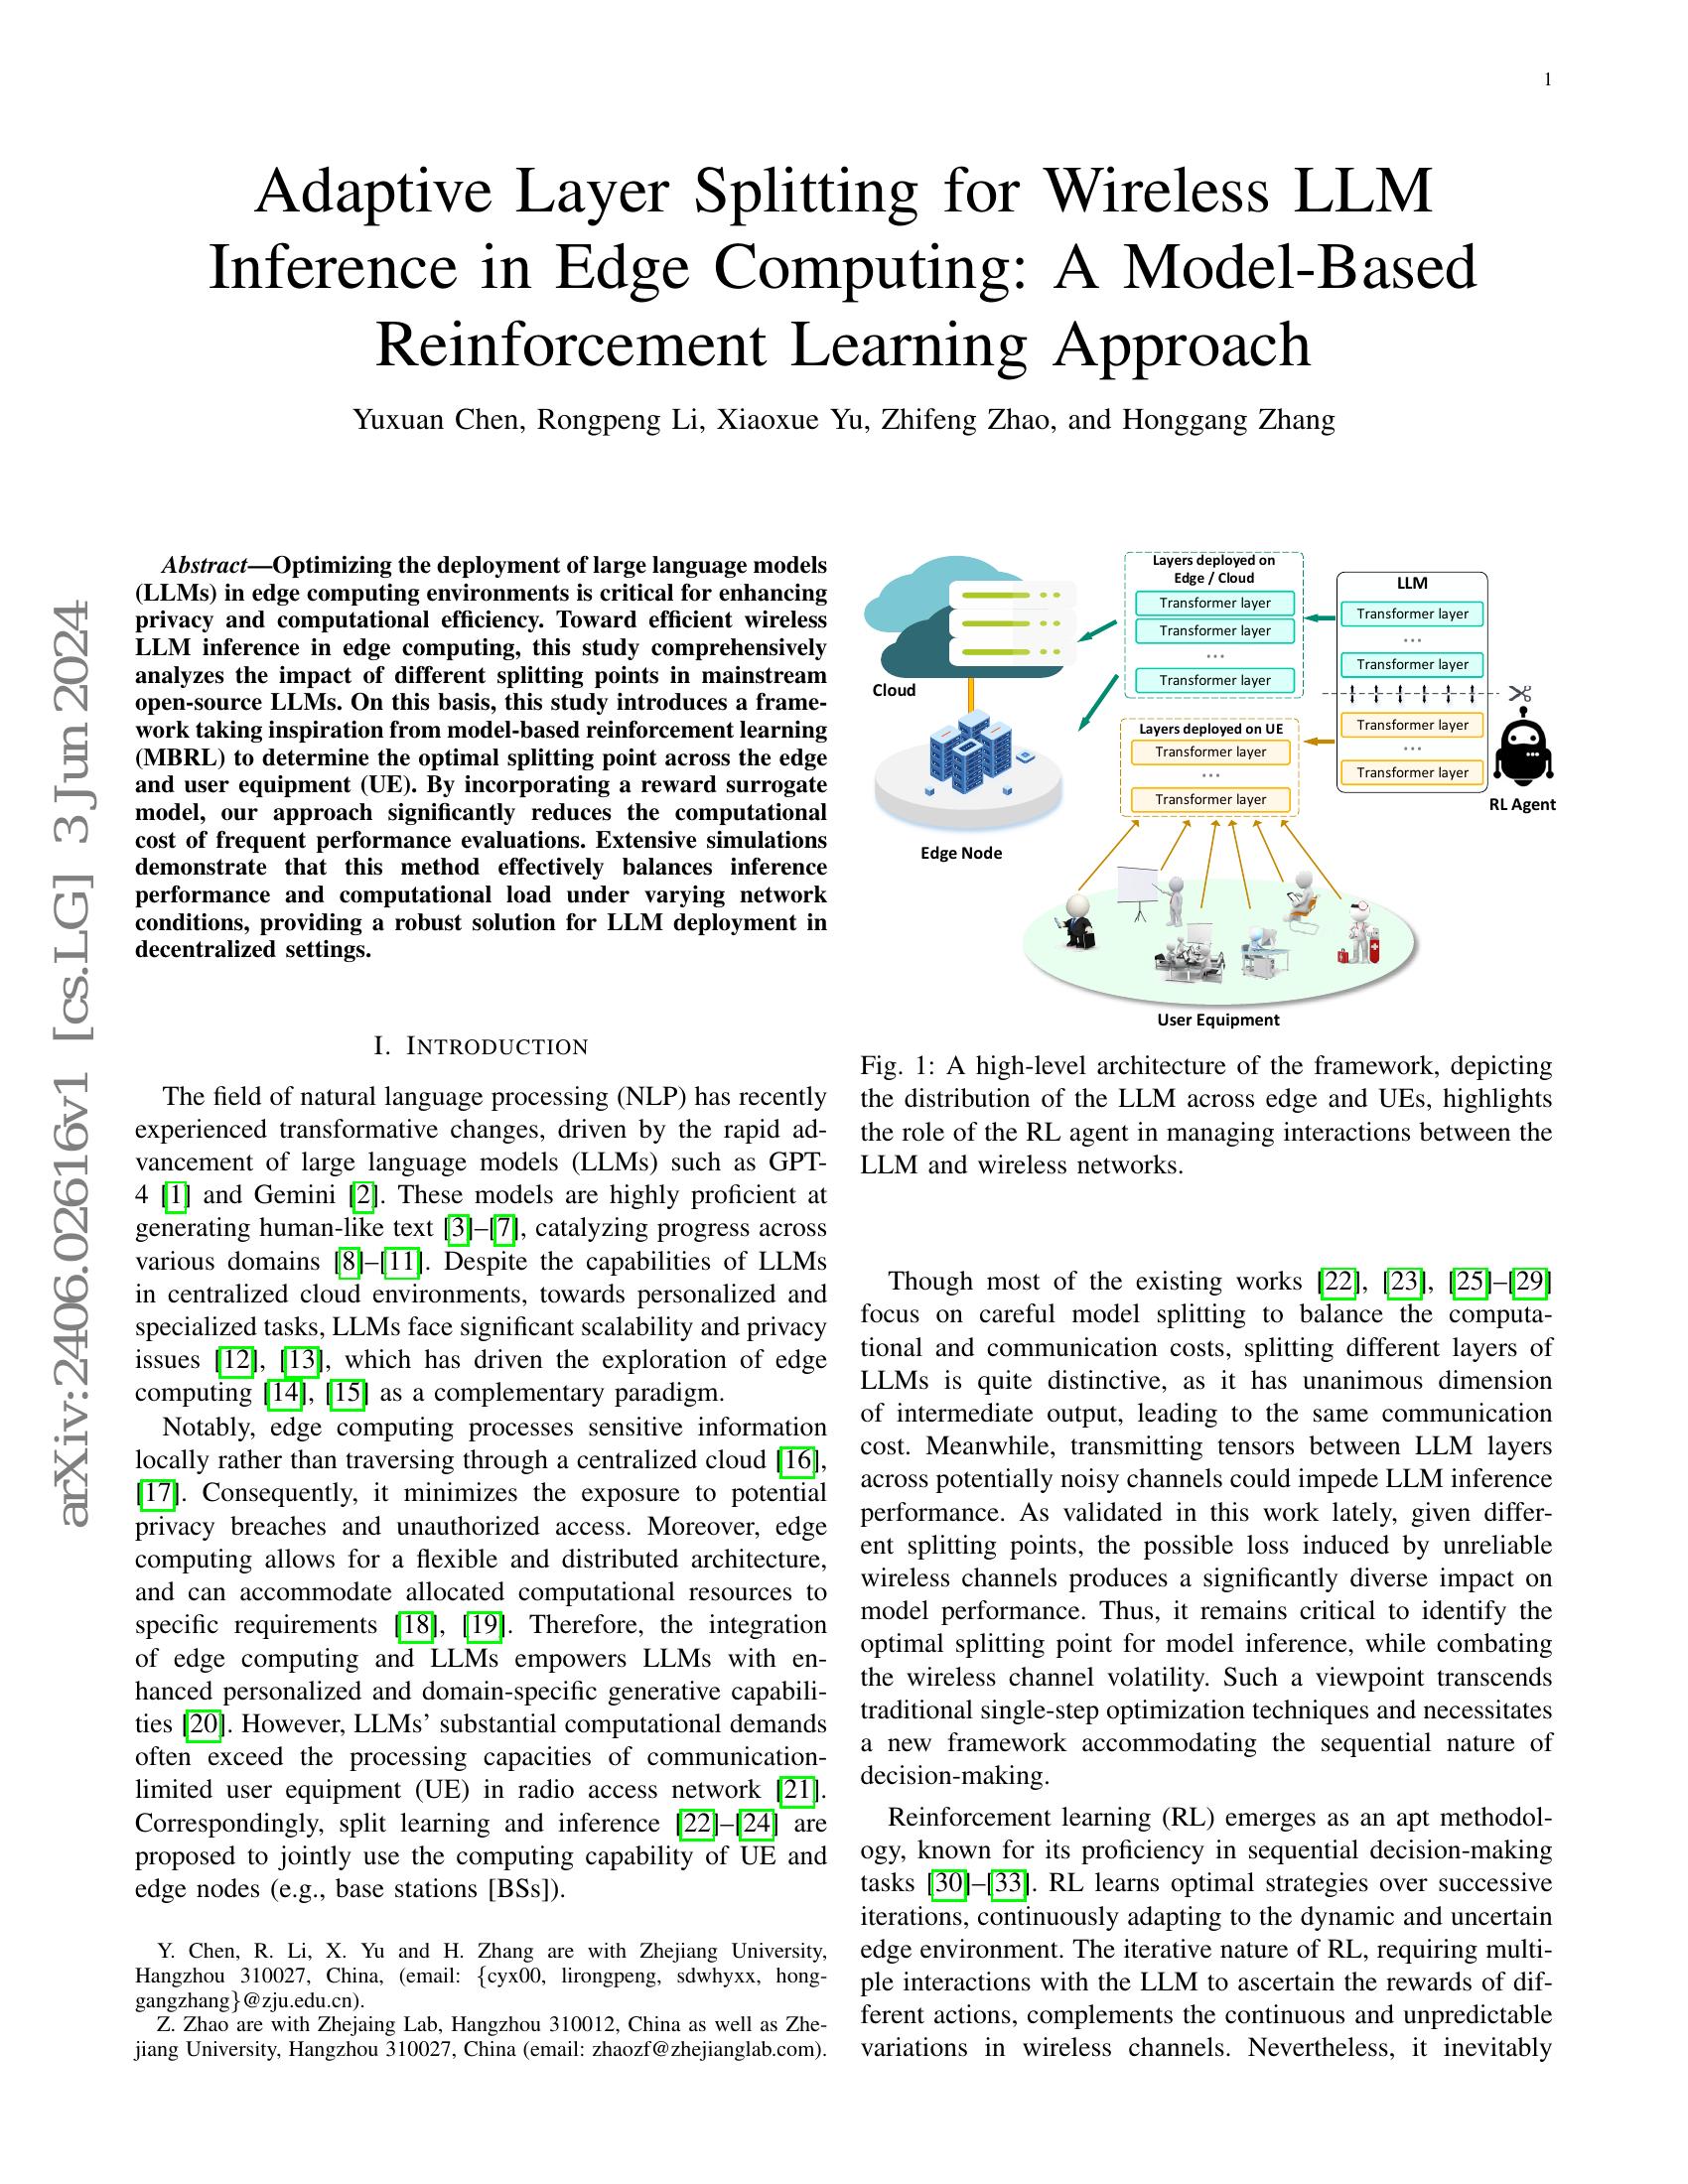
Adaptive Layer Splitting for Wireless LLM Inference in Edge Computing ...