
Nearest Neighbor Speculative Decoding For Llm Generation And
Nearest Neighbor Speculative Decoding for LLM Generation and ...

Nearest Neighbor Speculative Decoding for LLM Generation and ...

(PDF) Nearest Neighbor Speculative Decoding for LLM Generation and ...
Nearest Neighbor Speculative Decoding for LLM Generation and ...
Nearest Neighbor Speculative Decoding for LLM Generation and ...
Nearest Neighbor Speculative Decoding for LLM Generation and ...
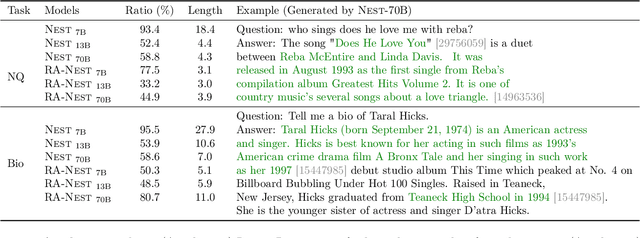
Nearest Neighbor Speculative Decoding for LLM Generation and Attribution
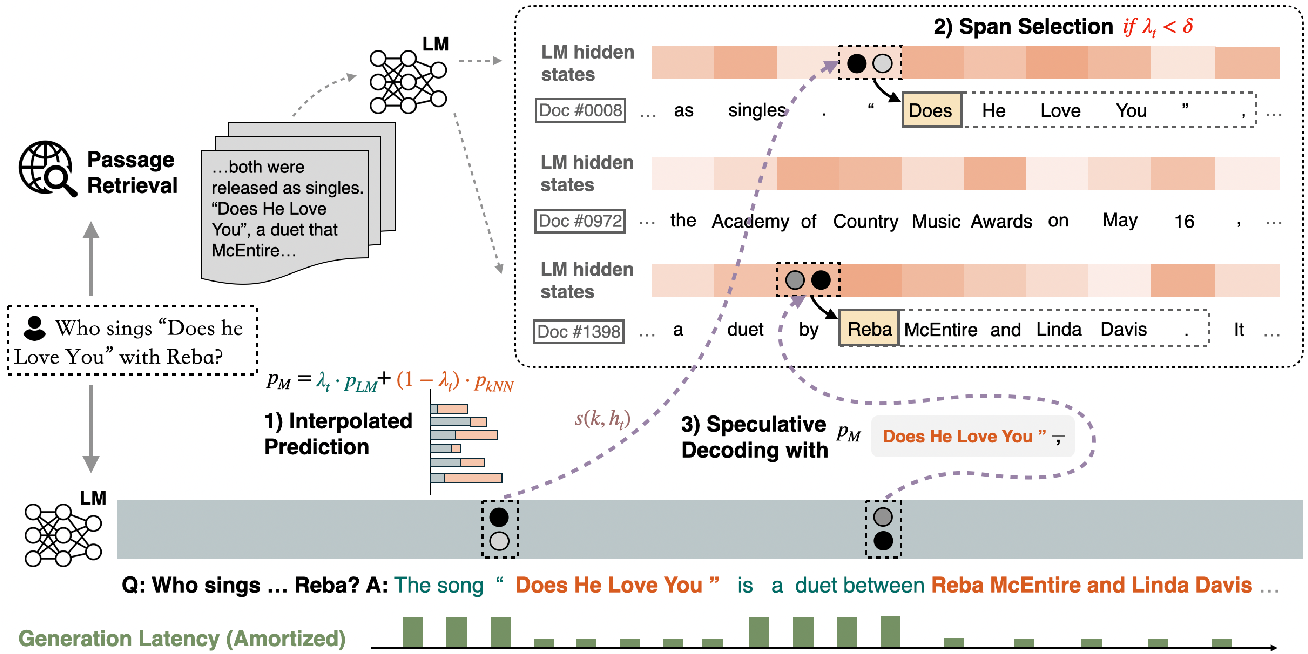
Figure 1 from Nearest Neighbor Speculative Decoding for LLM Generation ...

Paper page - Nearest Neighbor Speculative Decoding for LLM Generation ...
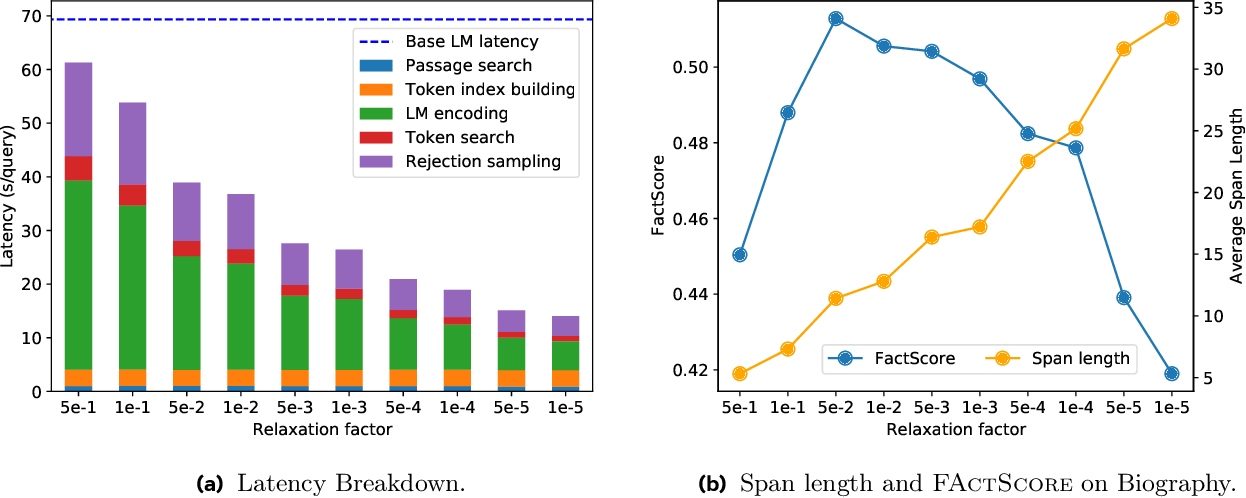
Figure 2 from Nearest Neighbor Speculative Decoding for LLM Generation ...
Advertisement Space (300x250)
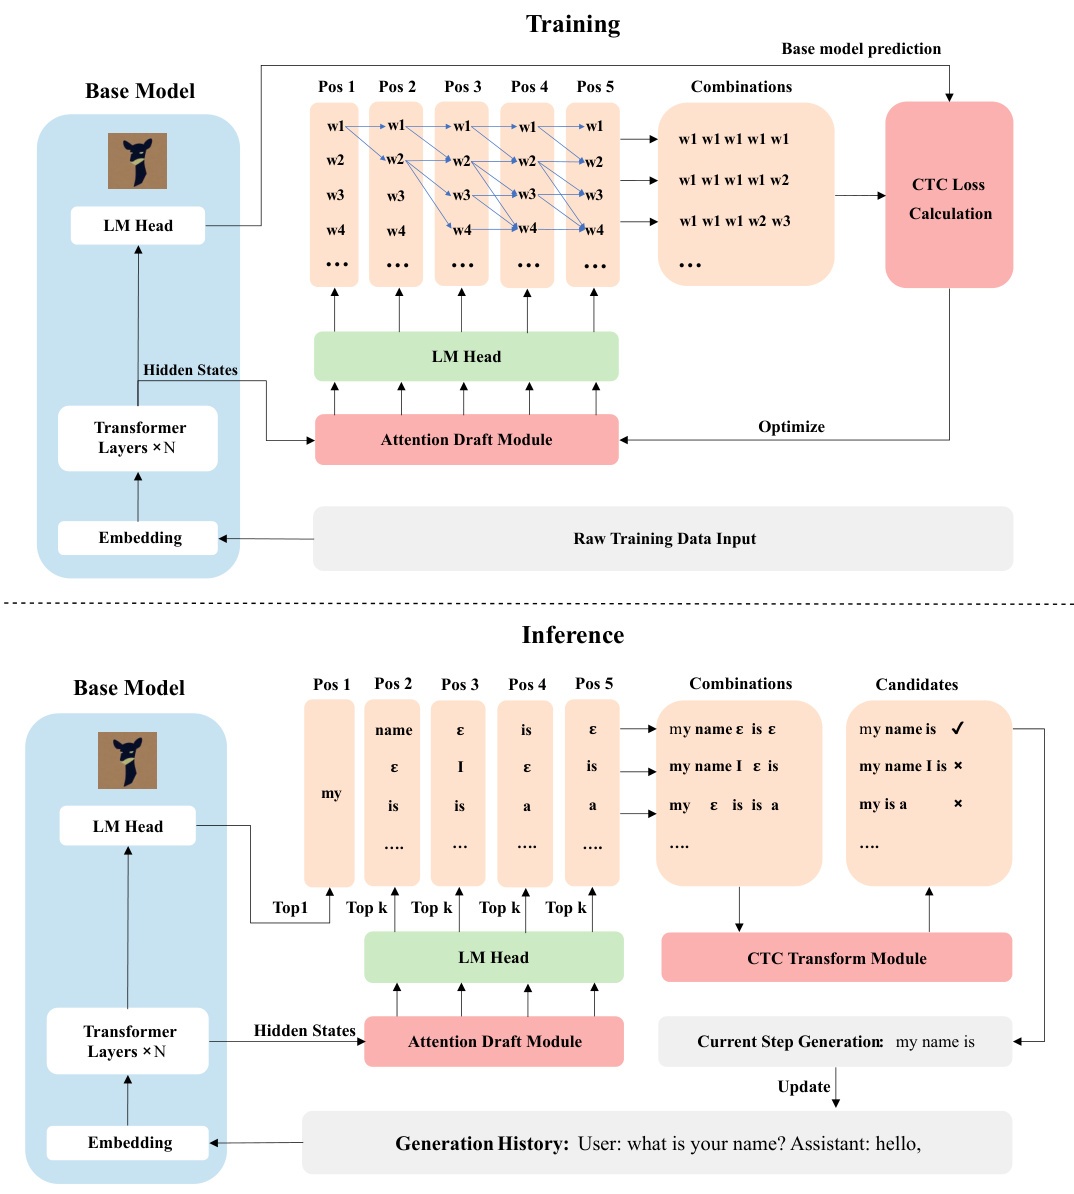
Speculative Decoding with CTC-based Draft Model for LLM Inference ...
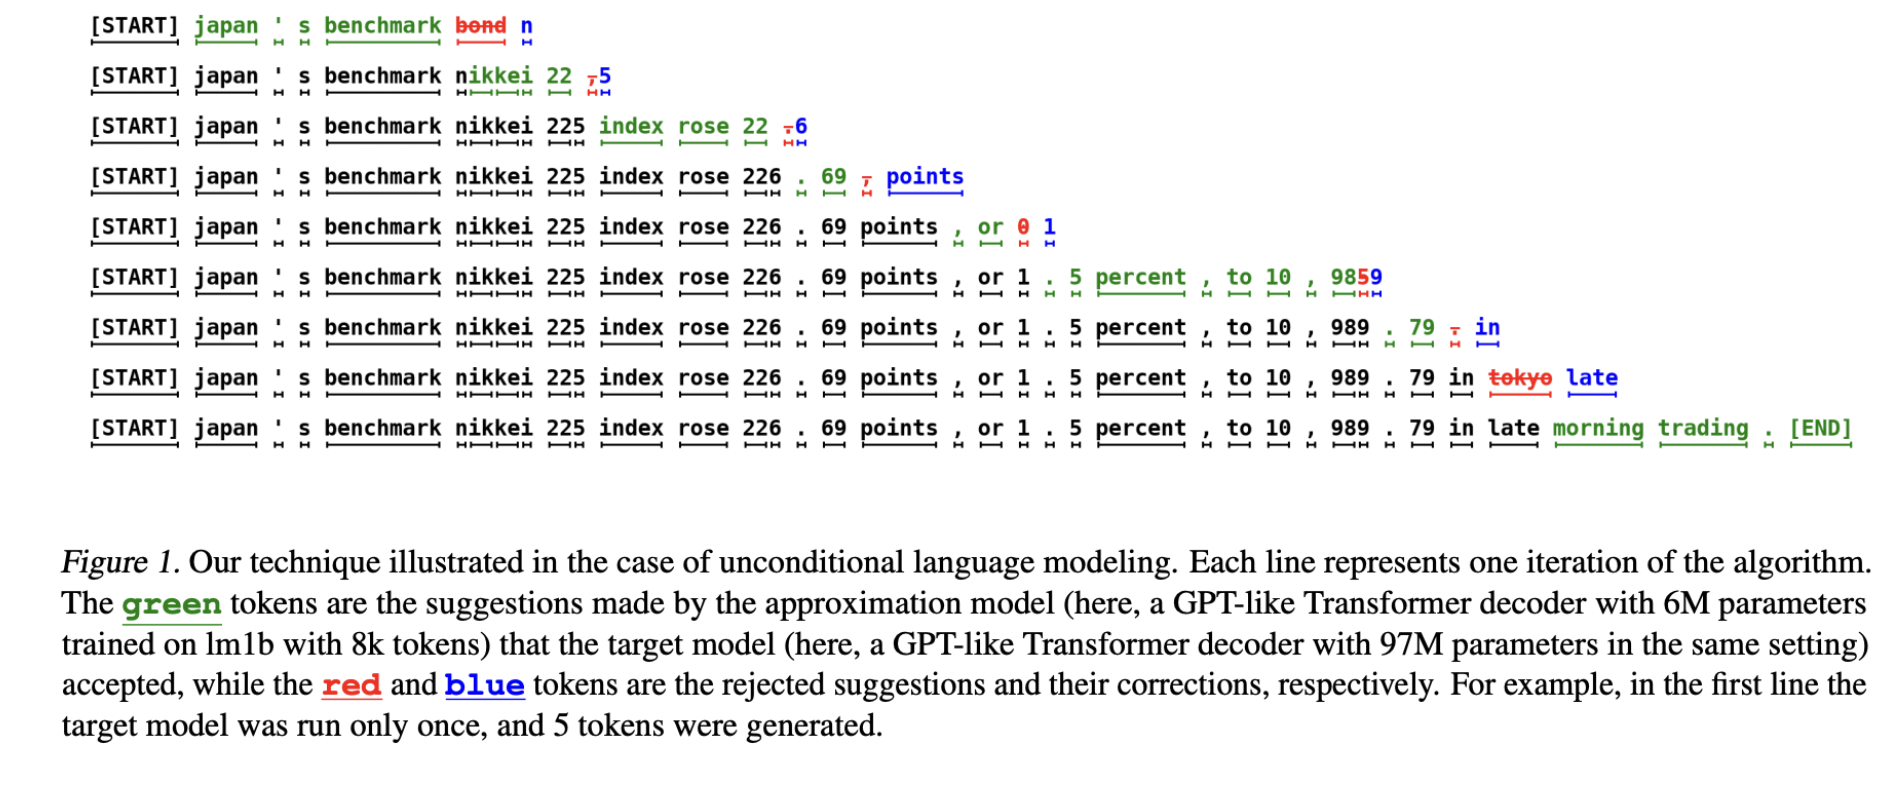
Speculative decoding for LLM inference - Adi Ganesh

[논문 리뷰] Reward-Guided Speculative Decoding for Efficient LLM Reasoning
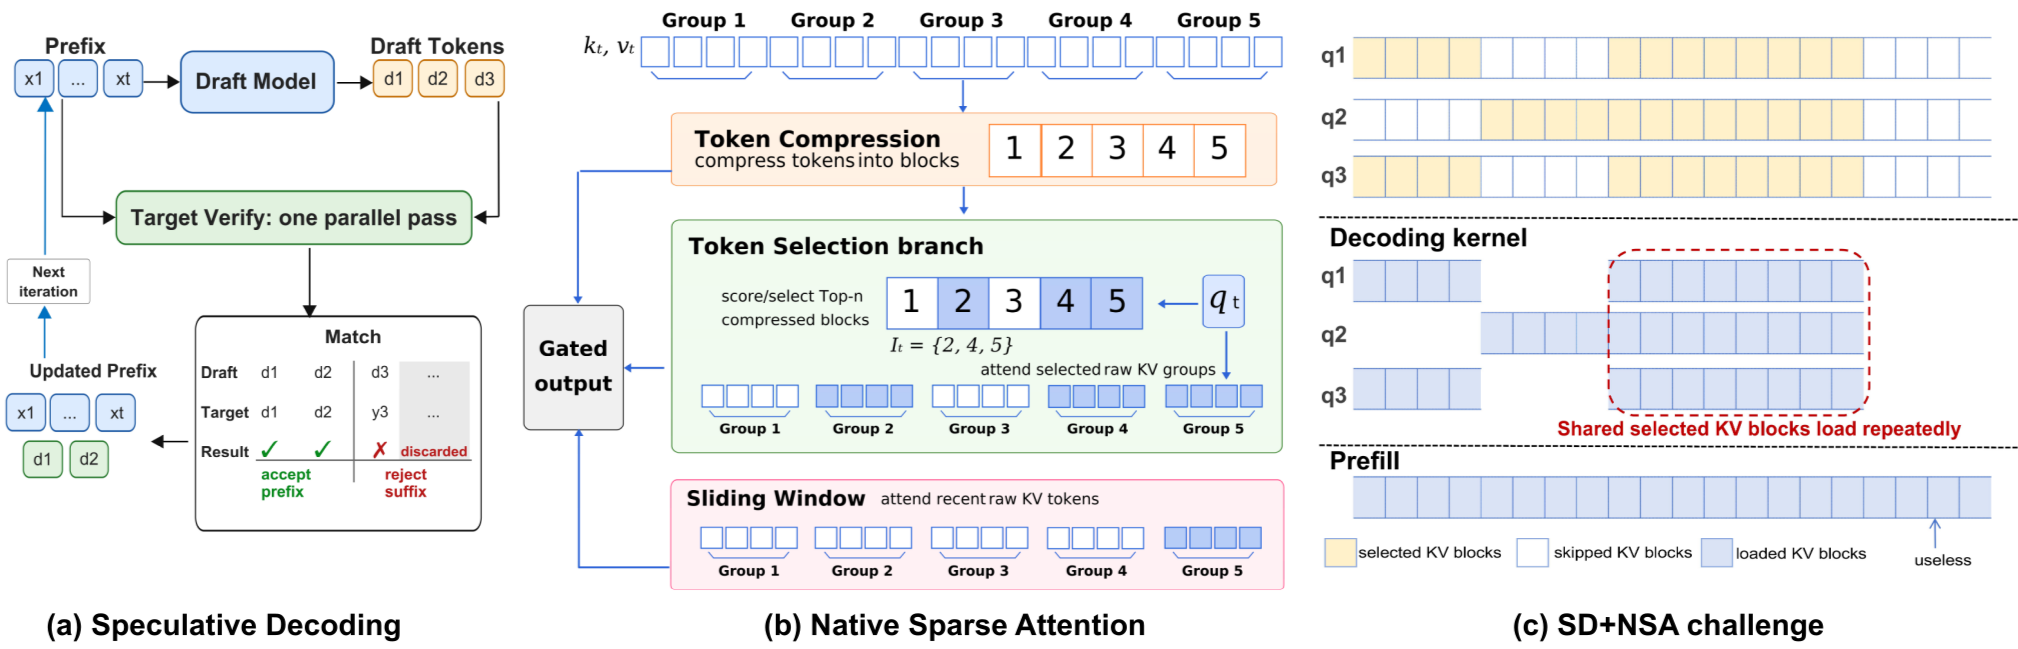
[論文レビュー] SpecSA: Bridging Speculative Decoding and Sparse Attention for ...
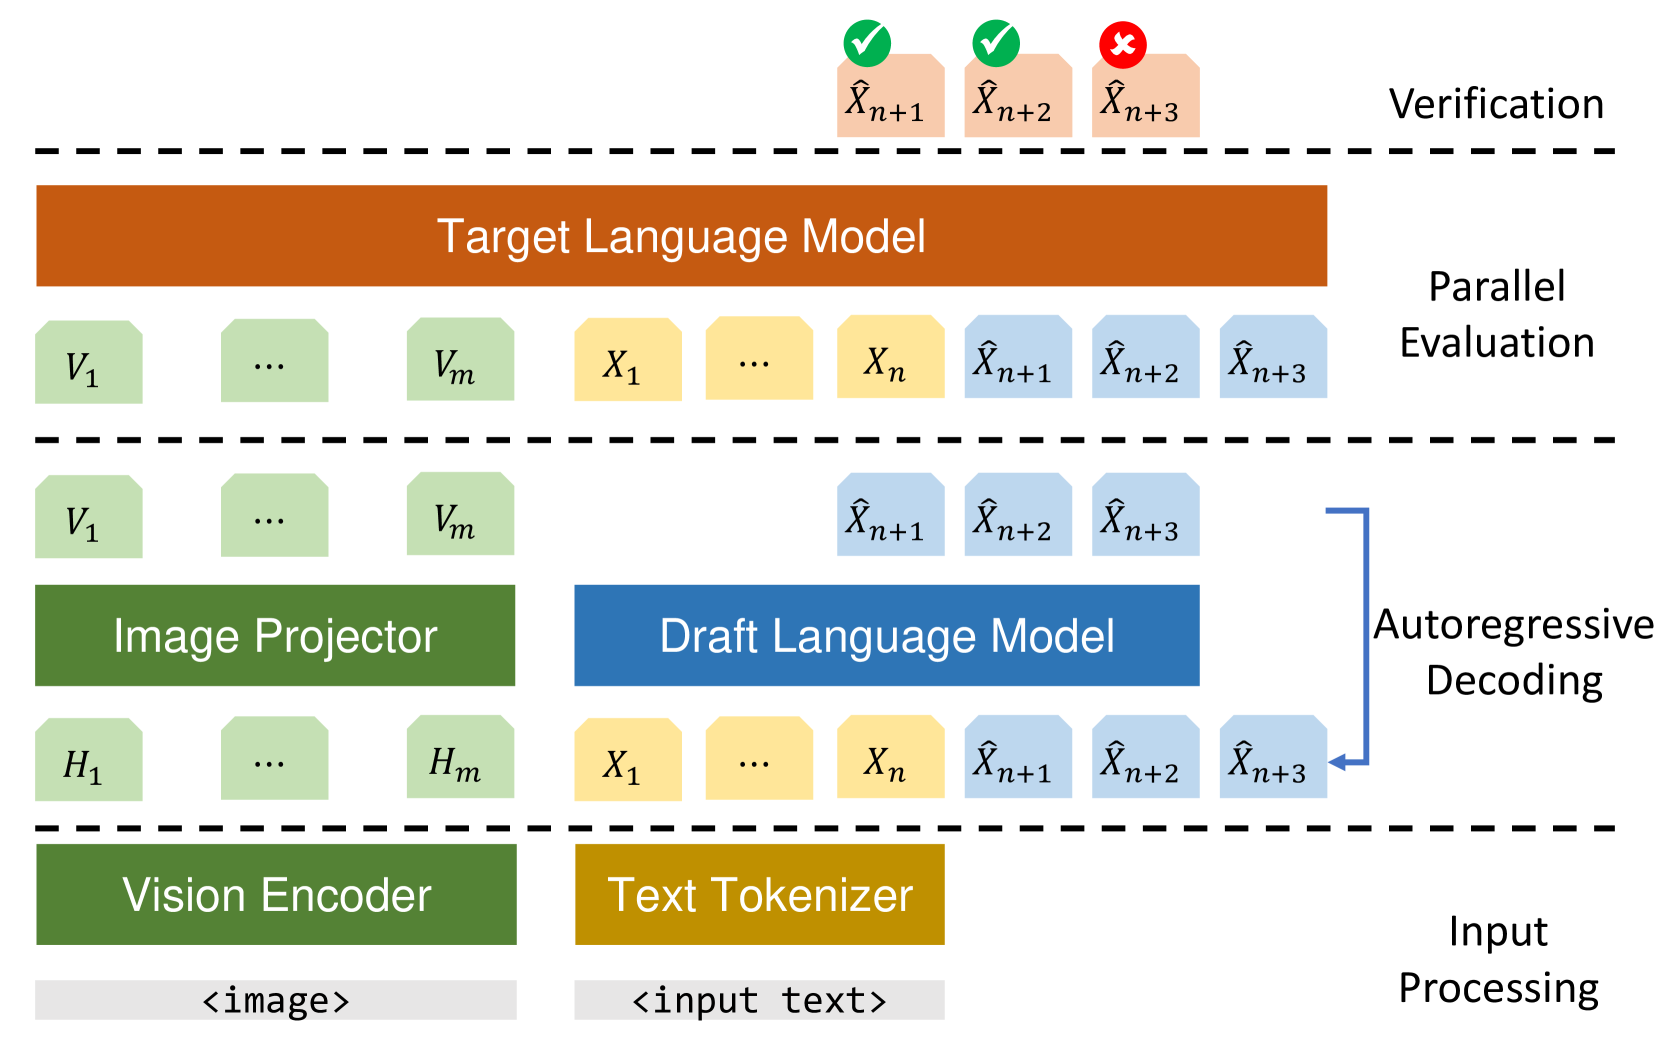
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...

[논문 리뷰] SLED: A Speculative LLM Decoding Framework for Efficient Edge ...
Speculative Decoding for Large Language Models: How Draft and Verifier ...

[2503.10325] Collaborative Speculative Inference for Efficient LLM ...
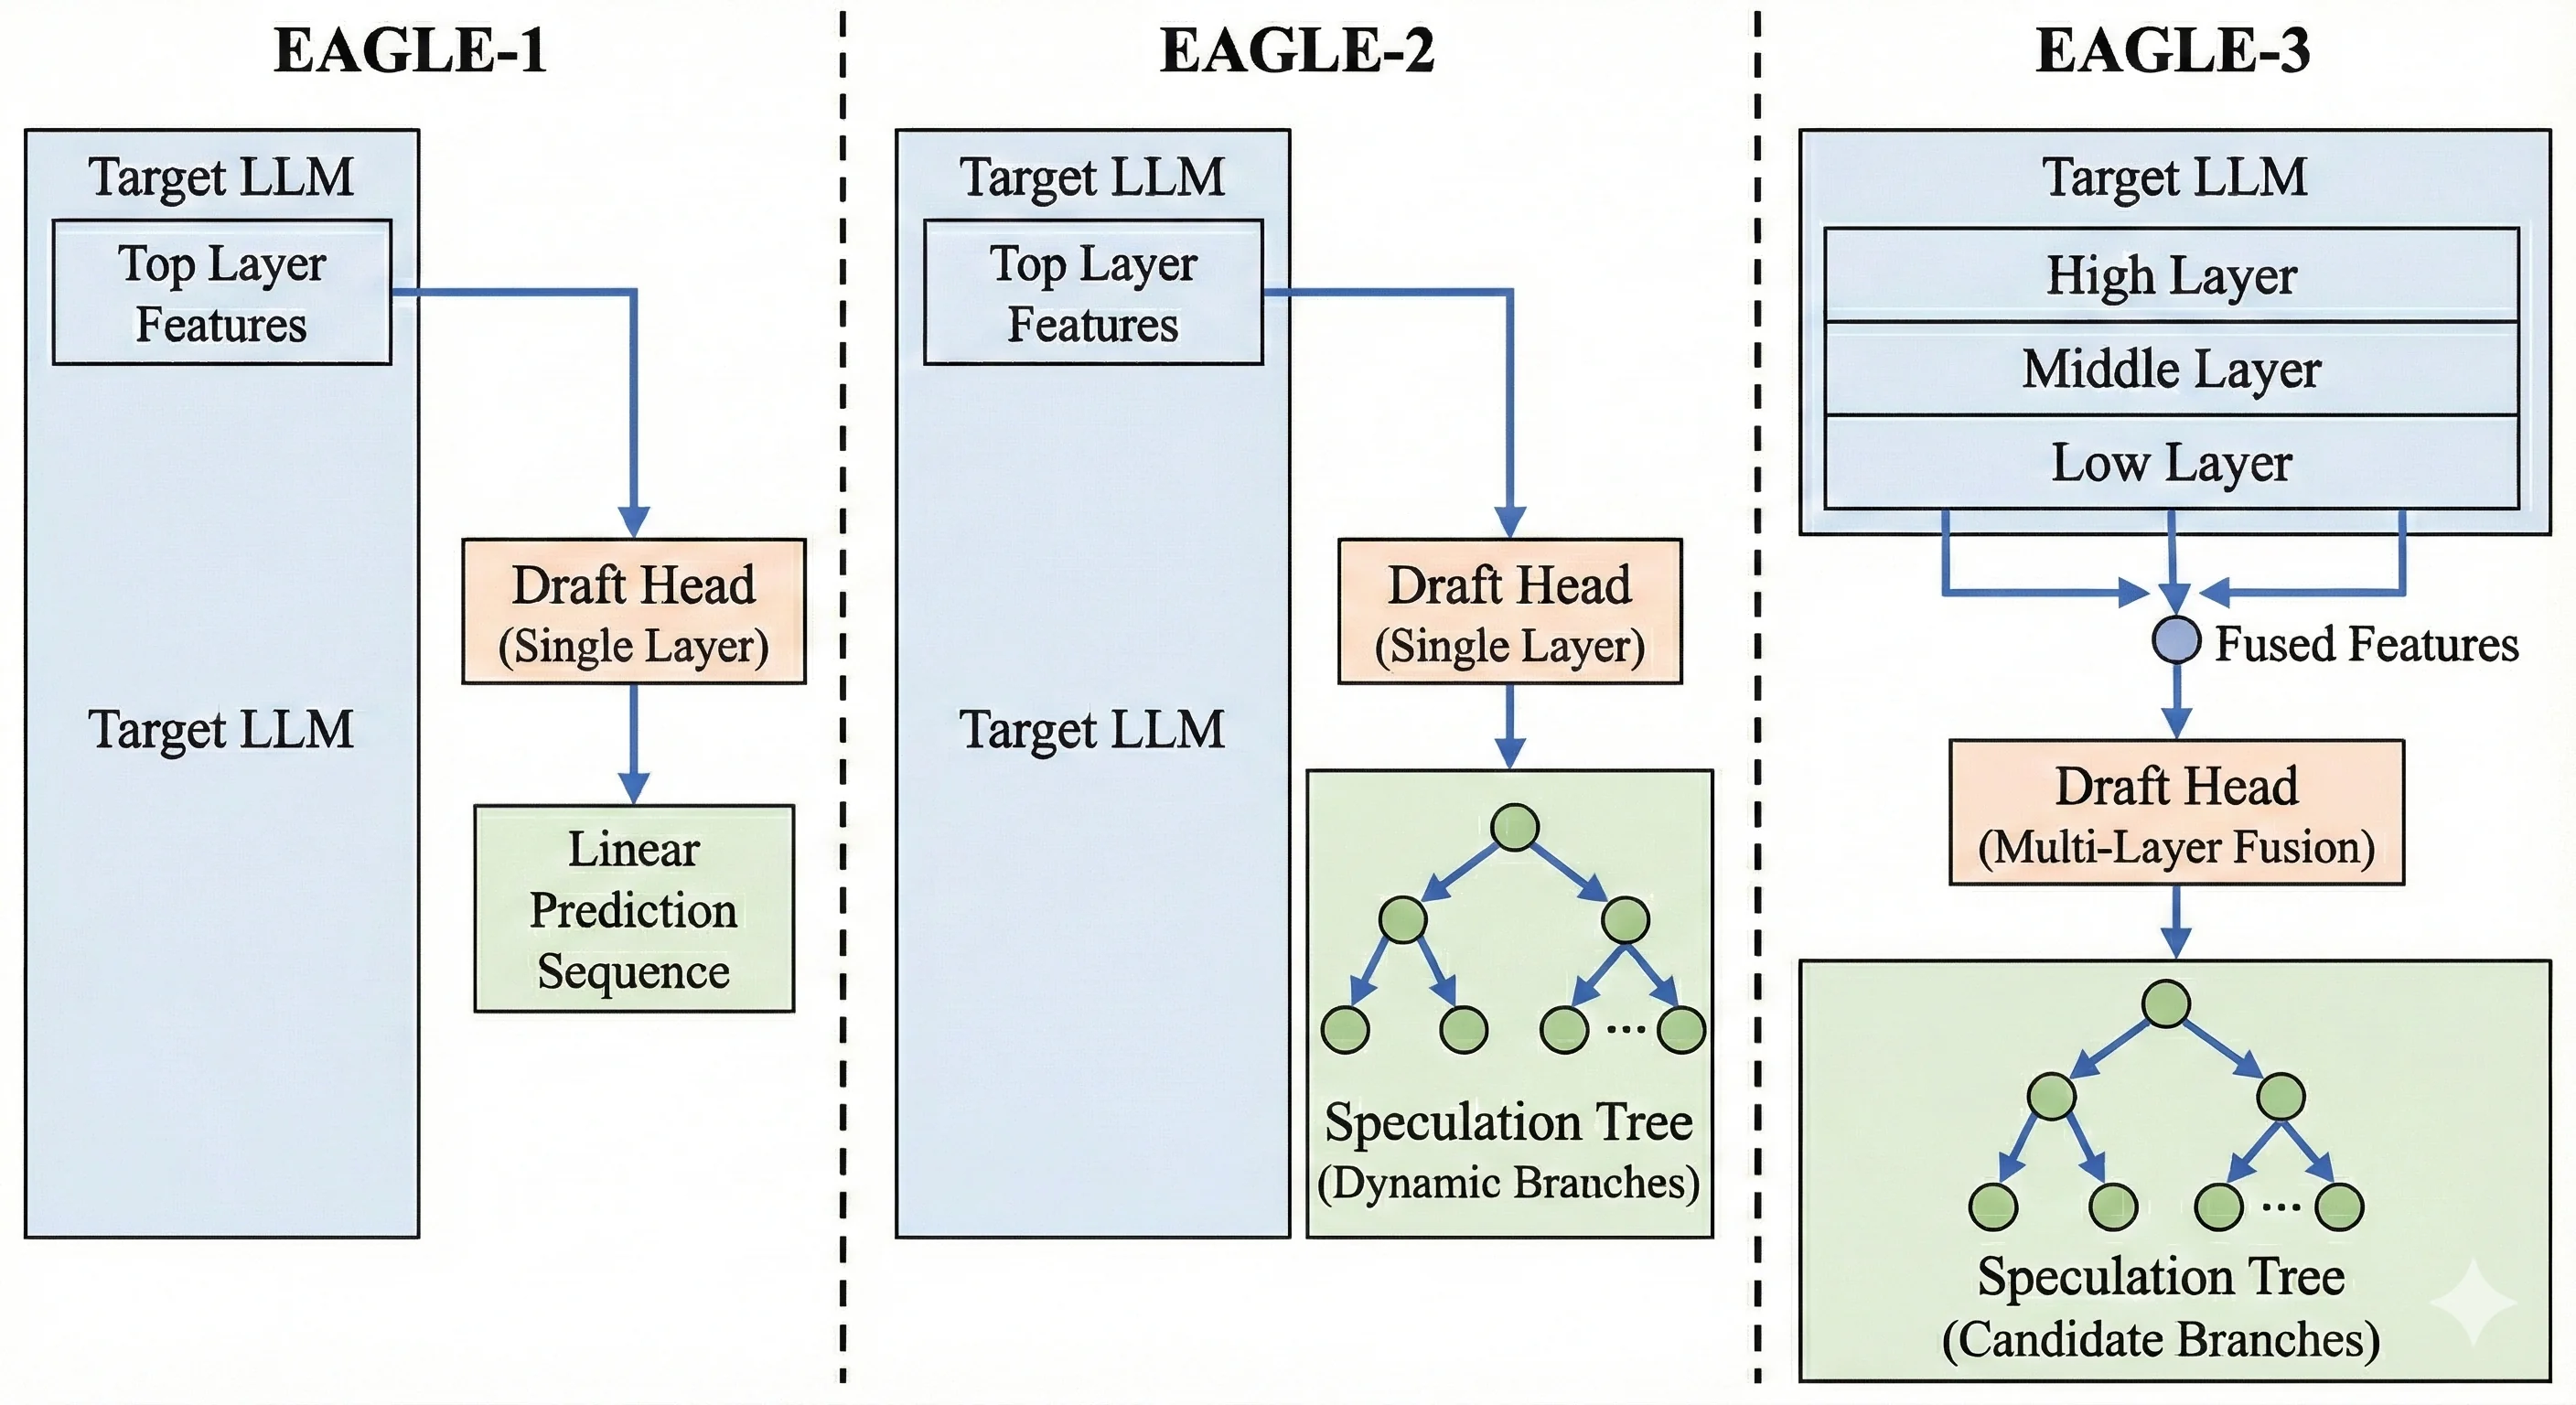
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
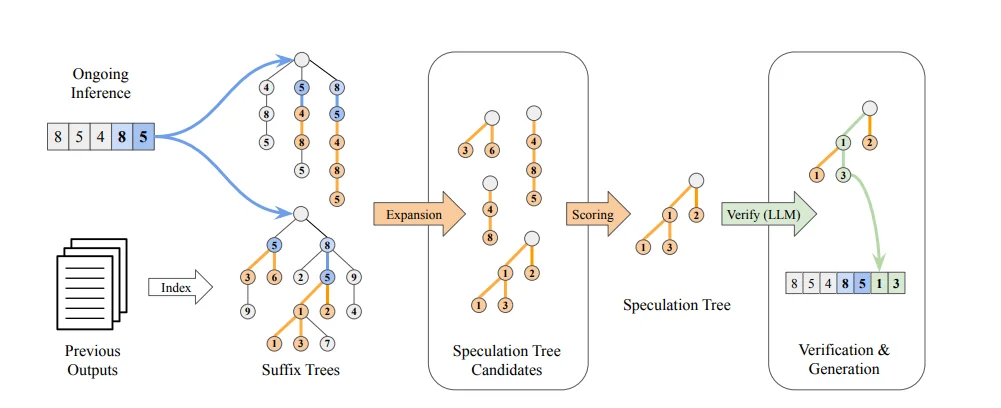
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (336x280)

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
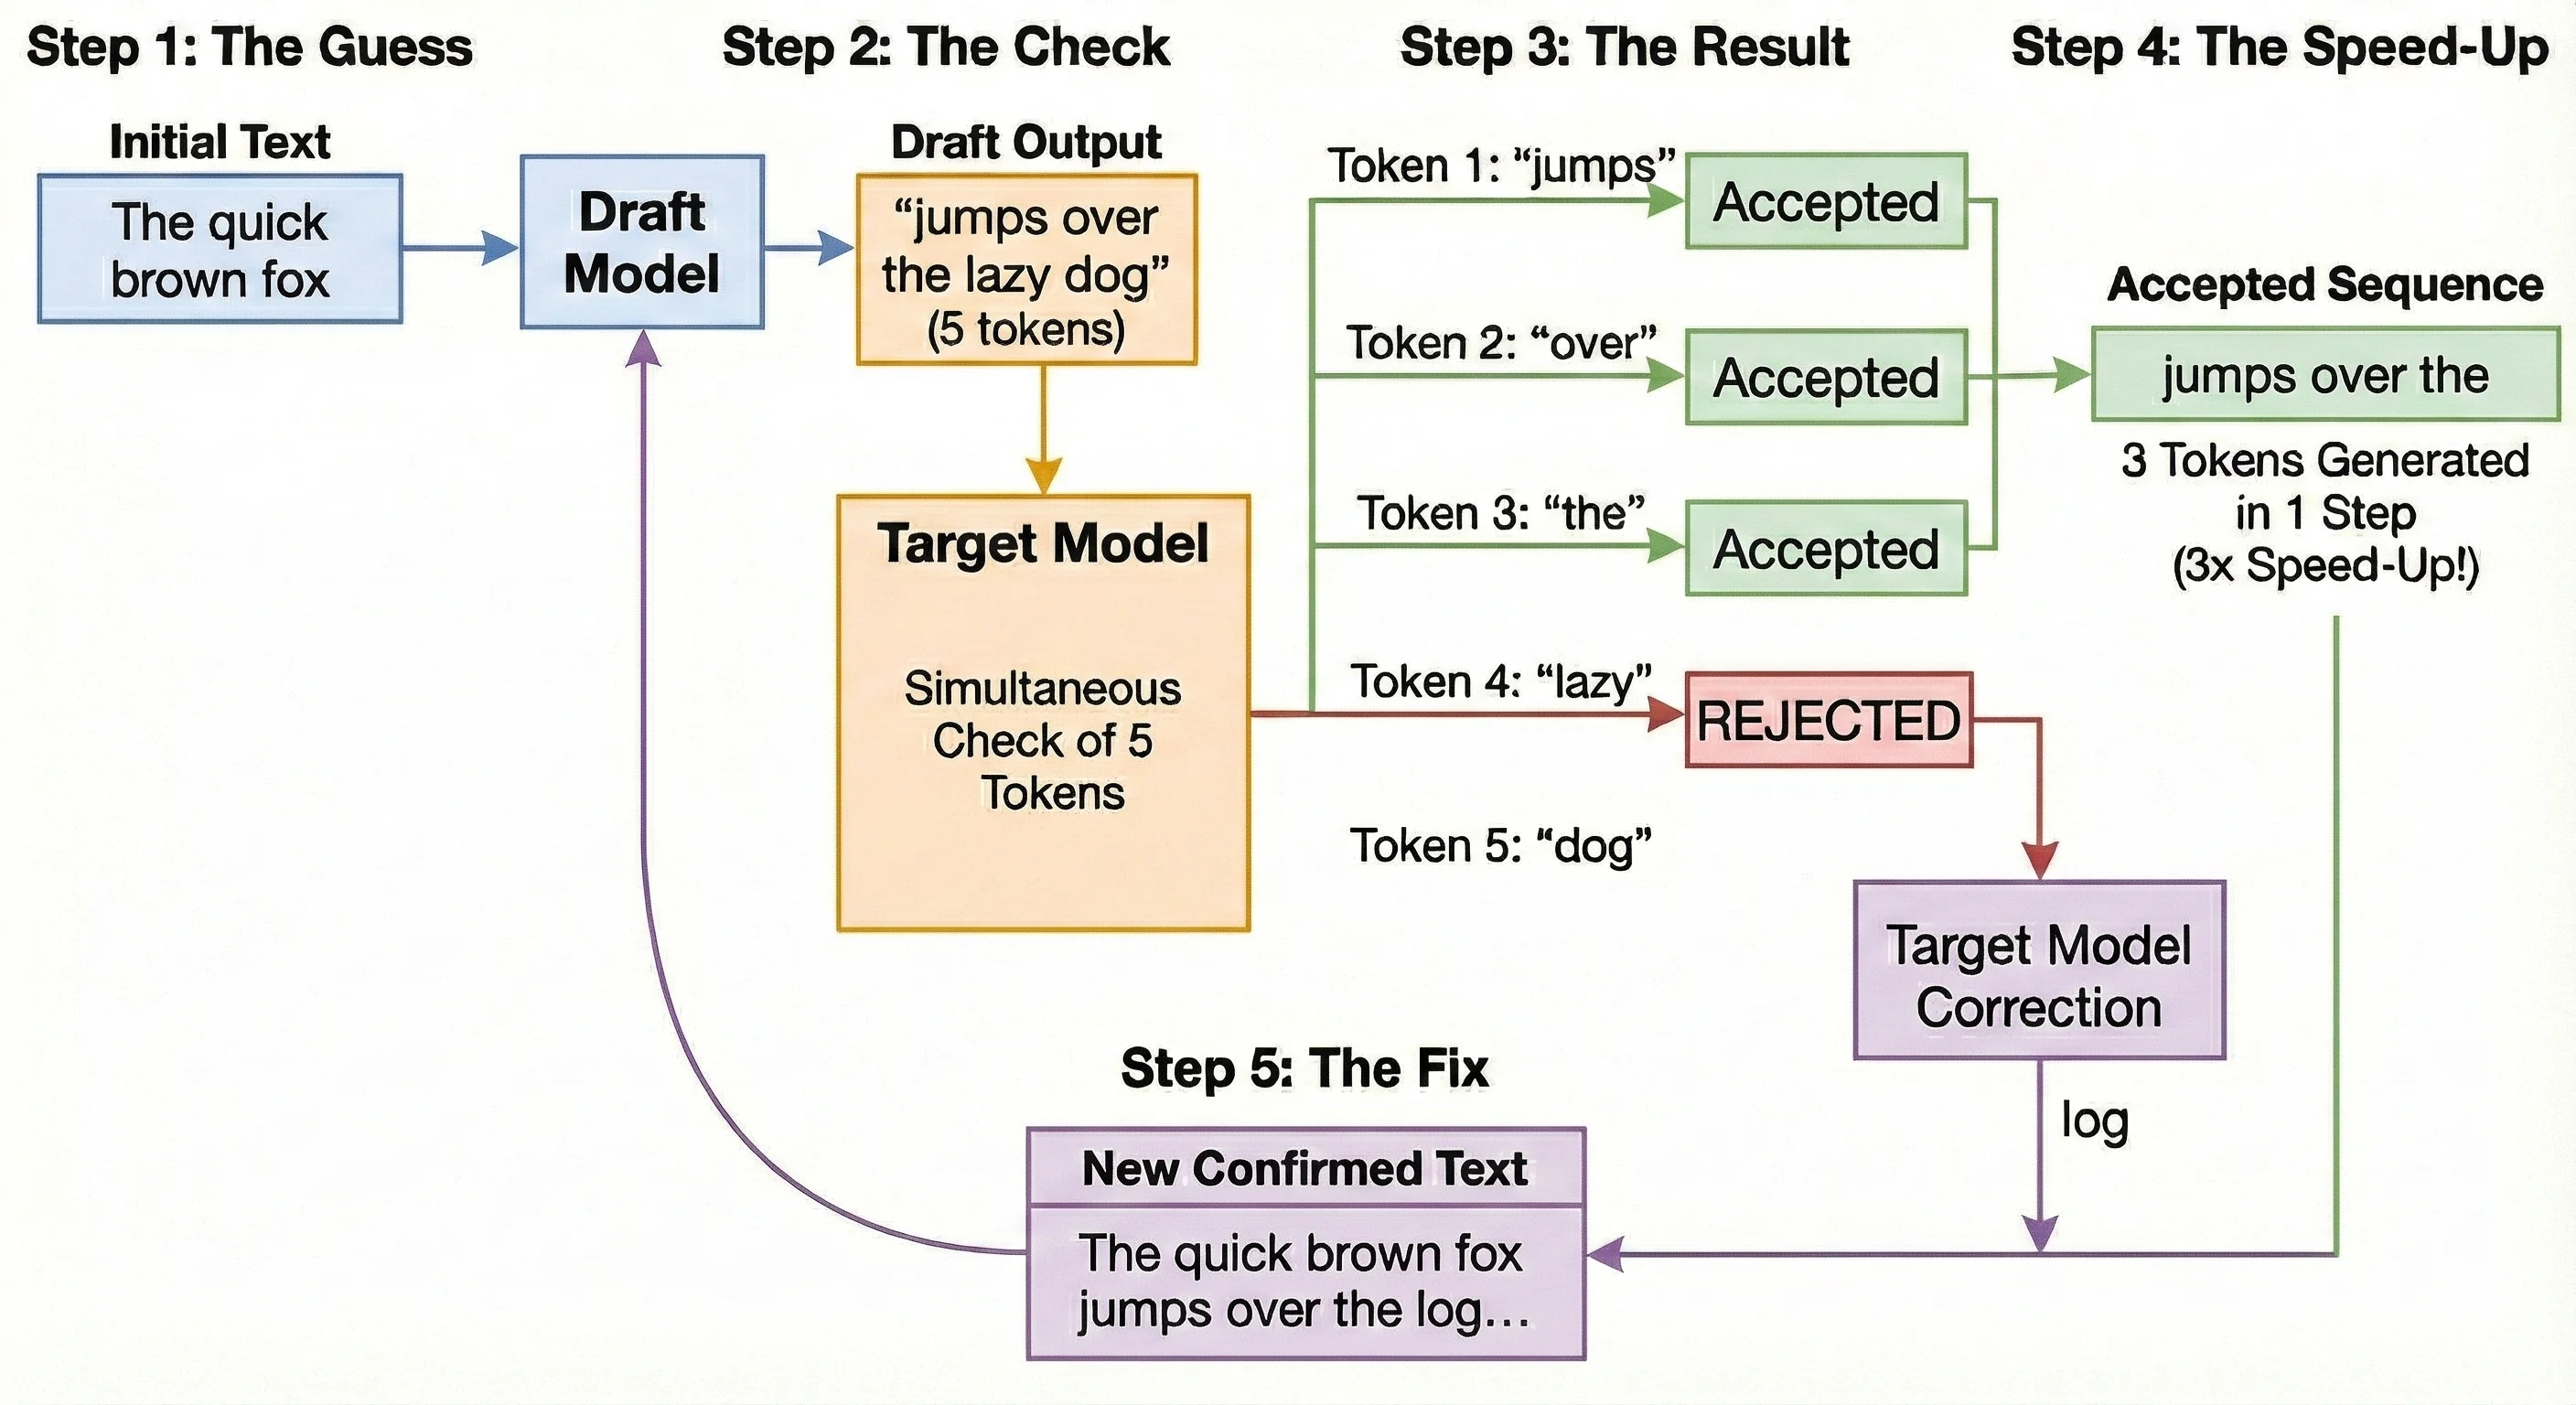
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
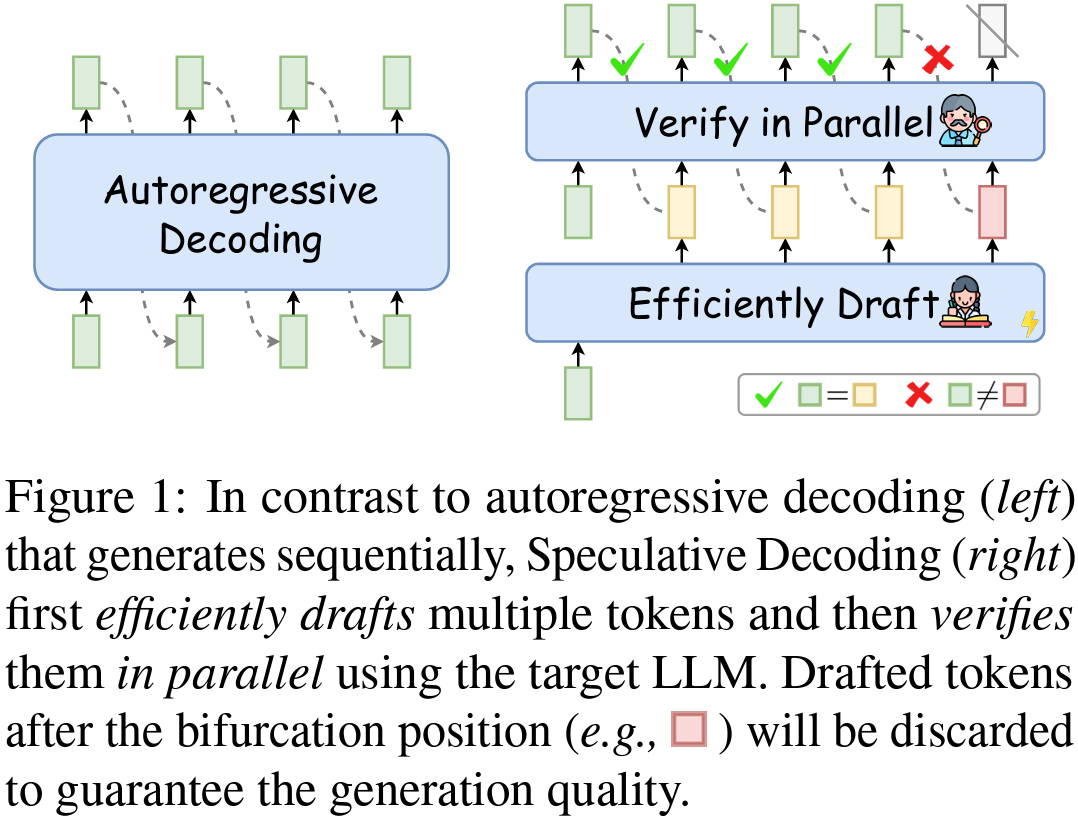
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
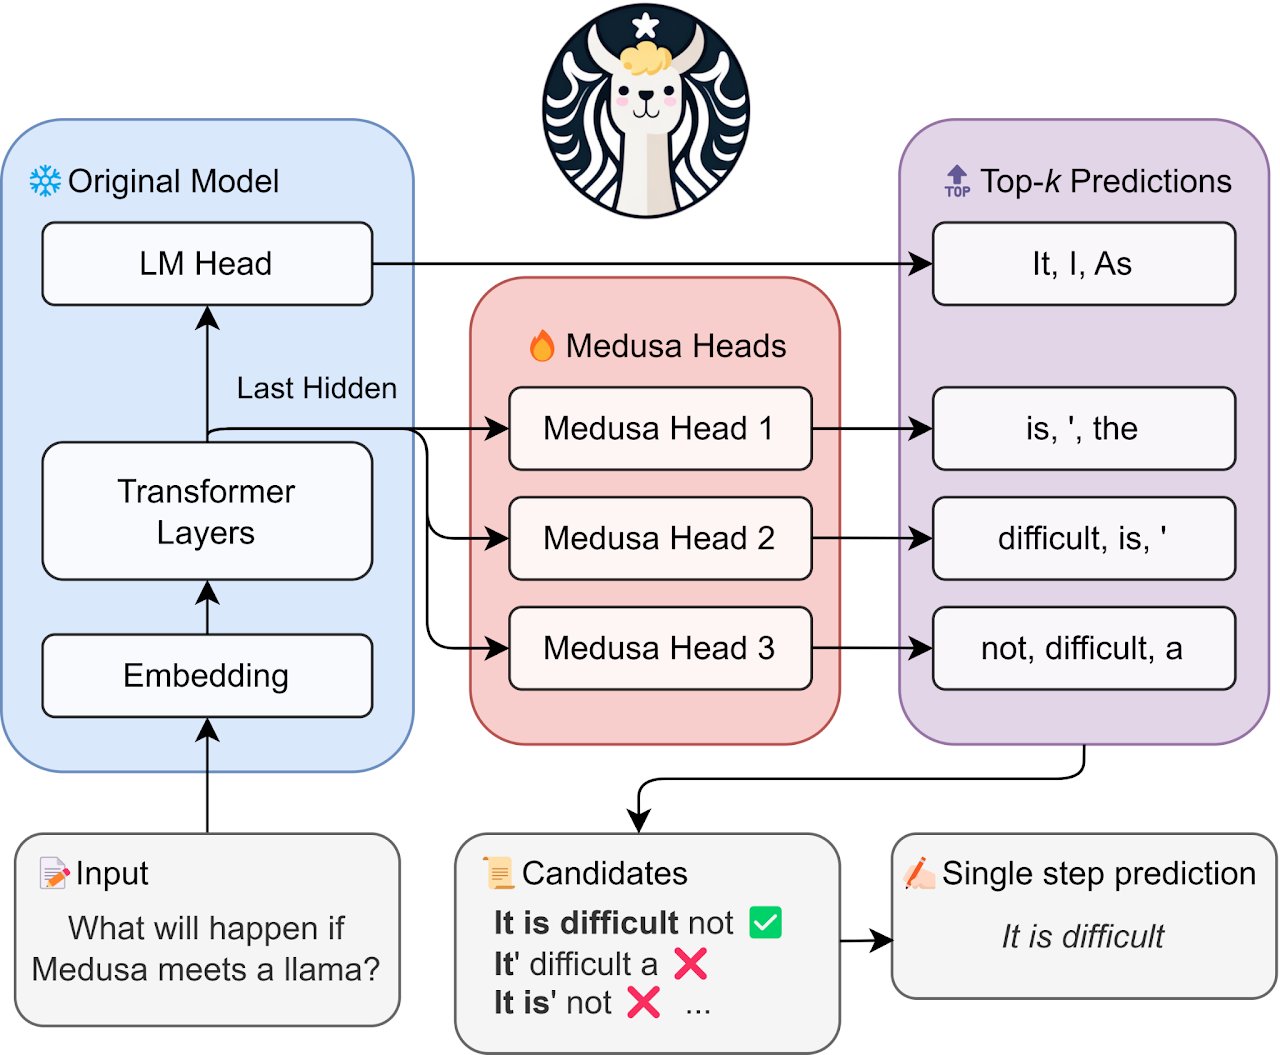
Accelerate LLM Inference with Speculative Decoding | Charles Xu
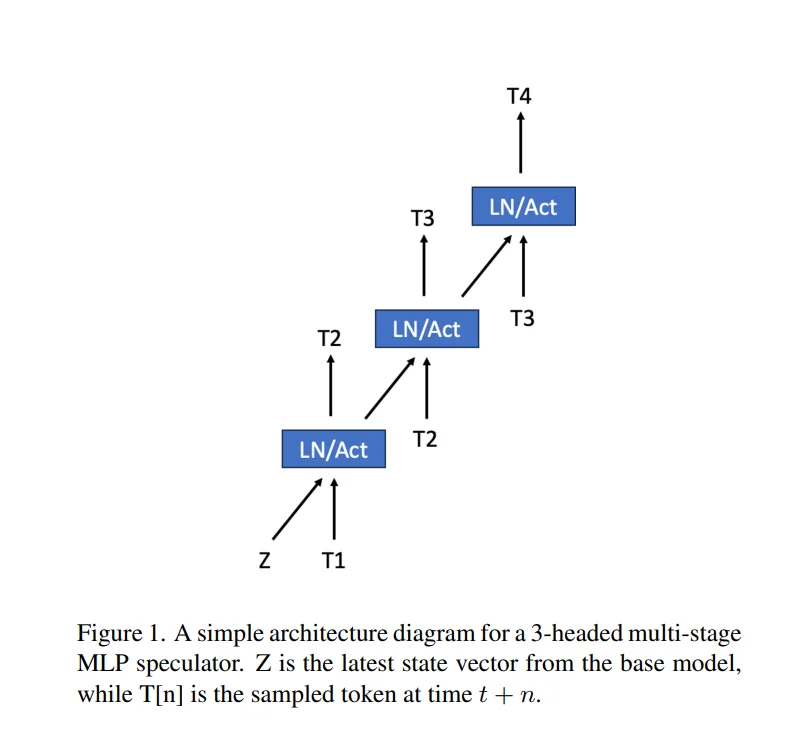
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
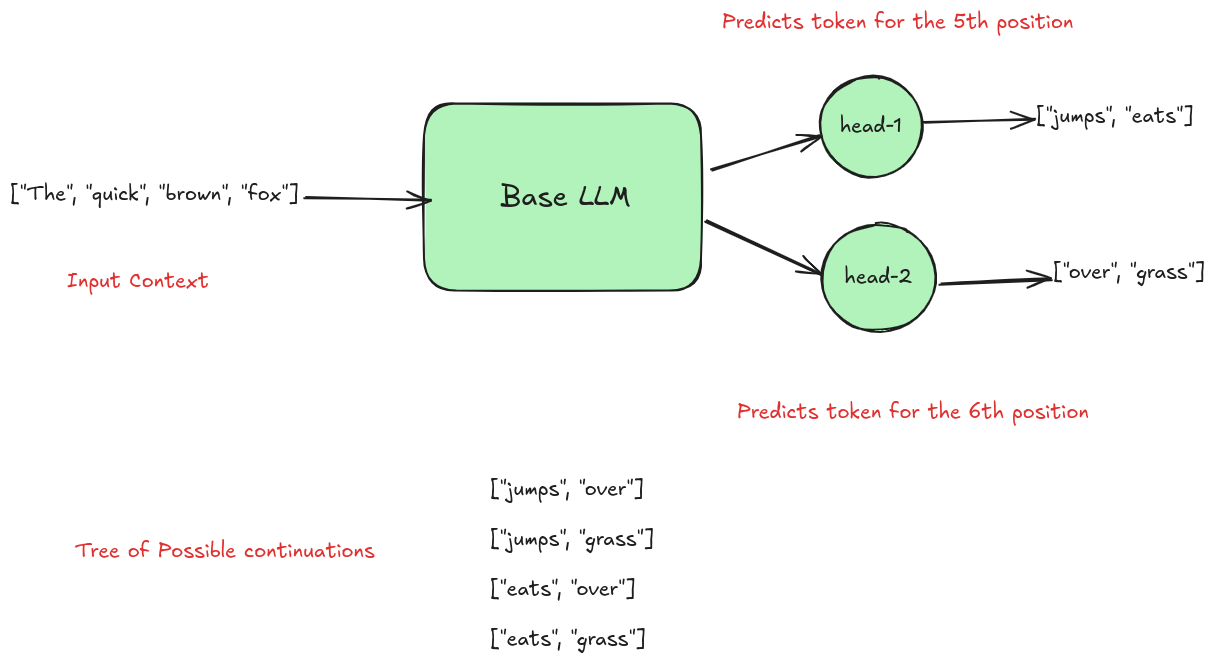
A Survey of Speculative Decoding Techniques in LLM Inference

Faster LLMs with speculative decoding and AWS Inferentia2
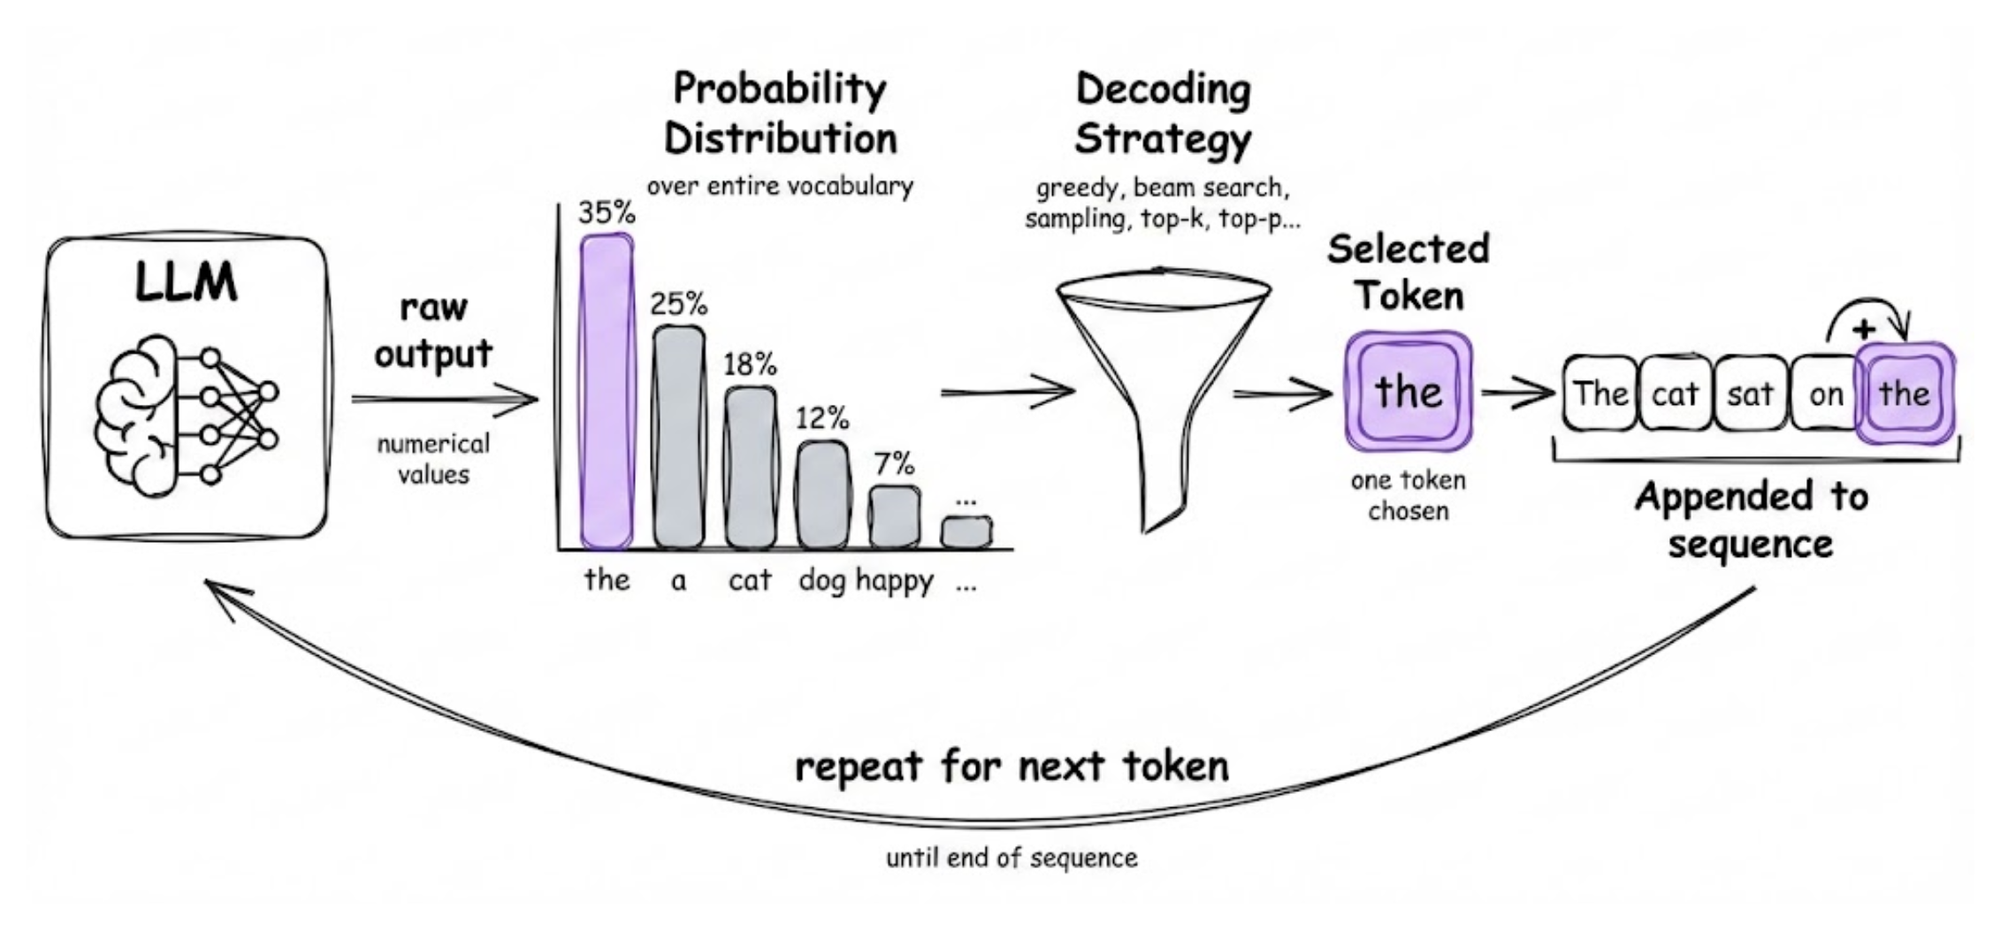
Building Blocks of LLMs: Decoding, Generation Parameters, and the LLM ...
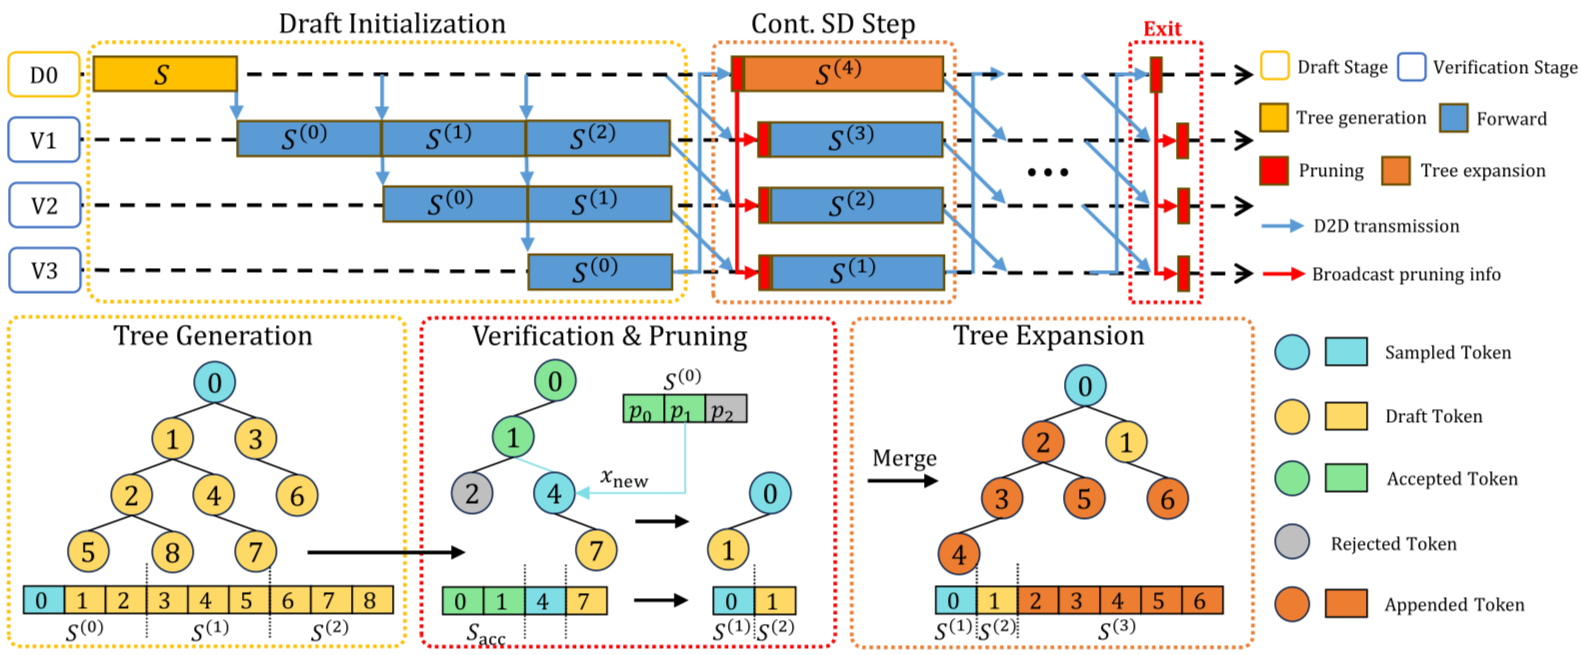
[论文评述] FlowSpec: Continuous Pipelined Speculative Decoding for ...

Accelerating LLM Inference with Staged Speculative Decoding: Paper and ...
Advertisement Space (336x280)

Speculative Decoding in Decentralized LLM Inference: Turning ...

(PDF) Accelerating LLM Inference with Staged Speculative Decoding
Speculative Decoding Production Guide: 2-5x Faster LLM Inference on GPU ...

Parallel LLM Decoding: Speculative and Diffusion

Introducing our Speculative Decoding Engine Builder integration for ...